commit ef0df92922e53716ec4b4792f1bb63f56552c811
parent 2609231e8134f28c8bba50a44fe995093df7d993
Author: Andrew Laack <andrew@laack.co>
Date:   Mon,  9 Nov 2026 00:38:39 -0600

More editorials

Diffstat:
| A | editorials/101.md | | | 91 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/102.md | | | 91 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/103.md | | | 55 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/104.md | | | 9 | +++++++++ |
| A | editorials/105.md | | | 88 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/106.md | | | 54 | ++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/107.md | | | 143 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/108.md | | | 143 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/109.md | | | 71 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/110.md | | | 71 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/111.md | | | 160 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/112.md | | | 160 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/113.md | | | 49 | +++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/114.md | | | 49 | +++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/115.md | | | 179 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/116.md | | | 179 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/117.md | | | 49 | +++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/119.md | | | 53 | +++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/158.md | | | 49 | +++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/159.md | | | 49 | +++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/160.md | | | 51 | +++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/162.md | | | 180 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/164.md | | | 147 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/165.md | | | 29 | +++++++++++++++++++++++++++++ |
| A | editorials/166.md | | | 43 | +++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/167.md | | | 73 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/169.md | | | 112 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/174.md | | | 147 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/99.md | | | 83 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
29 files changed, 2657 insertions(+), 0 deletions(-)
diff --git a/editorials/101.md b/editorials/101.md
@@ -0,0 +1,91 @@
+Source: https://codeforces.com/blog/entry/2393
+
+### **1. Clothes (A Div-2)**
+
+In this problem constraints are allow to look throw all triples of clothes. For every triple one can check if all elements of tripe areturn out to match with others, and anong those triples find one whith minimal cost.
+
+### **2. Sum of digits (B Div-2)**
+
+Initial number consist of no more then 100000 digits. Therefore after first transform resulting number will be no more then 900000, and then it will constist of no more then 6 digits. Thus after next transform number will be no more then 54 and so it will be two-digit or one-digit. Sum of digits of a two-digit number no more, then 18, and sum of digit of such number no more, then 9.
+
+Thus Gerald can't do nore, then 4 transforms. First transform one can implement one simple pass throw symbols of given string. Following operations take very little time.
+
+### **3. Homework (C Div-2, A Div-1)**
+
+Lets count up the number of entries to string of every letter. Let Gerald choose *x* letter and lose them. Obvious thet if he lose *x* rarest letters then overall number of losed letter do not increase, and then if he can lose some *x* lettes, he can lose *x* rarest ones. Thus it's easy to determine if Gerald can loses *x* letters. And now to calculate the answer one only need to find the minimal such *x*, so Gerald can lose *x* letters.
+
+### **4. Buses (D Div-2, B Div-1)**
+
+For every slop from 0 to *n* lets calculate *k**x* - number of ways come to them. Consider the *i*-th bus. Number of ways come to stop *t**i* applied *i*-th bus is uqual to number of way to embus to *i*-th bus.
+
+One can embus to *i*-th bus on the stops *s**i*, *s**i* + 1, ..., *t**i* - 1. Thus number of ways come to stop *t**i* in the *i* bus is equal to sum *k**s**i* + *k**s**i* + 1 + ... + *k**t**i* - 1. Finally, lets note that overall number of way to come to stop *t**i* is the sum of numbers of ways to come to stop *t**i* on every bus.
+
+It's remained two problems. First problem: 0 ≤ *n* ≤ 109. Therefore all *k**x* not climb in memory limit. But we need to know only non-zero *k**x*. For instance, one can gripe coordinates: create list of all occured stops (and also stops 0 and *n*), sort this list, delete the repeated stops and replace all numbers of stops they indexes in this list. After this operations all number of stops not exceed 200001, and all *k**x* are climb to the memory.
+
+Second problem: if we will use loop "for" for counting sum *k**s**i* + *k**s**i* + 1 + ... + *k**t**i* - 1, asymptotic of time of working will be O(m^2). There is an easy way to solve this problem: one can create and update array *sum*[], such that *sum*[*i*] = *k*[0] + *k*[1] + ... + *k*[*i* - 1], by another words, *sum*[0] = 0, *sum*[*i* + 1] = *sum*[*i*] + *k*[*i*].
+
+Then munber of ways to come to stop *t**i* using bus *i* is equal to *sum*[*t**i*] - *sum*[*s**i*].
+
+So time complexity is O(m \cdot log(m)), memory complexity is O(m).
+
+### **5. Vectors (E Div-2, C Div-1)**
+
+Lets formulate the problem in complex number.
+
+Consider complex numbers *a* = *x**A* + *iy**A*, *b* = *x**B* + *iy**B* and *c* = *x**C* + *iy**C*. One can do operation *A* → *A* + *C* and *A* → *iA*.
+
+If we apply this transform some times in some order to *A*, we will get number *A*· *i**k* + *aC* + *biC* - *cC* - *idC* for some non-negative integers *k*, *a*, *b*, *c*, *d* or, in another words, *A*· *i**k* + *aC* + *biC* for *k* = 0, 1, 2, 3 and some integers *a*, *b*. Since *k* can be equal only 0, 1, 2 or 3, sufficiently to get to know is one can to represent *B* - *A*, *B* - *iA*, *B* + *A* or *B* + *iA* in the form of *aC* + *biC*.
+
+Then, how to determine, is one can to represent some complex number D in the such form? One can represent equation *D* = *aC* + *biC* in the form of linear real equation system:
+
+*a*· *x**C* - *b*· *y**C* = *x**D*
+
+*a*· *y**C* + *b*· *x**C* = *y**D*
+
+To solve this system - is standart tehnical problem.
+
+**6. Castle (D Div-1)**
+
+Remunerate vertexes in such a way, that start Gerald vertex have got number 0.
+
+Consider that vertex 0 is the root of tree, and lets consider its children. Let Gerald first go to vertex *x*. Then he must to travel throw hole subtree, otherwise he will not visit all vertex in subtree. Then he come back to 0 and go to some next its child.
+
+Lets try to calculate looked for value for hole tree when we know all subtree values. If we can to do it, we can solve problem using dynamyc programming on the tree.
+
+Lets vertex 0 have *n* children. Lets *i*-th subtree have *k**i* offspring (inclusive *i*-th child of 0).
+
+Let the hole tree consist of *N* vertexes.
+
+Lets *T**i* is the doubled sum of lenght all edges in *i*-th subtree, inclusive edge between 0 and its *i*-th child. It is the time to travel throw hole *i*-th subtree, starting in 0 and returning to 0.
+
+Finally, lets *t**i* is answer to problem on *i*-th subtree. At once we add to this time length of edge between 0 and its *i*-th child.
+
+Lets Gerald travel throw all subtrees in order 1, 2, ..., *n*. What is average time of finding the treasure?
+
+Treasure can be in first subtree with probability . Then average time of finding the treasure will be *t*1.
+
+Treasure can be in second subtree with probability . Then average time of finding the treasure will be *T*1 + *t*2.
+
+And so on. Thus, average time of finding the treasure will be
+
+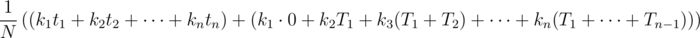
+
+Can we decrease this time? Lets swap *i* and *i* + 1 subtrees. Then item *k**i* + 1*T**i* disappear from sum and appear item *k**iT**i* + 1. Sum will chenge to *k**iT**i* + 1 - *k**i* + 1*T**i*. Sum will decrease, if *k**iT**i* + 1 - *k**i* + 1*T**i* < 0, in ather words .
+
+Therefore, one can't decrease average time, if subtrees are sorted by increasing value .
+
+So, we must to sorted trees in this order and traveling from them in this order.
+
+**7. Candies and Stones. (E Div-1)**
+
+Essence of problem is that there is a board *n* × *m* in cell of wich placed numbers. And one must go from cell (0, 0) to cell (*n* - 1, *m* - 1), doing moves to one cell up and right (that is, increasing by 1 on of coordinates), maximizing sum o number on the cell in the path.
+
+Gerald's problems is determine *m* + *n* - 1 cells of optimal path. Lets start with search one, middle cell. Lets . What cell of board can be *k*-th in path? It is cell, sum of coordinate of wich is equal to *k*, thus, it is diagonal of doard. And then we can calculate, what maximum sum Gerald can collect, came to every cell in the diagonal, by dynamic programming in lower triangle. And the same way, we can calculate, what maximum sum Gerald can collect, came to cell (n-1,m-1), starting from every cell in the diagonal. Sumed up this to values, we calculate, what maximum sum Gerald can collect, came to from cell (0, 0) to cell (*n* - 1, *m* - 1), travel throw every cell in the diagonal. And now we will find cell (*x*, *y*), in wich maximum is reached. It is *k*-th cell of the path. We used time *O*((*n* + *m*)2) and memory *O*(*n* + *m*).
+
+Then we make recursive call on subproblems. In other word, will find optimal path from cell (0, 0) to cell (*x*, *y*) and from cell (*x*, *y*) to cell (*n*, *m*).
+
+It is evident, this solution take memory O(n+m). Why it tkae time O((n+m)^2)?
+
+Lets *n* + *m* is *r*.
+
+Once we are find middle cell of path of length *k*. Twice we are find middle cell of path of length . Four times we are find middle cell of path of length . And so on. Therefore, time of program working will be 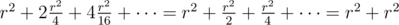. Thus, this solution take time *O*((*n* + *m*)2).
diff --git a/editorials/102.md b/editorials/102.md
@@ -0,0 +1,91 @@
+Source: https://codeforces.com/blog/entry/2393
+
+### **1. Clothes (A Div-2)**
+
+In this problem constraints are allow to look throw all triples of clothes. For every triple one can check if all elements of tripe areturn out to match with others, and anong those triples find one whith minimal cost.
+
+### **2. Sum of digits (B Div-2)**
+
+Initial number consist of no more then 100000 digits. Therefore after first transform resulting number will be no more then 900000, and then it will constist of no more then 6 digits. Thus after next transform number will be no more then 54 and so it will be two-digit or one-digit. Sum of digits of a two-digit number no more, then 18, and sum of digit of such number no more, then 9.
+
+Thus Gerald can't do nore, then 4 transforms. First transform one can implement one simple pass throw symbols of given string. Following operations take very little time.
+
+### **3. Homework (C Div-2, A Div-1)**
+
+Lets count up the number of entries to string of every letter. Let Gerald choose *x* letter and lose them. Obvious thet if he lose *x* rarest letters then overall number of losed letter do not increase, and then if he can lose some *x* lettes, he can lose *x* rarest ones. Thus it's easy to determine if Gerald can loses *x* letters. And now to calculate the answer one only need to find the minimal such *x*, so Gerald can lose *x* letters.
+
+### **4. Buses (D Div-2, B Div-1)**
+
+For every slop from 0 to *n* lets calculate *k**x* - number of ways come to them. Consider the *i*-th bus. Number of ways come to stop *t**i* applied *i*-th bus is uqual to number of way to embus to *i*-th bus.
+
+One can embus to *i*-th bus on the stops *s**i*, *s**i* + 1, ..., *t**i* - 1. Thus number of ways come to stop *t**i* in the *i* bus is equal to sum *k**s**i* + *k**s**i* + 1 + ... + *k**t**i* - 1. Finally, lets note that overall number of way to come to stop *t**i* is the sum of numbers of ways to come to stop *t**i* on every bus.
+
+It's remained two problems. First problem: 0 ≤ *n* ≤ 109. Therefore all *k**x* not climb in memory limit. But we need to know only non-zero *k**x*. For instance, one can gripe coordinates: create list of all occured stops (and also stops 0 and *n*), sort this list, delete the repeated stops and replace all numbers of stops they indexes in this list. After this operations all number of stops not exceed 200001, and all *k**x* are climb to the memory.
+
+Second problem: if we will use loop "for" for counting sum *k**s**i* + *k**s**i* + 1 + ... + *k**t**i* - 1, asymptotic of time of working will be O(m^2). There is an easy way to solve this problem: one can create and update array *sum*[], such that *sum*[*i*] = *k*[0] + *k*[1] + ... + *k*[*i* - 1], by another words, *sum*[0] = 0, *sum*[*i* + 1] = *sum*[*i*] + *k*[*i*].
+
+Then munber of ways to come to stop *t**i* using bus *i* is equal to *sum*[*t**i*] - *sum*[*s**i*].
+
+So time complexity is O(m \cdot log(m)), memory complexity is O(m).
+
+### **5. Vectors (E Div-2, C Div-1)**
+
+Lets formulate the problem in complex number.
+
+Consider complex numbers *a* = *x**A* + *iy**A*, *b* = *x**B* + *iy**B* and *c* = *x**C* + *iy**C*. One can do operation *A* → *A* + *C* and *A* → *iA*.
+
+If we apply this transform some times in some order to *A*, we will get number *A*· *i**k* + *aC* + *biC* - *cC* - *idC* for some non-negative integers *k*, *a*, *b*, *c*, *d* or, in another words, *A*· *i**k* + *aC* + *biC* for *k* = 0, 1, 2, 3 and some integers *a*, *b*. Since *k* can be equal only 0, 1, 2 or 3, sufficiently to get to know is one can to represent *B* - *A*, *B* - *iA*, *B* + *A* or *B* + *iA* in the form of *aC* + *biC*.
+
+Then, how to determine, is one can to represent some complex number D in the such form? One can represent equation *D* = *aC* + *biC* in the form of linear real equation system:
+
+*a*· *x**C* - *b*· *y**C* = *x**D*
+
+*a*· *y**C* + *b*· *x**C* = *y**D*
+
+To solve this system - is standart tehnical problem.
+
+**6. Castle (D Div-1)**
+
+Remunerate vertexes in such a way, that start Gerald vertex have got number 0.
+
+Consider that vertex 0 is the root of tree, and lets consider its children. Let Gerald first go to vertex *x*. Then he must to travel throw hole subtree, otherwise he will not visit all vertex in subtree. Then he come back to 0 and go to some next its child.
+
+Lets try to calculate looked for value for hole tree when we know all subtree values. If we can to do it, we can solve problem using dynamyc programming on the tree.
+
+Lets vertex 0 have *n* children. Lets *i*-th subtree have *k**i* offspring (inclusive *i*-th child of 0).
+
+Let the hole tree consist of *N* vertexes.
+
+Lets *T**i* is the doubled sum of lenght all edges in *i*-th subtree, inclusive edge between 0 and its *i*-th child. It is the time to travel throw hole *i*-th subtree, starting in 0 and returning to 0.
+
+Finally, lets *t**i* is answer to problem on *i*-th subtree. At once we add to this time length of edge between 0 and its *i*-th child.
+
+Lets Gerald travel throw all subtrees in order 1, 2, ..., *n*. What is average time of finding the treasure?
+
+Treasure can be in first subtree with probability . Then average time of finding the treasure will be *t*1.
+
+Treasure can be in second subtree with probability . Then average time of finding the treasure will be *T*1 + *t*2.
+
+And so on. Thus, average time of finding the treasure will be
+
+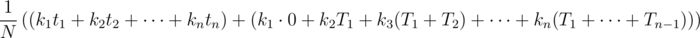
+
+Can we decrease this time? Lets swap *i* and *i* + 1 subtrees. Then item *k**i* + 1*T**i* disappear from sum and appear item *k**iT**i* + 1. Sum will chenge to *k**iT**i* + 1 - *k**i* + 1*T**i*. Sum will decrease, if *k**iT**i* + 1 - *k**i* + 1*T**i* < 0, in ather words .
+
+Therefore, one can't decrease average time, if subtrees are sorted by increasing value .
+
+So, we must to sorted trees in this order and traveling from them in this order.
+
+**7. Candies and Stones. (E Div-1)**
+
+Essence of problem is that there is a board *n* × *m* in cell of wich placed numbers. And one must go from cell (0, 0) to cell (*n* - 1, *m* - 1), doing moves to one cell up and right (that is, increasing by 1 on of coordinates), maximizing sum o number on the cell in the path.
+
+Gerald's problems is determine *m* + *n* - 1 cells of optimal path. Lets start with search one, middle cell. Lets . What cell of board can be *k*-th in path? It is cell, sum of coordinate of wich is equal to *k*, thus, it is diagonal of doard. And then we can calculate, what maximum sum Gerald can collect, came to every cell in the diagonal, by dynamic programming in lower triangle. And the same way, we can calculate, what maximum sum Gerald can collect, came to cell (n-1,m-1), starting from every cell in the diagonal. Sumed up this to values, we calculate, what maximum sum Gerald can collect, came to from cell (0, 0) to cell (*n* - 1, *m* - 1), travel throw every cell in the diagonal. And now we will find cell (*x*, *y*), in wich maximum is reached. It is *k*-th cell of the path. We used time *O*((*n* + *m*)2) and memory *O*(*n* + *m*).
+
+Then we make recursive call on subproblems. In other word, will find optimal path from cell (0, 0) to cell (*x*, *y*) and from cell (*x*, *y*) to cell (*n*, *m*).
+
+It is evident, this solution take memory O(n+m). Why it tkae time O((n+m)^2)?
+
+Lets *n* + *m* is *r*.
+
+Once we are find middle cell of path of length *k*. Twice we are find middle cell of path of length . Four times we are find middle cell of path of length . And so on. Therefore, time of program working will be 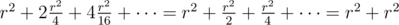. Thus, this solution take time *O*((*n* + *m*)2).
diff --git a/editorials/103.md b/editorials/103.md
@@ -0,0 +1,55 @@
+Source: https://codeforces.com/blog/entry/2426
+
+It will be fully translated later, sorry for slowpoking :(
+
+| | | |
+| --- | --- | --- |
+| | **Blackjack ([problem A, div-2](//codeforces.com/contest/104/problem/A)). The problem's author is [Alex_KPR](https://codeforces.com/profile/Alex_KPR "Подполковник Alex_KPR")** | |
+| | Obviously, suits are not change the answer. Look at all possible situations: [0 - 10] — zero ways. [11] — four ways using aces. [12 - 19] — four ways using cards from 2 to 9. [20] — 15 ways, they are described in statement. [21] — four ways using aces. [22 - 25] — zero ways. | |
+| | Complexity is *O*(1). | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **Testing Pants for Sadness ([problem B, div-2](//codeforces.com/contest/104/problem/B); [problem A, div-1](//codeforces.com/contest/103/problem/A)). The problem's author is [Alex_KPR](https://codeforces.com/profile/Alex_KPR "Подполковник Alex_KPR")** | |
+| | We can't move to the *i* + 1-th question before clicking all answers at *i*-th question. We will move to the very beginning clicking at *a**i* - 1 answers and only one will move us to the next step. Every way from beginning to *i*-th question have length equal to *i* - 1 plus one for click. There is a simple formula for *i* + 1-th question: *c**i* = (*a**i* - 1)· *i* + 1, 1-based numeration. Let's summarize all values of *c**i* for making the answer. | |
+| | Complexity is *O*(*n*). | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **Cthulhu ([problem C, div-2](//codeforces.com/contest/104/problem/C); [problem B, div-1](//codeforces.com/contest/103/problem/B)). The problem's author is [Alex_KPR](https://codeforces.com/profile/Alex_KPR "Подполковник Alex_KPR")** | |
+| | Look at the formal part of statement. Cthulhu is a simple cycle with length of 3 or more and every vertix of the cycle should be a root of some tree. Notice this two important facts: a) Cthulhu is a connected graph b) Cthulhu is a graph with only cycle If we add only one edge to tree (not a multiedge nor loop) then we will get a graph that a) and b) properties. There is a simple solution: let's check graph for connectivity (we can do it by one DFS only) and check *n* = *m* restriction. If all are ok then graph is Cthulhu. | |
+| | Complexity is *O*(*m*). | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **Russian Roulette ([problem D, div-2](//codeforces.com/contest/104/problem/D); [problem C, div-1](//codeforces.com/contest/103/problem/C)). The problem's author is [Alex_KPR](https://codeforces.com/profile/Alex_KPR "Подполковник Alex_KPR")** | |
+| | Let's solve the problem when value *n* is even. Obviously, if *k* = 1 we should put a bullet at most right position. For example, choose *n* = 8 and our answer string will be: .......X Let's find probability of winning at this situation. We will write zeros at losing positions and ones at winning positions: 10101010 The simple idea is to put every next bullet for non-dropping down our winning chance as long as we can. After that we should put bullets in lexicographically order with growing value of *k*. Look for the answer for another *k*'s with *n* = 8: .....X.X ...X.X.X .X.X.X.X .X.X.XXX .X.XXXXX .XXXXXXX XXXXXXXX When *n* is odd our reasoning will be the same with a little bit difference at the beginning. Look at the answer with *n* = 9 and *k* = 1:: ........X 010101010 We may put second bullet as at even case. But there is exists another way, we may put our bullet at **1st** position and turn left the cylinder, look here: X.......X => .......XX 010101010 101010100 Obvioulsy probability of winning was not changed but answer made better. Next steps of putting are equal to even case: .....X.XX ...X.X.XX .X.X.X.XX .X.X.XXXX .X.XXXXXX .XXXXXXXX XXXXXXXXX There is no difficulties to give answers to queries. | |
+| | Complexity is *O*(*p*). | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **Time to Raid Cowavans ([problem E, div-2](//codeforces.com/contest/104/problem/E); [problem D, div-1](//codeforces.com/contest/103/problem/D)). The problem's author is [Alex_KPR](https://codeforces.com/profile/Alex_KPR "Подполковник Alex_KPR")** | |
+| | Let's solve this problem by offline. Read all queries and sort them by increasing *b*. After that there are many effective solutions but I tell you a most simple of them. Look at two following algorithms: 1. For each (*a*, *b*)-query calculate the answer by the simple way: for(int i = a; i < n; i += b) ans += a[i]; 2. Fix the value of *b* and calculate DP for all possible values of *a*: for(int i = n - 1; i >= 0; i--) if (i + b >= n) d[i] = a[i]; else d[i] = d[i + b] + a[i]; Obvioulsy, the 1st algorithm is non-effective with little values of *b* and the 2nd algorithm is non-effecitve with very different values of *b*. Behold that it's impossible to generate the situation where all *b*'s are so little and different simultaniously. There is a simple idea: we may solve the problem by 1st algo if values of *b* are so large (if they are greater than *c*) and solve by 2nd algo if values of *b* are so small (if they are less of equal to *c*). We need to sort our queries because of no reason to calculate DP of any *b* more than once. If we choose *c* equal to that we will get a complexity. | |
+| | Complexity is . | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **Buying Sets ([problem E, div-1](//codeforces.com/contest/103/problem/E)). The problem's author is [winger](https://codeforces.com/profile/winger "Colonel winger")** | |
+| | Translated by [Borisp](https://codeforces.com/profile/Borisp "Lieutenant colonel Borisp"). *[http://codeforces.com/blog/entry/2539](//codeforces.com/blog/entry/2539)* | |
+| | | |
+
+
+
+| | | |
+| --- | --- | --- |
+| | **[Discuss this contest](//codeforces.com/blog/entry/2405)** | |
diff --git a/editorials/104.md b/editorials/104.md
@@ -0,0 +1,9 @@
+Source: https://codeforces.com/blog/entry/2539
+
+This is translation of author's solution of Div 1 problem E of round 80.
+
+Italics are [Borisp](https://codeforces.com/profile/Borisp "Лейтенант-полковник Borisp")'s notes.
+
+| |
+| --- |
+| *This problem's statement and Russian solution is by* [winger](https://codeforces.com/profile/winger "Подполковник winger"). Construct bipartite graph *G*1 with available sets on the left side and the numbers on the right side. We put an edge from a set to all the numbers contained in it. By Hall's theorem it follows from "the union of any k sets contains no less than k distinct numbers (for every positive integer k)" that there exists perfect matching of all the elements in the bipartite graph *(in fact the theorem states that there exists matching including all set vertices, but as the numbers are also restricted by n, this means that there exists perfect matching)*. After this observation we find whichever perfect matching in *G*1,let's denote it by *M* = {(*u**i*, *v**i*)}. Now we construct second oriented graph *G*2 with vertices corresponding to the available sets and edges (*u**i* → *u**j*) for each edge (*u**i*, *v**j*) from *G*1 that do not occur in *M (Note that the matching sets the indices of v's and thus we consider them, not the values of the corresponding numbers)*. Now for every suitable collection of size k there should be no outgoing edge to other set in *G*2 (otherwise the numbers included in the sets of the collection will be k plus the additional few numbers from the corresponding outgoing edges and the collection will not be suitable - more numbers than sets). Thus our problem has been transformed to the following equivalent: in an oriented graph with weight of vertices find subset S of the vertices with minimum sum of weights and without outgoing edge with other end not in S. This problem is known to be equivalent to finding minimum cut *(I wasn't able to prove the equivalence, didn't know it by heart either, but I found it even easier to prove if I consider the task as just max flow)* . Assign to the edges of *G*2 infinite weights, add additional vertices *s* and *t*,. Now for every set *u**i* with weight *w* add edge *u**i* → *t* with weight *w* iff *w* > 0 and edge *s* → *u**i* with weight - *w* iff *w* < 0. The part of the minimum cut of s and t in the constructed graph that contains s is the sought optimal collection *(in fact what I did was sum the outgoing weights from s after computing max flow in the graph; I was able to prove this is the required number)*. |
diff --git a/editorials/105.md b/editorials/105.md
@@ -0,0 +1,88 @@
+Source: https://codeforces.com/blog/entry/2462
+
+**A**. ([link](//codeforces.com/contest/105/problem/A)) In this problem you should do just that is written in the statement. At the first you should read all skills and multiply all levels of them by koefficient *k*. Next you should drop all skills which have level less than 100. After that you should add all new skills from the second list but only those thah are not present in the second list. At the end you should sort all skills by thier names and output them.
+
+***
+
+Problem with precision in this problem a bit shocked an author. This catch was not planned. Author's solution and all verifying solutions use integer arithmetic and think about probably problems didn't occur. In other side, it confirms following rule in the olympiad programming: be careful with comparation of floating numbers and if it is possible do it in integers.
+
+**B.** ([link](//codeforces.com/contest/105/problem/B)) Solution of this problem is search maximum for all cases of sweets' distribution.
+
+Common count of the distributions is *C**k* + *n* - 1*n* - 1, thah id always no mare than 6435. Let us define as current some distribution and calculate values *z**i* = *min*(*l**i* + *c**i* × 0.1, 1.0), where *z**i* is probability that *i*-th senator vote "yes", *l**i* is loyality of senator and *c**i* is number of candies that we should give *i*-th senator.
+
+Now you can calculate propability of success in *O*(2*n**n*). You should iterate ovel all masks of length *n*. 1-bits mean that corresponding senators vote "yes", 0-bits means that ones vote "no". Probability that this mask happen is *m**mask* = *П*(*z**i* × [*i* - *thsenatorvote*"*yes*"] + (1 - *z**i*) × [*i* - *thsenatorvote*"*no*"]), where [true] = 1 and [false] = 0. Now for every mask you should find propability that player's proposal will be approved. It is *s**mask* = 1 if number of votes "yes" more than half of *n* and *s**mask* = *A* / (*A* + *B*) it other case, where *B* is the sum of levels of senators that voted "no". So, propability for current distribution is 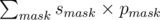.
+
+Solution has complexity *O*(*C**k* + *n* - 1*n* - 12*n**n*).
+
+***
+
+This problem was plannes more harder (like D problem). But later we decided make it more easier))
+
+**C.** ([link](//codeforces.com/contest/105/problem/C)) There you can see that if at least one item has empty slots then you can redistribute the residents in any order. This assertion can be easily proved. In other case you cannot move residents.
+
+Yet another thing that you can see here. In the optimal equipment all items have maximal possible paremeters. Moreover this items with thier residents do not affect each other. So, you can split all items and all residents by thier classes and types and three times solve same problem for groups (weapon, gladiators), (armor, senrties), (orbs, physicians).
+
+So, there are 2 cases: you cannot move residents and you can move ones.
+
+1. For every item you should find its paremeter considering residents that are living inside it. After thah you should choose item that have maximal parameter.
+
+2. Here you should sort all residents by desreasing its bonuses. Next you should iterate over all items, try put maximal count of strongest residents and calculate resulting value of parameter. Now you shouls choose item that have maxumal parameter.
+
+In the second case some catch exists. In the three choosen items you can have more empty slots than you had at the beginning of moving. It is impossible because you cannot drop residents. Therefore you should, for example, put as most as posiible unused residents into empty slots of three choosen items.
+
+***
+
+Initially we planned the first case as catch and put it into pretests, but not into samples. But because contest turned very hard, we put it into samples.
+
+**D.** ([link](//codeforces.com/contest/105/problem/D)) This problem can be solved by data structure like disjoint set union (dsu) with compression paths heuristic.
+
+Every vertex of dsu is geo-panel and every connected component is the set of one-colored geo-panels. All important information stores in the leader of component. It is size of group (count of geo-panels in it), its color and list of geo-symbols in this group that not destroyed.
+
+You should create queue that described in the statement. There you should store geo-symbols. Every symbol is color and position of map where this symbol was placed.
+
+Also yoy should create associative array (like std::map in с++), that returns leader of group in dsu by color of this group.
+
+At last you should create array with size 2*n* × 2*m* and store in it path of infinite spiral. This array you can use for easily sorting geo-symbols before putting its into queue.
+
+This system of data structures allows fast emulate all process.
+
+So, let put the first geo-symbol into queue, generate spiral array and set dsu and associative array into initial state.
+
+Now you can do following operations while queue is not empty:
+
+You should remove geo-symbol from front of queue. Let call it current geo-symbol. By its coordinates using dsu you can find group in which current geo-symbol is placed. Next you should compare colors of group and geo-symbol and understand this group should be repainted or not.
+
+If group should be repainted you should add size of its group to global answer. After that you should sort all geo-symbols in this group using spiral array. In this order you should insert these geo-symbols into back of queue and clear list of qeo-symbols in the group. Now you should repaint group and replace associative array.
+
+You can see that some situation can happen. Now you can have two groups with equal colors (you can fast know it using associative array). These groups chould by united. You should set parent of group that you this moment repainted the second group and increase size of the second group by size of first group.
+
+You can prove that this algorithm works in *O*(*nmlognm*).
+
+**E.** ([link](//codeforces.com/contest/105/problem/E)) At the beginning you should estimate maximal answer what you can get. It equals 42. This answer you can get from following obvious maximal test:
+
+8 10 10
+9 10 10
+10 10 10
+
+Common number of states in which character can be without regard to position is 8. 2 for moved/not-moved multiply to 4 for nobody-lifted/lifted-A/lifted-B/already-threw.
+
+Total number of states is (8 * 42)3 = 37933056. This count of states can be easily stored in memory.
+
+Solution is DFS or BFS from initial state. Maximal position in reached states is answer..
+
+Why it fits into time limits? In fact you can do about 60 moves from every state.
+
+Point is that most of states will be not reached. For example, following heuristics confirm it:
+1. If one character is lifted by another one, thier positions are equal.
+2. States where one characher lifted by both anothers are incorrect.
+3. In positions with big numbers no more than 2 characters can be. In positions with very big numbers no more than 1 character can be.
+
+Also from more states possible little number of moves. They are states in which some characrers already moved or already threw somebody.
+
+You can find exact number of moves only after writing solution. Run on the maxtest shows that number of moves about 2 × 10⁸. So, this solution fits into time limits. You should just accuracy write it.
+
+***
+
+Author's solution on С++ works about 0,3sec. Also we have solutions on Java, whish works 2,8sec and 0,8sec. In the first solution for every move new object is created. It calls some number of garbage collection. In the second solution this problem is fixed. But in order to solutions on Java like the first one pass tests, TL was increased to 3sec.
+
+I'm sorry for delay with thanslation into English.
diff --git a/editorials/106.md b/editorials/106.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/2493
+
+**A.** ([link](//codeforces.com/contest/106/problem/A)) Solution of this problem is written in the fourth paragraph of the statements. You should carefully read and implement it. Only one difficult part is how to to determine which card has higher rank. You can for every card iterate over array [ '6', '7', '8', '9', 'T', 'J', 'Q', 'K', 'A' ] and determine numbers of ranks in this array. Finally, just compare them.
+
+**B.** ([link](//codeforces.com/contest/106/problem/B)) You can create array for all laptops where true for outdated laptop and false otherwise. Value of every cell of this array you can determine by iterating over all laptops and comparing all their parameters. At the end you should itarate over all laptops once again and choose cheapest one that is not outdated.
+
+**C.** ([link](//codeforces.com/contest/106/problem/C)) Let create array dp by size n x m. dp[i][j] means maximum number of tugriks that the baker can earn if he used i grams of dough and cook buns with stuffings of types 1..j.
+
+Initially dp[i][0] is 0 for all i.
+
+You can easily calculate this dp:
+dp[i][j] = max{ dp[i-c[j]*k][j-1] + d[j]*k } for every k from 0 to a[j]/b[j], for which i-c[j]*k>=0
+
+The answer will be max{ dp[k][m] + ((n-k)/c0)*d0 } for every k from 0 to n.
+
+Of course, all divisions in editorial of this problem are integer.
+
+Solution works in O(nma), where a is maximum a_i.
+
+**D.** ([link](//codeforces.com/contest/106/problem/D)) Solution is simulation of all insrtuctions from all of local sights. But naive solution doesn't fit into time limit. You should speed up this solution and do every instruction in O(1).
+
+You can use one of following things.
+
+1. For every position and every direction you can precalculate nearest position of sea. Now before than you do an instruction you should check that nearest position of sea further than position whereto you move after doing the instruction.
+
+2. Let sea cells have 1 and all other ones have 0. For every cell (i,j) you can calculate sum of all cells in the rectangle with angles in (1,1) and (i,j). It can be done by the operations like:
+sum[i][j] = sum[i-1][j] + sum[i][j-1] - sum[i-1][j-1] + smth
+where smth is 0 or 1 according to type of according cell (i,j). Now you can determine sum of numbers for all rectangles of the map. Before you do instruction you should chech that sum of rectangle on which you will go has sum 0.
+
+Solution has complexity O(nm + kz), where z is number of local sights (this number no more than 26).
+
+**E.** ([link](//codeforces.com/contest/106/problem/E)) Author's solution is three ternary search for every demension that are nested within each other.
+
+It works because the function is convex. Maximum of convex functions also convex function. Author not very well imagine convex function in 3 dimrnsions, therefore you can read following proof that algorithm is correct:
+
+Let consider some straight line. Function of distance between points on this line and planet position will be convex (you can imagine it). If you get maximum of such functions it will be convex function too. Let's call this function f1.
+
+Now let's consider flat plane and choose one straight line in it. Set for every point of this line a minumum of function f1 of line that passes through this point and is perpendicular to choosen line. Let's call function on this choosen line f2.
+
+f2 is convex. It can be easily proved by contrary. If f2 is not convex, we can find at least two local minimums. Let's choose two neighbour of them. We can find this two minimums on the plane and drawn through them new line. f1 on this line will be not convex (you also can imagine it). Сontradiction.
+
+Now let's consider all space. Choose one line in it and define function f3 on it. Values of f3 will be minimums of functions f2 of planes that passes through the line and is perpendicular to it. f3 also is convex. Proof of it is analogically to that is written in the previous paragraph. []
+
+Now you can see that minimum can ge found by three ternary search over functions fi. You can add to these functions returning of value in which they reach a minimum.
+
+Also there are solutions that uses idea of Gradient descent or Hill climbing. Author was unable to write this solution (not enough precision), but some participants got AC with such solutions.
+
+There is exact solution O(n^4) (more exactly O(C_n^4)). This solution uses Helly's theorem and Jung's theorem that follows from the first one:
+[http://en.wikipedia.org/wiki/Helly's_theorem](https://en.wikipedia.org/wiki/Helly%27s_theorem)
+In this solution you should itarate over all pairs, triples and fours of points and for every of them build minimal ball that cover them. Answer is center of ball with maximum radius.
+
+Also you can google something like that
+<http://www.inf.ethz.ch/personal/gaertner/miniball.html>
+There are code and article, but the author of contest is not particularly delved into them))
diff --git a/editorials/107.md b/editorials/107.md
@@ -0,0 +1,143 @@
+Source: https://codeforces.com/blog/entry/2514
+
+### [Palindromic Times](//codeforces.com/contest/108/problem/A)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+In this problem it was required to find next palindrome on a digital clock. Since the lowest unit of time used 1 minute, and there are only 24 * 60 minutes in a day, one could simply go through each minute starting from the time given in the input plus 1 minute, until finding a palindrome. If no palindrome is found till the end of the day 23: 59, the output should then be 00: 00.
+
+---
+
+### [Datatypes](//codeforces.com/contest/108/problem/B)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+Let us call a pair of datatypes (*a*, *b*), where *a* < *b*, *BAD* if and only if there exists a number *x* where *x* fits in *a* bits but *x* * *x* does not fit in *b* bits. The following observation helps in finding a solution to the problem. The best candidate for the number *x* is the largest number fitting in *a* bits, which is *x* = 2*a* - 1. So for each *a**i* it is enough to check that the smallest *a**j* > *a**i* has enough bits to contain *x* * *x* = (2*a* - 1) * (2*a* - 1), which has at most 2 * *a* bits. Sorting the numbers first was needed to traverse the list of datatypes once and ensuring the condition above.
+
+---
+
+### [Dorm Water Supply](//codeforces.com/contest/108/problem/C)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+The problem describes a graph of houses as nodes and one-way pipes as edges. The problem states that the graph will contain 1 or more chains of nodes. The required is to find the start and end of every chain (consisting of more than 1 node, which caused many hacks). The other requirement was to find the weakest edge in each of the chains. This can be done by traversing (using Depth-First Search (DFS) for example) the graph from each un-visited node with no incoming edges. These nodes are the *start* of a chain. By keeping track of the *minimum* *diameter* so far, whenever the DFS reaches a node with no outgoing edges, it means that this node is the *end* of the current chain. After storing, in a list or vector, the tuples (*start*, *end*, *minimum* *diameter*), we sort these tuples by start index and print.
+
+---
+
+### [Basketball Team](https://codeforces.com/problemset/problem/107/B)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+This problem is asking for the probability. Consider two sets of teams: the set of teams where Herr Wafa is the only student from his major and the set where at least one other student from Herr Wafa's major is present. These two sets don't intersect, so once we can compute the number of teams in the first set, A, and the number of teams in the second set, *B*, the answer would be *B* / (*A* + *B*).
+
+The number of teams in the first set is A = 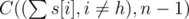. We subtract one as Herr Wafa is guaranteed the spot, and the other (*n* - 1) spots are to be taken by the remaining 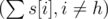 students.
+
+Now let's count the number of teams having exactly *k* students from Herr Wafa's major apart from him. This number would be 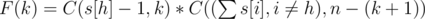. Much like for the first set, (*n* - (*k* + 1)) students from the other majors should he selected, and none of them should be from Herr Wafa's major. The total number of teams where at least one other student is from Herr Wafa's major is therefore 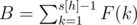.
+
+The statements above describe the mathematical solution. It can be implemented in various ways.
+
+---
+
+### [Crime Management](https://codeforces.com/problemset/problem/107/D)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+At the first glance the upper limit for *n* being 1018 looks huge. But in fact, combined with the fact, that the answer should be output modulo 12345, it's should not scare you but rather hint that the problem has a DP approach.
+
+Like all DP problems the way to approach it is to split the problem into sub-problems and figure out what extra information should be carried between the sub-problems in order to combine them into the solution to the whole problem.
+
+Say, *n* is 11 and we solved the problem for the first 10 crimes. Clearly, just the number of ways to commit the first 10 crimes is not enough to solve the full problem with *n* = 11. The extra information to be carried along with the number of ways to commit n crimes and be innocent is the following: the number of ways to commit the first *n* crimes and have remaining multiplicities *d*1, *d*2, ...*d*26 respectively. The fact that the product of the multiplicities does not exceed 123 makes this a solvable task, as the set of all possible remainders contains not more elements than the product of multiplicities.
+
+To illustrate the idea from the first paragraph consider the first example case. It has two constraints, A with multiplicity 1 and B with multiplicity 2. The remainder of the number of crimes of type A is always zero, and committing crimes of type A may not yield any punishment. The remainder of the number of crimes of type B is zero or one. Therefore, while solving the sub-problems for the first *n*2 < = *n* crimes, it's enough to keep track of only two numbers: "number of ways to commit *n*2 crimes and be completely innocent" and "number of ways to commit *n*2 crimes and have committed one 'extra' crime of type B".
+
+The key step to solve the problem now is to notice that each transition from the solution for the first *k* crimes to the solution for the first (*k* + 1) crimes can be seen as multiplying the vector of the current state by the transition matrix. Once all possible transitions are converted to the matrix form, the problem can be solved by raising the matrix into n-th power. Raising the matrix into large power can be done efficiently using matrix exponentiation: on some steps instead of computing *A**i* + 1 = *A**i*· *A*0 one can compute *A*2*i* = *A**i*· *A**i*.
+
+The last trick of this problem is to deal with multiple allowed multiplicities. If they were not allowed, the remainders per each crime type could have been kept with the modulo being equal to the multiplicity for this crime type. Moreover, if no crime type is listed more than once, the only valid final state is the state where the remainders are zero across all the crime types.
+
+With multiple allowed multiplicities, for each crime type the remainder modulo the product of the multiplicities of crimes for this type should be kept. (Strictly speaking, LCM is enough, but the constraints allow to use the plain product instead). Then, at the stage of printing the output, instead of treating the counter for the state with zero remainders as the only contributor to the output, one would have to iterate through all possible states and verify if each set of remainders conducts a valid final state.
+
+---
+
+### [Arrangement](https://codeforces.com/problemset/problem/107/C)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+The problem asks for finding the lexicographically *n*-th permutation satisfying the input constraints.
+
+The trick which confused many contestants, as well as a few authors and testers, is that instead of having the restrictions formulated in a way *position*[*a*[*i*]] < *position*[*b*[*i*]] the restrictions were *element at position[a[i]] < element at position[b[i]]*.
+
+As in most problems where one has to output lexicographically *n*-th answer, the idea which can result in the solution which is passing the systests is to learn how to compute the number of solutions satisfying certain constraints.
+
+We will speak about how to compute the number of solutions in a bit, but first let's understand how having such function would lead to a solution. The very first observation is: if the total number of possible solutions is less than *y* - 2000, then the answer is "The times have changed". Once we have ensured that the solution exists it can be found using some of search.
+
+A simple approach would be the following: fix the first element of the resulting permutation to be 1 and count the number of possible solutions. If we do have enough to reach year *y*, then the first element must be 1, because there exists enough permutations with the first element being 1 to cover the years up to *y*, and any permutation where the first element is not 1 comes after any permutation where the first element is 1 in lexicographical order.
+
+And if fixing the first element to be 1 is not giving enough permutations, then we should decrease the "desired" year by the number of solutions with 1 being fixed as the first element and start looking for the solutions with 2 as the first element. The intuition is that there are not enough solutions with 1 being the first element, but once we acknowledge that and start looking for the other solutions --- with 2 as the first element, we are speaking not about arrangements for years *2001* and onwards but about the years *2001 + number of solutions with first element being one* and onwards. Therefore instead of looking for the permutation with index *y* - 2001 with the first element being 1 we are looking for the permutation with the lower index, *y - 2001 - number of solutions with first element being one*, with the first element being 2 or higher.
+
+This process should be continued until all the elements are identified. Once the first index is fixed the known prefix would become a two-numbers prefix, and it will grow until all the permutation is constructed.
+
+Now to complete the solution we need to be able to compute the number of permutations which satisfy two restrictions: the input constraints and the added "*permutation has prefix P"* constraint. This problem can be solved using DP.
+
+For a given prefix *P* of length *m*, *(n-m)* other elements should be placed.
+
+Assume first that we are going to be iterating over all possible permutations with the given prefix using the brute force, but, instead of trying each possible value for the element at the next empty position *i*, we would be trying each possible position for the next not-yet-placed element *i*. This approach would work, but in *O*((*n* - *m*)!) time, which is obviously unfeasible. We need to find some way to reduce the state space and make it run faster.
+
+The key observation is the following: the state of the partially solved problem can be completely described by the bitmask of the currently occupied positions. This statement is nontrivial, as, from the first glance, it seems that apart from the unused positions mask, the information about the order, in which the already-placed elements are placed, is important. However it's not. Recall that all the constraints have the form of "element at position *a**i* is less than the element at position *b**i*". Provided the elements are placed in increasing order, in order to satisfy each constraint it's enough to confirm that, if the element to be placed is being put into position *i*, there is no such constraint in the input, that the element at position *i* should be less than the element at position *j*, while the element at position *j* has already been placed.
+
+This approach results in the DP with 2*n* - *m* states. Note that the next element to be placed can always be determined by the number of bits set in the mask and the prefix elements.
+
+The implementation of the above algorithm requires nontrivial coding, as the elements, belonging to the prefix, have to be treated differently compared to the elements which were placed by the DP. This is because the DP is enforcing that the elements are always added in the increasing order, which does not have to be the case for the elements conducting the prefix.
+
+---
+
+### [Darts](https://codeforces.com/problemset/problem/107/E)
+
+Writer: [Dima](https://codeforces.com/profile/Dima "Captain Dima")
+
+Before doing the coding let's do some math. The answer to this problem can be computed as *the total area of all input rectangles / the area of the union of all input rectangles*.
+
+One of the easy ways to understand it is the following. First notice that if all the rectangles are the same, the answer is always the number of rectangles. Now forget that the input figures are rectangles, assume any shape is allowed, and then try to construct the example case given the union area *s* and the resulting expected score *e*. Notice that you can start with any shape constructed of non-intersecting figures with the total area *s*, and then add more figures on top of these, such that the contour of the union is the same as the contour of the first original figure of area *s*. Specifically, you'd need to add some figures of the total sum of *t* = *s*· (*e* - 1), but the number doesn't matter here. The key is that the placement of these added figures doesn't change the result, and therefore the answer will always depend only on the total area of the input figures and the area of their union.
+
+Now back to the rectangles. Computing the sum of the ares of the rectangles is easy. The hard part is to compute the area of their union in better than *O*(*n*3). Note that the union may have multiple disjoins components, it does not have to be convex, it may have holes and, in short, does not have to be easy to describe.
+
+One of the relatively-easy-to-implement solutions is the following. We will be computing the are of the union of the rectangles using the trapezoid method. Note that for the trapezoid method the order, in which the segments of the figure are provided, doesn't matter. Therefore, in order to use the trapezoid method, we "only" need to find all non-vertical directed segments which are the part of the contour of the union.
+
+Let me elaborate a bit more on the previous paragraph. We don't need vertical segments, because their contribution to the resulting area is zero in the trapezoid method of computing the area. The direction of the segment is the important part though. It's not enough to know that the segment (*x*1, *x*2) - (*y*1, *y*2) belongs to the contour of the union. It's important to know whether the area of the union if the part of the plane above it or below it.
+
+Imagine the test case where the union of all the rectangles is a big rectangle with a hole inside it. In this case we need to know that the segments, describing the outer part of the union, should contribute to the area with the "plus" sign, while the segments describing the inner hole should be considered with the "minus" sign.
+
+Specifically, for the trapezoid method, the sign of *x*2 - *x*1 would be describing the direction of this segment: for example, if *x*1 < *x*2 than the segment is "positive" and if *x*1 < *x*2 it's "negative".
+
+To find all such segments let's consider all distinct non-vertical lines. There are at most 4*n* such lines in the input. Each segment of the final contour of the union should lay on one of those lines, so it's enough to focus on the lines only, consider them independently from each other (but make sure to process each distinct line only once!) and for each line construct a set of the positive and negative segments.
+
+Let's formulate the rules under which a part of the line would be a positive or negative segment. They turn out to be very simple:
+
+1) If some segment (*x*1, *y*1) - (*x*2, *y*2) is part of the border of one of the input rectangles, then it's a "positive" segment if this input rectangle lays below this segment and a "negative" segment if this rectangle lays above this segment.
+
+2) If some segment (*x*1, *y*1) - (*x*2, *y*2) belongs to the intersection of the borders of two different input rectangles, with one being a "positive" one and one being a "negative" one, then this segment does not belong to the contour.
+
+3) If some segment (*x*1, *y*1) - (*x*2, *y*2) is being covered by another rectangle, then it does not belong to the contour. "Covered" means laying completely inside some other rectangle, the border cases are covered above.
+
+The easy way of constructing all the segments could look as the following pseudo-code:
+
+**for each distinct non-vertical line**
+
+**create the array of markers. the marker holds the x coordinate and one of four events: { start union area below, end union area below, start union area above, end union area above }.**
+
+**iterate through all the input rectangles**
+
+**if this rectangle has one segment laying on the line under consideration**
+
+**add two markers: one for start and one for end. whether the markers are above or below is determined by the position of this rectangle with respect to this line**
+
+**else if this rectangle intersects this line**
+
+**find the intersection points and add four markers: { start area below } and { start area above } for the left intersection point and { end area below } and { end area above } for the right intersection point**
+
+**sort the array of markers by the x coordinate of the events**
+
+**traverse the array of markers. if some segment (*x*1..*x*2) is being reported as having the union area only above it or only below it, it becomes the negative or positive segment of the union respectively.**
+
+At this point one could run some sort of DFS to merge the segments into the connected loops, but this is actually unnecessary to compute the area using the trapezoid method. Just summing up (*x*2 - *x*1)· (*y*1 + *y*2) / 2 for all the segments does the trick, and it would automatically ensure that the outer contours are taken with the positive sign and the inner contours are taken with the negative sign.
+
+The solution described above runs in *O*(*n*2· *logn*) : for each of *O*(*n*) lines we have at most *O*(*n*) intersections, which should be sorted in *O*(*n*· *logn*) inside the loop over all the lines.
diff --git a/editorials/108.md b/editorials/108.md
@@ -0,0 +1,143 @@
+Source: https://codeforces.com/blog/entry/2514
+
+### [Palindromic Times](//codeforces.com/contest/108/problem/A)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+In this problem it was required to find next palindrome on a digital clock. Since the lowest unit of time used 1 minute, and there are only 24 * 60 minutes in a day, one could simply go through each minute starting from the time given in the input plus 1 minute, until finding a palindrome. If no palindrome is found till the end of the day 23: 59, the output should then be 00: 00.
+
+---
+
+### [Datatypes](//codeforces.com/contest/108/problem/B)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+Let us call a pair of datatypes (*a*, *b*), where *a* < *b*, *BAD* if and only if there exists a number *x* where *x* fits in *a* bits but *x* * *x* does not fit in *b* bits. The following observation helps in finding a solution to the problem. The best candidate for the number *x* is the largest number fitting in *a* bits, which is *x* = 2*a* - 1. So for each *a**i* it is enough to check that the smallest *a**j* > *a**i* has enough bits to contain *x* * *x* = (2*a* - 1) * (2*a* - 1), which has at most 2 * *a* bits. Sorting the numbers first was needed to traverse the list of datatypes once and ensuring the condition above.
+
+---
+
+### [Dorm Water Supply](//codeforces.com/contest/108/problem/C)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+The problem describes a graph of houses as nodes and one-way pipes as edges. The problem states that the graph will contain 1 or more chains of nodes. The required is to find the start and end of every chain (consisting of more than 1 node, which caused many hacks). The other requirement was to find the weakest edge in each of the chains. This can be done by traversing (using Depth-First Search (DFS) for example) the graph from each un-visited node with no incoming edges. These nodes are the *start* of a chain. By keeping track of the *minimum* *diameter* so far, whenever the DFS reaches a node with no outgoing edges, it means that this node is the *end* of the current chain. After storing, in a list or vector, the tuples (*start*, *end*, *minimum* *diameter*), we sort these tuples by start index and print.
+
+---
+
+### [Basketball Team](https://codeforces.com/problemset/problem/107/B)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+This problem is asking for the probability. Consider two sets of teams: the set of teams where Herr Wafa is the only student from his major and the set where at least one other student from Herr Wafa's major is present. These two sets don't intersect, so once we can compute the number of teams in the first set, A, and the number of teams in the second set, *B*, the answer would be *B* / (*A* + *B*).
+
+The number of teams in the first set is A = 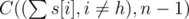. We subtract one as Herr Wafa is guaranteed the spot, and the other (*n* - 1) spots are to be taken by the remaining 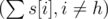 students.
+
+Now let's count the number of teams having exactly *k* students from Herr Wafa's major apart from him. This number would be 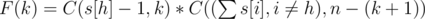. Much like for the first set, (*n* - (*k* + 1)) students from the other majors should he selected, and none of them should be from Herr Wafa's major. The total number of teams where at least one other student is from Herr Wafa's major is therefore 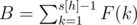.
+
+The statements above describe the mathematical solution. It can be implemented in various ways.
+
+---
+
+### [Crime Management](https://codeforces.com/problemset/problem/107/D)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+At the first glance the upper limit for *n* being 1018 looks huge. But in fact, combined with the fact, that the answer should be output modulo 12345, it's should not scare you but rather hint that the problem has a DP approach.
+
+Like all DP problems the way to approach it is to split the problem into sub-problems and figure out what extra information should be carried between the sub-problems in order to combine them into the solution to the whole problem.
+
+Say, *n* is 11 and we solved the problem for the first 10 crimes. Clearly, just the number of ways to commit the first 10 crimes is not enough to solve the full problem with *n* = 11. The extra information to be carried along with the number of ways to commit n crimes and be innocent is the following: the number of ways to commit the first *n* crimes and have remaining multiplicities *d*1, *d*2, ...*d*26 respectively. The fact that the product of the multiplicities does not exceed 123 makes this a solvable task, as the set of all possible remainders contains not more elements than the product of multiplicities.
+
+To illustrate the idea from the first paragraph consider the first example case. It has two constraints, A with multiplicity 1 and B with multiplicity 2. The remainder of the number of crimes of type A is always zero, and committing crimes of type A may not yield any punishment. The remainder of the number of crimes of type B is zero or one. Therefore, while solving the sub-problems for the first *n*2 < = *n* crimes, it's enough to keep track of only two numbers: "number of ways to commit *n*2 crimes and be completely innocent" and "number of ways to commit *n*2 crimes and have committed one 'extra' crime of type B".
+
+The key step to solve the problem now is to notice that each transition from the solution for the first *k* crimes to the solution for the first (*k* + 1) crimes can be seen as multiplying the vector of the current state by the transition matrix. Once all possible transitions are converted to the matrix form, the problem can be solved by raising the matrix into n-th power. Raising the matrix into large power can be done efficiently using matrix exponentiation: on some steps instead of computing *A**i* + 1 = *A**i*· *A*0 one can compute *A*2*i* = *A**i*· *A**i*.
+
+The last trick of this problem is to deal with multiple allowed multiplicities. If they were not allowed, the remainders per each crime type could have been kept with the modulo being equal to the multiplicity for this crime type. Moreover, if no crime type is listed more than once, the only valid final state is the state where the remainders are zero across all the crime types.
+
+With multiple allowed multiplicities, for each crime type the remainder modulo the product of the multiplicities of crimes for this type should be kept. (Strictly speaking, LCM is enough, but the constraints allow to use the plain product instead). Then, at the stage of printing the output, instead of treating the counter for the state with zero remainders as the only contributor to the output, one would have to iterate through all possible states and verify if each set of remainders conducts a valid final state.
+
+---
+
+### [Arrangement](https://codeforces.com/problemset/problem/107/C)
+
+Writer: [Atef](https://codeforces.com/profile/Atef "Captain Atef")
+
+The problem asks for finding the lexicographically *n*-th permutation satisfying the input constraints.
+
+The trick which confused many contestants, as well as a few authors and testers, is that instead of having the restrictions formulated in a way *position*[*a*[*i*]] < *position*[*b*[*i*]] the restrictions were *element at position[a[i]] < element at position[b[i]]*.
+
+As in most problems where one has to output lexicographically *n*-th answer, the idea which can result in the solution which is passing the systests is to learn how to compute the number of solutions satisfying certain constraints.
+
+We will speak about how to compute the number of solutions in a bit, but first let's understand how having such function would lead to a solution. The very first observation is: if the total number of possible solutions is less than *y* - 2000, then the answer is "The times have changed". Once we have ensured that the solution exists it can be found using some of search.
+
+A simple approach would be the following: fix the first element of the resulting permutation to be 1 and count the number of possible solutions. If we do have enough to reach year *y*, then the first element must be 1, because there exists enough permutations with the first element being 1 to cover the years up to *y*, and any permutation where the first element is not 1 comes after any permutation where the first element is 1 in lexicographical order.
+
+And if fixing the first element to be 1 is not giving enough permutations, then we should decrease the "desired" year by the number of solutions with 1 being fixed as the first element and start looking for the solutions with 2 as the first element. The intuition is that there are not enough solutions with 1 being the first element, but once we acknowledge that and start looking for the other solutions --- with 2 as the first element, we are speaking not about arrangements for years *2001* and onwards but about the years *2001 + number of solutions with first element being one* and onwards. Therefore instead of looking for the permutation with index *y* - 2001 with the first element being 1 we are looking for the permutation with the lower index, *y - 2001 - number of solutions with first element being one*, with the first element being 2 or higher.
+
+This process should be continued until all the elements are identified. Once the first index is fixed the known prefix would become a two-numbers prefix, and it will grow until all the permutation is constructed.
+
+Now to complete the solution we need to be able to compute the number of permutations which satisfy two restrictions: the input constraints and the added "*permutation has prefix P"* constraint. This problem can be solved using DP.
+
+For a given prefix *P* of length *m*, *(n-m)* other elements should be placed.
+
+Assume first that we are going to be iterating over all possible permutations with the given prefix using the brute force, but, instead of trying each possible value for the element at the next empty position *i*, we would be trying each possible position for the next not-yet-placed element *i*. This approach would work, but in *O*((*n* - *m*)!) time, which is obviously unfeasible. We need to find some way to reduce the state space and make it run faster.
+
+The key observation is the following: the state of the partially solved problem can be completely described by the bitmask of the currently occupied positions. This statement is nontrivial, as, from the first glance, it seems that apart from the unused positions mask, the information about the order, in which the already-placed elements are placed, is important. However it's not. Recall that all the constraints have the form of "element at position *a**i* is less than the element at position *b**i*". Provided the elements are placed in increasing order, in order to satisfy each constraint it's enough to confirm that, if the element to be placed is being put into position *i*, there is no such constraint in the input, that the element at position *i* should be less than the element at position *j*, while the element at position *j* has already been placed.
+
+This approach results in the DP with 2*n* - *m* states. Note that the next element to be placed can always be determined by the number of bits set in the mask and the prefix elements.
+
+The implementation of the above algorithm requires nontrivial coding, as the elements, belonging to the prefix, have to be treated differently compared to the elements which were placed by the DP. This is because the DP is enforcing that the elements are always added in the increasing order, which does not have to be the case for the elements conducting the prefix.
+
+---
+
+### [Darts](https://codeforces.com/problemset/problem/107/E)
+
+Writer: [Dima](https://codeforces.com/profile/Dima "Captain Dima")
+
+Before doing the coding let's do some math. The answer to this problem can be computed as *the total area of all input rectangles / the area of the union of all input rectangles*.
+
+One of the easy ways to understand it is the following. First notice that if all the rectangles are the same, the answer is always the number of rectangles. Now forget that the input figures are rectangles, assume any shape is allowed, and then try to construct the example case given the union area *s* and the resulting expected score *e*. Notice that you can start with any shape constructed of non-intersecting figures with the total area *s*, and then add more figures on top of these, such that the contour of the union is the same as the contour of the first original figure of area *s*. Specifically, you'd need to add some figures of the total sum of *t* = *s*· (*e* - 1), but the number doesn't matter here. The key is that the placement of these added figures doesn't change the result, and therefore the answer will always depend only on the total area of the input figures and the area of their union.
+
+Now back to the rectangles. Computing the sum of the ares of the rectangles is easy. The hard part is to compute the area of their union in better than *O*(*n*3). Note that the union may have multiple disjoins components, it does not have to be convex, it may have holes and, in short, does not have to be easy to describe.
+
+One of the relatively-easy-to-implement solutions is the following. We will be computing the are of the union of the rectangles using the trapezoid method. Note that for the trapezoid method the order, in which the segments of the figure are provided, doesn't matter. Therefore, in order to use the trapezoid method, we "only" need to find all non-vertical directed segments which are the part of the contour of the union.
+
+Let me elaborate a bit more on the previous paragraph. We don't need vertical segments, because their contribution to the resulting area is zero in the trapezoid method of computing the area. The direction of the segment is the important part though. It's not enough to know that the segment (*x*1, *x*2) - (*y*1, *y*2) belongs to the contour of the union. It's important to know whether the area of the union if the part of the plane above it or below it.
+
+Imagine the test case where the union of all the rectangles is a big rectangle with a hole inside it. In this case we need to know that the segments, describing the outer part of the union, should contribute to the area with the "plus" sign, while the segments describing the inner hole should be considered with the "minus" sign.
+
+Specifically, for the trapezoid method, the sign of *x*2 - *x*1 would be describing the direction of this segment: for example, if *x*1 < *x*2 than the segment is "positive" and if *x*1 < *x*2 it's "negative".
+
+To find all such segments let's consider all distinct non-vertical lines. There are at most 4*n* such lines in the input. Each segment of the final contour of the union should lay on one of those lines, so it's enough to focus on the lines only, consider them independently from each other (but make sure to process each distinct line only once!) and for each line construct a set of the positive and negative segments.
+
+Let's formulate the rules under which a part of the line would be a positive or negative segment. They turn out to be very simple:
+
+1) If some segment (*x*1, *y*1) - (*x*2, *y*2) is part of the border of one of the input rectangles, then it's a "positive" segment if this input rectangle lays below this segment and a "negative" segment if this rectangle lays above this segment.
+
+2) If some segment (*x*1, *y*1) - (*x*2, *y*2) belongs to the intersection of the borders of two different input rectangles, with one being a "positive" one and one being a "negative" one, then this segment does not belong to the contour.
+
+3) If some segment (*x*1, *y*1) - (*x*2, *y*2) is being covered by another rectangle, then it does not belong to the contour. "Covered" means laying completely inside some other rectangle, the border cases are covered above.
+
+The easy way of constructing all the segments could look as the following pseudo-code:
+
+**for each distinct non-vertical line**
+
+**create the array of markers. the marker holds the x coordinate and one of four events: { start union area below, end union area below, start union area above, end union area above }.**
+
+**iterate through all the input rectangles**
+
+**if this rectangle has one segment laying on the line under consideration**
+
+**add two markers: one for start and one for end. whether the markers are above or below is determined by the position of this rectangle with respect to this line**
+
+**else if this rectangle intersects this line**
+
+**find the intersection points and add four markers: { start area below } and { start area above } for the left intersection point and { end area below } and { end area above } for the right intersection point**
+
+**sort the array of markers by the x coordinate of the events**
+
+**traverse the array of markers. if some segment (*x*1..*x*2) is being reported as having the union area only above it or only below it, it becomes the negative or positive segment of the union respectively.**
+
+At this point one could run some sort of DFS to merge the segments into the connected loops, but this is actually unnecessary to compute the area using the trapezoid method. Just summing up (*x*2 - *x*1)· (*y*1 + *y*2) / 2 for all the segments does the trick, and it would automatically ensure that the outer contours are taken with the positive sign and the inner contours are taken with the negative sign.
+
+The solution described above runs in *O*(*n*2· *logn*) : for each of *O*(*n*) lines we have at most *O*(*n*) intersections, which should be sorted in *O*(*n*· *logn*) inside the loop over all the lines.
diff --git a/editorials/109.md b/editorials/109.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/2547
+
+1. [Lucky Number](https://codeforces.com/contest/110/problem/A) (Div2 A)
+
+In this problem you just need to find a number of lucky digits in *n* and output *YES* if it number is equal to 4 or 7, *NO* otherwise.
+
+2. [Lucky String](https://codeforces.com/contest/110/problem/B) (Div2 B)
+
+To solve this problem you need to notice that result is a prefix of string *abcdabcdabcd*...*abcd* and output first *n* characters of this string.
+
+3. [Lucky Sum of Digits](https://codeforces.com/contest/109/problem/A) (Div1 A, Div2 C)
+
+Let result number contains *a* digits 4 and *b* digits 7. Obviously, that *a* * 4 + *b* * 7 = *n*. Loop through all values of *b*. If we know *b*, we can calculate *a*, . Among all pairs (*a*;*b*) we need to choose one with *a* + *b* minimum. Among all that pairs we need to choose one with *b* minimum. Output will be an integer 444...444777...777, here number of digits 4 equal to *a*, number of digits 7 equal to *b*.
+
+4. [Lucky Probability](https://codeforces.com/contest/109/problem/B) (Div1 B, Div2 D)
+
+Let *L*[*i*] - *i*-th lucky number, starting from 1 (*L*[0] = 0, *L*[1] = 4, *L*[2] = 7...). At first choose first *k* lucky number, then second *k* numbers and so on. For each of that group lets find answer, result will be a sum of each of this probabilities. Let index of current first number if *i*, last - *j* (*j* = *i* + *k* - 1). Then we need to find intersection of intervals [*p**l*;*p**r*] and (*L*[*i* - 1];*L*[*i*]], and also [*v**l*;*v**r*] and [*L*[*j*];*L*[*j* + 1]), product of that values will be a number of ways in which *p* < *v*, similarly for *p* > *v*. Sum of all that values for each group will be a total number of ways, then result = total number of ways / ((*p**r* - *p**l* + 1) * (*v**r* - *v**l* + 1)).
+
+5. [Lucky Tree](https://codeforces.com/contest/109/problem/C) (Div1 C, Div2 E)
+
+Solve this problem using dynamic programming. Consider that root of a tree is vertex with number 1. Let *F*(*x*) - number of vertex in subtree of vertex *x* for which there is a path containing lucky edge. We will calculate *F*(*x*) using recursion. If *x* is a leaf, than *F*(*x*) = 0. Else, if there is an edge from *x* that leads to *y* and this edge is lucky, then to *F*(*x*) we need to add *C*(*y*), otherwise we add *F*(*y*), here *C*(*y*) - number of vertex in subtree of *y*, including *y*. But, to solve this problem we need to know also *F*'(*x*) - number of vertex which are not in subtree of *x* and there exits a path from *x* to that vertex that contains lucky edge. For a root of tree, *F*'(*x*) equals to 0. We should go recursive from root, and if we are in vertex *x* now, we suppose that *F*'(*x*) is already calculated. If from *x* we can directly go to *y* and that edge is lucky, then *F*'(*y*) = *C*(0) - *C*(*y*), otherwise *F*'(*y*) = *F*'(*x*) + *F*(*x*) - *F*(*y*).
+
+After that, result equals to 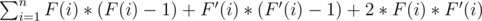.
+
+6. [Lucky Sorting](https://codeforces.com/contest/109/problem/D)(Div1 D)
+
+At first, if our array is already sorted, just return 0. Otherwise, if there is no lucky number in *A*, then output - 1. Otherwise, let *B* is sorted *A* (array from input). Now, for all numbers in *A* we know a final position in *B*. Let *k* is an index of minimal lucky number in *A*. If we want to place integer from position *i* to *j*, we need *A*[*j*] to be lucky number. If is not so, we just *Swap*(*A*[*j*], *A*[*k*]), then *A*[*j*] contains lucky number. After that we can *Swap*(*A*[*i*], *A*[*j*]) and number *A*[*i*] is on position *j*. So, to place one number to it's position in *B*, we need at most two operations and total number that replacements will be not more than *n*, so answer'll contain at most 2*n* operations.
+
+7. [Lucky Interval](https://codeforces.com/contest/109/problem/E) (Div1 E)
+
+That is only onw variation of solution, there are diffrent other, which uses same thinking.
+
+With constraints for *a* and *b* to 107 problem can be solved using KMP algorithm: consider a string *F*(1)*F*(2)*F*(3)*F*(4)...*F*(3 * 107). We need to find first occurrence after index *a* of string *F*(*a*)*F*(*a* + 1)*F*(*a* + 2)...*F*(*a* + *l* - 1). Complexity of that algorithm is *O*(*a* + *l*), obviously, that fails on time and memory. Lets try to optimize this algorithm using some facts from "Lucky numbers theory".
+
+Split all number interval on block with sizes 100: [0;99], [100;199] and so on. Introduce a concept "class of block". Class number of a block equals to *F*(*i* / 100), where *i* - any number from that block. There are 8 different block classes. There are at most 6 consecutive blocks with same class. All that can be seen using brute force.
+
+Note #1: if *l* ≥ 1000, then 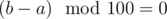.
+
+Proof: consider a string *F*(100 * *k*)*F*(100 * *k* + 1)...*F*(100 * *k* + 99). Number of different that strings is equal to number of different classes. For example, for first class that string looks like this:
+
+00001001000000100100000010010000001001001111211211000010010000001001001111211211
+
+00001001000000100100
+
+for second:
+
+11112112111111211211111121121111112112112222322322111121121111112112112222322322
+
+11112112111111211211
+
+and so on. According to the structure of that strings, different block (by classes) can't intersect (there'll be no match). Hence, any sequence of of consecutive blocks which contain at least two blocks of different classes will match only with the same sequence, so shift will be multiple of 100. Since there is no more than 6 consecutive blocks with the same classes, if *l* ≥ 1000 then, obviously, this interval will contain at least two blocks with different classes.
+
+So, problem with *l* ≥ 1000 can be solved using KMP with complexity *O*((*a* + *l*) / *C*), where *C* equals 100, let function that do that is named *Solve*(*l*, *r*).
+
+Now we need to solve problem for *l* < 1000. At first, let *a*' is minimal number that *F*(*a*') = *F*(*a*), *F*(*a*' + 1) = *F*(*a* + 1), ..., *F*(*a*' + *l* - 1) = *F*(*a* + *l* - 1), *a*' / 100 = *a* / 100, that can be done using brute force. Then result is the minimum of next numbers:
+
+- *r* = *Solve*(*a*', *a*' + *l* - 1);
+
+- Minimum *r*', for which *r* - *r*' < = 1000, *r*' > *a*, *F*(*r*') = *F*(*a*), *F*(*r*' + 1) = *F*(*a* + 1), ..., *F*(*r*' + *l* - 1) = *F*(*a* + *l* - 1).
+
+- Minimum *a*'' for which *a*'' > *a*, *a*'' - *a* ≤ 1000 and *F*(*a*'') = *F*(*a*), *F*(*a*'' + 1) = *F*(*a* + 1), ..., *F*(*a*'' + *l* - 1) = *F*(*a* + *l* - 1).
+
+That solves the problem of some non-100-multiple shifts, but that may be a doubt. Consider input interval is in just one block with class *C*. Then, probably, it is better to go to block with class *C* + 1, for example (397;1) → (400;1). Actually, second point solves that problem, because if block with class *C* + 1 is before *C* (and only in that case we will choose *C* + 1), then next block after current have class *C* + 1. To proof this we can use this note (which can be proofed using brute forces):
+
+Note #2: if there is two consecutive block, then absolute difference between they classes is not more then 1.
+
+Hence, if after block *C* (in which input interval is) goes block with class *C* - 1, then we will go to block *C* before *C* + 1, otherwise we will choose it (*C* or *C* + 1).
+
+Thus, problems solves by accurate analysis all moments. Complexity of solution is *O*((*A* + *L*) / 100), my solution works 1.5 sec. and use 250 mega bytes of memory.
+
+There are also solution which decompose of blocks with sizes depentding on *l*, that one work faster.
diff --git a/editorials/110.md b/editorials/110.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/2547
+
+1. [Lucky Number](https://codeforces.com/contest/110/problem/A) (Div2 A)
+
+In this problem you just need to find a number of lucky digits in *n* and output *YES* if it number is equal to 4 or 7, *NO* otherwise.
+
+2. [Lucky String](https://codeforces.com/contest/110/problem/B) (Div2 B)
+
+To solve this problem you need to notice that result is a prefix of string *abcdabcdabcd*...*abcd* and output first *n* characters of this string.
+
+3. [Lucky Sum of Digits](https://codeforces.com/contest/109/problem/A) (Div1 A, Div2 C)
+
+Let result number contains *a* digits 4 and *b* digits 7. Obviously, that *a* * 4 + *b* * 7 = *n*. Loop through all values of *b*. If we know *b*, we can calculate *a*, . Among all pairs (*a*;*b*) we need to choose one with *a* + *b* minimum. Among all that pairs we need to choose one with *b* minimum. Output will be an integer 444...444777...777, here number of digits 4 equal to *a*, number of digits 7 equal to *b*.
+
+4. [Lucky Probability](https://codeforces.com/contest/109/problem/B) (Div1 B, Div2 D)
+
+Let *L*[*i*] - *i*-th lucky number, starting from 1 (*L*[0] = 0, *L*[1] = 4, *L*[2] = 7...). At first choose first *k* lucky number, then second *k* numbers and so on. For each of that group lets find answer, result will be a sum of each of this probabilities. Let index of current first number if *i*, last - *j* (*j* = *i* + *k* - 1). Then we need to find intersection of intervals [*p**l*;*p**r*] and (*L*[*i* - 1];*L*[*i*]], and also [*v**l*;*v**r*] and [*L*[*j*];*L*[*j* + 1]), product of that values will be a number of ways in which *p* < *v*, similarly for *p* > *v*. Sum of all that values for each group will be a total number of ways, then result = total number of ways / ((*p**r* - *p**l* + 1) * (*v**r* - *v**l* + 1)).
+
+5. [Lucky Tree](https://codeforces.com/contest/109/problem/C) (Div1 C, Div2 E)
+
+Solve this problem using dynamic programming. Consider that root of a tree is vertex with number 1. Let *F*(*x*) - number of vertex in subtree of vertex *x* for which there is a path containing lucky edge. We will calculate *F*(*x*) using recursion. If *x* is a leaf, than *F*(*x*) = 0. Else, if there is an edge from *x* that leads to *y* and this edge is lucky, then to *F*(*x*) we need to add *C*(*y*), otherwise we add *F*(*y*), here *C*(*y*) - number of vertex in subtree of *y*, including *y*. But, to solve this problem we need to know also *F*'(*x*) - number of vertex which are not in subtree of *x* and there exits a path from *x* to that vertex that contains lucky edge. For a root of tree, *F*'(*x*) equals to 0. We should go recursive from root, and if we are in vertex *x* now, we suppose that *F*'(*x*) is already calculated. If from *x* we can directly go to *y* and that edge is lucky, then *F*'(*y*) = *C*(0) - *C*(*y*), otherwise *F*'(*y*) = *F*'(*x*) + *F*(*x*) - *F*(*y*).
+
+After that, result equals to 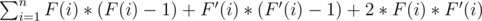.
+
+6. [Lucky Sorting](https://codeforces.com/contest/109/problem/D)(Div1 D)
+
+At first, if our array is already sorted, just return 0. Otherwise, if there is no lucky number in *A*, then output - 1. Otherwise, let *B* is sorted *A* (array from input). Now, for all numbers in *A* we know a final position in *B*. Let *k* is an index of minimal lucky number in *A*. If we want to place integer from position *i* to *j*, we need *A*[*j*] to be lucky number. If is not so, we just *Swap*(*A*[*j*], *A*[*k*]), then *A*[*j*] contains lucky number. After that we can *Swap*(*A*[*i*], *A*[*j*]) and number *A*[*i*] is on position *j*. So, to place one number to it's position in *B*, we need at most two operations and total number that replacements will be not more than *n*, so answer'll contain at most 2*n* operations.
+
+7. [Lucky Interval](https://codeforces.com/contest/109/problem/E) (Div1 E)
+
+That is only onw variation of solution, there are diffrent other, which uses same thinking.
+
+With constraints for *a* and *b* to 107 problem can be solved using KMP algorithm: consider a string *F*(1)*F*(2)*F*(3)*F*(4)...*F*(3 * 107). We need to find first occurrence after index *a* of string *F*(*a*)*F*(*a* + 1)*F*(*a* + 2)...*F*(*a* + *l* - 1). Complexity of that algorithm is *O*(*a* + *l*), obviously, that fails on time and memory. Lets try to optimize this algorithm using some facts from "Lucky numbers theory".
+
+Split all number interval on block with sizes 100: [0;99], [100;199] and so on. Introduce a concept "class of block". Class number of a block equals to *F*(*i* / 100), where *i* - any number from that block. There are 8 different block classes. There are at most 6 consecutive blocks with same class. All that can be seen using brute force.
+
+Note #1: if *l* ≥ 1000, then 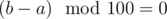.
+
+Proof: consider a string *F*(100 * *k*)*F*(100 * *k* + 1)...*F*(100 * *k* + 99). Number of different that strings is equal to number of different classes. For example, for first class that string looks like this:
+
+00001001000000100100000010010000001001001111211211000010010000001001001111211211
+
+00001001000000100100
+
+for second:
+
+11112112111111211211111121121111112112112222322322111121121111112112112222322322
+
+11112112111111211211
+
+and so on. According to the structure of that strings, different block (by classes) can't intersect (there'll be no match). Hence, any sequence of of consecutive blocks which contain at least two blocks of different classes will match only with the same sequence, so shift will be multiple of 100. Since there is no more than 6 consecutive blocks with the same classes, if *l* ≥ 1000 then, obviously, this interval will contain at least two blocks with different classes.
+
+So, problem with *l* ≥ 1000 can be solved using KMP with complexity *O*((*a* + *l*) / *C*), where *C* equals 100, let function that do that is named *Solve*(*l*, *r*).
+
+Now we need to solve problem for *l* < 1000. At first, let *a*' is minimal number that *F*(*a*') = *F*(*a*), *F*(*a*' + 1) = *F*(*a* + 1), ..., *F*(*a*' + *l* - 1) = *F*(*a* + *l* - 1), *a*' / 100 = *a* / 100, that can be done using brute force. Then result is the minimum of next numbers:
+
+- *r* = *Solve*(*a*', *a*' + *l* - 1);
+
+- Minimum *r*', for which *r* - *r*' < = 1000, *r*' > *a*, *F*(*r*') = *F*(*a*), *F*(*r*' + 1) = *F*(*a* + 1), ..., *F*(*r*' + *l* - 1) = *F*(*a* + *l* - 1).
+
+- Minimum *a*'' for which *a*'' > *a*, *a*'' - *a* ≤ 1000 and *F*(*a*'') = *F*(*a*), *F*(*a*'' + 1) = *F*(*a* + 1), ..., *F*(*a*'' + *l* - 1) = *F*(*a* + *l* - 1).
+
+That solves the problem of some non-100-multiple shifts, but that may be a doubt. Consider input interval is in just one block with class *C*. Then, probably, it is better to go to block with class *C* + 1, for example (397;1) → (400;1). Actually, second point solves that problem, because if block with class *C* + 1 is before *C* (and only in that case we will choose *C* + 1), then next block after current have class *C* + 1. To proof this we can use this note (which can be proofed using brute forces):
+
+Note #2: if there is two consecutive block, then absolute difference between they classes is not more then 1.
+
+Hence, if after block *C* (in which input interval is) goes block with class *C* - 1, then we will go to block *C* before *C* + 1, otherwise we will choose it (*C* or *C* + 1).
+
+Thus, problems solves by accurate analysis all moments. Complexity of solution is *O*((*A* + *L*) / 100), my solution works 1.5 sec. and use 250 mega bytes of memory.
+
+There are also solution which decompose of blocks with sizes depentding on *l*, that one work faster.
diff --git a/editorials/111.md b/editorials/111.md
@@ -0,0 +1,160 @@
+Source: https://codeforces.com/blog/entry/2616
+
+Here you can find solutions to the problems from the past round. Editorial for Problem D (Div 1) was prepared by [sdya](//codeforces.com/profile/sdya "Colonel sdya").
+
+**Division 2, [problem A](//codeforces.com/problemset/problem/112/A)**
+
+In this problem one could transform all letters in both strings to lower case and then compare the strings lexicographically.
+
+****Division 2, [problem B](//codeforces.com/problemset/problem/112/B)****
+
+One can notice that if we want to divide a square into two equal parts, then the cutting line should pass through the center of our square. Thus, if the marked cell contains the center of the square, then we can’t make a cut, otherwise we can. Here is the code which solves the problem:
+
+scanf("%d%d%d", &n, &x, &y);
+
+n /= 2;
+
+if ((x == n || x == n + 1) && (y == n || y == n + 1)) printf("NO\n"); else printf("YES\n");
+
+****Division 2, [problem C](//codeforces.com/problemset/problem/111/A)******(**Division 1, problem A**)**
+
+It is easy to see that in order to maximize the sum of squares, one should make all numbers except the first one equal to 1 and maximize the first number. Keeping this in mind we only need to check whether the given value of y is large enough to satisfy a restriction that all n numbers are positive. If y is not to small, then all we need is to ensure that *x* ≤ 1 + 1 + … + (*y* - (*n* - 1))2
+
+****Division 2, [Problem D](//codeforces.com/problemset/problem/111/B) (Divison 1, problem B)****
+
+Let’s create an array used[], j-th element of which will be the index of the last number from the input, which is divisible by j. Then for each query we’ll iterate over all divisors of xi and for each k, which divides xi we’ll check whether it is “unique”. After that we’ll update used[k].
+
+****Division 2, [Problem E](//codeforces.com/problemset/problem/111/C) (Division 1, problem C)****
+
+This problem has many different approaches. One of them uses the fact that the overall number of possible inputs is small and it is possible to compute the answer manually for all of them. One could also write a brute-force with a few optimizations, which works even without a precalc.
+
+However, the major part of all solutions involved dynamic programming with bitmasks. The solution below was described by Zlobober.
+
+Instead of counting the maximal number of free cells, we’ll count the minimal number of occupied cells. We’ll assume that the number of rows is not greater than 6 (otherwise we can rotate the board).
+
+Let D[k][pmask][mask] be the minimal number of occupied cells in the first k columns with the restrictions that the k-th column is described by pmask (ones correspond to occupied cells and zeroes correspond to free cells) and k+1-st column is described by mask. To make a transition from D[k-1][*][*] we can iterate over all possible masks for the k-1-st column, check whether we can distribute spiders in kth column knowing the masks for k+1-st and k-1-st columns and find the minimal value of D[k-1][*][pmask] for all such masks.
+
+
+
+The overall complexity is O(n*23m), n > m.
+
+
+
+****Division 1, [Problem D](//codeforces.com/problemset/problem/111/D)****
+
+One can notice that if *m* = 1 then the answer is kn, because all colorings are possible.
+ Now we’ll assume that m > 1. Let’s look on the first column of the board (i.e. the vertical cut will be made right next to the first column). Suppose there are *x* distinct colors in this column. Then in the rest of the board there are also *x* colors. If we move the vertical line by one unit to the right, the number of different colors to the left of it will not decrease and the number of colors to the right of it won’t increase. It means that the number of different colors in both parts of the board will be also *x*. We can repeat this process until the line reaches the rightmost column, which means that the number of distinct colors in it is also *x*. It is easy to see that we can only use colors which belong to the intersection of sets of colors in the leftmost and rightmost columns in the rest of the board.
+
+Let’s iterate over all values of *x* and *y*, where *x* is the number of colors in the leftmost column and *y* is the number of elements in intersection of sets of colors in the rightmost and leftmost columns. It is easy to see that *x* is limited by the number of rows in the board and y can’t be greater than *x*. Let’s find the answer for all such pairs of *x* and *y* and at the end we’ll add them up together.
+
+
+
+Suppose x and y are fixed. We first need to choose *(2x - y)* colors from the given k colors, which we will use, which means that the answer for will be multiplied by *C(k, 2x — y)*. After that we’ll choose *(x-y)* unique colors which will be used in the first column, which means that the answer will be also multiplied by *C(2x-y, x-y)*. Then we’ll choose *x-y* colors for the rightmost column and multiply the answer by *C(x, x-y)*. Now all we need to know is how many ways of coloring *n* cells into *x* colors are there. We’ll use a dynamic programming approach to solve this sub-problem.
+
+
+
+Let *d[i][j]* be the number of ways to color a rectangle of unit width and length *i* into colors, numerated from 1 to *j* with the following restriction: if *a < b* then the first appearence of color *a* in the rectangle will be before the first appearence of color *b*.
+ Then we can calculate this function using the following recurrence:
+
+*d[i][j] = j * d[i — 1][j] + d[i — 1][j — 1]*.
+
+After we finish calculating *d[i][j]*, we need to multiply the answer by *d[n][x]2* (to color the first and the last columns). Now we need to notice that we can reorder all colors in the first and the last columns in arbitrary way, which means that the answer should be multiplied by *(x!)2*. Finally, we need to multiply the answer by *yn(m-2)*, which correspond to coloring the rest of our board.
+
+
+
+Here is the code, which solves the problem for the given values of *x* and *y*:
+
+long long ans=0;
+
+
+
+for (int y=0; y<=n; y++){
+
+ long long cur=powmod(y,n*(m-2));
+
+ for (int x=y; x<=n; x++)
+
+ if (2*x-y<=k)
+
+ {
+
+ long long tek=cnk[2*x-y];
+
+ tek*=cnn[2*x-y][x-y], tek%=mod;
+
+ tek*=cnn[x][x-y], tek%=mod;
+
+ tek*=d[n][x], tek%=mod;
+
+ tek*=d[n][x], tek%=mod;
+
+ tek*=f[x], tek%=mod;
+
+ tek*=f[x], tek%=mod;
+
+ tek*=cur;
+
+ ans+=tek;
+
+ ans%=mod;
+
+ }
+
+}
+
+cout<<ans<<endl;
+
+Some contestants had problems with time limit, because of calculation of *C(N,K)*. One can notice that we won’t need more than *2000* colors, which reduces the time significantly. Author’s solution worked less than *200ms* with the time-limit of *5s*.
+
+**Division 1, [Problem E](//codeforces.com/problemset/problem/111/E)**
+
+Let the length of the maximal path be S. First, we’ll estimate the value of S without specifying the longest path itself.
+
+ Let’s color our board into a chess-coloring. Obviously, each two neighboring cells in the path will have different color. Keeping this in mind we can make some estimation on the value of S. For example, if there are 4 white cells and 5 black cells on the board and we know that both starting and ending cells are white, than the length of the path can’t be greater than 7, because white and black cells must alternate in the path. We can write a simple function which calculates the maximal value of S using only the fact described above. Here, n and m are the dimensions of the board, (sx, sy) is the starting cell and (fx, fy) is the ending cell.
+
+int fnd_ans(int n,int m,int sx,int sy,int fx,int fy){
+
+ int col1=((sx+sy+1)%2); //color of the start cell
+
+ int col2=((fx+fy+1)%2); //color of the finish cell
+
+
+
+ int cntb=(n*m+1)/2; //the number of black cells
+
+ int cntw=(n*m)/2; //the number of white cells
+
+
+
+ if (col1==1&&col2==1)
+
+ return cntb*2-1;
+
+ if (col1==1&&col2==0)
+
+ return cntw*2;
+
+ if (col1==0&&col2==1)
+
+ return cntw*2;
+
+ if (col1==0&&col2==0)
+
+ return 2*cntw-1;
+
+}
+
+It appears that for the constraints mentioned in the statement, this theoretical bound for S is always achievable. All we need is to find the path of the length S. Author solution divides the board into 5 pieces and solves the problem for each piece separately.
+
+ 
+
+Let’s divide the board into 5 parts as it was shown on the first picture. We’ll assume that the relative location of the starting and ending cells is the same as on the picture. In each part we’ll try to build a longest path which completely belongs to it. For the first part we’ll try to build a path from the upper-right corner to the upper-left corner. Similar rules will hold for all other parts (see the picture above for further clarification). Paths can be different for different boards, but they will have similar structure. One can notice that there are only two types of paths (with respect to rotations of the board): the one which starts at the upper-left corner and ends at the bottom-right corner and the one which starts at the upper-left corner and ends at the upper-right corner. Now we can write down an algorithm:
+
+ 1) Divide the board into 5 parts.
+ 2) Find the longest path in each of the parts.
+ 3) Check if the total length is equal to S.
+ 4) If the above is false, then rotate or reflect the board and continue to the step 1.
+
+ In order to find the longest path in a particular part, one can either consequently move through all rows of the part or through all its columns.
+
+ This solution gives correct answers for all 4 ≤ *n*, *m* ≤ 20. All possible cases of parity of each part are feasible within those constraints, which means that the solution will work for all boards, including ones with n > 20 or m > 20. The overall complexity of described algorithm is *O(N*M)*.
diff --git a/editorials/112.md b/editorials/112.md
@@ -0,0 +1,160 @@
+Source: https://codeforces.com/blog/entry/2616
+
+Here you can find solutions to the problems from the past round. Editorial for Problem D (Div 1) was prepared by [sdya](//codeforces.com/profile/sdya "Colonel sdya").
+
+**Division 2, [problem A](//codeforces.com/problemset/problem/112/A)**
+
+In this problem one could transform all letters in both strings to lower case and then compare the strings lexicographically.
+
+****Division 2, [problem B](//codeforces.com/problemset/problem/112/B)****
+
+One can notice that if we want to divide a square into two equal parts, then the cutting line should pass through the center of our square. Thus, if the marked cell contains the center of the square, then we can’t make a cut, otherwise we can. Here is the code which solves the problem:
+
+scanf("%d%d%d", &n, &x, &y);
+
+n /= 2;
+
+if ((x == n || x == n + 1) && (y == n || y == n + 1)) printf("NO\n"); else printf("YES\n");
+
+****Division 2, [problem C](//codeforces.com/problemset/problem/111/A)******(**Division 1, problem A**)**
+
+It is easy to see that in order to maximize the sum of squares, one should make all numbers except the first one equal to 1 and maximize the first number. Keeping this in mind we only need to check whether the given value of y is large enough to satisfy a restriction that all n numbers are positive. If y is not to small, then all we need is to ensure that *x* ≤ 1 + 1 + … + (*y* - (*n* - 1))2
+
+****Division 2, [Problem D](//codeforces.com/problemset/problem/111/B) (Divison 1, problem B)****
+
+Let’s create an array used[], j-th element of which will be the index of the last number from the input, which is divisible by j. Then for each query we’ll iterate over all divisors of xi and for each k, which divides xi we’ll check whether it is “unique”. After that we’ll update used[k].
+
+****Division 2, [Problem E](//codeforces.com/problemset/problem/111/C) (Division 1, problem C)****
+
+This problem has many different approaches. One of them uses the fact that the overall number of possible inputs is small and it is possible to compute the answer manually for all of them. One could also write a brute-force with a few optimizations, which works even without a precalc.
+
+However, the major part of all solutions involved dynamic programming with bitmasks. The solution below was described by Zlobober.
+
+Instead of counting the maximal number of free cells, we’ll count the minimal number of occupied cells. We’ll assume that the number of rows is not greater than 6 (otherwise we can rotate the board).
+
+Let D[k][pmask][mask] be the minimal number of occupied cells in the first k columns with the restrictions that the k-th column is described by pmask (ones correspond to occupied cells and zeroes correspond to free cells) and k+1-st column is described by mask. To make a transition from D[k-1][*][*] we can iterate over all possible masks for the k-1-st column, check whether we can distribute spiders in kth column knowing the masks for k+1-st and k-1-st columns and find the minimal value of D[k-1][*][pmask] for all such masks.
+
+
+
+The overall complexity is O(n*23m), n > m.
+
+
+
+****Division 1, [Problem D](//codeforces.com/problemset/problem/111/D)****
+
+One can notice that if *m* = 1 then the answer is kn, because all colorings are possible.
+ Now we’ll assume that m > 1. Let’s look on the first column of the board (i.e. the vertical cut will be made right next to the first column). Suppose there are *x* distinct colors in this column. Then in the rest of the board there are also *x* colors. If we move the vertical line by one unit to the right, the number of different colors to the left of it will not decrease and the number of colors to the right of it won’t increase. It means that the number of different colors in both parts of the board will be also *x*. We can repeat this process until the line reaches the rightmost column, which means that the number of distinct colors in it is also *x*. It is easy to see that we can only use colors which belong to the intersection of sets of colors in the leftmost and rightmost columns in the rest of the board.
+
+Let’s iterate over all values of *x* and *y*, where *x* is the number of colors in the leftmost column and *y* is the number of elements in intersection of sets of colors in the rightmost and leftmost columns. It is easy to see that *x* is limited by the number of rows in the board and y can’t be greater than *x*. Let’s find the answer for all such pairs of *x* and *y* and at the end we’ll add them up together.
+
+
+
+Suppose x and y are fixed. We first need to choose *(2x - y)* colors from the given k colors, which we will use, which means that the answer for will be multiplied by *C(k, 2x — y)*. After that we’ll choose *(x-y)* unique colors which will be used in the first column, which means that the answer will be also multiplied by *C(2x-y, x-y)*. Then we’ll choose *x-y* colors for the rightmost column and multiply the answer by *C(x, x-y)*. Now all we need to know is how many ways of coloring *n* cells into *x* colors are there. We’ll use a dynamic programming approach to solve this sub-problem.
+
+
+
+Let *d[i][j]* be the number of ways to color a rectangle of unit width and length *i* into colors, numerated from 1 to *j* with the following restriction: if *a < b* then the first appearence of color *a* in the rectangle will be before the first appearence of color *b*.
+ Then we can calculate this function using the following recurrence:
+
+*d[i][j] = j * d[i — 1][j] + d[i — 1][j — 1]*.
+
+After we finish calculating *d[i][j]*, we need to multiply the answer by *d[n][x]2* (to color the first and the last columns). Now we need to notice that we can reorder all colors in the first and the last columns in arbitrary way, which means that the answer should be multiplied by *(x!)2*. Finally, we need to multiply the answer by *yn(m-2)*, which correspond to coloring the rest of our board.
+
+
+
+Here is the code, which solves the problem for the given values of *x* and *y*:
+
+long long ans=0;
+
+
+
+for (int y=0; y<=n; y++){
+
+ long long cur=powmod(y,n*(m-2));
+
+ for (int x=y; x<=n; x++)
+
+ if (2*x-y<=k)
+
+ {
+
+ long long tek=cnk[2*x-y];
+
+ tek*=cnn[2*x-y][x-y], tek%=mod;
+
+ tek*=cnn[x][x-y], tek%=mod;
+
+ tek*=d[n][x], tek%=mod;
+
+ tek*=d[n][x], tek%=mod;
+
+ tek*=f[x], tek%=mod;
+
+ tek*=f[x], tek%=mod;
+
+ tek*=cur;
+
+ ans+=tek;
+
+ ans%=mod;
+
+ }
+
+}
+
+cout<<ans<<endl;
+
+Some contestants had problems with time limit, because of calculation of *C(N,K)*. One can notice that we won’t need more than *2000* colors, which reduces the time significantly. Author’s solution worked less than *200ms* with the time-limit of *5s*.
+
+**Division 1, [Problem E](//codeforces.com/problemset/problem/111/E)**
+
+Let the length of the maximal path be S. First, we’ll estimate the value of S without specifying the longest path itself.
+
+ Let’s color our board into a chess-coloring. Obviously, each two neighboring cells in the path will have different color. Keeping this in mind we can make some estimation on the value of S. For example, if there are 4 white cells and 5 black cells on the board and we know that both starting and ending cells are white, than the length of the path can’t be greater than 7, because white and black cells must alternate in the path. We can write a simple function which calculates the maximal value of S using only the fact described above. Here, n and m are the dimensions of the board, (sx, sy) is the starting cell and (fx, fy) is the ending cell.
+
+int fnd_ans(int n,int m,int sx,int sy,int fx,int fy){
+
+ int col1=((sx+sy+1)%2); //color of the start cell
+
+ int col2=((fx+fy+1)%2); //color of the finish cell
+
+
+
+ int cntb=(n*m+1)/2; //the number of black cells
+
+ int cntw=(n*m)/2; //the number of white cells
+
+
+
+ if (col1==1&&col2==1)
+
+ return cntb*2-1;
+
+ if (col1==1&&col2==0)
+
+ return cntw*2;
+
+ if (col1==0&&col2==1)
+
+ return cntw*2;
+
+ if (col1==0&&col2==0)
+
+ return 2*cntw-1;
+
+}
+
+It appears that for the constraints mentioned in the statement, this theoretical bound for S is always achievable. All we need is to find the path of the length S. Author solution divides the board into 5 pieces and solves the problem for each piece separately.
+
+ 
+
+Let’s divide the board into 5 parts as it was shown on the first picture. We’ll assume that the relative location of the starting and ending cells is the same as on the picture. In each part we’ll try to build a longest path which completely belongs to it. For the first part we’ll try to build a path from the upper-right corner to the upper-left corner. Similar rules will hold for all other parts (see the picture above for further clarification). Paths can be different for different boards, but they will have similar structure. One can notice that there are only two types of paths (with respect to rotations of the board): the one which starts at the upper-left corner and ends at the bottom-right corner and the one which starts at the upper-left corner and ends at the upper-right corner. Now we can write down an algorithm:
+
+ 1) Divide the board into 5 parts.
+ 2) Find the longest path in each of the parts.
+ 3) Check if the total length is equal to S.
+ 4) If the above is false, then rotate or reflect the board and continue to the step 1.
+
+ In order to find the longest path in a particular part, one can either consequently move through all rows of the part or through all its columns.
+
+ This solution gives correct answers for all 4 ≤ *n*, *m* ≤ 20. All possible cases of parity of each part are feasible within those constraints, which means that the solution will work for all boards, including ones with n > 20 or m > 20. The overall complexity of described algorithm is *O(N*M)*.
diff --git a/editorials/113.md b/editorials/113.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/2627
+
+**Div 2. Problem А.** [Cifera](//codeforces.com/problemset/problem/114/A)
+
+To solve this task, let's describe what is needed more formally. We should answer whether is number *l* some positive degree of number *k* or no. To answer this question we can proceed in 2 ways:
+1) Using 64 bit data type, we can find minimal degree *h* of number *k*, such that *k**h* ≥ *l*. If *k**h* = *l*, then the answer is *YES*, and number of articles is equal to *h* - 1. Otherwise, the answer is *NO*.
+2) We will divide *l* by *k*, until *k* divides *l* and *l* ≠ 1. If *l* = 1, then the answer - *YES* and number of articles is equal to *numberOfDivisions* - 1, and the answer is *NO* otherwise.
+
+**Div 2. Problem B.** [PFAST Inc.](//codeforces.com/problemset/problem/114/B)
+
+We can reformulate the statement more formally.
+In this case, we have a undirected graph, and we have to find some maximal clique in it. If we have a look to constraint *n* ≤ 16, then there can be noticed that we can iterate over all possbile subsets of vertices and find the answer. To do this, one can use bit masks and iterate from 0 to 216, checking current subgraph for being a clique. Also, it's necessary not to forget about sorting the names while printing the answer.
+
+**Div 1. Problem A.** [Grammar Lessons](//codeforces.com/problemset/problem/113/A)
+
+This task is an example of task that requires accurate realization.
+
+After reading the statement one can understand that we have to check whether the text from input represents exactly one correct sentence or no. If yes, therefore the text can be either a single word from our language or a following structure:
+
+{zero or non-zero count of adjectives} -> {a single noun} -> {zero or non-zero count of verbs}, and moreover, all these words should have equal gender.
+
+So, to check these facts, one can do the following:
+
+We count number of words. If this number is equal to 1, we check this word for being a valid word from our language. Otherwise, we can get gender of the first word, and iterate through the rest of the words validating existing of only one noun and order of these words. Also, while iterating we check the gender of each word for being equal to the gender of the first word.
+
+**Div 1.** **Problem** **B.** [Petr#](//codeforces.com/problemset/problem/113/B)
+
+Let's find all occurrences of begin and end. Then we'll map the whole string to number 0. After this we will simply add one symbol per iteration to already seen sub-strings and map new strings to some non-negative integers. One can notice that we will never reach a situation when more then 2000 different strings exist, so we can map them easily. Now, as per we know all the ends and beginnings of strings and different string of equal length are mapped to different numbers ( and equal strings are mapped equally), we can simply count the number of necessary sub-strings of certain length. So, we have time complexity *O*(*N*2*LogN*), since we are making *N* iterations and each is done in O(*NLogN*) time.
+
+**Div. 1.** **Problem** **C.** [Double Happiness](//codeforces.com/problemset/problem/113/C)
+
+In this task one have to find quantity of prime numbers that can be reproduced as sum of two perfect squares. Obviously, that 4*k* + 3 prime numbers are not suitable as sum of two perfect squares can not be equal to 3 (of course, modulo 4). So, we can prove or use the well-known fact ( also known as Fermat theorem), that every odd 4*k* + 1 prime number is a sum of two perfect squares. Also, we have not to forget about 2, as 2 = 12 + 12.
+
+Now, how can we get this task accepted? Simply using the sieve will exceed memory limit, but we can use block sieve, that works in the same time (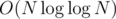), but uses  of memory. Also, we can use precalc for intervals of length equal to 100000. Also, [Romka](//codeforces.com/profile/Romka "Colonel Romka") used the fact, that using bitset compress memory up to 8 times, and it will enough to suite the ML. Also, it would be nice to count only odd numbers while buliding the sieve.
+
+**Div. 1.** **Problem** **D.**[Museum](//codeforces.com/problemset/problem/113/D)
+
+Let's consider a pair (i, j) as a state - this means that now Petya is in room i, and Vasya is in room j. Therefore, their meeting is state (i, i) for some i. So, it's quite easy to build transition matrix - this means that for each state (i, j) we will know probability of reaching state (x, y) in one step, where 1 ≤ *i*, *j*, *x*, *y* ≤ *n*. Also, from meeting state we can reach only the same state.
+Let's try to solve such a problem - what is the probability of meeting in the first room? We build system of linear algebraic equations:
+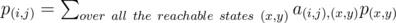, where *a*(*i*, *j*), (*x*, *y*) — probability of transition from state (i,j) to state (x,y). One can notice that *p*(1, 1) = 1, and *p*(*i*, *i*) = 0 when *i* ≠ 1, and the answer will be *p*(*a*, *b*).
+This system can be easily solved using Gauss method. Similarly we can solve such a problem for every room (considering that we will meet in certain room), but we have complexity O(*n*7), that will not pass time limit. But, after some observations, we now see that each time we are solving system *Ax* = *b* (and the only thing that is changing — is vector b). So, we can solve matrix equation *Ax* = *b*, where b is a matrix with dimensions *n*2 * *n*, and the answer will be in the row that corresponds to state (a, b) . With this approach we have time complexity O(*n*6), that will pass time limit.
+
+**Div. 1.** **Problem** **E.**[Sleeping](//codeforces.com/problemset/problem/113/E)
+
+Let's consider function *F*(*x*) (where *x* is some moment of time) — amount of moments from 0..00:00..00 up to *x* (and *x* doesn't switch to next moment ) when n *k* or more digits will be changed . The answer will be *F*(*h*2: *m*2) - *F*(*h*1: *m*1), also it's necessary not to forget that if *h*2: *m*2 < *h*1: *m*1, then *F*(*h*2: *m*2) will be enlarged by a day.
+Now we will learn how to calculate *F*(*x*). To start with, let's count amount of such numbers when hour will remain the same. As hour is not changing, then *k* or more digits have to be changed in minutes, but in this case we need our number of minutes to be of the following form:
+*a*..*a*99...9, where *a* means any digit,and at the end we have *k* - 1 nines. So k digits are changing every moment that is divisible by 10*k* - 1.
+So, the total amount of such moments (without changing an hour) is 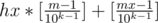, where*hx* и *mx* are numbers of hour and minute in time moment *x*, and [] is integer part.
+Now let's deal with such moments when hour is changing. If this happens, then minute turns from *m* - 1 to 0, and we have *y* different digits, where *y* is amount of non-zero digits of number *m* - 1. Therefore we have to count for hours ( in similar way) amount of moments, when *k* - *y* or more digits will be changed. *k* - *y* digits are changing every moment that is divisible by 10*max*(0, *k* - *y* - 1), this means that total amount of such moments is 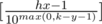. And the final value of *F* is 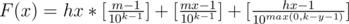.
diff --git a/editorials/114.md b/editorials/114.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/2627
+
+**Div 2. Problem А.** [Cifera](//codeforces.com/problemset/problem/114/A)
+
+To solve this task, let's describe what is needed more formally. We should answer whether is number *l* some positive degree of number *k* or no. To answer this question we can proceed in 2 ways:
+1) Using 64 bit data type, we can find minimal degree *h* of number *k*, such that *k**h* ≥ *l*. If *k**h* = *l*, then the answer is *YES*, and number of articles is equal to *h* - 1. Otherwise, the answer is *NO*.
+2) We will divide *l* by *k*, until *k* divides *l* and *l* ≠ 1. If *l* = 1, then the answer - *YES* and number of articles is equal to *numberOfDivisions* - 1, and the answer is *NO* otherwise.
+
+**Div 2. Problem B.** [PFAST Inc.](//codeforces.com/problemset/problem/114/B)
+
+We can reformulate the statement more formally.
+In this case, we have a undirected graph, and we have to find some maximal clique in it. If we have a look to constraint *n* ≤ 16, then there can be noticed that we can iterate over all possbile subsets of vertices and find the answer. To do this, one can use bit masks and iterate from 0 to 216, checking current subgraph for being a clique. Also, it's necessary not to forget about sorting the names while printing the answer.
+
+**Div 1. Problem A.** [Grammar Lessons](//codeforces.com/problemset/problem/113/A)
+
+This task is an example of task that requires accurate realization.
+
+After reading the statement one can understand that we have to check whether the text from input represents exactly one correct sentence or no. If yes, therefore the text can be either a single word from our language or a following structure:
+
+{zero or non-zero count of adjectives} -> {a single noun} -> {zero or non-zero count of verbs}, and moreover, all these words should have equal gender.
+
+So, to check these facts, one can do the following:
+
+We count number of words. If this number is equal to 1, we check this word for being a valid word from our language. Otherwise, we can get gender of the first word, and iterate through the rest of the words validating existing of only one noun and order of these words. Also, while iterating we check the gender of each word for being equal to the gender of the first word.
+
+**Div 1.** **Problem** **B.** [Petr#](//codeforces.com/problemset/problem/113/B)
+
+Let's find all occurrences of begin and end. Then we'll map the whole string to number 0. After this we will simply add one symbol per iteration to already seen sub-strings and map new strings to some non-negative integers. One can notice that we will never reach a situation when more then 2000 different strings exist, so we can map them easily. Now, as per we know all the ends and beginnings of strings and different string of equal length are mapped to different numbers ( and equal strings are mapped equally), we can simply count the number of necessary sub-strings of certain length. So, we have time complexity *O*(*N*2*LogN*), since we are making *N* iterations and each is done in O(*NLogN*) time.
+
+**Div. 1.** **Problem** **C.** [Double Happiness](//codeforces.com/problemset/problem/113/C)
+
+In this task one have to find quantity of prime numbers that can be reproduced as sum of two perfect squares. Obviously, that 4*k* + 3 prime numbers are not suitable as sum of two perfect squares can not be equal to 3 (of course, modulo 4). So, we can prove or use the well-known fact ( also known as Fermat theorem), that every odd 4*k* + 1 prime number is a sum of two perfect squares. Also, we have not to forget about 2, as 2 = 12 + 12.
+
+Now, how can we get this task accepted? Simply using the sieve will exceed memory limit, but we can use block sieve, that works in the same time (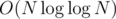), but uses  of memory. Also, we can use precalc for intervals of length equal to 100000. Also, [Romka](//codeforces.com/profile/Romka "Colonel Romka") used the fact, that using bitset compress memory up to 8 times, and it will enough to suite the ML. Also, it would be nice to count only odd numbers while buliding the sieve.
+
+**Div. 1.** **Problem** **D.**[Museum](//codeforces.com/problemset/problem/113/D)
+
+Let's consider a pair (i, j) as a state - this means that now Petya is in room i, and Vasya is in room j. Therefore, their meeting is state (i, i) for some i. So, it's quite easy to build transition matrix - this means that for each state (i, j) we will know probability of reaching state (x, y) in one step, where 1 ≤ *i*, *j*, *x*, *y* ≤ *n*. Also, from meeting state we can reach only the same state.
+Let's try to solve such a problem - what is the probability of meeting in the first room? We build system of linear algebraic equations:
+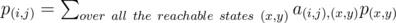, where *a*(*i*, *j*), (*x*, *y*) — probability of transition from state (i,j) to state (x,y). One can notice that *p*(1, 1) = 1, and *p*(*i*, *i*) = 0 when *i* ≠ 1, and the answer will be *p*(*a*, *b*).
+This system can be easily solved using Gauss method. Similarly we can solve such a problem for every room (considering that we will meet in certain room), but we have complexity O(*n*7), that will not pass time limit. But, after some observations, we now see that each time we are solving system *Ax* = *b* (and the only thing that is changing — is vector b). So, we can solve matrix equation *Ax* = *b*, where b is a matrix with dimensions *n*2 * *n*, and the answer will be in the row that corresponds to state (a, b) . With this approach we have time complexity O(*n*6), that will pass time limit.
+
+**Div. 1.** **Problem** **E.**[Sleeping](//codeforces.com/problemset/problem/113/E)
+
+Let's consider function *F*(*x*) (where *x* is some moment of time) — amount of moments from 0..00:00..00 up to *x* (and *x* doesn't switch to next moment ) when n *k* or more digits will be changed . The answer will be *F*(*h*2: *m*2) - *F*(*h*1: *m*1), also it's necessary not to forget that if *h*2: *m*2 < *h*1: *m*1, then *F*(*h*2: *m*2) will be enlarged by a day.
+Now we will learn how to calculate *F*(*x*). To start with, let's count amount of such numbers when hour will remain the same. As hour is not changing, then *k* or more digits have to be changed in minutes, but in this case we need our number of minutes to be of the following form:
+*a*..*a*99...9, where *a* means any digit,and at the end we have *k* - 1 nines. So k digits are changing every moment that is divisible by 10*k* - 1.
+So, the total amount of such moments (without changing an hour) is 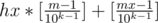, where*hx* и *mx* are numbers of hour and minute in time moment *x*, and [] is integer part.
+Now let's deal with such moments when hour is changing. If this happens, then minute turns from *m* - 1 to 0, and we have *y* different digits, where *y* is amount of non-zero digits of number *m* - 1. Therefore we have to count for hours ( in similar way) amount of moments, when *k* - *y* or more digits will be changed. *k* - *y* digits are changing every moment that is divisible by 10*max*(0, *k* - *y* - 1), this means that total amount of such moments is 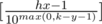. And the final value of *F* is 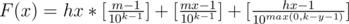.
diff --git a/editorials/115.md b/editorials/115.md
@@ -0,0 +1,179 @@
+Source: https://codeforces.com/blog/entry/2584
+
+**Time Capsule Remarks (planted before the contest)**
+
+Due to popular demand, today's problem statements are made to be as short as possible without too many (but existing!) embellishment. All of them are thinking-based problems (i.e., implementation is the easier of the two) - so I'm generally happy with the problems :). I hope nobody found them to be too easy :S
+
+As you may have noticed, we decided not to give devastatingly weak pretests. I guess it's just really evil to give weak pretests for my first match.
+
+And so, the editorial begins...
+
+Remarks
+
+I'm sorry - but I don't have access to my usual graphic editing tool and so, the graphics are fairly limited :) (Example: Lawnmower's pictures must be the ugliest lawnmower I have ever seen! (Is it even a lawnmower?) Not to mention I don't look like the actor at all...)
+
+**[D2-A: Tram](//codeforces.com/contest/116/problem/A)**
+
+If we know the number of people inside the tram at all possible time, then the answer is the maximum of such. We observe that the number of people inside the tram changes only at tram stops. The conclusion is that the answer will be the maximum of the number of people inside the tram directly before arriving at a particular stop and directly after leaving a particular stop (the more observant readers can notice that using only one of these is sufficient).
+
+It's sufficiently easy to calculate the number of people inside the tram directly before and after leaving a tram stop.
+
+**[D2-B: N Little Pigs](//codeforces.com/contest/116/problem/B)**
+
+No... not maximum matching ;)
+
+So, an equivalent less-evil rewording of the problem would be: "Return the number of wolves that are adjacent to at least one pig".
+
+To see this, since each pig has at most one wolf adjacent to it (the constraints impose that) we don't need to worry at a single pig may get eaten by two different wolves. Hence, each wolf can eat any of the pig adjacent to it.
+
+Remarks
+
+It's more interesting to reverse this problem isn't it:
+
+Each pig will be adjacent to at most one wolf
+
+becomes
+
+Each wolf will be adjacent to at most one pig
+
+Can you solve this one? (Of course, not using network flow mind you ;) - that's overkill)
+
+**[D2-C / D1-A Party](//codeforces.com/contest/115/problem/A)**
+
+We let an employee without a manager called as root. There's an edge from a manager to an employee that he/she manages.
+
+First notice that the graph is a collection of directed trees. Hence, we can assign a depth label to each node - denoting the number of nodes on the simple path from the root to it. The answer is then the maximum depth a node has.
+
+Why?
+
+First, the answer is bounded below by this number because any pair of employees in this path cannot be in the same group. Second, since the graph is a tree, each node in the graph has a unique depth label assigned to it. Simply put all nodes with the same depth in the same group. It's fairly easy to see that no one will be the superior of another within a group, for otherwise their depths will not be equal.
+
+Remark
+
+You might notice that there exist an O(N) implementation of the above algorithm, yet the constraint is 2000. Well, this problem was swapped with the D1-B because the previous D1-A was thought to be harder than expected. And so, in the process, we also decrease the constraint for N from 200,000 to 2,000. I hope you like it :)
+
+**[D2-D / D1-B: Lawnmower](//codeforces.com/contest/115/problem/B)**
+
+First, let's observe a particular strategy that turns out to be optimal at the end of our discussion.
+
+Suppose we're on a row, facing right. This strategy say that we need to move to the right as long as there is a weed to the right of us either on this row or on the row directly below us.
+
+The idea is that we need to mow that weed, hence, we need to move there. If it's in the same row as us, it's fairly obvious we have to mow that before going down. If it's at the row directly below us, since we can't move to the right in the row below us (since we'll be facing left there) we need to move there before going down.
+
+The strategy then says that if we no longer need to move right, we go down, and face left. Repeat this until all weeds are mowed (replacing left and right in the discussion above) - and we have our strategy.
+
+This strategy is optimal. Proof is using induction - but it's not particularly interesting, so the idea is given instead.
+
+Suppose we're on a row, facing right, again. If there exist a weed to the right in this row or below us, then any solution will necessarily move right as far as our strategy goes (for the reason we discussed above). Some solution however choose to go further right despite having no weed in this row or the row directly below us. This solution is not optimal if we need to go left directly after going down, for we can just simply go down instead of going right-down-left. On the other case, if we don't need to go left directly after going down, then it means that we go down twice-in-a-row! Hence, instead of moving right in this row, we go down twice, then move right there. And then the induction can continue and the proof can follow.
+
+Remarks
+
+I guess the actor should be Toastman instead :).
+
+Anyway, so sorry to disappoint you, but we decided to add some pretty strong pretest to this problem, despite the fact that many solutions will probably forget to take care of two consecutive empty rows. But still, the pretest we gave only consist of one column, so feel free to hack the stragglers :) (not that this suggestion matters after the contest but still...)
+
+**[D2-E / D1-C Plumber](//codeforces.com/contest/115/problem/C)**
+
+To solve this problem, let's imagine that the left and top sides of the grid also determines whether the pipe adjacent to that side has an end connecting it to the side or not. There are 2^(N+M) ways to pick them. We claim that if we fix them (i.e., pick one of the possible 2^(N+M) ways, then the entire grid's pipes are fixed).
+
+To see this, notice that each pipe segment will have either one vertical end (it either have end on the top or end on the bottom) and one horizontal end (left or right). We can pick any 4 combinations of them. Suppose we pick a row, and determine whether the leftmost pipe should have an end to the left of it, or not. Suppose it doesn't have an opening to the left. It means that the leftmost pipe should have an opening to the right, the next pipe should have an opening to the left, the next pipe to the right, and so on. Continuing this way, we have fixed the horizontal ends for an entire row - and only that. Hence, if we pick one of the possible 2^(N+M) ways to pick the ends, then the horizontal ends of each row and vertical ends of each column is fixed. Since there is exactly one pipe segment that has a particular configuration of ends, there is exactly one possible completed grid for each of the 2^(N+M) ways to pick the ends.
+
+Hence, the solution works by first checking if a solution exists. Any pre-assigned pipe simply sets whether or not its corresponding row and column has an end at the left and top side. We need to check that no two pipes sets this value contradictorily. If any of them are contradictory, then we return the answer as 0. Otherwise, we return 2^(number of rows without preassigned cell + number of columns without preassigned cell).
+
+**[D1-D Unambiguous Arithmetic Expression](//codeforces.com/contest/115/problem/D)**
+
+This problem is solved using Dynamic Programming. The somewhat straightforward dynamic programming is to represent the state as {start_pos, end_pos}, which represents the number of unambiguous arithmetic expression on the substring of the input starting at start_pos and ending at end_pos. This however has a complexity of O(N^3) and is not suitable for our problem.
+
+The solution uses the state {pos, braces}. This state is somewhat tricky to explain. This means that we have read the first pos characters in the input. We're expected to read a single unambiguous arithmetic expression, close it with some number of brackets that we don't care (to be explained below), and then, if braces is zero, that's it. Otherwise, we're then expected to read a binary operator (either + - * or /), then open a bracket, then move the state to {pos + some_value, braces-1}. That is, braces keeps track on the number of second operands of binary expression that we need to make.
+
+For an example how this works, let's try to solve a particular test case:
+
+"++0*+1"
+
+Let's denote with quotes the part of the input that we haven't processed. We're going to create the unambiguous arithmetic expression by scanning it left to right and making some choices.
+
+There are three choices:
+
+1) Create a unary expression. In the example above,
+
+"++0*+1" -> +("+0*+1"
+
+We don't really care about where the closing bracket is yet.
+
+2) Create a binary expression. In the example above,
+
++("+0*+1" -> +(("+0*+1"
+
+How does this tells that we will need to create a binary expression? The second open bracket does not have any operator preceeding it. The only thing that can makes this a proper prefix of an unambiguous arithmetic expression is that if this bracket belongs to the first operand of a binary expression.
+
+For our example, we suppose we read another unary expression
+
++(("+0*+1" -> +((+("0*+1"
+
+3a) Read an integer. In our example above,
+
++((+("0*+1" -> +((+(0))*("+1"
+
+There are two questions. a) how do we know the number of closing brackets we have to make? This is actually easy - for every open bracket we have, if it's for a unary expression, we simply close and repeat. Otherwise it's a closing bracket for possibly the first operand to a binary expression, so we close it, and we read a binary operator (* in the example above), and try to read the second operand of the binary expression.
+
+Finally:
+
++((+(0))*("+1" -> +((+(0))*(+("1"
+
+3b) We try to read an integer again and we have no open brackets that belongs to the first operand of a binary expression, and we have ourself a possible answer.
+
++((+(0))*(+("1" -> +((+(0))*(+(1)))
+
+So, in the state {pos, braces}, pos determines the starting location of the remaining unprocessed input. braces indicates the number of open brackets that belongs to a binary expression. So, in the examples above:
+
+1)
+
+"++0*+1" -> +("+0*+1" is represented by
+
+{0, 0} -> {1, 0}
+
+More specifically, for unary expressions, {pos, braces} -> {pos+1, braces}
+
+2)
+
++("+0*+1" -> +(("+0*+1" is represented by
+
+{1, 0} -> {1, 1}
+
+More specifically, for binary expressions, {pos, braces} -> {pos, braces+1}
+
+3a)
+
++((+("0*+1" -> +((+(0))*("+1"
+
+{2, 1} -> {4, 0}
+
+More specifically, {pos, braces} -> {pos + length_of_integer + 1, braces-1}
+
+3b)
+
++((+(0))*(+("1" -> +((+(0))*(+(1)))
+
+{5, 0} -> Done
+
+More specifically, {pos, braces} -> done if braces is zero and the remaining input forms a single integer.
+
+Remarks
+
+My favorite problem of this match (because it's hard-to-think and easy-to-code) ;). This turns out to be the hardest problem of the match.
+
+During the match, three coders ([shik](//codeforces.com/profile/shik "Lieutenant colonel shik"), [ivan.popelyshev](//codeforces.com/profile/ivan.popelyshev "Colonel ivan.popelyshev"), and [watashi](//codeforces.com/profile/watashi "General watashi")) submitted solutions which I think works in N^2. [Petr](//codeforces.com/profile/Petr "General Petr") submitted a solution that (I think) uses Catalan number, while [Egor](//codeforces.com/profile/Egor "Colonel Egor") submitted a solution which uses polynomial to quickly count each of the dp values (see his [comment](//codeforces.com/blog/entry/2584?locale=ru#comment-55420) in the Editorial). [tourist](//codeforces.com/profile/tourist "General tourist") submitted a solution which uses a highly-optimized inner loop with no branching and expensive operations (only a single multiplication) - he cleverly avoid branching in his code.
+
+**[D1-E Races](//codeforces.com/contest/115/problem/E)**
+
+We process the roads one by one. Associated with each road is the races whose UBi is that road (i.e., races that 'ends' at that road). We will discuss the Dynamic Programming solution first, then improve it with a data structure into the optimal solution.
+
+Let's say we're going to process a road. Our state is this : DP[X] is the maximum possible profit such that the last X roads before this road are fixed and the X+1-th road before this road is NOT fixed. We are going to compute the value of DP for the next iteration, let's call this FUTURE. FUTURE[0] is obtained if we don't fix this road, FUTURE[0] = maximum amongst the value of DP. Otherwise, if we decide to fix this road, then for each of DP[X], FUTURE[X+1] >?= DP[X] - cost to fix the road + all races' profit that ends at this road and whose starting point is not before X roads from current road (i.e., all the races that is contained and ends at this road). This should work in N^2 + N * M. It can be improved to N^2 + M
+
+The data structure approach is slightly different. We will use a segment tree that allows finding a maximum value in a subset and modifying the values of a range, all of which should work in either O(1) or O(log N). The segment tree will consist of N+1 leaves. However, not all the leaves are active at the start of the algorithm. At the start, only one leaf is active and it corresponds to the initial value of DP[0]. Next, we can compute the maximum value amongst all active leaves in O(log N). Then, we create a new active leaf that corresponds to FUTURE[0]. This will be located in the same tree however, the values represented by the leaves will be shifted one to the right - this is done implicitly (for example, we use the last node as DP[0] for the first iteration, but treat it as DP[1] for the next, and so on). These shifted values will correspond to FUTURE[X], since we notice that FUTURE[X] = DP[X-1] - cost to fix the road + races that this series contains and ends at this current road (i.e., it's value directly depends on the leaf BEFORE it was shifted). Next, we decrement the value of all these new leaves (except FUTURE[0]) by the cost to fix the road (in O(log N)). Finally, for each race that ends at this road, we increment the value of the leaves that contains this race. This will be continuous, i.e., FUTURE[X] for X in [race_len, INFINITY]. This can also be done in O(log N). Since a race ends at at most one road, the total complexity this will contribute is M log N.
+
+The answer will then simply the maximum value amongst all members of the tree.
+
+Remarks
+
+This is one of the problems I submitted to this year's IOI but didn't got accepted - I sort of agree that this doesn't suit IOI very well. IOI likes a non-numeric output :) #goparrots!
diff --git a/editorials/116.md b/editorials/116.md
@@ -0,0 +1,179 @@
+Source: https://codeforces.com/blog/entry/2584
+
+**Time Capsule Remarks (planted before the contest)**
+
+Due to popular demand, today's problem statements are made to be as short as possible without too many (but existing!) embellishment. All of them are thinking-based problems (i.e., implementation is the easier of the two) - so I'm generally happy with the problems :). I hope nobody found them to be too easy :S
+
+As you may have noticed, we decided not to give devastatingly weak pretests. I guess it's just really evil to give weak pretests for my first match.
+
+And so, the editorial begins...
+
+Remarks
+
+I'm sorry - but I don't have access to my usual graphic editing tool and so, the graphics are fairly limited :) (Example: Lawnmower's pictures must be the ugliest lawnmower I have ever seen! (Is it even a lawnmower?) Not to mention I don't look like the actor at all...)
+
+**[D2-A: Tram](//codeforces.com/contest/116/problem/A)**
+
+If we know the number of people inside the tram at all possible time, then the answer is the maximum of such. We observe that the number of people inside the tram changes only at tram stops. The conclusion is that the answer will be the maximum of the number of people inside the tram directly before arriving at a particular stop and directly after leaving a particular stop (the more observant readers can notice that using only one of these is sufficient).
+
+It's sufficiently easy to calculate the number of people inside the tram directly before and after leaving a tram stop.
+
+**[D2-B: N Little Pigs](//codeforces.com/contest/116/problem/B)**
+
+No... not maximum matching ;)
+
+So, an equivalent less-evil rewording of the problem would be: "Return the number of wolves that are adjacent to at least one pig".
+
+To see this, since each pig has at most one wolf adjacent to it (the constraints impose that) we don't need to worry at a single pig may get eaten by two different wolves. Hence, each wolf can eat any of the pig adjacent to it.
+
+Remarks
+
+It's more interesting to reverse this problem isn't it:
+
+Each pig will be adjacent to at most one wolf
+
+becomes
+
+Each wolf will be adjacent to at most one pig
+
+Can you solve this one? (Of course, not using network flow mind you ;) - that's overkill)
+
+**[D2-C / D1-A Party](//codeforces.com/contest/115/problem/A)**
+
+We let an employee without a manager called as root. There's an edge from a manager to an employee that he/she manages.
+
+First notice that the graph is a collection of directed trees. Hence, we can assign a depth label to each node - denoting the number of nodes on the simple path from the root to it. The answer is then the maximum depth a node has.
+
+Why?
+
+First, the answer is bounded below by this number because any pair of employees in this path cannot be in the same group. Second, since the graph is a tree, each node in the graph has a unique depth label assigned to it. Simply put all nodes with the same depth in the same group. It's fairly easy to see that no one will be the superior of another within a group, for otherwise their depths will not be equal.
+
+Remark
+
+You might notice that there exist an O(N) implementation of the above algorithm, yet the constraint is 2000. Well, this problem was swapped with the D1-B because the previous D1-A was thought to be harder than expected. And so, in the process, we also decrease the constraint for N from 200,000 to 2,000. I hope you like it :)
+
+**[D2-D / D1-B: Lawnmower](//codeforces.com/contest/115/problem/B)**
+
+First, let's observe a particular strategy that turns out to be optimal at the end of our discussion.
+
+Suppose we're on a row, facing right. This strategy say that we need to move to the right as long as there is a weed to the right of us either on this row or on the row directly below us.
+
+The idea is that we need to mow that weed, hence, we need to move there. If it's in the same row as us, it's fairly obvious we have to mow that before going down. If it's at the row directly below us, since we can't move to the right in the row below us (since we'll be facing left there) we need to move there before going down.
+
+The strategy then says that if we no longer need to move right, we go down, and face left. Repeat this until all weeds are mowed (replacing left and right in the discussion above) - and we have our strategy.
+
+This strategy is optimal. Proof is using induction - but it's not particularly interesting, so the idea is given instead.
+
+Suppose we're on a row, facing right, again. If there exist a weed to the right in this row or below us, then any solution will necessarily move right as far as our strategy goes (for the reason we discussed above). Some solution however choose to go further right despite having no weed in this row or the row directly below us. This solution is not optimal if we need to go left directly after going down, for we can just simply go down instead of going right-down-left. On the other case, if we don't need to go left directly after going down, then it means that we go down twice-in-a-row! Hence, instead of moving right in this row, we go down twice, then move right there. And then the induction can continue and the proof can follow.
+
+Remarks
+
+I guess the actor should be Toastman instead :).
+
+Anyway, so sorry to disappoint you, but we decided to add some pretty strong pretest to this problem, despite the fact that many solutions will probably forget to take care of two consecutive empty rows. But still, the pretest we gave only consist of one column, so feel free to hack the stragglers :) (not that this suggestion matters after the contest but still...)
+
+**[D2-E / D1-C Plumber](//codeforces.com/contest/115/problem/C)**
+
+To solve this problem, let's imagine that the left and top sides of the grid also determines whether the pipe adjacent to that side has an end connecting it to the side or not. There are 2^(N+M) ways to pick them. We claim that if we fix them (i.e., pick one of the possible 2^(N+M) ways, then the entire grid's pipes are fixed).
+
+To see this, notice that each pipe segment will have either one vertical end (it either have end on the top or end on the bottom) and one horizontal end (left or right). We can pick any 4 combinations of them. Suppose we pick a row, and determine whether the leftmost pipe should have an end to the left of it, or not. Suppose it doesn't have an opening to the left. It means that the leftmost pipe should have an opening to the right, the next pipe should have an opening to the left, the next pipe to the right, and so on. Continuing this way, we have fixed the horizontal ends for an entire row - and only that. Hence, if we pick one of the possible 2^(N+M) ways to pick the ends, then the horizontal ends of each row and vertical ends of each column is fixed. Since there is exactly one pipe segment that has a particular configuration of ends, there is exactly one possible completed grid for each of the 2^(N+M) ways to pick the ends.
+
+Hence, the solution works by first checking if a solution exists. Any pre-assigned pipe simply sets whether or not its corresponding row and column has an end at the left and top side. We need to check that no two pipes sets this value contradictorily. If any of them are contradictory, then we return the answer as 0. Otherwise, we return 2^(number of rows without preassigned cell + number of columns without preassigned cell).
+
+**[D1-D Unambiguous Arithmetic Expression](//codeforces.com/contest/115/problem/D)**
+
+This problem is solved using Dynamic Programming. The somewhat straightforward dynamic programming is to represent the state as {start_pos, end_pos}, which represents the number of unambiguous arithmetic expression on the substring of the input starting at start_pos and ending at end_pos. This however has a complexity of O(N^3) and is not suitable for our problem.
+
+The solution uses the state {pos, braces}. This state is somewhat tricky to explain. This means that we have read the first pos characters in the input. We're expected to read a single unambiguous arithmetic expression, close it with some number of brackets that we don't care (to be explained below), and then, if braces is zero, that's it. Otherwise, we're then expected to read a binary operator (either + - * or /), then open a bracket, then move the state to {pos + some_value, braces-1}. That is, braces keeps track on the number of second operands of binary expression that we need to make.
+
+For an example how this works, let's try to solve a particular test case:
+
+"++0*+1"
+
+Let's denote with quotes the part of the input that we haven't processed. We're going to create the unambiguous arithmetic expression by scanning it left to right and making some choices.
+
+There are three choices:
+
+1) Create a unary expression. In the example above,
+
+"++0*+1" -> +("+0*+1"
+
+We don't really care about where the closing bracket is yet.
+
+2) Create a binary expression. In the example above,
+
++("+0*+1" -> +(("+0*+1"
+
+How does this tells that we will need to create a binary expression? The second open bracket does not have any operator preceeding it. The only thing that can makes this a proper prefix of an unambiguous arithmetic expression is that if this bracket belongs to the first operand of a binary expression.
+
+For our example, we suppose we read another unary expression
+
++(("+0*+1" -> +((+("0*+1"
+
+3a) Read an integer. In our example above,
+
++((+("0*+1" -> +((+(0))*("+1"
+
+There are two questions. a) how do we know the number of closing brackets we have to make? This is actually easy - for every open bracket we have, if it's for a unary expression, we simply close and repeat. Otherwise it's a closing bracket for possibly the first operand to a binary expression, so we close it, and we read a binary operator (* in the example above), and try to read the second operand of the binary expression.
+
+Finally:
+
++((+(0))*("+1" -> +((+(0))*(+("1"
+
+3b) We try to read an integer again and we have no open brackets that belongs to the first operand of a binary expression, and we have ourself a possible answer.
+
++((+(0))*(+("1" -> +((+(0))*(+(1)))
+
+So, in the state {pos, braces}, pos determines the starting location of the remaining unprocessed input. braces indicates the number of open brackets that belongs to a binary expression. So, in the examples above:
+
+1)
+
+"++0*+1" -> +("+0*+1" is represented by
+
+{0, 0} -> {1, 0}
+
+More specifically, for unary expressions, {pos, braces} -> {pos+1, braces}
+
+2)
+
++("+0*+1" -> +(("+0*+1" is represented by
+
+{1, 0} -> {1, 1}
+
+More specifically, for binary expressions, {pos, braces} -> {pos, braces+1}
+
+3a)
+
++((+("0*+1" -> +((+(0))*("+1"
+
+{2, 1} -> {4, 0}
+
+More specifically, {pos, braces} -> {pos + length_of_integer + 1, braces-1}
+
+3b)
+
++((+(0))*(+("1" -> +((+(0))*(+(1)))
+
+{5, 0} -> Done
+
+More specifically, {pos, braces} -> done if braces is zero and the remaining input forms a single integer.
+
+Remarks
+
+My favorite problem of this match (because it's hard-to-think and easy-to-code) ;). This turns out to be the hardest problem of the match.
+
+During the match, three coders ([shik](//codeforces.com/profile/shik "Lieutenant colonel shik"), [ivan.popelyshev](//codeforces.com/profile/ivan.popelyshev "Colonel ivan.popelyshev"), and [watashi](//codeforces.com/profile/watashi "General watashi")) submitted solutions which I think works in N^2. [Petr](//codeforces.com/profile/Petr "General Petr") submitted a solution that (I think) uses Catalan number, while [Egor](//codeforces.com/profile/Egor "Colonel Egor") submitted a solution which uses polynomial to quickly count each of the dp values (see his [comment](//codeforces.com/blog/entry/2584?locale=ru#comment-55420) in the Editorial). [tourist](//codeforces.com/profile/tourist "General tourist") submitted a solution which uses a highly-optimized inner loop with no branching and expensive operations (only a single multiplication) - he cleverly avoid branching in his code.
+
+**[D1-E Races](//codeforces.com/contest/115/problem/E)**
+
+We process the roads one by one. Associated with each road is the races whose UBi is that road (i.e., races that 'ends' at that road). We will discuss the Dynamic Programming solution first, then improve it with a data structure into the optimal solution.
+
+Let's say we're going to process a road. Our state is this : DP[X] is the maximum possible profit such that the last X roads before this road are fixed and the X+1-th road before this road is NOT fixed. We are going to compute the value of DP for the next iteration, let's call this FUTURE. FUTURE[0] is obtained if we don't fix this road, FUTURE[0] = maximum amongst the value of DP. Otherwise, if we decide to fix this road, then for each of DP[X], FUTURE[X+1] >?= DP[X] - cost to fix the road + all races' profit that ends at this road and whose starting point is not before X roads from current road (i.e., all the races that is contained and ends at this road). This should work in N^2 + N * M. It can be improved to N^2 + M
+
+The data structure approach is slightly different. We will use a segment tree that allows finding a maximum value in a subset and modifying the values of a range, all of which should work in either O(1) or O(log N). The segment tree will consist of N+1 leaves. However, not all the leaves are active at the start of the algorithm. At the start, only one leaf is active and it corresponds to the initial value of DP[0]. Next, we can compute the maximum value amongst all active leaves in O(log N). Then, we create a new active leaf that corresponds to FUTURE[0]. This will be located in the same tree however, the values represented by the leaves will be shifted one to the right - this is done implicitly (for example, we use the last node as DP[0] for the first iteration, but treat it as DP[1] for the next, and so on). These shifted values will correspond to FUTURE[X], since we notice that FUTURE[X] = DP[X-1] - cost to fix the road + races that this series contains and ends at this current road (i.e., it's value directly depends on the leaf BEFORE it was shifted). Next, we decrement the value of all these new leaves (except FUTURE[0]) by the cost to fix the road (in O(log N)). Finally, for each race that ends at this road, we increment the value of the leaves that contains this race. This will be continuous, i.e., FUTURE[X] for X in [race_len, INFINITY]. This can also be done in O(log N). Since a race ends at at most one road, the total complexity this will contribute is M log N.
+
+The answer will then simply the maximum value amongst all members of the tree.
+
+Remarks
+
+This is one of the problems I submitted to this year's IOI but didn't got accepted - I sort of agree that this doesn't suit IOI very well. IOI likes a non-numeric output :) #goparrots!
diff --git a/editorials/117.md b/editorials/117.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/2752
+
+**[Problem A.](//codeforces.com/contest/117/problem/A)**
+
+Consider three cases.
+
+* *s* = *f*, *ans* = *t*.
+* *s* < *f*, we must find the smallest non-negative *k* such, that *t* ≤ (*s* - 1) + 2(*m* - 1)*k*. *ans* = *s* - 1 + 2(*m* - 1)*k* + (*f* - *s*).
+* *s* > *f*, similarly, we must find the smallest non-negative *k* such, that *t* ≤ 2(*m* - 1) - (*s* - 1) + 2(*m* - 1)*k*. *ans* = 2(*m* - 1) - (*s* - 1) + 2(*m* - 1)*k* + (*s* - *f*).
+
+We can find *k* in any reasonable manner, for example, by using formulas of integer division.
+
+**[Problem B.](//codeforces.com/contest/117/problem/B)**
+
+Suppose, that the first player made a move *x* ≤ *a*, then consider the remainder *rem* = *x*· 109%*mod*. Obviously, if (*mod* - *rem*)%*mod* ≤ *b*, then the second player can win. Thus, we must iterate through all relevant values of *x* (we don't need iterate through more than *mod* values) and check whether the second player to win. If there exist a losing move for second player, then won the first, else second. Since we iterate through all relevant moves of the first player, then we can easily determine his winning move (if such move exist).
+
+**[Problem С.](//codeforces.com/contest/117/problem/C)**
+
+Approval. If the tournament has at least one cycle, then there exist a cycle of length three.
+
+A constructive proof. Find any cycle in the tournament by using any standard algorithm, such as depth-first search. If there is no cycle, then output -1, else choose any three consecutive vertices of the cycle *v*1 *v*2 *v*3 (*A**v*1, *v*2 = *A**v*2, *v*3 = 1). Since given graph is a tournament, then there is an edge (*v*3, *v*1), or there is an edge (*v*1, *v*3). The first of these two cases, we find immediately the cycle of length three of the vertices *v*1 *v*2 *v*3, the second, we can reduce the length of the loop (erase vertex *v*2).
+
+We can reduce the length of the cycle until we find a cycle of length three.
+
+**[Problem D.](//codeforces.com/contest/117/problem/D)**
+
+Imagine a recursion tree our transformation *F*. This tree is binary. We write on the edges leading into the left subtree, zero, and on the edges, leading to the right, one. Now consider the path of some number *a* (hereafter, we assume that we substracted one from all numbers in the array over which we make the conversion). This path start in the root of the tree and end in some leaf, and numbers written on the edges of the path is exactly bit representation of *a* in order from least significant bit to the most significant bit.
+
+Construct the recursive function which solve our problem, similar to how we carry out a query to the segment tree. Here is the prototype of this function.
+
+*solve*(*idx*, *tl*, *tr*, *l*, *r*, *u*, *v*)
+
+This function returns the answer to the query (*l*, *r*, *u*, *v*), if we consider only subtree with positions [*tl*, *tr*], while on the path from the root to the subtree is written bit representation of *idx*. If *l* ≤ *tl* ≤ *tr* ≤ *r*, then we calculate answer by formulae, else we divide our segment of positions and return sum of answers from left and right part.
+
+As described above, the answer to the whole subtree is a formula. Here you need to use the fact that all the numbers in the subtree have the form *k*· 2*depth* + *idx*, where *depth* - depth of subtree. We must find *k* such, that *u* ≤ *k*· 2*depth* + *idx* ≤ *v* and then calculate the sum of appropriate numbers.
+
+Asymptotics of this solution *O*(*m*· *log*(*n*)· (*formulae* - *for* - *whole* - *subtree*)). We can calculate formulae for whole subtree in *O*(*logn*).
+
+**[Problem E.](//codeforces.com/contest/117/problem/E)**
+
+In this problem, suggested a solution using heavy light decomposition. Graph, given in problem statement, is a cycle, on which are suspended trees. For each tree construct the data structure (heavy light + segment tree), which can perform *change* on the path from some vertex to any parent, and to maintain the amount of ones. The same structure we use for the cycle.
+
+Suppose, that we have no cycle, i.e. there is just a bunch of trees (forest). Then the amount of switched-on edges uniquely determines the number of connected components (each switched-on edge decrease the amount of components by one).
+
+Suppose, that we have only the cycle. Then, similarly, the amount of switched-on edges uniquely determines the number of connected components.
+
+We will maintain the amount of switched-on edges in the cycle and in the all trees. So, the answer to the problem *Comps**cicle* + *Comps**trees* - *Cnt**Cicle*, where *Comps**cicle* - the amount of connected components in cycle, *Comps**trees* - the amount of connected components in all trees, *Cnt**Cicle* - the amount of vertexes in cycle.
+
+([Google](https://www.google.com/search?aq=0&oq=Heavy+light+decom&gcx=w&sourceid=chrome&ie=UTF-8&q=heavy+light+decomposition)).
diff --git a/editorials/119.md b/editorials/119.md
@@ -0,0 +1,53 @@
+Source: https://codeforces.com/blog/entry/3229
+
+Для начала немного переформулируем нашу задачу. Рассмотрим, что значит то, что активировались все сферы. Это значит что если мы спроецируем все сферы на плоскость, то у них всех будет общая точка. В силу того, что проекцией сферы на плоскость является окружность, то наша задача состоит в нахождении минимального радиуса окружности такого, что все окружности имеют общую точку.
+
+Будем отвечать на каждый запрос отдельно. Для ответа на запрос будем делать следующее:
+
+1) Спроецируем все точки на плоскость.
+
+2) Выполним преобразование поворота к плоскости, так чтобы она стала *Oxy*.
+
+Итого мы получили следующую задачу:
+
+Имеется *N* точек на плоскости и необходимо найти такой минимальный радиус окружности, чтобы окружности построенные вокруг заданных точек имели общую точку. Пускай мы нашли радиус *R* и общую точку (*x*0, *y*0). Тогда рассмотрим окружность построенную в точке (*x*0, *y*0), радуиса *R*. Заметим, она покрывает *N* исходных точек. Аналогично рассмотрев некоторое покрытие исходных точек при помощи какой-то окружности, получаем окружности имеющие общую точку. Т.е. задача минимизации *R* в данной задаче эквивалентна задаче нахождения минимальной покрывающей окружности. Научимся эффективно решать эту задачу в силу того, что очевидный алгоритм решения данной задачи приводит к решению за *O*(*N*4*M*), что очевидно не подходит для данных ограничений.
+
+**Рандомизированный алгоритм за *O*(*N*).**
+
+Не нарушая общности считаем что точек более чем одна. Перемешаем имеющиеся точки случайным образом после чего будем делать слещующее:
+
+1) Выберем две произвольные точки и построим на них окружность как на диаметре. Будем идти по точкам. Если точка лежит внутри окружности, то ничего не меняем. Если же точка лежит вне окружности, то значит среди уже рассмотренных точек она должна быть на покрывающей окружности (в силу того что не лежит внутри покрывающей предыдущие). А тогда переходим к 2.
+
+2) Необходимо найти минимальную покрывающую окружность с одной фиксированной точкой. Для этого перемешаем точки рассмотренные в 1 и поступим аналогично пункту 1. Т.е. вначале построим произвольную на окружность на фиксированной точке и некоторой произвольной из остальных. И будем рассматривать остальные. В итоге мы получим или что мы нашли ответ, или нам надо найти окружность с уже зафиксированными двумя точками. Т.е. переходим к 3.
+
+3) Необходимо найти минимальную покрывающую окружность с двумя фиксированной точкой. Для этого перемешаем точки рассмотренные в 2 и поступим аналогично пункту 1. Т.е. вначале построим окружность на фиксированных точках и будем рассматривать остальные. В итоге мы получим или что мы нашли ответ, или нам надо найти окружность на каких-то трёх точках. А данную окружность уже можно найти за *О*(1).
+
+Выполнив все действия указанные выше мы найдем минимальную покрывающую окружность.
+
+Нетрудно показать, что ожидаемая сложность алгортима - *O*(*N*). А значит сложность решения - *O*(*NM*).
+
+Но в силу того что данный алгоритм, не может являтся авторским решением в силу того что не гарантирует решения задачи в указанное время рассмотрим следующий алгоритм.
+
+**Детерминированный алгоритм за *O*(*N*2).**
+
+Для простоты будем считать, что все точки различны. Если точка всего одна, то ответ - очевиден радиус 0 достигается в самой точке.
+
+В противном случае делаем следующее:
+
+1) Выберем произвольную точку *C* и положим радиус *R* окружности описанной в данной точке равным бесконечности. Очевидно, что это не оптимальное решение, и можно сделать нашу окружность меньше выбрав радиус равным расстоянием до самой удалённой точки.
+
+2) После выбора такого радуиса у нас возможны следующие две ситуации:
+
+> a) На окружности есть хотя бы две точки. Тогда перейдем к шагу 3.
+
+> b) На окружности находится ровно одна точка. В таком случае будем двигать центр окружности уменьшая радиус пока на окружности не окажется ровно две точки (а такой момент наступит).
+
+3) Рассмотрим окружность *C* и точки которые лежат на ней.
+
+> a) На ней есть дуга опирающая на угол больше чем π (пусть у неё концевые точки *D* и *E*), то окружность можно сделать меньше двигая её центр в направлении середины отрезка *DE* и уменьшая радиус окружности, пока на этой дуге не появится точка или же мы не получим, окружность у которой *DE* - диаметр. Повторим 3) ещё раз.
+>
+> b) Любая из дуг опирается на угол не больше чем π. А тогда мы нашли ответ в силу того что куда бы мы не двигали центр радиус будет только увеличиваться и т.к. функция радиуса выпукла.
+
+В приведенных выше рассуждениях движение организуется следующим образом: получаем вектор на который надо сместить центр и ищем минимальное , что у нас появляется точка на окружности.
+
+Заметим, что все 1), 2), 3) выполняются за линейное время. При этом нетрудно показать, что итераций 3) будет не больше чем *N* - 2, а тогда общее время работы - *O*(*N*2). Или же для исходной задачи: *O*(*MN*2)
diff --git a/editorials/158.md b/editorials/158.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/4089
+
+Qualification Round 1
+
+A [158A - Next Round](/contest/158/problem/A "VK Cup 2012 Qualification Round 1")
+
+Just sort. Notice 0 in the array.
+
+B [158B - Taxi](/contest/158/problem/B "VK Cup 2012 Qualification Round 1")
+
+Choose the 3 and 1 as much as possible. And let 2 combine with themselves. If there are more 1s and 2s, let two 1s combine with 2, and every four 1s take same taxi.
+
+C [158C - Cd and pwd commands](/contest/158/problem/C "VK Cup 2012 Qualification Round 1")
+
+Implement with stack. If the string begin with '/', let top = 0, else remain the top; Then process the substring one by one, when meeting ".." , top--; else remain the top;
+
+D [158D - Ice Sculptures](/contest/158/problem/D "VK Cup 2012 Qualification Round 1")
+
+The number of new regular polygon's edges must be the factor of the given polygon. Listing all the factors take O(sqrt(n)) time. Then choose the best point take O(n). So the time complexity is O(n*sqrt(n)).
+
+E [158E - Phone Talks](/contest/158/problem/E "VK Cup 2012 Qualification Round 1")
+
+It's a classic DP problem. Array dp[i][j] stands for the min rightmost endpoint when choosing at most j segments from the first i segments . dp[i][j] =dp[i][j] = min(dp[i-1][j-1], max(dp[i-1][j],left[i])+length[i]). When the dp array is completed , find the max value of left[i+1]-dp[i][k] and rightmost point — dp[n][k]. Totally take O(n*n).
+
+Qualification Round 2
+
+A [159A - Friends or Not](/contest/159/problem/A "VK Cup 2012 Qualification Round 2")
+
+Compare every two records and find the right friends. Give every name a unique number so as to avoid counting same friend twice. If a and b is friends, let friend[a][b] = true.
+
+B [159B - Matchmaker](/contest/159/problem/B "VK Cup 2012 Qualification Round 2")
+
+Establish two hash tables counting the number of the size (say 2) exiting in set makers and set caps. Obviously the sum of min number of every size in two sets is the first answer. Similarly establish two hash tables in order to count the number of the same size and same color. The hash function can be hash(color, size) = color*1000+size.
+
+C [159C - String Manipulation 1.0](/contest/159/problem/C "VK Cup 2012 Qualification Round 2")
+
+Because the length of string is at most 100*2000, so we can build 26 line-segment-trees to count the 26 Latin letters. The way to build tree and find the position of K-th letter is quite simple if you under stand line-segment-tree :)
+
+D [159D - Palindrome pairs](/contest/159/problem/D "VK Cup 2012 Qualification Round 2")
+
+A dp method is really great~ , sum[i] stands for the number of palindrome string in the first i letters. palindrome[i][j] judges weather the substring i...j is a palindrome string. dp[i] is the answer for the first i letters. dp[i] = dp[i-1]+Sum( palindrome[j][i]*sum[j-1] ) for all j<=i && j>0 . sum[i] = sum[i-1]+Sum(palindrome[j][i]) for all j<=i.
+
+E [159E - Zebra Tower](/contest/159/problem/E "VK Cup 2012 Qualification Round 2")
+
+sort the array with compare condition (cube[i].color < cube[j].color ||(cube[i].color==cube[j].color && cube[i].size>cube[j].size)). Then for the first i cubes , there is a array Max_cube, Max_cube[j] records the max sum of j cubes' size with same color. To the cube i+1, if it's the k-th largest size of its color. Compare the answer with cube[i+1].size + max(Max_cube[k],Max_cube[k+1],Max_cube[k-1]). The time complexity is O(n*logn).
+
+Forgive my poor English :)
+
+gl and hf tonight!
diff --git a/editorials/159.md b/editorials/159.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/4089
+
+Qualification Round 1
+
+A [158A - Next Round](/contest/158/problem/A "VK Cup 2012 Qualification Round 1")
+
+Just sort. Notice 0 in the array.
+
+B [158B - Taxi](/contest/158/problem/B "VK Cup 2012 Qualification Round 1")
+
+Choose the 3 and 1 as much as possible. And let 2 combine with themselves. If there are more 1s and 2s, let two 1s combine with 2, and every four 1s take same taxi.
+
+C [158C - Cd and pwd commands](/contest/158/problem/C "VK Cup 2012 Qualification Round 1")
+
+Implement with stack. If the string begin with '/', let top = 0, else remain the top; Then process the substring one by one, when meeting ".." , top--; else remain the top;
+
+D [158D - Ice Sculptures](/contest/158/problem/D "VK Cup 2012 Qualification Round 1")
+
+The number of new regular polygon's edges must be the factor of the given polygon. Listing all the factors take O(sqrt(n)) time. Then choose the best point take O(n). So the time complexity is O(n*sqrt(n)).
+
+E [158E - Phone Talks](/contest/158/problem/E "VK Cup 2012 Qualification Round 1")
+
+It's a classic DP problem. Array dp[i][j] stands for the min rightmost endpoint when choosing at most j segments from the first i segments . dp[i][j] =dp[i][j] = min(dp[i-1][j-1], max(dp[i-1][j],left[i])+length[i]). When the dp array is completed , find the max value of left[i+1]-dp[i][k] and rightmost point — dp[n][k]. Totally take O(n*n).
+
+Qualification Round 2
+
+A [159A - Friends or Not](/contest/159/problem/A "VK Cup 2012 Qualification Round 2")
+
+Compare every two records and find the right friends. Give every name a unique number so as to avoid counting same friend twice. If a and b is friends, let friend[a][b] = true.
+
+B [159B - Matchmaker](/contest/159/problem/B "VK Cup 2012 Qualification Round 2")
+
+Establish two hash tables counting the number of the size (say 2) exiting in set makers and set caps. Obviously the sum of min number of every size in two sets is the first answer. Similarly establish two hash tables in order to count the number of the same size and same color. The hash function can be hash(color, size) = color*1000+size.
+
+C [159C - String Manipulation 1.0](/contest/159/problem/C "VK Cup 2012 Qualification Round 2")
+
+Because the length of string is at most 100*2000, so we can build 26 line-segment-trees to count the 26 Latin letters. The way to build tree and find the position of K-th letter is quite simple if you under stand line-segment-tree :)
+
+D [159D - Palindrome pairs](/contest/159/problem/D "VK Cup 2012 Qualification Round 2")
+
+A dp method is really great~ , sum[i] stands for the number of palindrome string in the first i letters. palindrome[i][j] judges weather the substring i...j is a palindrome string. dp[i] is the answer for the first i letters. dp[i] = dp[i-1]+Sum( palindrome[j][i]*sum[j-1] ) for all j<=i && j>0 . sum[i] = sum[i-1]+Sum(palindrome[j][i]) for all j<=i.
+
+E [159E - Zebra Tower](/contest/159/problem/E "VK Cup 2012 Qualification Round 2")
+
+sort the array with compare condition (cube[i].color < cube[j].color ||(cube[i].color==cube[j].color && cube[i].size>cube[j].size)). Then for the first i cubes , there is a array Max_cube, Max_cube[j] records the max sum of j cubes' size with same color. To the cube i+1, if it's the k-th largest size of its color. Compare the answer with cube[i+1].size + max(Max_cube[k],Max_cube[k+1],Max_cube[k-1]). The time complexity is O(n*logn).
+
+Forgive my poor English :)
+
+gl and hf tonight!
diff --git a/editorials/160.md b/editorials/160.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/4044
+
+## [160A - Twins](/contest/160/problem/A "Codeforces Round 111 (Div. 2)")
+
+В этой задаче требовалось найти подмножество наименьшего размера, сумма чисел в котором строго больше, чем половина суммы всех чисел. Несложно понять, что выгоднее брать наибольшие числа в массиве, так мы быстрее наберем нужную сумму. Тогда решение выглядит следующим образом: отсортируем числа по невозрастанию и переберем сколько первых чисел заберем мы, а сколько – наш близнец, Как только у нас строго больше, чем осталось для близнеца – выведем ответ.
+
+## [160B - Unlucky Ticket](/contest/160/problem/B "Codeforces Round 111 (Div. 2)")
+
+Запишем в массив *a* первые *n* цифр, а в массив *b* — последние *n* цифр, и отсортируем эти массивы. Нетрудно понять, что если для всех *i* выполняется *a*[*i*] < *b*[*i*], или для всех *i* выполняется *a*[*i*] > *b*[*i*], то билет точно является несчастливым. Но также нетрудно понять, что для любого несчастливого билета выполняется или первое условие, или второе. Таким образом, мы придумали критерий несчастливости, можно реализовать за время *O*(*n*·*log*(*n*)).
+
+## [160C - Find Pair](/contest/160/problem/C "Codeforces Round 111 (Div. 2)")
+
+Для начала, мы, авторы раунда, хотим отметить, что эта задача вызвала множество вопросов, хотя в условии было совершенно четко и недвусмысленно написано, что нужно делать. Более того, на почти все вопросы по условию этой задачи мы отвечали скопированным из текста предложением – и у большинства участников больше вопросов не возникало.
+
+Пусть число k и массив a заданы в 0-нумерации, а сам массив отсортируем. Тогда если все числа различны, то очевидный ответ – это пара (a[k / n], a[k % n]), где операция % означает остаток по модулю. Однако, если в массиве есть повторяющиеся числа, то ситуация становится немного хитрее, рассмотрим пример: пусть дан массив (1, 1, 2, 2), тогда пары записаны следующим образом: (1, 1), (1, 1), (1, 1), (1, 1), (1, 2), (1, 2), (1, 2), (1, 2), (2, 1), (2, 1), (2, 1), (2, 1), (2, 2), (2, 2), (2, 2), (2, 2), каждая пара учитывается и никуда не девается, всегда рассматриваются ровно *n*2 пар чисел.
+
+По-прежнему верно, что первое число – это *a*[*k* / *n*]. А второе число – это *a*[(*k*–*n*·*cnt*) / *num*], где *cnt* – количество чисел в массиве строго меньших, чем *a*[*k* / *n*], а *num* – количество чисел в массиве, которые равны *a*[*k* / *n*].
+
+В этой формуле несложно убедиться, рассмотрев пару примеров с повторяющимися элементами. В крайнем случае, можно написать тривиальное решение за *O*(*n*2·*log*(*n*)) и убедиться, что вы правильно придумали формулу.
+
+P. S. Претест 3 имеет вид: в массиве (1, 1, 2) нужно найти 3-ю по лексикографичности пару. Она равна (1, 1).
+
+## [160D - Edges in MST](/contest/160/problem/D "Codeforces Round 111 (Div. 2)")
+
+Во-первых, разберем случай, когда все веса одинаковы. Тогда очевидно, что любое ребро может быть в дереве, но в случае, если ребро – мост, то оно является единственным способом соединить две компоненты, а значит, оно принадлежит любому MST. Итак, для мостов ответ равен «any», а для всех остальных – «at least one».
+
+Рассмотрим алгоритм Краскала (или Крускала – кто как привык). В нем в MST пытаются добавляться ребра в порядке возрастания их весов. Но если у двух ребер вес одинаковый, то их порядок добавления может быть любым, а значит, одно ребро может зависить от того, добавилось раньше другое ребро того же веса, или оно добавится позже.
+
+А значит, мы можем решать задачу по слоям: на каждом слое мы рассматриваем одновременно все ребра с данным весом, а сами слои – в порядке возрастания веса.
+
+Построим на каждом слое отдельный граф, причем вершинами будут являться уже сформированные на данный момент компоненты связности, а ребра добавляются между соответствующими компонентами. Если ребро – петля, то значит, что существует способ связать два конца этого ребра за меньшую стоимость, и это ребро никогда нам не нужно, ответ для него – «none».
+
+Если ребро в построенном графе – мост, то по ранее разобранному случаю, ответ для него «any», а для всех остальных – ответ «at least one». При разборе этих случаев нужно быть аккуратным, потому что при сжатии графа появляются мультиребра, ответ для них всегда «at least one», потому что ни одно из повторяющихся ребер не является мостом.
+
+Решение это задачи можно реализовать за время *O*(*n*·*log*(*n*)).
+
+## [160E - Buses and People](/contest/160/problem/E "Codeforces Round 111 (Div. 2)")
+
+Для начала, промасштабируем все координаты и времена, а также, так как все *t**i* различны, то запомним для каждого *t**i* номер автобуса, который поедет с этим временем.
+
+Для каждого автобуса создадим событие вида «при координате *s**i* появляется автобус, который поедет в момент времени *t**i* и уедет до точки *f**i*». Для каждого человека создадим событие вида «при координате *l**i* появляется человек, который поедет в момент времени *b**i* и уедет до точки $r_i$».
+
+Эти события отсортируем в порядке возрастания координаты (*s**i*, если это автобус, и *l**i*, если это человек) и будем выполнять в этом порядке.
+
+Будем поддерживать структуру данных, в которой для каждого времени *t**i* будем хранить максимальное *f**i* автобуса, который едет в этот момент. Тогда если текущее событие означает автобус, то нужно просто обновить соответствующее значение в структуре данных. А если текущее событие означает человека, который в момент времени *b**i* поедет до остановки *r**i*, то нужно с помощью структуры данных отвечать на запрос «найти в структуре минимальную позицию *t*, которая не менее *b**i*, а соответствующее ему значение не менее *r**i*», тогда соответствующий этому *t* номер автобуса и есть ответ.
+
+Вопрос в том, какую структуру данных использовать. Проще всего это делать с помощью дерева отрезков по максимуму, тогда на этот запрос можно отвечать за время *O*(*log*(*n*)), но также можно было использовать и другие структуры данных, например декартово дерево с неявным ключом и др.
+
+Таким образом авторское решение работает за время *O*((*n* + *m*)·*log*(*n* + *m*)).
+
+Существует достаточно простое решение с двумерным деревом отрезков, работающее за *O*((*n* + *m*)·*log*2(*n* + *m*)), но не гарантировалось, что оно уложится в Time Limit.
diff --git a/editorials/162.md b/editorials/162.md
@@ -0,0 +1,180 @@
+Source: https://codeforces.com/blog/entry/4139
+
+So here goes the editorial. Note that Factor allows pretty random codes, feel free to put all words in one line, but all words must be separated by at least one space, don't try to skip a space between a bracket and a word or something like that.
+
+#### [162A - Pentagonal numbers](/contest/162/problem/A "VK Cup 2012 Wild-card Round 1")
+
+This problem was almost the same as [130A - Hexagonal numbers](/contest/130/problem/A "Unknown Language Round 4") from Befunge round. Data input and output is done exactly as in the sample code, and besides them the program needs only basic stack operations.
+
+```
+USING: io kernel math math.parser ;
+
+readln string>number
+dup 3 * 1 - * 2 /
+number>string print
+```
+
+Factor has a very system of built-in libraries which liberate the programmer from solving a lot of basic routine tasks. So after the first (trivial) probllem I gave several one-liners which needed only to find a proper library for the task.
+
+#### [162B - Binary notation](/contest/162/problem/B "VK Cup 2012 Wild-card Round 1")
+
+This problem can be solved in several ways; the shortest one is to use >bin word from math.parser dictionary which does exactly what we need.
+
+```
+USING: io kernel math math.parser ;
+
+readln string>number 2 >base print
+```
+
+#### [162C - Prime factorization](/contest/162/problem/C "VK Cup 2012 Wild-card Round 1")
+
+Looks like here I misestimated the complexity of the problem; D and E turned out to be easier. Actually, another library function, factors from math.primes.factors, performs all primes decomposition and even returns them as a sequence in a correct order. The second line converts a sequence of numbers into a sequence of strings (map combinator applies operations in square brackets to every element of the sequence). Finally, join concatenates elements of a sequence and inserts * between them.
+
+```
+USING: io kernel math math.parser math.primes.factors sequences ;
+
+readln string>number factors
+[ number>string ] map
+"*" join print ;
+```
+
+#### [162D - Remove digits](/contest/162/problem/D "VK Cup 2012 Wild-card Round 1")
+
+This is yet another problem with multiple approaches possible — for example, one could find non-digits using a regular expression and concatenate them. My solution used replace word:
+
+```
+USING: math math.parser peg peg.parsers peg.search io kernel ;
+
+readln 'integer' [ drop "" ] action replace print
+```
+
+#### [162E - HQ9+](/contest/162/problem/E "VK Cup 2012 Wild-card Round 1")
+
+Now this is a match for regular expression. Word matches? checks whether the given string matches the given regular expression and pushes a boolean result on the stack. Word if checks this result and prints YES or NO depending on its value.
+
+```
+USING: io kernel regexp ;
+
+readln R/ \S*[HQ9]\S*/ matches?
+[ "YES" ]
+[ "NO" ]
+if
+print
+```
+
+The problems from the second part of the match required not only googling but also learning some deeper aspects of the language.
+
+#### [162F - Factorial zeros](/contest/162/problem/F "VK Cup 2012 Wild-card Round 1")
+
+The quantity of tailing zeros of factorial is defined by the number of 5s this factorial is divisible by (matching 2s are more numerous, there will be enough of them). This number, in turn, can be calculated as *n* / 5 + *n* / 25 + *n* / 125 + ... + *n* / 390625. Note that here we need to use integer division (/i) or round each division result down using truncate, otherwise the leftovers might add up and produce a couple of extra zeros.
+
+The reference solution contained elements of precalculation (to avoid the loop to calculate the powers of 5) and a named variable n (to avoid remembering the order of things on the top of the stack).
+
+```
+USING: io formatting kernel locals math math.parser math.functions sequences ;
+IN: trailing-zeros
+
+:: trailing-zeros ( -- )
+ readln string>number :> n
+ { 5 25 125 625 3125 15625 78125 390625 }
+ 0
+ [ n swap / truncate + ] reduce
+ "%d" printf ;
+
+trailing-zeros
+```
+
+#### [162G - Non-decimal sum](/contest/162/problem/G "VK Cup 2012 Wild-card Round 1")
+
+This problem turned to be the hardest in the contest, and this surprised me a lot. It could be solved in a way similar to "42" example program, with minor modifications: after reading the quantity of numbers we had to read radix and store it to a named variable (for convenience only), and in the loop body strings had to be converted to numbers using base> word instead of string>number. Finally, the result had to be printed using >base instead of number>string.
+
+```
+USING: io kernel locals math math.parser sequences unicode.case ;
+IN: basesum
+
+:: basesum ( -- )
+ readln string>number iota
+ readln string>number :> base
+ 0
+ [ drop readln base base> + ] reduce
+ base >base >upper print ;
+
+basesum
+```
+
+**Update** The docs for the language say that words >base and base> work for radixes only up to 16; actually they work with larger radixes as well, but this lessens my surprise at the complexity of this problem.
+
+#### [162H - Alternating case](/contest/162/problem/H "VK Cup 2012 Wild-card Round 1")
+
+In this problem I finally needed a real while loop! The first square brackets contain the continuation condition, the second ones — the loop body. I used it to slice the string in two-character pieces (and a leftover), convert each of them into title case (first letter is uppercase, the rest are lowercase) and print it without newline after it. The same process was applied to the leftover piece 1 or 2 characters long.
+
+```
+USING: io formatting kernel math sequences unicode.case ;
+
+readln
+[ dup length 2 > ]
+[ 2 cut swap >title "%s" printf ]
+while
+>title print
+```
+
+[Skiminok](/profile/Skiminok "Expert Skiminok") suggested a shorter and cleaner code:
+
+```
+USING: io kernel math sequences ascii ;
+readln [ odd? [ ch>lower ] [ ch>upper ] if ] map-index print
+```
+
+#### [162I - Truncatable primes](/contest/162/problem/I "VK Cup 2012 Wild-card Round 1")
+
+The second hardest problem, based on OEIS sequence [A024785](http://oeis.org/A024785/). One can use a library word prime? for primality testing, so the main part of the solution is another while-loop which checks whether the string contains a prime and removes its leftmost character. Note that the value of answer is not final at its first assignment, it will be modified later so you have to add ! to its name whenever assigning to it.
+
+```
+USING: io formatting locals kernel math math.parser math.primes sequences unicode.case ;
+IN: truncatable-primes
+
+:: trancatable ( str -- )
+ "YES" :> answer!
+ str
+ [ dup length 0 > ]
+ [ dup string>number prime? [ "NO" answer! ] unless
+ 1 cut swap drop
+ ]
+ while
+ drop
+ answer print ;
+
+readln
+trancatable
+```
+
+#### [162J - Brackets](/contest/162/problem/J "VK Cup 2012 Wild-card Round 1")
+
+Judging by the number of solutions submitted, I misestimated this problem as the hardest one. My solution was based on counting the brackets which stay open.
+
+```
+USING: io formatting locals kernel math sequences unicode.case ;
+IN: balanced-brackets
+
+:: balanced ( str -- )
+ 0 :> counter!
+ 1 :> ok!
+ str
+ [ dup length 0 > ]
+ [ 1 cut swap
+ "(" = [ counter 1 + counter! ] [ counter 1 - counter! ] if
+ counter 0 < [ 0 ok! ] when
+ ]
+ while
+ drop
+ ok 0 =
+ [ "NO" ]
+ [ counter 0 > [ "NO" ] [ "YES" ] if ]
+ if
+ print ;
+
+readln
+balanced
+```
+
+Check out [another editorial](https://codeforces.com/blog/entry/4140) by [wjomlex](/profile/wjomlex "Candidate Master wjomlex") which relies heavily on recursion. Evidently, recursion is a natural response of a high-rated contestant to a functional language — well, I used none :-)
diff --git a/editorials/164.md b/editorials/164.md
@@ -0,0 +1,147 @@
+Source: https://codeforces.com/blog/entry/4303
+
+[164A - Переменная, или Туда и обратно](/contest/164/problem/A "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — dfs, O(E).**
+
+Пустим поиск в глубину из всех вершин, где переменная присваивается. Пометим все посещенные.
+
+Пустим поиск в глубину по обратным ребрам из всех вершин, где переменная используется. Запретим ему проходить по вершинам, где переменная присваивается. Пометим все посещенные.
+
+Вершины помеченные оба раза — это и есть те вершины, где состояние Васи кого-то волнует
+
+[164B - Древние берляндские иероглифы](/contest/164/problem/B "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — метод двух указателей, O(N).**
+
+Давайте для удобства предположим, что каждый символ в каждой строке встречается ровно один раз.
+
+Тогда у нас есть перестановка *p**i* (позиция во второй строке *i*-го символа первой строки)
+
+Решение за квадрат теперь такое: фиксируем начало подстроки и идем по ней вперед, при этом параллельно идем по подпоследовательности и следим, что и там, и там мы не прошли больше круга.
+
+Решение за линию.
+
+Будем теперь идти двумя указателями "начало подстроки" и "конец подстроки". Параллельно будем хранить очередь — текущая парная подпоследовательность. В очереди все *p**i* обязательно возрастают (этого не сложно достичь, т.к. можно прибавлять к *p**i* число *n* столько раз, сколько нужно. То что подпоследовательность не зациклилась проверяется так *queue*.*first* - *queue*.*last* < *n*. Значит, мы можем двигать конец подстроки вперед, пока это неравенство выполнено. Как только конец подстроки нельзя увеличить, увеличиваем начало. Заметим, что начало и конец подстроки также двигаются по кругу.
+
+Альтернативное решение:
+
+После того, как мы увидели перестановку *p*, можно воспользоваться методом двоичных подъемов и получить решение за O(NlogN), которое тоже получало Accepted.
+
+[164C - Автоматное программирование](/contest/164/problem/C "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — MinCost flow, O(*N*2 K) или O(NlogN K).**
+
+Самое главное было — увидеть граф, где вершины = задания, множества заданий, выполняемые автоматами = вершиннонепересекающиеся пути, а ребра можно было строить двумя способами (см. ниже).
+
+Как сделать пути вершиннонепересекающимися? Раздвоить вершины.
+
+Как добавить стоимость? Между двумя половинками вершины должна быть стоимость - *c**i*.
+
+Первый способ, граф *G*1 : вершины A, B соединены ребром, если после задания A можно успеть выполнить задание B тем же автоматом. Тогда ребер *O*(*N*2).
+
+Второй способ, граф *G*2 : все вершины упорядочены по *s**i* из вершины i ведут два ребра — в *i* + 1 (не берем *i* задание, пробуем взять следующее) и в вершину с минимальным *j* : *s**j* ≥ *s**i* + *t**i* (берем задание, переходим к минимальному из возможных следующих). Тогда ребер *O*(*N*).
+
+Если вы пользовались первым способом и для поиска пути реализовали одну из вариаций алгоритма Форда-Беллмана, то вы могли получить TL. Собственно пока из-за того, что на java все медленно, TL не подняли, все Форд-Беллманы кроме одного особенного получали заслуженный TL.
+
+Чтобы в *G*1 использовать Дейкстру с потенциалами, удобнее всего было заметить, что граф ацикличен и первый раз расстояния посчитать за O(E).
+
+[164D - Минимальный диаметр](/contest/164/problem/D "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — бинпоиск по ответу, а внутри перебор за O(Fib(K)).**
+
+Правильное решение состояло из четырех несложных идей:
+
+1) Нужно из *N*2 ребер покрыть удаленными вершинами сколько то максимальных. Когда мы покрываем еще не покрытое ребро, у нас 2 варианта это сделать — выбрать 1 конец, выбрать второй конец. Эта идея сама по себе давала асимптотику *O*(2*K* * *N*).
+
+2) Если сделать бинпоиск по ответу, то мы решаем более простую задачу: можно ли покрыть первые X ребер K вершинами? Т.е. правда ли, что размер контролирующего множества в таком графе не более K.
+
+3) Если мы теперь внутри бинпоиска не берем какую-то вершину, то мы должны брать всех ее соседей в уменьшенном графе. Из этого можно сделать 2 вывода: во-первых, если есть вершина степени больше чем K, ее брать обязательно, во-вторых, не выгодно брать вершину степени 1.
+
+4) Теперь решение работает за log * Fib(K) * K, где log — константа от бинпоиска, Fib(K) — K-е число Фибоначчи, K --- максимальная степень вершины в уменьшенном графе.
+
+Почему Fib(K)? Теперь, когда мы делаем выбор, в одной ветке рекурсии K уменьшается на 1, а в другой хотя бы на 2... На лицо числа Фибоначчи.
+
+P.S. Из похожих задач я знаю вот эту: [задача 2 с РОИ 2009-2010](http://neerc.ifmo.ru/school/archive/2009-2010/ru-olymp-roi-2010-statements.rar)
+
+[164E - Поликарп и работы](/contest/164/problem/E "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — жадность + куча запросов на отрезке, асимптотика = O(NlogN).**
+
+В этой задаче так и не получилось написать очевидное условие...
+
+Расскажу некоторую легенду, чтобы дать понять, что задачка не искусственна, взята из "реальной жизни".
+
+Все вы читали задачу C. Давайте чуть поменяем ее, скажем, что автомат у нас один, а работа должна начаться не раньше *l**i*, закончиться на позже *r**i*, а времени на нее уйдет *t**i*. Рассмотрим случай, когда *l**i* и *r**i* возрастают.
+
+Попробуем придумать жадное решение: отсортируем все работы по *l**i* и будем пытаться "брать". Если можно взять, то выполнять работу будем в минимально возможный момент времени.
+
+Это жадное решение не сложно завалить тестом (L=1, R=10, T=10), (L=2,R=11,T=5), (L=3,R=12,T=5).
+
+Поэтому давайте жадность улучшим, попробуем, если добавить в конец не получается менять на кого-нибудь так, чтобы правый конец (последний использованный момент времени) максимально уменьшился.
+
+Собственно задача E состояла в моделировании процесса. В том, чтобы запрограммировать эту жадность.
+
+**Итак, решение:**
+
+Для каждого отрезка определим величину *shift**i* = *s**i* — *l**i* (насколько можно отрезок подвинуть влево).
+
+У нас уже есть *k* отрезков. Добавляем *k* + 1-й, не получается. Пробуем сделать замену. Перебираем все отрезки в порядке уменьшения индекса, смотрим, насколько уменьшится правый конец.
+
+Это min(*t**i*, min по j=i+1..k (*shift**j*)).
+
+Т.е. ни один из отрезков из 1..i уже не даст ответ лучше, чем min(max по j=i+1..k (*t**j*), min по j=i+1..k (*shift**j*)).
+
+Зачем я выдумал этот максимум? Дело в том, что под минимумом теперь две функции, убывающая и возрастающая. Значит, максимум можно искать бинарным или троичным поиском.
+
+Следующая идея заключается в том, что когда мы нашли оптимальную замену *besti*, то чтобы пересчитать все *shift**j*, достаточно сделать вычитание на отрезке besti+1..k
+
+Полученное решение имеет асимптотику *O*(*Nlog*2*N*). Его можно улучшить до *O*(*NlogN*), заменив бинпоиск, а внутри него обращение к дереву поиска или дереву отрезков на один спуск по дереву.
+
+**UPD:**
+
+**По просьбам участников выкладываю "разбор" задач A,B,C второго дивизиона.**
+
+Задачи второго дивизиона я не готовил, не читал, не решал. Но вроде бы, если почитать, они решаются так, как описано ниже. Так что разбор второго дивизиона не стоит воспринимать как авторский, это просто рассказ "как бы я решал эти задачки". Надеюсь, нигде не наврал.
+
+[Задача A](https://codeforces.com/contest/174/problem/A)
+
+X = (*a*1 + *a*2 + ... + *a**n* + b) / n.
+
+Если *X* **меньше** максимального *a**i*, то нельзя сделать так, как просят. Иначе нужно вывести числа X — *a**i*.
+
+[Задача B](https://codeforces.com/contest/174/problem/B)
+
+**Решение #1, жадное:**
+
+Если между двумя точками больше 11 или меньше 2 символов, то нельзя так разрезать.
+
+Если перед первой точкой больше 8 символов, то нельзя так разрезать.
+
+Если между после последней точки больше 3 символов, то нельзя так разрезать.
+
+А иначе режем жадно :-) Если количество символов между двумя точками равно X, то разрез проводится в позиции min(8,X-1).
+
+**Решение #2, DP:**
+
+is[i] — можем ли мы разрезать префикс длины *i*.
+
+Изначально is[0] = 1, остальные нули.
+
+Теперь перебираем *i* в порядке возрастания и если is[i] = 1, пытаемся сделать переход в *i* + 1..*i* + 12.
+
+[Задача C](https://codeforces.com/contest/174/problem/C)
+
+Основная идея — жадность.
+
+Если минимум на всем массиве равен нулю, то задача естественным образом распадается на подзадачи, а иначе нужно уменьшить весь отрезок на 1.
+
+**Решение #1, ищем минимум**
+
+Ищем минимум в массиве, вычитаем 1 из всего массива *min* раз, задача распадается на несколько (т.е. в каждый момент времени, задача = отрезок исходного массива). Минимум на отрезке нужно искать быстро, за O(logN), например.
+
+**Решение #2, простое**
+
+Будем идти слева направо и хранить, сколько у нас отрезков уже начато торчит налево, пусть это X. Если *X* < *a**i*, то нужно начать несколько новых отрезков, если же *X* > *a**i*, то несколько уже начатых нужно закончить в позиции *i* - 1. Начатые отрезки можно хранить в стэке. Хранить, конечно, нужно только позицию начала. Новый *X* будет равен *a**i*.
+
+**Конец.**
diff --git a/editorials/165.md b/editorials/165.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/4124
+
+[165A - Supercentral Point](/contest/165/problem/A "Codeforces Round 112 (Div. 2)")
+
+In this problem you should just code what was written in the problem. For every point you can check if it is supercentral. Consider every point consecutively and find neighbors from every side. The complexity is *O*(*N*2).
+
+[165B - Burning Midnight Oil](/contest/165/problem/B "Codeforces Round 112 (Div. 2)")
+
+This problem can be solved using binary search for the answer. obviously, if number *v* is an answer than every number *w* > *v* is also the answer, because the number of written lines of code could only become more. To check some number *v* you can use formula given in the problem, because it will have less than *O*(*logN*) positive elements. The complexity is *O*(*log*2(*N*)).
+
+[165C - Another Problem on Strings](/contest/165/problem/C "Codeforces Round 112 (Div. 2)")
+
+You was to find number of segments [*lf*;*rg*] of the strings on which the sum equals to *k* (we are working with array of integers 0 and 1). We will count array *sum* where the value *sum*[*i*] equals to sum on segment [0;*i*]. We will count the answer going from left to right. Let's say we are in position *pos*. Now we will add the number of segments on which the sum equals to *k* and ends in position *pos*. To do it we will count array *cnt* where *cnt*[*i*] — number of occurrences of *sum*[*i*]. Then in position *pos* we add *cnt*[*sum*[*pos*] - *k*] to the answer. The complexity is *O*(*N*).
+
+[165D - Beard Graph](/contest/165/problem/D "Codeforces Round 112 (Div. 2)")
+
+Beard-graph is a tree. It consists of one root and several paths from this root. There is a single path between every pair of vertices. That's why you should check whether every edge on the path between two vertices is black. If some edge is white there is no path between two vertices now.
+
+The distances could be found separately. For every vertex *v* precalc such information: index of path from the root where *v* is situated and *d*[*v*] distance between root and *v*. If you know such information you can find distance between any two vertices.
+
+To check whether every edge on the path between two vertices is black we will use segment tree. Mark black edge with value 0 and white with 1. Than repainting some edge — update in some point. The query — sum on some segment (the path between two vertices). If the sum equals to 0 there is a single path. Else the answer is -1 now. Complexity is *O*(*NlogN*).
+
+[165E - Compatible Numbers](/contest/165/problem/E "Codeforces Round 112 (Div. 2)")
+
+Consider some number *x* from the array. Inverse all bits in *x* and say it is number *y*. Consider an integer *a*[*i*] from array. It can be an answer to the number *x* if for every position of zero bit from *y* there is zero bit in *a*[*i*] in the same position. Other bits in *a*[*i*] we can change to ones.
+
+Then we will use such dynamic programming *z*[*mask*] = {0, 1} which means if we can change some zero bits to ones in some integer from given array *a* and get mask *mask*. Initial states are all integers from array *a* (*z*[*a*[*i*]] = 1). To go from one state to another we consider every bit in *mask* and try to change it to one. The length of bit representation of all integers in *a* is less or equal than 22.
+
+To answer the question YES or NO for some number *x* you need to get value [*z*(*y*)&(1«22) - 1] (inverse all bits in *x* and make the length of the number 22). If you want to know the exact answer what number *a*[*i*] you should choose you can save previous states for every state *z*[*mask*] or just save it in *z*[*mask*]. Complexity *O*(2*K* * *K*), where *K* – length of bit representation of numbers (*K* < = 22).
diff --git a/editorials/166.md b/editorials/166.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/4173
+
+Initially the order of problems was A-C-E-D-B. But we were not sure about last two.
+
+[166A - Rank List](/contest/166/problem/A "Codeforces Round 113 (Div. 2)")
+
+This is simple straight-forward problem — you were asked to sort the teams with the following comparator: (*p*1 > *p*2) or (*p*1 = *p*2 and *t*1 < *t*2). After that you can split the teams into groups with equal results and find the group which shares the *k*-th place. Many coders for some reason used wrong comparator: they sorted teams with equal number of problems by descending of time. Such submits accidentally passed pretests but get WA #13.
+
+[166B - Polygons](/contest/166/problem/B "Codeforces Round 113 (Div. 2)")
+
+Polygon A is convex, so it is sufficient to check only that every vertex of polygon B is strictly inside polygon A. In theory the simplest solution is building common convex hull of both polygons. You need to check that no vertex of polygon B belongs to this hull. But there is a tricky detail: if there are many points lying on the same side of convex hull than your convex hull must contain all these points as vertices. So this solution is harder to implement and has some corner case.
+
+Another solution: cut polygon A into triangles (by vertex numbers): (1, 2, 3), (1, 3, 4), (1, 4, 5), ..., (1, *n* - 1, *n*). The sequences of angles 2 - 1 - 3, 2 - 1 - 4, 2 - 1 - 5, ..., 2 - 1 - *n* is increasing. It means that you can find for each vertex of B to which triangle of A it can belong using binsearch by angle.
+
+Similarly you can cut polygon A into trapezoids (with vertical cuts). In this case you'll need a binsearch by *x*-coordinate.
+
+[166C - Median](/contest/166/problem/C "Codeforces Round 113 (Div. 2)")
+
+If the initial array doesn't contain number *x*, than you definitely need to add it (that's +1 to answer). Than do the following. While median is strictly less than *x* you need to increase it. Obviously the surest way to increase the median is to add a maximal possible number (105). Similarly while the median is strictly more than *x*, add a number 1 to the array. Constraints are small, so you can add the numbers one by one and recalculate the median after every addition.
+
+Also there is a solution without any cases: while the median isn't equal to *x*, just add one more number *x* to array.
+
+[166D - Shoe Store](/contest/166/problem/D "Codeforces Round 113 (Div. 2)")
+
+Let's sort the people by decreasing of shoes size. Observe that when considering the *i*-th man we are interested in no more than 2 pairs of shoes: with size *l**i* and *l**i* + 1. It allows solving with dynamics. The state will be (the number of first unconsidered man *i*, is pair of shoes with size *l**i* available, is pair of shoes with size *l**i* + 1 available). You have 3 options: leave the *i*-th man without shoes or sell him a pair of shoes of one of suitable size (if available).
+
+[166E - Tetrahedron](/contest/166/problem/E "Codeforces Round 113 (Div. 2)")
+
+Obvious solution with dynamics: you need to know only how many moves are left and where is the ant. This is 4*n* states, each with 3 options – most of such solution passes. Observe that the vertices A, B, C are equivalent. This allows writing such solution:
+
+```
+int zD = 1;
+int zABC = 0;
+for (int i = 1; i <= n; i++) {
+ int nzD = zABC * 3LL % MOD;
+ int nzABC = (zABC * 2LL + zD) % MOD;
+ zD = nzD;
+ zABC = nzABC;
+}
+cout << zD;
+```
+
+Also this problem could be solved by *log*(*n*) with binary exponentiation of some 2 × 2 matrix into power *n*.
diff --git a/editorials/167.md b/editorials/167.md
@@ -0,0 +1,73 @@
+Source: https://codeforces.com/blog/entry/4214
+
+I am sorry for mistakes in English and I will be glad if you tell me about them.
+
+#### [168A - Wizards and Demonstration](/contest/168/problem/A "Codeforces Round 114 (Div. 2)") Аuthor [PavelKunyavskiy](/profile/PavelKunyavskiy "Grandmaster PavelKunyavskiy").
+
+In this task, it was necessary to write exactly what has been described in statement. In particular, it was necessary to have  people, who come to the meeting. For this it was necessary to create 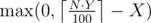 clones.
+
+#### [168B - Wizards and Minimal Spell](/contest/168/problem/B "Codeforces Round 114 (Div. 2)") Аuthor [PavelKunyavskiy](/profile/PavelKunyavskiy "Grandmaster PavelKunyavskiy").
+
+In this problem you had to write exactly what has been described in statment too. Read lines one by one. Also keep the last block of lines that are not amplyfying. If the next line is amplyfying (which can be checked by linear search), we print the last block, if any, and the line itself. Otherwise, remove all spaces from the string and add to the last block. It only remains to distinguish between an empty block and a block of empty lines.
+
+#### [167A - Wizards and Trolleybuses](/contest/167/problem/A "Codeforces Round 114 (Div. 1)") Аuthor [Alex-Gran](/profile/Alex-Gran "Expert Alex-Gran").
+
+This was the first problem where you had a little bit away from translating statements to a programming language. Because acceleration trolleybuses are all the same and they can slow down immediately, the answer for the next trolleybus is the maximum of the time when it would come if it were not to stop when he reach the rest trolleybuses which was traveling in front of him and the arrival time of the previous trolleybus.
+
+It remains only to calculate the arrival time of each trolleybus if ignore others. Here, the easiest way to analyze two cases. If , then trolley should accelerate as long as it can and the answer is equal to . Otherwise the trolley should accelerate all the time and the answer is equal to .
+
+#### [167B - Wizards and Huge Prize](/contest/167/problem/B "Codeforces Round 114 (Div. 1)") Author [PavelKunyavskiy](/profile/PavelKunyavskiy "Grandmaster PavelKunyavskiy").
+
+This problem can be solved using dynamic programming.
+
+Let d[i][j][m] — the probability we won j of first i days and get bags total capacity of m. For convenience, we assume that the bag is also a prize and the prize is a bag of capacity 0. To do that, retaining a task we must add 1 to all a[i]. Then from d[i][j][m] we can go to the d[i+1][j+1][m+a[i]] with probability p[i]/100, and to d[i+1][j][m] with probability 1-p[i]/100. The answer will be the sum of d[n+1][j][m] for all j,m such that *L* ≤ *j* ≤ *m* + *k*. This solution works for 2004, and do not fit into the time limit.
+
+It remains to note that if we have over 200 places for prizes, it does not matter how many exactly. So we need to calculate states with *m* ≤ 200 and now solution works for 2003.
+
+#### [167C - Wizards and Numbers](/contest/167/problem/C "Codeforces Round 114 (Div. 1)") Author [Alex-Gran](/profile/Alex-Gran "Expert Alex-Gran").
+
+Consider the position (a, b). Let a < b. From this there is a move to . Recursively check if this position is a winning or a losing. If it is losing, then (a, b) exactly winning. Otherwise, no one will take the remainder. So everyone will subtract from larger number nonnegative degree of smaller. Then the left to learn to solve such problem. You can subtract the nonnegative powers of a from x, and player who cannot move losses. And solve it for . This problem can be solved as follows. If a is odd, then all odd number are wining. In other all the numbers, giving an odd residue modulo a+1 or -1 residue on the same module are wining. This can be easily proved by induction.
+
+#### [167D - Wizards and Roads](/contest/167/problem/D "Codeforces Round 114 (Div. 1)") Author [PavelKunyavskiy](/profile/PavelKunyavskiy "Grandmaster PavelKunyavskiy").
+
+This was the first really hard problem in the contest. One of the challenges was to understand the statement. I hope that we had written the statement as clear as it possible in this problem.
+
+Consider this graph. In particular, we consider more closely the point with the largest y.
+
+1) It is connected with the highest points on the left and right of it.
+
+2) It is not connected to all other points.
+
+3) It is inside all corners on points from different sides of it.
+
+All three of these properties are seen quite clearly in the pictures.
+
+So,
+
+1) Building roads on the left and right sides are independent.
+
+2) The graph is a tree.
+
+Once a graph is a tree, the maximum matching in it can be found greedy, or with a simple dynamic. But it works in linear time, which clearly is not enough to answer all of 105 queries.
+
+But this is not just a tree! Those who know what it is probably already noticed, that it is Cartesian tree (also known as treep). This allows to get a tree for the subsegments in time which is *O*(*h*), counting all the necessary dynamics, where h is the height of the tree.
+
+Well, since the city built at random points (the method for the construction of cities guarantees this), the height of the tree *h* = *O*(*K* + *logN*).
+
+#### [167E - Wizards and Bets](/contest/167/problem/E "Codeforces Round 114 (Div. 1)") Author [Dmitry_Egorov](/profile/Dmitry_Egorov "International Master Dmitry_Egorov").
+
+This task was about the pathes from the sources to sinks. For this pathes there was a condition which made them dependent — they should not interfere at vertexes. But in any combinatorics is much easier when everything is independent. So we should try to get rid of the condition of the absence of crossings at the vertices. It is very easy — just forget about it. Lets understand why the answer will not change: Suppose that a certain set of ways in which the two paths intersect. We show that taking into account this way, we at the same time take into account an another with the opposite sign. To do this, change the endings for paths that intersect. The signum of the permutation in this case has changed, so this set of paths is taken into account with the opposite sign and their sum is 0.
+
+How can it helps us? If we fix the permutation, the number of sets of paths that it corresponds well to the product of the number of paths for each pair of corresponding source and sink.
+
+Suppose that from the i-th source in the j-th sink there are *cnt**ij* paths. This value can be calculated by depth-first-search and simple dynamic.
+
+Then the answer is
+
+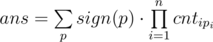
+
+. This value is called the determinant of matrix cnt, which can be calculated using Gauss method in *O*(*S*3) time where S is the number of sinks and sources.
+
+And we had to remember about isolated vertexes. Deleting one of them either do not change the answer or multiply the answer by -1.
+
+It remains to see that after deleting all isolated vertexes 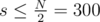, and 3003 fine fits into TL.
diff --git a/editorials/169.md b/editorials/169.md
@@ -0,0 +1,112 @@
+Source: https://codeforces.com/blog/entry/4187
+
+** UPD: Formulas are already fixed. **
+
+**[163A - Substring and Subsequence](/contest/163/problem/A "VK Cup 2012 Round 2")**
+
+Solution summary: dynamic programming.
+
+Sample jury solution: [1415300](/contest/163/submission/1415300 "Submission 1415300 by Burunduk1") (author = [levlam](/profile/levlam "Master levlam"))
+
+The problem could be solved with the following dynamic programming. Let *f*[*i*, *j*] be the number of distinct pairs ("substring starting at position *i*" and "subsequence of the substring *t*[*j*... |*t*|]")
+
+Then:
+
+```
+f[i, j] = f[i, j + 1];
+if (s[i] == t[j])
+ add(f[i, j], f[i + 1, j + 1] + 1)
+```
+
+Answer =  f[i,0]
+
+**[163B - Lemmings](/contest/163/problem/B "VK Cup 2012 Round 2")**
+
+Solution summary: sorting + binary search.
+
+Sample jury solution: [1415306](/contest/163/submission/1415306 "Submission 1415306 by Burunduk1") (author: [Burunduk1](/profile/Burunduk1 "Grandmaster Burunduk1"))
+
+We need to find the minimal time *T*. Let us find it using binary search.
+
+Once the time is fixed, one can arrange lemmings using greedy approach starting either from the top or from the bottom. In this solution we consider the way to start from the bottom. Among all lemmings, that can get on the first ledge, let's choose the lemming with the minimal weight (and among all such lemmings the one with the minimal speed). Why is it correct? Assume that we used some heavier lemming, then we can't use any lighter lemming anywhere, so we could replace it. Among all lemmings with the minimal weight we choose the slowest, as the faster ones can climb higher.
+
+To arrange lemmings fast, we can sort them beforehand, comparing first the weight and then the speed. After if, we consider all the lemmings in that order and either choose the current one, if it can get in time, or leave it. It is useless to consider one lemming twice, as we won't be able to use it anyway.
+
+So, the solution consists of sorting and a binary search with a linear search inside. The time is .
+
+However, that was not enough. One also had to deal with precision problems. Let us evaluate the number of binary search iterations.
+
+0 ≤ *T* ≤ *H* * *K* (the maximal time does not exceed 109). We need to understand how the times can differ. In the case of "N = K = 105, H = 104, V about 109" the times needed for two lemmings to get on some ledges, can differ by 10- 18, as the times are fractions like , where *X* and *Y* are about 109.
+
+So we need to make *log*21027 = 90 iterations. In fact, jury solution made 75 and that was enough, however 70 was not. The idea above shows that 90 will be definitely enough.
+
+**[163C - Conveyor](/contest/163/problem/C "VK Cup 2012 Round 2")**
+
+Solution summary: events along the circle or binary search.
+
+Sample solution: [1415310](/contest/163/submission/1415310 "Submission 1415310 by Burunduk1") (author: [Burunduk1](/profile/Burunduk1 "Grandmaster Burunduk1"))
+
+Sample solution: [1415316](/contest/163/submission/1415316 "Submission 1415316 by Burunduk1") (author: [arseny30](/profile/arseny30 "Master arseny30"))
+
+Wherever Anton starts, he will run along the conveyor a segment of length . Consider one candy. To eat it, he needs to get on the conveyor in any moment of the segment [*a**i* - *D*..*a**i*]. Consider all points like *a**i* - *D* and *a**i* (add 2*l* if that is negative). Also add points 0 and 2*l*.
+
+Sort these points. Consider two neighboring points: x[i] и x[i+1]. If Anton starts at any moment between them, he will eat the same amount of candies.
+
+From now on, we can create one of the solving solutions:
+
+1. Start from every middle of the segment M = (x[i]+x[i+1]) / 2 and use binary search to find the number of candies on the segment [*M*..*M* + *D*].
+2. Consider events along a circle like (a[i] — D, +1) and (a[i], -1). One needs to move twice along the circle and use the second run to add the current length to the answer for the current number of candies.
+
+The both solutions require  time.
+
+**[163D - Large Refrigerator](/contest/163/problem/D "VK Cup 2012 Round 2")**
+
+Solution summary: backtracking + boundaries evalutaion.
+
+Sample solution: [1415320](/contest/163/submission/1415320 "Submission 1415320 by Burunduk1") (author: [Burunduk1](/profile/Burunduk1 "Grandmaster Burunduk1"))
+
+The solution consists of three main ideas:
+
+1. *V* = *ABC*, *A* ≤ *B* ≤ *C* тогда *A* ≤ *N*1 / 3, *B* ≤ (*N* / *A*)1 / 2.
+2. *A* and *B* are divisors of *V*, as we are already given the factorization of *V*, we can run only through the divisors
+3. Given fixed *A*, the optimal real *B* and *C* are (*N* / *A*)1 / 2 (denote this values as *X*). I.e. the square will always be greater than ≥ 2(2*AX* + *X*2). So we can use this value as a boundary for the answer.
+
+If that still was not enough, one could optimize using the following ideas:
+
+1. Border evaluation will be more useful while running through possible values of *A* in descending order
+2. *A* and *B* are 32-bit integers.
+3. Once we have calculated the answer for *V*, memoize it (this one makes possible maximal test a bit smaller).
+
+If anyone needs any theoretical base, here's some statistical information:
+
+1. The maximal number of divisors of numbers from 1 through 1018 is 103860 (the number 897612484786617600 = 2834527211 ...)
+2. Using only first two optimizations, the number of numbers *A*, found by our solution, is 10 471 (in the case of the number with maximal number of divisors)
+3. Using only first two optimizations, the number of pairs of *A* and *B*, found by our solution, is 128 264 (in the case of the number with maximal number of divisors)
+
+**[163E - e-Government](/contest/163/problem/E "VK Cup 2012 Round 2")**
+
+Solution summary: Aho-Corasick and finding the sum along a way in a tree of suffix links
+
+Sample solution: [1415345](/contest/163/submission/1415345 "Submission 1415345 by Burunduk1") (author: [arseny30](/profile/arseny30 "Master arseny30"))
+
+We assume that the reader is familiar with the Aho-Corasick algorithm ([http://en.wikipedia.org/wiki/Aho-Corasick](https://en.wikipedia.org/wiki/Aho-Corasick))
+
+Consider a trie of names and suffix links over it. For every vertex *v* one can calculate the number of names, ending in that vertex (*end*[*v*]).
+
+Then, the "add name *i*" operation is *end*[*v*[*i*]] += 1, where *v*[*i*] is ending vertex of *i*-th name.
+
+Similarly, "remove name *i*": *end*[*v*[*i*]] -= 1.
+
+To answer a request "calculate how politicized the text is", one needs to know, that the suffix links form a tree. Once we move though the text and simultaneously through the trie with suffix links, we add the sum of all *end*[*v*[*i*]] along the path to the root of the tree of suffix links the politicization of the text.
+
+Now, there's another problem: we need to calculate the sum of weights along a way to the root, the weights may change.
+
+One can do it in the following way:
+
+1. Move the weights from vertices to corresponding edges to vertices' parents
+2. Build the Eulerian traversal of the tree, where the down-move will store positive weight of the edge and up-move will store its negation.
+3. The sum along a path to the root if the sum on a segment of the Eulerian traversal (the endpoints are any entries of the vertices in the traversal).
+
+A fast and short way to calculate the sum on a segment is Fenwick's tree.
+
+Here's a solution running in O(|SumLen| * log) time and 26 * |SumLen| memory (the trie will not be compressed).
diff --git a/editorials/174.md b/editorials/174.md
@@ -0,0 +1,147 @@
+Source: https://codeforces.com/blog/entry/4303
+
+[164A - Переменная, или Туда и обратно](/contest/164/problem/A "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — dfs, O(E).**
+
+Пустим поиск в глубину из всех вершин, где переменная присваивается. Пометим все посещенные.
+
+Пустим поиск в глубину по обратным ребрам из всех вершин, где переменная используется. Запретим ему проходить по вершинам, где переменная присваивается. Пометим все посещенные.
+
+Вершины помеченные оба раза — это и есть те вершины, где состояние Васи кого-то волнует
+
+[164B - Древние берляндские иероглифы](/contest/164/problem/B "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — метод двух указателей, O(N).**
+
+Давайте для удобства предположим, что каждый символ в каждой строке встречается ровно один раз.
+
+Тогда у нас есть перестановка *p**i* (позиция во второй строке *i*-го символа первой строки)
+
+Решение за квадрат теперь такое: фиксируем начало подстроки и идем по ней вперед, при этом параллельно идем по подпоследовательности и следим, что и там, и там мы не прошли больше круга.
+
+Решение за линию.
+
+Будем теперь идти двумя указателями "начало подстроки" и "конец подстроки". Параллельно будем хранить очередь — текущая парная подпоследовательность. В очереди все *p**i* обязательно возрастают (этого не сложно достичь, т.к. можно прибавлять к *p**i* число *n* столько раз, сколько нужно. То что подпоследовательность не зациклилась проверяется так *queue*.*first* - *queue*.*last* < *n*. Значит, мы можем двигать конец подстроки вперед, пока это неравенство выполнено. Как только конец подстроки нельзя увеличить, увеличиваем начало. Заметим, что начало и конец подстроки также двигаются по кругу.
+
+Альтернативное решение:
+
+После того, как мы увидели перестановку *p*, можно воспользоваться методом двоичных подъемов и получить решение за O(NlogN), которое тоже получало Accepted.
+
+[164C - Автоматное программирование](/contest/164/problem/C "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — MinCost flow, O(*N*2 K) или O(NlogN K).**
+
+Самое главное было — увидеть граф, где вершины = задания, множества заданий, выполняемые автоматами = вершиннонепересекающиеся пути, а ребра можно было строить двумя способами (см. ниже).
+
+Как сделать пути вершиннонепересекающимися? Раздвоить вершины.
+
+Как добавить стоимость? Между двумя половинками вершины должна быть стоимость - *c**i*.
+
+Первый способ, граф *G*1 : вершины A, B соединены ребром, если после задания A можно успеть выполнить задание B тем же автоматом. Тогда ребер *O*(*N*2).
+
+Второй способ, граф *G*2 : все вершины упорядочены по *s**i* из вершины i ведут два ребра — в *i* + 1 (не берем *i* задание, пробуем взять следующее) и в вершину с минимальным *j* : *s**j* ≥ *s**i* + *t**i* (берем задание, переходим к минимальному из возможных следующих). Тогда ребер *O*(*N*).
+
+Если вы пользовались первым способом и для поиска пути реализовали одну из вариаций алгоритма Форда-Беллмана, то вы могли получить TL. Собственно пока из-за того, что на java все медленно, TL не подняли, все Форд-Беллманы кроме одного особенного получали заслуженный TL.
+
+Чтобы в *G*1 использовать Дейкстру с потенциалами, удобнее всего было заметить, что граф ацикличен и первый раз расстояния посчитать за O(E).
+
+[164D - Минимальный диаметр](/contest/164/problem/D "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — бинпоиск по ответу, а внутри перебор за O(Fib(K)).**
+
+Правильное решение состояло из четырех несложных идей:
+
+1) Нужно из *N*2 ребер покрыть удаленными вершинами сколько то максимальных. Когда мы покрываем еще не покрытое ребро, у нас 2 варианта это сделать — выбрать 1 конец, выбрать второй конец. Эта идея сама по себе давала асимптотику *O*(2*K* * *N*).
+
+2) Если сделать бинпоиск по ответу, то мы решаем более простую задачу: можно ли покрыть первые X ребер K вершинами? Т.е. правда ли, что размер контролирующего множества в таком графе не более K.
+
+3) Если мы теперь внутри бинпоиска не берем какую-то вершину, то мы должны брать всех ее соседей в уменьшенном графе. Из этого можно сделать 2 вывода: во-первых, если есть вершина степени больше чем K, ее брать обязательно, во-вторых, не выгодно брать вершину степени 1.
+
+4) Теперь решение работает за log * Fib(K) * K, где log — константа от бинпоиска, Fib(K) — K-е число Фибоначчи, K --- максимальная степень вершины в уменьшенном графе.
+
+Почему Fib(K)? Теперь, когда мы делаем выбор, в одной ветке рекурсии K уменьшается на 1, а в другой хотя бы на 2... На лицо числа Фибоначчи.
+
+P.S. Из похожих задач я знаю вот эту: [задача 2 с РОИ 2009-2010](http://neerc.ifmo.ru/school/archive/2009-2010/ru-olymp-roi-2010-statements.rar)
+
+[164E - Поликарп и работы](/contest/164/problem/E "VK Cup 2012 Раунд 3")
+
+**Кратко о решении — жадность + куча запросов на отрезке, асимптотика = O(NlogN).**
+
+В этой задаче так и не получилось написать очевидное условие...
+
+Расскажу некоторую легенду, чтобы дать понять, что задачка не искусственна, взята из "реальной жизни".
+
+Все вы читали задачу C. Давайте чуть поменяем ее, скажем, что автомат у нас один, а работа должна начаться не раньше *l**i*, закончиться на позже *r**i*, а времени на нее уйдет *t**i*. Рассмотрим случай, когда *l**i* и *r**i* возрастают.
+
+Попробуем придумать жадное решение: отсортируем все работы по *l**i* и будем пытаться "брать". Если можно взять, то выполнять работу будем в минимально возможный момент времени.
+
+Это жадное решение не сложно завалить тестом (L=1, R=10, T=10), (L=2,R=11,T=5), (L=3,R=12,T=5).
+
+Поэтому давайте жадность улучшим, попробуем, если добавить в конец не получается менять на кого-нибудь так, чтобы правый конец (последний использованный момент времени) максимально уменьшился.
+
+Собственно задача E состояла в моделировании процесса. В том, чтобы запрограммировать эту жадность.
+
+**Итак, решение:**
+
+Для каждого отрезка определим величину *shift**i* = *s**i* — *l**i* (насколько можно отрезок подвинуть влево).
+
+У нас уже есть *k* отрезков. Добавляем *k* + 1-й, не получается. Пробуем сделать замену. Перебираем все отрезки в порядке уменьшения индекса, смотрим, насколько уменьшится правый конец.
+
+Это min(*t**i*, min по j=i+1..k (*shift**j*)).
+
+Т.е. ни один из отрезков из 1..i уже не даст ответ лучше, чем min(max по j=i+1..k (*t**j*), min по j=i+1..k (*shift**j*)).
+
+Зачем я выдумал этот максимум? Дело в том, что под минимумом теперь две функции, убывающая и возрастающая. Значит, максимум можно искать бинарным или троичным поиском.
+
+Следующая идея заключается в том, что когда мы нашли оптимальную замену *besti*, то чтобы пересчитать все *shift**j*, достаточно сделать вычитание на отрезке besti+1..k
+
+Полученное решение имеет асимптотику *O*(*Nlog*2*N*). Его можно улучшить до *O*(*NlogN*), заменив бинпоиск, а внутри него обращение к дереву поиска или дереву отрезков на один спуск по дереву.
+
+**UPD:**
+
+**По просьбам участников выкладываю "разбор" задач A,B,C второго дивизиона.**
+
+Задачи второго дивизиона я не готовил, не читал, не решал. Но вроде бы, если почитать, они решаются так, как описано ниже. Так что разбор второго дивизиона не стоит воспринимать как авторский, это просто рассказ "как бы я решал эти задачки". Надеюсь, нигде не наврал.
+
+[Задача A](https://codeforces.com/contest/174/problem/A)
+
+X = (*a*1 + *a*2 + ... + *a**n* + b) / n.
+
+Если *X* **меньше** максимального *a**i*, то нельзя сделать так, как просят. Иначе нужно вывести числа X — *a**i*.
+
+[Задача B](https://codeforces.com/contest/174/problem/B)
+
+**Решение #1, жадное:**
+
+Если между двумя точками больше 11 или меньше 2 символов, то нельзя так разрезать.
+
+Если перед первой точкой больше 8 символов, то нельзя так разрезать.
+
+Если между после последней точки больше 3 символов, то нельзя так разрезать.
+
+А иначе режем жадно :-) Если количество символов между двумя точками равно X, то разрез проводится в позиции min(8,X-1).
+
+**Решение #2, DP:**
+
+is[i] — можем ли мы разрезать префикс длины *i*.
+
+Изначально is[0] = 1, остальные нули.
+
+Теперь перебираем *i* в порядке возрастания и если is[i] = 1, пытаемся сделать переход в *i* + 1..*i* + 12.
+
+[Задача C](https://codeforces.com/contest/174/problem/C)
+
+Основная идея — жадность.
+
+Если минимум на всем массиве равен нулю, то задача естественным образом распадается на подзадачи, а иначе нужно уменьшить весь отрезок на 1.
+
+**Решение #1, ищем минимум**
+
+Ищем минимум в массиве, вычитаем 1 из всего массива *min* раз, задача распадается на несколько (т.е. в каждый момент времени, задача = отрезок исходного массива). Минимум на отрезке нужно искать быстро, за O(logN), например.
+
+**Решение #2, простое**
+
+Будем идти слева направо и хранить, сколько у нас отрезков уже начато торчит налево, пусть это X. Если *X* < *a**i*, то нужно начать несколько новых отрезков, если же *X* > *a**i*, то несколько уже начатых нужно закончить в позиции *i* - 1. Начатые отрезки можно хранить в стэке. Хранить, конечно, нужно только позицию начала. Новый *X* будет равен *a**i*.
+
+**Конец.**
diff --git a/editorials/99.md b/editorials/99.md
@@ -0,0 +1,83 @@
+Source: https://codeforces.com/blog/entry/2326
+
+I ended up solving 3 questions.. the 3rd one took me a lot of time because I manually pre-computed all the configurations and wrote them in my code.
+
+Here is a short description on how I solved the 3 problems hopefully it is helpful.
+
+**Problem A**
+
+The first problem required manual checking. As I use Java, StringTokenizer helped me to break the string using '.' as the delimiter. As I had 2 strings I could check for the last character of the first string and if it was equal to 9 I printed "GOTO Vasilisa." and for the other case I checked if the first char of the other string was greater than '5' if yes I added 1 to the first strings last char else print the same string.
+
+**Problem B**
+
+Problem B was easier considering the mathematical nature of the problem. There were a few cases to take care of and a score of 900+ was easily get able. On summing up the volumes if they don't divide equally among the n cups, then the answer is unrecoverable. If all of the values are equal to the average then the pages did not play any prank. On the other hand if more than 2 cups deviate from the average the answer is again unrecoverable. If the number of cups that deviate is 2. We can find the cups which were used for transfer and find the volume transferred by calculating the difference of the values from the mean.
+
+**Problem C**
+
+The problem is easy but during the contest I could not come with a very good approach in one go. I started waywardly and in the end pre computed all the 24 configurations which are equal to each other. Then I just checked how many different configurations can be made using the colors given. Generate all the 720 permutations of the string for that.
+
+For the generation of the 24 configurations I fixed a top and then rotated the cube by 90 degs again and again to get all the 4 configurations for that top. Fixing all the 6 tops. We get in total 6*4=24 configurations as equivalent to each other.
+
+code snippet
+
+//24 configurations given
+
+configs[]={"012345","031425","043215","024135","103254","120534",
+
+"152304","135024","254103","215043","201453",
+
+"240513","310542","351402","345012","304152","453201",
+
+"425031","402351","430521","513240","521430","542310","534120"};
+
+for(int i=0;i<720;i++)
+
+{
+
+boolean different=different(in,conf[i]);
+
+for(int j=0;j<i;j++)
+
+if(!different(conf[i],conf[j]))
+
+{
+
+different=false;
+
+break;
+
+}
+
+if(different)
+
+tot++;
+
+}
+
+boolean different(String a,String b)
+
+{
+
+for(int i=0;i<24;i++)
+
+{
+
+boolean equal=true;
+
+for(int j=0;j<6;j++)
+
+{
+
+if(a.charAt(j)!=b.charAt(configs[i].charAt(j)-'0'))
+
+equal=false;
+
+}
+
+if(equal)
+
+return false;
+
+}return true;
+
+}
