commit 2609231e8134f28c8bba50a44fe995093df7d993
parent 78011188d55d18a2de97aa700880f9318be7c70e
Author: Andrew Laack <andrew@laack.co>
Date:   Mon,  9 Nov 2026 00:26:42 -0600

More editorials

Diffstat:
184 files changed, 14269 insertions(+), 0 deletions(-)
diff --git a/editorials/1.md b/editorials/1.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/85
+
+Problem A.
+
+The constraint that edges of each flagstone much be parralel to edges of the square allows to analyze X and Y axes separately, that is, how many segments of length 'a' are needed to cover segment of length 'm' and 'n' -- and take product of these two quantities. Answer = ceil(m/a) * ceil(n/a), where ceil(x) is the least integer which is above or equal to x. Using integers only, it is usually written as ((m+a-1)/a)*((n+a-1)/a). Note that answer may be as large as 10^18, which does not fit in 32-bit integer.
+
+Most difficulties, if any, contestants had with data types and operator priority, which are highly dependant on language used, so they are not covered here.
+
+Problem B.
+
+Let each letter representation of column number be associated with integer in radix-26, where 'A' = 0, 'B' = 1 ... 'Z'=25. Then, when converting letter representation to decimal representation, we take associated integer and add one plus quantity of valid all letter representations which are shorter than letter representation being converted. When converting from decimal representation to letter representation, we have to decide how many letters do we need. Easiest way to do this is to subtract one from number, then quantity of letter representation having length 1, then 2, then 3, and so on, until next subtraction would have produced negative result. At that point, the reduced number is the one which must be written using defined association with fixed number of digits, with leading zeroes (i.e. 'A's) as needed.
+
+Note that there is other ways to do the same which produce more compact code, but they are more error-prone as well.
+
+Problem C.
+
+The points can be vertices of regular N-polygon, if, and only if, for each pair, difference of their polar angles (as viewed from center of polygon) is a multiple of 2*pi/N. All points should lie on the circle with same center as the polygon. We can locate the center of polygon/circle [but we may avoid this, as a chord (like, say, (x1,y1)-(x2,y2)) is seen at twice greater angle from center, than it is seen from other point of a cricle (x3,y3)]. There are many ways to locate center of circle, the way I used is to build midpoint perpendiculares to segments (x1,y1)-(x2,y2) and (x2,y2)-(x3,y3) in form y = a*x + b and find their intersection. Formula y = a*x + b has drawback that it cannot be used if line is parallel to y, possible workaround is to rotate all points by random angle (using formulae x' = x*cos(a) - y*sin(a), y' = y*cos(a) + x*sin(a) ) until no segments are horizontal (and hence no perperdiculares are vertical).
+
+After the coordinates of the center are known, we use fancy function atan2, which returns angle in right quadrant: a[i] = atan2(y[i]-ycenter, x[i]-xcenter)
+
+Area of regular polygon increases with increasing N, so it is possible just to iterate through all possible values on N in ascending order, and exit from cycle as first satisfying N is found.
+
+Using sin(x) is makes it easy: sin(x) = 0 when x is mutiple of pi. So, for points to belong to regular, N-polygon,
+
+sin( N * (a[i]-a[j]) /2 )=0
+
+because of finite precision arithmetic,
+
+fabs( sin( N * (a[i]-a[j]) /2 ) ) < eps
diff --git a/editorials/13.md b/editorials/13.md
@@ -0,0 +1,60 @@
+Source: https://codeforces.com/blog/entry/364
+
+Let me introduce an editorial to Codeforces Beta Round #13. If you have any questions or propositions - feel free to post them in the comments.
+
+**Problem A.**
+
+It is sufficient to iterate over all bases from 2 to A-2 and find the sum of digits in them. Then one should find the greatest common divisor of found sum and A-2 (which is equal to number of bases in which we found the sums). The numerator of the answer is equal to founded sum divided by this GCD and the denominator is equal to A-2 divided by this GCD.
+
+The complexity is O(A).
+
+**Problem B.**
+
+This problem appeared to be quite unpleasant to code, but all what one need to do is to check whether all three statements are true. It is recommended to perform all computations using integer arithmetics and to use scalar and vector product instead of computing cosines of angles or angles itself.
+
+**Problem C.**
+
+Note, that there exists a non-decreasing sequence, which can be obtained from the given sequence using minimal number of moves and in which all elements are equal to some element from the initial sequence (i.e. which consists only from the numbers from the initial sequence).
+
+Suppose {ai} is the initial sequence, {bi} is the same sequence, but in which all elements are distinct and they are sorted from smallest to greatest. Let f(i,j) be the minimal number of moves required to obtain the sequence in which the first i elements are non-decreasing and i-th element is at most bj. In that case the answer to the problem will be equals to f(n,k), where n is the length of {ai} and k is the length of {bi}. We will compute f(i,j) using the following recurrences:
+
+f(1,1)=|a1-b1|
+
+f(1,j)=min{|a1-bj|,f(1,j-1)}, j>1
+
+f(i,1)=|ai-b1|+f(i-1,1), i>1
+
+f(i,j)=min{f(i,j-1),f(i-1,j)+|ai-bj|}, i>1, j>1
+
+The complexity is O(N2). To avoid memory limit one should note that to compute f(i,*) you only need to know f(i-1,*) and the part of i-th row which is already computed.
+
+**Problem D.**
+
+We will solve the problem using the following algorithm:
+
+1. Fix some red point.
+2. Find the number of triangles with vertices in the red points which don't contain any blue points inside and which have the fixed red point as one of the vertices.
+3. Remove the fixed red point and go back to statement 1, if there remain any red point.
+
+The first and third statements are obvious, so the main part of the solution is statement 2.
+
+Suppose the red point A is fixed (in the first statement). Also suppose we have all other points which are still not removed (blue and red together) sorted by angle around the point A. We will iterate over all red points B, which will be the second vertice of triangle. Now, we need to find the number of triangles with vertices in red points which have points A and B as two vertices and which don't contain any blue point inside.
+
+To solve this problem we will iterate over all unremoved points C in the increasing order of angle ABC starting from the point after the point B (in the same order). To avoid double counting we will stop when the angle between vectors AB and AC become greater than 180 degrees or when we reach the point which was already considered. Then we will perform such actions:
+
+* If C is red then we will check whether there are blue points inside triangle ABC and if not - we will increase the answer by 1. Note, that to perform this check we don't need to iterate over all blue points. It is sufficient to maintain such point D from the ones which we have already seen for which the angle ABD is the smallest possible. If D doesn't lies inside the triangle ABC, then there is no blue point which lies inside it.
+* If C is blue, then we will compare the angle ABC with ABD and if ABC is smaller, we will replace old D with C.
+
+Note, that after choosing new B we consider that there is no point D and there will be no blue points inside triangles ABC until we reach the first blue point.
+
+The complexity is O(N2(N+M)).
+
+**Problem E.**
+
+Let's divide all row into blocks of length K=sqrt(N) of consecutive holes. If N is not a complete square, then we will take K=sqrt(N) rounded down. For each hole we will maintain not only it's power (let's call it power[i]), but also the number of the first hole which belongs to other block and which can be reached from the current one with sequence of jumps (let's call it next[i]). Also, for each hole we will maintain the number of jumps required to reach the hole next[i] from the current one (let's call it count[i]). We will consider that there is a fictious hole, which lies after the hole N and it belongs to it's own block.
+
+To answer the query of the first type (when the ball is thrown) we will jump from the hole i to hole next[i] and so on, until we reach the fictious hole. Each time we will add count[i] to the answer. We will jump not more than N/K times.
+
+To maintain the query of the seqond type (when the power of hole i is changed) we will change power[i], next[i] and count[i]. Then for each hole which belongs to the same block as i and has smaller number than i we will update next[i] and power[i] in decreasing order of number of the hole. We will perform not more than K updates.
+
+The complexity is O(Nsqrt(N)).
diff --git a/editorials/14.md b/editorials/14.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/389
+
+### [A. Letter](../../../contest/14/problem/A)
+
+To find the smallest rectangle containing the picture, iterate through the pairs (i,j) such that the j-th symbol in i-th line is '*'; find the minimum and maximum values of i and j from these pairs. The rectangle to output is [*i**min*, *i**max*] × [*j**min*, *j**max*].
+
+
+### [B. Young Photographer](../../../contest/14/problem/B)
+
+First we find the intersection of all segments. To do this, denote by m the rightmost of left ends of the segments and denote by M the leftmost of right ends of the segments. The intersection of the segments is [m,M] (or empty set if m>M). Now determine the nearest point from this segment. If *x*0 < *m*, it's *m*, and the answer is *m* - *x*0. If *x*0 > *M*, it's *M*, and the answer is *x*0 - *M*. If , it's *x*0, and the answer is 0. If m>M, then the answer is -1.
+
+
+### [C. Four Segments](../../../contest/14/problem/C)
+
+There must be many ways to solve this problem. The following one seems quite easy to code.
+First count the number of distinct points among segments' ends. If it's not equal to 4, the segments can't form a rectangle and we output "NO". Then calculate the minimum and maximum coordinates of the 4 points: *x**min*, *x**max*, *y**min*, *y**max*. If *x**min* = *x**max* or *y**min* = *y**max*, then even if the segments form a rectangle, it has zero area, so we also output "NO" in this case.
+Now if the segments indeed form a rectangle, we know the coordinates of its vertices — (*x**min*, *y**min*), (*x**min*, *y**max*), (*x**max*, *y**min*) and (*x**max*, *y**max*). We just check that every side of this rectangle appears in the input. If it is the case, we output "YES", otherwise we output "NO".
+
+
+### [D. Two Paths](../../../contest/14/problem/D)
+
+Take any pair of non-intersecting paths. Since Flatland is connected, there must be a third path, connecting these two. Remove a road from the third path. Then Flatland is divided into two components — one containing the first path, and the other containing the second path. This observation suggests us the algorithm: iterate over the roads; for each road remove it, find the longest path in both connected components and multiply the lengths of these paths. The longest path in a tree can be found by depth first search from each leaf.
+
+
+### [E. Camels](../../../contest/14/problem/E)
+
+Let us call an index j such that *y**j* - 1 > *y**j* < *y**j* + 1 a *cavity*. Also, we'll call humps and cavities by the common word *break*. Then there must be exactly *T* = 2*t* - 1 breaks, and the first one must be a hump.
+Denote by *f**nth* the number of ways in which a camel with *t* breaks, ending at the point (n,h), can be extended to the end (the vertical *x**N* = *N*) so that the total number of breaks was equal to T. Note that:
+1. *f**NTh* = 1, if h=1,2,3,4. (We have already finished the camel and it has T breaks)
+2. *f**Nth* = 0, if 0 ≤ *t* < *T*, *h* = 1, 2, 3, 4. (We have already finished the camel, but it has less than T breaks)
+3. *f**n*, *T* + 1, *h* = 0, if 1 ≤ *n* ≤ *N*, *h* = 1, 2, 3, 4. (The camel has already more than T breaks).
+
+Now we find the recurrent formula for *f**nth*. Suppose that *t* is even. Then the last break was a cavity, and we are moving up currently. We can continue moving up, then the number of breaks stays the same, and we move to one of the points (*n* + 1, *h* + 1), (*n* + 1, *h* + 2), ..., (*n* + 1, 4). Or we can move down, then the number of breaks increases by 1, and we move to one of the points (*n* + 1, *h* - 1), (*n* + 1, *h* - 2), ..., (*n* + 1, 1). This gives us the formula
+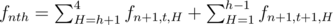.
+
+If *t* is odd, then the last break was a hump, and similar reasoning leads to the formula
+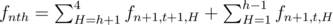.
+
+We can calculate *f**nth* by dynamic programming. Consider now the point (2, *h*) on a camel. There are h-1 ways to get to this point (starting from points (1, 1), ..., (1, *h* - 1)), and *f*2, 0, *h* ways to extend the camel to the end. So the answer to the problem is 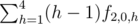.
diff --git a/editorials/15.md b/editorials/15.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/411
+
+А) Необходимо было отсортировать все дома по возрастанию координаты центра х. Для каждой пары последовательных домов (x_i, a_i) и (x_(i+1), a_(i+1)) определить расстояние между домами:
+
+d = x_(i + 1) - x_i + a_(i+1) / 2 + a_i / 2;
+
+если d > T то ans = ans + 2
+
+если d == T то ans = ans + 1
+
+иначе ничего не делаем
+
+в конце к ответу нужно было добавить два, чтобы еще закрыть крайние позиции.
+
+B) Для простоты написания, нужно было заметить, что геометрическое место точек которые можно выжечь лазером это два прямоугольника. Оставалось только посчитать их суммарную площадь, что делается очень просто по формуле включения-исключения. И не забудьте про 64 битное целое!
+
+С) Еще раз извиняюсь за ошибку в описании входа. Прочитав немного материала по теории игр и числам [Шпрага Гранди](https://ru.wikipedia.org/wiki/%D0%A4%D1%83%D0%BD%D0%BA%D1%86%D0%B8%D1%8F_%D0%A8%D0%BF%D1%80%D0%B0%D0%B3%D0%B0-%D0%93%D1%80%D0%B0%D0%BD%D0%B4%D0%B8) вам станет очевидно, что для решения этой задачи достаточно проксорить все числа: x_1, x_1 + 1, ... x_1+m_1-1, x_2, x_2 + 1, .. x_2+m_2 ... x_n, x_n + 1, ... x_n + m_n - 1 и определить является ли результат нулем или нет. Что правда учитывая их количество вам не удастся вложится в ТЛ. По-этому заметим что Вам требуется проксорить не просто какие-то числа, а несколько отрезков вида [x_i, x_i + m_i - 1]. Пускай f([a,b]) = a^(a+1)^(a+2)..^(b - 1) ^ b.
+
+Так как f([x_i, x_i + m_i - 1]) = f([1, x_i + m_i - 1]) ^ f([1, x_i - 1]); можно ксорить отрезок за О(1), учитывая то что f([1,x]) можно считать так:
+
+if (x mod 4 == 0) f(x) = x;
+
+if (x mod 4 == 1) f(x) = 1;
+
+if (x mod 4 == 2) f(x) = x + 1;
+
+if (x mod 4 == 3) f(x) = 0;
+
+тогда имеем сложность решения О(N)
+
+D) Решать ее стоило так:
+
+1. Перебрать все левые верхние углы прямоугольников годных для размещения города и для каждого из них посчитать количество земли которую бы было необходимо вывезти для того, чтобы построить город. Для этого нам необходимо считать сумму на прямоугольнике и минимум. Первое делается частичными суммами, а второе на выбор либо [двумерным деревом отрезков](http://e-maxx.ru/algo/segment_tree), либо для этого можно приспособить [очередь с минимумом за О(1)](http://e-maxx.ru/algo/stacks_for_minima) (вместо нее также подойдет эмуляция ее с помощью STL-евских [multiset](http://www.cplusplus.com/reference/stl/multiset/) и [priority_queue](http://www.cplusplus.com/reference/stl/priority_queue/)).
+
+2. После первого этапа необходимо собрать все данные в массив в форме (<количество вывезенной земли, координата верхнего угла>) и отсортировать его в лексикографическом порядке (по увеличению количества земли).
+
+3. Пройтись по уже отсортированному массиву проверяя можно ли поставить в данной клетке левый верхний угол города. Для этого нужно оценить не накладывается ли он на уже поставленный. Это можно делать заведя массив булеанов used[][] в котором будут отмечаться уже покрытые клетки. При добавлении города нужно будет просто оббегать весь прямоугольник и проставлять в его клетках true, а при запросе на возможность покрытия будем смотреть только на угловые клетки. (Так "халтурить" можно потому что у нас все прямоугольники одинакового размера и статической ориентации). Не сложно посчитать, что таким образом будет выполнено в сумме не более N*M операций.
+
+E) Можно было перейти к графу [двойственному](https://ru.wikipedia.org/wiki/%D0%A1%D0%BB%D0%BE%D0%B2%D0%B0%D1%80%D1%8C_%D1%82%D0%B5%D1%80%D0%BC%D0%B8%D0%BD%D0%BE%D0%B2_%D1%82%D0%B5%D0%BE%D1%80%D0%B8%D0%B8_%D0%B3%D1%80%D0%B0%D1%84%D0%BE%D0%B2) данному и обнаружить, что он дерево, а также установить взаимно однозначное соответствие между путями о которых шла речь в условии и не пустыми компонентами связности включающих корень данного дерева. Такие компоненты легко считать используя ДП по дереву: DP[u] = (DP[child1] + 1) * (DP[child2] + 1), DP[leaf] = 1. Но конечно такое решение не укладывалось в ТЛ и потому нужно было используя уравнение ДП свести к комбинаторной формуле благодаря рекуррентному соотношению между "нишами"(поддеревья которые идут от края карты вглубь).
diff --git a/editorials/17.md b/editorials/17.md
@@ -0,0 +1,50 @@
+Source: https://codeforces.com/blog/entry/451
+
+[Contest discussion](https://codeforces.com/blog/entry/447)
+ **Problem A. Noldbach problem**To solve this problem you were to find prime numbers in range [2..*N*]. The constraints were pretty small, so you could do that in any way - using the Sieve of Eratosthenes or simply looping over all possible divisors of a number.
+Take every pair of neighboring prime numbers and check if their sum increased by 1 is a prime number too. Count the number of these pairs, compare it to *K* and output the result.
+
+**Problem B. Hierarchy**
+
+Note that if employee, except one, has exactly one supervisor, then our hierarchy will be tree-like for sure.
+For each employee consider all applications in which he appears as a subordinate. If for more than one employee there are no such applications at all, it's obvious that - 1 is the answer. In other case, for each employee find such an application with minimal cost and add these costs to get the answer.
+Alternatively, you could use Kruskal's algorithm finding a minimum spanning tree for a graph. But you should be careful so that you don't assign the second supervisor to some employee.
+And yes, the employees' qualifications weren't actually needed to solve this problem :)
+
+**Problem C. Balance**
+Consider the input string *A* of length *n*. Let's perform some operations from the problem statement on this string; suppose we obtained some string *B*. Let *compression* of string *X* be a string *X*' obtained from *X* by replacing all consecutive equal letters with one such letter. For example, if *S* = "*aabcccbbaa*", then its compression *S*' = "*abcba*".
+Now, consider compressions of strings *A* and *B* - *A*' and *B*'. It can be proven that if *B* can be obtained from some string *A* using some number of operations from the problem statement, then *B*' is a subsequence of *A*', and vice versa - if for any strings *A* and *B* of equal length *B*' is a subsequence of *A*', then string *B* can be obtained from string *A* using some number of operations.
+Intuitively you can understand it in this manner: suppose we use some letter *a* from position *i* of *A* in order to put letter *a* at positions *j*..*k* of *B* (again, using problem statement operations). Then we can't use letters at positions 1..*i* - 1 of string *A* in order to influence positions *k* + 1..*n* of string *B* in any way; also, we can't use letters at positions *i* + 1..*n* of string *A* in order to influence positions 1..*j* - 1 of string *B*.
+
+Now we have some basis for our solution, which will use dynamic programming. We'll form string *B* letter by letter, considering the fact that *B*' should still be a subsequence of *A*' (that is, we'll search for *B*' in *A*' while forming *B*). For this matter we'll keep some position *i* in string *A*' denoting where we stopped searching *B*' in *A*' at the moment, and three variables *kA*, *kB*, *kC*, denoting the frequences of characters *a*, *b*, *c* respectively in string *B*. Here are the transitions of our DP:
+1) The next character of string *B* is *a*. Then we may go from the state (*i*, *kA*, *kB*, *kC*) to the state (*next**i*, '*a*', *kA* + 1, *kB*, *kC*).
+2) The next character of string *B* is *b*. Then we may go from the state (*i*, *kA*, *kB*, *kC*) to the state (*next**i*, '*b*', *kA*, *kB* + 1, *kC*).
+3) The next character of string *B* is *c*. Then we may go from the state (*i*, *kA*, *kB*, *kC*) to the state (*next**i*, '*c*', *kA*, *kB*, *kC* + 1).
+Where *next**i*, *x* is equal to minimal *j* such that *j* ≥ *i* and *A*'*j* = *x* (that is, the nearest occurrence of character *x* in *A*', starting from position *i*). Clearly, if in some case *next**i*, *x* is undefined, then the corresponding transition is impossible.
+Having calculated *f*(*i*, *kA*, *kB*, *kC*), it's easy to find the answer: 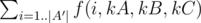 for all triples *kA*, *kB*, *kC* for which the balance condition is fulfilled.
+
+Such a solution exceeds time and memory limits. Note that if string *B* is going to be balanced, then *kA*, *kB*, *kC* ≤ (*n* + 2) / 3, so the number of states can be reduced up to 27 times. But it's also possible to decrease memory usage much storing matrix *f* by layers, where each layer is given by some value of *kA* (or *kB* or *kC*). It's possible since the value of *kA* is increased either by 0 or by 1 in each transition.
+
+The overall complexity is *O*(*N*4) with a quite small constant.
+ **Problem D. Notepad**
+
+The answer to the problem is *b**n* - 1 * (*b* - 1) mod *c*. The main thing you should be able to do in this problem - count the value of *A**B* mod *C* for some long numbers *A* and *B* and a short number *C*. Simple exponentiation by squaring exceeds time limit since to converse of *B* to binary you need about *O*(|*B*|2) operations, where |*B*| is the number of digits in decimal representation of number *B*.
+The first thing to do is to transform *A* to *A* mod *C*. It isn't difficult to understand that this transformation doesn't change the answer.
+Let's represent *C* as *C* = *p*1*k*1*p*2*k*2...*p**m**k**m*, where *p**i* are different prime numbers.
+Calculate *t**i* = *A**B* mod *p**i**k**i* for all *i* in the following way. There are two possible cases:
+1) *A* is not divisible by *p**i*: then *A* and *p**i* are coprime, and you can use [Euler's theorem](https://en.wikipedia.org/wiki/Euler%27s_theorem): *A**B*' = *A**B* (mod *C*), where *B*' = *B* mod φ(*C*) and φ(*C*) is Euler's totient function;
+2) *A* is divisible by *p**i*: then if *B* ≥ *k**i* then *t**i* = *A**B* mod *p**i**k**i* = 0, and if *B* < *k**i* then you can calculate *t**i* in any way since B is very small.
+Since all *p**i**k**i* are pairwise coprime you may use [chinese remainder theorem](https://en.wikipedia.org/wiki/Chinese_remainder_theorem) to obtain the answer.
+
+You can also use Euler's theorem directly. Note that if for some *B*1, *B*2 ≥ 29 you know that |*B*1 - *B*2| mod φ(*C*) = 0, then all *t**i* for them will be the same (29 is the maximal possible value of *k**i*). Using that you may reduce *B* so that it becomes relatively small and obtain the answer using exponentiation by squaring.
+
+There is another solution used by many contestants. Represent *B* as *B* = *d*0 + 10*d*1 + 102*d*2 + ... + 10*m**d**m*, where 0 ≤ *d**i* ≤ 9 (in fact *d**i* is the *i*-th digit of *B* counting from the last). Since *a**x* + *y* = *a**x*· *a**y*, you know that *A**B* = *A**d*0· *A*10*d*1· ...· *A*10*m**d**m*. The values of *u**i* = *A*10*i* can be obtained by successive exponentiation (that is, *u**i* = *u**i* - 110); if you have *A*10*i*, it's easy to get *A*10*i**d**i* = *u**i**d**i*. The answer is the product above (modulo *C*, of course).
+
+**Problem E. Palisection**
+The first thing to do is to find all subpalindromes in the given string. For this you may use a beautiful algorithm described for example [here](http://www.akalin.cx/2007/11/28/finding-the-longest-palindromic-substring-in-linear-time/). In short, this algorithm find the maximal length of a subpalindrome with its center either at position *i* of the string or between positions *i* and *i* + 1 for each possible placement of the center.
+For example, suppose that the maximal subpalindrome length with center at position *i* is 5; it means that there are three subpalindromes with center at *i*, with lengths 1 (*i*..*i*), 3 (*i* - 1..*i* + 1) and 5 (*i* - 2..*i* + 2). In general, all starting and finishing positions of subpalindromes with a fixed center lie on some interval of positions, which is pretty easy to find.
+Let's find for each position *i* the value of *start**i*, which is equal to the number of subpalindromes starting at position *i*. All these values can be found in linear time. Let's create an auxiliary array *a**i*. If after processing a position in the string some new pack of subpalindromes was found and they start at positions *i*..*j*, then increase the value of *a**i* by 1, and decrease the value of *a**j* + 1 by 1. Now 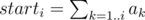. Proving this fact is left as an exercise to the reader :)
+In a similar way it's possible to calculate *finish**i*, which is equal to the number of subpalindromes finishing at position *i*.
+Since it's easy to count the total number of subpalindromes, let's find the number of **non**-intersecting pairs of subpalindromes and subtract this number from the total number of pairs to obtain the answer. Note that if two subpalindromes don't intersect then one of them lies strictly to the left of the other one in the string. Then, the number of non-intersecting pairs of subpalindromes is equal to: 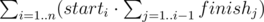
+This can be calculated in linear time if the value of 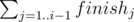 is recalculated by addition of *finish**i* before moving from position *i* to position *i* + 1.
+The overall complexity of the algorithm is *O*(*N*).
diff --git a/editorials/171.md b/editorials/171.md
@@ -0,0 +1,53 @@
+Source: https://codeforces.com/blog/entry/4255
+
+Congratulations to [KADR](/profile/KADR "Master KADR") who was the first of two people to solve all 8 problems!
+
+#### [171A - Mysterious numbers - 1](/contest/171/problem/A "April Fools Day Contest")
+
+The easiest way to make the problem statement unusual is to omit it. This is an extremely convenient approach — you don't have to maintain the statement in two languages or to worry that it might turn out to be ambiguous or too long or too scary. 690 people solved this problem, so evidently we can omit statements even in regular rounds :-)
+
+As for the problem itself, it required to sum the first number and the reverse of the second number.
+
+#### [171B - Star](/contest/171/problem/B "April Fools Day Contest")
+
+They say it's better to see once than to hear ten times or to read a hundred times. In this problem we decided to check this and to replace the traditional textual statement with a single image. Same as in the previous problem, it did well — at least 645 participants recognized star numbers (sequence <http://oeis.org/A003154> in OEIS), the numbers of balls needed to form a six-pointed start of certain size. After this one had only to code the formula — *S**n* = 6*n*(*n*−1) + 1.
+
+#### [171D - Broken checker](/contest/171/problem/D "April Fools Day Contest")
+
+What does one do if the statement is unknown and the only source of information about the problem is the checker? Right — you just try all possible functions which convert 5 input values into 3 output values and see which of them fits :-)
+
+#### [171F - ucyhf](/contest/171/problem/F "April Fools Day Contest")
+
+This problem finally has a statement! The trick is, it's encoded. We decided to be kind to you and to use the simplest cipher possible — Caesar cipher (each letter is shifted the same number of positions in the alphabet). By a long stretch of imagination one could break the cipher by hand — observe frequent letters and short words, deduce possible values of shift and verify it against the rest of the message. A lazier one could Google for a tool like [this one](http://www.sccs.swarthmore.edu/users/03/julieg/hw14cipher.html) and get the decoded version semi-automatically.
+
+After cracking the statement the rest was almost easy — you had to find a prime whose reverse is a prime different from the original one (sequence <http://oeis.org/A006567)>. 11184-th such number equals 999983, so one could do a brute-force check of all numbers in row.
+
+#### [171E - MYSTERIOUS LANGUAGE](/contest/171/problem/E "April Fools Day Contest")
+
+A special contest written by me and no special programming language? Impossible! I pulled myself up and made only 25% of all problems esoteric — that's two. There really should be three but the third interpreter refused to cooperate. Maybe next time...
+
+What can one do if all he knows about the language is its compiler? Just run any code and see what the compiler says. In this case the compiler said "DO YOU EXPECT ME TO FIGURE THIS OUT?", and Google should tell you immediately that the language in question is [INTERCAL](http://progopedia.com/language/intercal/). The problem simplifies to figure out the dialect used and how to output "INTERCAL" in it.
+
+In Codeforces round #96 I gave a problem [133C - Turing Tape](/contest/133/problem/C "Codeforces Beta Round 96 (Div. 2)") which explained the mechanism of string output in INTERCAL and asked to write a program which converted a string into an array of numbers which would print this string. Combine this knowledge with [Hello, World! example](http://progopedia.com/example/hello-world/257/) and you get the program you need. Actually, that's what I did to write the reference solution.
+
+```
+PLEASE DO ,1 <- #8
+DO ,1 SUB #1 <- #110
+PLEASE DO ,1 SUB #2 <- #32
+DO ,1 SUB #3 <- #72
+DO ,1 SUB #4 <- #136
+DO ,1 SUB #5 <- #88
+DO ,1 SUB #6 <- #136
+DO ,1 SUB #7 <- #64
+DO ,1 SUB #8 <- #80
+PLEASE READ OUT ,1
+PLEASE GIVE UP
+```
+
+#### [171C - A Piece of Cake](/contest/171/problem/C "April Fools Day Contest")
+
+The second esoteric problem had a [Chef](http://progopedia.com/language/chef/) program as the statement. You had only to figure out what it does and do it in any regular language. It turns out that this program reads N followed by N numbers *a*1, *a*2, ..., *a**N* and calculated the sum *i* * *a**i*.
+
+#### [171G - Mysterious numbers - 2](/contest/171/problem/G "April Fools Day Contest")
+
+This one was much harder to guess but much easier to code. First two numbers were the start of a Fibonacci-like sequence, and the third one was the index of the required number in this sequence.
diff --git a/editorials/173.md b/editorials/173.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/4289
+
+**A.** Naive solution in *O*(*n*) (some simulation all of n rounds) gets TL. Let's speed up this solution. Let's consider rounds on segments [1..mk], [mk+1..2mk], [2mk+1..3mk] and so on. You can see that results of games on these segments will repeat. So you can simulate over exactly one segment and then take into consideration them [n/(mk)] times ([x] is rounding down). Remainder of n%(mk) last rounds you can simulate separately. So you have *O*(*mk*) solution that easily fits into time limits.
+
+Authors are [Ripatti](/profile/Ripatti "Master Ripatti") and [Gerald](/profile/Gerald "Master Gerald") .
+
+**B.** In this problem you should build bipartite graph with n+m vertices. All vertices of the firts part correspond to the rows of the table, vertices of the second part correspond to the columns of the one. Edge connects vertices iff some regular column is placed in the cross of corresponding row and column.
+
+Firstly death ray covers only last row of the table that corresponds to one of vertices of our graph. When you are changing regular column into magic one, you are allowing death ray "go" by corresponding edge.
+
+Now you can reformulate the statement by this way: "activate" minimal number of edges in biratrite graph, so some path of minimal lenght connects vertex of the last row of the table and vertex of the first row of the table.
+
+You can see that required set of edges is just shortest path between these vertices. You can find this path using BFS. If BFS didn't find any path — answer is -1.
+
+This solution works in *O*((*n* + *m*)2).
+
+Author is [haas](/profile/haas "Candidate Master haas").
+
+**C.** Let's iterate over all spirals and chose one of them that has maximal sum of elements. Because you have *O*(*n*3) spirals, you should calculate sum of any of them in *O*(1). Only in this case your solution will fit into time limits.
+
+Let's define a way for iterate over all spirals. Let's fix one of cells and then iterate over all spirals that have own center in that cell in order of increasing side. So, you can recalculate sum for every spiral from previous one in *O*(1) using following picture:
+
+
+
+For finding the first "summand", you should in the beginning calculate rectangular partial sums.
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti").
+
+**D.** You have bipartite graph with 3*k* vertices and should to color its vertices by *k* colors. Every color should be used exactly 3 times and there should be no edges that connect vertices at same color.
+
+At the first, you should find both of parts of our birartite graph using, for example, DFS. Now let's consider sizes of parts.
+
+Case 0. If both of sizes divides by 3, you can just split every of parts into groups of 3 vertices and color them.
+
+Otherwise we can note then size of the first part is 1 modulo 3 and size of the second part is 2 modulo 3.
+
+There are yet another 2 cases:
+
+Case 1. You should try to find one vertex from the firts part that have 2 "antiedges" to 2 different vertices of the second part. If you found it, you should color them and reduce the problem to case 0.
+
+Case 2. There you should try to find 2 vertices on the second part. Every of them should have 2 "antiedges" that "connect" them with 4 different vertices trom the firts part. If you found such 6 vertices, you can color them by 2 different colors and reduce the problem to case 0.
+
+If you doesn't find coloring using this cases, answer is NO.
+
+About implementation: it is not clear how to analyse the case 2 in acceptable time. Actually, you can find any two vertices from the second part that have at least two "antiedges". These "antiedges" will conduct to 4 different vertices of the first part because otherwise case 1 would have worked.
+
+This solution works in *O*(*n* + *m*).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti").
+
+**E.** Let's transform all people into points on a plane with coordinates (*x* = *a**i*, *y* = *r**i*). What the maximal number in group of people that can be formed with some fixed leader? Answer is number of points inside rectangle (*x*, *y*): *x**i* - *k* ≤ *x* ≤ *x**i* + *k*, *y* ≤ *y**i*.
+
+Let's we allready found size of group for every person. How to find maximal group that contain points (*x**i*, *y**i*) and (*x**j*, *y**j*) both? The required group should have leader with age in range from *max*(*x**i* - *k*, *x**j* - *k*) то *min*(*x**i* + *k*, *x**j* + *k*) and responsibility at least *max*(*y**i*, *y**j*). From such leaders you should chose one that have maximal size of group. You can see that it is just query for maximum on some rectangle.
+
+Well, let's learn to quickly find answers for queries of sums in rectangle. You should compress coordinates *x* ans build segment tree for sum. Then you should answer all queries in increasing order of coordinate *y*. When you consider some group with same *y*, you should initially do queries of adding values in points, and after that do sum queries on the segments from *x**i* - *k* to *x**i* + *k*.
+
+Queries for maximum you can satisfy fully analogicaly using segment tree for maximum.
+
+So, you have  offline solution.
+
+Author is [havaliza](/profile/havaliza "Candidate Master havaliza").
diff --git a/editorials/175.md b/editorials/175.md
@@ -0,0 +1,52 @@
+Source: https://codeforces.com/blog/entry/4339
+
+#### Problem [175A - Robot Bicorn Attack](/contest/175/problem/A "Codeforces Round 115")
+
+Go over all possible partitions of the given string into 3 substrings (for example, go over a pair of indexes — the ends of the first and the second substrings). If all three substrings of the partition satisfy constraints (there are no leading zeroes and the corresponding number does not exceed 1000000), then update the current answer with the sum of obtained numbers (if it is necessary). The total amount of partitions is *O(N^2)*, where *N* is the length of the string. The check of one partition takes *O(N)*.
+
+#### Problem [175B - Plane of Tanks: Pro](/contest/175/problem/B "Codeforces Round 115")
+
+The solution is to simulate actions described in the statement. Find the best result for each player and count total amount of players *N*. Then find a number of players *C* for each player , those results are not better than best result of the considering player (this can be done by going over all players). Then it is necessary to determine players category using numbers *C* and *N*. In order to avoid rounding error use the following approach:
+
+* if *C* * 100 >= *N* * 99, then the player belongs to category "pro"
+* if *C* * 100 >= *N* * 90, then the player is "hardcore"
+* if *C* * 100 >= *N* * 80, then the player is "average"
+* if *C* * 100 >= *N* * 50, then the player is "random"
+
+In other case the player is "noob".
+
+#### Problem [175C - Geometry Horse](/contest/175/problem/C "Codeforces Round 115")
+
+Obvious, that figures should be destroyed in the cost increasing order. Sort figures type in ascending order of their costs. Consider two pointers – position *i* in the array *P* (current factor) and position *j* in the array of figures type. Consider the current answer and the number of figures *G*, those need to be destroyed to move to the next value of factor. If the number of figures *F* of the current type does not exceed *G*, then add *F * (i + 1) * Сj* to the answer and reduce *G* by *F* and increase pointer *j* by 1. In other case add *G * (i + 1) * Cj* to the answer, reduce *F* by *G*, increase *i* by 1 and set *G = Pi – P(i-1)*. Continue iteration until all figure types are considered.
+
+#### Problem [175D - Plane of Tanks: Duel](/contest/175/problem/D "Codeforces Round 115")
+
+First consider case when at least one probability of not-piercing is equal to 100%. If Vasya does not pierce the enemy tank with probability 100%, then the answer is 0. If the enemy tank cannot pierce Vasya's tank with probability 100% then the answer is 1. Then consider that the probability of shot does not pierce tank does not exceed 99%. It can be checked that the probability that tank will stay alive after *D* = 5000 shots is less than 10^-6 (for any damage value, probability of not-piercing and amount of hit points). For each tank calculate the following table *dp*[*i*][*j*] — probability that tank will have *j* hit points after i shots to him. *dp*[0][*hp*] = 1, where *hp* – is the initial amount of hit points. In order to calculate the line *dp*[*i+1*] it is necessary to go over all possible damages for each value of *j* in the line *dp*[*i*], which shot *(i+1)*-th damages (considering cases when the shot does not pierce the tank armour) and update appropriate values of the line *(i+1)*:
+
+```
+dp[i + 1][max(0, j – x)] += dp[i][j] * (1 – p) / (r – l + 1)
+```
+
+where *p* – is the probability of not-piercing, *x* – possible shot damage. Let's *dpv* – calculcated table for Vasya's tank and *dpe* is the table for enemy's tank. Now it is necessary to find probability that enemy's tank will be destroyed after *i* shots of Vasya's tank: *pk*[*i*] = *dpe*[*i*][0] – *dpe*[*i-1*][0]. Vasya wins the following way: Vasya fired *(K — 1)* shots and do not destroy enemy tank and is still alive also. After that Vasya fires *K*-th shot and destroy the enemy. Go over *K* and calculate the probability of Vasya's victory with the *K*-th shot. In order to do this find how many shots *T* can fire the enemy before Vasya makes *K*-th shot (here is the only place in the solution where we must use the gun recharge speed):
+
+```
+T = ((K – 1) * dtv + dte - 1) / dte
+```
+
+where *dtv* is the time required to recharge the gun, *dte* is the time of enemy gun recharge. Then the probability of victory is (1 – *dpv*[*T*][0]) * *pk*[*K*]. The answer for the problem is the sum all these probabilities for each *K* from 1 to *D*. The algorithmic complexity of the algorithm is *O(D * hp * (r – l))*.
+
+#### Задача [175E - Power Defence](/contest/175/problem/E "Codeforces Round 115")
+
+If we reflect the position of towers alogn the line OX then the interval where towers will affect the Villain will not change. So, we can consider that towers can be built in the points (_x_, 1), not more than two towers in the same point. If there exists point *X* that there are towers to the left and to the right from *X* but in the point *X* there is no tower, then abscissas of all towers "to the right" can be reduced by 1 and the answer will not become worse. The same way, we can prove that there are no adjacent points with exactly one tower in each one. Now it is easy to check that in order to construct the optimal solution it is enough to check 13 successive points.
+
+Go over positions of freezing towers. In the worst case there are approximately 200000 cases to put freezing towers into 13 points. Consider the case when we fixed positions of several freezing towers. Let's calculate how much damage can hit fire-tower or electric-tower in the point for each empty points (points where we can put two towers are splitted into two) and save numbers into the array *d* (_d_[*k*].f and *d*[*k*].e – damage by fire and electricity in the point *k* correspondingly). Sort the array *d* in the order of decreasing of the value *d*[*k*].f. Then optimal position of the rest towers can be found using dynamic programming. Designate *dp*[*i*][*j*] – the maximum possible damage, which can be hitted if we have *i* fire-towers and *j* electric-towers. Designate *p* — the amount of towers have been set already: *p = cf – i + ce – j*. If *i* = 0 then we used first *p* values of array *d* and the answer is the sum of *j* maximum elemets of *d*[*k*].e, starting from index *p*. Otherwise we put one fire-tower or one electric tower in the position *p*. It is necessary to put the tower into position *p* because in the opposite case the *d*[*p*].f will decrease. Then:
+
+```
+dp[i][j] += max(dp[i - 1][j] + d[p].f, d[i][j – 1] + d[p].e)
+```
+
+The answer is the value *dp*[*cf*][*ce*], which is calculated in *O(cf * ce * log(ce))*
+
+**Comment1**: exhaustive search can be reduced in 2 times because any two symmetric towers arrangements are equivalent and have the same answer. However, this optimization is not required with a given constraints.
+
+**Comment2**: the formula of Villain speed decrease *1 / (K + 1)* allows to calculate the tower damage for a case when all freezing towers are fixed easily. Freezing towers can be taken into account separately.
diff --git a/editorials/176.md b/editorials/176.md
@@ -0,0 +1,77 @@
+Source: https://codeforces.com/blog/entry/4372
+
+**A div2.** Required row is row that have only one star inside. Requred column is comumn that also have only one star inside. So, you can iterate over all rows/columns, calculate number of stars inside them and find the answer.
+
+Authors are [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov"), [Gerald](/profile/Gerald "Master Gerald") .
+
+**B div2.** Naive solution *O*(*n*3) (where you check all triplets) doesn't fin into time limits.
+
+You can see that for every two points from triplet (for example, for A and C) you can find place of the third point. So you can find number of requred triplets just inerate over all pairs of points and check middle point between points in every pair.
+
+How to fast check position? You can add 1000 for all coordinates (you can see that this operation doesn't change the answer) and mark them in the 2-dimensional boolean array 2001х2001. So you can check every position for point in *O*(1) time.
+
+Obtained solution works in *O*(*n*2).
+
+Authors are [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov"), [Gerald](/profile/Gerald "Master Gerald")
+
+**A div1. C div2.** In this problem some greedy solution expected.
+
+Let fix 2 planets: in planet i we will buy items, in planet j we will sell the ones. *Profit of item* of type k will be b_jk-a_ik. Every item has size 1, so you should greedy take items in order of decreasing of profits of items while you have place in the hold.
+
+Scheme of full solution: you should iterate over all pairs of planet, for every pair greedy take items and find total profit. At the end you should find maximal total profit over all pairs and output it.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**B div1. D div2.** You can see that split oparetion is just cyclically shift of string. You can go from any cyclically shift to any other one except the current one.
+
+Let's call some cyclically shift *good* iff it equal to the final string. All others cyclically shifts we will call *bad*. You can check all shifts in *O*(|*w*|2) time. Let's you have A good shifts and B bad ones.
+
+Let's define dpA[n] as number of ways to get some good shift using n splits and за dpB[n] as number of ways to get some bad shift using n splits.
+
+dpA[0]=1, dpB[0]=0 or dpA[0]=0, dpB[0]=1 according to the first shift is good or not. All other values of dp you can get using following reccurences:
+
+dpA[n] = dpA[n-1] * (A-1) + dpB[n-1] * A
+
+dpB[n] = dpA[n-1] * B + dpB[n-1] * (B-1)
+
+Answer will be dpA[k]. So you have *O*(|*w*|2 + *k*) solution.
+
+Also this problem can be solved in 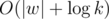 time.
+
+Author is [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+**C div1. E div2.** The second player have easy strategy to hold some chip in position (*X*, *Y*) in one of four half-planes — *x* ≤ *X* + 2, *x* ≥ *X* - 2, *y* ≤ *Y* + 2 и *y* ≥ *Y* - 2. He can chose one of these half-planes by himself.
+
+So, in case *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) > 4 the second player wins — he just holds chips in half-planes that have no common cells.
+
+Cases for *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) ≤ 4 expected to solve using some bruteforce. You can see that moving chips in way of distancing from each other is not profitable for the first player. Therefore you can bruteforce the game in square no more than 5 × 5. If your bruteforce so slow and doesn't fit into 2 sec, you can use precalculation. Also you can write some dp using masks.
+
+Also you can check cases *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) ≤ 4 by hand. But there you can easy make some mistakes.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**D div1.** Let's define *dp*[*pre*][*len*] as the minimal prefix of hyperstring that have with prefix of *t* of length *len* largest common sequence of length *len*.
+
+Then you have see reccurences:
+
+*dp*[*pre*][*len*] = *min*(*dp*[*pre* - 1][*len*], leftmost position of letter *s*[*pre*] in *t* that right than *dp*[*pre* - 1][*len* - 1]).
+
+For finding value of the second part inside min-function of formula above in *O*(1), you should calculate some additional dp's:
+
+dp1 — for every basic string, positions inside of them and letter you should calculate leftmost position of current letter that right than current position;
+
+dp2 — for every element of array of basic strings (it is hyperstring) and letter you should calculate leftmost basic string that have current letter and this string is rinht than current basic string.
+
+So you have 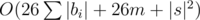 solution.
+
+Author is [havaliza](/profile/havaliza "Candidate Master havaliza").
+
+**E div1.** At the first let's try to solve another problem: we have *k* chosed vertices in the tree and we want to find sum of subtree that "spanned" dy them in time  (with any preprocessing time).
+
+Let's sort all *k* vertices in order of dfs traversal — *v*1, *v*2, ... , *v**k*. Consider pathes v1-v2, v2-v3, ... , v(k-1)-vk and vk-v1. You can see that they cover only our requred subtree and every edge is covered exactly two times. So you can just find sum of lengths of these pathes (you can do it in required  time using LCA algo) and divide obtained value by 2.
+
+For solving initial problem you should support set of active vertices in ordered state (for example, you can use std::set) and sum of all pathes between all neighbour vertices. Now you can process insert/remove queries in , and recalculate sum of pathes by finding no more than 3 new pathes also in .
+
+So you have 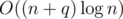 solution.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
diff --git a/editorials/178.md b/editorials/178.md
@@ -0,0 +1,76 @@
+Source: https://codeforces.com/blog/entry/4435
+
+**UPD1:**
+
+### Editorial to Problem <>
+
+First of all note that merchants will pay only for those edge which are bridges. All other edges don’t match as after their deletion graph stay connected and between any nodes of graph the way stay. So first step to solve problem is to search bridges. Use this algorithm which works at *O*(*n* + *m*)
+
+After deletion all the graph bridges graph is divided for some components of connectivity (maybe one component). Let’s build new graph in which recieved components will be nodes and bridges — edges. This graph will be a tree. The graph is connected therefore the tree is connected. The edges correspond to bridges therefore there is no cycles in the tree.
+
+Note that the number of denarii means the pay of every merchant — is a distance between some the nodes in a new graph. But as this graph is a tree this distances can be easily find out using LCA search algorithms for two nodes. In this problem one should use the simplest LCA search algorithm which accomplish the preprocess for  and handle one request for . The complexity of computations id 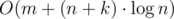.
+
+One can solve this problem easier. Let’s build a graph recursive pass-by initial graph and weight its edges. The edges with weight equals 1 will have bridges and others will have weight equals 0. So after all these reductions for solving problem it will be enough to compute the distance between two nodes in the graph recursive pass-by initial graph.
+
+**UPD:**
+
+### Editorial to Problem <<Beaver's Problem — 2>>
+
+Solving this problem can be divided into two parts:
+
+* Noise deletion on the picture;
+* Fugures' classification.
+
+For noise deletion one can use the following methods:
+
+a. Do following steps: scan picture and build new on using it. If sone black pixel have white neighbours, we make it white. During thise steps we get rid of almost all noise on the picture. Then we make inverse opreation replacing all white pixels with black. So we get rid of almost all noise inside the picture.
+
+Note, that after all these opreations noise can stay as little black components. And some figures can lose their connectivity. These problems can be solved by deletion little black components and then unite near black components.
+
+b. But one can use easier way. Highlight black components and then cast away little ones. If to look closely to the texts in real under even distribution of the noise there is no little black components and it is not losing connectivity. However previous way is more reliable.
+
+The simplest way to classificate figures is to compare distributions of the distances from all the figure pixels to centre of the every figure. The centre can be calculated as average of the all points coordinates of the figure. Ditributions can be compared by expectation values and variations.
+
+### An Editorial to Problem <>
+
+Let’s iterate through the cells of the hash table with step m (modulo h). So, all cells are separated into some cycles modulo h (all cycles have the same number of elements). It can be proven that the number of cycles is *gcd*(*h*, *m*) and the number of elements in each cycle is *h* / *gcd*(*h*, *m*). How can we use this property? The element with fixed hash-value will be added into some (next) cell in the corresponding to element’s hash-value cycle.
+
+So, we can process each cycle separately. To do this effectively (we want to solve large test package) we have to use any tree-structure like segment tree or combination of Fenwick tree with binary search.
+
+An effectiveness of solution with segment tree is , of solution with Fenwick tree — .
+
+### An Editorial to Problem <>
+
+Let’s consider two different ways to solve this problem. Note that firstly (before finding correct magic square) we can easily determine the value of *s*. This value equal to the sum of all given numbers divided by *n*. So next, we will use this value.
+
+The first way to solve problem is brute force. This way based on two main ideas:
+
+* We can determine some square elements during the brute force using already fixed values. For example, if we have fixed three of values on the main diagonal, we can easily determine the fourth value. This trick decrease the number of brute force iterations.
+
+* We can rotate (or mirror) magic square without breaking his magic properties.
+
+The second way use discrete-optimization approach. Let’s consider the function *Q* = |*sum*1 - *s*| + ... + |*sum**t* - *s*|, where |*x*| — the absolute value of *x*, *t* = 2 * *n* + 2, *sum*1, .., *sum**n* — the sum of elements in one row, *sum**n* + 1, *sum*2*n* — the sum of element in one column, *sum**t* - 1 — the sum of elements on the main diagonal, *sum**t* --- the sum of elements on the secondary diagonal.
+
+So, we want to find such permutation of the given elements that make our function as small as possible (We want to obtain zero). One way to do this: pick the random permutation. Try to make swaps in this permutation using greedy strategy (try to make swaps that make our function better). Let’s do 1000 swaps. If we obtain *Q* = 0 — we have found answer, else *Q* > 0 -- pick another random permutation and repeat this process again.
+
+### An Editorial to Problem <>
+
+It is the simplest task of the set. The solution is based on greedy algorithmm.
+
+First of all, we need to zero out *a*1. One needs to make *a*1 steps with *i* = 1 and some *t* on each step. Which *t* is the most efficient? The maximum *t*, where 1 + 2*t* ≤ *n*. In that case later zeroing out longer prefixes of the sequence will take less steps. Having zeroed *a*1, we will write a current answer and notice that we reduce the task to the smaller one — sequence becomes one element shorter.
+
+The complexity of a solution  or *O*(*n*) — depends on implementation.
+
+One can solve the task in a different way. To start from, the task can be solved for each element *a**i* separately. In other words, if we fix some *k*, contribution of each *a**i* to an answer can be counted separately.
+
+We fix some *a**i*. Then we find maximum *j* so that *i* + 2*j* ≤ *n*. Evidently, that for every *k* < *i* + 2*j*, contribution of *a**i* to the answer equals *a**i*. In other words, one needs to make *a**i* steps with transition to *a**i*. Further we need to find maximum *u*, so that 2*j* + 2*u* ≤ *n*. Notice that *u* < *j*. Contribution of *a**i* to the answer is equal 2 * *a**i*, for every *k* that *i* + 2*j* ≤ *k* < *i* + 2*j* + 2*u*. Then we find *q* that *i* + 2*j* + 2*u* + 2*q* ≤ *n*, and so on ...
+
+A corresponding sequence of powers of 2 should be found for each element *a**i*. Evidently, that overall complexity of this process is .
+
+Now we need to calculate an answer. It can be done, for example, like that: we will store the array *b**i* — the change of the answer at the transition from *i* to 4*i* + 1. This array is formed in a trivial way during construction of sequences of powers of twos. Then it is easy to get the answer.
+
+The overall complexity of the solution equals .
+
+### An Editorial to Problem <>
+
+[Here](http://pastebin.com/3KYnbr3X) one can see author's solution.
diff --git a/editorials/18.md b/editorials/18.md
@@ -0,0 +1,59 @@
+Source: https://codeforces.com/blog/entry/463
+
+[Contest discussion](https://codeforces.com/blog/entry/462)
+
+### Problem А. Triangle
+
+Pythagorean theorem, brute force
+
+In this problem you should implement a function, which takes three points and checks whether they form a right-angled triangle. There are a lot of ways to do so, but the simplest one is using a Pythagorean theorem.
+
+You should use squared distances instead of taking roots to overcome problems related to precision errors.
+
+To examine a triangle on almost-rightness, you can try to move each point in each of four possible directions and check the new triangle using our function. It's good and easy to use two arrays: dx={-1,0,1,0} and dy={0,1,0,-1} for moving. Then we can get the new coordinates of shifted point simply using the following code:
+
+> for (int i = 0; i < 4; i ++)
+
+> {
+
+> > int x = dx[i] + px;
+
+> > int y = dy[i] + py;
+
+> }
+
+### Problem B. Platforms
+
+Simulation
+
+Illustrative picture:
+
+
+
+In this problem you were to determine a coordinate where the grasshoper would fall down. To do so, let's keep the position of grasshoper at a certain moment of time.
+To avoid TLE one should "move" the grasshoper along a platform in *O(1)* time (not in the cycle). The grasshoper will do *j = (righti-x)/d* jumps along platform "*i*", where *x* is the grasshoper's coordinate (he's standing at the platform), and *righti* is a right coordinate of the platform. So we can move the grasshoper on *j*d* to the right at once.
+
+### Problem C. Stripe
+
+Brute force
+
+One should keep two sums S1 ans S2, where S1 is the sum of all numbers on the left part of the stripe, and S2 is the sum of the right one. At the beginning S1 = 0 and S2 equals to the sum of all numbers of the stripe. Then we move the border of the parts within a cycle from left to right recalculating the values of S1 and S2 each iteration and increasing the answer when it's necessary.
+
+### Problem D. Seller Bob
+
+Greedy, long arithmetics
+
+In this problem we need big integers because the number 22000 doesn't fit in int64.
+We are given an assertion that for every memory stick there will be at most one potential customer. Since 2x> 2x-1 + 2x-2 + ... 20, the earnings of selling the most expensive stick will be greater than the earnings of selling all other sticks. So we first try to sell the most expensive stick, then the second one and so on. So one should try to sell sticks in descending order of their costs.
+
+### Probelm E. Flag 2
+
+Dynamic programming
+
+In this problem one should use dynamic programming. Consider the function *DP(level, A, B)* (where *A* and *B* are the numbers of colors, from 0 to 25), which returns the minimal number of repaintings required to repaint the first level rows. The last row will be like *ABABAB...*
+
+Consider recalculating of this function. First, calculate the number of repaintings required for row *level* to be like *ABABAB...* (let *D* will be this number). Obviously, the row can be painted so if the color of the first element of the previous row is not "*A*" and the second one - not "*B*" (it's a condition of adjacent cells not to have the same color) or it should be the first row. So *DP(level, A, B) = min(DP(level-1, i, j)) + D , i = 0..25, j = 0..25, i != j, i != B, j != A.*
+
+Estimate the run time of our program: *O(N*26*26*(M+26*26))*, this value is smaller than *4*108*
+
+**Great t****hanks to [Ilya Akolzin](https://codeforces.com/profile/OBepkJIokEP) for his help in translation**
diff --git a/editorials/181.md b/editorials/181.md
@@ -0,0 +1,77 @@
+Source: https://codeforces.com/blog/entry/4372
+
+**A div2.** Required row is row that have only one star inside. Requred column is comumn that also have only one star inside. So, you can iterate over all rows/columns, calculate number of stars inside them and find the answer.
+
+Authors are [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov"), [Gerald](/profile/Gerald "Master Gerald") .
+
+**B div2.** Naive solution *O*(*n*3) (where you check all triplets) doesn't fin into time limits.
+
+You can see that for every two points from triplet (for example, for A and C) you can find place of the third point. So you can find number of requred triplets just inerate over all pairs of points and check middle point between points in every pair.
+
+How to fast check position? You can add 1000 for all coordinates (you can see that this operation doesn't change the answer) and mark them in the 2-dimensional boolean array 2001х2001. So you can check every position for point in *O*(1) time.
+
+Obtained solution works in *O*(*n*2).
+
+Authors are [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov"), [Gerald](/profile/Gerald "Master Gerald")
+
+**A div1. C div2.** In this problem some greedy solution expected.
+
+Let fix 2 planets: in planet i we will buy items, in planet j we will sell the ones. *Profit of item* of type k will be b_jk-a_ik. Every item has size 1, so you should greedy take items in order of decreasing of profits of items while you have place in the hold.
+
+Scheme of full solution: you should iterate over all pairs of planet, for every pair greedy take items and find total profit. At the end you should find maximal total profit over all pairs and output it.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**B div1. D div2.** You can see that split oparetion is just cyclically shift of string. You can go from any cyclically shift to any other one except the current one.
+
+Let's call some cyclically shift *good* iff it equal to the final string. All others cyclically shifts we will call *bad*. You can check all shifts in *O*(|*w*|2) time. Let's you have A good shifts and B bad ones.
+
+Let's define dpA[n] as number of ways to get some good shift using n splits and за dpB[n] as number of ways to get some bad shift using n splits.
+
+dpA[0]=1, dpB[0]=0 or dpA[0]=0, dpB[0]=1 according to the first shift is good or not. All other values of dp you can get using following reccurences:
+
+dpA[n] = dpA[n-1] * (A-1) + dpB[n-1] * A
+
+dpB[n] = dpA[n-1] * B + dpB[n-1] * (B-1)
+
+Answer will be dpA[k]. So you have *O*(|*w*|2 + *k*) solution.
+
+Also this problem can be solved in 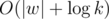 time.
+
+Author is [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+**C div1. E div2.** The second player have easy strategy to hold some chip in position (*X*, *Y*) in one of four half-planes — *x* ≤ *X* + 2, *x* ≥ *X* - 2, *y* ≤ *Y* + 2 и *y* ≥ *Y* - 2. He can chose one of these half-planes by himself.
+
+So, in case *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) > 4 the second player wins — he just holds chips in half-planes that have no common cells.
+
+Cases for *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) ≤ 4 expected to solve using some bruteforce. You can see that moving chips in way of distancing from each other is not profitable for the first player. Therefore you can bruteforce the game in square no more than 5 × 5. If your bruteforce so slow and doesn't fit into 2 sec, you can use precalculation. Also you can write some dp using masks.
+
+Also you can check cases *max*(|*x*1 - *x*2|, |*y*1 - *y*2|) ≤ 4 by hand. But there you can easy make some mistakes.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**D div1.** Let's define *dp*[*pre*][*len*] as the minimal prefix of hyperstring that have with prefix of *t* of length *len* largest common sequence of length *len*.
+
+Then you have see reccurences:
+
+*dp*[*pre*][*len*] = *min*(*dp*[*pre* - 1][*len*], leftmost position of letter *s*[*pre*] in *t* that right than *dp*[*pre* - 1][*len* - 1]).
+
+For finding value of the second part inside min-function of formula above in *O*(1), you should calculate some additional dp's:
+
+dp1 — for every basic string, positions inside of them and letter you should calculate leftmost position of current letter that right than current position;
+
+dp2 — for every element of array of basic strings (it is hyperstring) and letter you should calculate leftmost basic string that have current letter and this string is rinht than current basic string.
+
+So you have 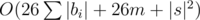 solution.
+
+Author is [havaliza](/profile/havaliza "Candidate Master havaliza").
+
+**E div1.** At the first let's try to solve another problem: we have *k* chosed vertices in the tree and we want to find sum of subtree that "spanned" dy them in time  (with any preprocessing time).
+
+Let's sort all *k* vertices in order of dfs traversal — *v*1, *v*2, ... , *v**k*. Consider pathes v1-v2, v2-v3, ... , v(k-1)-vk and vk-v1. You can see that they cover only our requred subtree and every edge is covered exactly two times. So you can just find sum of lengths of these pathes (you can do it in required  time using LCA algo) and divide obtained value by 2.
+
+For solving initial problem you should support set of active vertices in ordered state (for example, you can use std::set) and sum of all pathes between all neighbour vertices. Now you can process insert/remove queries in , and recalculate sum of pathes by finding no more than 3 new pathes also in .
+
+So you have 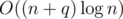 solution.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
diff --git a/editorials/182.md b/editorials/182.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/4408
+
+Приветствую всех участников раунда!
+
+Давайте проведем разбор задач в примерном порядке их сложности
+
+## [182B - Vasya's Calendar](/contest/182/problem/B "Codeforces Round 117 (Div. 2)")
+
+Обратим внимание, что Вася должен вручную прибавлять номер дня только тогда, когда заканчивается один месяц, и начинается следующий. Значит, пусть у нас в текущем месяце было *x* дней, а в следующем уже *y*. Тогда в первый день следующего месяца часы будут показывать день *x* + 1 (не забываем про модуль *d*), а должен показывать номер 1.
+
+Очевидно, что Вася должен вручную прибавить *d* - *x* дней, чтобы часы показывали то, что нужно.
+
+Значит, ответ — это сумма всех чисел *d* - *a**i*, где 1 ≤ *i* < *n*.
+
+## [182D - Common Divisors](/contest/182/problem/D "Codeforces Round 117 (Div. 2)")
+
+Эта задача решается многими способами, но самый простой подход следующий: найдем все делители строки *s*1, все делители *s*2 и найдем пересечение этих двух множеств.
+
+Как же найти все делители строки? Пусть *t* — это делитель строки *s*. Тогда очевидно, что |*s*| = 0(*mod*|*t*|), а также *t* является префиксом строки *s*. Эти соображения и позволяют найти все делители строки, а именно переберем длину префикса, проверим делимость, а потом проверим, что префикс записанный подряд нужное количество раз совпадает с *s*.
+
+Всего подходящих префиксов не более , проверка каждого работает за *O*(|*s*|), значит, итоговое решение за , где *n* = *max*(|*s*|, |*t*|).
+
+Найти пересечение двух множеств строк несложно, можно воспользоваться стандартными структурами данных
+
+## [182E - Wooden Fence](/contest/182/problem/E "Codeforces Round 117 (Div. 2)")
+
+Условие задачи было сформулировано неверно, что привело к несоответствию решений, правильный вариант условия появится совсем скоро, приносим участникам свои извинения.
+
+Основа решения этой задачи — это динамическое программирование.
+
+Состояние — (*last*, *type*, *l*), где *last* — номер последней доски, *type* характеризует поворот последней доски, а *l* — длина оставшейся части забора.
+
+Пересчитывать эту динамику тоже очень просто: переберем номер следующей доски, ее поворот, проверим подходит ли она в текущее состояние, и прибавим нужную величину.
+
+Асимпотика решения — *O*(*n*2·*len*).
+
+## [182C - Optimal Sum](/contest/182/problem/C "Codeforces Round 117 (Div. 2)")
+
+Представим мысленно задачу в виде движения слева направо некоторого окошка длины *len* по исходному массиву. То есть нам нужно найти способ достичь максимума в выбранном окошке, а потом сместить его на одну ячейку вправо.
+
+Пусть мы зафиксировали положения окошка, теперь посчитаем ответ. Для этого отдельно запишем все положительные и все отрицательные числа в окошке. Если положительных не больше, чем *k*, или отрицательных не больше *k*, то мы можем все числа сделать одинакового знака, и ответ — это сумма модулей чисел в подмассиве. Это простой случай.
+
+Несложно понять, что невыгодно некоторые отрицательные числа делать положительными и одновременно некоторые положительные — отрицательными. То есть мы обязательно выберем знак <<+>> или <<->> и *k* чисел этого знака сделаем противоположными. Также несложно понять, что всегда при смене знака у некоторых чисел выгодно брать ровно *k* максимальных по модулю чисел этого знака.
+
+Для того, чтобы поддерживать движение окошка будем использовать два отдельных дерева отрезков: одно для отрицательных, другое для положительных чисел.
+
+Если в вершине дерева хранить пару (количество чисел в поддереве, сумма этих чисел), то такая структура умеет возвращать сумму *k* максимальных чисел, что нам и требуется.
+
+Асимптотика решения — *O*(*n*·*log*(*n*)).
+
+## [182A - Battlefield](/contest/182/problem/A "Codeforces Round 117 (Div. 2)")
+
+В этой задаче есть два главных момента:
+
+1. длина любой траншеи в метрах численно не превосходит *b*
+2. траншеи не пересекаются
+
+Первый пункт означает, что если Вася забегает в траншею чтобы переждать, пока лазер работает, то за это время он может придти в любую его точку.
+
+Второй пункт означает, что пока лазер работает, Вася обязан находиться в той траншее, в которой он на данный момент сидит.
+
+Значит, путь Васи — это перебежки от одной траншеи к другой, где он пережидает лазерную атаку. Таким образом все решение задачи — это найти кратчайший по времени путь по траншеям от стартовой точки до конечной (их мы тоже будем считать траншеями, просто нулевой длины), для этого нужно всего лишь предподсчитать матрицу расстояний между отрезками траншей и запустить алгоритм, например, Дейкстры.
+
+Два тонких момента:
+
+1. мы не можем перебегать между траншеями, если между ними расстояние больше *a*
+2. пусть Вася прибежал в момент времени *t*, теперь нам нужно найти момент, когда он сможет убежать дальше. Для этого нужно найти следующий момент времени, когда лазер будет перезаряжаться. Эта величина *T* несложно ищется по формуле:
+
+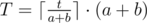
+
+Асимптотика решения — *O*(*n*2).
diff --git a/editorials/183.md b/editorials/183.md
@@ -0,0 +1,236 @@
+Source: https://codeforces.com/blog/entry/4419
+
+This is the editorial for [Croc Champ 2012 - Final](/contest/183 "Croc Champ 2012 - Final")
+
+### Remarks
+
+One day, I applied to write another round in Codeforces. To my surprise, I was offered to write CROC instead. I'm quite surprised they offer me (an unknown programmer from a notorious country) to write for such an important match! So I happily oblige — kudos for the open culture nurtured by Codeforces!
+
+I like most the problems of this final round. I think all of them are beautiful in some aspects :). Oh, and all of them emits such concise solutions ;).
+
+### [Problem A](//codeforces.com/contest/183/problem/A)
+
+Author: [dolphinigle](/profile/dolphinigle "Grandmaster dolphinigle")
+ Ad Hoc I supppose...
+
+This problem is equivalent to calculating the number of reachable locations from point (0, 0) by doing the allowed moves.
+
+The naive solution is to process the information one by one from first to last, and to keep track on all the reachable positions.
+
+Claim: At any moment in time, all reachable locations as described above forms a "diamond".
+
+An extremely informal proof is by induction:
+
+For instance, let's use the first example:
+
+```
+UR UL ULDR
+```
+
+Initially, there's only one possible location (namely, (0, 0)). It forms the basis of our induction: a diamond with width=1 and height=1.
+ 
+
+"UR" (and also "DL") extends the width of the diamond into a 2x1 diamond:
+ 
+
+Then, "UL" (and also "DR") extends the height of the diamond into a 2x2 diamond:
+ 
+
+Finally, "ULDR" extends both the height and the width of the diamond into a 3x3 diamond:
+ 
+
+And so there's 9 possible locations.
+
+To see that this claim is true, suppose by induction our locations so far forms a diamond. By symmetry we only need to see that in the "UR" case, its width is increased by one (I'll omit the similarly seen "ULDR" case). The idea is the new possible locations = the previous diamond shifted one step up UNION that diamond shifted one step right. Indeed, the union of these two diamonds accounts for both the "U" and the "R" moves.
+ 
+
+It's not hard to proof that the union of two diamonds with equal dimension that is displaced by vector (1, 1) forms the same diamond with its width increased by 1.
+
+So, the solution is to keep track the dimension of the diamond, starting from a 1x1 diamond. Then, simply return width * height.
+
+Reference: See [1631223](/contest/183/submission/1631223 "Submission 1631223 by Endagorion") by [Endagorion](/profile/Endagorion "Master Endagorion") (my favorite CF author! :) ).
+
+### [Problem B](//codeforces.com/contest/183/problem/B)
+
+Author: [dolphinigle](/profile/dolphinigle "Grandmaster dolphinigle")
+ Geometry
+
+Since there are at least one flamingo, all binoculars will be able to see at least one flamingo. When a binocular is able to see more than one flamingos, then those two flamingos and the binocular must form a line. How many such lines are there?
+
+Instead of iterating for each pair of binocular and flamingo, we iterate over each pair of flamingos. These two pair of flamingos completely determine the line as described above. If there does not exists a binocular in this line, we can ignore this pair and continue. Otherwise, calculate the number of flamingos in this line, and let it be one of the possible number of flamingos visible from that binocular.
+
+After this is done, simply sum the maximum number of flamingos of each binocular. This works in O(M^3). Note that this problem can be made to run in O(M^2 log M), but coding that solution is sort of... boring ;3.
+
+For instance, see [vepifanov](/profile/vepifanov "International Master vepifanov")'s [1631294](/contest/183/submission/1631294 "Submission 1631294 by vepifanov")
+
+**Remarks**
+
+Actually [havaliza](/profile/havaliza "Candidate Master havaliza") prepared a much nicer B problem. Unfortunately, we found out at the last moments that the problem may be too similar to a problem (that is used a looooooooong time ago), so we decided to switch that problem with something else. And that's why this problem is here.
+
+It's too bad, the problem proposed by [havaliza](/profile/havaliza "Candidate Master havaliza") is actually very nice. Perhaps we will see it in one of the upcoming rounds :)
+
+### [Problem C](//codeforces.com/contest/183/problem/C)
+
+Author: [dolphinigle](/profile/dolphinigle "Grandmaster dolphinigle")
+ DFS
+
+Let's drop the (modulo K). That is, the rule becomes:
+
+* X->Y implies that Y = X+1
+* Y->X implies that Y = X-1
+
+Notice that this problem is then equivalent to finding the maximum possible K such that the above equation holds for all edges, modulo K.
+
+While we still dropping the "modulo K" thingy, we try to calculate the values of each node. We iterate over each node, and if we haven't processed the node:
+
+* Number the node 0 (or any other number you like). let's denote this by no[i] = 0.
+* DFS the node:
+ + DFS(X): if there exists X->Y, then no[Y] = no[X]+1. This follows from the first rule.
+ + DFS(X): if there exists Y->X, then no[Y] = no[X]-1. This follows from the second rule.
+ + If Y is renumbered (that is, the algorithm has renumber it in the past and we renumber it again), consider the difference between the two numbers. We claim that this difference, if not zero, must be a multiple of K. To see this, suppose the two numbers are A and B. By the way our algorithm works, that node must be able to be numbered A or B. Hence, A == B (mod K) must holds. But then, A-B == 0 (mod K) implies that (A-B) is a multiple of K.
+* If a non-empty multiple of K (let's say it's CYCLEN) is not found in the step above, we claim that the answer is the maximum possible answer: N. Indeed if no such value is found, it means that renumbering the nodes into no[i] % N be correct, since every edge is already consistent with no[i].
+* Otherwise, we can simply brute force all divisors of CYCLEN and try each of them. Since "trying" uses O(E) time (that is, by setting each number into no[i] % K and checking whether the two rules holds for all edges) , we have a O(number_of_divisors * E) algorithm, which with the given constraints is less than O(E * sqrt(N)).
+
+For instance, [sexyprincess91](/profile/sexyprincess91 "Master sexyprincess91") implemented this. [1632321](/contest/183/submission/1632321 "Submission 1632321 by sexyprincess91")
+
+### [Problem D](//codeforces.com/contest/183/problem/D)
+
+Author: [dolphinigle](/profile/dolphinigle "Grandmaster dolphinigle")
+ Dynamic Programming, Probabilities, and a little Greedy
+
+Suppose we have decided to bring N1 T-shirts of size 1, N2 T-shirts of size 2, ... NM T-shirts of size M. By the linearity of expectation, the expected number of engineers that will receive a T-shirt is equal to the sum of the expected number of engineers that will receive a T-shirt of size K, for all K.
+
+Suppose we bring Ni T-shirts of size i. Define a random variable Xij as the number of engineer that will receive the j-th T-shirt of size Ni that we bring. Hence, the expected number of engineers that will receive the Ni T-shirts of size i that we bring is equal to the sum of Xij over all j. Since Xij is either 0 or 1, Xij is equal to Pij, the probability that there will be an engineer that will receive the j-th T-shirt of size i that we bring. This is equal to the probability that there will be at least j engineers that fits inside T-shirt of size i.
+
+As a result of our discussion, to maximize the expectation, it boils to maximizing the sum over Xij. Hence, we receive our first solution: Calculate the value of all Xij, and pick the N largest value. A DP implementation allows us to accumulate all Xij value in O(N*N*M) time, yielding an O(N*N*M) solution.
+
+We will now reduce the time limit to O(N*N + N*M). Notice that the algorithm above only need us to find the N largest values of Xij. Denote by f(n, i, j) the probability that, amongst engineers numbere 1 through n, at least j of them fits inside T-shirt of size i. f(n, i, j) can be computed with the following recurrence: f(n, i, j) = f(n-1, i, j-1) * fit_chance(n, i) + f(n-1, i, j) * (1.0 — fit_change(n, i)) Where fit_chance(t-shirt, engineer) is the probability that engineer fits inside the t-shirt size.
+
+The formula above can be inferred from simple logic: if the n-th engineer fits inside t-shirt of size i (with fit_change(n, i) probability), then f(n, i, j) is obviously equal to f(n-1, i, j-1). Otherwise, it'll equal f(n-1, i, j).
+
+Now, observe that Xij = f(N, i, j). Indeed, this is one of the possible DPs that can lead to the O(N*N*M) solution. However, we will show that we do not need to compute f(n, i, j) for all possible inputs if we're asked to find only the N largest values of Xij.
+
+The key observation is the following obvious fact. If Xij is included in the N largest values, then Xi(j-1) must also be included there. Inductively, Xik for k < j must also be included in the N largest values. Indeed, it's obvious that Xij must be non-increasing with respect to j.
+
+Hence the algorithm works as follows. First, we create a pool of numbers Xi1, for all i, totalling M numbers. Then, we iterate N times. In each iteration, we pick the largest number in the pool, say, Xij. Then, we add Xij as one of the K largest values. Then, we take out Xij from the pool, and insert Xi(j+1) as its replacement. That it correctly picks the N largest Xij values follows immediately from our argument in the paragraph preceeding this.
+
+Now, if we use the recurrence f(n, i, j) above to compute each Xij, what is the complexity of this algorithm? If we memoize f(n, i, j), we claim that it's O(N*N + N*M). To see this, we notice that the only values required to compute f(n, i, j) using the recurrence above are the values f(m, i, l) such that m <= n and l <= j. However, we notice that due to how our algorithm works, when we need to compute Xij, we must have already computed Xi(j-1) before, so that all values f(m, i, l) for m <= n and l <= j-1 are already available. So the only NEW values that we need to compute are f(m, i, j), m <= n. There are n such values.
+
+Since we need to compute at most O(N) values of Xij, the total complexity this part contributes is O(N*N). Depending on how you implement the "pick largest from pool" algorithm, the total complexity can be either O(N*N + N*M) or O(N*N + N*log M).
+
+Yes, somebody did this in the contest :). [Dmitry_Egorov](/profile/Dmitry_Egorov "Candidate Master Dmitry_Egorov") [1632270](/contest/183/submission/1632270 "Submission 1632270 by Dmitry_Egorov") saved my problem from loneliness :)
+
+Bonus Section: Now here's an extremely interesting solution shown by the following Python pseudocode:
+
+```
+values = []
+for size in range(M):
+ i = 1
+ while (val = f(N, size, i)) > epsilon:
+ values.append(val)
+ ++i
+ end
+end
+Print the sum of the largest N values in array values.
+```
+
+Its correctness is immediate as long as epsilon is reasonably small (since f(N, size, i) is non-increasing with respect to i). What is the complexity of this very simple algorithm?
+
+I am unable to come up with a hard, solid proof, but since f(N, size, i) exponentially falls (except if some probabilities are 1, in which case some other T-shirt must have less value to worry on), the complexity is somewhere near O(N * N). Indeed for the current set of test cases, its speed exceeds that of the intended solution.
+
+Although [rng_58](/profile/rng_58 "International Grandmaster rng_58") do not implement this exact algorithm, he used the <EPS ignore idea in his solution [1631960](/contest/183/submission/1631960 "Submission 1631960 by rng_58")
+
+**Remarks**
+
+I really really wanted to link [Gerald](/profile/Gerald "Master Gerald")'s handle in the statement :). Too bad Codeforces doesn't support it.
+
+### [Problem E](//codeforces.com/contest/183/problem/E)
+
+Author: [dolphinigle](/profile/dolphinigle "Grandmaster dolphinigle")
+ Very greedy
+
+Brute force P: the number of Packages each kid will have at the end. There are at most N/M possible such value. We will assume that P is fixed during our discussion.
+
+If we know P, we know that if kid i purchases a total of X candies, then kid i+1 must purchase at least X+P candies (1 more than each package purchased by kid i). Hence, assume that money[i] <= money[i+1] — P.
+
+Two consecutive packages purchased by the SAME kid must differ by at least M. Indeed, otherwise there are less than M-1 packages for the other M-1 kids to buy from (Pigeonhole rocks by the way).
+
+For the sake of our discussions below, we refer to the following example with N=8, and M=3 kids. The allowances of the kids are 7, 10, and 14.
+
+
+
+Suppose we know all candies kid 0 purchased (red bags denote the packages kid 0 purchased).
+
+
+
+We claim that the optimal solution can be computed rather... easily with the following greedy algorithm: (assume that the candy packages kid 0 purchase is sorted in an ascending order). We iterate over the remaining kids, starting from kid 1. First, let the kid purchase the minimum possible candies:
+
+
+
+Next, if the allowance is still greater than the sum of candies, and if one of his package(s) can still be shifted to the right while maintaining the condition that a possible solution exists, do so. If there are multiple package(s) that can be shifted, shifting any of them does not change the optimal answer.
+
+
+
+Note: since we've assumed that money[i] <= money[i+1]-P, the only condition is that between the package purchased by kid 1 an the next package purchased by kid 0, there exists at least N-2 packages. For instance, this is illegal, since there is no package that kid 2 will be able to purchase between 4 and 5.
+
+
+
+We iterate this once more for kid 2, obtaining:
+
+
+
+And we're done. It's arguably the maximum possible value, since there is no reason why we shouldn't shift a package for a kid to the right if we can (formal proof by contradiction).
+
+Claim: If we know the packages for kid 0, the maximum total candies purchased can be computed in O(M), where M is the number of kids.
+
+The algorithm simulates our discussion above. However it is not obvious how to do that in O(M). So, suppose kid 0 purchase the candies like this:
+
+
+
+Now, try putting the other P-1 packages into the minimum possible locations:
+
+
+
+The packages inside the yellow boxes denote what we will call [FREEDOM](http://gundam.wikia.com/wiki/ZGMF-X10A_Freedom_Gundam). Basically FREEDOM is the count on how many times we can at most shift a package to the right as in our discussion above.
+
+Now, consider kid 1. First, as in our discussion, kid 1 takes the minimum amount of packages, which is equal to sum[kid 0] + P. Next, he will attempt to shift the packages if possible. Notice that the only thing that affects the overall sum of the candy is only the number of shifts performed, not which package actually got shifted. So, this means that, the amount of shift can be easily calculated by min(money[1] — (sum[kid 0] + P), FREEDOM). And then, FREEDOM is deducted from this value, while the amount of candies purchased by kid 1 is incremented by this value.
+
+Hence, simulating the algorithm in our discussion if we're only to output the total amount of candies can be done in O(M).
+
+The result of our discussion so far is this. Notice that the last algorithm only depends on how many candies kid 0 purchased, and FREEDOM.
+
+Now we will remove the assumption that we know which packages kid 0 decides to purchase.
+
+Claim: It is optimal for kid 0 to purchase as many candies as possible.
+
+Suppose kid 0 does not purchase the maximum possible of candies he can purchase. Now, consider whether or not kid 1 "shifted" his candies.
+
+* If he shifted any of them, say package X, then instead of purchasing package X-1, kid 0 should purchase package X, improving the overall amount of candies. That is, instead of
+ 
+ It's better to
+ 
+* If kid 1 did not "shift" his candies because the amount of money he spent is already equal to his allowance, then the amount of candies purchased by kid 0 must be maximum since money[i] <= money[i+1] — P.
+* Otherwise, we can apply this inductively to kid 2 and so forth. That is, instead of
+ 
+ It's better to
+ 
+
+Okay, now we know the sum of candies that we should give to kid 1. Since the performance of our algorithm increase with FREEDOM, we should next try to maximize FREEDOM.
+
+Claim: FREEDOM depends only on the position of the FIRST candy package purchased by kid 0.
+
+This can be shown by simple computation, and its equal to N — pos — M*P (or something like that).
+
+Hence, we should try to minimize the first candy package purchased by kid 0, while keeping the sum maximum. This can be done in O(1) using a bunch of N*(N+1)/M * P formulas.
+
+Hence, since there are N/M package numbers to be brute forced, and each iteration uses O(M) time, the total complexity is O(N/M) * O(M) = O(N).
+
+For instance, see [1632210](/contest/183/submission/1632210 "Submission 1632210 by rng_58") by [rng_58](/profile/rng_58 "International Grandmaster rng_58") (again :) ).
+
+**Epilogue**
+
+Thank you for participating in the match!
+
+
+
+Hope to see you again!
diff --git a/editorials/185.md b/editorials/185.md
@@ -0,0 +1,66 @@
+Source: https://codeforces.com/blog/entry/4488
+
+No problem was specially taken from "Wikipedia". For me it's really hard to understand, that problem "B" was there.
+
+**A (Div 2).** (Idea : [Gerald](/profile/Gerald "Master Gerald"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1670635](/contest/186/submission/1670635 "Submission 1670635 by Aksenov239"))
+
+If the lengths of 2 strings aren't equal — that means "NO". We try to find the positions in strings, where chars are different. If there 1 or more than 2 such positions — "NO". After that we swap 2 characters in the first string, and check for their equality.
+
+**B (Div 2).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1670637](/contest/186/submission/1670637 "Submission 1670637 by Aksenov239"))
+
+1. We can see, that we can do all in integers, because k is integer number of percent.
+2. For each dwarf we should find his optimal strategy — to check 2 strategies with speed.
+3. We should sort them.
+
+**A (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652592](/contest/185/submission/1652592 "Submission 1652592 by Aksenov239")) Let's propose, that after the *i*-th year, there is *x* triangles up and *y* triangles down. After another iteration we can see, that amount of triangles became — 3*x* + *y* up and *x* + 3*y* down. Let's see the difference between them: at the *i*-th it's *x* - *y* and at the *i* + 1-th — it's (3*x* + *y*) - (*x* + 3*y*) = 2 * (*x* - *y*). We can see, that difference between amount of triangles grown up by 2. Because on the *i*-th year the difference became 2*i* and all amount of triangles is 4*i*. We can see, that on the *i*-th year the number of our triangles is . That can be computed by modulo p using the fast-power algorithm.
+
+**B (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652597](/contest/185/submission/1652597 "Submission 1652597 by Aksenov239")) This problem was made by my love to inequalities. :-)! The answer for this problem is 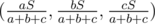.
+
+Prove: 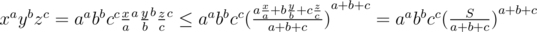. (This is AM-GM inequality. [Link for whom don't know it.](http://www.artofproblemsolving.com/Wiki/index.php/AM-GM))
+
+The equality becomes only, when .
+
+And you should check on zeroes. If *a* = *b* = *c* = 0 — you can choose any good answer — *x* + *y* + *z* ≤ *S*.
+
+**C (Div 1).** No comments. :-)!
+
+**D (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [cerealguy](/profile/cerealguy "International Master cerealguy"), [Gerald](/profile/Gerald "Master Gerald"), [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652604](/contest/185/submission/1652604 "Submission 1652604 by Aksenov239"))
+
+This is number theory problem.
+
+I'm trying to explain it step by step:
+
+1) Let's prove, that LCD is maximum 2.
+
+Let 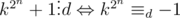. Squaring both sides we get 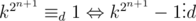, but we want to . This means, that *d* can be only 2.
+
+2) Let's make this lenghty product simplier.
+
+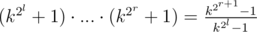.
+
+We can count this by modulo *p* fast, and divide it by 2*r* - *l*, if *k* is odd.
+
+3) There is many interesting things in this solution.
+
+Firstly, it doesn't work, when *p* = 2 — but it can easily done by you.
+
+The other problem is harder, what if , this means that for each *i* ≥ *l* : , and this mean,
+that for each *i* ≥ *l* : *k*2*i* + 1 ≡ *p*2. And the product by modulo *p* is equal to 2*r* - *l* + 1.
+
+E (Div. 1) (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), relization : [cerealguy](/profile/cerealguy "International Master cerealguy"), code : [1652611](/contest/185/submission/1652611 "Submission 1652611 by Aksenov239"))
+
+This problem wasn't taken to ROI, because of that I gave it here. This is pretty hard problem. I can't now realize, what [cerealguy](/profile/cerealguy "International Master cerealguy") wrote, but his solution is *O*(*nlogn*) — without binary search. For me it's quite hard to understand, because my first solution was with binary search. And there were solutions, that has a worse asymptothic, but they run faster.
+
+Because of that I can only give you key ideas, that can help you. (afterwards you can see the code of [cerealguy](/profile/cerealguy "International Master cerealguy"))
+
+Ideas:
+
+1. Let's find for each person the nearest subway point for them. It can be done in nlogn with use of segment tree or something else.
+2. We can see, that if one person goes to subway, the others, which distance to subway is smaller, can go to subway too — it doesn't affect the answer. Because of that we sort all persons by their distanse to subway.
+3. The area of the person, where he can come in *t* seconds, is romb. And we can intersect all rombes in *O*(*n*) — the intersection is like rectangle.
+4. Let's make the first intersection. When nobody goes to subway. We get a rectangle.
+5. The main idea, that for this rectangle — the nearest subway becomes always the same. We go throught people in sorted order, we can fast recalculate this small rectangle — and because of that we can fast recalculate the answer.
+
+And we get a solution in *O*(*nlogn*) time. Ta-dams.
+
+Thank you all for your attention. I'm deeply sorry about the problem "C".
diff --git a/editorials/186.md b/editorials/186.md
@@ -0,0 +1,66 @@
+Source: https://codeforces.com/blog/entry/4488
+
+No problem was specially taken from "Wikipedia". For me it's really hard to understand, that problem "B" was there.
+
+**A (Div 2).** (Idea : [Gerald](/profile/Gerald "Master Gerald"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1670635](/contest/186/submission/1670635 "Submission 1670635 by Aksenov239"))
+
+If the lengths of 2 strings aren't equal — that means "NO". We try to find the positions in strings, where chars are different. If there 1 or more than 2 such positions — "NO". After that we swap 2 characters in the first string, and check for their equality.
+
+**B (Div 2).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1670637](/contest/186/submission/1670637 "Submission 1670637 by Aksenov239"))
+
+1. We can see, that we can do all in integers, because k is integer number of percent.
+2. For each dwarf we should find his optimal strategy — to check 2 strategies with speed.
+3. We should sort them.
+
+**A (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652592](/contest/185/submission/1652592 "Submission 1652592 by Aksenov239")) Let's propose, that after the *i*-th year, there is *x* triangles up and *y* triangles down. After another iteration we can see, that amount of triangles became — 3*x* + *y* up and *x* + 3*y* down. Let's see the difference between them: at the *i*-th it's *x* - *y* and at the *i* + 1-th — it's (3*x* + *y*) - (*x* + 3*y*) = 2 * (*x* - *y*). We can see, that difference between amount of triangles grown up by 2. Because on the *i*-th year the difference became 2*i* and all amount of triangles is 4*i*. We can see, that on the *i*-th year the number of our triangles is . That can be computed by modulo p using the fast-power algorithm.
+
+**B (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652597](/contest/185/submission/1652597 "Submission 1652597 by Aksenov239")) This problem was made by my love to inequalities. :-)! The answer for this problem is 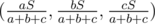.
+
+Prove: 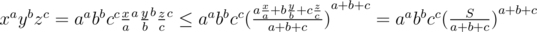. (This is AM-GM inequality. [Link for whom don't know it.](http://www.artofproblemsolving.com/Wiki/index.php/AM-GM))
+
+The equality becomes only, when .
+
+And you should check on zeroes. If *a* = *b* = *c* = 0 — you can choose any good answer — *x* + *y* + *z* ≤ *S*.
+
+**C (Div 1).** No comments. :-)!
+
+**D (Div 1).** (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), realization : [cerealguy](/profile/cerealguy "International Master cerealguy"), [Gerald](/profile/Gerald "Master Gerald"), [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), code : [1652604](/contest/185/submission/1652604 "Submission 1652604 by Aksenov239"))
+
+This is number theory problem.
+
+I'm trying to explain it step by step:
+
+1) Let's prove, that LCD is maximum 2.
+
+Let . Squaring both sides we get 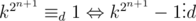, but we want to . This means, that *d* can be only 2.
+
+2) Let's make this lenghty product simplier.
+
+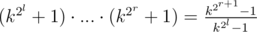.
+
+We can count this by modulo *p* fast, and divide it by 2*r* - *l*, if *k* is odd.
+
+3) There is many interesting things in this solution.
+
+Firstly, it doesn't work, when *p* = 2 — but it can easily done by you.
+
+The other problem is harder, what if , this means that for each *i* ≥ *l* : , and this mean,
+that for each *i* ≥ *l* : *k*2*i* + 1 ≡ *p*2. And the product by modulo *p* is equal to 2*r* - *l* + 1.
+
+E (Div. 1) (Idea : [Aksenov239](/profile/Aksenov239 "Candidate Master Aksenov239"), relization : [cerealguy](/profile/cerealguy "International Master cerealguy"), code : [1652611](/contest/185/submission/1652611 "Submission 1652611 by Aksenov239"))
+
+This problem wasn't taken to ROI, because of that I gave it here. This is pretty hard problem. I can't now realize, what [cerealguy](/profile/cerealguy "International Master cerealguy") wrote, but his solution is *O*(*nlogn*) — without binary search. For me it's quite hard to understand, because my first solution was with binary search. And there were solutions, that has a worse asymptothic, but they run faster.
+
+Because of that I can only give you key ideas, that can help you. (afterwards you can see the code of [cerealguy](/profile/cerealguy "International Master cerealguy"))
+
+Ideas:
+
+1. Let's find for each person the nearest subway point for them. It can be done in nlogn with use of segment tree or something else.
+2. We can see, that if one person goes to subway, the others, which distance to subway is smaller, can go to subway too — it doesn't affect the answer. Because of that we sort all persons by their distanse to subway.
+3. The area of the person, where he can come in *t* seconds, is romb. And we can intersect all rombes in *O*(*n*) — the intersection is like rectangle.
+4. Let's make the first intersection. When nobody goes to subway. We get a rectangle.
+5. The main idea, that for this rectangle — the nearest subway becomes always the same. We go throught people in sorted order, we can fast recalculate this small rectangle — and because of that we can fast recalculate the answer.
+
+And we get a solution in *O*(*nlogn*) time. Ta-dams.
+
+Thank you all for your attention. I'm deeply sorry about the problem "C".
diff --git a/editorials/187.md b/editorials/187.md
@@ -0,0 +1,107 @@
+Source: https://codeforces.com/blog/entry/4540
+
+### Problem [189A — Cut Ribbon](//www.codeforces.com/problemset/problem/189/A)
+
+The problem is to maximize *x+y+z* subject to *ax+by+cz=n*. Constraints are low, so simply iterate over two variables (say *x* and *y*) and find the third variable (if any) from the second equation. Find the maximum over all feasible solutions.
+
+Other approaches: Use dynamic programming with each state being the remainder of ribbon. Select the next piece to be *a*, *b* or *c*.
+
+### Problem [189B — Counting Rhombi](//www.codeforces.com/problemset/problem/189/B)
+
+Observe that lots of rhombi have the same shape, but are in different locations.
+
+What uniquely determines the shape of a rhombus? Its width and its height.
+
+Is it possible to build a rhombus with every width and every height such that the vertices of the rhombus are in integer points? No, it is possible only if the width and the height are both even.
+
+How many places we can put a rhombus of width *w0* and height *h0* in a rectangle of width *w* and height *h*? *(w * w0 + 1)(h * h0 + 1)*
+
+So, iterator over all even widths and heights and for each of them add the number of possible locations to the final result.
+
+### Problem [187A — Permutations](//www.codeforces.com/problemset/problem/187/A)
+
+It is easy to see that if we replace each number in the first permutation with position of that number in the second permutation, the problem reduces to sorting the first permutation.
+
+Each time we take a number from the end of array, we can postpone its insertion until we know the most suitable position for insertion. Note that it is not good to insert a number and take it again, as we could make a better decision first time we took the number.
+
+So, as long as the remainder of the array is not in increasing order, we should take more numbers from the end. But as soon as you have an increasing subsequence, you can insert the numbers you have taken to make the array sorted.
+
+Therefore to solve the problem, we find the largest *i* such the numbers from *1* to *i* are in increasing order. The answer would be *n-i*.
+
+### Problem [187B — AlgoRace](//www.codeforces.com/problemset/problem/187/B)
+
+First we solve the problem when the number of allowed car changes is zero (_k=0_). Let *W(i,j,l)* be the length of shortest path from *i* to *j* with car *l*. We use Floyd-Warshal on graph of each car to find this value. Then answer for the case that we can use only one car for each pair of cities *i* and *j* is:
+
+*ans(0,i,j) = min W(i,j,l)* for (_1≤l≤m_)
+
+This part has time complexity *O(m*n^3)*.
+
+For larger values of maximum number of changes (_k_), we use the following equation:
+
+*ans(k,i,j) = min (ans(k-1,i,l)+ans(0,l,j))* for (_1≤l≤k_)
+
+which can be computed in *O(k*n^3)* using dynamic programming.
+
+But how large can be *k* in worst case? We know that shortest paths are simple paths (i.e. they have no repeated vertices). Because otherwise we could eliminate the path we go between two appearances of one vertex and have a smaller result. This and the fact that we change the car at most once in each vertex, guarantees in any optimal solution we will not need more that *n* car changes. Thus the order of the solution would be *O(m*n^3+n^4)*.
+
+### Problem [187C — Weak Memory](//www.codeforces.com/problemset/problem/187/C)
+
+There were many different correct approaches to this problem during the contest. But I will explain author’s solution.
+
+First we can use binary search over the value of *q*. Now for a fixed *q* we want to check *s-t* connectivity.
+
+Let *K* be the set of all intersections with volunteers union s and t. One can use BFS from each *k∈K*, one by one. Then build a graph *G’* with vertices *K*. For each two vertices *k1,k2∈K* add an edge between them, if their shortest distance is less than or equal to *q*. Finally use any path finding algorithm to check the connectivity. Unfortunately this solution has time (and space) complexity of *O(|K|*m)* which is not good enough.
+
+We can optimize the above solution by initiating BFS from all *k∈K* at once. In other words during the initialization step in BFS algorithm, we push all these vertices in the queue with distance *0*. Each element in the queue also maintains its source (i.e. the source it is originating from). In BFS each time we have have a vertex *u* with source *su* and we want to set the minimum distance to a vertex *v* that is already set from a different path with source *sv*, we connect *su* and *sv* in *G’* if *d(u)+d(v)+1<= q*, where *d(x)* denotes length of the shortest path from a vertex in *K* to *x*. As we are only dealing with connectivity, this approach is correct. (Proof of correctness is left as an exercise)
+
+BFS takes *O(m)* time and we add at most *O(m)* edges to *G’*, so the overall complexity is *O(m)* for a fixed *q*. As we used binary search to find the smallest *q*, we can solve the problem in *O(m*logn)*.
+
+### Problem [187D — BRT Contract](//www.codeforces.com/problemset/problem/187/D)
+
+We define *ti* as follows: assume a bus starts moving from *i*-th intersection exactly at the time when the light changes to green. The time it takes for the bus to get the final station is *ti*. We call the times when a green interval begins *t0* (so every *g+r* seconds *t0* occurs once)
+
+If a bus gets to *i*-th intersection during the red phase, it should wait and then start moving at *t0*. So considering the fact that all lights are synchronized (and length of segments are fixed) if we have *ti* for *i*-th intersection, we can compute the time for the bus to get final station.
+
+Clearly *tn* is the length of the last segments. For computing *ti* we should find the smallest *j* such that if a bus starts at *t0* from *i*-th intersection, it gets to *j*-th intersection during the red phase. So we have:
+
+*ti=tj+d(i,j)+w*
+
+where *d(i,j)* is the distance between *i*-th and *j*-th intersections and *w* is the time that the bus should wait behind the red light at *j*-th intersection. The later value can be computed easily.
+
+The only problem that remains is to find *j* for *i*-th intersection. So we start iterating over *i* for *(n-1)*-th intersection backwards and we compute *ti* for all intersections. Assume *p=g+r* and *ta=d(i,j)%p*. Now if the bus starts from *i*-th intersection at time *t0* and we have *ta>=g*, in this case we are in red phase at *j*-th intersection. Actually *ta* should be in interval [_g, g+r_).
+
+Here we can use segment trees. That is for all intersections from *i+1* to *n*, we store some values in the tree that helps us find the smallest *j*. But we should note the value of *ta* depends on *d(i,j)* which changes as *i* changes. Thus we cannot use *ta* in the tree. Instead, we define *si* the be the distance of *i*-th intersection to the destination. So we have *d(i,j)=si-sj* and we use the value of *sj* with storing *–sj%p* in the segment tree as the key and the value would be *j* itself. In other words for each intersection we store the key-value pair *(-sj%p, j)* in the tree. According to what we said so far, to be in the red phase at *j*-th intersection we should have:
+
+*ta=(d(i,j)%p)=((si-sj)%p)∈[g,g+r) => -sj%p ∈ [(g-si)%p, (g+r-si)%p)*
+
+As we stored *–sj%p* in the tree, we can retrieve the smallest *j* in the above interval with a query in the segment tree.
+
+This way we can compute *ti* for all intersections. Answering to each query in the problem can be solve in exactly the same way. So the overall complexity would be *O((n+q)logn)*.
+
+### Problem [187E — Heaven Tour](//www.codeforces.com/problemset/problem/187/E)
+
+**Step 1**. Solve the problem if the starting man is the leftmost man and the finishing man is the rightmost man.
+
+Obviously every segment (the distance between two consecutive men) should be covered at least once. We also argue that at least *l* (the number of left tickets) segments should be covered at least three times.
+
+*Proof*: Each time you use a left ticket to go to man *i* with *1<i<n-1*, the segment between *i*-th and (_i+1_)-th men is covered at least three times:
+
+1. Once for you should go after *i* be in a position to come back.
+2. Once for you use a left ticked to come back to *i*
+3. And once again you should go after *i*, because you want to finish at man number *n*
+
+Note that in the first and the last segments are always covered once, no matter what we do. But except for these two segments, every other segment can be chosen to be among the segments that are covered three times, and every combination that we choose *l* segments is feasible. (Proof it as practice) So we choose the smallest *l* segments and the problem can be solved with a simple sort in *O(n*logn)*.
+
+**Step 2**. Solve the problem if the starting man is the leftmost man, but the finishing man can be anywhere.
+
+To solve this problem we first fix the finishing man. With reasoning similar to that of step 1, we conclude that at least *l* segments should be covered with at least two times if they are after the finishing man or three times if they are before him. But obviously every segment after the finishing man is covered at least two times. So it is always good to waste as many left tickets as possible after the finishing man to prevent them from breaching the left side of finishing man and becoming multiple three.
+
+So the algorithm would be: iterate over *i*, the number of finishing man, and maintain the *l-(n-i)* smallest segments to the right of finishing man as you progress. This can be implemented in *O(n*logn)*.
+
+**Step 3**. Solve the problem if the starting man is fixed, but the finishing man can be anywhere.
+
+Assume that the starting man is not the first man or the last man, otherwise we could use algorithm of step 2 to solve the problem. Without loss of generality assume that you finish your tour to the right side of finishing man. Therefore every segment to the left of starting man is covered at least two times and actually it is always possible to arrange visits such that every segment to right is covered exactly two times. So just like what we said in step 2, it is good to waste as many left tickets as possible in this area.
+
+So the algorithm would be, choose to finish left or right first, then greedily waste as many bad moves (by bad moves I mean the moves that if breach to the other side will be more costly) as possible there and follow the algorithm in step 2 to solve the whole problem.
+
+There are some special cases such as when the tour cannot be finished at all, that we left to readers find a way how to handle them.
diff --git a/editorials/188.md b/editorials/188.md
@@ -0,0 +1,327 @@
+Source: https://codeforces.com/blog/entry/4633
+
+Roco is a very simple language. On one hand, it's esoteric, so everything you need to know about it fits in two pages. On the other hand, it's powerful enough to enable writing rather complicated programs in it without racking one's brains over each elementary operation (like in Brainfuck). Being able to refer variables using names (numerical, but names nevertheless) is already a gift to the programmer :-)
+
+#### [188A - Hexagonal Numbers](/contest/188/problem/A "Surprise Language Round 6")
+
+As usual, the first problem tests the competitor's understanding of basic arithmetic operations. The solution is very similar to the example.
+
+```
+iin [0]
+mul [1] [0] 2
+dec [1]
+mul [1] [1] [0]
+iout [1]
+ac
+```
+
+Starting with the second one, the problems need learning the main feature of the language — the coroutines. A coroutine is a named piece of code executed in an endless loop. Something in between a procedure (without input parameters and variables, but with a name used for calling it) and a loop (without loop counter or break conditions, but with a chance to break it at any moment), coroutines allow to implement both these concepts.
+
+#### [188B - A + Reverse B](/contest/188/problem/B "Surprise Language Round 6")
+
+The key element of this problem is reversing a number (we knew how to add the second number to it ever since the example). There are two ways to do this: either read the number as a sequence of characters and accumulate its reverse simultaneously, or read the number as, well, a number and calculate its reverse using math. I used the second approach, so I needed a single loop-like coroutine which stopped when the number being reversed turned zero.
+
+```
+/* coroutine to reverse a number [1] into [2] */
+co reverse {
+ eq [3] [1] 0
+ if [3]
+ ac
+
+ /* find current number modulo 10 */
+ mod [3] [1] 10
+ /* add it to reversed number */
+ mul [2] [2] 10
+ add [2] [2] [3]
+ /* and divide current number */
+ div [1] [1] 10
+}
+
+iin [0]
+iin [1]
+ca reverse
+add [2] [2] [0]
+iout [2]
+ac
+```
+
+#### [188C - LCM](/contest/188/problem/C "Surprise Language Round 6")
+
+In other languages the easiest way to get LCM of two numbers is recursive. The specifics of Roco is that one can't write a recursion with a single coroutine calling itself — after the second call of the coroutine its execution continues from the place where it stopped last time. So it was easier to rewrite the standard algorithm as a loop.
+
+```
+/* [0] - a
+ [1] - b
+*/
+co gcd {
+ eq [2] [0] 0
+ if [2]
+ ac
+ set [2] [1]
+ set [1] [0]
+ mod [0] [2] [1]
+}
+
+iin [0]
+iin [1]
+set [3] [0]
+set [4] [1]
+ca gcd
+/* now [1] is gcd */
+div [5] [3] [1]
+mul [5] [5] [4]
+iout [5]
+ac
+```
+
+#### [188D - Asterisks](/contest/188/problem/D "Surprise Language Round 6")
+
+Ok, let's move on to a more complicated task: here we need a nested loop, the outer one running through the lines and the inner one — through the asterisks in the line. The inner loop will be called several times (from each iteration of the outer one), so here one could meet the mentioned feature of the coroutines for the first time.
+
+```
+/* [0] - * quantity
+ [1] - current line
+ [2] - current * in line
+*/
+
+co one_row {
+ lt [3] [1] [2]
+ if [3]
+ ac
+ cout 42
+ inc [2]
+}
+
+co print_all {
+ lt [3] [0] [1]
+ if [3]
+ ac
+ set [2] 1
+ ca one_row
+ cout 10
+ inc [1]
+}
+
+iin [0]
+set [1] 1
+ca print_all
+ac
+```
+
+#### [188E - HQ9+](/contest/188/problem/E "Surprise Language Round 6")
+
+This time one can't solve this problem in one line using regular expressions, since this language has none. So one has to do it in an old-fashioned way, reading characters one-by-one and checking them for equality with each of the required ones. The code is rather long — there are three characters to compare each one to, and the answer has to be printed char-by-char, but overall there is nothing complex here.
+
+```
+/* [0] - YES or NO
+ [1] - current char
+*/
+
+co one_char {
+ cin [1]
+
+ eq [2] [1] 10
+ if [2]
+ ac
+
+ /* H */
+ eq [2] [1] 72
+ or [0] [0] [2]
+ /* Q */
+ eq [2] [1] 81
+ or [0] [0] [2]
+ /* 9 */
+ eq [2] [1] 57
+ or [0] [0] [2]
+}
+
+co say_yes {
+ cout 89
+ cout 69
+ cout 83
+ cout 10
+ ac
+}
+
+co say_no {
+ cout 78
+ cout 79
+ cout 10
+ ac
+}
+
+set [0] 0
+ca one_char
+/* output the result stored in [0] */
+if [0]
+ ca say_yes
+dec [0]
+if [0]
+ ca say_no
+ac
+```
+
+Three last problems are almost real programming :-) They use the fact that in Roco variables are referenced not by names but by their indices in the heap, and the index can in turn be the contents of a variable. One can do more interesting things with arrays, but the programs become longer and more error-prone.
+
+#### [188F - Binary Notation](/contest/188/problem/F "Surprise Language Round 6")
+
+The bad thing about the binary notation is that the digits are calculated right-to-left but have to be printed left-to-right. This can be done without arrays (reverse the number in binary using the math trick from [188B - A + Reverse B](/contest/188/problem/B "Surprise Language Round 6") and then print its digits in the same order as they are calculated), but I used an array solution which first calculates the digits and writes them into an array and then goes through the array from the end to the start and prints the digits.
+
+```
+/* [0] - current number
+ [1] - index of last digit calculated
+ [2]..[9] - service cells
+ [10]..[[1]] - the actual digits of the number
+*/
+
+co calculate_digits {
+ /* stop when the number is 0 */
+ eq [3] [0] 0
+ if [3]
+ ac
+
+ /* get next digit - put it to its location directly */
+ mod [[1]] [0] 2
+ /* update the number and its notation length */
+ div [0] [0] 2
+ inc [1]
+}
+
+co output_digits {
+ /* stop when the next digit printed will be outside of the number */
+ eq [3] [1] 9
+ if [3]
+ ac
+
+ /* output the digit at [1] */
+ iout [[1]]
+ dec [1]
+}
+
+
+iin [0]
+set [1] 10
+ca calculate_digits
+dec [1]
+ca output_digits
+ac
+```
+
+#### [188G - Array Sorting](/contest/188/problem/G "Surprise Language Round 6")
+
+Unlike Befunge, in Roco the memory size limit is technical, not conceptual, so one could coed counting sort as well as comparison-based sort. Here is a code for the former one.
+
+```
+/* [1]..[100] - the counts of numbers
+ [101] - quantity of numbers
+ [102] - current number
+ [103] - current index
+*/
+
+iin [101]
+
+set [103] 1
+co init {
+ eq [104] [103] 101
+ if [104]
+ ac
+ set [[103]] 0
+ inc [103]
+}
+ca init
+
+set [103] 0
+co read {
+ eq [104] [103] [101]
+ if [104]
+ ac
+ iin [102]
+ inc [[102]]
+ inc [103]
+}
+ca read
+
+set [102] 1
+co print_sorted {
+ eq [104] [102] 101
+ if [104]
+ ac
+ set [103] 1
+ co print_one_number {
+ gt [104] [103] [[102]]
+ if [104]
+ ac
+ iout [102]
+ cout 32
+ inc [103]
+ }
+ /* due to coroutine property (!), call only for positive quantity of numbers*/
+ gt [104] [[102]] 0
+ if [104]
+ ca print_one_number
+ inc [102]
+}
+ca print_sorted
+ac
+```
+
+#### [188H - Stack](/contest/188/problem/H "Surprise Language Round 6")
+
+This problem required to simulate a stack using an array — nothing too complicated, especially since the data never overflows and never attempts to do invalid calculations.
+
+```
+/* [0] - current character
+ [1] - current stack size
+ [2]..[9] - service
+ [10]... - stack
+*/
+
+co plus {
+ dec [1]
+ add [3] [1] 9
+ add [4] [3] 1
+ add [[3]] [[3]] [[4]]
+ ac
+}
+
+co multiply {
+ dec [1]
+ add [3] [1] 9
+ add [4] [3] 1
+ mul [[3]] [[3]] [[4]]
+ ac
+}
+
+co number {
+ sub [2] [0] 48
+ inc [1]
+ add [3] [1] 9
+ set [[3]] [2]
+ ac
+}
+
+co process {
+ cin [0]
+ /* end of line */
+ eq [2] [0] 10
+ if [2]
+ ac
+ /* digit - push on the stack */
+ gt [2] [0] 47
+ if [2]
+ ca number
+ eq [2] [0] 43
+ if [2]
+ ca plus
+ eq [2] [0] 42
+ if [2]
+ ca multiply
+}
+
+set [2] 0
+ca process
+/* output the topmost element of the stack */
+add [2] [1] 9
+iout [[2]]
+ac
+```
diff --git a/editorials/189.md b/editorials/189.md
@@ -0,0 +1,107 @@
+Source: https://codeforces.com/blog/entry/4540
+
+### Problem [189A — Cut Ribbon](//www.codeforces.com/problemset/problem/189/A)
+
+The problem is to maximize *x+y+z* subject to *ax+by+cz=n*. Constraints are low, so simply iterate over two variables (say *x* and *y*) and find the third variable (if any) from the second equation. Find the maximum over all feasible solutions.
+
+Other approaches: Use dynamic programming with each state being the remainder of ribbon. Select the next piece to be *a*, *b* or *c*.
+
+### Problem [189B — Counting Rhombi](//www.codeforces.com/problemset/problem/189/B)
+
+Observe that lots of rhombi have the same shape, but are in different locations.
+
+What uniquely determines the shape of a rhombus? Its width and its height.
+
+Is it possible to build a rhombus with every width and every height such that the vertices of the rhombus are in integer points? No, it is possible only if the width and the height are both even.
+
+How many places we can put a rhombus of width *w0* and height *h0* in a rectangle of width *w* and height *h*? *(w * w0 + 1)(h * h0 + 1)*
+
+So, iterator over all even widths and heights and for each of them add the number of possible locations to the final result.
+
+### Problem [187A — Permutations](//www.codeforces.com/problemset/problem/187/A)
+
+It is easy to see that if we replace each number in the first permutation with position of that number in the second permutation, the problem reduces to sorting the first permutation.
+
+Each time we take a number from the end of array, we can postpone its insertion until we know the most suitable position for insertion. Note that it is not good to insert a number and take it again, as we could make a better decision first time we took the number.
+
+So, as long as the remainder of the array is not in increasing order, we should take more numbers from the end. But as soon as you have an increasing subsequence, you can insert the numbers you have taken to make the array sorted.
+
+Therefore to solve the problem, we find the largest *i* such the numbers from *1* to *i* are in increasing order. The answer would be *n-i*.
+
+### Problem [187B — AlgoRace](//www.codeforces.com/problemset/problem/187/B)
+
+First we solve the problem when the number of allowed car changes is zero (_k=0_). Let *W(i,j,l)* be the length of shortest path from *i* to *j* with car *l*. We use Floyd-Warshal on graph of each car to find this value. Then answer for the case that we can use only one car for each pair of cities *i* and *j* is:
+
+*ans(0,i,j) = min W(i,j,l)* for (_1≤l≤m_)
+
+This part has time complexity *O(m*n^3)*.
+
+For larger values of maximum number of changes (_k_), we use the following equation:
+
+*ans(k,i,j) = min (ans(k-1,i,l)+ans(0,l,j))* for (_1≤l≤k_)
+
+which can be computed in *O(k*n^3)* using dynamic programming.
+
+But how large can be *k* in worst case? We know that shortest paths are simple paths (i.e. they have no repeated vertices). Because otherwise we could eliminate the path we go between two appearances of one vertex and have a smaller result. This and the fact that we change the car at most once in each vertex, guarantees in any optimal solution we will not need more that *n* car changes. Thus the order of the solution would be *O(m*n^3+n^4)*.
+
+### Problem [187C — Weak Memory](//www.codeforces.com/problemset/problem/187/C)
+
+There were many different correct approaches to this problem during the contest. But I will explain author’s solution.
+
+First we can use binary search over the value of *q*. Now for a fixed *q* we want to check *s-t* connectivity.
+
+Let *K* be the set of all intersections with volunteers union s and t. One can use BFS from each *k∈K*, one by one. Then build a graph *G’* with vertices *K*. For each two vertices *k1,k2∈K* add an edge between them, if their shortest distance is less than or equal to *q*. Finally use any path finding algorithm to check the connectivity. Unfortunately this solution has time (and space) complexity of *O(|K|*m)* which is not good enough.
+
+We can optimize the above solution by initiating BFS from all *k∈K* at once. In other words during the initialization step in BFS algorithm, we push all these vertices in the queue with distance *0*. Each element in the queue also maintains its source (i.e. the source it is originating from). In BFS each time we have have a vertex *u* with source *su* and we want to set the minimum distance to a vertex *v* that is already set from a different path with source *sv*, we connect *su* and *sv* in *G’* if *d(u)+d(v)+1<= q*, where *d(x)* denotes length of the shortest path from a vertex in *K* to *x*. As we are only dealing with connectivity, this approach is correct. (Proof of correctness is left as an exercise)
+
+BFS takes *O(m)* time and we add at most *O(m)* edges to *G’*, so the overall complexity is *O(m)* for a fixed *q*. As we used binary search to find the smallest *q*, we can solve the problem in *O(m*logn)*.
+
+### Problem [187D — BRT Contract](//www.codeforces.com/problemset/problem/187/D)
+
+We define *ti* as follows: assume a bus starts moving from *i*-th intersection exactly at the time when the light changes to green. The time it takes for the bus to get the final station is *ti*. We call the times when a green interval begins *t0* (so every *g+r* seconds *t0* occurs once)
+
+If a bus gets to *i*-th intersection during the red phase, it should wait and then start moving at *t0*. So considering the fact that all lights are synchronized (and length of segments are fixed) if we have *ti* for *i*-th intersection, we can compute the time for the bus to get final station.
+
+Clearly *tn* is the length of the last segments. For computing *ti* we should find the smallest *j* such that if a bus starts at *t0* from *i*-th intersection, it gets to *j*-th intersection during the red phase. So we have:
+
+*ti=tj+d(i,j)+w*
+
+where *d(i,j)* is the distance between *i*-th and *j*-th intersections and *w* is the time that the bus should wait behind the red light at *j*-th intersection. The later value can be computed easily.
+
+The only problem that remains is to find *j* for *i*-th intersection. So we start iterating over *i* for *(n-1)*-th intersection backwards and we compute *ti* for all intersections. Assume *p=g+r* and *ta=d(i,j)%p*. Now if the bus starts from *i*-th intersection at time *t0* and we have *ta>=g*, in this case we are in red phase at *j*-th intersection. Actually *ta* should be in interval [_g, g+r_).
+
+Here we can use segment trees. That is for all intersections from *i+1* to *n*, we store some values in the tree that helps us find the smallest *j*. But we should note the value of *ta* depends on *d(i,j)* which changes as *i* changes. Thus we cannot use *ta* in the tree. Instead, we define *si* the be the distance of *i*-th intersection to the destination. So we have *d(i,j)=si-sj* and we use the value of *sj* with storing *–sj%p* in the segment tree as the key and the value would be *j* itself. In other words for each intersection we store the key-value pair *(-sj%p, j)* in the tree. According to what we said so far, to be in the red phase at *j*-th intersection we should have:
+
+*ta=(d(i,j)%p)=((si-sj)%p)∈[g,g+r) => -sj%p ∈ [(g-si)%p, (g+r-si)%p)*
+
+As we stored *–sj%p* in the tree, we can retrieve the smallest *j* in the above interval with a query in the segment tree.
+
+This way we can compute *ti* for all intersections. Answering to each query in the problem can be solve in exactly the same way. So the overall complexity would be *O((n+q)logn)*.
+
+### Problem [187E — Heaven Tour](//www.codeforces.com/problemset/problem/187/E)
+
+**Step 1**. Solve the problem if the starting man is the leftmost man and the finishing man is the rightmost man.
+
+Obviously every segment (the distance between two consecutive men) should be covered at least once. We also argue that at least *l* (the number of left tickets) segments should be covered at least three times.
+
+*Proof*: Each time you use a left ticket to go to man *i* with *1<i<n-1*, the segment between *i*-th and (_i+1_)-th men is covered at least three times:
+
+1. Once for you should go after *i* be in a position to come back.
+2. Once for you use a left ticked to come back to *i*
+3. And once again you should go after *i*, because you want to finish at man number *n*
+
+Note that in the first and the last segments are always covered once, no matter what we do. But except for these two segments, every other segment can be chosen to be among the segments that are covered three times, and every combination that we choose *l* segments is feasible. (Proof it as practice) So we choose the smallest *l* segments and the problem can be solved with a simple sort in *O(n*logn)*.
+
+**Step 2**. Solve the problem if the starting man is the leftmost man, but the finishing man can be anywhere.
+
+To solve this problem we first fix the finishing man. With reasoning similar to that of step 1, we conclude that at least *l* segments should be covered with at least two times if they are after the finishing man or three times if they are before him. But obviously every segment after the finishing man is covered at least two times. So it is always good to waste as many left tickets as possible after the finishing man to prevent them from breaching the left side of finishing man and becoming multiple three.
+
+So the algorithm would be: iterate over *i*, the number of finishing man, and maintain the *l-(n-i)* smallest segments to the right of finishing man as you progress. This can be implemented in *O(n*logn)*.
+
+**Step 3**. Solve the problem if the starting man is fixed, but the finishing man can be anywhere.
+
+Assume that the starting man is not the first man or the last man, otherwise we could use algorithm of step 2 to solve the problem. Without loss of generality assume that you finish your tour to the right side of finishing man. Therefore every segment to the left of starting man is covered at least two times and actually it is always possible to arrange visits such that every segment to right is covered exactly two times. So just like what we said in step 2, it is good to waste as many left tickets as possible in this area.
+
+So the algorithm would be, choose to finish left or right first, then greedily waste as many bad moves (by bad moves I mean the moves that if breach to the other side will be more costly) as possible there and follow the algorithm in step 2 to solve the whole problem.
+
+There are some special cases such as when the tour cannot be finished at all, that we left to readers find a way how to handle them.
diff --git a/editorials/19.md b/editorials/19.md
@@ -0,0 +1,91 @@
+Source: https://codeforces.com/blog/entry/559
+
+I find that no one write a solution about this contest..So I write one..
+
+A. World Football Cup
+
+I think is' just a problem about writing code
+
+quickly and correctly.Just follow the statement.
+
+if you use c++ STL will make you life easier
+
+B. Checkout Assistant
+
+First,for every i increase ti by 1..then you will
+
+ see that statement require sum of t of the items
+
+ bigger or equal to n..and their sum of c should
+
+be minimal..so it's just a 0-1 knapsack problem.
+
+C. Deletion of Repeats
+
+First let's generate all repeats.In a repeat,the
+ first number and the middle number must be the
+ same, so we just look at all pair of postion which
+ have same number..Thank to the statement..There
+ are at most O(10N) such pair..And use suffix array
+ to check if each pair can build a repeat...Then
+ just sort all the interval and go through then to
+ get the answer...
+[http://en.wikipedia.org/wiki/Suffix_array](https://en.wikipedia.org/wiki/Suffix_array)
+maybe you think suffix array is hard to code..you
+can use hash and binary search to do the same..
+my code here <http://www.ideone.com/N5zPS>
+
+D. Points
+ First of all,do the discretization.Then the biggest
+ value of x is n,so we can build a Segment Tree to
+ Ask the question "what is the first place from
+ postion x and its value is bigger than y"..if we
+ find such postion we just find the smallest Y-value
+ bigger than y in such postion--it can be done using
+ set's operation upper_bound...
+[http://en.wikipedia.org/wiki/Segment_tree](https://en.wikipedia.org/wiki/Segment_tree)
+ so the algorithm is clear..For every possible value
+ of x use a set to store all y value in it..And every
+ time the action is "find" or "remove" just change
+ this set and update the Segment Tree..otherwise use
+ Segment Tree to find the answer..
+
+my code here <http://www.ideone.com/4iNol>
+
+E. Fairy
+ It's a interesting problem.If you for every edge,
+ try to remove it and check if it is a bipartite
+ graph..I think it will get TLE..so let's analysis
+ the property of bipartite graph..
+[http://en.wikipedia.org/wiki/Bipartite_graph](https://en.wikipedia.org/wiki/Bipartite_graph)
+After reading it...we know..
+ It should never contain a cycle of odd length...
+ and it can be 2-colored..
+ so first build a spanning forest for the graph..
+ and do the 2-color on it(Tree can be 2-colored).
+ for convenience.
+ Let TreeEdge={all edge in forest}
+ NotTreeEdge={All edge}/TreeEdge
+ ErrorEdge={all edge that two endpoint have the same color..}
+ NotErorEdge=NotTreeEdge/ErroEdge..
+ First,consider a edge form NotTreeEdge,remove it
+ can't change any node's color..so..
+
+if |ErrorEdge|=0 of course we can remove all NotTreeEdge
+
+if =1 we just can remove the ErrorEdge
+
+if >1 we can't remove any from NotTreeEdge
+ Now,Let consider a Edge e from TreeEdge..
+ Let Path(Edge e)=the path in forest between e's two endpoints..
+ if there is a Edge e' from ErrorEdge that Path(e')
+ didn't go through e..it will destroy the bipartite
+ graph..
+ if there is a Edge e' from ErrorEdge that Path(e') go through e and there is a Edge e'' from NotErrorEdge that Path(e'') go through e..it will also destroy the bipartite graph..
+ so now we need to know for every edge,how many such path go through it..it require a data structure...
+ one way is to use heavy-light decomposition then we can update every path in O(LogN^2)...
+ another way is to use Link-Cut Tree..It can do the same in O(LogN)....
+if you didn't see Link-Cut tree before,you can read this
+
+[http://www.cs.cmu.edu/~sleator/papers/dynamic-trees.pdf](https://en.wikipedia.org/wiki/Link/cut_tree)
+or my code..use heavy-light decomposition <http://www.ideone.com/dPS5N>
diff --git a/editorials/190.md b/editorials/190.md
@@ -0,0 +1,41 @@
+Source: https://codeforces.com/blog/entry/4556
+
+#### *A* — [Vasya and the Bus](//codeforces.com/contest/190/problem/A)
+
+Firstly, if *n* = 0, then children can't be in the bus, so if *m* = 0 then the answer is (0, 0), otherwise the answer is "*Impossible*". Now *n* > 0. If *m* = = 0, than it is only one possible variant of passage — the answer is (*n*, *n*). Otherwise, more grown-up take some children, less the sum that people pay. So, if only one adult takes all children, than we get maximal sum — *n* + *m* - 1. Maximum *min*(*n*, *m*) adults can take the children with them, so the minimal answer is *n* + *m* - *min*(*n*, *m*) = *max*(*n*, *m*).
+
+#### *B* — [Surrounded](//codeforces.com/contest/190/problem/B)
+
+Let's find the minimum distance between two circles *L*. Then the answer to our problem is *L* / 2.
+Now *d* is the distance between the centers of the circles, *R*, *r* — their radiuses. There are 3 possible cases:
+- Circles don't intersect. Then *L* = *d* - *R* - *r*. Firstly, it's reachable: let's consider the segment, connecting the centers of the circles, and take its part, which is out of both circles — its length is exactly *d* - *R* - *r*.
+     
+
+     Let's prove that lesser distance is impossible. If the segment connecting two points of distinct circles have length l, than *R* + *l* + *r* > = *d*, so *l* > = *d* - *R* - *r*.
+     
+- If one circle is into another, than analogically the answer is *R* - *d* - *r*, where *R* is the radius of the bigger circle.
+- If the circles intersect, then the answer is 0.
+
+#### *C* — [STL](//codeforces.com/contest/190/problem/C)
+
+In this problem we have an array of strings (*s*1, *s*2, ...*s**n*), where *s**i* = *pair* or *int*.
+Let's consider *bal**i* = the difference between number of "pair" and "int" int the subarray (*s*1, *s*2, ...*s**i*).
+Than we can prove that the type can be reestablished from the array *s* < = > *bal**i* > = 0 for 1 < = *i* < *n* and *bal**n* = - 1. This can be proved using mathematical induction, the parameter is the number of "*int*"-s in the array.
+And how to find the solution, if we know that is exists? Consider the function *gettype*(*inti*), which builds the type beginning in the position *i* and returns the index, next to the position where it finished building of type. How it works? If *s**i* = "*int*", then the function prints "*int*" and returns *i* + 1. Else it prints "*pair* < ", *gettype*(*i* + 1) is launched, let it returns *j*. Then we print ", " and launch *gettype*(*j*) (it returns *k*), then we print " > " and return *k*.
+We can not to do check if the type can be reestablished from the array in the beginning: launch *gettype*() and print "Error occurred" if there became some contradiction during the building of type.
+
+#### *D* — [Non-secret Cypher](//codeforces.com/contest/190/problem/D)
+
+First solution: Let's use the method of two pointers. For every number we will know how many times it occurs in the current segment [*l*, *r*]. For fixed *l* we increase *r* until *a*[*r*] occurs in the current segment less than *k* times. If *a*[*r*] occurs int the segment [*l*, *r*] *k* times, we add to the answer all segments [*l*, *t*] for all *t* > = *r* and increase *l* (and do not forget to decrease the number of *a*[*l*] in the current segment).
+To keep the number of every value in the segment we can use *map* or compression of the coordinates. Also it's important not to forget that the maximal answer is , which doesn't fit in *int*.
+Second solution: firstly, let's do the compression of the coordinates. For every value *X* we write the list of the positions *i* such that *a*[*i*] = *X*. Now using that we fill the array *b*: *b*[*i*] is the minimum index that segment [*i*, *b*[*i*]] contains *k* numbers equal to *a*[*i*] (obviosly, *a*[*b*[*i*]] = *a*[*i*]), if this index doesn't exist, then *b*[*i*] = *n* + 1.
+Let's find for every index *i* a minimal index *j* such that segment [*i*, *j*] contsins *k* equal numbers (if such *j* doesn't exist, we say that *j* = *n* + 1) — then we add to the answer *n* + 1 - *j*. This *j* is equal to . All that minimums can be found in a single pass through *a* from its end. Then we can sum the answers for all indexes 1 < = *i* < = *n*.
+The complexity of these solutions is *O*(*nlogn*).
+
+#### *E* — [Counter Attack](//codeforces.com/contest/190/problem/E)
+
+This problem has several different solutions. Anyway, we should consider towns as the vertices of the graph, roads as its edges. Now we are to find the connected components of the complementary graph (CG) of the given graph. Let's take the vertex *A* with the minimal degree *c*: . We call the set of the vertices who are connected with *A* — *B*, that are not connected — *D* . All vertices which don't connect with *A* will be in the same connected component of the CG. Let's build the complemented graph to the subgraph including *A* and set *B* — there are  vertices and  =  = *O*(*m*) edges.
+Let's build DSU for the vertices of given graph and merge components which we have found using the new-built graph. All that we should do after it is to consider vertices from *B*: now we look to the vertex *v*. We put *v* in the same component as *A* if *v* has edges not to all vertices of *D* (we do it using DSU too). The complexity of this solution is *O*(*m*) or *O*(*mlogn*).
+
+Another solution: we keep *set* *a*, which contains vertices, which haven't been visited yet. Let's run series of bfs to find the components of CG. If we are working now with the vertex *v*, pass through *a*. Consider *u* is the element of *a*. If edge (*u*, *v*) isn't in the given graph, than *u* is in the same component of CG as *v*, so, we can erase it from *a* and add to queue. Otherwise, we do nothing.
+What is the complexity of this solution? To understand that, we must know how many times whe consider fixed vertex *u* in the *set* *a*. *u* remains int *a* when we run to them from vertex *v* < = > edge (*u*, *v*) is in the given graph. So, every vertex *u* remains in *a* no more than its degree. So, the complexity of this algorithm is *O*(*mlogn*) (log n because of binsearch — we need use it to know, is (*u*, *v*) in the graph). If we use *HashMap*, we'll get *O*(*m*).
diff --git a/editorials/191.md b/editorials/191.md
@@ -0,0 +1,69 @@
+Source: https://codeforces.com/blog/entry/4634
+
+Задача [192A - Funky Numbers](/contest/192/problem/A "Codeforces Round 121 (Div. 2)")
+
+Кратко о решении: перебор
+
+Подробно о решении: Нетрудно заметить, что это числа положительны, следовательно каждое из слагаемых меньше *N*. То есть всего различных возможных слагаемых порядка . Это значит то, что мы взять и одно из слагаемых перебрать. Тогда нам нужно научиться проверять, является ли какое-то число треугольным. Заметим, что если мы заранее выпишем все слагаемые в порядке увеличения то мы сможем с помощью бинарного поиска в массиве искать наше число. Это даем там решение за 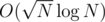. Если перебирать первое слагаемое в порядке увеличения, то можно использовать два указателя, что дает нам решение за .
+
+Задача [192B - Walking in the Rain](/contest/192/problem/B "Codeforces Round 121 (Div. 2)")
+
+Кратко о решении: динамика.
+
+Подробно о решении: динамика *d*[*i*] — количество дней, в течении которых плитка номер *i* доступна. Пересчет: *d*[*i*] = *min*(*a*[*i*], *max*(*d*[*i* - 1], *d*[*i* - 2]))
+
+Асимптотика решения: *O*(*N*)
+
+Задача [191A - Dynasty Puzzles](/contest/191/problem/A "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: динамика
+
+Подробно о решении: динамика d[i][j], *i* — первый символ в имени династии, *j* — последний текущий символ. *d*[*i*][*j*] — максимальная текущая длина. Переход: для слова с первой буквой *l*, последней буквой *r* и длиной *s* для всех возможных первых букв *i* состояние *d*[*i*][*r*] может быть улучшено значением *d*[*i*][*l*] + *s*.
+
+Ответом будет являться максимальное значение *d*[*i*][*i*] для всех *i*.
+
+Асимптотика решения: *O*(*N* * *alpha*), где *alpha* — это размер алфавита.
+
+Задача [191B - Demonstration](/contest/191/problem/B "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: конструктив
+
+Подробно о решении: заметим, что на последнюю площадь никогда не выгодно подавать заявку (денег мэрии не потратим, ничего не изменится, мы просто потеряем ход). Переберем площадь, на которой мы хотим провести митинг. У нас есть *k* - 1 ход на то, чтобы потратить деньги мэрии (один ход нам нужен на подачу заявки на искомую площадь). Тратить деньги выгоднее всего на самых дорогих площадях, за исключением последней. Осталось научиться быстро выбирать *k* - 1 максимум из всего массива, за исключением данного элемента. Для этого сначала отсортируем массив и получим *k* максимумов (последнюю площадь мы не должны рассматривать). Проверяем, лежит ли наше текущее значение в *k* - 1 максимальных (бинпоиск и не только). Если лежит, то искомые *k* - 1 максимумов — это максимальные *k* элементов без нашего. Если не лежит, то это просто максимальные *k* элементов.
+
+Теперь когда мы понимаем, сколько денег мэрии мы можем потратить, то тратим их и смотрим, остаются ли еще у мэрии деньги на проведение события на нашей текущей площади
+
+Асимптотика решения: 
+
+Задача [191C - Fools and Roads](/contest/191/problem/C "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: lca
+
+Подробно о решении: Разобьем каждый путь на два, строго идущих вверх к наименьшему общему предку. Теперь у нас есть только "вертикальные пути". Для каждой вершины насчитаем такую величину: количество вертикальных путей, начинающихся в ней минус количество вертикальных путей в ней заканчивающихся. Если мы насчитали эту величину, то ответ для ребра — это сумма значений в его поддереве. Насчитать такую величину довольно просто: берем для каждой пары дураков считаем lca этой пары. В города дураков прибавляем единичку, в lca значение уменьшаем на два.
+
+Асимптотика решения: 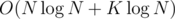
+
+Задача [191D - Metro Scheme](/contest/191/problem/D "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: снова динамика
+
+Подробно о решении: динамика *d*[*v*][*rest*][*cycle*] — количество линий, которое требуется для того, чтобы в поддереве вершины *v* все покрасить, в *v* остаются *rest* незамкнутым, *cycle* — правда ли, что нам надо обрабатывать цикл, в котором мы находимся.
+
+Если мы находимся не в вершине цикла, то обрабатываем всех детей, говоря что мы хотим, чтобы в них было по одному незакрытому пути. Пусть у нас есть *s* сыновей, нам надо взять и замкнуть все лишние линии, а недостающие нагенерить. То есть ответ это 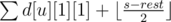, если *s* > *rest*, и  в противном случае.
+
+Если мы находимся в вершине цикла, то либо мы покрываем этот цикл кольцом и это стоит нам 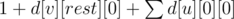, где *u* — это вершина на цикле. отличная от *v*. Другой вариант — покрыть все участки кольца радиальными линиями. Утверждение: это всегда можно оптимально сделать ровно двумя радиальными. Пусть это не так. Тогда рассмотрим некоторую вершину, в которой радиальные линии <<подвешиваются>> к кольцу. От неё по кольцу в разные стороны уходят два тоннеля, принадлежащие этим линиям. Так как различных линий на кольце сейчас не менее трех, то мы можем перенаправить радиальные линии следующим образом: соединить куски вне кольца друг с другом, а кольцо замкнуть. На кольце останется не менее двух кусков, следовательно все линии останутся валидными, а их число не изменится.
+
+Теперь надо выбрать две станции, из поддерева которых будут выходить радиальные ветки, покрывшее кольцо. Стоимость такой станции это *d*[*u*][2][0], а обычной — *d*[*u*][0][0] (*d*[*v*][*rest*][0] в случае той вершины, которую мы сейчас обрабатываем) . Соответственно, нам надо выбрать две станции с максимальным значением *d*[*u*][2][0] - *d*[*u*][0][0].
+
+Асимптотика решения: *O*(*N*)
+
+Задача [191E - Thwarting Demonstrations](/contest/191/problem/E "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: бинарный поиск по ответу
+
+Подробно о решении: Сделаем бинарный поиск по ответу. Нам надо посчитать количество отрезков, на которых сумма больше нашего некоторого значения. Как мы это будем делать: будем обрабатывать все отрезки в порядке увеличения правых концов. Отрезки с одинаковыми правыми концами будем обрабатывать пачками. Более подробно: мы будем поддерживать некоторую структуру данных в которой будут храниться суммы всех отрезков c фиксированным правым концом.
+
+Для того, чтобы быстро пересчитывать, нам нужно всего добавить в множество некоторый элемент ( 0, если точнее) и добавить ко всем элементам множества некоторое значение (*a*[*i*], если быть точнее). Еще нам нужно уметь отвечать на запрос <<количество элементов, больших данного на отрезке>>. Все это умеет быстро реализовывать, например, декартово дерево. Но нам придется дополнительно хранить некоторую величину *X*, означающую <<надо прибавить к элементу из декартова дерева *X*, чтобы получить реальное значение>>. Тогда при добавлении элемента *a* в нашу структуру надо будет положить в декартово дерево величину *a* - *X*, а прибавление некоторой величины ко всему множеству реализуется простым изменением *X*.
+
+То есть у нас есть структура данных, которая умеет все эти операции выполнять за . То есть одна итерация внешнего бинпоиска работает за , следовательно весь алгоритм работает за 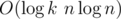
+
+Асимптотика решения: 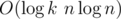
diff --git a/editorials/192.md b/editorials/192.md
@@ -0,0 +1,69 @@
+Source: https://codeforces.com/blog/entry/4634
+
+Задача [192A - Funky Numbers](/contest/192/problem/A "Codeforces Round 121 (Div. 2)")
+
+Кратко о решении: перебор
+
+Подробно о решении: Нетрудно заметить, что это числа положительны, следовательно каждое из слагаемых меньше *N*. То есть всего различных возможных слагаемых порядка . Это значит то, что мы взять и одно из слагаемых перебрать. Тогда нам нужно научиться проверять, является ли какое-то число треугольным. Заметим, что если мы заранее выпишем все слагаемые в порядке увеличения то мы сможем с помощью бинарного поиска в массиве искать наше число. Это даем там решение за 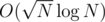. Если перебирать первое слагаемое в порядке увеличения, то можно использовать два указателя, что дает нам решение за .
+
+Задача [192B - Walking in the Rain](/contest/192/problem/B "Codeforces Round 121 (Div. 2)")
+
+Кратко о решении: динамика.
+
+Подробно о решении: динамика *d*[*i*] — количество дней, в течении которых плитка номер *i* доступна. Пересчет: *d*[*i*] = *min*(*a*[*i*], *max*(*d*[*i* - 1], *d*[*i* - 2]))
+
+Асимптотика решения: *O*(*N*)
+
+Задача [191A - Dynasty Puzzles](/contest/191/problem/A "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: динамика
+
+Подробно о решении: динамика d[i][j], *i* — первый символ в имени династии, *j* — последний текущий символ. *d*[*i*][*j*] — максимальная текущая длина. Переход: для слова с первой буквой *l*, последней буквой *r* и длиной *s* для всех возможных первых букв *i* состояние *d*[*i*][*r*] может быть улучшено значением *d*[*i*][*l*] + *s*.
+
+Ответом будет являться максимальное значение *d*[*i*][*i*] для всех *i*.
+
+Асимптотика решения: *O*(*N* * *alpha*), где *alpha* — это размер алфавита.
+
+Задача [191B - Demonstration](/contest/191/problem/B "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: конструктив
+
+Подробно о решении: заметим, что на последнюю площадь никогда не выгодно подавать заявку (денег мэрии не потратим, ничего не изменится, мы просто потеряем ход). Переберем площадь, на которой мы хотим провести митинг. У нас есть *k* - 1 ход на то, чтобы потратить деньги мэрии (один ход нам нужен на подачу заявки на искомую площадь). Тратить деньги выгоднее всего на самых дорогих площадях, за исключением последней. Осталось научиться быстро выбирать *k* - 1 максимум из всего массива, за исключением данного элемента. Для этого сначала отсортируем массив и получим *k* максимумов (последнюю площадь мы не должны рассматривать). Проверяем, лежит ли наше текущее значение в *k* - 1 максимальных (бинпоиск и не только). Если лежит, то искомые *k* - 1 максимумов — это максимальные *k* элементов без нашего. Если не лежит, то это просто максимальные *k* элементов.
+
+Теперь когда мы понимаем, сколько денег мэрии мы можем потратить, то тратим их и смотрим, остаются ли еще у мэрии деньги на проведение события на нашей текущей площади
+
+Асимптотика решения: 
+
+Задача [191C - Fools and Roads](/contest/191/problem/C "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: lca
+
+Подробно о решении: Разобьем каждый путь на два, строго идущих вверх к наименьшему общему предку. Теперь у нас есть только "вертикальные пути". Для каждой вершины насчитаем такую величину: количество вертикальных путей, начинающихся в ней минус количество вертикальных путей в ней заканчивающихся. Если мы насчитали эту величину, то ответ для ребра — это сумма значений в его поддереве. Насчитать такую величину довольно просто: берем для каждой пары дураков считаем lca этой пары. В города дураков прибавляем единичку, в lca значение уменьшаем на два.
+
+Асимптотика решения: 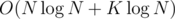
+
+Задача [191D - Metro Scheme](/contest/191/problem/D "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: снова динамика
+
+Подробно о решении: динамика *d*[*v*][*rest*][*cycle*] — количество линий, которое требуется для того, чтобы в поддереве вершины *v* все покрасить, в *v* остаются *rest* незамкнутым, *cycle* — правда ли, что нам надо обрабатывать цикл, в котором мы находимся.
+
+Если мы находимся не в вершине цикла, то обрабатываем всех детей, говоря что мы хотим, чтобы в них было по одному незакрытому пути. Пусть у нас есть *s* сыновей, нам надо взять и замкнуть все лишние линии, а недостающие нагенерить. То есть ответ это 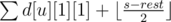, если *s* > *rest*, и  в противном случае.
+
+Если мы находимся в вершине цикла, то либо мы покрываем этот цикл кольцом и это стоит нам 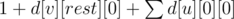, где *u* — это вершина на цикле. отличная от *v*. Другой вариант — покрыть все участки кольца радиальными линиями. Утверждение: это всегда можно оптимально сделать ровно двумя радиальными. Пусть это не так. Тогда рассмотрим некоторую вершину, в которой радиальные линии <<подвешиваются>> к кольцу. От неё по кольцу в разные стороны уходят два тоннеля, принадлежащие этим линиям. Так как различных линий на кольце сейчас не менее трех, то мы можем перенаправить радиальные линии следующим образом: соединить куски вне кольца друг с другом, а кольцо замкнуть. На кольце останется не менее двух кусков, следовательно все линии останутся валидными, а их число не изменится.
+
+Теперь надо выбрать две станции, из поддерева которых будут выходить радиальные ветки, покрывшее кольцо. Стоимость такой станции это *d*[*u*][2][0], а обычной — *d*[*u*][0][0] (*d*[*v*][*rest*][0] в случае той вершины, которую мы сейчас обрабатываем) . Соответственно, нам надо выбрать две станции с максимальным значением *d*[*u*][2][0] - *d*[*u*][0][0].
+
+Асимптотика решения: *O*(*N*)
+
+Задача [191E - Thwarting Demonstrations](/contest/191/problem/E "Codeforces Round 121 (Div. 1)")
+
+Кратко о решении: бинарный поиск по ответу
+
+Подробно о решении: Сделаем бинарный поиск по ответу. Нам надо посчитать количество отрезков, на которых сумма больше нашего некоторого значения. Как мы это будем делать: будем обрабатывать все отрезки в порядке увеличения правых концов. Отрезки с одинаковыми правыми концами будем обрабатывать пачками. Более подробно: мы будем поддерживать некоторую структуру данных в которой будут храниться суммы всех отрезков c фиксированным правым концом.
+
+Для того, чтобы быстро пересчитывать, нам нужно всего добавить в множество некоторый элемент ( 0, если точнее) и добавить ко всем элементам множества некоторое значение (*a*[*i*], если быть точнее). Еще нам нужно уметь отвечать на запрос <<количество элементов, больших данного на отрезке>>. Все это умеет быстро реализовывать, например, декартово дерево. Но нам придется дополнительно хранить некоторую величину *X*, означающую <<надо прибавить к элементу из декартова дерева *X*, чтобы получить реальное значение>>. Тогда при добавлении элемента *a* в нашу структуру надо будет положить в декартово дерево величину *a* - *X*, а прибавление некоторой величины ко всему множеству реализуется простым изменением *X*.
+
+То есть у нас есть структура данных, которая умеет все эти операции выполнять за . То есть одна итерация внешнего бинпоиска работает за , следовательно весь алгоритм работает за 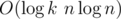
+
+Асимптотика решения: 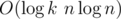
diff --git a/editorials/193.md b/editorials/193.md
@@ -0,0 +1,129 @@
+Source: https://codeforces.com/blog/entry/4673
+
+Please, report me about every grammar mistake, you see. Thank you.
+
+**Problem <>**
+
+Let's notice that 2*n* ≤ *k* ≤ 5*n*. If *k* < 3*n* author has to get 2 on some exams. There are 3*n* - *k* such exams and that's the answer). If 3*n* ≤ *k* author will pass all exams (answer is 0).
+
+**Problem <>**
+
+Let the pencil move by the line and put crosses through every (*n* + 1) point. Lets associate every point on the line with point on square perimeter. Namely, point *x* on the line will be associated with point on square perimeter that we will reach if we move pencil around square to *x* clockwise. Then lower left corner will be associated with all points 4*np* for every non-negative integer *p*. Crosses will be associated with points *k*(*n* + 1) for some non-negative *k*. Nearest point of overlap of two families of points will be in point LCM(*n* + 1, 4*n*). Then we will put 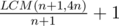 crosses.
+
+**Problem "Cutting Figure"**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: using the fact that the answer cannot be greater than 2, check answer 1.
+
+Let's proof that the answer is not greater than 2. Let area of the figure be greater than 3. Let's examine the leftmost of all topmost squares. There is no neighbors left or up to it. So, number of its neighbors is not more than 2. Thus, if we delete its neighbors, we shall disconnect the figure. If the area is equal to 3, we always can disconnect the figure by deletion of one square. It can be proofed by considering all two primary cases. If the area is not greater than 2, there is no way to disconnect the figure.
+
+The algorithm: Check answer 1. We can simply brute-force the square to delete, and for each instance start dfs from any existing square. If during the dfs we visited not all of the remaining squares, we have found the square to delete. The answer is 1 if our bruteforce succeeded, and 2 otherwise.
+
+That was necessary to consider the case when there is no answer.
+
+The complexity of the described algorithm is *O*(*n*4). That was possible to search for articulation points and solve the problem in complexity *O*(*n*2), but in my opinion that required more time and effort.
+
+**Problem <>**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: bruteforce in complexity *O*(*F**u**n*) where *F**u* if fibonacci number at position *u*.
+
+This problem had complex statements. We have an array *a*, and we can transform it in two ways. The goal was to maximize the sum of all its elements with given multipliers after exactly *u* operations.
+
+A simple bruteforce of all combinations of operations with subsequent modeling leads to complexity *O*(2*u* * *nu*), what is not fast enough. That was possible to optimize it by modeling parallel to recursive bruteforce. Now we have complexity *O*(2*u**n*). Actually, the correct solution is not too far from this algorithm.
+
+There is just one conjecture: every two successive xor operations change nothing, and we can move them to any place of the combination. Thus, it will be enough to bruteforce only combinations in which every pair of successive xor operations is at the end.
+
+It could be done using recoursive bruteforce. We must change in previous solution two things. First, we must n't put xor after xor. Besides that, we should update answer if number *u* - *l* is even, where *l* is current level of recoursion (all remaining operations in the end separates to pairs of xors).
+
+Let's calculate complexity of this algo. There are *F**i* sequences of length *i* without two consecutive xors. It's easy to proof, you can calculate some dp to see it. That's why, complexity of our algo is *O*(*F**u**n*).
+
+**Problem "Hamming distance"**
+
+Main idea: reduction to system of linear equations and solving it using Gauss algorithm.
+
+Let's notice that order of columns in answer doesn't matter. That's why there is only one important thing — quantity of every type of column. There is only 24 = 16 different columns.
+
+Let's represent Hamming distance between every pair of strings as sum of quantities of types of columns. It's possible because every column adds to every distance between pairs 0 or 1.
+
+Now we have system of 6 linear equations with 16 variables. It's not good, let's decrease number of variables. First, some columns adds same values to every Hamming distance. For example strings "abbb" and "baaa". For every column *q* we can replace all letters "a" by letters "b" and all letters "b" by letters "a" and reach column that adds same values to every distance. We reduced number of variables to 8. We also can notice that columns "aaaa" and "bbbb" is useless and reduce number of variables to 7.
+
+This system can be solved using Gauss algorithm. One variable steel be free. Let's fix it. It's value can't be more than maximum of *h*(*s**i*, *s**j*) because column adds positive value to one or more Hamming distance. For every fixed value we should check if all variables take non-negative integer value and choose the best answer.
+
+We can solve system of equations in integers because coefficients of equation is little.
+
+Complexity of this solution if *O*(*max*(*h*(*s**i*, *s**j*))). If we solve it in rational numbers complexity will change to 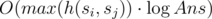.
+
+**Problem "Two segments"**
+
+Main idea: inverse the permutation and solve simplified problem (see below), consider function "quantity of segments of permutation that form the given segment of natural series".
+
+In order to solve this problem, we suggest solve another: <<we have a permutation *p**n*, we have to calculate the count of segments such that their elements form one or two segments of natural series>>.
+
+If we solve the inverse problem for some permutation *q**n* such that , we shall get the answer for the initial problem and initial permutation *p**i*.
+
+Straight-forward algo: let's bruteforce the segment of permutation and mark its elements in a boolean array. Check that in that array there is not more than two marked segments. This algo has complexity *O*(*n*3).
+
+Let's notice that during the changeover from [*l*, *r*] to [*l*, *r* + 1] the quantity of segments changes in some predictable way. Let *s*([*a*, *b*]) be quantity of segments that form segment [*a*, *b*] of permutation. There are three cases (see picture below):
+
+* If the new element *p**r* + 1 is between two marked elements (that is, both elements with values *p**r* + 1 - 1 and *p**r* + 1 + 1 belong to segment [*l*, *r*]), then *s*([*l*, *r* + 1]) = *s*([*l*, *r*]) - 1. The new element will <> the segments near it.
+* If the new element *p**r* + 1 has only one neighbor with value belonging to [*l*, *r*], then *s*([*l*, *r* + 1]) = *s*([*l*, *r*]). The new element will lengthen one of existing segments.
+* If there are no marked elements near *p**r* + 1 the new element forms a new segment, *s*([*l*, *r* + 1]) = *s*([*l*, *r*]) + 1.
+
+
+
+The new element is red, elements that are marked to this moment are black.
+
+Improved algo: Let's bruteforce position of the left border and for each instance move the right border from left to right. During each move we shall recount the actual quantity of segments forming the current segment of permutation (*s*([*l*, *r*])). Now we have a solution in complexity *O*(*n*2). It works fast enough even when *n* = 20000. Obviously, that is not enough to get AC.
+
+Move on full solution. It is based on previous. Now we can calc *s*([*l*, *r*]) using *s*([*l*, *r* - 1]). Now we should look at way of changing *s*([*l* - 1, *r*]) as compared with *s*([*l*, *r*]). Let's move left border of segment from the right to left and support some data structure with *s*([*l*, *i*]) for every *i* satisfying *l* < *i* ≤ *n* and current *l*. This structure should answer queries "count numbers 1 and 2 in structure", that is count segments [*l*, *i*] that generates one or two segments in the original permutaton.
+
+Let Δ*i* be *s*([*l* - 1, *i*]) - *s*([*l*, *i*]). Δ*l* will be equal to 1 because one element form one segment in permutation (notice that in final answer we must not consider 1-element segments, that's why we must subtract *n* from answer in the end of solution).
+
+Δ*i* determined by the number of neighbors of element *l* - 1 in the segment [*l* - 1, *i*]. Neighbors of *l* - 1 is elements *p**l* - 1 + 1 and *p**l* - 1 - 1 if they're exist.
+
+* If *l* - 1 hasn't neighbors in this segment, Δ*i* = 1, because *l* - 1 froms new 1-element segment.
+* If *l* - 1 has one neighbor in this segment Δ*i* = 0, because *l* - 1 join to existing segment of its neighbor.
+* If *l* - 1 has two neighbors in this segment Δ*i* = - 1, because *l* - 1 connect segments of its neighbors.
+
+Number of neighbors in segment [*l* - 1, *i*] non-decreasing with increasing *i*. That's why Δ*i* non-decreasing with increasing *i*. That means that there are only three segments of equivalence of Δ*i*. We are interested only in neighbors of *l* - 1 which positions are right than *l* - 1. Let *a* is position of first neighbor, *b* is position of second neighbor, without loss of generality *a* < *b*. Then 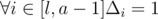, 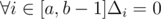, 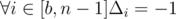. (elements of permutation are numbered from 0). If *a* and *b* aren't exist, for all  Δ*i* = 1. If only *b* isn't exist for 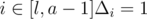, for 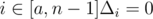.
+
+
+
+Look at example to clear your understanding. (Δ*i* is in top right corners, *l* = 3, *p**l* = 5)
+
+Using this facts we can code data structure support following operations:
+
+* Add +1 or -1 on segment
+* Calc number of 1 and 2 in the structure.
+
+Sum of answers of structure in every iteration (for every *l*) is answer to problem.
+
+Let's notice that all numbers in structure will be positive. That's why elements 1 and 2 will be minimal of pre-minimal in the structure. Using this fact we can code segment tree, supports these operations.
+
+Complexity of this solution is .
+
+We also can code sqrt-decomposition and obtain complexity .
+
+**Problem <>**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: baby-step-giant-step.
+
+In this problem we had some Fibonacci number modulo 1013 *f*, and we had to determine the position of its first occurence in Fibonacci sequence modulo 1013.
+
+* Let *a* and *b* be two different coprime modula — divisors of 1013.
+* Let *F* be the actual Fibonacci number such that 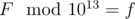. Then 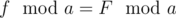 and 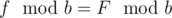.
+* Find all occurences of number  in Fibonacci sequence modulo *a* period.
+* Find all occurences of number  in Fibonacci sequence modulo *b* period.
+* Let's fix a pair of such occurences. Let the occurence modulo *a* be in position *i*, and the occurence modulo *b* be in position *j*.
+* Let *t*(*m*) be Fibonacci sequence modulo *m* period.
+* From the Chinese Remainder Theorem, it follows that *t*(*ab*) = *LCM*(*t*(*a*), *t*(*b*)) (remember that *a* and *b* are coprime).
+* Then from fixed occurences of *f* in periods of sequences modulo *a* and *b* we can recover the position of occurence of *f* in period of sequence modulo *ab*. It could be done by solving the following Diophantine equation: *i* + *t*(*a*) * *x* = *j* + *t*(*b*) * *y*. We can solve it using a simple bruteforce of one of the roots.
+* If the occurence in sequence modulo *ab* period ( we have just found it) is *u*, then every occurence *f* in Fibonacci sequence modulo 1013 period can be represented as *t*(*ab*) * *k* + *u*. Then let's bruteforce *k* and find all occurences in sequence modulo 1013 period. To determine Fibonacci number on position α + *t*(*ab*) from known Fibonacci number on position α, we need to multiply the vector (*F*α, *F*α + 1) and some matrix.
+* Let's choose *a* = 59 and *b* = 213. Note that there is no number that occur Fibonacci sequence modulo *a* or *b* period more than 8 times. That means that total count of pairs will never be greater than 64. For each occurence we'll bruteforce not more than 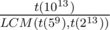 numbers. That was the author's solution.
+
+Also that was possible to use the fact that for any number the count of its occurences in period of sequence modulo 10*p* (for any natural *p*) is not big more efficiently. From occurences in sequence modulo 10*i* period we could get occurences in sequence modulo 10*i* + 1 period using the method we use to jump from modulus *ab* to modulus 1013.
diff --git a/editorials/194.md b/editorials/194.md
@@ -0,0 +1,129 @@
+Source: https://codeforces.com/blog/entry/4673
+
+Please, report me about every grammar mistake, you see. Thank you.
+
+**Problem <>**
+
+Let's notice that 2*n* ≤ *k* ≤ 5*n*. If *k* < 3*n* author has to get 2 on some exams. There are 3*n* - *k* such exams and that's the answer). If 3*n* ≤ *k* author will pass all exams (answer is 0).
+
+**Problem <>**
+
+Let the pencil move by the line and put crosses through every (*n* + 1) point. Lets associate every point on the line with point on square perimeter. Namely, point *x* on the line will be associated with point on square perimeter that we will reach if we move pencil around square to *x* clockwise. Then lower left corner will be associated with all points 4*np* for every non-negative integer *p*. Crosses will be associated with points *k*(*n* + 1) for some non-negative *k*. Nearest point of overlap of two families of points will be in point LCM(*n* + 1, 4*n*). Then we will put 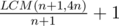 crosses.
+
+**Problem "Cutting Figure"**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: using the fact that the answer cannot be greater than 2, check answer 1.
+
+Let's proof that the answer is not greater than 2. Let area of the figure be greater than 3. Let's examine the leftmost of all topmost squares. There is no neighbors left or up to it. So, number of its neighbors is not more than 2. Thus, if we delete its neighbors, we shall disconnect the figure. If the area is equal to 3, we always can disconnect the figure by deletion of one square. It can be proofed by considering all two primary cases. If the area is not greater than 2, there is no way to disconnect the figure.
+
+The algorithm: Check answer 1. We can simply brute-force the square to delete, and for each instance start dfs from any existing square. If during the dfs we visited not all of the remaining squares, we have found the square to delete. The answer is 1 if our bruteforce succeeded, and 2 otherwise.
+
+That was necessary to consider the case when there is no answer.
+
+The complexity of the described algorithm is *O*(*n*4). That was possible to search for articulation points and solve the problem in complexity *O*(*n*2), but in my opinion that required more time and effort.
+
+**Problem <>**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: bruteforce in complexity *O*(*F**u**n*) where *F**u* if fibonacci number at position *u*.
+
+This problem had complex statements. We have an array *a*, and we can transform it in two ways. The goal was to maximize the sum of all its elements with given multipliers after exactly *u* operations.
+
+A simple bruteforce of all combinations of operations with subsequent modeling leads to complexity *O*(2*u* * *nu*), what is not fast enough. That was possible to optimize it by modeling parallel to recursive bruteforce. Now we have complexity *O*(2*u**n*). Actually, the correct solution is not too far from this algorithm.
+
+There is just one conjecture: every two successive xor operations change nothing, and we can move them to any place of the combination. Thus, it will be enough to bruteforce only combinations in which every pair of successive xor operations is at the end.
+
+It could be done using recoursive bruteforce. We must change in previous solution two things. First, we must n't put xor after xor. Besides that, we should update answer if number *u* - *l* is even, where *l* is current level of recoursion (all remaining operations in the end separates to pairs of xors).
+
+Let's calculate complexity of this algo. There are *F**i* sequences of length *i* without two consecutive xors. It's easy to proof, you can calculate some dp to see it. That's why, complexity of our algo is *O*(*F**u**n*).
+
+**Problem "Hamming distance"**
+
+Main idea: reduction to system of linear equations and solving it using Gauss algorithm.
+
+Let's notice that order of columns in answer doesn't matter. That's why there is only one important thing — quantity of every type of column. There is only 24 = 16 different columns.
+
+Let's represent Hamming distance between every pair of strings as sum of quantities of types of columns. It's possible because every column adds to every distance between pairs 0 or 1.
+
+Now we have system of 6 linear equations with 16 variables. It's not good, let's decrease number of variables. First, some columns adds same values to every Hamming distance. For example strings "abbb" and "baaa". For every column *q* we can replace all letters "a" by letters "b" and all letters "b" by letters "a" and reach column that adds same values to every distance. We reduced number of variables to 8. We also can notice that columns "aaaa" and "bbbb" is useless and reduce number of variables to 7.
+
+This system can be solved using Gauss algorithm. One variable steel be free. Let's fix it. It's value can't be more than maximum of *h*(*s**i*, *s**j*) because column adds positive value to one or more Hamming distance. For every fixed value we should check if all variables take non-negative integer value and choose the best answer.
+
+We can solve system of equations in integers because coefficients of equation is little.
+
+Complexity of this solution if *O*(*max*(*h*(*s**i*, *s**j*))). If we solve it in rational numbers complexity will change to 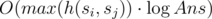.
+
+**Problem "Two segments"**
+
+Main idea: inverse the permutation and solve simplified problem (see below), consider function "quantity of segments of permutation that form the given segment of natural series".
+
+In order to solve this problem, we suggest solve another: <<we have a permutation *p**n*, we have to calculate the count of segments such that their elements form one or two segments of natural series>>.
+
+If we solve the inverse problem for some permutation *q**n* such that , we shall get the answer for the initial problem and initial permutation *p**i*.
+
+Straight-forward algo: let's bruteforce the segment of permutation and mark its elements in a boolean array. Check that in that array there is not more than two marked segments. This algo has complexity *O*(*n*3).
+
+Let's notice that during the changeover from [*l*, *r*] to [*l*, *r* + 1] the quantity of segments changes in some predictable way. Let *s*([*a*, *b*]) be quantity of segments that form segment [*a*, *b*] of permutation. There are three cases (see picture below):
+
+* If the new element *p**r* + 1 is between two marked elements (that is, both elements with values *p**r* + 1 - 1 and *p**r* + 1 + 1 belong to segment [*l*, *r*]), then *s*([*l*, *r* + 1]) = *s*([*l*, *r*]) - 1. The new element will <> the segments near it.
+* If the new element *p**r* + 1 has only one neighbor with value belonging to [*l*, *r*], then *s*([*l*, *r* + 1]) = *s*([*l*, *r*]). The new element will lengthen one of existing segments.
+* If there are no marked elements near *p**r* + 1 the new element forms a new segment, *s*([*l*, *r* + 1]) = *s*([*l*, *r*]) + 1.
+
+
+
+The new element is red, elements that are marked to this moment are black.
+
+Improved algo: Let's bruteforce position of the left border and for each instance move the right border from left to right. During each move we shall recount the actual quantity of segments forming the current segment of permutation (*s*([*l*, *r*])). Now we have a solution in complexity *O*(*n*2). It works fast enough even when *n* = 20000. Obviously, that is not enough to get AC.
+
+Move on full solution. It is based on previous. Now we can calc *s*([*l*, *r*]) using *s*([*l*, *r* - 1]). Now we should look at way of changing *s*([*l* - 1, *r*]) as compared with *s*([*l*, *r*]). Let's move left border of segment from the right to left and support some data structure with *s*([*l*, *i*]) for every *i* satisfying *l* < *i* ≤ *n* and current *l*. This structure should answer queries "count numbers 1 and 2 in structure", that is count segments [*l*, *i*] that generates one or two segments in the original permutaton.
+
+Let Δ*i* be *s*([*l* - 1, *i*]) - *s*([*l*, *i*]). Δ*l* will be equal to 1 because one element form one segment in permutation (notice that in final answer we must not consider 1-element segments, that's why we must subtract *n* from answer in the end of solution).
+
+Δ*i* determined by the number of neighbors of element *l* - 1 in the segment [*l* - 1, *i*]. Neighbors of *l* - 1 is elements *p**l* - 1 + 1 and *p**l* - 1 - 1 if they're exist.
+
+* If *l* - 1 hasn't neighbors in this segment, Δ*i* = 1, because *l* - 1 froms new 1-element segment.
+* If *l* - 1 has one neighbor in this segment Δ*i* = 0, because *l* - 1 join to existing segment of its neighbor.
+* If *l* - 1 has two neighbors in this segment Δ*i* = - 1, because *l* - 1 connect segments of its neighbors.
+
+Number of neighbors in segment [*l* - 1, *i*] non-decreasing with increasing *i*. That's why Δ*i* non-decreasing with increasing *i*. That means that there are only three segments of equivalence of Δ*i*. We are interested only in neighbors of *l* - 1 which positions are right than *l* - 1. Let *a* is position of first neighbor, *b* is position of second neighbor, without loss of generality *a* < *b*. Then , 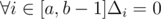, 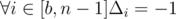. (elements of permutation are numbered from 0). If *a* and *b* aren't exist, for all  Δ*i* = 1. If only *b* isn't exist for 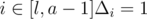, for 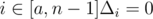.
+
+
+
+Look at example to clear your understanding. (Δ*i* is in top right corners, *l* = 3, *p**l* = 5)
+
+Using this facts we can code data structure support following operations:
+
+* Add +1 or -1 on segment
+* Calc number of 1 and 2 in the structure.
+
+Sum of answers of structure in every iteration (for every *l*) is answer to problem.
+
+Let's notice that all numbers in structure will be positive. That's why elements 1 and 2 will be minimal of pre-minimal in the structure. Using this fact we can code segment tree, supports these operations.
+
+Complexity of this solution is .
+
+We also can code sqrt-decomposition and obtain complexity .
+
+**Problem <>**
+
+Translation by [fdoer](/profile/fdoer "Candidate Master fdoer")
+
+Main idea: baby-step-giant-step.
+
+In this problem we had some Fibonacci number modulo 1013 *f*, and we had to determine the position of its first occurence in Fibonacci sequence modulo 1013.
+
+* Let *a* and *b* be two different coprime modula — divisors of 1013.
+* Let *F* be the actual Fibonacci number such that 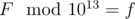. Then 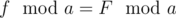 and 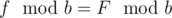.
+* Find all occurences of number  in Fibonacci sequence modulo *a* period.
+* Find all occurences of number  in Fibonacci sequence modulo *b* period.
+* Let's fix a pair of such occurences. Let the occurence modulo *a* be in position *i*, and the occurence modulo *b* be in position *j*.
+* Let *t*(*m*) be Fibonacci sequence modulo *m* period.
+* From the Chinese Remainder Theorem, it follows that *t*(*ab*) = *LCM*(*t*(*a*), *t*(*b*)) (remember that *a* and *b* are coprime).
+* Then from fixed occurences of *f* in periods of sequences modulo *a* and *b* we can recover the position of occurence of *f* in period of sequence modulo *ab*. It could be done by solving the following Diophantine equation: *i* + *t*(*a*) * *x* = *j* + *t*(*b*) * *y*. We can solve it using a simple bruteforce of one of the roots.
+* If the occurence in sequence modulo *ab* period ( we have just found it) is *u*, then every occurence *f* in Fibonacci sequence modulo 1013 period can be represented as *t*(*ab*) * *k* + *u*. Then let's bruteforce *k* and find all occurences in sequence modulo 1013 period. To determine Fibonacci number on position α + *t*(*ab*) from known Fibonacci number on position α, we need to multiply the vector (*F*α, *F*α + 1) and some matrix.
+* Let's choose *a* = 59 and *b* = 213. Note that there is no number that occur Fibonacci sequence modulo *a* or *b* period more than 8 times. That means that total count of pairs will never be greater than 64. For each occurence we'll bruteforce not more than 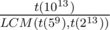 numbers. That was the author's solution.
+
+Also that was possible to use the fact that for any number the count of its occurences in period of sequence modulo 10*p* (for any natural *p*) is not big more efficiently. From occurences in sequence modulo 10*i* period we could get occurences in sequence modulo 10*i* + 1 period using the method we use to jump from modulus *ab* to modulus 1013.
diff --git a/editorials/195.md b/editorials/195.md
@@ -0,0 +1,58 @@
+Source: https://codeforces.com/blog/entry/4699
+
+[195A - Let's Watch Football](/contest/195/problem/A "Codeforces Round 123 (Div. 2)")
+
+The whole video will be downloaded in *all* = (*c*·*a* + *b* - 1) / *b* seconds. In this problem you can choose every 1 < = *t* < = *all* as an answer. To fulfill coditions of the problem it is enough to check the condition *t*0·*b* > = (*t*0 - *t*)·*a* at the moment of time t0 = all.
+
+[195B - After Training](/contest/195/problem/B "Codeforces Round 123 (Div. 2)")
+
+In this problem you should carefully implement the given process. Firstly note that ball number *i* > *m* will be in the same basket as ball number *i* - *m*. Therefore it is enough to distribute first *m* balls. It can be done using two pointers *lf*, *rg* from the middle. Alternately put one ball to the left and to the right and shift pointers. In only case you should shift left pointer twice in the first moment of time if *m* is odd.
+
+[195C - Try and Catch](/contest/195/problem/C "Codeforces Round 123 (Div. 2)")
+
+In this problem you was to implement what was writen in the statement. In my solution I did the following. Erase all spaces from the text except spaces in messages in try-catch blocks. Then when we get word "try" we put number of the new try-catch block in stack. When we get word "throw" we remember it's type and current state of stack (that is what try-catch blocks are opened). For example, put these number in set. When we get word "catch" if it's type equals to type of operator "throw" and the number of current try-catch block is in your set then write the answer now else erase this try-catch block from stack. If there was no suitable try-catch block write "Unhandled Exception".
+
+[195D - Analyzing Polyline](/contest/195/problem/D "Codeforces Round 123 (Div. 2)")
+
+Tutorial by author [Igor_Kudryashov](/profile/Igor_Kudryashov "Candidate Master Igor_Kudryashov")
+
+In fact in this problem we were given lines *y**i* = *k**i* * *x* + *b**i* but negative values were replaced by zero. Your task was to find the number of angles that do not equal 180 degrees in the graph s(x), that is the sum of the given functions.
+
+Firstly note that sum of two lines is also line. Indeed *y* = *y*1 + *y*2 is *y* = *k*1 * *x* + *b*1 + *k*2 * *x* + *b*2 = (*k*1 + *k*2) * *x* + (*b*1 + *b*2).
+
+Consider points where *y**i* = 0, that is *x**i* = - *b**i* / *k**i*. While we assume that *k**i* doesn't equal to 0. Then line number *i* is divided in two lines one of which identically equals to 0. Consider all different points *x**i* and sort them. Then, obviously, the sum of the given functions between two consecutive points is line. Find the equation of the line. Assume that we consider point *i* from the left. Then equation of the line between points *i* and *i* + 1 will not be equal to equation of the line between points *i* and *i* - 1. That is in point *i* is formed an angle that doesn't equal 180 degrees.
+
+So we should find equations of lines between every pair of points *i* and *i* + 1. It can be easily done using two arrays with queries of increasing value on the interval offline.
+
+[195E - Building Forest](/contest/195/problem/E "Codeforces Round 123 (Div. 2)")
+
+Tutorial by author [Fefer_Ivan](/profile/Fefer_Ivan "Candidate Master Fefer_Ivan")
+
+The longest operation in this problem is to find the root of some vertex and the sum of the path to this root. To find these values fast we will use compression ways heuristics which is used in data structure "disjoint-set-union".
+
+For every vertex v we keep two values : *c*[*v*] and *sum*[*v*]. *c*[*v*] = *v*, if *v* — root, else *c*[*v*] — next vertex on path from *v* to root. *sum*[*v*] = sum of lengths of edges on path from *v* to *c*[*v*].
+
+To add new edge from *u* to *v* of length *w* it is enough to do *c*[*u*] = *v* and *sum*[*u*] = *w*.
+
+Note that we only add new edges (we don't erase edges).
+
+That is, if we find *root*(*v*) and *depth*(*v*) for some vertex *v* we can assign *c*[*v*] = *root*(*v*),
+
+Unable to parse markup [type=CF_TEX]
+
+time. The approximate implementation is shown below.
+
+```
+int root(int v){
+ if(c[v] == v){
+ return v;
+ }else{
+ int u = root(c[v]);
+ sum[v] = (sum[c[v]] + sum[v]) % M;
+ c[v] = u;
+ return u;
+ }
+}
+```
+
+It can proved that such implementation works using *O*(*log*(*n*)) time for every query. The complexity of the solution is *O*(*n* * *log*(*n*)).
diff --git a/editorials/196.md b/editorials/196.md
@@ -0,0 +1,87 @@
+Source: https://codeforces.com/blog/entry/4717
+
+[197A - Plate Game](/contest/197/problem/A "Codeforces Round 124 (Div. 2)")
+
+If first player can't make first move (table is too small and plate doesn't fit it, i.e. 2*r* > *min*(*a*, *b*)), second player wins. Else first player wins. Winning strategy for first player: place first plate to the center of table. After that he symmetrically reflects moves of second player with respect to center of table. If second player has move, first player has symmetrical move, too. If not, first player won.
+
+[197B - Limit](/contest/197/problem/B "Codeforces Round 124 (Div. 2)")
+
+From math lessons we know, that only higher degrees of polinomials matter in this problem.
+
+1. If denominator degree is larger than numenator degree, answer is "0/1".
+2. If numenator degree is larger, answer is infinity. But what is sign of this infinity? To get it consider signs of highest degree factors of polinomials. If they are same, answer is positive infinity, else — negative infinity.
+3. If degrees of numenator and denominator are equal, answer is . To get irreducible fraction, you should divide this numbers by *gcd*(*a*0, *b*0). And don't forget that denominator of answer must be positive.
+
+[196A - Lexicographically Maximum Subsequence](/contest/196/problem/A "Codeforces Round 124 (Div. 1)")
+
+Solution is greedy. First, write all 'z' letters (if there is any) — answer must contain them all for sure. Now it's time for 'y' letters. We can use only those of them which are on the right of last used 'z' letter. Then write 'x' letters — they must be on the right of the last used 'y' and 'z' letters. And so on.
+
+[196B - Infinite Maze](/contest/196/problem/B "Codeforces Round 124 (Div. 1)")
+
+Answer is "Yes" iff there are two distinct, reachable from start position cells, which correspond to same cell in initial labyrinth.
+
+Proof: If these cells exist, move to first of them, and infinitely repeat moves leading from first to second. On the contrary, if infinite far path exist, on this path we obviously can find such cells.
+
+How to find out if they exist? Start DFS from initial cell. For each cell visited, let *visit*[*x*%*n*][*y*%*m*] = (*x*, *y*). Now, if DFS tries to go to cell (*x*, *y*), *visit*[*x*%*n*][*y*%*m*] contains something, and (*x*, *y*) ≠ *visit*[*x*%*n*][*y*%*m*], we found these cells: they are (*x*, *y*) and *visit*[*x*%*n*][*y*%*m*]. Notice that DFS will visit no more than *nm* + 1 cells (Dirichlet's principle). So the asymptotic is *O*(*nm*).
+
+[196C - Paint Tree](/contest/196/problem/C "Codeforces Round 124 (Div. 1)")
+
+No three points are in the same line, so the solution always exists.
+
+First, choose any one vertex as the root of tree. Find size of each subtree using dfs.
+
+Then, we can build the answer recursively.
+
+Put the root of tree to the most lower left point.
+
+Sort all other points by angle relative to this lower left point.
+
+Let us name the sizes of subtrees of the root as *s*1, *s*2, ..., *s**k*.
+
+Run the algorithm recursively, giving first *s*1 points (in sorted order) for the first subtree of root, next *s*2 points for the second subtree and so on.
+
+Obviously, no two edges from different subtrees can intersect now.
+
+At each step of recursion we are to put the root of current subtree to the first point in sorted-by-angle order, and then sort other points by angle relative to it.
+
+So, no two subtrees will have any intersecting edges.
+
+The asymptotic of solution is .
+
+[196D - The Next Good String](/contest/196/problem/D "Codeforces Round 124 (Div. 1)")
+
+Notice, that only palindromes with length *d* and *d* + 1 matter. Any palindrome with greater length contains one of them. Let's call these palindromes bad.
+
+First, find leftmost position *pos*, in which we surely should increase value of symbol. If there are no bad subpalindromes, *pos* = |*s*| - 1, else *pos* is leftmost position amongst all ends of bad palindromes.
+
+Increase *s*[*pos*]. Increase it more, while *s*[*pos*] is end of bad subpalindrome. If you try increase 'z' symbol, you should proceed to increasing previous symbol. If this way you reached situation when you need to increase first symbol, and it is 'z', answer is "Impossible".
+
+Now, let pos be position of leftmost changed symbol. We know, that prefix *s*[0..*pos*] doesn't contain bad palindromes. Now we can greedily fill suffix *s*[*pos* + 1..*length*(*s*) - 1]: go over positions *i* in ascending order, assign *s*[*i*] = 'a', and increase it, while *s*[*i*] is end of bad palindrome. Obviously, any of suffix symbols will be 'a', 'b' or 'c'.
+
+So we got algorithm, which requires fast implementation of next operations — assigning single symbol, and query: is given substring palindrome? You can perform this operations using hashes and Fenwick tree.
+
+Let's learn, how to get hash of substring in dynamically changing string. If we can it, we will keep string *s* and it's reversed copy. For query of second type we just need to compare hashes of substring in *s* and hash of corresponding substring in reversed copy.
+
+Let Fenwick tree store values *h*[*i*] = *s*[*i*]*P**i*, where *P* is the prime number used for hashing. Then hash of substring *s*[*L*..*R*] equals to (*h*[*L*] + *h*[*L* + 1] + ...*h*[*R*])*P*- *L*. For assigning *s*[*i*] = *c*, add value (*c* - *s*[*i*])*P**i* to *h*[*i*]. Both these operations Fenwick tree does in .
+
+Also we have faster solution without hashes and data structures, it will be published soon.
+
+[196E - Opening Portals](/contest/196/problem/E "Codeforces Round 124 (Div. 1)")
+
+First of all, we can note that if each graph vertex is portal, the answer will be a sum of all edges' weights in MST (minimal spanning tree). We can find MST by using Kruskal's algo.
+
+In this problem, not an every vertex is portal. Let's fix this.
+
+Start with a precalculation. Run Dijkstra's algo from all the portals, simultaneously. We will get *d*[*i*] — a distance between vertex *i* and *p*[*i*] — the nearest portal to vertex *i*.
+
+Let's trace Kruskal's algo on a graph of portals. On the first iteration, it will choose the edge with the minimal cost, i.e. a shortest path between all the portals in the original graph.
+
+Let the path leads from portal *x* to portal *y*. Note that there exists a path with the same length such as *p*[*i*] changes only once through it. Indeed, *p*[*x*] = *x*, *p*[*y*] = *y*, i.e. *p*[*i*] changed on the path. If it happens on edge , *p*[*i*] = *x*, a path 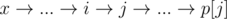 will not be longer than the path from *x* to *y*.
+
+As *p*[*i*] = *x* and *p*[*i*] = *y*, we can see that the length of this path will be *d*[*i*] + *w*(*i*, *j*) + *d*[*j*], where *w*(*i*, *j*) is the weight of edge (*i*, *j*). Kruskal's algo will add this value to the answer and merge portals *x* and *y*. The shortest-path trees of vertexes *x* and *y* will also be merged.
+
+Note, that almost nothing changed. The next edge for Kruskal's algo can be find in a similar way — 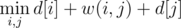. If this edge connects *x* and *y* again, DSU makes us not to count this edge, otherwise this edge connects a different pair of edges and will be counted in an answer.
+
+We can easily implement this. Just create a new graph of portals, with an edge (*p*[*i*], *p*[*j*]) of weight *d*[*i*] + *w*(*i*, *j*) + *d*[*j*] for every edge (*i*, *j*) of weight *w*(*i*, *j*) from original graph and run Kruskal's algo.
+
+Finally, note that if the starting vertex is not a portal, we shall add *d*[1] to the answer.
diff --git a/editorials/197.md b/editorials/197.md
@@ -0,0 +1,87 @@
+Source: https://codeforces.com/blog/entry/4717
+
+[197A - Plate Game](/contest/197/problem/A "Codeforces Round 124 (Div. 2)")
+
+If first player can't make first move (table is too small and plate doesn't fit it, i.e. 2*r* > *min*(*a*, *b*)), second player wins. Else first player wins. Winning strategy for first player: place first plate to the center of table. After that he symmetrically reflects moves of second player with respect to center of table. If second player has move, first player has symmetrical move, too. If not, first player won.
+
+[197B - Limit](/contest/197/problem/B "Codeforces Round 124 (Div. 2)")
+
+From math lessons we know, that only higher degrees of polinomials matter in this problem.
+
+1. If denominator degree is larger than numenator degree, answer is "0/1".
+2. If numenator degree is larger, answer is infinity. But what is sign of this infinity? To get it consider signs of highest degree factors of polinomials. If they are same, answer is positive infinity, else — negative infinity.
+3. If degrees of numenator and denominator are equal, answer is . To get irreducible fraction, you should divide this numbers by *gcd*(*a*0, *b*0). And don't forget that denominator of answer must be positive.
+
+[196A - Lexicographically Maximum Subsequence](/contest/196/problem/A "Codeforces Round 124 (Div. 1)")
+
+Solution is greedy. First, write all 'z' letters (if there is any) — answer must contain them all for sure. Now it's time for 'y' letters. We can use only those of them which are on the right of last used 'z' letter. Then write 'x' letters — they must be on the right of the last used 'y' and 'z' letters. And so on.
+
+[196B - Infinite Maze](/contest/196/problem/B "Codeforces Round 124 (Div. 1)")
+
+Answer is "Yes" iff there are two distinct, reachable from start position cells, which correspond to same cell in initial labyrinth.
+
+Proof: If these cells exist, move to first of them, and infinitely repeat moves leading from first to second. On the contrary, if infinite far path exist, on this path we obviously can find such cells.
+
+How to find out if they exist? Start DFS from initial cell. For each cell visited, let *visit*[*x*%*n*][*y*%*m*] = (*x*, *y*). Now, if DFS tries to go to cell (*x*, *y*), *visit*[*x*%*n*][*y*%*m*] contains something, and (*x*, *y*) ≠ *visit*[*x*%*n*][*y*%*m*], we found these cells: they are (*x*, *y*) and *visit*[*x*%*n*][*y*%*m*]. Notice that DFS will visit no more than *nm* + 1 cells (Dirichlet's principle). So the asymptotic is *O*(*nm*).
+
+[196C - Paint Tree](/contest/196/problem/C "Codeforces Round 124 (Div. 1)")
+
+No three points are in the same line, so the solution always exists.
+
+First, choose any one vertex as the root of tree. Find size of each subtree using dfs.
+
+Then, we can build the answer recursively.
+
+Put the root of tree to the most lower left point.
+
+Sort all other points by angle relative to this lower left point.
+
+Let us name the sizes of subtrees of the root as *s*1, *s*2, ..., *s**k*.
+
+Run the algorithm recursively, giving first *s*1 points (in sorted order) for the first subtree of root, next *s*2 points for the second subtree and so on.
+
+Obviously, no two edges from different subtrees can intersect now.
+
+At each step of recursion we are to put the root of current subtree to the first point in sorted-by-angle order, and then sort other points by angle relative to it.
+
+So, no two subtrees will have any intersecting edges.
+
+The asymptotic of solution is .
+
+[196D - The Next Good String](/contest/196/problem/D "Codeforces Round 124 (Div. 1)")
+
+Notice, that only palindromes with length *d* and *d* + 1 matter. Any palindrome with greater length contains one of them. Let's call these palindromes bad.
+
+First, find leftmost position *pos*, in which we surely should increase value of symbol. If there are no bad subpalindromes, *pos* = |*s*| - 1, else *pos* is leftmost position amongst all ends of bad palindromes.
+
+Increase *s*[*pos*]. Increase it more, while *s*[*pos*] is end of bad subpalindrome. If you try increase 'z' symbol, you should proceed to increasing previous symbol. If this way you reached situation when you need to increase first symbol, and it is 'z', answer is "Impossible".
+
+Now, let pos be position of leftmost changed symbol. We know, that prefix *s*[0..*pos*] doesn't contain bad palindromes. Now we can greedily fill suffix *s*[*pos* + 1..*length*(*s*) - 1]: go over positions *i* in ascending order, assign *s*[*i*] = 'a', and increase it, while *s*[*i*] is end of bad palindrome. Obviously, any of suffix symbols will be 'a', 'b' or 'c'.
+
+So we got algorithm, which requires fast implementation of next operations — assigning single symbol, and query: is given substring palindrome? You can perform this operations using hashes and Fenwick tree.
+
+Let's learn, how to get hash of substring in dynamically changing string. If we can it, we will keep string *s* and it's reversed copy. For query of second type we just need to compare hashes of substring in *s* and hash of corresponding substring in reversed copy.
+
+Let Fenwick tree store values *h*[*i*] = *s*[*i*]*P**i*, where *P* is the prime number used for hashing. Then hash of substring *s*[*L*..*R*] equals to (*h*[*L*] + *h*[*L* + 1] + ...*h*[*R*])*P*- *L*. For assigning *s*[*i*] = *c*, add value (*c* - *s*[*i*])*P**i* to *h*[*i*]. Both these operations Fenwick tree does in .
+
+Also we have faster solution without hashes and data structures, it will be published soon.
+
+[196E - Opening Portals](/contest/196/problem/E "Codeforces Round 124 (Div. 1)")
+
+First of all, we can note that if each graph vertex is portal, the answer will be a sum of all edges' weights in MST (minimal spanning tree). We can find MST by using Kruskal's algo.
+
+In this problem, not an every vertex is portal. Let's fix this.
+
+Start with a precalculation. Run Dijkstra's algo from all the portals, simultaneously. We will get *d*[*i*] — a distance between vertex *i* and *p*[*i*] — the nearest portal to vertex *i*.
+
+Let's trace Kruskal's algo on a graph of portals. On the first iteration, it will choose the edge with the minimal cost, i.e. a shortest path between all the portals in the original graph.
+
+Let the path leads from portal *x* to portal *y*. Note that there exists a path with the same length such as *p*[*i*] changes only once through it. Indeed, *p*[*x*] = *x*, *p*[*y*] = *y*, i.e. *p*[*i*] changed on the path. If it happens on edge , *p*[*i*] = *x*, a path 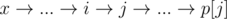 will not be longer than the path from *x* to *y*.
+
+As *p*[*i*] = *x* and *p*[*i*] = *y*, we can see that the length of this path will be *d*[*i*] + *w*(*i*, *j*) + *d*[*j*], where *w*(*i*, *j*) is the weight of edge (*i*, *j*). Kruskal's algo will add this value to the answer and merge portals *x* and *y*. The shortest-path trees of vertexes *x* and *y* will also be merged.
+
+Note, that almost nothing changed. The next edge for Kruskal's algo can be find in a similar way — 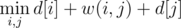. If this edge connects *x* and *y* again, DSU makes us not to count this edge, otherwise this edge connects a different pair of edges and will be counted in an answer.
+
+We can easily implement this. Just create a new graph of portals, with an edge (*p*[*i*], *p*[*j*]) of weight *d*[*i*] + *w*(*i*, *j*) + *d*[*j*] for every edge (*i*, *j*) of weight *w*(*i*, *j*) from original graph and run Kruskal's algo.
+
+Finally, note that if the starting vertex is not a portal, we shall add *d*[1] to the answer.
diff --git a/editorials/198.md b/editorials/198.md
@@ -0,0 +1,88 @@
+Source: https://codeforces.com/blog/entry/4764
+
+**Div2 A.** You can just output "0 0 n".
+
+Author is [Alex_KPR](/profile/Alex_KPR "Master Alex_KPR") .
+
+**Div2 B.** You should check for every circle of one ring: it have intersections with another ring or not. So, there are 4 checks.
+
+There are 2 cases:
+1. circle is inside of ring;
+2. circle is outside of ring and ring is outside of circle;
+3. circle is outside of ring and ring is inside of circle.
+If at least one of these cases is performed, circle is good.
+
+You can easily do checks following way. Let us *d* be a distance between centers of ring and circle, *r*1 and *R*1 are inside and outside radii of ring, *r* be radius of circle. Then conditions for all cases will be
+1. *d* + *r* ≤ *r*1.
+2. *r* + *R*1 ≤ *d*.
+3. *d* + *R*1 ≤ *r*.
+You can check all conditions in integers using squares of distances.
+
+Author is [Alex_KPR](/profile/Alex_KPR "Master Alex_KPR")
+
+**Div2 C.** **Div1 A.**
+The first solution. Consider sequence *a*0 = 1, *a**i* = *a**i* - 1*k* + *b*:
+*a*0, *a*1, *a*2, ..., *a**n* = *z*.
+You can see that for all numbers from segment [*a*0, *a*1 - 1] you can number not less than *z* using exactly *n* steps. But for *n* - 1 steps you will bet number less than *z*. It works because transformation is monotonous. Analogically, for numbers from segments [*a*1, *a*2 - 1], [*a*2, *a*3 - 1], etc, you need exactly *n* - 1, *n* - 2, etc steps. So you just need find segment that contains number *t*. You can do it by generate a few first members of the sequence *a*. You need no more than *t* members.
+
+The second solution. Equation:
+*tk**x* + *b*(*k**x* - 1 + *k**x* - 2... + 1) ≥ *k**n* + *b*(*k**x* - 1 + *k**x* - 2... + 1)
+Using formula for geometric progression you can get:
+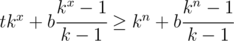
+For *k* ≠ 1 we can multiply both sides by *k* - 1, (you can consider case *k* = 1 by yourself).
+*t*(*k* - 1)*k**x* + *bk**x* - *b* ≥ (*k* - 1)*k**n* + *bk**n* - *b*
+
+*k**x*(*t*(*k* - 1) + *b*) ≥ *k**n*(*k* - 1 + *b*)
+
+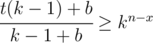
+
+So, you can find value *n* - *x* using simply raising to a power.
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") and [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div2 D.** **Div1 B.** You should construct graph where vertices are areas of walls and edges are actions of ninja. Then you should run BFS with one modification: is you reach vertex later then water, you shouldn't do moves from this vertex.
+
+It is solution in *O*(*n*).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div2 E.** **Div1 C.** If you can reach the planet in time *t*, you also can reach one in any time greater then *t* (you can just reach planet in time *t* and then move along with planet). There exists some *t*0 for that for all *t* > *t*0 you can reach planet, and for all *t* < *t*0 you cannot do in. Let us find *t*0 using binary search.
+
+Checking every of *t* inside of binary search you can do following way. You should calculate place if planet after time *t* and find distance between ship's place and new planet place.
+
+So, you have following "classic" problem: there are two points *A* and *B* and circle with center in *O* and radius *R* (points are outside of circle), you need find distance between points and you cannot moving inside of circle.
+
+There are 2 cases:
+1. You can move direct way
+2. You should skirt the circle
+
+The second case is performed iff two following conditions are performed:
+a. Angles *OAB* and *OBA* are acute
+b. Height *OH* of triangle *OAB* less than *R*
+All checks you can do in integers.
+
+Well, let's understand how to precess our cases:
+1. Obviously
+2. Let us *C* and *D* be tangency points (i.e. you are moving along line *ACDB*). Thiangles *OAC* and *OBD* are right and you can easily calculate all angles inside of them. Then you should find angle *COD*. After that you can find length of line *ACDB*. You can see that you don't need find places of points *C* and *D*.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div1 D.** We will construct solution recursively. For every *k* it is possible construct parallelepiped *k* × *k* × (*k* + 1) that contains 2 cubes *k* × *k* × *k*. For *k* = 2 solution is obliviousо. How to build solutions for *k* > 2 is shown in following picture:
+
+
+
+Red and blue cubes are start and end of chain. Firstly you should build one floor over. Then you should build 2 layers on two opposite sides.
+
+For every *n* you can build parallelepiped *n* × *n* × (*n* + 1), and drop one layer for getting cube *n* × *n* × *n*.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div1 E.** You can allocate all grippers as points on plane with coordinates (distance, mass). So, when you use some gripper, you are collecting grippers inside some rectangle with corner in origin. Let us collect grippers and put them into queue. For current gripper you should take all grippers from rectangle and store them into queue. Then you should take next gripper from queue and do some manipulations with them and so on. Well, now you need do it fast.
+
+Let us create segment tree (for example, there you can use Fenwick tree) for dimention "distance". In every vertex of that tree you should store stack of points ordered by "mass". More details: every vertex of segment tree is some range of coordinates, and you should store in thet vertex points only from this range. At the top of every stack should be point with minimal mass. Well, let us put all points into tree. Every position is covered by no more thenм  segmetns, therefore all tree will require  of memory.
+
+When you process query, you should extract points from some stacks and put them into queue. You can see that you may put some points into queue twice. To avoid this you should also put number of point into stack. So, when you are extracting point from stack you can check that it is the first extract using some array of flags.
+
+This solution works in .
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") ; the above solution was proposed by [RAD](/profile/RAD "Grandmaster RAD")
diff --git a/editorials/199.md b/editorials/199.md
@@ -0,0 +1,88 @@
+Source: https://codeforces.com/blog/entry/4764
+
+**Div2 A.** You can just output "0 0 n".
+
+Author is [Alex_KPR](/profile/Alex_KPR "Master Alex_KPR") .
+
+**Div2 B.** You should check for every circle of one ring: it have intersections with another ring or not. So, there are 4 checks.
+
+There are 2 cases:
+1. circle is inside of ring;
+2. circle is outside of ring and ring is outside of circle;
+3. circle is outside of ring and ring is inside of circle.
+If at least one of these cases is performed, circle is good.
+
+You can easily do checks following way. Let us *d* be a distance between centers of ring and circle, *r*1 and *R*1 are inside and outside radii of ring, *r* be radius of circle. Then conditions for all cases will be
+1. *d* + *r* ≤ *r*1.
+2. *r* + *R*1 ≤ *d*.
+3. *d* + *R*1 ≤ *r*.
+You can check all conditions in integers using squares of distances.
+
+Author is [Alex_KPR](/profile/Alex_KPR "Master Alex_KPR")
+
+**Div2 C.** **Div1 A.**
+The first solution. Consider sequence *a*0 = 1, *a**i* = *a**i* - 1*k* + *b*:
+*a*0, *a*1, *a*2, ..., *a**n* = *z*.
+You can see that for all numbers from segment [*a*0, *a*1 - 1] you can number not less than *z* using exactly *n* steps. But for *n* - 1 steps you will bet number less than *z*. It works because transformation is monotonous. Analogically, for numbers from segments [*a*1, *a*2 - 1], [*a*2, *a*3 - 1], etc, you need exactly *n* - 1, *n* - 2, etc steps. So you just need find segment that contains number *t*. You can do it by generate a few first members of the sequence *a*. You need no more than *t* members.
+
+The second solution. Equation:
+*tk**x* + *b*(*k**x* - 1 + *k**x* - 2... + 1) ≥ *k**n* + *b*(*k**x* - 1 + *k**x* - 2... + 1)
+Using formula for geometric progression you can get:
+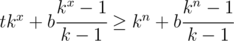
+For *k* ≠ 1 we can multiply both sides by *k* - 1, (you can consider case *k* = 1 by yourself).
+*t*(*k* - 1)*k**x* + *bk**x* - *b* ≥ (*k* - 1)*k**n* + *bk**n* - *b*
+
+*k**x*(*t*(*k* - 1) + *b*) ≥ *k**n*(*k* - 1 + *b*)
+
+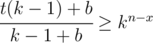
+
+So, you can find value *n* - *x* using simply raising to a power.
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") and [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div2 D.** **Div1 B.** You should construct graph where vertices are areas of walls and edges are actions of ninja. Then you should run BFS with one modification: is you reach vertex later then water, you shouldn't do moves from this vertex.
+
+It is solution in *O*(*n*).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div2 E.** **Div1 C.** If you can reach the planet in time *t*, you also can reach one in any time greater then *t* (you can just reach planet in time *t* and then move along with planet). There exists some *t*0 for that for all *t* > *t*0 you can reach planet, and for all *t* < *t*0 you cannot do in. Let us find *t*0 using binary search.
+
+Checking every of *t* inside of binary search you can do following way. You should calculate place if planet after time *t* and find distance between ship's place and new planet place.
+
+So, you have following "classic" problem: there are two points *A* and *B* and circle with center in *O* and radius *R* (points are outside of circle), you need find distance between points and you cannot moving inside of circle.
+
+There are 2 cases:
+1. You can move direct way
+2. You should skirt the circle
+
+The second case is performed iff two following conditions are performed:
+a. Angles *OAB* and *OBA* are acute
+b. Height *OH* of triangle *OAB* less than *R*
+All checks you can do in integers.
+
+Well, let's understand how to precess our cases:
+1. Obviously
+2. Let us *C* and *D* be tangency points (i.e. you are moving along line *ACDB*). Thiangles *OAC* and *OBD* are right and you can easily calculate all angles inside of them. Then you should find angle *COD*. After that you can find length of line *ACDB*. You can see that you don't need find places of points *C* and *D*.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div1 D.** We will construct solution recursively. For every *k* it is possible construct parallelepiped *k* × *k* × (*k* + 1) that contains 2 cubes *k* × *k* × *k*. For *k* = 2 solution is obliviousо. How to build solutions for *k* > 2 is shown in following picture:
+
+
+
+Red and blue cubes are start and end of chain. Firstly you should build one floor over. Then you should build 2 layers on two opposite sides.
+
+For every *n* you can build parallelepiped *n* × *n* × (*n* + 1), and drop one layer for getting cube *n* × *n* × *n*.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti")
+
+**Div1 E.** You can allocate all grippers as points on plane with coordinates (distance, mass). So, when you use some gripper, you are collecting grippers inside some rectangle with corner in origin. Let us collect grippers and put them into queue. For current gripper you should take all grippers from rectangle and store them into queue. Then you should take next gripper from queue and do some manipulations with them and so on. Well, now you need do it fast.
+
+Let us create segment tree (for example, there you can use Fenwick tree) for dimention "distance". In every vertex of that tree you should store stack of points ordered by "mass". More details: every vertex of segment tree is some range of coordinates, and you should store in thet vertex points only from this range. At the top of every stack should be point with minimal mass. Well, let us put all points into tree. Every position is covered by no more thenм  segmetns, therefore all tree will require  of memory.
+
+When you process query, you should extract points from some stacks and put them into queue. You can see that you may put some points into queue twice. To avoid this you should also put number of point into stack. So, when you are extracting point from stack you can check that it is the first extract using some array of flags.
+
+This solution works in .
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") ; the above solution was proposed by [RAD](/profile/RAD "Grandmaster RAD")
diff --git a/editorials/2.md b/editorials/2.md
@@ -0,0 +1,40 @@
+Source: https://codeforces.com/blog/entry/107
+
+Lets start from the end.
+
+## [Problem С. Commentator problem](https://codeforces.com/contest/2/problem/C)
+
+Let *R* be the distance from point А to a circle with center О and radius *r*. From this point the circle is observed at the angle 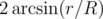.
+ So, the three stadiums are observed at the same angle if **R*1 / *r*1 = *R*2 / *r*2 = *R*3 / *r*3.*
+ Take two different points A, B. The set of points C that *AC* / *BC* = *const* is either a line (perpendicular bisector of AB) or a circle with center somewhere on the line AB. This circle is easy to find. It contains two points that lie on AB and satisfy *AC* / *BC* condition.
+
+Let *X*1 be the set of points from which stadiums 1 and 2 are observed at the same angle. Let *X*2 be the set of points from which stadiums 2 and 3 are observed at the same angle. The answer belongs to both *X*1 and *X*2 . The centers of the three stadiums don't lie on one line, so the number of points in the intersection of *X*1 and *X*2 will be finite.
+Check them all. The answer is the point that lies closer to any of the stadiums. The stadiums don't intersect, so that point will not lie inside any of them.
+How to get a big circle for *X*1 : put the centers of the stadiums in the points far away, for example in (0, 0) and (1000, 0). The ratio of the radii should be the closer possible to 1, for example . The center and the radius of the new circle will have the order 106 . The answer should be known with 10- 5 precision. Roofly speaking, we need 11 digits, double precision will be enough.
+
+
+## [Problem B. The least round way](https://codeforces.com/contest/2/problem/B)
+
+Let us solve the problem in the case of positive matrix.
+Let the number in the end be *N* = 2*k*· 5*m*·(other primes). The number of zeroes at the end of *N* is equal to *min*(*k*, *m*). At the aid of dynamic programming find minimal value of *k* (let it be *k*1) and minimal value of *m* (let it be *m*1), and paths that lead to these values. In case of *k*1 < *m*1 choose the path corresponding to *k*1, else *m*1.
+ So *min*(*k*, *m*) is the upper bound for the answer. Let us prove that it is the lower bound too. If there exists a path leading to a number with number of zeroes less than *min*(*k*, *m*) then in the factorization of that number the power of two is *k* < *k*1 or the power of five is *m* < *m*1. We come to a contradiction.
+So we need to calculate the power of 2 and 5 in the factorization of each value in the matrix and use dynamic programming on each of the two matrices.
+
+In the case of matrix containing zeroes, calculate separately the best path not containing zeroes and any path containing zeroes:
+
+Replace all 0by 10 and use the method described above. For paths containing zeroes the result will contain at least one zero at the end. If the method returned a number without zeroes at the end, the corresponding path is the answer, else any path containing zeroes is the answer.
+The complexity of the algorithm depends on the complexity of the dynamics, it is *O*(*N*· *M*).
+
+
+## [Problem A. Winner](https://codeforces.com/contest/2/problem/A)
+
+Simple problem, just code it.
+ At the first pass calculate the sum of points for each player at game end. Let *M* be the maximum of these sums. At the second pass check every round. If current player *X* has not less than *M* points and his final score is equal to *M* then he is the winner.
+ The following test illustrates that player could receive more than *M* points, then lose some and, finally, win.
+ Input:
+ Masha 12
+ Masha -5
+ Sasha 10
+ Masha 3
+ Output:
+ Masha
diff --git a/editorials/200.md b/editorials/200.md
@@ -0,0 +1,37 @@
+Source: https://codeforces.com/blog/entry/4769
+
+[200A — Cinema](https://codeforces.com/contest/200/problem/A)
+
+In this problem were given the field, which size is *n* × *m*, and *k* queries. Each query is the cell of the field. You had to find closest free cell for given one (there was used manhattan metric). Than found cell was marked as used. The time complexity of the solution is supposed to be . Firstly, we show the main idea, than we show why solution has time complexity .
+
+First of all, if *n* > *m*, than rotate matrix by 90 degrees (than we explain purpose of this transformation). We will have two matrices, size of each is *n* × *m*. In this matrices we will maintain for each cell the nearest free one to the left and to the right. Suppose we have query — cell (*x*, *y*). Iterate *d* — how much rows we will go above or below. Suppose we fix *d*, than look at the row *x* - *d*, for example (also we should do same things for row *x* + *d*). Lets find in this row nearest free cells to the left and to the right of (*x* - *d*, *y*) by using our matrices and try to update answer. When *d* will be greater than current found answer we will stop, because answer won't update in this case. After we find the answer, we have to change value in some cells of our matrices. It can be done by using structure DSU for each row.
+
+Lets show why this solution has time complexity . Suppose all queries are equal, for example each query is (*x*, *y*). Than if field is big enough, all points will be placed in form of square, which is rotated by 45 degrees and have center in point (*x*, *y*). Also the side of the square will have length . Than diagonal will have length  too. It means that we see  rows in each query and we do *O*(1) operations in each row. If the square doesn't fit into the field, than field is too thin verticaly or horizontaly. So we will have figure looks like rectangle, and one side of this rectangle will be less than . In this case rotate field so, than least side of rectangle means rows. Than we will see not greater than  rows in each query and will perform not greater than *O*(1) operations in each row.
+
+This problem is supposed to be the hardest problem of the contest.
+
+[200B — Drinks](https://codeforces.com/contest/200/problem/B)
+
+This problem was the easiest problem of the contest. There you had to find average of the given numbers. The most participants solved this problem.
+
+[200C — Football Championship](https://codeforces.com/contest/200/problem/C)
+
+In this problem was given description of the group stage of some football competition and scoring system. There were given results of all matches, excepting one, and you had to find result of the last match, satisfied some given criterias. Also Berland's team must be first or the second team of the group after than match.
+
+Lets note, that in each finished match were not greater than 18 goals. It means that we can brute-force all results of the last match, when score is not greater than 200 goals, and find the best one. One of the easiest way is to fill table to the end (it means to change points value and balls value), than to sort teams according to the given rules and to check that Berland is the first or the second team of the group.
+
+[200D — Programming Language](https://codeforces.com/contest/200/problem/D)
+
+In this task were given the list of template functions. Each function have its name and the list of types of arguments (also it can be used universal type). Also there were given set of variables and thier types, and some queries. Each query is function, which has name and list of arguments. For each query you had to find, how many functions from the given list fit to the function from query. There fit means that functions have the same name, same number of arguments and types of all arguments also equal.
+
+For solving this problem it is needed to implement comparing of functions. Constrains gave the possibility to brute-force function from the given list and check if the names and arguments of functions are equal.
+
+[200E — Tractor College](https://codeforces.com/contest/200/problem/E)
+
+In this problem were given four integer numbers *c*3, *c*4, *c*5, *s*. You had to find 0 ≤ *k*3 ≤ *k*4 ≤ *k*5 such, that *c*3·*k*3 + *c*4·*k*4 + *c*5·*k*5 = *s* and |*c*3·*k*3–*c*4·*k*4| + |*c*4·*k*4–*c*5·*k*5| is minimal.
+
+Firstly, brute-force *k*4 so, that *s*–*c*4·*k*4 ≥ 0. Than look at 4 cases, according to the sign of the value in each modulus.
+
+Lets see the case, when *c*3·*k*3–*c*4·*k*4 ≥ 0 and *c*4·*k*4–*c*5·*k*5 ≥ 0. Than we have to minimize *c*3·*k*3–*c*5·*k*5. Also 0 ≤ *k*3 ≤ *k*4 ≤ *k*5 and *c*3·*k*3 + *c*5·*k*5 = *s*–*c*4·*k*4. Lets see diofant equation *c*3·*k*3 + *c*5... *k*5 = *s*–*c*4·*k*4. It can be that this equation doesn't have solution. Lets see the case, when equation has solution. As *c*3, *c*5 ≥ 0, than for minimization *c*3·*k*3–*c*5·*k*5 we have to minimize *k*3 and maximize *k*5. All solutions of diofant equation *c*3·*k*3 + *c*5·*k*5 = *s*–*c*4·*k*4 can be described by using one argument *k*. Than we have to find such segment, that for all *k* from it, *k*3 will fit above constrains, such segment, that for all *k* from it, *k*5 will fit above constrains, find intersection of this segments and, if intersection isn't empty, choose such *k*, that *k*5 is maximal.
+
+Similar you have to manage remain 3 cases and choose optimal values *k*3 and *k*5 for fixed *k*4. Also you can note, that in all cases minimized function is linear and in segment it has minimal value in one of its ends. So we can only find such segments, that for all *k* from that segments *k*3, *k*5 will fit above constrains, and calculate answer in the ends of this segments. If for all fixed *k*4 diofant equation doesn't have solution, or intersections of the described segments are empty, than answer is *IMPOSSIBLE*, else we should find the best. So the time complexity is *O*(*s*·*log*(*s*)) — brute-force of *k*4 and solving diofant equation for fixed *k*4.
diff --git a/editorials/201.md b/editorials/201.md
@@ -0,0 +1,117 @@
+Source: https://codeforces.com/blog/entry/4808
+
+#### Problem A(div 2) — LLPS
+
+It's assumed that this problem can be solved just looking at the samples and without reading the statement itself :)
+
+Let's find the letter in the given string which comes last in the alphabet, denote this letter by *z*. If this letter occurs *p* times in the given string, then the answer is string *a* consisting of letter *z* repeated *p* times.
+
+Why is it so? Using the definition of lexicographical comparison and the fact that *z* is the largest letter in the string it's easy to understand that if some other subsequence *b* of the given string is lexicographically larger than *a*, then string *b* should be longer than *a* and, moreover, *a* should be a prefix of *b* (that is, *b* should start with *a*). But string *b* must be a palindrome, therefore its last letter must be *z*. In this case string *b* must contain more occurrences of letter *z* than the original string *s* does, which is impossible as *b* is a subsequence of *s*.
+
+Besides that, the constraint on the length of the string was very low, so the problem could be solved using brute force. For every subsequence of the given string it's necessary to check whether it's a palindrome, and from all palindromic subsequences of *s* the lexicographically largest should be chosen as the answer. The complexity of such a solution is *O*(2*n*·*n*), where *n* is the length of the string (unlike the solution above with complexity *O*(*n*)).
+
+#### Problem В(div 2) — Brand New Easy Problem
+
+The constraints in this problem were so low that a solution with complexity *O*(*m*·*k**n*) was just fine. In each problem's description it's enough to loop over all possible subsequences of words which are permutations of words in Lesha's problem, for each of them calculate the number of inversions and choose a permutation with the smallest number of inversions. This can result in a short solution using recursion or, for example, you can use several nested loops (from 1 to 4).
+
+Here is an example of pseudocode for *n* = 4:
+
+```
+w - array of words of Lesha''s problem
+s - the description of the current problem
+best = 100
+for a = 1 to k do
+ for b = 1 to k do
+ for c = 1 to k do
+ for d = 1 to k do
+ if s[a] == w[1] and s[b] == w[2] and s[c] == w[3] and s[d] == w[4] then
+ inversions = 0
+ if a > b then inversions = inversions + 1
+ if a > c then inversions = inversions + 1
+ if a > d then inversions = inversions + 1
+ if b > c then inversions = inversions + 1
+ if b > d then inversions = inversions + 1
+ if c > d then inversions = inversions + 1
+ if inversions < best then
+ best = inversions
+```
+
+At the end you should choose the problem with the smallest value of *best* and print the answer in the corresponding form.
+
+#### Problem A(div 1)/C(div 2) — Clear Symmetry
+
+It's interesting that originally the authors had an idea not to include the *x* = 3 case into pretests. Imagine the number of successful hacking attempts in this contest -- considering the fact that none of the first 43 solutions to this problem passed pretests :)
+
+Note that the sought *n* is always an odd number. Indeed, if *n* is even, then two central rows of matrix *A* must contain zeroes, otherwise there will exist two neighbouring cells containing ones. Similar restriction applies to two central columns of matrix *A*. Replacing two central rows with just one and two central columns with just one and leaving zeroes in them, we'll obtain a smaller matrix with the same sharpness.
+
+Note that the sharpness of a matrix with side *n* can't exceed . It's easy to see that it's possible to lay out  "domino pieces" 1 by 2 without intersections on a field with side *n* (in other words, all cells except one can be divided into pairs so that each pair contains neighbouring cells). Then there can be at most one one in the cells under each "domino piece" in the corresponding matrix. Therefore, the total number of ones doesn't exceed 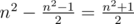.
+
+Note that a matrix with side *n* and sharpness  exists for an odd *n*. Paint all cells of the matrix in chess order and put ones into black cells and zeroes into white cells. It's easy to see that such a matrix is both clear and symmetrical and has sharpenss exactly .
+
+Intuitively it seems that if there exists a matrix with sharpness  there should also exist a matrix with every smaller sharpness. That's correct except only one case -- there doesn't exist a matrix with side 3 and sharpness 3, though there exists a matrix with side 3 and sharpness 5.
+
+Let's show that the claim above is correct for odd *n* ≥ 5. We'll build a matrix with sharpness  as shown above and gradually turn ones into zeroes reducing the sharpness. Cells containing ones in the matrix can be divided into three types.
+
+The first type is the central cell. The number in it can be turned into zero and the matrix won't stop satisfying the required conditions.
+
+The second type is the cells in the central row and the central column (except central cell). Such cells are divided into pairs by the condition of symmetry -- if we turn the number in one of them into zero, we should turn the number in its pair cell into zero as well.
+
+The third type is all the other cells. Such cells are divided into groups of four by the condition of symmetry -- if we turn the number in one of them into zero, we should turn the number in all cells from this group into zero as well.
+
+Now for obtaining the required sharpness of *x* we'll act greedily. Let's turn ones into zeroes in third type cells by four until the current shapness exceeds *x* by less than 4 or there are no third type cells with ones remaining. After that let's turn ones into zeroes in second type cells by pairs while the current sharpness exceeds *x* by at least 2. At this moment the sharpness of our matrix is either *x* or *x* + 1. If it's equal to *x* + 1, let's put a zero into the central cell and obtain a matrix with sharpness *x*. It's easy to check that we'll be able to obtain a matrix with any sharpness acting this way.
+
+Why is this reasoning incorrect for *n* = 3? Because second type cells are absent in the matrix with sharpness 5 obtained from chess coloring. For *n* ≥ 5 this matrix contains cells of all types, which is important for the algorithm above. It's better to find the answers for *x* ≤ 5 by hand but carefully -- for example, a lot of contestants decided that the answer for *x* = 2 is 5 instead of 3.
+
+#### Problem В(div 1)/D(div 2) — Guess That Car!
+
+We need to find such *x* and *y* that the value of 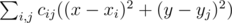 is minimum possible. This expression can be rewritten as 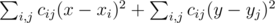. Note that the first part doesn't depend on *y* and the second part doesn't depend on *x*, so we can minimize these parts separately. Here is how to minimize 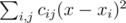, the second part is minimized similarly. As the expression in the brackets doesn't depend on *j*, this part can be rewritten as 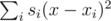, where . Now it's enough to calculate the required value for all possible values of *x* and choose *x* for which this value is the smallest. The optimal value of *y* can be found similarly.
+
+The overall complexity of this solution is *O*(*n*·*m* + *n*2 + *m*2).
+
+As the objective function is convex, other approaches to this problem are possible, for example, ternary search, gradient descent or analytical approach (calculation of derivatives).
+
+The main hero of this problem is [Ra16bit](/profile/Ra16bit "Master Ra16bit").
+
+#### Problem С(div 1)/E(div 2) — Fragile Bridges
+
+There are a few different ways to solve this problem, the editorial contains one of them.
+
+For any solution the following fact is useful. Suppose the sought path starts on platform *i* and ends on platform *j* (*i* ≤ *j*, if that's not the case, we can reverse the path). Then all bridges between platforms *i* and *j* will be passed through an odd number of times, and all other bridges will be passed through an even number of times.
+
+Let's find the maximum length of a path with its ends on platforms *i* and *j*. To do that, let's find the following auxiliary values for each platform: *left**i* -- the maximum length of a path starting and ending on platform *i* and passing only through bridges to the left of platform *i*; *right**j* -- similarly for bridges to the right of platform *j*. Also for each bridge define *odd**i* as the largest odd number not larger than *a**i*, and for each platform define *sumOdd**i* as the sum of *odd**j* for all bridges to the left of platform *i*.
+
+Then the maximum length of a path with its ends on platforms *i* and *j* is equal to *left**i* + *right**j* + (*sumOdd**j* - *sumOdd**i*), or, which is the same, (*right**j* + *sumOdd**j*) + (*left**i* - *sumOdd**i*).
+
+Now we can find the pair (*i*, *j*) for which this value is the largest in linear time. Let's loop over *j*. From the formula it's obvious that we should find such *i* ≤ *j* that (*left**i* - *sum**Odd**i*) is the largest. If we loop over *j* from 1 to *n*, we can maintain the largest value of this expression for all *i* ≤ *j* and recalculate it when moving to the next *j*, comparing (*left**j* - *sumOdd**j*) with the current maximum and possibly updating this maximum. This way for each *j* we have to check only one value of *i* and not all *i* ≤ *j*.
+
+The last thing to show is how to find all *left**i* quickly (all *right**j* can be found similarly). Clearly *left*1 = 0, then we'll calculate *left**i* using *left**i* - 1. Note that when *a**i* - 1 = 1, we have *left**i* = 0 as after passing the bridge to platform (*i* - 1) this bridge will collapse and it will be impossible to return to platform *i*. If *a**i* - 1 > 1, then *left**i* = *left**i* - 1 + *even**i* - 1, where *even**i* - 1 is the largest even number not larger than *a**i* - 1. Indeed, we can move to platform (*i* - 1), then move along the path corresponding to *left**i* - 1, and then move along the bridge between platforms (*i* - 1) and *i* until the limit on the number of transitions is less than 2 (finishing on platform *i*).
+
+The overall complexity of this solution is *O*(*n*).
+
+#### Problem D(div 1) — Brand New Problem
+
+The first solution coming to mind is dynamic programming *f*[*i*][*j*] = (the smallest possible number of inversions to the moment if among the first *j* words of the archive problem we've found a permutation of words included in bitmask *i*). In this solution parameter *j* varies from 0 to 500000, parameter *i* varies from 0 to 215 - 1 and calculation of each value is possible in *O*(1) (we are either using the current word in the subsequence or not). That's too much.
+
+Let's make use of a standard technique: make the value of DP a new parameter and make one of the existing parameters the value of DP. Not for every DP this is possible, but at least it's possible for this one :)
+
+It's clear that with a fixed subset of words and a fixed number of inversions it's optimal to choose the first occurrences of these words giving this number of inversions. Let *f*[*i*][*j*] = (the smallest number *z* such that among first *z* words of the archive problem there exists a permutation of words from bitmask *i* containing exactly *j* inversions). The basis of this DP is *f*[0][0] = 0, *f*[0][*j*] = ∞ for *j* > 0. Recalculation of values happens in the following way: loop over a word *q* from the bitmask *i* which was the last in the permutation. With the knowledge of this word and the number of inversions *j* it's easy to find how many inversions *j*' there were without this word — that's *j* minus the number of words in the mask which appeared later in Lesha's problem than word *q*. Let *p* = *f*[*i*^(1«*q*)][*j*']. Then we should consider *p*2 equal to the position of the next occurrence of word *q* after position *p* as a possible value for *f*[*i*][*j*]. To find *p*2 quickly we should fill an array *next*[500010][15] so that *next*[*i*][*j*] = (the smallest position *k* > *i* such that the *k*-th word in the archive problem equals the *j*-th word in Lesha's problem) for each archive problem in advance. This array can be easily filled passing from right to left once.
+
+The total number of operations can be calculated as *m*·(*k*·*n* + 2*n*·*C**n*2·*n*), where *m* is the number of problems in the archive, *k* is the number of words in one archive problem description and *n* is the number of words in Lesha's problem description. Under the given constraints that is about 200 million operations, and the author's solutions (including a Java solution) worked for less than 2 seconds. The time limit was set with a margin -- 5 seconds.
+
+The main heroes of problems D(div 1) and B(div 2) are [Chmel_Tolstiy](/profile/Chmel_Tolstiy "Grandmaster Chmel_Tolstiy") and [ivan.metelsky](/profile/ivan.metelsky "Grandmaster ivan.metelsky").
+
+#### Problem E(div 1) — Thoroughly Bureaucratic Organization
+
+Let's imagine that we have a magic function *maxN*(*m*, *k*) that returns, given *m* and *k*, the largest value of *n* such that it's possible to solve the problem for *n* people and *m* empty lines in the form using *k* requests. Then we'll be able to use binary search on the answer -- the number of requests *k*.
+
+Suppose we've made *k* requests. Let's match a string of length *k* to each person, where the *i*-th character is equal to 1 if this person is mentioned in the *i*-th request and 0 otherwise. Note that we'll be able to determine the exact appointment date for each person if and only if all *n* strings of length *k* are pairwise distinct. Indeed, if two persons' strings are the same, their appointment dates could be exchanged and the responses to the requests wouldn't have changed. If all strings are distinct, for each date we may find the person appointed for this date looking at the set of requests with responses containing this date and finding the person mentioned in the same set of requests.
+
+The constraint on *m* empty lines in the form means that each of *k* positions in the strings should contain no more than *m* ones in all *n* strings overall. Thus function *maxN*(*m*, *k*) should return the maximum size of a set of distinct *k*-bit strings meeting this condition. Let's make this restriction weaker: we'll search for a set such that the total number of ones in all *n* strings doesn't exceed *k*·*m*. As we'll prove later, the answer won't change.
+
+With this weaker restriction the problem can be solved using a simple greedy strategy. It's obvious that strings with smaller number of ones are better. Let's loop over the number of ones *i* in the string from 0 to *k* and also maintain a variable *t* containing the remaining number of ones (initially it's equal to *k*·*m*). Then at the *i*-th step we can take at most 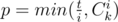 strings containing *i* ones. Let's add *p* to the answer and subtract *p*·*i* from *t*. Note that the values of *C**k**i* should be calculated with care -- they can turn out to be too large, so it's important not to allow overflows.
+
+It can be shown that the overall complexity of this algorithm is at most *O*(*log*2 *n*).
+
+The remaining thing is to prove the claim above. The idea of the proof below belongs to [rng_58](/profile/rng_58 "Grandmaster rng_58") (the author's proof is notably harder).
+
+Let's solve the problem with a greedy algorithm with the *k*·*m* constraint on the total number of ones. The resulting set of strings may not satisfy the restriction of *m* ones for each position. If it doesn't, some of the positions contain more than *m* ones and some contain less than *m* ones. Let's pick any position *X* containing more than *m* ones and any position *Y* containing less than *m* ones. Find all strings containing 1 at *X* and 0 at *Y* (suppose there are *x* such strings) and all strings containing 0 at *X* and 1 at *Y* (suppose there are *y* such strings). It's clear that *x* > *y*. In each of *x* strings we can try to put 0 at *X* and 1 at *Y* -- then the string we obtain will either remain unique in this set or coincide with one of those *y* strings (but only one). As *x* > *y*, for at least one of *x* strings the change above leaves this string unique. Let's take this string and put 0 at *X* and 1 at *Y*. Now position *X* contains one 1 less, and position *Y* contains one 1 more. It means that the total number of "extra" ones in the positions has been decreased (as *Y* still contains no more than *m* ones). Doing this operation for a needed number of times, we'll achieve our goal.
diff --git a/editorials/202.md b/editorials/202.md
@@ -0,0 +1,117 @@
+Source: https://codeforces.com/blog/entry/4808
+
+#### Problem A(div 2) — LLPS
+
+It's assumed that this problem can be solved just looking at the samples and without reading the statement itself :)
+
+Let's find the letter in the given string which comes last in the alphabet, denote this letter by *z*. If this letter occurs *p* times in the given string, then the answer is string *a* consisting of letter *z* repeated *p* times.
+
+Why is it so? Using the definition of lexicographical comparison and the fact that *z* is the largest letter in the string it's easy to understand that if some other subsequence *b* of the given string is lexicographically larger than *a*, then string *b* should be longer than *a* and, moreover, *a* should be a prefix of *b* (that is, *b* should start with *a*). But string *b* must be a palindrome, therefore its last letter must be *z*. In this case string *b* must contain more occurrences of letter *z* than the original string *s* does, which is impossible as *b* is a subsequence of *s*.
+
+Besides that, the constraint on the length of the string was very low, so the problem could be solved using brute force. For every subsequence of the given string it's necessary to check whether it's a palindrome, and from all palindromic subsequences of *s* the lexicographically largest should be chosen as the answer. The complexity of such a solution is *O*(2*n*·*n*), where *n* is the length of the string (unlike the solution above with complexity *O*(*n*)).
+
+#### Problem В(div 2) — Brand New Easy Problem
+
+The constraints in this problem were so low that a solution with complexity *O*(*m*·*k**n*) was just fine. In each problem's description it's enough to loop over all possible subsequences of words which are permutations of words in Lesha's problem, for each of them calculate the number of inversions and choose a permutation with the smallest number of inversions. This can result in a short solution using recursion or, for example, you can use several nested loops (from 1 to 4).
+
+Here is an example of pseudocode for *n* = 4:
+
+```
+w - array of words of Lesha''s problem
+s - the description of the current problem
+best = 100
+for a = 1 to k do
+ for b = 1 to k do
+ for c = 1 to k do
+ for d = 1 to k do
+ if s[a] == w[1] and s[b] == w[2] and s[c] == w[3] and s[d] == w[4] then
+ inversions = 0
+ if a > b then inversions = inversions + 1
+ if a > c then inversions = inversions + 1
+ if a > d then inversions = inversions + 1
+ if b > c then inversions = inversions + 1
+ if b > d then inversions = inversions + 1
+ if c > d then inversions = inversions + 1
+ if inversions < best then
+ best = inversions
+```
+
+At the end you should choose the problem with the smallest value of *best* and print the answer in the corresponding form.
+
+#### Problem A(div 1)/C(div 2) — Clear Symmetry
+
+It's interesting that originally the authors had an idea not to include the *x* = 3 case into pretests. Imagine the number of successful hacking attempts in this contest -- considering the fact that none of the first 43 solutions to this problem passed pretests :)
+
+Note that the sought *n* is always an odd number. Indeed, if *n* is even, then two central rows of matrix *A* must contain zeroes, otherwise there will exist two neighbouring cells containing ones. Similar restriction applies to two central columns of matrix *A*. Replacing two central rows with just one and two central columns with just one and leaving zeroes in them, we'll obtain a smaller matrix with the same sharpness.
+
+Note that the sharpness of a matrix with side *n* can't exceed . It's easy to see that it's possible to lay out  "domino pieces" 1 by 2 without intersections on a field with side *n* (in other words, all cells except one can be divided into pairs so that each pair contains neighbouring cells). Then there can be at most one one in the cells under each "domino piece" in the corresponding matrix. Therefore, the total number of ones doesn't exceed 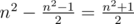.
+
+Note that a matrix with side *n* and sharpness  exists for an odd *n*. Paint all cells of the matrix in chess order and put ones into black cells and zeroes into white cells. It's easy to see that such a matrix is both clear and symmetrical and has sharpenss exactly .
+
+Intuitively it seems that if there exists a matrix with sharpness  there should also exist a matrix with every smaller sharpness. That's correct except only one case -- there doesn't exist a matrix with side 3 and sharpness 3, though there exists a matrix with side 3 and sharpness 5.
+
+Let's show that the claim above is correct for odd *n* ≥ 5. We'll build a matrix with sharpness  as shown above and gradually turn ones into zeroes reducing the sharpness. Cells containing ones in the matrix can be divided into three types.
+
+The first type is the central cell. The number in it can be turned into zero and the matrix won't stop satisfying the required conditions.
+
+The second type is the cells in the central row and the central column (except central cell). Such cells are divided into pairs by the condition of symmetry -- if we turn the number in one of them into zero, we should turn the number in its pair cell into zero as well.
+
+The third type is all the other cells. Such cells are divided into groups of four by the condition of symmetry -- if we turn the number in one of them into zero, we should turn the number in all cells from this group into zero as well.
+
+Now for obtaining the required sharpness of *x* we'll act greedily. Let's turn ones into zeroes in third type cells by four until the current shapness exceeds *x* by less than 4 or there are no third type cells with ones remaining. After that let's turn ones into zeroes in second type cells by pairs while the current sharpness exceeds *x* by at least 2. At this moment the sharpness of our matrix is either *x* or *x* + 1. If it's equal to *x* + 1, let's put a zero into the central cell and obtain a matrix with sharpness *x*. It's easy to check that we'll be able to obtain a matrix with any sharpness acting this way.
+
+Why is this reasoning incorrect for *n* = 3? Because second type cells are absent in the matrix with sharpness 5 obtained from chess coloring. For *n* ≥ 5 this matrix contains cells of all types, which is important for the algorithm above. It's better to find the answers for *x* ≤ 5 by hand but carefully -- for example, a lot of contestants decided that the answer for *x* = 2 is 5 instead of 3.
+
+#### Problem В(div 1)/D(div 2) — Guess That Car!
+
+We need to find such *x* and *y* that the value of 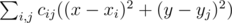 is minimum possible. This expression can be rewritten as 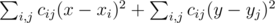. Note that the first part doesn't depend on *y* and the second part doesn't depend on *x*, so we can minimize these parts separately. Here is how to minimize 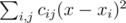, the second part is minimized similarly. As the expression in the brackets doesn't depend on *j*, this part can be rewritten as 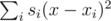, where . Now it's enough to calculate the required value for all possible values of *x* and choose *x* for which this value is the smallest. The optimal value of *y* can be found similarly.
+
+The overall complexity of this solution is *O*(*n*·*m* + *n*2 + *m*2).
+
+As the objective function is convex, other approaches to this problem are possible, for example, ternary search, gradient descent or analytical approach (calculation of derivatives).
+
+The main hero of this problem is [Ra16bit](/profile/Ra16bit "Master Ra16bit").
+
+#### Problem С(div 1)/E(div 2) — Fragile Bridges
+
+There are a few different ways to solve this problem, the editorial contains one of them.
+
+For any solution the following fact is useful. Suppose the sought path starts on platform *i* and ends on platform *j* (*i* ≤ *j*, if that's not the case, we can reverse the path). Then all bridges between platforms *i* and *j* will be passed through an odd number of times, and all other bridges will be passed through an even number of times.
+
+Let's find the maximum length of a path with its ends on platforms *i* and *j*. To do that, let's find the following auxiliary values for each platform: *left**i* -- the maximum length of a path starting and ending on platform *i* and passing only through bridges to the left of platform *i*; *right**j* -- similarly for bridges to the right of platform *j*. Also for each bridge define *odd**i* as the largest odd number not larger than *a**i*, and for each platform define *sumOdd**i* as the sum of *odd**j* for all bridges to the left of platform *i*.
+
+Then the maximum length of a path with its ends on platforms *i* and *j* is equal to *left**i* + *right**j* + (*sumOdd**j* - *sumOdd**i*), or, which is the same, (*right**j* + *sumOdd**j*) + (*left**i* - *sumOdd**i*).
+
+Now we can find the pair (*i*, *j*) for which this value is the largest in linear time. Let's loop over *j*. From the formula it's obvious that we should find such *i* ≤ *j* that (*left**i* - *sum**Odd**i*) is the largest. If we loop over *j* from 1 to *n*, we can maintain the largest value of this expression for all *i* ≤ *j* and recalculate it when moving to the next *j*, comparing (*left**j* - *sumOdd**j*) with the current maximum and possibly updating this maximum. This way for each *j* we have to check only one value of *i* and not all *i* ≤ *j*.
+
+The last thing to show is how to find all *left**i* quickly (all *right**j* can be found similarly). Clearly *left*1 = 0, then we'll calculate *left**i* using *left**i* - 1. Note that when *a**i* - 1 = 1, we have *left**i* = 0 as after passing the bridge to platform (*i* - 1) this bridge will collapse and it will be impossible to return to platform *i*. If *a**i* - 1 > 1, then *left**i* = *left**i* - 1 + *even**i* - 1, where *even**i* - 1 is the largest even number not larger than *a**i* - 1. Indeed, we can move to platform (*i* - 1), then move along the path corresponding to *left**i* - 1, and then move along the bridge between platforms (*i* - 1) and *i* until the limit on the number of transitions is less than 2 (finishing on platform *i*).
+
+The overall complexity of this solution is *O*(*n*).
+
+#### Problem D(div 1) — Brand New Problem
+
+The first solution coming to mind is dynamic programming *f*[*i*][*j*] = (the smallest possible number of inversions to the moment if among the first *j* words of the archive problem we've found a permutation of words included in bitmask *i*). In this solution parameter *j* varies from 0 to 500000, parameter *i* varies from 0 to 215 - 1 and calculation of each value is possible in *O*(1) (we are either using the current word in the subsequence or not). That's too much.
+
+Let's make use of a standard technique: make the value of DP a new parameter and make one of the existing parameters the value of DP. Not for every DP this is possible, but at least it's possible for this one :)
+
+It's clear that with a fixed subset of words and a fixed number of inversions it's optimal to choose the first occurrences of these words giving this number of inversions. Let *f*[*i*][*j*] = (the smallest number *z* such that among first *z* words of the archive problem there exists a permutation of words from bitmask *i* containing exactly *j* inversions). The basis of this DP is *f*[0][0] = 0, *f*[0][*j*] = ∞ for *j* > 0. Recalculation of values happens in the following way: loop over a word *q* from the bitmask *i* which was the last in the permutation. With the knowledge of this word and the number of inversions *j* it's easy to find how many inversions *j*' there were without this word — that's *j* minus the number of words in the mask which appeared later in Lesha's problem than word *q*. Let *p* = *f*[*i*^(1«*q*)][*j*']. Then we should consider *p*2 equal to the position of the next occurrence of word *q* after position *p* as a possible value for *f*[*i*][*j*]. To find *p*2 quickly we should fill an array *next*[500010][15] so that *next*[*i*][*j*] = (the smallest position *k* > *i* such that the *k*-th word in the archive problem equals the *j*-th word in Lesha's problem) for each archive problem in advance. This array can be easily filled passing from right to left once.
+
+The total number of operations can be calculated as *m*·(*k*·*n* + 2*n*·*C**n*2·*n*), where *m* is the number of problems in the archive, *k* is the number of words in one archive problem description and *n* is the number of words in Lesha's problem description. Under the given constraints that is about 200 million operations, and the author's solutions (including a Java solution) worked for less than 2 seconds. The time limit was set with a margin -- 5 seconds.
+
+The main heroes of problems D(div 1) and B(div 2) are [Chmel_Tolstiy](/profile/Chmel_Tolstiy "Grandmaster Chmel_Tolstiy") and [ivan.metelsky](/profile/ivan.metelsky "Grandmaster ivan.metelsky").
+
+#### Problem E(div 1) — Thoroughly Bureaucratic Organization
+
+Let's imagine that we have a magic function *maxN*(*m*, *k*) that returns, given *m* and *k*, the largest value of *n* such that it's possible to solve the problem for *n* people and *m* empty lines in the form using *k* requests. Then we'll be able to use binary search on the answer -- the number of requests *k*.
+
+Suppose we've made *k* requests. Let's match a string of length *k* to each person, where the *i*-th character is equal to 1 if this person is mentioned in the *i*-th request and 0 otherwise. Note that we'll be able to determine the exact appointment date for each person if and only if all *n* strings of length *k* are pairwise distinct. Indeed, if two persons' strings are the same, their appointment dates could be exchanged and the responses to the requests wouldn't have changed. If all strings are distinct, for each date we may find the person appointed for this date looking at the set of requests with responses containing this date and finding the person mentioned in the same set of requests.
+
+The constraint on *m* empty lines in the form means that each of *k* positions in the strings should contain no more than *m* ones in all *n* strings overall. Thus function *maxN*(*m*, *k*) should return the maximum size of a set of distinct *k*-bit strings meeting this condition. Let's make this restriction weaker: we'll search for a set such that the total number of ones in all *n* strings doesn't exceed *k*·*m*. As we'll prove later, the answer won't change.
+
+With this weaker restriction the problem can be solved using a simple greedy strategy. It's obvious that strings with smaller number of ones are better. Let's loop over the number of ones *i* in the string from 0 to *k* and also maintain a variable *t* containing the remaining number of ones (initially it's equal to *k*·*m*). Then at the *i*-th step we can take at most 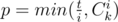 strings containing *i* ones. Let's add *p* to the answer and subtract *p*·*i* from *t*. Note that the values of *C**k**i* should be calculated with care -- they can turn out to be too large, so it's important not to allow overflows.
+
+It can be shown that the overall complexity of this algorithm is at most *O*(*log*2 *n*).
+
+The remaining thing is to prove the claim above. The idea of the proof below belongs to [rng_58](/profile/rng_58 "Grandmaster rng_58") (the author's proof is notably harder).
+
+Let's solve the problem with a greedy algorithm with the *k*·*m* constraint on the total number of ones. The resulting set of strings may not satisfy the restriction of *m* ones for each position. If it doesn't, some of the positions contain more than *m* ones and some contain less than *m* ones. Let's pick any position *X* containing more than *m* ones and any position *Y* containing less than *m* ones. Find all strings containing 1 at *X* and 0 at *Y* (suppose there are *x* such strings) and all strings containing 0 at *X* and 1 at *Y* (suppose there are *y* such strings). It's clear that *x* > *y*. In each of *x* strings we can try to put 0 at *X* and 1 at *Y* -- then the string we obtain will either remain unique in this set or coincide with one of those *y* strings (but only one). As *x* > *y*, for at least one of *x* strings the change above leaves this string unique. Let's take this string and put 0 at *X* and 1 at *Y*. Now position *X* contains one 1 less, and position *Y* contains one 1 more. It means that the total number of "extra" ones in the positions has been decreased (as *Y* still contains no more than *m* ones). Doing this operation for a needed number of times, we'll achieve our goal.
diff --git a/editorials/204.md b/editorials/204.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/4849
+
+### [205A - Little Elephant and Rozdil](/contest/205/problem/A "Codeforces Round 129 (Div. 2)")
+
+This problem was the simplest in the problemset. All you need to do is just to sort all distances (keeping track on all indices). If the first two distances are equal, just output "Still Rozdil", otherwise output the index of the first element of the array.
+
+The complexity is *O*(*NlogN*).
+
+### [205B - Little Elephant and Sorting](/contest/205/problem/B "Codeforces Round 129 (Div. 2)")
+
+In this problem you need to notice the fact (which can be proven, but it is almost obvious) that if you are doing some operation for interval from *l* to *r* (inclusive), *r* must be equal to *n*. This is becuase when you add something to all right part the answer can't be worse. After that you need to go from left to right and greedly add appropriate number of turns.
+
+The complexity is *O*(*N*).
+
+### [205C - Little Elephant and Interval](/contest/205/problem/C "Codeforces Round 129 (Div. 2)")
+
+It is well-known that for such problem you need to write function *F*(*x*) which solves the problem for the interval 0..*x*, and the answer then is *F*(*r*) - *F*(*l* - 1).
+
+Now you need to write *F*(*x*) function. If *x* < 10, then answer is, of course, equal to *x*. Otherwise, let *len* be the length of *x*, *x*' — the integer *x* but without first and last digits, *x**i* — the *i*-th digit of integer *x* (from left to right, starting from 0). Interate through all possible first digit *d* (which is the last at the same time) and through the length *i* of the number. Then if *i* < *len* - 2 or (*i* = *len* - 2 and *d* < *x*0) you need to add 10*i* to the answer. Otherwise, if *i* = *len* - 2 and *d* = *x*0 you need to add *x*' to the answer. Finally, if *i* = *len* - 2 and *d* = *x*0 and *x**len* - 1 ≥ *d* add 1 to the answer.
+
+This problems also can be solved using DP.
+
+### [205D - Little Elephant and Cards](/contest/205/problem/D "Codeforces Round 129 (Div. 2)")
+
+It is nice to use the *map* structure in this problem, but you can solve it without *map* (using sorting and binary serach). Lets iterate through all possible colors that we have and suppose that this currect color is the one that will make our set funny. The minimal number through all this will be the answer. To find the minimal number of turns to make our set funny using current color we need to know two numbers: the number of cards with current color on the front side and the number of cards with the current color on back side (but not at the same time). Let it be integers *a* and *b*. Let *m* = (*n* + 1) / 2 — the minimal number of the same cards required to get the funny set. Then if *a* + *b* < *m* it is impossible to make set funny using current color at all. If *a* ≥ *m* then the answer is 0, otherwise the answer is *m* - *a*.
+
+### [205E - Little Elephant and Furik and Rubik](/contest/205/problem/E "Codeforces Round 129 (Div. 2)")
+
+This problem is to find the expected value. Important fact here is the linearity of the expected value. This means that we can for each element of the first strings find the probability that exactly this element will me matched with some other (but, of course, equal) from the second string. The answer will be the sum of all such probabilities.
+
+Let the current character of the first string be the *i*-th character (1-based numeration). Firstly we try to solve problem in *O*(*N*2) time. Namely, as it was said above, we need to find the number of such pairs of substrings that *i*-th character (which is on probably some other position in substring) is the same as the corresponding character of the second substring. Iterate through all *j* (*j* ≤ *i*) such that *A**i* = *B**j*. The number of such pairs of substrings that have match in that characters is *j*(*n* - *i* + 1) (considering 1-based numeration). This is *O*(*N*2). And because we need to find the sum of such values for all possible *j*, we can rewrite it as *S**i*(*n* - *i* + 1), where *S**i* equals to the sum of all integers *j* (*j* ≤ *i*) that *A**i* = *B**i*. Array *S* can be simply computed in a linear time. Analogically you should process all indices to the right from *i*.
+
+After we know the number of pairs of substrings with the match with the *i*-th character (let it be *count*), the probability is *count* / *total*, where *total* is the total number of pair of substrings (it can be found by loop or with some simple formula).
+
+The comlexity is *O*(*N*).
+
+### [204D - Little Elephant and Retro Strings](/contest/204/problem/D "Codeforces Round 129 (Div. 1)")
+
+Firstly we should solve following subproblem: for each prefix find the number of it's fillings such that there is no consecutive block of *k* characters *B*. Let it be *F*(*x*), where *x* is the index in of the last character if the prefix. Assing *F*(*x*) = *F*(*x* - 1) * *cnt*, where *cnt* = 2 if *S**x* = 'X' and 1 otherwise. After such assing there may be some bad filling included to *F*(*x*). Since we suppouse that *F*(*x* - 1) is caclulated correctly, all bad filling must contain blocks of *k* charcters *B* only at the end of the prefix (they may be included only if substring *S**x* - *k* + 1..*x* doesn't contain characters *W* and character *S**x* - *k* is not *B*). So, if it's possible, we must subtract from *F*(*x*) value *F*(*x* - *k* - 1), because it's exactly the number of bad fillings.
+
+With the same DP you should you calc the same values for suffixes (but this time changing *B* by *W* and vice versa).
+
+Now we should carefully calculate the result in such way that now repeatings occur. Let iterate (from right to left) through all possible positions of the first blocks of *k* characters *B* (this means that we suppose that no block occur to the left). Using our DP we can simply find the number of fillings of all characters to the left from that block in such way that no another blocks of *k* characters *B* occur. Considering *O*(*N*2) solutions, we can iterate through all possible indexes of the begging of the last block of *k* characters *W* (again we suppose that this blocks must be the last and no another may occur to the right) and agin using our DP count the number of fillings to the right. We don't care what is between that blocks, so we just multiply answer by 2^(the number of characters *X* between blocks). But, since we are going from right to the left, we can just keep tracking on all possible last blocks and get *O*(*N*) solution.
+
+### [204E - Little Elephant and Strings](/contest/204/problem/E "Codeforces Round 129 (Div. 1)")
+
+To solve this problems we can use suffix array. More information about suffix arrays you can find in the Internet.
+
+Firstly, concatenate all strings into the one separating consecutive strings by some unique characters (it was also useful to not use strings, but arrays of integers). For example, three strings *abc*, *a*, *ab* may be concatenated in the following way: *abc*#*a*@*ab*. Now we should build suffix array using this total string, this allows to us to sort all cyclic shifts of the string. After that each cyclic shift will either begin with additional character or the character from the input strings.
+
+Notice now that to find the result we need to find for each cyclic shift (begging of which doesn't contain additional character) the largest size of it's prefix such that this prefix is substring of at least *k* different input strings. This value can be found by binary search, but for this we need some function *F*(*x*, *len*) which can answer the questions: how many input strings contain prefix of size *len* of *x* cyclic shift as a substring.
+
+How to make *F*(*x*, *len*)? Look at all cyclic shifts, prefix of size *len* of which is equal to preifx of size *len* of *x*-th shift. Since all shifts are sorted lexicoraphically, this set of shifts can be represented as integral [*l*;*r*] of indices of shifts (1 ≤ *l* ≤ *x* ≤ *r*). How to find *l* and *r*? For each pair of consecutive shifts we can find it's greatest common prefix (using properties of suffix array). Than *l* and *r* can be found using RMQ. For *l* we need to know the rigthmost pair of shift (but to the left from *x*) that their greatest common prefix is less than *len*. Analogically we can find *r*. After that we have interval [*l*;*r*] and we need to find the number of different input strings that belongs to the shifts from *l*-th to *r*-th (actually, we need to find the number of different integer on interval). But, notice that we dont need the exactly number of different integers, we need to know just it is at least *k* or not. So let *L*[*i*] equals to the greatest *j* (*j* ≤ *i*) such that the number of different integers on interval [*j*;*i*] is equal to *k*. Then if *L*[*r*] ≥ *l*, obiously, interval [*l*;*r*] will also contains at least *k* different. So *F*(*x*, *len*) is done.
+
+The only thing to done is to fill array *L*. This is pretty simple using *set* (but it is possible without it but using RMQ). We will go from left to righ at keep the indices of the last (the rightmost) *k* different integers in the *set*. If some integer comes, then (if it was earlier) we need to erase this previous index from set (if it was still in) and insert new current. While the size of set is greater than *k*, we should erase the minimal number from it. Then if in some position *i* the size of the set (after above changings) is equal to *k*, than *L*[*i*] is equal to the minimal number in set.
+
+Since we *O*(*N*) times use binary search, and function *F*(*x*, *len*) works in *O*(*logN*) time, the total complexity is *O*(*Nlog*2*N*).
diff --git a/editorials/205.md b/editorials/205.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/4849
+
+### [205A - Little Elephant and Rozdil](/contest/205/problem/A "Codeforces Round 129 (Div. 2)")
+
+This problem was the simplest in the problemset. All you need to do is just to sort all distances (keeping track on all indices). If the first two distances are equal, just output "Still Rozdil", otherwise output the index of the first element of the array.
+
+The complexity is *O*(*NlogN*).
+
+### [205B - Little Elephant and Sorting](/contest/205/problem/B "Codeforces Round 129 (Div. 2)")
+
+In this problem you need to notice the fact (which can be proven, but it is almost obvious) that if you are doing some operation for interval from *l* to *r* (inclusive), *r* must be equal to *n*. This is becuase when you add something to all right part the answer can't be worse. After that you need to go from left to right and greedly add appropriate number of turns.
+
+The complexity is *O*(*N*).
+
+### [205C - Little Elephant and Interval](/contest/205/problem/C "Codeforces Round 129 (Div. 2)")
+
+It is well-known that for such problem you need to write function *F*(*x*) which solves the problem for the interval 0..*x*, and the answer then is *F*(*r*) - *F*(*l* - 1).
+
+Now you need to write *F*(*x*) function. If *x* < 10, then answer is, of course, equal to *x*. Otherwise, let *len* be the length of *x*, *x*' — the integer *x* but without first and last digits, *x**i* — the *i*-th digit of integer *x* (from left to right, starting from 0). Interate through all possible first digit *d* (which is the last at the same time) and through the length *i* of the number. Then if *i* < *len* - 2 or (*i* = *len* - 2 and *d* < *x*0) you need to add 10*i* to the answer. Otherwise, if *i* = *len* - 2 and *d* = *x*0 you need to add *x*' to the answer. Finally, if *i* = *len* - 2 and *d* = *x*0 and *x**len* - 1 ≥ *d* add 1 to the answer.
+
+This problems also can be solved using DP.
+
+### [205D - Little Elephant and Cards](/contest/205/problem/D "Codeforces Round 129 (Div. 2)")
+
+It is nice to use the *map* structure in this problem, but you can solve it without *map* (using sorting and binary serach). Lets iterate through all possible colors that we have and suppose that this currect color is the one that will make our set funny. The minimal number through all this will be the answer. To find the minimal number of turns to make our set funny using current color we need to know two numbers: the number of cards with current color on the front side and the number of cards with the current color on back side (but not at the same time). Let it be integers *a* and *b*. Let *m* = (*n* + 1) / 2 — the minimal number of the same cards required to get the funny set. Then if *a* + *b* < *m* it is impossible to make set funny using current color at all. If *a* ≥ *m* then the answer is 0, otherwise the answer is *m* - *a*.
+
+### [205E - Little Elephant and Furik and Rubik](/contest/205/problem/E "Codeforces Round 129 (Div. 2)")
+
+This problem is to find the expected value. Important fact here is the linearity of the expected value. This means that we can for each element of the first strings find the probability that exactly this element will me matched with some other (but, of course, equal) from the second string. The answer will be the sum of all such probabilities.
+
+Let the current character of the first string be the *i*-th character (1-based numeration). Firstly we try to solve problem in *O*(*N*2) time. Namely, as it was said above, we need to find the number of such pairs of substrings that *i*-th character (which is on probably some other position in substring) is the same as the corresponding character of the second substring. Iterate through all *j* (*j* ≤ *i*) such that *A**i* = *B**j*. The number of such pairs of substrings that have match in that characters is *j*(*n* - *i* + 1) (considering 1-based numeration). This is *O*(*N*2). And because we need to find the sum of such values for all possible *j*, we can rewrite it as *S**i*(*n* - *i* + 1), where *S**i* equals to the sum of all integers *j* (*j* ≤ *i*) that *A**i* = *B**i*. Array *S* can be simply computed in a linear time. Analogically you should process all indices to the right from *i*.
+
+After we know the number of pairs of substrings with the match with the *i*-th character (let it be *count*), the probability is *count* / *total*, where *total* is the total number of pair of substrings (it can be found by loop or with some simple formula).
+
+The comlexity is *O*(*N*).
+
+### [204D - Little Elephant and Retro Strings](/contest/204/problem/D "Codeforces Round 129 (Div. 1)")
+
+Firstly we should solve following subproblem: for each prefix find the number of it's fillings such that there is no consecutive block of *k* characters *B*. Let it be *F*(*x*), where *x* is the index in of the last character if the prefix. Assing *F*(*x*) = *F*(*x* - 1) * *cnt*, where *cnt* = 2 if *S**x* = 'X' and 1 otherwise. After such assing there may be some bad filling included to *F*(*x*). Since we suppouse that *F*(*x* - 1) is caclulated correctly, all bad filling must contain blocks of *k* charcters *B* only at the end of the prefix (they may be included only if substring *S**x* - *k* + 1..*x* doesn't contain characters *W* and character *S**x* - *k* is not *B*). So, if it's possible, we must subtract from *F*(*x*) value *F*(*x* - *k* - 1), because it's exactly the number of bad fillings.
+
+With the same DP you should you calc the same values for suffixes (but this time changing *B* by *W* and vice versa).
+
+Now we should carefully calculate the result in such way that now repeatings occur. Let iterate (from right to left) through all possible positions of the first blocks of *k* characters *B* (this means that we suppose that no block occur to the left). Using our DP we can simply find the number of fillings of all characters to the left from that block in such way that no another blocks of *k* characters *B* occur. Considering *O*(*N*2) solutions, we can iterate through all possible indexes of the begging of the last block of *k* characters *W* (again we suppose that this blocks must be the last and no another may occur to the right) and agin using our DP count the number of fillings to the right. We don't care what is between that blocks, so we just multiply answer by 2^(the number of characters *X* between blocks). But, since we are going from right to the left, we can just keep tracking on all possible last blocks and get *O*(*N*) solution.
+
+### [204E - Little Elephant and Strings](/contest/204/problem/E "Codeforces Round 129 (Div. 1)")
+
+To solve this problems we can use suffix array. More information about suffix arrays you can find in the Internet.
+
+Firstly, concatenate all strings into the one separating consecutive strings by some unique characters (it was also useful to not use strings, but arrays of integers). For example, three strings *abc*, *a*, *ab* may be concatenated in the following way: *abc*#*a*@*ab*. Now we should build suffix array using this total string, this allows to us to sort all cyclic shifts of the string. After that each cyclic shift will either begin with additional character or the character from the input strings.
+
+Notice now that to find the result we need to find for each cyclic shift (begging of which doesn't contain additional character) the largest size of it's prefix such that this prefix is substring of at least *k* different input strings. This value can be found by binary search, but for this we need some function *F*(*x*, *len*) which can answer the questions: how many input strings contain prefix of size *len* of *x* cyclic shift as a substring.
+
+How to make *F*(*x*, *len*)? Look at all cyclic shifts, prefix of size *len* of which is equal to preifx of size *len* of *x*-th shift. Since all shifts are sorted lexicoraphically, this set of shifts can be represented as integral [*l*;*r*] of indices of shifts (1 ≤ *l* ≤ *x* ≤ *r*). How to find *l* and *r*? For each pair of consecutive shifts we can find it's greatest common prefix (using properties of suffix array). Than *l* and *r* can be found using RMQ. For *l* we need to know the rigthmost pair of shift (but to the left from *x*) that their greatest common prefix is less than *len*. Analogically we can find *r*. After that we have interval [*l*;*r*] and we need to find the number of different input strings that belongs to the shifts from *l*-th to *r*-th (actually, we need to find the number of different integer on interval). But, notice that we dont need the exactly number of different integers, we need to know just it is at least *k* or not. So let *L*[*i*] equals to the greatest *j* (*j* ≤ *i*) such that the number of different integers on interval [*j*;*i*] is equal to *k*. Then if *L*[*r*] ≥ *l*, obiously, interval [*l*;*r*] will also contains at least *k* different. So *F*(*x*, *len*) is done.
+
+The only thing to done is to fill array *L*. This is pretty simple using *set* (but it is possible without it but using RMQ). We will go from left to righ at keep the indices of the last (the rightmost) *k* different integers in the *set*. If some integer comes, then (if it was earlier) we need to erase this previous index from set (if it was still in) and insert new current. While the size of set is greater than *k*, we should erase the minimal number from it. Then if in some position *i* the size of the set (after above changings) is equal to *k*, than *L*[*i*] is equal to the minimal number in set.
+
+Since we *O*(*N*) times use binary search, and function *F*(*x*, *len*) works in *O*(*logN*) time, the total complexity is *O*(*Nlog*2*N*).
diff --git a/editorials/208.md b/editorials/208.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/4930
+
+First, arrange the problems in order of their difficulties. The authors assume such order: A, D, B, C, E. Now make the tutorial of problems in their order in the contest.
+
+[208A - Dubstep](/contest/208/problem/A "Codeforces Round 130 (Div. 2)")
+
+This problem was technical. First, you should erase all occurrences or word WUB in the beginning and in the end of the string. And then parse the remaining string separating tokens by word WUB. Empty tokens should be also erased. Given string was rather small, you can realize the algorithm in any way.
+
+[208B - Solitaire](/contest/208/problem/B "Codeforces Round 130 (Div. 2)")
+
+In this problem you could write breadth-first search. The state is the following four elements: number of remaining piles and three strings — three rightmost cards on the top of three rightmost piles. We have two transitions in general case. We can take the rightmost pile and shift it left by 1 or 3 on another pile. If the number of remaining piles become 0 at some moment print *YES*, else print *NO*. The number of states is *O*(*N*4), the number of transitions 2, so the complexity of solution is *O*(*N*4).
+
+[208C - Police Station](/contest/208/problem/C "Codeforces Round 130 (Div. 2)")
+
+In this problem we will find the sought quantity for every vertex and find the maximum value. For this for every vertex *v* count two values: *cnt*1[*v*] and *cnt*2[*v*] — number of shortest paths from vertex *v* to *n*-th and 1-st vertices respectively. For this you should construct graph of shortest paths and use dynamic programming on the constructed graph (because the new graph will be acyclic). To construct the graph of shortest paths you should leave only useful edges in original graph. It can be done, for example, using breadth-first search launched from vertices 1 and *n* respectively.
+
+After values *cnt*1[*v*] and *cnt*2[*v*] are found consider every useful edge (*u*, *v*) and add to vertices *u* and *v* value (*cnt*2[*u*] * *cnt*1[*v*]) / (*cnt*2[*n*–1]), which is the contribution of this edge in the sought quantity for the vertices *u* and *v*. Note that value (*cnt*2[*n*–1]) is the number of shortest paths between 1 and *n*. All said values can be found in time *O*(*N* + *M*). The complexity of solution is *O*(*N* + *M*).
+
+[208D - Prizes, Prizes, more Prizes](/contest/208/problem/D "Codeforces Round 130 (Div. 2)")
+
+In this problem every time you get points you should greedily get as much prizes as you can. For this, consider every prize from the most expensive and try to get as much as you can. If we have *cnt* points and the prize costs *p* points you can get  prizes. So we get simple solution with complexity *O*(5 * *N*).
+
+[208E - Blood Cousins](/contest/208/problem/E "Codeforces Round 130 (Div. 2)")
+
+In this problem you have some set of rooted down- oriented trees. First, launch depth-first search from every root of every tree and renumber the vertices. Denote size of subtree of vertex *v* as *cnt*[*v*]. In this way all descendants of vertex *v* (including *v*) wiil have numbers [*v*;*v* + *cnt*[*v*]–1].
+
+Then we wiil handle requests (*v*, *p*) in their order. First, go up from vertex *v* on *p* steps to the root using binary rise like in LCA algorithm. Denote this vertex *u*. If *u* doesn’t exist print 0 else you should count the number of descendants of vertex *u* on the same height as vertex *v*.
+
+For this write all numbers of vertices for every height in some array. Then you should determine which of these vertices are descendants of *u*. You can do it using binary search in corresponding array. Find the segment of appropriate vertices (because we know the numbers of all descendants of *u*), find the amount of them, subtract one (vertex *v*), and this is the answer. The complexity of the solution is *O*(*Nlog*(*N*)).
diff --git a/editorials/213.md b/editorials/213.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/4982
+
+Sorry for my poor English, this blog will be corrected soon.
+
+### [214A - System of Equations](/contest/214/problem/A "Codeforces Round 131 (Div. 2)")
+
+Solution for this problem — just go through the possible pairs of numbers and check them for correctness. We can do that in any way.
+
+### [214B - Hometask](/contest/214/problem/B "Codeforces Round 131 (Div. 2)")
+
+Nuber is divisible by 2,3,5 only if sum of the digits is divisible by 3 and last digit is 0, so if we havent 0 in our set answer is -1, otherwise solution exists(we can return 0 as solution). A further solution — analysis of the cases.
+Lets sort all didgits in nonincreasing order. If sum of all digits is divisible by 3 — answer is our set of digits(without spaces ofcourse :) ). If modulo equals 1 — we must delete minimum digit from out set with modulo after division by 3 equals 1, if we haven't such we must delete 2 minimal digits with modulo after division by 3 equals 2. If we have modulo equals 2 — we have identical case.
+Also we must remember that we cannot use leading zeros. In case when we have more then one 0 and no another digit we must print only one zero.
+
+### [213A - Game](/contest/213/problem/A "Codeforces Round 131 (Div. 1)")
+
+Solution — Greedy.
+Lets our computers settled on circle, and moves (1->2, 2->3, 3->1) will be steps "forward", and moves (1->3,3->2,2->1) will steps "back".
+
+Note that "back" moves is not optimal, as we can make two moves "forward" that is identical in time. We will look over all starts. Further, we will go by circle while we not complited all game. For every level we will remember number ne[i] — count of another level that "direct" need for it. We will complited levels with ne[i]=0 and update all ne[i] that we must. It can be implemented with O(n^3) time.
+
+### [213B - Numbers](/contest/213/problem/B "Codeforces Round 131 (Div. 1)")
+
+Solution — dynamic programming.
+Look over for length of the number that we will build. Further, we will use DP f(len,i) — how many numbers with length len we can make with digits i..9.
+Recount:
+- f(len,0) = sum(f(len-i,1)*C(len-1,i), i=a[0]..len);
+- f(len,j) = sum(f(len-i,j+1)*C(len,i), i=a[j]..len), 0<j<9;
+- f(len,9) = 1, если len>=a[9], 0 если len<a[9].
+C(n,k) — binomial coefficient.
+
+### [213C - Relay Race](/contest/213/problem/C "Codeforces Round 131 (Div. 1)")
+
+Solution — dynamic programming.
+Note, that we can make 2 pathes form cell (1,1) to cell (n,n).
+Note, that after each move our cells will be located on the same diagonal.
+We will solve the problem with DP f(d,i1,i2), d — diagonal number, i1 — 1st coordinate 1st path, i2 — 1st coordinate 2nd path. It is clear that we can calculate 2nd coordinate when we know number of the diagonal and 1st coordinate. Recount — obvious, we make all 4 transition, and if pathes are intersected in temporary point, we add value of the cell only one, otherwise we add both values of the cells. We can imlement this solution with O(n^2) memory if we will rewrite array of DP after increasing of diagonal number. Also we must remember that answer can be lower then 0.
+
+### [213D - Stars](/contest/213/problem/D "Codeforces Round 131 (Div. 1)")
+
+I present solution as few pictures:
+<https://get.google.com/albumarchive/pwa/115317317397602031319/Solutions131>
+
+Implementation.
+We have only one difficult moment — how to count coordinates? We can calculate them from regular pentagon, all that you need, you can read [there](https://en.wikipedia.org/wiki/Pentagon).
+
+### [213E - Two Permutations](/contest/213/problem/E "Codeforces Round 131 (Div. 1)")
+
+For given two permutation we will make two another by next transformation: New_A[A[i]] = i, where New_A — news permutation, A — given permutation. Lets we get two permutation A and B. Now our problem is next: how many sub-arrays of length n are equals to firs permutation. Two arrays will be equal if after swaping every element with its number in sorted array obtained arrays will be element-wise equal.
+Further solution hashes, but we will use not only modulo 2^64, we will use some big modulos, but they must be smaller then 2^32-1.
+Lets step[i] = 1000003^i.
+Lets F(A) = num[1]*step[1] + num[2]*step[2] + ... + num[n]*step[n], where num[i] — number of the element A[i] in sorted array.
+If we will compare arrays, we can use this function. But it can be very big, so we will count it by modulos.
+So now our problem is to calculate F function to every subarray. Lets look what will change after adding/deleting some elent from set: some element from num array willnot change, and some will become grater after adding, and become lower after deleting. So we must use some interval-tree to recount our F function. We need to know sum of step[i] on some interval of added numbers and count of elements on some interval. Uses this information we can simply recount out function. Also we must remember that after adding element with coeficinet step[i], where i>n and deleting some previos element our function will become grater that we need. So we will multiple hash of first array by 1000003 to avoid this issue.
diff --git a/editorials/214.md b/editorials/214.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/4982
+
+Sorry for my poor English, this blog will be corrected soon.
+
+### [214A - System of Equations](/contest/214/problem/A "Codeforces Round 131 (Div. 2)")
+
+Solution for this problem — just go through the possible pairs of numbers and check them for correctness. We can do that in any way.
+
+### [214B - Hometask](/contest/214/problem/B "Codeforces Round 131 (Div. 2)")
+
+Nuber is divisible by 2,3,5 only if sum of the digits is divisible by 3 and last digit is 0, so if we havent 0 in our set answer is -1, otherwise solution exists(we can return 0 as solution). A further solution — analysis of the cases.
+Lets sort all didgits in nonincreasing order. If sum of all digits is divisible by 3 — answer is our set of digits(without spaces ofcourse :) ). If modulo equals 1 — we must delete minimum digit from out set with modulo after division by 3 equals 1, if we haven't such we must delete 2 minimal digits with modulo after division by 3 equals 2. If we have modulo equals 2 — we have identical case.
+Also we must remember that we cannot use leading zeros. In case when we have more then one 0 and no another digit we must print only one zero.
+
+### [213A - Game](/contest/213/problem/A "Codeforces Round 131 (Div. 1)")
+
+Solution — Greedy.
+Lets our computers settled on circle, and moves (1->2, 2->3, 3->1) will be steps "forward", and moves (1->3,3->2,2->1) will steps "back".
+
+Note that "back" moves is not optimal, as we can make two moves "forward" that is identical in time. We will look over all starts. Further, we will go by circle while we not complited all game. For every level we will remember number ne[i] — count of another level that "direct" need for it. We will complited levels with ne[i]=0 and update all ne[i] that we must. It can be implemented with O(n^3) time.
+
+### [213B - Numbers](/contest/213/problem/B "Codeforces Round 131 (Div. 1)")
+
+Solution — dynamic programming.
+Look over for length of the number that we will build. Further, we will use DP f(len,i) — how many numbers with length len we can make with digits i..9.
+Recount:
+- f(len,0) = sum(f(len-i,1)*C(len-1,i), i=a[0]..len);
+- f(len,j) = sum(f(len-i,j+1)*C(len,i), i=a[j]..len), 0<j<9;
+- f(len,9) = 1, если len>=a[9], 0 если len<a[9].
+C(n,k) — binomial coefficient.
+
+### [213C - Relay Race](/contest/213/problem/C "Codeforces Round 131 (Div. 1)")
+
+Solution — dynamic programming.
+Note, that we can make 2 pathes form cell (1,1) to cell (n,n).
+Note, that after each move our cells will be located on the same diagonal.
+We will solve the problem with DP f(d,i1,i2), d — diagonal number, i1 — 1st coordinate 1st path, i2 — 1st coordinate 2nd path. It is clear that we can calculate 2nd coordinate when we know number of the diagonal and 1st coordinate. Recount — obvious, we make all 4 transition, and if pathes are intersected in temporary point, we add value of the cell only one, otherwise we add both values of the cells. We can imlement this solution with O(n^2) memory if we will rewrite array of DP after increasing of diagonal number. Also we must remember that answer can be lower then 0.
+
+### [213D - Stars](/contest/213/problem/D "Codeforces Round 131 (Div. 1)")
+
+I present solution as few pictures:
+<https://get.google.com/albumarchive/pwa/115317317397602031319/Solutions131>
+
+Implementation.
+We have only one difficult moment — how to count coordinates? We can calculate them from regular pentagon, all that you need, you can read [there](https://en.wikipedia.org/wiki/Pentagon).
+
+### [213E - Two Permutations](/contest/213/problem/E "Codeforces Round 131 (Div. 1)")
+
+For given two permutation we will make two another by next transformation: New_A[A[i]] = i, where New_A — news permutation, A — given permutation. Lets we get two permutation A and B. Now our problem is next: how many sub-arrays of length n are equals to firs permutation. Two arrays will be equal if after swaping every element with its number in sorted array obtained arrays will be element-wise equal.
+Further solution hashes, but we will use not only modulo 2^64, we will use some big modulos, but they must be smaller then 2^32-1.
+Lets step[i] = 1000003^i.
+Lets F(A) = num[1]*step[1] + num[2]*step[2] + ... + num[n]*step[n], where num[i] — number of the element A[i] in sorted array.
+If we will compare arrays, we can use this function. But it can be very big, so we will count it by modulos.
+So now our problem is to calculate F function to every subarray. Lets look what will change after adding/deleting some elent from set: some element from num array willnot change, and some will become grater after adding, and become lower after deleting. So we must use some interval-tree to recount our F function. We need to know sum of step[i] on some interval of added numbers and count of elements on some interval. Uses this information we can simply recount out function. Also we must remember that after adding element with coeficinet step[i], where i>n and deleting some previos element our function will become grater that we need. So we will multiple hash of first array by 1000003 to avoid this issue.
diff --git a/editorials/215.md b/editorials/215.md
@@ -0,0 +1,13 @@
+Source: https://codeforces.com/blog/entry/5034
+
+Hi! I'll try to explain solution of problem E on Codeforces Round #132.
+
+Ok, in the very beginning let's try solve some other task. We'll find the number of such integers in the interval (2*k*, *x*], where 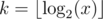. And someone can see that *x* has length *len* = *k* + 1.
+
+Then we should try blocks of {0, 1} to be the same part of periodical number. These blocks have length, which is divisor of *len*.
+
+Let's calculate number *g*[*i*] of such blocks of length *i*, where *i* is some divisor of *len*. We get *i* of first(from the left side) bits of number *x* and name it as *t* = *x* >> (*len* - *i*), e.g. if *x* = 100110002, and *i* = 4 then *t* = 10012, if *i* = 2 then *t* = 102. Firstly, we should check block *t*, it needs for example to check number *p* = *ttttt*... repeated  times, it can be calculated in a loop *p* = *p* << *i* + *t*. It's clear if *p* ≤ *x*, then we should take into account this block *g*[*i*] = 1. It's clear that every correct block less or equal than *t*, and it should begin from 1 (because of periodical number is without leading zeroes). Case of equality we took. And we should add to *g*[*i*] difference between *t* and 2*i* = 10000...2 i-1 zeroes, *g*[*i*] = *g*[*i*] + *t* - (1 << (*i* - 1)). It seems that all is ready and we can sum *g*[*i*] for every divisor of *len* and not equal *len*, but we cant. Because some cases we count more than once, e.g. *x* = 101011002, *i* = 4, *g*[4] = 1 + (10102 - 10002) = 3 we considered cases of blocks 1000, 1001, 1010, and when we count for *i* = 2,*g*[2] = 1 + (102 - 102) = 1, we considered one case 10, but 1010 is obtained from 10 repeated two times. But we can easily escape these problems, for this we should substract from *g*[*i*] all *g*[*j*] where *j* < *i* and *j* divides *i*.
+
+Some note. We get some DP problem, we calculate *g*[*i*] from *i* = 1 to the most divisor of *len* which is not equal to *len*, and update its value by substracting all g[j].
+
+Let us summarize some ideas, we can count number of periodical numbers in the interval (2*k*, *x*], by going through divisors of *len* and calculating *g*[*i*], and then we return sum of *g*[*i*] where *i* < *len* and *i* divides *len*. One can see that 2*k* cant be periodical. Given this fact we will calculate this value for *x* = 2*k* - 1, then 2*k* - 1 - 1 and so on.In the end we get *x* = 1, and we get set of non-intersecting intervals, counting on each of them and sum up it we get answer. It can be done recursively. My [code](http://ideone.com/96ZjG) in C++, when I also precalculated divisors of each number from 1 to 60. I'm waiting for your replies and some criticism.
diff --git a/editorials/216.md b/editorials/216.md
@@ -0,0 +1,41 @@
+Source: https://codeforces.com/blog/entry/5066
+
+**A.** For solving this problem you might find some formula like
+*res* = *abc* - (*a* - 1)(*b* - 1)(*c* - 1), *res* = *ab* + *bc* + *ca* - *a* - *b* - *c* + 1, or something else.
+Also the problem can be solved in *O*(*a* + *b* + *c*) time — you can move from the top line to the bottom line of hexagon and sum number of tiles in every line.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**B.** You can build some graph where vertices are students and edges are enmities. You should drop some vertices and then paint them in two colors. Any edge should connect vertices of distinct colors and numbers of vertices of every color should be same.
+
+You can see that graph consists chians, cycles and sepatated vertices. Every of that component can be painted in 2 colors except one case: cycles of odd length. So, you should drop one vertex from every odd cycle. After that you can get odd number of vertices. Then you should drop one more vertex (you can chose any of them). The obtained graph can be easily painted in 2 colors in the required manner.
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") , [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**С.** The first solution: analysis of the cases
+1. *k* = 1. For *n* ≤ *m* + 1 3 employees is enough (in most cases). For *n* > *m* + 1 answer is 2. Also, there are only one tricky corner case: for *n* = 2, *m* = 2, *k* = 1 answer is 4.
+2. *k* > 1. If *n* = *m*, answer is 2*k* + 1, otherwise answer is 2*k*.
+For any case it is easy to construct solution, and prove that this solution is optimal.
+
+The second solution: greedy.
+Let's create an array where we will store current number of employees for some number of the first days. Now you should iterate over all days from the first to the *n* + *m*-th and hire employees every time when it needed. You should hire workers if there are less than *k* people in the current day; also you should hire worker if there will be no people tomorrow (thet worker will bring the key to the workers that will work tomorrow).
+This solution works in *O*((*n* + *m*)*k*).
+This solution also works correctly for cases *n* < *m*, but then it has bigger complexity and requires more time.
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") , [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**D.** For every sector you should sort bridges in order of increasing distance from the conter of the web. Now for every sector you should iterate over bridges of the current sector and two adjacent sectors using 3 pointers. During every pass you should carefully calculate number of bad cells. That is all solution.
+
+Solition in , where *m* is total number of bridges.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**E.** Digital root of number is equal to that number modulo *k* - 1 for most cases. It is lie only for digital roots 0 and *k* - 1 — in that cases number modulo *k* - 1 will be 0. But you can get digital root 0 only for numbers like 00...00. Total number of numbers that type you can find using any other way. So, now you can find number of substrings that have some digital root, if you know number of substrings that equals some number modulo *k* - 1.
+
+How to find number of substrings of some modulo? You should iterate over all digits of *s* from the left to the rigth and for every modulo store number of prefixes of that modulo in some array dp[] of size *k*. Let's current position is *i*. Then number of substrings modulo *b* that ends in position *i* equals to number of prefixes leftmost position *i* that have modulo (*x* - *b*)*mod*(*k* - 1), where *x* is modulo of *s*[1... *i*]. I.e. just *dp*[(*x* - *b*)*mod*(*k* - 1)].
+
+To fit into memory limit, you should replace array dp[] by some associative array. For example, std::map from С++ or some hashtable.
+
+So we have solution in *O*(*nz*), where *z* is complexety of access to dp[] ( for std::map and *O*(1) for hashtable).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
diff --git a/editorials/217.md b/editorials/217.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/5285
+
+#### A. Ice Skating
+
+Notice that the existence of a snow drift at the point (*x*, *y*) implies that "if I'm on the horizontal line at *y* then I am certainly able to get to the vertical line at *x*, and vice versa". Thus, the snow drifts are the edges of a bipartite graph between x- and y- coordinates. The number of snow drifts that need to be added to make this (as well as the original) graph connected is the number of its connected components reduced by one.
+
+#### B. Blackboard Fibonacci
+
+If you look at the described process backwards, it resembles the Euclidean algorithm a lot. Indeed, if you rewinded a recording of Bajtek's actions, he always takes the larger out of two numbers (say
+
+Unable to parse markup [type=CF_TEX]
+
+) and replaces them by *a* - *b*, *b*. Since we know one of the final numbers (*r*) we can simply check all numbers between 1 and *r* and run a faster version of Euclid's algorithm (one that replaces *a*, *b* by ) for all possibilities for a total runtime of . This was one of the expected solutions.
+
+However, with some insight, it can be seen that this optimization is in fact not neccessary — we can simply simulate the reverse process as described (replacing *a*, *b* by *a* - *b*, *b*) for all candidates between 1 and *r* and the total runtime of our algorithm will remain . The proof of this fact is left to the reader.
+
+#### C. Formurosa
+
+One of the major difficulties in this problem is finding an easily formulated condition for when Formurosa can be used to distinguish the bacteria. Let Formurosa's digestive process be a function *F*(*s*) that maps binary sequences of length *m* to elements of {0, 1}. It turns out that the condition we seek for can be stated as follows:
+
+*We can distinguish all the bacteria if and only if there exists a sequence *s* of length *m* for which *F*(*s*) ≠ *F*( - *s*), where - *s* is the negation of *s*.*
+
+First, not that if no such sequence exists, then there is no way to distinguish between zero and one. If such a sequence exists, we can pick any two bacteria *a* and *b* and try both ways to substitute them for 0 and 1 in the expression. If the two expressions evaluate to different values, we will determine the exact types of both bacteria. Otherwise, we will be certain that the bacteria are of the same type. Repeating the process for all pairs of bacteria will let us identify all the types (since it is guaranteed that not all bacteria are of the same type).
+
+To determine whether such a sequence *s* exists, dynamic programming over the expression tree of Formurosa can be applied. The model solution keeps track for each subtree *G* of the expression which of the following sequences can be found:
+
+* a sequence *s* such that *G*(*s*) = *G*( - *s*) = 0
+* a sequence *s* such that *G*(*s*) = *G*( - *s*) = 1
+* a sequence *s* such that *G*(*s*) ≠ *G*( - *s*)
+
+#### D. Bitonix' Patrol
+
+*Observation 1.*
+
+Fuel tanks for which capacity gives the same remainder  are equivalent for Bitonix's purposes. Moreover, fuel tanks for which the capacities' remainders  sum to *D* are also equivalent. Out of every group of equivalent tanks, the agency can only leave at most one.
+
+*Observation 2.*
+
+If more than six tanks remain, Bitonix can certainly complete his patrol. Indeed, let us assume that 7 tanks were left undestroyed by the agency. Out of the 128 possible subsets of those tanks, at least two distinct ones, say *A* and *B*, sum up to the same remainders modulo *D*. Thus, if Bitonix moves forward with tanks from *A* - *B* and backwards with tanks from *B* - *A*, he will finish at some station after an actual journey.
+
+Because of observations 1 and 2, it turns out that a simple recursive search suffices to solve the problem. However, because of the large constraints, it may prove necessary to use some optimizations, such as using bitmasks for keeping track of what distances Bitonix can cover.
+
+#### E. Alien DNA
+
+Note that it is easy to determine, looking at only the last mutation, how many letters it adds to the final result. Indeed, if we need to print out the first *k* letters of the sequence, and the last mutation is [*l*, *r*], it suffices to find out the length of the overlap of segments [1, *k*] and [*r* + 1, 2*r* - *l* + 1]. Say that it is *x*. Then, after the next to last mutation, we are only interested in the first *k* - *x* letters of the result — the rest is irrelevant, as it will become "pushed out" by the elements added in the last mutation. Repeating this reasoning going backwards, we shall find out that we can spend linear time adding letters to the result after every mutation, which turns out to be the main idea needed to solve the problem.
+
+For a neat *O*(*n*2 + *k*) implementation of this idea you can check out [ACRush](/profile/ACRush "Grandmaster ACRush")'s solution: [2029369](/contest/217/submission/2029369 "Submission 2029369 by ACRush").
+
+The only other contestant to solve the problem during the competition, [panyuchao](/profile/panyuchao "Candidate Master panyuchao"), used a slightly different approach, based in part on the same idea. Check out his ingenious, astonishingly short 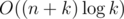 solution here: [2028007](/contest/217/submission/2028007 "Submission 2028007 by panyuchao").
diff --git a/editorials/218.md b/editorials/218.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/5285
+
+#### A. Ice Skating
+
+Notice that the existence of a snow drift at the point (*x*, *y*) implies that "if I'm on the horizontal line at *y* then I am certainly able to get to the vertical line at *x*, and vice versa". Thus, the snow drifts are the edges of a bipartite graph between x- and y- coordinates. The number of snow drifts that need to be added to make this (as well as the original) graph connected is the number of its connected components reduced by one.
+
+#### B. Blackboard Fibonacci
+
+If you look at the described process backwards, it resembles the Euclidean algorithm a lot. Indeed, if you rewinded a recording of Bajtek's actions, he always takes the larger out of two numbers (say
+
+Unable to parse markup [type=CF_TEX]
+
+) and replaces them by *a* - *b*, *b*. Since we know one of the final numbers (*r*) we can simply check all numbers between 1 and *r* and run a faster version of Euclid's algorithm (one that replaces *a*, *b* by ) for all possibilities for a total runtime of . This was one of the expected solutions.
+
+However, with some insight, it can be seen that this optimization is in fact not neccessary — we can simply simulate the reverse process as described (replacing *a*, *b* by *a* - *b*, *b*) for all candidates between 1 and *r* and the total runtime of our algorithm will remain . The proof of this fact is left to the reader.
+
+#### C. Formurosa
+
+One of the major difficulties in this problem is finding an easily formulated condition for when Formurosa can be used to distinguish the bacteria. Let Formurosa's digestive process be a function *F*(*s*) that maps binary sequences of length *m* to elements of {0, 1}. It turns out that the condition we seek for can be stated as follows:
+
+*We can distinguish all the bacteria if and only if there exists a sequence *s* of length *m* for which *F*(*s*) ≠ *F*( - *s*), where - *s* is the negation of *s*.*
+
+First, not that if no such sequence exists, then there is no way to distinguish between zero and one. If such a sequence exists, we can pick any two bacteria *a* and *b* and try both ways to substitute them for 0 and 1 in the expression. If the two expressions evaluate to different values, we will determine the exact types of both bacteria. Otherwise, we will be certain that the bacteria are of the same type. Repeating the process for all pairs of bacteria will let us identify all the types (since it is guaranteed that not all bacteria are of the same type).
+
+To determine whether such a sequence *s* exists, dynamic programming over the expression tree of Formurosa can be applied. The model solution keeps track for each subtree *G* of the expression which of the following sequences can be found:
+
+* a sequence *s* such that *G*(*s*) = *G*( - *s*) = 0
+* a sequence *s* such that *G*(*s*) = *G*( - *s*) = 1
+* a sequence *s* such that *G*(*s*) ≠ *G*( - *s*)
+
+#### D. Bitonix' Patrol
+
+*Observation 1.*
+
+Fuel tanks for which capacity gives the same remainder  are equivalent for Bitonix's purposes. Moreover, fuel tanks for which the capacities' remainders  sum to *D* are also equivalent. Out of every group of equivalent tanks, the agency can only leave at most one.
+
+*Observation 2.*
+
+If more than six tanks remain, Bitonix can certainly complete his patrol. Indeed, let us assume that 7 tanks were left undestroyed by the agency. Out of the 128 possible subsets of those tanks, at least two distinct ones, say *A* and *B*, sum up to the same remainders modulo *D*. Thus, if Bitonix moves forward with tanks from *A* - *B* and backwards with tanks from *B* - *A*, he will finish at some station after an actual journey.
+
+Because of observations 1 and 2, it turns out that a simple recursive search suffices to solve the problem. However, because of the large constraints, it may prove necessary to use some optimizations, such as using bitmasks for keeping track of what distances Bitonix can cover.
+
+#### E. Alien DNA
+
+Note that it is easy to determine, looking at only the last mutation, how many letters it adds to the final result. Indeed, if we need to print out the first *k* letters of the sequence, and the last mutation is [*l*, *r*], it suffices to find out the length of the overlap of segments [1, *k*] and [*r* + 1, 2*r* - *l* + 1]. Say that it is *x*. Then, after the next to last mutation, we are only interested in the first *k* - *x* letters of the result — the rest is irrelevant, as it will become "pushed out" by the elements added in the last mutation. Repeating this reasoning going backwards, we shall find out that we can spend linear time adding letters to the result after every mutation, which turns out to be the main idea needed to solve the problem.
+
+For a neat *O*(*n*2 + *k*) implementation of this idea you can check out [ACRush](/profile/ACRush "Grandmaster ACRush")'s solution: [2029369](/contest/217/submission/2029369 "Submission 2029369 by ACRush").
+
+The only other contestant to solve the problem during the competition, [panyuchao](/profile/panyuchao "Candidate Master panyuchao"), used a slightly different approach, based in part on the same idea. Check out his ingenious, astonishingly short 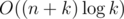 solution here: [2028007](/contest/217/submission/2028007 "Submission 2028007 by panyuchao").
diff --git a/editorials/219.md b/editorials/219.md
@@ -0,0 +1,48 @@
+Source: https://codeforces.com/blog/entry/5158
+
+Итак, начнём разбор.
+
+### [219A - k-String](/contest/219/problem/A "Codeforces Round 135 (Div. 2)")
+
+Давайте для каждой буквы *l* посчитаем, сколько раз она встретилась в строке --- массив *c*[*l*]. Подсчет осуществляется примерно так: `c[s[i]]++`. Если количество вхождений какой-то буквы не кратно *k*, то мы уже сразу понимаем, что составить нужную нам строку невозможно. Теперь построим строку *p*: добавим в неё  букв 'a',  букв 'b', и так далее. Выведем полученную строку *k* раз.
+
+### [219B - Special Offer! Super Price 999 Bourles!](/contest/219/problem/B "Codeforces Round 135 (Div. 2)")
+
+Переберем количество девяток на конце числа от 1 до 18. Пусть эта величина равна *k*. В таком случае максимальное число не превосходящее заданное *p* можно получить так:
+
+* сотрем последние *k* цифр числа *x*: = *p* / 10*k*
+* добавим справа *k* девяток *y*: = *x*·10*k* + 10*k* - 1
+* если значение *y* больше *p*, то уменьшим число *x* (то, что идет до *k* девяток) на 1 и к результату допишем *k* девяток *y*: = (*x* - 1)·10*k* + 10*k* - 1
+
+Если получившееся *y* > = *p* - *d*, то обновим ответ значением *k*.
+
+### [219C - Color Stripe](/contest/219/problem/C "Codeforces Round 135 (Div. 2)")
+
+Разберём 2 два случая:
+
+1. *k* равно 2. Тогда нам подходят только две строки — чередующиеся буквы 'A' и 'B'. Выбираем из них тот, который требует меньшего числа перекрасок.
+2. *k* больше 2. Возьмем самый левый блок из одинаковых букв. Пусть его длина равна *k*, тогда надо не менее *k* / 2 перекрашиваний, чтобы избавиться от соседних одинаковых клеток в этом блоке. Если *k* нечетно, то можно каждую вторую клетку в блоке перекрасить в любой из цветов, отличных от цвета блока. Если *k* четно, то можно делать тоже самое, но аккуратнее выбрать цвет: он должен отличаться не только от цвета блока, но и от цвета следующей клетки за блоком. Это всегда возможно сделать, так как количество цветов больше 2.
+
+### [219D - Choosing Capital for Treeland](/contest/219/problem/D "Codeforces Round 135 (Div. 2)")
+
+Для того, чтобы решить эту задачу посчитаем для каждого города количество ребер, которые надо переориентировать, чтобы данный город стал столицей.
+
+В задаче были достаточно большие ограничения, поэтому нельзя было просто посчитать все эти значения *n* обходами в глубину. Авторское решение запускает только два обхода в глубину. Первым обходом в глубину посчитаем ответ для города номер 1. Заметим, что если посчитан ответ для вершины *x*, то ответ для вершины *y*, которая соединена с *x*, можно посчитать за *O*(1). А именно, *ans*(*y*) = *ans*(*x*) - *direction*(*x*, *y*) + (1 - *direction*(*x*, *y*)), где *direction*(*x*, *y*) — равно 1, если ребро (*x*, *y*) ориентировано не так как во входных данных, и равно 0, иначе.
+
+Пользуясь описанным фактом, можно посчитать все значения *ans*(*v*) одним обходом, зная *ans*(1).
+
+Итоговая ассимптотика решения *O*(*n*).
+
+### [219E - Parking Lot](/contest/219/problem/E "Codeforces Round 135 (Div. 2)")
+
+Будем поддерживать две структуры: множество отрезков свободных парковочных мест, в котором отрезки отсортированы по их началу, и множество отрезков свободных парковочных мест отсортированных по размеру. Такие структуры должны поддерживать операцию быстрого поиска первого больше либо равного элемента, удаление элемента и его вставку, нахождениe максимума и следующего по величине элемента.
+
+В языке C++, авторское решение использовало set `<pair<int,int>>` и map `<int, set<int>>`. Set отрезков и Map из длины отрезка в набор отрезков с заданной длиной. Операция поиска больше либо равного элемента в этих структурах называется lower_bound.
+
+Научимся поддерживать эти структуры от операции к операции. Для того, чтобы определить автомобилиста на стоянку, нужно взять свободный отрезок с максимальной длиной или с (максимальной длиной минус один), который не упирается в начало или конец стоянки, и попробовать определить автомобилиста на свободное парковочное место в середину этого отрезка (если точной середины нет, то в ближайшую к ней клетеку). Среди всех таких позиций нужно выбрать наилучшую (в смысле условия задачи). После нахождения лучшей позиции надо разрезать соотвествующий отрезок свободных позиций на два и обновить обе структуры (удалить старый отрезок и вставить два новых).
+
+Чтобы удалить автомобилиста со стоянки нужно добавить новый отрезок свободных парковочных мест длины один в структуру. Предварительно нужно удалить смежные с этим отрезком отрезки в структуре. Соединить их с нашим отрезком и добавить один большой отрезок в структуру.
+
+Отдельные случаи возникает при рассмотрении крайних отрезков.
+
+Итоговая сложность решения *O*(*m* *log* *n*)
diff --git a/editorials/22.md b/editorials/22.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/507
+
+[Contest discussion](//codeforces.com/blog/entry/505)
+
+### **Problem А. Second Order Statistics**
+
+Sorting
+
+In this problem one should find a minimal element from all elements, that are strictly greater, then the minimal one or report that it doesn't exist. Of course, there can be a lot of different solutions, but one of the simplest - to sort the given sequence and print the first element, that's not equal to the previous. If all elements are equal, then the required element doesn't exist.
+
+### Problem B. Bargaining Table
+
+Simulation, dynamic programming
+
+In this problem one should find the maximal perimeter of a rectangle that contains no '1'. Define these rectangles "correct". To solve a problem you are to check each possible rectangle for correctness and calculate its perimeter. The easiest way to check all rectangles is using 6 nested cycles. Using 4 of them you fix the coordinates while other 2 will look for '1'. So the complexity is O((n*m)3). It seems slow, but those, who wrote such a solution, says that it hasn't any problems with TL.
+
+One may interest in much faster solution. Using simple DP solution one can get a solution with an O((n*m)2) complexity. It's clear, that rectangle with coordinates (x1, y1, x2, y2) is correct if and only if rectangles (x1, y1, x2-1, y2) and (x1, y1, x2, y2-1) are correct, and board[x2][y2] = '0'. So each of rectangles can be checked in O(1) and totally there will be O((n*m)2) operations.
+
+### Problem C. System Administrator
+
+Simulation
+
+In this problem you are to construct a connected graph, which contains n vertexes and m edges, and if we delete vertex with number v, our graph stops being connected or to report that such a graph doesn't exist. Moreover, each pair of vertexes can have no more than one edge connecting them. Obviously, a connected graph doesn't exist if the number of edges is less than n-1. It's easy to notice, that the maximal possible number of edges reaches when there is a vertex connected to v and doesn't connected to any other vertex, those can form up to complete graph. So the maximal number of edges is (n-1)*(n-2)/2+1. If m is in that range then required graph always exists. Then you should place one vertex on the one side of v (let it be 1), and other vertexes - on the other side. First, you should connect all this vertexes to v and then connect them between each other (except 1).
+
+### Problem D. Segments
+
+Scanning line
+
+In this problem one should place minimal number of points on the line such that any given segment touches at least one of these points. Let's call the coordinate of ending of any segment as event. There will be events of two types: beginning of a segment and its ending. Let's sort this events by coordinates. In the case of equality of some events consider that the event of the beginning will be less than the event of ending. Look at our events from left to right: if there is a beginning event, then push the number of this segment to the special queue. Once we take an ending of some segment, place the point here and clear the special queue (because each of segment in this queue will touch this point).
+
+### Problem E. Scheme
+
+Graph theory
+
+Given an oriented graph, find the minimal number of edges one should add to this graph to make it strongly connected. Looking at statement we can get the fact that each vertex has exactly one outcoming edge. It means that starting at some point we'll get stuck in some cycle. So each connected (not strongly) component is a set of simple paths, ending in some cycle or just a simple cycle. First consider vertexes, which has no incoming edges. When passing through some vertex we'll paint it until the current vertex will be already painted. Then we call the starting vertex as "beginning" and the finishing one as "ending" of a component.
+
+After that consider other vertexes - they belong to cycles. Beginning and ending of a cycle - is any vertexes (possible coinciding) belonging to it. So we got a number of components which we have to connect. Let's connect them cyclically: the edge will pass from the ending of i-th component to the beginning of ((i+1)%k)-th, where k is the number of such components. The answer will be k. There is an exception: if we have only one component which is a simple cycle, the answer will be equal to 0.
+
+So we'll consider each edge exactly once and the total complexity will be O(n).
diff --git a/editorials/220.md b/editorials/220.md
@@ -0,0 +1,45 @@
+Source: https://codeforces.com/blog/entry/5177
+
+### [221A - Little Elephant and Function](/contest/221/problem/A "Codeforces Round 136 (Div. 2)")
+
+In this problems you should notice that the answer for the problem is always of the following form: *n*, 1, 2, 3, ..., *n*-1. In such case array will be always sorted after the end of the algorithm.
+
+### [221B - Little Elephant and Numbers](/contest/221/problem/B "Codeforces Round 136 (Div. 2)")
+
+Here you just need to find all divisors of *n*. This can be done using standart algorithm with iterating from 1 to *sqrt*(*n*). After that you need to write some function that checks whether two numbers has same digits. This also can be done using simple loops.
+
+### [220A - Little Elephant and Problem](/contest/220/problem/A "Codeforces Round 136 (Div. 1)")
+
+There are multiple possible solutions for this problem. For example, the following. Find the last index *x* such that there exists some *y* (*y* < *x*) (minimal possible) that *A**x* < *A**y*. Then you just need to try two possibilities — either swap *A**x* and *A**y*, or don't change anything.
+
+### [220B - Little Elephant and Array](/contest/220/problem/B "Codeforces Round 136 (Div. 1)")
+
+This problem can be solve in simpler *O*(*NsqrtN*) solution, but I will describe *O*(*NlogN*) one.
+
+We will solve this problem in offline. For each *x* (0 ≤ *x* < *n*) we should keep all the queries that end in *x*. Iterate that *x* from 0 to *n* - 1. Also we need to keep some array *D* such that for current *x* *D**l* + *D**l* + 1 + ... + *D**x* will be the answer for query [*l*;*x*]. To keep *D* correct, before the processing all queries that end in *x*, we need to update *D*. Let *t* be the current integer in *A*, i. e. *A**x*, and vector *P* be the list of indices of previous occurences of *t* (0-based numeration of vector). Then, if |*P*| ≥ *t*, you need to add 1 to *D**P*[|*P*| - *t*], because this position is now the first (from right) that contains exactly *t* occurences of *t*. After that, if |*P*| > *t*, you need to subtract 2 from *D**P*[|*P*| - *t* - 1], in order to close current interval and cancel previous. Finally, if |*P*| > *t* + 1, then you need additionally add 1 to *D**P*[|*P*| - *t* - 2] to cancel previous close of the interval.
+
+### [220C - Little Elephant and Shifts](/contest/220/problem/C "Codeforces Round 136 (Div. 1)")
+
+Each of the shifts can be divided into two parts — the right (the one that starts from occurrence 1) and the left (the rest of the elements). If we could keep minimal distance for each part, the minimal of these numbers will be the answers for the corresponding shift. Lets solve the problems of the right part, the left will be almost the same.
+
+Let we have some shift, for example 34567[12] and the permutation *A* is 4312765 and *B* is 2145673, then shifted *B* is 4567321. Let we keep two sets (*S*1 and *S*2). The first will keep all the distances from integers in current left part to the corresponding positions in *A* (for the example above, it is \texttt{2, 4}). When you come to the next shift, all integers in *S*1 should be decreased by 1 (that is because all distances are also decreased by 1). But now some integers in set may be negative, when any negative integer occures (it always will be -1) you need to delete it from *S*1 and put 1 to the *S*2. Also after shifting to the next shifts, all integers in *S*2 must be increase by 1. After that, for any shift, the answer will be minimum from the smallest numbers in *S*1 and *S*2.
+
+It was very useful to use standart "set" in C++.
+
+### [220D - Little Elephant and Triangle](/contest/220/problem/D "Codeforces Round 136 (Div. 1)")
+
+Let iterate all possible points that, as we consider, must be the first point. Let it be (*x*;*y*). Let the second and the third points be (*x*1;*y*1) and (*x*2;*y*2). Then the doubled area is |(*x*1 - *x*)(*y*2 - *y*) - (*x*2 - *x*)(*y*1 - *y*)|. We need this number to be even and nonzero. For first we will find the number of groups of points that are even, after that just subtract the number of groups with area equal to zero.
+
+For the first subproblem, we need to rewrite our formula. It is equal to |*x*(*y*1 - *y*2) + *y*(*x*2 - *x*1)|. Since we know *x* and *y* and we just need to check parity, we can try all possible 24 values of parity of *x*1, *y*1, *x*2 and *y*2 (let it be *d*0, *d*1, *d*2 and *d*3, respectively). And check whether they will form a 0 after multiplications and taking modulo 2. If it froms a 0, then add to the answer value *cx**d*0*cy**d*1*cx**d*2*cy**d*3, where *cx**d* is equal to the number of integers between 0 and *n*, inclusve, that modulo 2 are equal *d*. *cy**d* is the same but in range [0..*m*].
+
+Now we need to subtract bad groups — the ones that has the area equal to zero. This means that they will either form a dot or a segment. If it is segment, we can just iterate *dx* = |*x*1 - *x*2| and *dy* = |*y*1 - *y*2| instead of all 4 coordinates. Then the number of such segments on the plane will be (*n* - *dx* + 1)(*m* - *dy* + 1). Also for counting the number of triples of points on the segment you need to find the number of integer coordinates on the segment. It is well-know problem, and the answer is *gcd*(*dx*, *dy*) + 1.
+
+This gives us, with some simple optimizations, and *O*(*nm*) solution.
+
+### [220E - Little Elephant and Inversions](/contest/220/problem/E "Codeforces Round 136 (Div. 1)")
+
+In this problems you can use a method of two pointers. Also some RMQ are required. If you do not know about RMQ, please, read about it in the Internet before solving this problem.
+
+Firstly, map all the elements in the input array. After that all of them will be in range [0..*n* - 1]. We need to keep two RMQs, both of size *n*. Let the first RMQ be *Q*1 and the second *Q*2. *Q*1*i* will contain the number of numbers *i* in current left subarray. *Q*2*i* will contain the number of numbers *i* in the left subarray. Firstly, add all *n* number to the *Q*2. After that iterate some pointer *r* from *n* - 1 downto 1, by the way keeping point *l* (which, at the beggining, is equal to *n* - 1) Using RMQs, you can keep the number of inversions when you decrease *r* or *l* (using "sum on the range" operation). While the current number of inversions is more then *k* and *l* ≥ 0, decrease *l*. Then for each *r* the answer of correct *l* will be *l* + 1 (considering 0-based numeration).
+
+This makes the algorithm working in *O*(*NlogN*) time with correct realisation.
diff --git a/editorials/221.md b/editorials/221.md
@@ -0,0 +1,45 @@
+Source: https://codeforces.com/blog/entry/5177
+
+### [221A - Little Elephant and Function](/contest/221/problem/A "Codeforces Round 136 (Div. 2)")
+
+In this problems you should notice that the answer for the problem is always of the following form: *n*, 1, 2, 3, ..., *n*-1. In such case array will be always sorted after the end of the algorithm.
+
+### [221B - Little Elephant and Numbers](/contest/221/problem/B "Codeforces Round 136 (Div. 2)")
+
+Here you just need to find all divisors of *n*. This can be done using standart algorithm with iterating from 1 to *sqrt*(*n*). After that you need to write some function that checks whether two numbers has same digits. This also can be done using simple loops.
+
+### [220A - Little Elephant and Problem](/contest/220/problem/A "Codeforces Round 136 (Div. 1)")
+
+There are multiple possible solutions for this problem. For example, the following. Find the last index *x* such that there exists some *y* (*y* < *x*) (minimal possible) that *A**x* < *A**y*. Then you just need to try two possibilities — either swap *A**x* and *A**y*, or don't change anything.
+
+### [220B - Little Elephant and Array](/contest/220/problem/B "Codeforces Round 136 (Div. 1)")
+
+This problem can be solve in simpler *O*(*NsqrtN*) solution, but I will describe *O*(*NlogN*) one.
+
+We will solve this problem in offline. For each *x* (0 ≤ *x* < *n*) we should keep all the queries that end in *x*. Iterate that *x* from 0 to *n* - 1. Also we need to keep some array *D* such that for current *x* *D**l* + *D**l* + 1 + ... + *D**x* will be the answer for query [*l*;*x*]. To keep *D* correct, before the processing all queries that end in *x*, we need to update *D*. Let *t* be the current integer in *A*, i. e. *A**x*, and vector *P* be the list of indices of previous occurences of *t* (0-based numeration of vector). Then, if |*P*| ≥ *t*, you need to add 1 to *D**P*[|*P*| - *t*], because this position is now the first (from right) that contains exactly *t* occurences of *t*. After that, if |*P*| > *t*, you need to subtract 2 from *D**P*[|*P*| - *t* - 1], in order to close current interval and cancel previous. Finally, if |*P*| > *t* + 1, then you need additionally add 1 to *D**P*[|*P*| - *t* - 2] to cancel previous close of the interval.
+
+### [220C - Little Elephant and Shifts](/contest/220/problem/C "Codeforces Round 136 (Div. 1)")
+
+Each of the shifts can be divided into two parts — the right (the one that starts from occurrence 1) and the left (the rest of the elements). If we could keep minimal distance for each part, the minimal of these numbers will be the answers for the corresponding shift. Lets solve the problems of the right part, the left will be almost the same.
+
+Let we have some shift, for example 34567[12] and the permutation *A* is 4312765 and *B* is 2145673, then shifted *B* is 4567321. Let we keep two sets (*S*1 and *S*2). The first will keep all the distances from integers in current left part to the corresponding positions in *A* (for the example above, it is \texttt{2, 4}). When you come to the next shift, all integers in *S*1 should be decreased by 1 (that is because all distances are also decreased by 1). But now some integers in set may be negative, when any negative integer occures (it always will be -1) you need to delete it from *S*1 and put 1 to the *S*2. Also after shifting to the next shifts, all integers in *S*2 must be increase by 1. After that, for any shift, the answer will be minimum from the smallest numbers in *S*1 and *S*2.
+
+It was very useful to use standart "set" in C++.
+
+### [220D - Little Elephant and Triangle](/contest/220/problem/D "Codeforces Round 136 (Div. 1)")
+
+Let iterate all possible points that, as we consider, must be the first point. Let it be (*x*;*y*). Let the second and the third points be (*x*1;*y*1) and (*x*2;*y*2). Then the doubled area is |(*x*1 - *x*)(*y*2 - *y*) - (*x*2 - *x*)(*y*1 - *y*)|. We need this number to be even and nonzero. For first we will find the number of groups of points that are even, after that just subtract the number of groups with area equal to zero.
+
+For the first subproblem, we need to rewrite our formula. It is equal to |*x*(*y*1 - *y*2) + *y*(*x*2 - *x*1)|. Since we know *x* and *y* and we just need to check parity, we can try all possible 24 values of parity of *x*1, *y*1, *x*2 and *y*2 (let it be *d*0, *d*1, *d*2 and *d*3, respectively). And check whether they will form a 0 after multiplications and taking modulo 2. If it froms a 0, then add to the answer value *cx**d*0*cy**d*1*cx**d*2*cy**d*3, where *cx**d* is equal to the number of integers between 0 and *n*, inclusve, that modulo 2 are equal *d*. *cy**d* is the same but in range [0..*m*].
+
+Now we need to subtract bad groups — the ones that has the area equal to zero. This means that they will either form a dot or a segment. If it is segment, we can just iterate *dx* = |*x*1 - *x*2| and *dy* = |*y*1 - *y*2| instead of all 4 coordinates. Then the number of such segments on the plane will be (*n* - *dx* + 1)(*m* - *dy* + 1). Also for counting the number of triples of points on the segment you need to find the number of integer coordinates on the segment. It is well-know problem, and the answer is *gcd*(*dx*, *dy*) + 1.
+
+This gives us, with some simple optimizations, and *O*(*nm*) solution.
+
+### [220E - Little Elephant and Inversions](/contest/220/problem/E "Codeforces Round 136 (Div. 1)")
+
+In this problems you can use a method of two pointers. Also some RMQ are required. If you do not know about RMQ, please, read about it in the Internet before solving this problem.
+
+Firstly, map all the elements in the input array. After that all of them will be in range [0..*n* - 1]. We need to keep two RMQs, both of size *n*. Let the first RMQ be *Q*1 and the second *Q*2. *Q*1*i* will contain the number of numbers *i* in current left subarray. *Q*2*i* will contain the number of numbers *i* in the left subarray. Firstly, add all *n* number to the *Q*2. After that iterate some pointer *r* from *n* - 1 downto 1, by the way keeping point *l* (which, at the beggining, is equal to *n* - 1) Using RMQs, you can keep the number of inversions when you decrease *r* or *l* (using "sum on the range" operation). While the current number of inversions is more then *k* and *l* ≥ 0, decrease *l*. Then for each *r* the answer of correct *l* will be *l* + 1 (considering 0-based numeration).
+
+This makes the algorithm working in *O*(*NlogN*) time with correct realisation.
diff --git a/editorials/222.md b/editorials/222.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/5251
+
+Problem A:
+
+Note that the k-th element is copied to the end. Then the (k+1)-th element from the initial sequence is copied, then (k+2)-th, … , n-th, k-th, (k+1)-th, etc. So all the numbers on the blackboard will become equal if and only if all the numbers from the k-th to the n-th in the initial sequence were equal. It's now also obvious that the number of operations needed for it is equal to the index of the last number that is not equal to the n-th element of the initial sequence, because it's exactly the number of deletions needed to eliminate the elements that are not equal to the last one. If this number is greater than k, than answer is -1. Complexity — O(n).
+
+Problem B:
+
+Let’s store the order of the rows and columns of table. Thus, row[x] is the number of the row x in the initial table and column[x] is the number of column x in the initial table. Then, the value of an element in the row x and column y in the current table is equal to t[row[x], column[y]], where t — initial table. When we get the update request, we need to swap the x-th element and the y-th element in the corresponding array. Complexity — O(n * m + k).
+
+Problem C:
+
+Let's factorize the numerator and denominator. Now for each prime integer x we know the extent of x in the factorization of the numerator(a[x]) and the denominator(b[x]). For each prime number x we can calculate the extent of x in the factorization of the numerator and the denominator after reduction : newa[x]=a[x]-min(a[x], b[x]), newb[x]=b[x]-min(a[x],b[x]). We have the numerator and the denominator of the answer in factorized form. Now we have to bring them into the form which is required in the condition. One of the ways to do it is to note that the fraction from the statement satisfies the conditions. We can factorize it again and in the answer we will have the same fraction for which there will not be such a prime x so that the degree of x in answer would be greater than newa[x] or newb[x]. (This operation can be called reduction) The result will satisfy the condition and the fraction will be equal to the required number. If you try to build answer greedily (put factors in the answer till their product <= 10^7), the count of numbers in the answer (n_out or m_out) will be bigger than 10^5. Factorization by O(sqrt(max)) received TL. You should have found a faster way. For example you could have used linear sieve of Eratosthenes. Complexity — O(max + n * log(max)). log(max) is size of factorization.
+
+Problem D:
+
+First of all, note that in any case the best place which Vasya can take is the first place for he can earn maximum points. Now we must find the worst place which Vasya can take. We need to find maximal matching in bipartite graph, where the edge between vertice i from the first part and vertice j from the second part exists if a[i] + b[j] >= x. To solve this task, it is enough just to sort the vertices in both parts of the graph by their weights and use two pointers method. Suppose that we have sorted all the vertices by non-increasing points (a1 >= a2 >= ... >= an). Let's take two pointers — L = 1 in the first part and R = N in the second part. While a[L] + b[R] < x we must decrease R to find the first vertice such a[L] + b[R] >= x. When we found such R, we must add this edge to the answer, i.e. increase the answer, increase L by 1, decrease R by 1. It is easy to show why this algo is correct and it finds the optimal solution. I have discovered a truly marvelous proof of this, but the margins of this analysis are too narrow to for him. Complexity — O(N log N) for sorting and O(N) for two pointers.
+
+Problem E:
+
+1) Solution with complexity O(n*m*m), using the dynamic programming: State — d[n][m] — the number of allowed chains of length n that ends in symbol m. Transition — sort out all possible characters, and check if you can put the symbol k after symbol m.
+
+2) Solution with complexity O(m*m*m*log n): Note that the transition in the first solution is always the same. So we can make the transition matrix A of size MxM. If j-th symbol can follow i-th then A[i][j]=1 else A[i][j]=0. Define a vector of size 1хМ b={1,1,…,1}. We can see that b * a^(n-1) = answer. Now we can use fast exponentiation for computing a^(n-1). We should consider the case with n=1 separately. The answer is the sum of numbers in the vector ans. Complexity — O(m^3) from matrix multiplication and O(log n) from fast exponentiation.
diff --git a/editorials/223.md b/editorials/223.md
@@ -0,0 +1,75 @@
+Source: https://codeforces.com/blog/entry/5301
+
+### Div2 A. Parallelepiped
+
+You were given areas of three faces of a rectangular parallelepiped. Your task was to find the sum of lengths of it's sides.
+
+Let *a*, *b* and *c* be the lengths of the sides that have one common vertex. Then the numbers we are given are *s*1 = *ab*, *s*2 = *bc* и *s*3 = *ca*. It is easy to find the lengths in terms of faces areas: 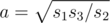, 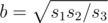, 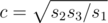. The answer is 4(*a* + *b* + *c*), because there are four sides that have lengths equal to *a*, *b* and *c*. The complexity is *O*(1).
+
+### Div2 B. Array
+
+You were given an array *a* consisting of *n* integers. Its elements *a**i* were positive and not greater than 105 for each 1 ≤ *i* ≤ *n*. Also you were given positive integer *k*. You had to find minimal by inclusion segment [*l*, *r*] such that there were exactly *k* different numbers among *a**l*, ..., *a**r*. The definition of the "minimal by inclusion" you can read in the statement.
+
+Let us make a new array *cnt*. In the beginning its element *cnt**i* is equal to number of occurencies of number *i* in array *a*. It is possible to make this array because elements of *a* are not very large. Amount of nonzero elements in *cnt* is equal to amount of different elements in *a*. There is no solution if this number is less then *k*.
+
+If it is not true, we have to find the answer segment [*l*, *r*]. In the beginning let [*l*, *r*] = [1, *n*]. We decrease its right end *r* by 1 until amount of different elements on the segment [*l*, *r*] is less than *k*. We can keep the amount of different numbers in following way: we decrease *cnt**a**r* by 1 if we delete element number *r*. Then we have to decrease current number of different elements by 1 if *cnt**a**r* becomes zero. After this we return the last deleted element back to the segment in order to make amount of different elements equal to *k*. Then we have to do the same with the left end *l*, but we have not to decrease but to increase its value by 1 on each step. Finally, we get a segment [*l*, *r*]. The amount of different numbers on it is equal to *k* and on every its subsegment is less than *k*. Therefore, this segment is an answer. The complexity is *O*(*n*).
+
+### Div2 C/Div1 A. Bracket sequence
+
+You were given a bracket sequence *s* consisting of brackets of two kinds. You were to find regular bracket sequence that was a substring of *s* and contains as many <<>> braces as possible.
+
+We will try to determine corresponding closing bracket for every opening one. Formally, let a bracket on the i-th position be opening, then the closing bracket on the position j is corresponding to it if and only if a substring *s**i*... *s**j* is the shortest regular bracket sequence that begins from the i-th position. In common case there can be brackets with no corresponding ones.
+
+We scan the sting *s* and put positions with the opening brackets into a stack. Let us proceed the i-th position. If *s**i* is an opening bracket we simply put *i* on the top of the stack. Otherwise, we have to clean the stack if the stack is empty or the bracket on the top does not correspond to the current one. But if the bracket on the top is ok we just remove the top of the stack and remember that the bracket on position *i* is corresponding to the bracket removed from the top. So, we find all the correspondings for all the brackets.
+
+Then we can split *s* into blocks. Let block be a segment [*l*, *r*] such that the bracket on the *r*-th position is corresponding for the bracket on the *i*-th and there is no couple of corresponding brackets on positions *x* and *y* such that  and [*l*, *r*] ≠ [*x*, *y*]. It is easy to understand that the blocks do not intersect and the split is unique. We can join the consequent blocks into the regular bracket sequences. We should join as many blocks as possible in order to get the maximal number of braces. We get several substrings that are regular bracket sequences after we join all the consecutive blocks. The answer is the substring that has the largest amount of braces <<>>. The complexity is *O*(|*s*|).
+
+### Div2 D/Div1 B. Two strings.
+
+You were given two strings: *s* and *t*. You were required to examine all occurrences of the string *t* in the string *s* as subsequence and to find out if it is true that for each position of the *s* string there are such occurrence, that includes this position.
+
+For each position *i* of the *s* string we calculate two values *l**i* and *r**i* where *l**i* is the maximal possible number that the string *t*1... *t**l**i* occurs as subsequence in the string *s*1... *s**i*, *r**i* is the maximal possible number that the string *t*|*t*| - *r**i* + 1... *t*|*t*| occurs in the string *s**i*... *s*|*s*| as subsequence. Let us find all of *l* for the position 1... *i* - 1 and want to find *l**i*. If the symbol *t**l**i* - 1 + 1 exists and concurs with the symbol *s**i* then *l**i* = *l**i* - 1 + 1, in other case *l**i* = *l**i* - 1. In the same way we can find *r**i* if we move from the end of the string.
+
+Now we should check if the position *i* in the string *s* belongs to at least one occurrence. Let us assume this to be correct and the symbol *s**i* corresponds to the symbol *t**j* of the string *t*. Then *l**i* - 1 ≥ *j* - 1 and *r**i* + 1 ≥ |*t*| - *j* by definition of the *l* and *r*. Then if *j* exists that *s**i* = *t**j* and *l**i* - 1 + 1 ≥ *j* ≥ |*t*| - *r**i* + 1, then the position *i* of the string *s* belongs to at least one occurrence of the *t*, in other case the occurrence doesn’t exist. We can easily check it by creating an array *cnt**a*, *i* for each letter, which is a number of letters *a* in the positions 1... *i* of the string *t*. The complexity of the solution is *O*(|*s*| + |*t*|).
+
+### Div2 E/Div1 C. Частичные суммы
+
+You were given an array *a* in this problem. You could replace *a* by the array of its partial sums by one step. You had to find the array after *k* such steps. All the calculations were modulo *P* = 109 + 7.
+
+Write partial sums in following way:
+
+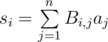
+
+where *B**i*, *j* = 1 if *i* ≥ *j* and *B**i*, *j* = 0 if *i* < *j*, for each 1 ≤ *i*, *j* ≤ *n*. We can represent *a* and *s* as vector-columns, therefore one step corresponds to multiplying matrix *B* and vector-column *a*. Then the array *a* after *k* steps is equal to *B**k**a*. We can raise a matrix to a power for . It is not bad, but not fast enough.
+
+We can notice, that  = , i.e. the elements of the matrix *B**k* on diagonals parallel to the main are the equal. It is easy to prove this fact using mathematical induction. You may prove it by yourself. Then we can determine the matrix by an array of numbers 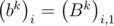, equal to the elements of the first column. The elements of the first column of the product *B**k**B**l* are equal 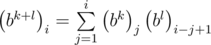. It is a straight consequence of formula of matrix product. The computing of one element requires *O*(*n*) time, there are *n* elements therefore we can multiply matriсеs in *O*(*n*2) time. Then we can solve the problem in  time and this solution fits the consrtaints.
+
+This problem can be solved faster. We can assure that 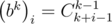. Let this formula be correct for some *k*. Prove that it is correct for *k* + 1 either. Using the formula of product we get:
+
+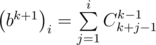 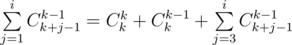 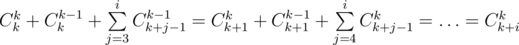
+
+Используя формулу *C**n**k* = *n*! / *k*!(*n* - *k*)!, можно получить, что 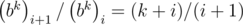, поэтому мы можем построить все коэффициенты *b*, если умеем делить по модулю *P*, поэтому в этом решении существенна простота *P*. Обратный для числа *x* по простому модулю равен 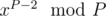 в силу малой теоремы Ферма. Таким образом, мы получаем решение за *O*(*n*2).
+
+Using the formula *C**n**k* = *n*! / *k*!(*n* - *k*)! we can obtain 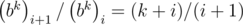, so we can find all the coefficients *b* if we can divide modulo *P*. Therefore it is significant that *P* is prime. Inverse *x* modulo *P* is equal to 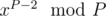 according to the Fermat little theorem. Therefore we get *O*(*n*2)*solution*.
+
+### Div1 D. Spider
+
+You were given a polygon consisting of *n* vertices, you had to find the shortest way from one of its vertices to another. You were allowed to move along the border and go stricktly down without going outside the polygon
+
+All the sides of the polygon can be divided into three groups: top, bottom and vertical. The side is vertical if and only if the *x* coordinates of its ends are equal. The side is bottom if and only if the polygon's interior is above the side. The side it top if and only if the polygon's interior is below the side. We can descend only from points of the top sides to the points of the bottom sides. Vertical sides can be ignored because every descend that has common points with a vertical side can be splitted into two descends and one transfer. One can prove that it is useless to descend from a side's interior to side's interior. Len one of the descends in the optimal solution start in the inner point and end in the inner point. We can slightly change the *x* coordinate of the descend. The path's lenght is monotonically (possibly not strictly) depends on *x*, so we can move *x* in order to improve the answer. In case of not strictly monotone dependance the answer do not depend on *x*, so we also can move it. This proof is wrong if the descend passes through a vertex, therefore we have to examine all possible descends from the vertices and to the vertices.
+
+We can solve this problem using scan-line method. We well move a vertical straight line from the left to the right and keep set *S* of the sides that intersect the line. We store the segments in the *S* in the sorted by *y* order. Let *X* be an abscissa of the line. The events happen during the moving: some segments are added to the *S* set, some are deleted. We can make an array of events, each events is described by its *x* coordinate that is equal to *X* of the line when the corresponding event happens, the number of the segment and a kind of event: adding or deleting. There are two events for every side, their *x* coordinates correspond to abscissas of their ends. The vertical sides can be ignored.
+
+Let us proceed the events in non-decreasing order of *x* coords. If the current event is adding we add the side to *S* set. Then we check on its closest neighbours in the set. If the current segment is a top segment we can make a descend from its left vertex down to the intersection with it's lower neighbor. We find the point of the intersection, remember the segment where the point is located and remember that there can be a descend from a vertex to the new point. If the current side is the bottom side we make a descand from the upper neighbour to the left end of the current segment and do the same things. If the current event is deleting we analize its neighbours in the same way, but the descends start or end on the right end of the segment we are going to delete. It is important that if there are many events of one kind we should proceed them simultaneously, i.e. if there are many addings in the same *x* coordinate we must add all the segments and then examine their neighbours. It is the same for deletings: firstly we analize the neighbours for all the segments and only then we delete them. Also in the case of equal *x* coords of the events the adding events must be first, otherwise the solution is wrong for the case of two angles separated by a vertical line with vertices lying on this line.
+
+Set *S* is easy to keep in container such as "set". We have to write a comparator for segments. We can do it in following way: two segments can be in *S* simultaneously if and only if there is a vertical line that intersects both of them. In common case such a line is not the unique, all the possible values of *X* are in segment [*l*, *r*] that can be easily found if we know the coors of the ends of the segments. Then we can choose an arbitrary *X* inside of [*l*, *r*] and compare the ordinates of the intersection points. Is better to choose inner point because in this case we don't have to examine special cases of segments having a common point.
+
+After this we can build a graph. It's vertices are the vertices of the polygon and the ends of possible descends. The edges of the graphs are the sides of the polygon and the descends. The shortest path can be found using Dijkstra algorithm. The complexity of the solution is .
+
+### Div1 E. Planar graph
+
+In the problem we were given an undirected planar graph without bridges, cutpoints, loops and multiedge laid on the plane. We get requests of the following type: to calculate the number of vertices inside the cycle or on it.
+
+Let us take an arbitrary vertex on the border of the graph, for example a vertex that has the least absciss. Let's add a new vertex with an edge to the chosen vertex in such way that the edge is outside the outer border of the graph. We'll call this new vertex a sink. Let's create a 1 value flow running to the sink from each vertex except the sink. Flow can be created using breadth-first or depth-first search. This operation will take the *O*(*E*) time.
+
+Let's examine any request. We assume that the cycle is oriented counter-clockwise (if it is not so, we can just reorient it). Let's make a cut on the graph. The first part will contain the vertices laying on the cycle or inside it, the second one — all remaining vertices including the sink. We'll now prove that the flow value through the cut is equal to the vertices number in the first part. It's obvious that we can calculate contribution from every vertex to the flow value independently. Let's assume that the vertex is situated in the first part. A unit flow runs from it to the sink along some path. As soon as this vertex and the sink are situated in different parts the flow passes the edges of the cut an odd number of times, that's why the contribution of this vertex to the flow through the cut is equal to 1. Let's take now a vertex situated in the second part. As soon as it's situated in the same part as the sink the flow passes the edges of the cut an even number of times, that's why the contribution of this vertex to the flow through the cut is zero. In order to calculate the flow value through the cut we need to sum up flow values passing through the cut's edges. It's important to notice that every edge of the cut is incident to only one vertex lying on the cycle, that's why we can sum up flows passing though edges going outside the cycle for each vertex in the cycle. In order to find all edges going outside the cycle we'll sort all edges going from each vertex counter-clockwise by angle. In this case all edges going outside the cycle will be placed after the previous vertex of the cycle and before the following vertex of the cycle. That's why the sum of flow values over the edges going outside reduces to a sum over an segment which is easily calculated using partial sums. The complexity of the solution is  for graph sorting plus  for the request where *l* is the cycle length. There is  in complexity because we have to know a position of a vertex in the adjacency list of another vertex.
diff --git a/editorials/224.md b/editorials/224.md
@@ -0,0 +1,75 @@
+Source: https://codeforces.com/blog/entry/5301
+
+### Div2 A. Parallelepiped
+
+You were given areas of three faces of a rectangular parallelepiped. Your task was to find the sum of lengths of it's sides.
+
+Let *a*, *b* and *c* be the lengths of the sides that have one common vertex. Then the numbers we are given are *s*1 = *ab*, *s*2 = *bc* и *s*3 = *ca*. It is easy to find the lengths in terms of faces areas: 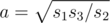, 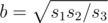, 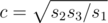. The answer is 4(*a* + *b* + *c*), because there are four sides that have lengths equal to *a*, *b* and *c*. The complexity is *O*(1).
+
+### Div2 B. Array
+
+You were given an array *a* consisting of *n* integers. Its elements *a**i* were positive and not greater than 105 for each 1 ≤ *i* ≤ *n*. Also you were given positive integer *k*. You had to find minimal by inclusion segment [*l*, *r*] such that there were exactly *k* different numbers among *a**l*, ..., *a**r*. The definition of the "minimal by inclusion" you can read in the statement.
+
+Let us make a new array *cnt*. In the beginning its element *cnt**i* is equal to number of occurencies of number *i* in array *a*. It is possible to make this array because elements of *a* are not very large. Amount of nonzero elements in *cnt* is equal to amount of different elements in *a*. There is no solution if this number is less then *k*.
+
+If it is not true, we have to find the answer segment [*l*, *r*]. In the beginning let [*l*, *r*] = [1, *n*]. We decrease its right end *r* by 1 until amount of different elements on the segment [*l*, *r*] is less than *k*. We can keep the amount of different numbers in following way: we decrease *cnt**a**r* by 1 if we delete element number *r*. Then we have to decrease current number of different elements by 1 if *cnt**a**r* becomes zero. After this we return the last deleted element back to the segment in order to make amount of different elements equal to *k*. Then we have to do the same with the left end *l*, but we have not to decrease but to increase its value by 1 on each step. Finally, we get a segment [*l*, *r*]. The amount of different numbers on it is equal to *k* and on every its subsegment is less than *k*. Therefore, this segment is an answer. The complexity is *O*(*n*).
+
+### Div2 C/Div1 A. Bracket sequence
+
+You were given a bracket sequence *s* consisting of brackets of two kinds. You were to find regular bracket sequence that was a substring of *s* and contains as many <<>> braces as possible.
+
+We will try to determine corresponding closing bracket for every opening one. Formally, let a bracket on the i-th position be opening, then the closing bracket on the position j is corresponding to it if and only if a substring *s**i*... *s**j* is the shortest regular bracket sequence that begins from the i-th position. In common case there can be brackets with no corresponding ones.
+
+We scan the sting *s* and put positions with the opening brackets into a stack. Let us proceed the i-th position. If *s**i* is an opening bracket we simply put *i* on the top of the stack. Otherwise, we have to clean the stack if the stack is empty or the bracket on the top does not correspond to the current one. But if the bracket on the top is ok we just remove the top of the stack and remember that the bracket on position *i* is corresponding to the bracket removed from the top. So, we find all the correspondings for all the brackets.
+
+Then we can split *s* into blocks. Let block be a segment [*l*, *r*] such that the bracket on the *r*-th position is corresponding for the bracket on the *i*-th and there is no couple of corresponding brackets on positions *x* and *y* such that  and [*l*, *r*] ≠ [*x*, *y*]. It is easy to understand that the blocks do not intersect and the split is unique. We can join the consequent blocks into the regular bracket sequences. We should join as many blocks as possible in order to get the maximal number of braces. We get several substrings that are regular bracket sequences after we join all the consecutive blocks. The answer is the substring that has the largest amount of braces <<>>. The complexity is *O*(|*s*|).
+
+### Div2 D/Div1 B. Two strings.
+
+You were given two strings: *s* and *t*. You were required to examine all occurrences of the string *t* in the string *s* as subsequence and to find out if it is true that for each position of the *s* string there are such occurrence, that includes this position.
+
+For each position *i* of the *s* string we calculate two values *l**i* and *r**i* where *l**i* is the maximal possible number that the string *t*1... *t**l**i* occurs as subsequence in the string *s*1... *s**i*, *r**i* is the maximal possible number that the string *t*|*t*| - *r**i* + 1... *t*|*t*| occurs in the string *s**i*... *s*|*s*| as subsequence. Let us find all of *l* for the position 1... *i* - 1 and want to find *l**i*. If the symbol *t**l**i* - 1 + 1 exists and concurs with the symbol *s**i* then *l**i* = *l**i* - 1 + 1, in other case *l**i* = *l**i* - 1. In the same way we can find *r**i* if we move from the end of the string.
+
+Now we should check if the position *i* in the string *s* belongs to at least one occurrence. Let us assume this to be correct and the symbol *s**i* corresponds to the symbol *t**j* of the string *t*. Then *l**i* - 1 ≥ *j* - 1 and *r**i* + 1 ≥ |*t*| - *j* by definition of the *l* and *r*. Then if *j* exists that *s**i* = *t**j* and *l**i* - 1 + 1 ≥ *j* ≥ |*t*| - *r**i* + 1, then the position *i* of the string *s* belongs to at least one occurrence of the *t*, in other case the occurrence doesn’t exist. We can easily check it by creating an array *cnt**a*, *i* for each letter, which is a number of letters *a* in the positions 1... *i* of the string *t*. The complexity of the solution is *O*(|*s*| + |*t*|).
+
+### Div2 E/Div1 C. Частичные суммы
+
+You were given an array *a* in this problem. You could replace *a* by the array of its partial sums by one step. You had to find the array after *k* such steps. All the calculations were modulo *P* = 109 + 7.
+
+Write partial sums in following way:
+
+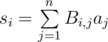
+
+where *B**i*, *j* = 1 if *i* ≥ *j* and *B**i*, *j* = 0 if *i* < *j*, for each 1 ≤ *i*, *j* ≤ *n*. We can represent *a* and *s* as vector-columns, therefore one step corresponds to multiplying matrix *B* and vector-column *a*. Then the array *a* after *k* steps is equal to *B**k**a*. We can raise a matrix to a power for . It is not bad, but not fast enough.
+
+We can notice, that  = , i.e. the elements of the matrix *B**k* on diagonals parallel to the main are the equal. It is easy to prove this fact using mathematical induction. You may prove it by yourself. Then we can determine the matrix by an array of numbers 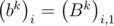, equal to the elements of the first column. The elements of the first column of the product *B**k**B**l* are equal 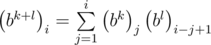. It is a straight consequence of formula of matrix product. The computing of one element requires *O*(*n*) time, there are *n* elements therefore we can multiply matriсеs in *O*(*n*2) time. Then we can solve the problem in  time and this solution fits the consrtaints.
+
+This problem can be solved faster. We can assure that 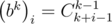. Let this formula be correct for some *k*. Prove that it is correct for *k* + 1 either. Using the formula of product we get:
+
+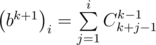 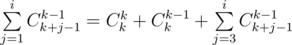 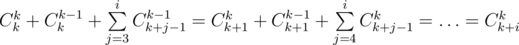
+
+Используя формулу *C**n**k* = *n*! / *k*!(*n* - *k*)!, можно получить, что 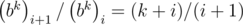, поэтому мы можем построить все коэффициенты *b*, если умеем делить по модулю *P*, поэтому в этом решении существенна простота *P*. Обратный для числа *x* по простому модулю равен 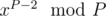 в силу малой теоремы Ферма. Таким образом, мы получаем решение за *O*(*n*2).
+
+Using the formula *C**n**k* = *n*! / *k*!(*n* - *k*)! we can obtain 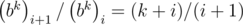, so we can find all the coefficients *b* if we can divide modulo *P*. Therefore it is significant that *P* is prime. Inverse *x* modulo *P* is equal to 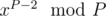 according to the Fermat little theorem. Therefore we get *O*(*n*2)*solution*.
+
+### Div1 D. Spider
+
+You were given a polygon consisting of *n* vertices, you had to find the shortest way from one of its vertices to another. You were allowed to move along the border and go stricktly down without going outside the polygon
+
+All the sides of the polygon can be divided into three groups: top, bottom and vertical. The side is vertical if and only if the *x* coordinates of its ends are equal. The side is bottom if and only if the polygon's interior is above the side. The side it top if and only if the polygon's interior is below the side. We can descend only from points of the top sides to the points of the bottom sides. Vertical sides can be ignored because every descend that has common points with a vertical side can be splitted into two descends and one transfer. One can prove that it is useless to descend from a side's interior to side's interior. Len one of the descends in the optimal solution start in the inner point and end in the inner point. We can slightly change the *x* coordinate of the descend. The path's lenght is monotonically (possibly not strictly) depends on *x*, so we can move *x* in order to improve the answer. In case of not strictly monotone dependance the answer do not depend on *x*, so we also can move it. This proof is wrong if the descend passes through a vertex, therefore we have to examine all possible descends from the vertices and to the vertices.
+
+We can solve this problem using scan-line method. We well move a vertical straight line from the left to the right and keep set *S* of the sides that intersect the line. We store the segments in the *S* in the sorted by *y* order. Let *X* be an abscissa of the line. The events happen during the moving: some segments are added to the *S* set, some are deleted. We can make an array of events, each events is described by its *x* coordinate that is equal to *X* of the line when the corresponding event happens, the number of the segment and a kind of event: adding or deleting. There are two events for every side, their *x* coordinates correspond to abscissas of their ends. The vertical sides can be ignored.
+
+Let us proceed the events in non-decreasing order of *x* coords. If the current event is adding we add the side to *S* set. Then we check on its closest neighbours in the set. If the current segment is a top segment we can make a descend from its left vertex down to the intersection with it's lower neighbor. We find the point of the intersection, remember the segment where the point is located and remember that there can be a descend from a vertex to the new point. If the current side is the bottom side we make a descand from the upper neighbour to the left end of the current segment and do the same things. If the current event is deleting we analize its neighbours in the same way, but the descends start or end on the right end of the segment we are going to delete. It is important that if there are many events of one kind we should proceed them simultaneously, i.e. if there are many addings in the same *x* coordinate we must add all the segments and then examine their neighbours. It is the same for deletings: firstly we analize the neighbours for all the segments and only then we delete them. Also in the case of equal *x* coords of the events the adding events must be first, otherwise the solution is wrong for the case of two angles separated by a vertical line with vertices lying on this line.
+
+Set *S* is easy to keep in container such as "set". We have to write a comparator for segments. We can do it in following way: two segments can be in *S* simultaneously if and only if there is a vertical line that intersects both of them. In common case such a line is not the unique, all the possible values of *X* are in segment [*l*, *r*] that can be easily found if we know the coors of the ends of the segments. Then we can choose an arbitrary *X* inside of [*l*, *r*] and compare the ordinates of the intersection points. Is better to choose inner point because in this case we don't have to examine special cases of segments having a common point.
+
+After this we can build a graph. It's vertices are the vertices of the polygon and the ends of possible descends. The edges of the graphs are the sides of the polygon and the descends. The shortest path can be found using Dijkstra algorithm. The complexity of the solution is .
+
+### Div1 E. Planar graph
+
+In the problem we were given an undirected planar graph without bridges, cutpoints, loops and multiedge laid on the plane. We get requests of the following type: to calculate the number of vertices inside the cycle or on it.
+
+Let us take an arbitrary vertex on the border of the graph, for example a vertex that has the least absciss. Let's add a new vertex with an edge to the chosen vertex in such way that the edge is outside the outer border of the graph. We'll call this new vertex a sink. Let's create a 1 value flow running to the sink from each vertex except the sink. Flow can be created using breadth-first or depth-first search. This operation will take the *O*(*E*) time.
+
+Let's examine any request. We assume that the cycle is oriented counter-clockwise (if it is not so, we can just reorient it). Let's make a cut on the graph. The first part will contain the vertices laying on the cycle or inside it, the second one — all remaining vertices including the sink. We'll now prove that the flow value through the cut is equal to the vertices number in the first part. It's obvious that we can calculate contribution from every vertex to the flow value independently. Let's assume that the vertex is situated in the first part. A unit flow runs from it to the sink along some path. As soon as this vertex and the sink are situated in different parts the flow passes the edges of the cut an odd number of times, that's why the contribution of this vertex to the flow through the cut is equal to 1. Let's take now a vertex situated in the second part. As soon as it's situated in the same part as the sink the flow passes the edges of the cut an even number of times, that's why the contribution of this vertex to the flow through the cut is zero. In order to calculate the flow value through the cut we need to sum up flow values passing through the cut's edges. It's important to notice that every edge of the cut is incident to only one vertex lying on the cycle, that's why we can sum up flows passing though edges going outside the cycle for each vertex in the cycle. In order to find all edges going outside the cycle we'll sort all edges going from each vertex counter-clockwise by angle. In this case all edges going outside the cycle will be placed after the previous vertex of the cycle and before the following vertex of the cycle. That's why the sum of flow values over the edges going outside reduces to a sum over an segment which is easily calculated using partial sums. The complexity of the solution is  for graph sorting plus  for the request where *l* is the cycle length. There is  in complexity because we have to know a position of a vertex in the adjacency list of another vertex.
diff --git a/editorials/225.md b/editorials/225.md
@@ -0,0 +1,67 @@
+Source: https://codeforces.com/blog/entry/5322
+
+**A.** You should iterate over all dices from up to down and restore answer. You can easily find number of the bottom side of the 1st dice. Using known sides of the 2nd dice you can find pair of numbets on top and bottom side of the 2nd dice. If one of them equal to number on bottom of the 1st dice, you can restore all numbers on the 2n dice. Then using this idea you can try restore numbers on the 3rd dice and so on. If you restored all numbers, you should write YES. If for some dice you cannot uniquely determine order of numbers on the top and botton sides, there will be at least 2 placing of numbers. In this case you shoyld write NO.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**B.** Firstly you should generate all k-bonacci numbers less than *n*. For *k* ≤ 32 you can do it straightforward, for bigger *k* you can see that all *k*-bonacci numbers less 109 are powers of two only (and 0). So you will have no more then 100 numbers.
+
+Then you should use greedy algo. You should substract from *n* maximal possible *k*-bonacci numbers. You should repeat this operation while *n* is not decomposed. And in the end you will have answer.
+
+Why all numbers will be different? One of possible proves:
+
+*F*(*k*, *n*) = *F*(*k*, *n* - 1) + *F*(*k*, *n* - 2) + ... + *F*(*k*, *n* - *k*)
+
+*F*(*k*, *n* - 1) = *F*(*k*, *n* - 2) + *F*(*k*, *n* - 3) + ... + *F*(*k*, *n* - *k* - 1)
+
+You can substract the 2nd equation from the 1st one and you will recieve *F*(*k*, *n*) + *F*(*k*, *n* - *k* - 1) = 2*F*(*k*, *n* - 1), that equal to 2*F*(*k*, *n* - 1) ≥ *F*(*k*, *n*). This unequation also holds for *n* ≤ *k*.
+
+Suppose than greedy also constricted 2 equal numbers *F*(*k*, *x*) in decomposition. But then in virtue of unequation we should take number *F*(*k*, *x* + 1) insead these 2 numbers. Сontradiction.
+
+But you didn't need prove than greedy algo works, you might believe that it works:)
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") , [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**C.** Firstly you should calculate number of white and black pixels in every column. After that you should calculate number of white and black pixels for every prefix in sequence of columns. Now you can calculate number of black or white pixels in every vertical line of any width in *O*(1).
+
+Now you should use dynamic programming. Let's *dp*[*i*][*j*] will store numbers of repainted pixels in prefix from the 1st column to the *j*-th and color of the last column will be white for *i* = 0 and black for *i* = 1.
+
+Than you can recalculate *dp* using forlulas: *dp*[0][0] = *dp*[1][0] = 0 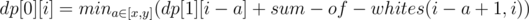 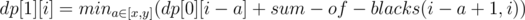
+
+Answer will be *min*(*dp*[0][*m*], *dp*[1][*m*]).
+
+This solution works in *O*(*nm* + *m* * (*y* - *x*)).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**D.** There is just BFS. State is head place and mask that store place of tail: using 2 bits you can code position of every segment in relation to previous segment. Mask will contain no more than 16 bits, and number of all states will be no more than 48 × 15 × 15 (also you can try understand that number of states no more than 38 × 15 × 15).
+
+Then you should just carefully implement it.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
+
+**E.** You have *z* = [*x* / 2] + *y* + *xy*. That is equivalent to
+
+*z* = [2*k* / 2] + *y* + 2*ky*, where *x* = 2*k*, *k* > 0
+or
+*z* = [(2*k* + 1) / 2] + *y* + (2*k* + 1)*y*, where *x* = 2*k* + 1, *k* ≥ 0.
+
+*z* = *k* + *y* + 2*ky*, *k* > 0
+or
+*z* = *k* + *y* + (2*k* + 1)*y*, *k* ≥ 0.
+
+Still more steps:
+
+2*z* + 1 = 2*k* + 2*y* + 4*ky* + 1, *k* > 0
+or
+*z* + 1 = *k* + 2*y* + 2*ky* + 1, *k* ≥ 0.
+
+2*z* + 1 = (2*k* + 1)(2*y* + 1), *k* > 0
+or
+*z* + 1 = (2*y* + 1)(*k* + 1), *k* ≥ 0.
+
+From the 2nd equation you can see than *z* should be 2*t* - 1 because otherwise *z* + 1 will have odd divisor and we can build solution. From the 1st equation you can see that 2*t* + 1 - 1 should be prime, otherwise we also can build solution. If *z* = 2*t* - 1 and 2*t* + 1 - 1 is prime, obliviously there are no solutions.
+
+Prime numbers like 2*a* - 1 are Mersenne primes. Only about 46 such numbers are found now. Powers of 2 for the firts 40 numbers you can find for example [here](http://oeis.org/A000043).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti") .
diff --git a/editorials/226.md b/editorials/226.md
@@ -0,0 +1,101 @@
+Source: https://codeforces.com/blog/entry/5378
+
+### [A div2. Where do I Turn?](https://codeforces.com/contest/227/problem/A)
+
+Let's consider cross product of vectors  and , which is equal to 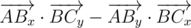. Sign of cross product defines sign of a sine of oriented angle between vectors (because cross product is also equal to 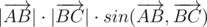), and that sign leads us to the correct answer.
+
+If cross product is equal to zero, then *A*, *B* and *C* lay on the same straight line. So the answer is <>.
+
+If cross product is more than zero, then answer is <>.
+
+And, at last, if it's less than zero, the answer is <>.
+
+Also you should notice that the value of cross product doesn't fit 32-bit type, so you have to use 64-bit type in order to avoid integer overflow.
+
+[Implementation](http://pastebin.com/qMfEbpyi)
+
+### [B div2. Effective Approach](https://codeforces.com/contest/227/problem/B)
+
+Let's assume that number *t* is on the *ind**t**th* position in the original permutation. Then, obviously, during iterating from left to right this number will be found in *ind**t* comparisons, and during iterating from right to left — in *n* - *ind**t* + 1 comparisons. Let's declare additional array, in *i**th* element of each there will be such number *j*, that *a**j* = *i*. This array allows to process each query in *O*(1) using formulas referred above. Additional array is built in *O*(*n*) during iterating array *a*. So, the final complexity is *O*(*n* + *m*).
+
+[Implementation](http://pastebin.com/YiyedFVM)
+
+### [C div2 — A div1. Flying Saucer Segments.](https://codeforces.com/contest/227/problem/C)
+
+Let *F**n* be the answer for the task, where *n* is equal to the amount of aliens. Let's assume, that we've solved problem for *n* - 1 aliens, i.e. we know the value of *F**n* - 1. Let's try to find value of *F**n*. Notice, that the most junior alien in rank will be able to leave the 3*rd* section, if and only if all other aliens are in the 1*st* section. So, now we know first *F**n* - 1 actions. Then the most junior alien may go to the 2*nd* section. To make for him entrance to the 1*st* section possible, it's necessary for all other aliens to return to the first one. So, *F**n* - 1 more actions are necessary. At last, after the most junior alien will go to the 1*st* section, *F**n* - 1 more actions are required for *n* - 1 other aliens to return to the 1*st* section from the 3*rd*. So, *F**n* = *F**n* - 1 + 1 + *F**n* - 1 + 1 + *F**n* - 1. It allows to count *F**n* using matrix exponentiation in *O*(*log* *n*), but we'll improve current solution. Let's add 1 to both parts of the equality and after elementary operations we'll have *F**n* = 3·(*F**n* - 1 + 1) - 1. Now it's easy to solve this reccurence: *F**n* = 3*n* - 1.
+
+To count *F**n* quickly you should use binary power method. Solution's complexity — *O*(*log* *n*).
+
+Don't forget that if 3*n* *mod* *m* = 0, answer is equal to *m* - 1, but not - 1.
+
+And, in conclusion, notice that the task is equal to [Hanoi Towers](https://en.wikipedia.org/wiki/Hanoi_tower) problem with a slight modification (it's impossible to move disks between one pair of rods).
+
+[Implementation](http://pastebin.com/BPLFVFnt)
+
+### [D div2 — B div1. Naughty Stone Piles](https://codeforces.com/contest/227/problem/D)
+
+Consider the following interpretation of the problem: stone piles are graph vertices. Operation "add pile *a* to pile *b*" changes to operation of suspencion of subtree of vertice *b* to vertice *a*. Numbers, written on vertices, — piles' sizes. Your task is to get such tree configuration, that each vertice has no more than *k* subtrees suspended to it, and sum of the products of numbers, written on vertices, and vertices' depth (where root's depth is 0) is minimal. In order to minimize the sum, at first, vertice with a larger number must be not deeply than vertice with smaller number (otherwise it's possible to change them and to get less sum), at second, each inner vertice, besides, maybe, one, has exactly *k* successors (the second condition is also proved using proof by contradiction). Now you are to learn how to calculate sum (described above) for this configuration quickly. In order do to it, let's sort piles' size array, and then let's do the following: at first, let's add to answer sum of sizes of piles from 1*st* to *k**th* (in 0-indexed array, sorted in non-increasing order), multiplied by 1; then sum of sizes of next *k*2 piles, multiplied by 2; and so on till the end of array. In order to answer for the query about the sum of segment, precalculate sums of prefixes immediately after array sorting. Now in the case *k* > 1 we can find answer in *O*(*log* *n*). If you follow the same considerations for *k* = 1, answer for query will get *O*(*n*) operations that's why solution will get TL, if *k* is equal to 1 in most of the queries. So you should calculate the answer for *k* = 1 beforehand and memorize it, in order to response such queries in *O*(1).
+
+Complexity — *O*(*n* · *log* *n* + *q* · *log* *n*).
+
+[Implementation](http://pastebin.com/rwVYVMUH)
+
+### [E div2 — C div1. Anniversary](https://codeforces.com/contest/227/problem/E)
+
+At first, let's prove the statement: *GCD*(*F**n*, *F**m*) = *F**GCD*(*n*, *m*).
+
+Let's express *F**n* + *k* using *F**n* and *F**k*. We'll get the formula: *F**n* + *k* = *F**k*·*F**n* + 1 + *F**k* - 1·*F**n*, which is easy to prove by induction.
+
+Then use the derived formula and notice, that *GCD*(*F**n* + *k*, *F**n*) = *GCD*(*F**k*, *F**n*).
+
+Now you are to notice an analogy with [Euclidean algorithm](https://en.wikipedia.org/wiki/Euclidean_algorithm) and to understand, that we've got necessary equality for *GCD* of two Fibonacci numbers.
+
+So, our current task is to find in the given set subset of *k* (or at least of *k*) elements with maximal possible *GCD*. To be exactly, to find this *GCD*.
+
+Let the answer be equal to *q*. Then  - ⌉ + 1 ≥ *k* **(1)** must be true.
+
+Notice, that for each summand from left part of inequality *O*( 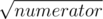 ) segments exist, in which its value is constant. Moreover, we can find all these segments and values in . To be more precise, we are intersted in such *q*, that in the point *q* - 1 value of at least one summand changes (obviously, increases). There are also  such values. Go over all of them and try to use each of them as the answer (i.e., check inequality **(1)** for each of them), and choose maximum from all satisfying numbers. The answer always exists, as *q* = 1 is true for any input.
+
+So, we've found index of required Fibonacci number. The number itself can be calculated by matrix exponentiation.
+
+[Implementation](http://pastebin.com/cDmPBaZ7)
+
+Complexity — 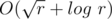.
+
+### [D div1. The table.](https://codeforces.com/contest/226/problem/D)
+
+Let's get the required table. Act in the following way: find any row or column with negative sum and invert it. Notice, that sum of numbers in the entire table will always increase (at least, by 2). It can't increase permanently, because its maximal possible summary change is 200·*n*·*m*. So we'll get the required table anyway. It takes us not more than 100·*n*·*m* operations (applying of the spell), each of those is performed in *O*(*n*) or *O*(*m*). So, we've learned how to get required table in not more than ~ 1004 operations.
+
+Now let's restore the answer. It's easy to understand that it will contain those rows and columns, which we've inverted odd times.
+
+[Implementation](http://pastebin.com/TP0gdKJi)
+
+### [E div1. Noble Knight's Path](https://codeforces.com/contest/226/problem/E)
+
+#### *Solution 1*
+
+It's easy to guess that castles form a tree. Let's build heavy-light decomposition over it. Moreover, let's build persistent segment tree (with sum as the function) over each path. Tree's vertex will contain 0, if castle wasn't attacked by barbarians, and 1 otherwise.
+
+Each knight's path should be divided into not more than two subpaths each of them lays on the path from one of the route's end to tree's root (just use lca in order to do it). Now let's solve the problem for each of the subpaths separately. We should sequentially process paths from heavy-light decomposition and single vertices, which lay on subpath. We are going to count the amount of vertices, which was not visited since year *y* + 1 up to the current year, i.e. (in the case of a path of the decomposition) such vertices, that the difference between values in the current version of persistent segment tree and in the version corresponding to year *y* (use binary search to find required version in the list of versions) is equal to zero (in case with single vertice it's enough to remember time when vertice was visited). As soon as the amount of appropriate vertices become not less than *k*, we should simultaneously walk down in two tree's versions in order to get the answer.
+
+If the *k**th* vertex isn't found on the first subpath, you should pay attention on the fact, that as we always go from down to up, we should accurately recalculate required vertex's number, in order to know it's position in the second subpath from down to up.
+
+Complexity: *O*(*m*·*log*2 *n*) — in each query of the first type it can be necessary to update some segment tree, this action takes *O*(*log* *n*) operations; in each query of the second type there are *O*(*log* *n*) decomposition's paths, each of them is processed in *O*(*log* *n*) (firstly, binary search through versions' list, then query to the tree/walking down).
+
+[Implementation](http://pastebin.com/Le5hN5Xv)
+
+#### *Solution 2*
+
+Let's go round the tree using dfs. When we enter the vertex and when we leave it let's put down vertex's number in the additional array (you can find out that this list has something same with regular brackets sequence). Assign 0 as the second number to all elements of the array. Then build persistent segment tree on the described array.
+
+Now, when the first event happens, we'll assign + 1 to the second number in position of the first occurence of a castle's number, and - 1 to a position of the last one.
+
+In order to answer for the second query, just notice, that we should count sum of the second numbers assigned to positions between first occurences of the vertices *a* and *b* in the array described above for finding the amount of visited vertices in the path connecting them.
+
+Now on each of the paths separately start binary search for an answer — position of required castle. For the answer's check use the idea from the previous paragraph.
+
+Complexity: *O*(*m*·*log*2 *n*) — in each query of the first type it can be necessary to update some segment tree, this action takes *O*(*log* *n*) operations; in each query of the second type there are *O*(*log* *n*) iterations of binary search on answer, each of iterations takes *O*(*log* *n*) operations.
+
+[Implementation](http://pastebin.com/xt2gSrhP)
+
+#### Questions?
diff --git a/editorials/227.md b/editorials/227.md
@@ -0,0 +1,101 @@
+Source: https://codeforces.com/blog/entry/5378
+
+### [A div2. Where do I Turn?](https://codeforces.com/contest/227/problem/A)
+
+Let's consider cross product of vectors  and , which is equal to 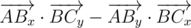. Sign of cross product defines sign of a sine of oriented angle between vectors (because cross product is also equal to 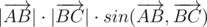), and that sign leads us to the correct answer.
+
+If cross product is equal to zero, then *A*, *B* and *C* lay on the same straight line. So the answer is <>.
+
+If cross product is more than zero, then answer is <>.
+
+And, at last, if it's less than zero, the answer is <>.
+
+Also you should notice that the value of cross product doesn't fit 32-bit type, so you have to use 64-bit type in order to avoid integer overflow.
+
+[Implementation](http://pastebin.com/qMfEbpyi)
+
+### [B div2. Effective Approach](https://codeforces.com/contest/227/problem/B)
+
+Let's assume that number *t* is on the *ind**t**th* position in the original permutation. Then, obviously, during iterating from left to right this number will be found in *ind**t* comparisons, and during iterating from right to left — in *n* - *ind**t* + 1 comparisons. Let's declare additional array, in *i**th* element of each there will be such number *j*, that *a**j* = *i*. This array allows to process each query in *O*(1) using formulas referred above. Additional array is built in *O*(*n*) during iterating array *a*. So, the final complexity is *O*(*n* + *m*).
+
+[Implementation](http://pastebin.com/YiyedFVM)
+
+### [C div2 — A div1. Flying Saucer Segments.](https://codeforces.com/contest/227/problem/C)
+
+Let *F**n* be the answer for the task, where *n* is equal to the amount of aliens. Let's assume, that we've solved problem for *n* - 1 aliens, i.e. we know the value of *F**n* - 1. Let's try to find value of *F**n*. Notice, that the most junior alien in rank will be able to leave the 3*rd* section, if and only if all other aliens are in the 1*st* section. So, now we know first *F**n* - 1 actions. Then the most junior alien may go to the 2*nd* section. To make for him entrance to the 1*st* section possible, it's necessary for all other aliens to return to the first one. So, *F**n* - 1 more actions are necessary. At last, after the most junior alien will go to the 1*st* section, *F**n* - 1 more actions are required for *n* - 1 other aliens to return to the 1*st* section from the 3*rd*. So, *F**n* = *F**n* - 1 + 1 + *F**n* - 1 + 1 + *F**n* - 1. It allows to count *F**n* using matrix exponentiation in *O*(*log* *n*), but we'll improve current solution. Let's add 1 to both parts of the equality and after elementary operations we'll have *F**n* = 3·(*F**n* - 1 + 1) - 1. Now it's easy to solve this reccurence: *F**n* = 3*n* - 1.
+
+To count *F**n* quickly you should use binary power method. Solution's complexity — *O*(*log* *n*).
+
+Don't forget that if 3*n* *mod* *m* = 0, answer is equal to *m* - 1, but not - 1.
+
+And, in conclusion, notice that the task is equal to [Hanoi Towers](https://en.wikipedia.org/wiki/Hanoi_tower) problem with a slight modification (it's impossible to move disks between one pair of rods).
+
+[Implementation](http://pastebin.com/BPLFVFnt)
+
+### [D div2 — B div1. Naughty Stone Piles](https://codeforces.com/contest/227/problem/D)
+
+Consider the following interpretation of the problem: stone piles are graph vertices. Operation "add pile *a* to pile *b*" changes to operation of suspencion of subtree of vertice *b* to vertice *a*. Numbers, written on vertices, — piles' sizes. Your task is to get such tree configuration, that each vertice has no more than *k* subtrees suspended to it, and sum of the products of numbers, written on vertices, and vertices' depth (where root's depth is 0) is minimal. In order to minimize the sum, at first, vertice with a larger number must be not deeply than vertice with smaller number (otherwise it's possible to change them and to get less sum), at second, each inner vertice, besides, maybe, one, has exactly *k* successors (the second condition is also proved using proof by contradiction). Now you are to learn how to calculate sum (described above) for this configuration quickly. In order do to it, let's sort piles' size array, and then let's do the following: at first, let's add to answer sum of sizes of piles from 1*st* to *k**th* (in 0-indexed array, sorted in non-increasing order), multiplied by 1; then sum of sizes of next *k*2 piles, multiplied by 2; and so on till the end of array. In order to answer for the query about the sum of segment, precalculate sums of prefixes immediately after array sorting. Now in the case *k* > 1 we can find answer in *O*(*log* *n*). If you follow the same considerations for *k* = 1, answer for query will get *O*(*n*) operations that's why solution will get TL, if *k* is equal to 1 in most of the queries. So you should calculate the answer for *k* = 1 beforehand and memorize it, in order to response such queries in *O*(1).
+
+Complexity — *O*(*n* · *log* *n* + *q* · *log* *n*).
+
+[Implementation](http://pastebin.com/rwVYVMUH)
+
+### [E div2 — C div1. Anniversary](https://codeforces.com/contest/227/problem/E)
+
+At first, let's prove the statement: *GCD*(*F**n*, *F**m*) = *F**GCD*(*n*, *m*).
+
+Let's express *F**n* + *k* using *F**n* and *F**k*. We'll get the formula: *F**n* + *k* = *F**k*·*F**n* + 1 + *F**k* - 1·*F**n*, which is easy to prove by induction.
+
+Then use the derived formula and notice, that *GCD*(*F**n* + *k*, *F**n*) = *GCD*(*F**k*, *F**n*).
+
+Now you are to notice an analogy with [Euclidean algorithm](https://en.wikipedia.org/wiki/Euclidean_algorithm) and to understand, that we've got necessary equality for *GCD* of two Fibonacci numbers.
+
+So, our current task is to find in the given set subset of *k* (or at least of *k*) elements with maximal possible *GCD*. To be exactly, to find this *GCD*.
+
+Let the answer be equal to *q*. Then  - ⌉ + 1 ≥ *k* **(1)** must be true.
+
+Notice, that for each summand from left part of inequality *O*( 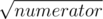 ) segments exist, in which its value is constant. Moreover, we can find all these segments and values in . To be more precise, we are intersted in such *q*, that in the point *q* - 1 value of at least one summand changes (obviously, increases). There are also  such values. Go over all of them and try to use each of them as the answer (i.e., check inequality **(1)** for each of them), and choose maximum from all satisfying numbers. The answer always exists, as *q* = 1 is true for any input.
+
+So, we've found index of required Fibonacci number. The number itself can be calculated by matrix exponentiation.
+
+[Implementation](http://pastebin.com/cDmPBaZ7)
+
+Complexity — 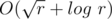.
+
+### [D div1. The table.](https://codeforces.com/contest/226/problem/D)
+
+Let's get the required table. Act in the following way: find any row or column with negative sum and invert it. Notice, that sum of numbers in the entire table will always increase (at least, by 2). It can't increase permanently, because its maximal possible summary change is 200·*n*·*m*. So we'll get the required table anyway. It takes us not more than 100·*n*·*m* operations (applying of the spell), each of those is performed in *O*(*n*) or *O*(*m*). So, we've learned how to get required table in not more than ~ 1004 operations.
+
+Now let's restore the answer. It's easy to understand that it will contain those rows and columns, which we've inverted odd times.
+
+[Implementation](http://pastebin.com/TP0gdKJi)
+
+### [E div1. Noble Knight's Path](https://codeforces.com/contest/226/problem/E)
+
+#### *Solution 1*
+
+It's easy to guess that castles form a tree. Let's build heavy-light decomposition over it. Moreover, let's build persistent segment tree (with sum as the function) over each path. Tree's vertex will contain 0, if castle wasn't attacked by barbarians, and 1 otherwise.
+
+Each knight's path should be divided into not more than two subpaths each of them lays on the path from one of the route's end to tree's root (just use lca in order to do it). Now let's solve the problem for each of the subpaths separately. We should sequentially process paths from heavy-light decomposition and single vertices, which lay on subpath. We are going to count the amount of vertices, which was not visited since year *y* + 1 up to the current year, i.e. (in the case of a path of the decomposition) such vertices, that the difference between values in the current version of persistent segment tree and in the version corresponding to year *y* (use binary search to find required version in the list of versions) is equal to zero (in case with single vertice it's enough to remember time when vertice was visited). As soon as the amount of appropriate vertices become not less than *k*, we should simultaneously walk down in two tree's versions in order to get the answer.
+
+If the *k**th* vertex isn't found on the first subpath, you should pay attention on the fact, that as we always go from down to up, we should accurately recalculate required vertex's number, in order to know it's position in the second subpath from down to up.
+
+Complexity: *O*(*m*·*log*2 *n*) — in each query of the first type it can be necessary to update some segment tree, this action takes *O*(*log* *n*) operations; in each query of the second type there are *O*(*log* *n*) decomposition's paths, each of them is processed in *O*(*log* *n*) (firstly, binary search through versions' list, then query to the tree/walking down).
+
+[Implementation](http://pastebin.com/Le5hN5Xv)
+
+#### *Solution 2*
+
+Let's go round the tree using dfs. When we enter the vertex and when we leave it let's put down vertex's number in the additional array (you can find out that this list has something same with regular brackets sequence). Assign 0 as the second number to all elements of the array. Then build persistent segment tree on the described array.
+
+Now, when the first event happens, we'll assign + 1 to the second number in position of the first occurence of a castle's number, and - 1 to a position of the last one.
+
+In order to answer for the second query, just notice, that we should count sum of the second numbers assigned to positions between first occurences of the vertices *a* and *b* in the array described above for finding the amount of visited vertices in the path connecting them.
+
+Now on each of the paths separately start binary search for an answer — position of required castle. For the answer's check use the idea from the previous paragraph.
+
+Complexity: *O*(*m*·*log*2 *n*) — in each query of the first type it can be necessary to update some segment tree, this action takes *O*(*log* *n*) operations; in each query of the second type there are *O*(*log* *n*) iterations of binary search on answer, each of iterations takes *O*(*log* *n*) operations.
+
+[Implementation](http://pastebin.com/xt2gSrhP)
+
+#### Questions?
diff --git a/editorials/228.md b/editorials/228.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/5404
+
+[228A - Is your horseshoe on the other hoof?](/contest/228/problem/A "Codeforces Round 141 (Div. 2)")
+
+In this problem you should count different numbers from input *cnt* and print 4–*cnt*. You could do it in different ways. For example, you could use set.
+
+[228B - Two Tables](/contest/228/problem/B "Codeforces Round 141 (Div. 2)")
+
+In this problem you should carefully consider every shift - *N* < = *x*, *y* < = *N*, count the answer and find the maximum value. The complexity of solution is *O*(*N*4).
+
+[228C - Fractal Detector](/contest/228/problem/C "Codeforces Round 141 (Div. 2)")
+
+This problem could be solved using dynamic programming. State *z*[*x*][*y*][*st*][*mask*] means if the square with upper left corner (*x*, *y*) is fractal with nesting level *st* and colors *mask*. The value *z*[*x*][*y*][*st*][*mask*] is 0 or 1. There are *O*(*N*2·*Log*(*N*)·24) states in this dynamic programming.
+
+The transitions from state to state are rather simple. If *st* = 1 you should fairly check that the square 2*2 with upper left corner (*x*, *y*) matches colors of *mask*. If *st* > 1 you should divide the square into four parts and check them separately. If the value in *mask* in one quarter means black color, you should check that the whole quarter is black. It could be done using partial sums on rectangles using *O*(1) of time. If the quarter is white, you should check that it is a fractal with nesting level *st* - 1 with the same *mask*. So, there are less than 4 transitions from every state.
+
+To get the answer to the problem you should consider every upper left corner of squares, every mask and every nesting level of fractal and check this square. It is done using your dynamic.
+
+[228D - Zigzag](/contest/228/problem/D "Codeforces Round 141 (Div. 2)")
+
+In this problem we will use that sequence *s* is cyclic because of its structure. Also, it is important that 2 < = *z* < = 6. For every *z* we will write the sequence *s* and note that its period is 2 * (*z*–1).
+
+So, for every *z* and modulo 0 < = *mod* < 2 * (*z*–1) we will build separate segment tree or Fenwick tree. You should be careful with memory, it needs *O*(*Z*·(2·*Z*)·*N*) of memory. So, if the query is to update some value, we should update *z* values of trees with correct modules. If the query is to find sum, we should consider every 2·(*z*–1) modules, count the sum and multiply by correct coefficient from sequence *s*. The complexity is *O*(*Z*·*N*·*Log*(*N*)).
+
+[228E - The Road to Berland is Paved With Good Intentions](/contest/228/problem/E "Codeforces Round 141 (Div. 2)")
+
+This problem can be solved in different ways. It was expected the solution that solved the system of modular equations using Gauss algorithm. Here is another simple solution.
+
+The vertices from the result call switched-on. Firstly, note that every vertex should be switched-on no more than once. Then, consider every edge (*x*, *y*) of color *c*. We want to make its color 1. So, if *c* = 1 we should switch on vertices *x* and *y* or don’t switch them on simultaneously. If *c* = 0 we should switch on *x* or *y*. So, consider some vertex *v* and try to switch it on or not. Thus, we can uniquely determine the state of every vertex of the same connected component as *v*. If we face some collision, we can’t get the solution, you should print Impossible. The solution can be realized using bfs with complexity *O*(*N* + *M*).
diff --git a/editorials/229.md b/editorials/229.md
@@ -0,0 +1,58 @@
+Source: https://codeforces.com/blog/entry/5437
+
+### [Div. 2 A — Dragons](/contest/230/problem/A)
+
+Observe that if Kirito fights a dragon whose strength is less than Kirito's strength, then Kirito does not lose anything — in fact, he even gains a nonnegative strength increase. Taking note of this, let's for each step choose some dragon whose strength is less than Kirito's current strength, and fight it. After performing some amount of these steps we'll eventually end up in one of these two situations: either all dragons are slain (then the answer is "YES"), or only dragons whose strength is not less than Kirito's strength remain (then the answer is "NO"). On each step we can choose a suitable dragon to fight either by searching through all dragons or by sorting the dragons by strength in non-descending order in advance.
+
+The complexity of the solution is *O*(*n*2) or . Sample solution: <http://pastie.org/4897164> ([archived copy](https://web.archive.org/web/20170102021203/http://pastie.org:80/4897164))
+
+### [Div. 2 B — T-primes](/contest/230/problem/B)
+
+It can be shown that only squares of prime numbers are T-primes, and that there are not too many of them — as many as there are prime numbers not greater than . Precompute these numbers (using, for example, the sieve of Eratosthenes) and store them in an array or an `std::set`, then we can answer each query by simply checking whether the number in question is amongst the precomputed numbers.
+
+The complexity of the solution is linear in relation to *n* — 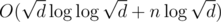 or 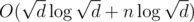, where *d* = 1012 (one can also get a tighter bound). Sample solution: <http://pastie.org/4897166> ([archived copy](https://web.archive.org/web/20161225205232/http://pastie.org/4897166))
+
+### [Div. 1 A — Shifts](/contest/229/problem/A)
+
+Let's compute the minimum number of operations needed to get all 1s in each of the *m* columns. For this, traverse each row twice — one time to the left and one time to the right, recording the index of the nearest cell with 1 (in corresponding direction) for each column in this row. Then the number of operations for any particular column is the sum of the computed values over all rows. In turn, the answer to the problem is the minimal value of these sums.
+
+The complexity of the solution is *O*(*nm*). Sample solution: <http://pastie.org/4897169> ([archived copy](https://web.archive.org/web/20150723073039/http://pastie.org/4897169))
+
+### [Div. 1 B — Planets](/contest/229/problem/B)
+
+Observe that when we visit some planet, the best strategy is to arrive as early as we can and then wait for the nearest free moment of time to move further. Hence this problem can be solved with the Dijkstra's algorithm by slightly altering the definition of a shortest distance. When we process a planet (meaning that we already know the minimum time needed to reach it), we need to check the array of arrival times for this planet and find the first moment of time in which we can leave this planet — this will be the distance that we will be adding to outgoing paths from this planet. It's clear that we will traverse each array of arrival times no more than once. Additionally, one must pay attention to these cases: when a traveller arrives to planet 1 at time 0 (then Jack has to wait) and when a traveller arrives to planet *n* at the same time as Jack (then Jack needs not to wait).
+
+The complexity of the solution — 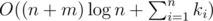. Sample solution: <http://pastie.org/4897171> ([archived copy](https://web.archive.org/web/20160409073253/http://pastie.org/4897171))
+
+### [Div. 1 C — Triangles](/contest/229/problem/C)
+
+Let's call Alice's edges simply edges, and Bob's edges the antiedges. For each edge pair of the initial complete graph that pass through the same vertices, assign a weight: for each pair of edges the weight +2, for each pair of edge and antiedge −1 and for each pair of antiedges +2. Now calculate the sum of all the weights. Observe that each Alice's or Bob's triangle adds exactly +6 to the sum, and each combination of three vertices that do not form the triangle in any of the two graphs adds exactly 0 to the sum. The sum itself is calculated by iterating over all vertices and adding the total weight of all the edge pairs that pass through this vertex. If the degree of the vertex is *d*, then we should add 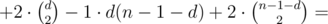 *d*(*d* - 1) - *d*(*n* - *d* - 1) + (*n* - *d* - 1)(*n* - *d* - 2) to the final sum. Since each triangle adds +6 to the sum, then the answer is equal to the sum divided by 6.
+
+The complexity of the solution is *O*(*n* + *m*). Sample solution: <http://pastie.org/4897512> ([archived copy](https://web.archive.org/web/20160409073145/http://pastie.org/4897512))
+
+### [Div. 1 D — Towers](/contest/229/problem/D)
+
+Let's calculate the dynamics `d[i][k]` — the minimal possible height of the last tower that we can obtain by merging the first *i* left towers into at least *k* towers. Assume we already have calculated the dynamics' values for the first *i* towers. Now we iterate over the all possible tower intervals [*i* + 1;*j*]; say the sum in the pending interval is equal to *s*. Now we find the greatest *k* such that `d[i][k]` is not greater than *s*. Then we update the value of `d[j][k+1]` to the minimum of *s* and `d[j][k+1]`. Notice that when *k* increases the values `d[i][k]` do not decrease. Because of that we can iterate over intervals in the decreasing value of *j*, and corresponding *k* can be found using a single pointer over values of `d[i][k]`.
+
+When we arrive in the position *j* during the dynamics, some of the `d[j][k]` values are updated, but some are still not. Using the same observation that along with the increasing of *k* the values `d[j][k]` do not decrease as well, we can make a single run over the values of *k* in the decreasing order and update the dynamics' values as follows: `d[j][k] := min(d[j][k], d[j][k+1])`. This is done in the beginning of the dynamics' iteration.
+
+In the end we can find the greatest *k* for which there exists an answer among the values of `d[n][k]`. The answer to the problem then is *n* - *k*.
+
+The complexity of the solution is *O*(*n*2). Sample solution: <http://pastie.org/4897515> ([archived copy](https://web.archive.org/web/20161109061650/http://pastie.org/4897515))
+
+### [Div. 1 E — Gifts](/contest/229/problem/E)
+
+First let's establish some facts that we will use in the solution. With how much probability can the fisherman get a particular set of gifts, among which there are *a**i* gifts of *i*-th name? In total there are 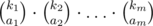 such sets, since there are exactly  subsets of gifts with *i*-th name of size *a**i*, and two different names are independent during the gold fish's choice. Then the described particular set of gifts we can get with the probability of 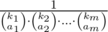, by asking *a**i* gifts of *i*-th name.
+
+Now we know the probability *p* of obtaining one particular gift set *A*. Now observe that from *p* we can calculate the probabiltity *p*' of obtaining the set *A* along with some one other gift of *x*-th name in constant time. Say there are already *a**x* elements of *x*-th name in *A*. Using the formula from the first paragraph, we can deduce that:
+
+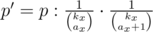 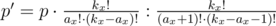 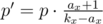
+
+Let's solve the main problem now. We sort all the gifts in descending order of their prices. It is clear that the fisherman will definitely ask the names of all the gifts among the first *n* ones whose prices are not equal to the price of the *n*-th gift in the list. Let's say that this set of gifts is the base, and it has *b* elements. Then there is still *n* - *b* unchosen gifts, and we know that all of them will have the price equal to the price of the *n*-th gift in the list. Say the price of the *n*-th gift is *d*, and there are exactly *s* gifts with the price *d* (keep in mind that each of them has a different name); also call these gifts dubious. We can also deduce that the fisherman can make  different decisions, where *l* = *n* - *b*.
+
+So now we have some *s* dubious gifts with the price of *d*; let's enumerate them in any order. We calculate the dynamics *f*(*x*, *y*) — the cumulative probability of obtaining *n* most valuable gifts, if there are *x* chosen from the first *y* in the list. It is clear that *f*(0, 0) = *p*, and *f*(*l*, *s*) contains the answer to the problem. Using the coefficients we have deduced earlier, we get two transitions in the dynamics:
+
+1. 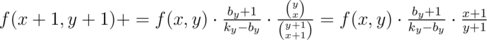, if we add *y* + 1-th dubious gift to the set of *x* chosen among the first *y* dubious gifts;
+2. 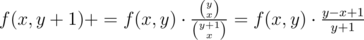, otherwise, if do not put the *y* + 1-th dubious gift. This dynamics can be computed in *O*(*t*2) time, where *t* is the total number of gifts.
+
+The complexity of the solution is 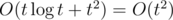. Sample solution: <http://pastie.org/4897519> ([archived copy](https://web.archive.org/web/20160409073206/http://pastie.org/4897519))
diff --git a/editorials/23.md b/editorials/23.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/530
+
+### A. [You're given a string...](../../../contest/23/problem/A)
+
+
+Iterate over all substrings, starting with the longest ones, and for each one count the number of appearances. The complexity is *O*(*L*4) with a small multiplicative constant.
+
+
+### B. [Party](../../../contest/23/problem/B)
+
+
+It's clear that at least one person (the one with the least number of friends) will have to leave. We claim that at least two persons will leave. Indeed, suppose that only one person left, and he had *d* friends. Then all other people had more than *d* friends before he left, and after that they had less than *d* + 1 friends, i.e. not more than *d*. So, his leaving influenced the number of friends for every other person, which means that he was friends with everyone: *d* = *N* - 1. But he has fewer friends than everyone — a contradiction.
+
+So, the answer is not more than *N* - 2. We'll prove that it's possible for *N* - 2 people to stay (of course, if *N* > 1). The graph of friendship will be the following: take a complete graph on *N* vertices and delete one edge. Then the degrees of two vertices equal *N* - 2, and other degrees equal *N* - 1. After the first two vertices are removed, we have a complete graph on *N* - 2 vertices, and all degrees equal *N* - 3, which means that no one else will leave.
+
+
+### C. [Oranges and Apples](../../../contest/23/problem/C)
+
+
+Sort the boxes in increasing number of oranges. Count the total number of apples in boxes with odd and even numbers. If the boxes with odd numbers contain at least half of all apples, choose them (there are exactly *N* boxes with odd numbers). If the boxes with even numbers contain at least half of all apples, take them and the last box (which contains the largest number of oranges). It's easy to see that in both cases the conditions of the task are fulfilled.
+
+
+### D. [Tetragon](../../../contest/23/problem/D)
+
+
+Let ABCD be the quadrangle that we're looking for, and K, L, and M be the middle points of equal sides AB, BC and CD, correspondingly. Let M' be the point symmetric to M with respect to L. Triangles BLM' and CLM are equal by two sides and angle, so BM' = CM = BL = BK, i. e. B is the circumcenter of the triangle KLM'.
+
+Knowing B, we can reconstruct the whole quadrangle, using the symmetries with respect to the points K, L, and M, and then check whether it satisfies all conditions.
+Note that we don't know which of the given points is L, so we need to check all 3 cases.
+
+
+### E. [Tree](../../../contest/23/problem/E)
+
+
+**Lemma**. In one of optimal solutions there are no simple paths of length 3.
+**Proof**. We can remove the middle edge from such a path. The connected component will split into two components of sizes *a* and *b*, where *a* ≥ 2, *b* ≥ 2, and therefore *ab* ≥ *a* + *b*.
+
+We'll root the tree and calculate recursively the numbers *h**v* = the solution of the problem for the subtree with the root *v*, and *f**v* = the product of *h**u* for all children of *v*. If *v* is a leaf, then *h**v* = *f**v* = 1.
+
+We show how to calculate *h**v*, given the solution for all subtrees of *v*. Consider the connected component of *v* in an optimal solution. It follows from the lemma that the component has one of the following types:
+1. The single vertex *v*.
+2. The vertex *v* and several children of *v*.
+3. The vertex *v*, one child of *v* — *w*, and several children of *w*.
+
+In the first case the result of the game is *f**v*.
+
+In the second case it equals *Πf**i* · *Πh**j* · *k* = *Π*(*f**i* / *h**i*) · *f**v* · *k*, where *i* iterates over children belonging to the connected component, *j* iterates over the rest children, and *k* is the size of the component. Since we want to maximize the result, we're interested in children with the largest value of *f**i* / *h**i*. Therefore, the largest possible result in this case equals the maximum value of *Π**i* ≤ *s* (*f**i* / *h**i*) · *f**v* · (*s* + 1), where it's supposed that the children are sorted in descending order of *f**i* / *h**i*.
+
+In the third case we can use a similar reasoning for every child *w*. The best result will be the maximum of the expression *f**v* · (*f**w* / *h**w*) · *Π**i* ≤ *s* (*f**i* / *h**i*) · (*s* + 2) as *w* iterates over children of *v*, and *s* iterates from 1 to the number of children of *w*; note that the children of *w* have already been sorted in the previous step.
+
+Therefore, the number of operations necessary to calculate *f**v* is proportional to the total number of children and grandchildren of *v*, which is less than *n*. The complexity of the algorithm, then, is *O*(*n*2) (ignoring operations with long numbers).
diff --git a/editorials/230.md b/editorials/230.md
@@ -0,0 +1,58 @@
+Source: https://codeforces.com/blog/entry/5437
+
+### [Div. 2 A — Dragons](/contest/230/problem/A)
+
+Observe that if Kirito fights a dragon whose strength is less than Kirito's strength, then Kirito does not lose anything — in fact, he even gains a nonnegative strength increase. Taking note of this, let's for each step choose some dragon whose strength is less than Kirito's current strength, and fight it. After performing some amount of these steps we'll eventually end up in one of these two situations: either all dragons are slain (then the answer is "YES"), or only dragons whose strength is not less than Kirito's strength remain (then the answer is "NO"). On each step we can choose a suitable dragon to fight either by searching through all dragons or by sorting the dragons by strength in non-descending order in advance.
+
+The complexity of the solution is *O*(*n*2) or . Sample solution: <http://pastie.org/4897164> ([archived copy](https://web.archive.org/web/20170102021203/http://pastie.org:80/4897164))
+
+### [Div. 2 B — T-primes](/contest/230/problem/B)
+
+It can be shown that only squares of prime numbers are T-primes, and that there are not too many of them — as many as there are prime numbers not greater than . Precompute these numbers (using, for example, the sieve of Eratosthenes) and store them in an array or an `std::set`, then we can answer each query by simply checking whether the number in question is amongst the precomputed numbers.
+
+The complexity of the solution is linear in relation to *n* — 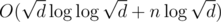 or 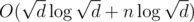, where *d* = 1012 (one can also get a tighter bound). Sample solution: <http://pastie.org/4897166> ([archived copy](https://web.archive.org/web/20161225205232/http://pastie.org/4897166))
+
+### [Div. 1 A — Shifts](/contest/229/problem/A)
+
+Let's compute the minimum number of operations needed to get all 1s in each of the *m* columns. For this, traverse each row twice — one time to the left and one time to the right, recording the index of the nearest cell with 1 (in corresponding direction) for each column in this row. Then the number of operations for any particular column is the sum of the computed values over all rows. In turn, the answer to the problem is the minimal value of these sums.
+
+The complexity of the solution is *O*(*nm*). Sample solution: <http://pastie.org/4897169> ([archived copy](https://web.archive.org/web/20150723073039/http://pastie.org/4897169))
+
+### [Div. 1 B — Planets](/contest/229/problem/B)
+
+Observe that when we visit some planet, the best strategy is to arrive as early as we can and then wait for the nearest free moment of time to move further. Hence this problem can be solved with the Dijkstra's algorithm by slightly altering the definition of a shortest distance. When we process a planet (meaning that we already know the minimum time needed to reach it), we need to check the array of arrival times for this planet and find the first moment of time in which we can leave this planet — this will be the distance that we will be adding to outgoing paths from this planet. It's clear that we will traverse each array of arrival times no more than once. Additionally, one must pay attention to these cases: when a traveller arrives to planet 1 at time 0 (then Jack has to wait) and when a traveller arrives to planet *n* at the same time as Jack (then Jack needs not to wait).
+
+The complexity of the solution — 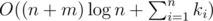. Sample solution: <http://pastie.org/4897171> ([archived copy](https://web.archive.org/web/20160409073253/http://pastie.org/4897171))
+
+### [Div. 1 C — Triangles](/contest/229/problem/C)
+
+Let's call Alice's edges simply edges, and Bob's edges the antiedges. For each edge pair of the initial complete graph that pass through the same vertices, assign a weight: for each pair of edges the weight +2, for each pair of edge and antiedge −1 and for each pair of antiedges +2. Now calculate the sum of all the weights. Observe that each Alice's or Bob's triangle adds exactly +6 to the sum, and each combination of three vertices that do not form the triangle in any of the two graphs adds exactly 0 to the sum. The sum itself is calculated by iterating over all vertices and adding the total weight of all the edge pairs that pass through this vertex. If the degree of the vertex is *d*, then we should add 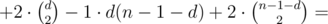 *d*(*d* - 1) - *d*(*n* - *d* - 1) + (*n* - *d* - 1)(*n* - *d* - 2) to the final sum. Since each triangle adds +6 to the sum, then the answer is equal to the sum divided by 6.
+
+The complexity of the solution is *O*(*n* + *m*). Sample solution: <http://pastie.org/4897512> ([archived copy](https://web.archive.org/web/20160409073145/http://pastie.org/4897512))
+
+### [Div. 1 D — Towers](/contest/229/problem/D)
+
+Let's calculate the dynamics `d[i][k]` — the minimal possible height of the last tower that we can obtain by merging the first *i* left towers into at least *k* towers. Assume we already have calculated the dynamics' values for the first *i* towers. Now we iterate over the all possible tower intervals [*i* + 1;*j*]; say the sum in the pending interval is equal to *s*. Now we find the greatest *k* such that `d[i][k]` is not greater than *s*. Then we update the value of `d[j][k+1]` to the minimum of *s* and `d[j][k+1]`. Notice that when *k* increases the values `d[i][k]` do not decrease. Because of that we can iterate over intervals in the decreasing value of *j*, and corresponding *k* can be found using a single pointer over values of `d[i][k]`.
+
+When we arrive in the position *j* during the dynamics, some of the `d[j][k]` values are updated, but some are still not. Using the same observation that along with the increasing of *k* the values `d[j][k]` do not decrease as well, we can make a single run over the values of *k* in the decreasing order and update the dynamics' values as follows: `d[j][k] := min(d[j][k], d[j][k+1])`. This is done in the beginning of the dynamics' iteration.
+
+In the end we can find the greatest *k* for which there exists an answer among the values of `d[n][k]`. The answer to the problem then is *n* - *k*.
+
+The complexity of the solution is *O*(*n*2). Sample solution: <http://pastie.org/4897515> ([archived copy](https://web.archive.org/web/20161109061650/http://pastie.org/4897515))
+
+### [Div. 1 E — Gifts](/contest/229/problem/E)
+
+First let's establish some facts that we will use in the solution. With how much probability can the fisherman get a particular set of gifts, among which there are *a**i* gifts of *i*-th name? In total there are 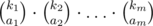 such sets, since there are exactly  subsets of gifts with *i*-th name of size *a**i*, and two different names are independent during the gold fish's choice. Then the described particular set of gifts we can get with the probability of 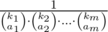, by asking *a**i* gifts of *i*-th name.
+
+Now we know the probability *p* of obtaining one particular gift set *A*. Now observe that from *p* we can calculate the probabiltity *p*' of obtaining the set *A* along with some one other gift of *x*-th name in constant time. Say there are already *a**x* elements of *x*-th name in *A*. Using the formula from the first paragraph, we can deduce that:
+
+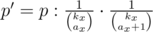 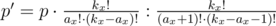 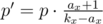
+
+Let's solve the main problem now. We sort all the gifts in descending order of their prices. It is clear that the fisherman will definitely ask the names of all the gifts among the first *n* ones whose prices are not equal to the price of the *n*-th gift in the list. Let's say that this set of gifts is the base, and it has *b* elements. Then there is still *n* - *b* unchosen gifts, and we know that all of them will have the price equal to the price of the *n*-th gift in the list. Say the price of the *n*-th gift is *d*, and there are exactly *s* gifts with the price *d* (keep in mind that each of them has a different name); also call these gifts dubious. We can also deduce that the fisherman can make  different decisions, where *l* = *n* - *b*.
+
+So now we have some *s* dubious gifts with the price of *d*; let's enumerate them in any order. We calculate the dynamics *f*(*x*, *y*) — the cumulative probability of obtaining *n* most valuable gifts, if there are *x* chosen from the first *y* in the list. It is clear that *f*(0, 0) = *p*, and *f*(*l*, *s*) contains the answer to the problem. Using the coefficients we have deduced earlier, we get two transitions in the dynamics:
+
+1. 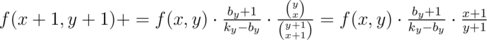, if we add *y* + 1-th dubious gift to the set of *x* chosen among the first *y* dubious gifts;
+2. 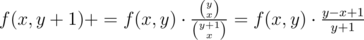, otherwise, if do not put the *y* + 1-th dubious gift. This dynamics can be computed in *O*(*t*2) time, where *t* is the total number of gifts.
+
+The complexity of the solution is 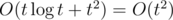. Sample solution: <http://pastie.org/4897519> ([archived copy](https://web.archive.org/web/20160409073206/http://pastie.org/4897519))
diff --git a/editorials/231.md b/editorials/231.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/5486
+
+[231A - Team](/contest/231/problem/A "Codeforces Round 143 (Div. 2)")
+
+It is needed just to implement actions described in statement. You had to read data and to calculate number of members of team, which were sure about the solution, for every task. If this number is greater than one, the answer must be increased by one.
+
+[231B - Magic, Wizardry and Wonders](/contest/231/problem/B "Codeforces Round 143 (Div. 2)")
+
+Let's see, what will be the last number of array after *i* iterations. After the first iteration it will be *a**n* - 1–*a**n* (and total number of elements will be decreased by one). After the second iteration the last number will be *a**n* - 2–*a**n* - 1 + *a**n*. It is not hard to see, that after *n* - 1 iterations remain *a*1–*a*2 + *a*3–*a*4 + ... + ( - 1)*n* + 1·*a**n*. In a such way, our task is to put numbers from 1 to *l* in array so, that sum of numbers in odd positions minus sum of numbers in even positions will equal to given *d*. This means sum of numbers in odd positions must be equal 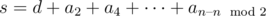. But the minimal sum can be , and the maximal — 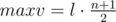.
+
+Because of this we should choose *a*2·*k* so, that *s* fits the boundaries. Constrains allow to do it in a such manner. Firstly, put ones on the even positions. If *s* > *maxv* after that, the answer is - 1. Otherwise, let's increase each *a*2·*k* by one until *s* = *minv*. If we put *l* in all even positions and *s* < *minv*, than answer is - 1 too. After we put numbers on even positions, let's write 1 in all odd positions, and while sum of this elements is less than *s* increase each one by fitting value.
+
+[231C - To Add or Not to Add](/contest/231/problem/C "Codeforces Round 143 (Div. 2)")
+
+One of the main observations, needed to solve this problem, is that the second number in answer always coincides with someone *a**j*. Let's see why it is true. Suppose, the second number of the answer is *a**j* + *d* for someone *j* and *a**j* + *d* ≠ *a**i* for all *i*. This means, we increased some numbers, which is less than *a**j*, so that they became equal to *a**j*, and then all this numbers and some numbers, which is equal to *a**j*, we increased to *a**j* + *d*. But if we didn't increase all this numbers to *a**j* + *d* and remain they equal to *a**j*, we'd perform less operations and the answer would be better.
+
+Due to this fact we can solve problem in a such manner. Sort array in non-decreasing order. Iterate over *a**i* and calculate, what is the maximal number of *a**i* we can obtain. For maximizing first number of answer, we must increase some lesser numbers to *a**i* and perform not greater than *k* operations. It is obvious that firstly we should increase such *a**j* that *a**i*–*a**j* is minimal. So, if we can solve problem in *O*(*n*2), we would iterate *j* from *i* to 0 and increase *a**j* to *a**i*, while we could. But the solution must be faster, and we will use binary search. We will brute the number of numbers, which we must do equal to *a**i*. Suppose we fix *cnt* this value. Now we have to check if we can do *cnt* numbers equal to *a**i* by not greater than *k* operations. For doing this, let’s calculate 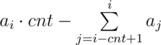. If this value not greater than *k*, we can do it. For calculating sum quickly, we can save prefix sums and than *s**i* - *cnt* + 1, *i* = *s**i*–*s**i*–*cnt*. Finally we solved this problem in *O*(*n*·*logn*).
+
+[231D - Magic Box](/contest/231/problem/D "Codeforces Round 143 (Div. 2)")
+
+The main subtask of this problem is to check whether we can observe the center of face of parallelepiped from point *p* = (*x*, *y*, *z*). Let’s see the case, when the face belongs to plane *z* = *z*1. For performing all calculations in integer numbers, multiply all coordinates *x*, *y*, *z*, *x*1, *y*1, *z*1 by 2. Take the point 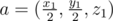 and normal to plane, containing the fixed face, which is directed out of interior of parallelepiped, that is . Also take vector . If undirected angle between this vectors is less than 90 degrees, we can observe *a* from *p*. For checking this we can use scalar product. If scalar product of  and  is strictly greater than zero, than that angle is fitting.
+
+[231E - Cactus](/contest/231/problem/E "Codeforces Round 143 (Div. 2)")
+
+In this problem you should find the number of simple paths between some pair of vertices in vertex cactus. If you learn the structure of these graphs, it is not hard to see, that if we’ll squeeze each cycle in one vertex, we get a tree. So let’s squeeze all cycles in source graph and get this tree. Also every vertex of this tree we’ll mark, if it is squeezed cycle (let’s call this vertices *1-vertices*) or single vertex in source graph (this vertices we’ll call *0-vertices*).
+
+Then, we’ll do the following to find the number of paths between vertices *a* and *b* in source graph. Suppose *c* is a vertex, corresponding to *a* in obtained tree (it can be a single vertex or a vertex, corresponding to a squeezed cycle with *a*), and *d* is a vertex, corresponding to *b*. Let’s denote *deg* is the number of 1-vertices in path from *c* to *d* in tree. Than it is easy to understand, that the answer for query is 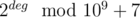, because every cycle (1-vertex) increase the number of possible ways twice (you can go from one vertex to other by two ways in cycle).
+
+It means that we need to count the number of 1-vertex on the path from one vertex to other in tree quickly to answer a query. We can do it in a following way. Hang our tree for one vertex, which we’ll call a root. Denote for every vertex *cnt**v* is the number of 1-vertex on the way to the root (including root and vertex itself). Suppose we want to find the number of 1-vertex on the path from *a* to *b*. Denote *c* is the least common ancestor of vertices *a* and *b*. Than number of 1-vertex on the way from *a* to *b* is equal to *cnt**a* + *cnt**b*–2·*cnt**c*, if *c* is 0-vertex and *cnt**a* + *cnt**b*–2·*cnt**c* + 1, if *c* is 1-vertex. The least common ancestor can be found by standard method — binary method recovery. Finally we have *O*(*m* + *k*·*logn*) solution.
diff --git a/editorials/232.md b/editorials/232.md
@@ -0,0 +1,138 @@
+Source: https://codeforces.com/blog/entry/5514
+
+It will be finised in few hours. If you don't understand something, ask your questions, please.
+
+[233A - Perfect Permutation](/contest/233/problem/A "Codeforces Round 144 (Div. 2)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Consider permutation *p* such that *p**i* = *i*. Actually *p* is a sequence of numbers from 1 to *n*. Obviously *p**p**i* = *i*. Now the only trick is to change the permutation to satisfy the second equation: *p**i* ≠ *i*. Let's swap every two consequtive elements. More formally, for each *k*: 2*k* ≤ *n* let's swap *p*2*k* - 1 and *p*2*k*. It's easy to see that the obtained permutation satisfies both equations for every *n* with the only exception: when *n* is odd, there is no answer and we should print - 1.
+
+[233B - Non-square Equation](/contest/233/problem/B "Codeforces Round 144 (Div. 2)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Gerald](/profile/Gerald "Master Gerald") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Firstly let's find the interval of possible values of *s*(*x*). Hence *x*2 ≤ *n* and *n* ≤ 1018, *x* ≤ 109. In other words, for every considerable solution *x* the decimal length of *x* does not extend 10 digits. So *s**max* ≤ *s*(9999999999) = 10·9 = 90.
+
+Let's bruteforce the value of *s*(*x*) (0 ≤ *s*(*x*) ≤ 90). Now we have an ordinary square equation. The deal is to solve it and to check that the current bruteforced value of *s*(*x*) is equal to sum of digits of the solution. If the solution exists and the equality holds, we should relax the answer.
+
+It seems that the most error-generating part of this problem is solving the equation.
+
+Knowing arrays is not neccessary to solve these two problems.
+
+[232A - Cycles](/contest/232/problem/A "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash"), [fdoer](/profile/fdoer "Expert fdoer") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's add edge in order of increasing *a* and for equal *b* in order of increasing *b* (here *a* and *b* — the least and the greatest vertices of the edge). If the new edge adds too much 3-cycles, we won't add it. We can count the number of new 3-cycles in *O*(*n*) complexity (they all contain the new edge, so it's enough to check all variants of the third vertex). Obviously we will obtain some proper graph, because we can always add a vertex and two edges to make a new triangle. So, there is always an answer. The complexity of this solution is *O*(*n*3).
+
+Let's proof that 100 vertices are always enough for the given restrictions on *n*.
+
+* For some *p* after first *p* iterations we will have a complete graph of *p* vertices.
+* Now we have exactly *C*(*p*, 3) triangles. Consider *p* such that *C*(*p*, 3) ≤ *k* and *C*(*p*, 3) is maximal.
+* For the given restrictions *p* ≤ 85.
+* From this moment, if we add *u* from some vertex, we increase the total number of 3-cycles on *C*(*u*, 2).
+* So we have to present a small number that is less than *C*(85, 3) as sum of *C*(*i*, 2).
+* The first number we subtruct will differ *C*(85, 1) on some value not greater than *C*(85, 1) = 85, because *C*(*n*, *k*) - *C*(*n* - 1, *k*) = *C*(*n* - 1, *k* - 1).
+* The second number we subtruct will differ the number we have on some value not greater than *C*(14, 1) = 14.
+* and so on.
+* For every *k* it's enough to use not more that 90 vertices.
+
+[232B - Table](/contest/232/problem/B "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Skird](/profile/Skird "Expert Skird") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+* Let *s**i* number of points in the column *i*.
+
+
+
+* Two neighboring squares are drawn at this picture, *A* is the number of point it the left area (it is one column), *B* is the number of points in the middle area and *C* is the number of points in the right area (it is one column too). That's why by definition we have:
+
+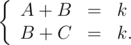
+
+* Therefore *A* = *C*.
+* That's why 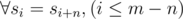
+* Divide all columns by equivalence classes on the basis of . For all *a* and *b* from one class *s**a* = *s**b*.
+* *cnt**a* is number of columns in class with 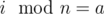.
+* There are (*C**n**k*)*cnt**a* ways to draw *k* points in the each of columns in the class *a* independendently of the other classes.
+* *dp*[*i*][*j*] is number of ways to fill all columns in classes 1, ... *i* in such way that . 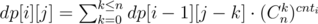
+* *cnt**i* take only two values  and . Let's calc (*C**n**a*)*cnt**i* for all *a* and *cnt**i* and use it to calc our dp. We have *O*(*n*2·*k*) complexity.
+
+[232C - Doe Graphs](/contest/232/problem/C "Codeforces Round 144 (Div. 1)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald"),[tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Gerald](/profile/Gerald "Master Gerald") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's reduce the problem to the same problem for graphs with less orders. Vertex |*D*(*n* - 1)| + 1 is cutpoint (except cases *n* ≤ 2 but equations below is true for these cases).
+
+Without loss of generality *a* < *b*.
+
+Let *dist*(*a*, *b*, *n*) — length of the shortest path in graph of order *n*.
+
+The first case is *a* ≤ |*D*(*n* - 1)| and |*D*(*n* - 1)| + 1 ≤ *b*
+
+*dist*(*a*, *b*, *n*) = *min*(*dist*(*a*, |*D*(*n* - 1)|, *n* - 1), *dist*(*a*, 1, *n* - 1)) + *dist*(*b* - |*D*(*n* - 1)|, 1, *n* - 2) + 1
+
+
+
+Edges is marked in red, paths is marked in blue. This formula means that we can go from the vertex *a* by the path 1 to the vertex 1. Then we can go to the |*D*(*n* - 1)| + 1 by the edge and go to the vertex *b* by the path 3. Or we can go to the vertex |*D*(*n* - 1)| by the path 2 and then go to the vertex |*D*(*n* - 1)| + 1 by the path 2 and then go to the vertex *b* by the path 3.
+
+The second case is |*D*(*n* - 1)| + 1 ≤ *a*, *b*.
+
+*dist*(*a*, *b*, *n*) = *dist*(*a* - |*D*(*n* - 1)|, *b* - |*D*(*n* - 1)|, *n* - 2)
+
+That's easy case.
+
+The third case is *a*, *b* ≤ |*D*(*n* - 1)|
+
+*dist*(*a*, *b*, *n*) = *min*(*dist*(*a*, *b*, *n* - 1), *min*(*dist*(1, *a*, *n* - 1), *dist*(|*D*(*n* - 1)|, *a*, *n* - 1)) + *min*(*dist*(1, *b*, *n* - 1), *dist*(|*D*(*n* - 1)|, *b*, *n* - 1) + 2)
+
+
+
+If shortest path contains cutpoint (|*D*(*n* - 1)| + 1) we can go to the vertex 1 or |*D*(*n* - 1)+1$ form the both of *a* and *b*. After that we can go to the cutpoint. Else we should consider path from *a* to *b* in *D*(*n* - 1).
+
+Let's notice that for all of *n* will be no more than 4 distinct runnings of *dist*(*i*, *j*, *n*).
+
+It can be prooved by the considering many cases of our actions.
+
+In authors colution we cashed all *dist*(1, *i*, *n*) and *dist*(*i*, |*D*(*n*)|, *n*) for all achieveable *i* and *n*.
+
+We have complexity 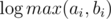 for one query. (it's log because |*D*(*n*)| grows like φ*n*).
+
+[232D - Fence](/contest/232/problem/D "Codeforces Round 144 (Div. 1)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald"), [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [fdoer](/profile/fdoer "Expert fdoer") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Let *d* and *d*' be arrays such that *d**i* = *h**i* - *h**i* + 1, *d*'*i* = - *d**i* for every 1 ≤ *i* ≤ (*n* - 1). With that notation the conditions of matching look somehow like these:
+
+* the pieces do not intersect, that is, there isn't a single plank, such that it occurs in both pieces of the fence;
+* the pieces are of the same width;
+* for all i *i* (0 ≤ *i* ≤ *r*1 - *l*1 - 1) the following condition holds: *d**l*1 + *i* = *d*'*l*2 + *i* (that is true in case when *l* = *r*).
+
+The main idea of our solution is stated in the next sentence. For each query *l*...*r* the answer is number of pairs (*a*, *b*) such that (*a* > *r* or *b* < *l*), 1 ≤ *a* ≤ *b* ≤ *n* - 1, *b* - *a* = *r* - *l* and *d**l*...*r* - 1 exactly matches *d*'*a*...*b* - 1. Let's build a suffix array *sa* from the concatenation of arrays *d* and *d*' with a fictive number between them for separation. Let position of suffix *i* in *sa* be *pos**i*. For each query all pieces of the fence that satisfy both second and third conditions of matching will be placed in *sa* on some segment *bound**left*...*bound**right* such that *bound**left* ≤ *pos**l* ≤ *bound**right* and *lcp*(*bound**left*...*bound**right*) ≥ (*r* - *l*). So, it's possible to use binary search to find *bound*'s. Depending on complexity of *lcp* finding algorithm, we could get them in *O*(*logn*) or *O*(*log*2*n*) complexity.
+
+But there is still a problem to count the number of suffixes from *sa**bound**left*...*bound**right* that satisfy the first condition too. Actually it is equal to count the number of *i* (*bound**left* ≤ *i* ≤ *bound**right*) such that (*n* + 1 ≤ *sa**i* ≤ *n* + *l* - (*r* - *l*) - 1 or *sa**i* ≥ *n* + *r*) (in the concatenation *d*' starts from *n* + 1). It is a classic problem to count numbers from the given interval in the given subarray. For each query it could be solved in *O*(*logn*) complexity.
+
+For instance, we could solve it offline using sweep line method and any data structure that support queries of sum on an interval and increment of an element. Or we could use some 2D/persistent structure.
+
+So, the summary of the algorithm looks like this:
+
+* build *d* and *d*'. Build a suffix array on their concatenation.
+
+For each query:
+
+* find the interval (*bound**left*...*bound**right*) with two consecutive binary searches using lcp function.
+* query the count of suffixes from that interval that do not intersect with the given piece of the fence.
+
+The best author's solution complexity is *O*(*nlogn* + *qlogn*), but careful written solutions in *O*(*nlog*2*n*) comply with the lime limit too.
+
+[232E - Quick Tortoise](/contest/232/problem/E "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [KAN](/profile/KAN "Candidate Master KAN") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's choose central column of the area and for all cells to the left from column calc masks of achieveable cells in the central column and for all cells to the right from column calc masks of cells of which this is achievable. It's easy dp with bitsets. 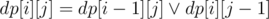 for the right part of board. 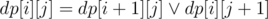 ( — logical or, here it's bitwise or for masks) for the left part. dp calcs mask of achieveable points in the central column.
+
+
+
+For query *x*1, *y*1, *x*2, *y*2 (if *y*1 ≤ *mid* ≤ *y*2, where *mid* is chosen central column) answer is yes if 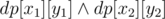 ( is bitwise and) is not empty.
+
+Run this algo for left and right part of board we will get answers for all queries. Complexity is 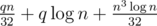.
diff --git a/editorials/233.md b/editorials/233.md
@@ -0,0 +1,138 @@
+Source: https://codeforces.com/blog/entry/5514
+
+It will be finised in few hours. If you don't understand something, ask your questions, please.
+
+[233A - Perfect Permutation](/contest/233/problem/A "Codeforces Round 144 (Div. 2)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Consider permutation *p* such that *p**i* = *i*. Actually *p* is a sequence of numbers from 1 to *n*. Obviously *p**p**i* = *i*. Now the only trick is to change the permutation to satisfy the second equation: *p**i* ≠ *i*. Let's swap every two consequtive elements. More formally, for each *k*: 2*k* ≤ *n* let's swap *p*2*k* - 1 and *p*2*k*. It's easy to see that the obtained permutation satisfies both equations for every *n* with the only exception: when *n* is odd, there is no answer and we should print - 1.
+
+[233B - Non-square Equation](/contest/233/problem/B "Codeforces Round 144 (Div. 2)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Gerald](/profile/Gerald "Master Gerald") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Firstly let's find the interval of possible values of *s*(*x*). Hence *x*2 ≤ *n* and *n* ≤ 1018, *x* ≤ 109. In other words, for every considerable solution *x* the decimal length of *x* does not extend 10 digits. So *s**max* ≤ *s*(9999999999) = 10·9 = 90.
+
+Let's bruteforce the value of *s*(*x*) (0 ≤ *s*(*x*) ≤ 90). Now we have an ordinary square equation. The deal is to solve it and to check that the current bruteforced value of *s*(*x*) is equal to sum of digits of the solution. If the solution exists and the equality holds, we should relax the answer.
+
+It seems that the most error-generating part of this problem is solving the equation.
+
+Knowing arrays is not neccessary to solve these two problems.
+
+[232A - Cycles](/contest/232/problem/A "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash"), [fdoer](/profile/fdoer "Expert fdoer") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's add edge in order of increasing *a* and for equal *b* in order of increasing *b* (here *a* and *b* — the least and the greatest vertices of the edge). If the new edge adds too much 3-cycles, we won't add it. We can count the number of new 3-cycles in *O*(*n*) complexity (they all contain the new edge, so it's enough to check all variants of the third vertex). Obviously we will obtain some proper graph, because we can always add a vertex and two edges to make a new triangle. So, there is always an answer. The complexity of this solution is *O*(*n*3).
+
+Let's proof that 100 vertices are always enough for the given restrictions on *n*.
+
+* For some *p* after first *p* iterations we will have a complete graph of *p* vertices.
+* Now we have exactly *C*(*p*, 3) triangles. Consider *p* such that *C*(*p*, 3) ≤ *k* and *C*(*p*, 3) is maximal.
+* For the given restrictions *p* ≤ 85.
+* From this moment, if we add *u* from some vertex, we increase the total number of 3-cycles on *C*(*u*, 2).
+* So we have to present a small number that is less than *C*(85, 3) as sum of *C*(*i*, 2).
+* The first number we subtruct will differ *C*(85, 1) on some value not greater than *C*(85, 1) = 85, because *C*(*n*, *k*) - *C*(*n* - 1, *k*) = *C*(*n* - 1, *k* - 1).
+* The second number we subtruct will differ the number we have on some value not greater than *C*(14, 1) = 14.
+* and so on.
+* For every *k* it's enough to use not more that 90 vertices.
+
+[232B - Table](/contest/232/problem/B "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Skird](/profile/Skird "Expert Skird") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+* Let *s**i* number of points in the column *i*.
+
+
+
+* Two neighboring squares are drawn at this picture, *A* is the number of point it the left area (it is one column), *B* is the number of points in the middle area and *C* is the number of points in the right area (it is one column too). That's why by definition we have:
+
+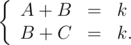
+
+* Therefore *A* = *C*.
+* That's why 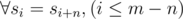
+* Divide all columns by equivalence classes on the basis of . For all *a* and *b* from one class *s**a* = *s**b*.
+* *cnt**a* is number of columns in class with 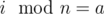.
+* There are (*C**n**k*)*cnt**a* ways to draw *k* points in the each of columns in the class *a* independendently of the other classes.
+* *dp*[*i*][*j*] is number of ways to fill all columns in classes 1, ... *i* in such way that . 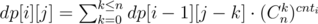
+* *cnt**i* take only two values  and . Let's calc (*C**n**a*)*cnt**i* for all *a* and *cnt**i* and use it to calc our dp. We have *O*(*n*2·*k*) complexity.
+
+[232C - Doe Graphs](/contest/232/problem/C "Codeforces Round 144 (Div. 1)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald"),[tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [Gerald](/profile/Gerald "Master Gerald") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's reduce the problem to the same problem for graphs with less orders. Vertex |*D*(*n* - 1)| + 1 is cutpoint (except cases *n* ≤ 2 but equations below is true for these cases).
+
+Without loss of generality *a* < *b*.
+
+Let *dist*(*a*, *b*, *n*) — length of the shortest path in graph of order *n*.
+
+The first case is *a* ≤ |*D*(*n* - 1)| and |*D*(*n* - 1)| + 1 ≤ *b*
+
+*dist*(*a*, *b*, *n*) = *min*(*dist*(*a*, |*D*(*n* - 1)|, *n* - 1), *dist*(*a*, 1, *n* - 1)) + *dist*(*b* - |*D*(*n* - 1)|, 1, *n* - 2) + 1
+
+
+
+Edges is marked in red, paths is marked in blue. This formula means that we can go from the vertex *a* by the path 1 to the vertex 1. Then we can go to the |*D*(*n* - 1)| + 1 by the edge and go to the vertex *b* by the path 3. Or we can go to the vertex |*D*(*n* - 1)| by the path 2 and then go to the vertex |*D*(*n* - 1)| + 1 by the path 2 and then go to the vertex *b* by the path 3.
+
+The second case is |*D*(*n* - 1)| + 1 ≤ *a*, *b*.
+
+*dist*(*a*, *b*, *n*) = *dist*(*a* - |*D*(*n* - 1)|, *b* - |*D*(*n* - 1)|, *n* - 2)
+
+That's easy case.
+
+The third case is *a*, *b* ≤ |*D*(*n* - 1)|
+
+*dist*(*a*, *b*, *n*) = *min*(*dist*(*a*, *b*, *n* - 1), *min*(*dist*(1, *a*, *n* - 1), *dist*(|*D*(*n* - 1)|, *a*, *n* - 1)) + *min*(*dist*(1, *b*, *n* - 1), *dist*(|*D*(*n* - 1)|, *b*, *n* - 1) + 2)
+
+
+
+If shortest path contains cutpoint (|*D*(*n* - 1)| + 1) we can go to the vertex 1 or |*D*(*n* - 1)+1$ form the both of *a* and *b*. After that we can go to the cutpoint. Else we should consider path from *a* to *b* in *D*(*n* - 1).
+
+Let's notice that for all of *n* will be no more than 4 distinct runnings of *dist*(*i*, *j*, *n*).
+
+It can be prooved by the considering many cases of our actions.
+
+In authors colution we cashed all *dist*(1, *i*, *n*) and *dist*(*i*, |*D*(*n*)|, *n*) for all achieveable *i* and *n*.
+
+We have complexity 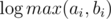 for one query. (it's log because |*D*(*n*)| grows like φ*n*).
+
+[232D - Fence](/contest/232/problem/D "Codeforces Round 144 (Div. 1)")
+
+Idea: [Gerald](/profile/Gerald "Master Gerald"), [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [fdoer](/profile/fdoer "Expert fdoer") Editorial: [fdoer](/profile/fdoer "Expert fdoer")
+
+Let *d* and *d*' be arrays such that *d**i* = *h**i* - *h**i* + 1, *d*'*i* = - *d**i* for every 1 ≤ *i* ≤ (*n* - 1). With that notation the conditions of matching look somehow like these:
+
+* the pieces do not intersect, that is, there isn't a single plank, such that it occurs in both pieces of the fence;
+* the pieces are of the same width;
+* for all i *i* (0 ≤ *i* ≤ *r*1 - *l*1 - 1) the following condition holds: *d**l*1 + *i* = *d*'*l*2 + *i* (that is true in case when *l* = *r*).
+
+The main idea of our solution is stated in the next sentence. For each query *l*...*r* the answer is number of pairs (*a*, *b*) such that (*a* > *r* or *b* < *l*), 1 ≤ *a* ≤ *b* ≤ *n* - 1, *b* - *a* = *r* - *l* and *d**l*...*r* - 1 exactly matches *d*'*a*...*b* - 1. Let's build a suffix array *sa* from the concatenation of arrays *d* and *d*' with a fictive number between them for separation. Let position of suffix *i* in *sa* be *pos**i*. For each query all pieces of the fence that satisfy both second and third conditions of matching will be placed in *sa* on some segment *bound**left*...*bound**right* such that *bound**left* ≤ *pos**l* ≤ *bound**right* and *lcp*(*bound**left*...*bound**right*) ≥ (*r* - *l*). So, it's possible to use binary search to find *bound*'s. Depending on complexity of *lcp* finding algorithm, we could get them in *O*(*logn*) or *O*(*log*2*n*) complexity.
+
+But there is still a problem to count the number of suffixes from *sa**bound**left*...*bound**right* that satisfy the first condition too. Actually it is equal to count the number of *i* (*bound**left* ≤ *i* ≤ *bound**right*) such that (*n* + 1 ≤ *sa**i* ≤ *n* + *l* - (*r* - *l*) - 1 or *sa**i* ≥ *n* + *r*) (in the concatenation *d*' starts from *n* + 1). It is a classic problem to count numbers from the given interval in the given subarray. For each query it could be solved in *O*(*logn*) complexity.
+
+For instance, we could solve it offline using sweep line method and any data structure that support queries of sum on an interval and increment of an element. Or we could use some 2D/persistent structure.
+
+So, the summary of the algorithm looks like this:
+
+* build *d* and *d*'. Build a suffix array on their concatenation.
+
+For each query:
+
+* find the interval (*bound**left*...*bound**right*) with two consecutive binary searches using lcp function.
+* query the count of suffixes from that interval that do not intersect with the given piece of the fence.
+
+The best author's solution complexity is *O*(*nlogn* + *qlogn*), but careful written solutions in *O*(*nlog*2*n*) comply with the lime limit too.
+
+[232E - Quick Tortoise](/contest/232/problem/E "Codeforces Round 144 (Div. 1)")
+
+Idea: [tunyash](/profile/tunyash "Candidate Master tunyash") Implementation: [tunyash](/profile/tunyash "Candidate Master tunyash"), [KAN](/profile/KAN "Candidate Master KAN") Editorial: [tunyash](/profile/tunyash "Candidate Master tunyash")
+
+Let's choose central column of the area and for all cells to the left from column calc masks of achieveable cells in the central column and for all cells to the right from column calc masks of cells of which this is achievable. It's easy dp with bitsets. 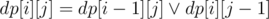 for the right part of board. 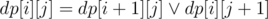 ( — logical or, here it's bitwise or for masks) for the left part. dp calcs mask of achieveable points in the central column.
+
+
+
+For query *x*1, *y*1, *x*2, *y*2 (if *y*1 ≤ *mid* ≤ *y*2, where *mid* is chosen central column) answer is yes if 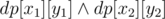 ( is bitwise and) is not empty.
+
+Run this algo for left and right part of board we will get answers for all queries. Complexity is 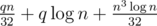.
diff --git a/editorials/235.md b/editorials/235.md
@@ -0,0 +1,113 @@
+Source: https://codeforces.com/blog/entry/5592
+
+### [236A - Boy or Girl](/contest/236/problem/A "Codeforces Round 146 (Div. 2)")
+
+It is a very simple problem, just count how many distinct chars in the input and output the correct answer.
+
+### [236B - Easy Number Challenge](/contest/236/problem/B "Codeforces Round 146 (Div. 2)")
+
+First of all, we can make a table of size a*b*c to store every number's d value. Then we can just brute force through every tripe to calculate the answer.
+
+### [235A - LCM Challenge](/contest/235/problem/A "Codeforces Round 146 (Div. 1)")
+
+It is a simple problem, but many competitors used some wrong guesses and failed. First of all, we should check if n is at most 3 and then we can simply output 1,2,6.
+
+Now there are two cases: When n is odd, the answer is obviously n(n-1)(n-2). When n is even, we can still get at least (n-1)(n-2)(n-3), so these three numbers in the optimal answer would not be very small compared to n. So we can just iterate every 3 number triple in [n-50,n] and update the answer.
+
+### [235B - Let's Play Osu!](/contest/235/problem/B "Codeforces Round 146 (Div. 1)")
+
+Let us take a deep look at how this score is calculated. For an *n* long 'O' block, it contributes *n*2 to the answer.
+
+Let us reformat this problem a bit and consider the following alternative definition of the score: (1) For each two 'O' pair which there is no 'X' between them, they add 2 to the score. (2) For each 'O', it adds 1 to the score.
+
+We claim that this new definition of the score is equivalent to the definition in the problem statement.
+
+Proof of the claim: For an *n* long 'O' block, there are *C**n*2 pairs of 'O' in it and *n* 'O' in it. Note that 2*C**n*2 + *n* = *n*2.
+
+So now we work with the new definition of the score. For each event(i,j) (which means s[i] and s[j] are 'O', and there is no 'X' between them). If event(i,j) happens, it adds 2 to the score.
+
+So we only need to sum up the probabilities of all events and multiply them by 2, and our task becomes how to calculate the sum of probabilities of all the event(i,j). Let P(i,j) be the probability of event(i,j).
+
+We can see that P(i,j) can be computed by . Then we denote P(j) as the sum of all event(i,j) for i<j. We have dp(0)=0 and dp(j)=(dp(j-1)+*p**j* - 1)**p**j*
+
+### [235C - Cyclical Quest](/contest/235/problem/C "Codeforces Round 146 (Div. 1)")
+
+This problem can be solved by many suffix structures. Probably using suffix automaton is the best way to solve it since suffix automaton is simple and clear.
+
+Let us build a suffix automaton of the input string S, and consider the query string x.
+
+Let us also build a string t as x concatenated with x dropping the last char. One can see that every consecutive sub-string of t with length |x| is a rotation of x.
+
+Let us read the string t with suffix automaton we have build, and every time take the first char out and add a new char, add the answer by the number of string equal to this current sub-string of t (which is a rotation of x).
+
+And one more thing, we should consider the repetend of x as well, check my solution here:[2403375](/contest/235/submission/2403375 "Submission 2403375 by YuukaKazami").
+
+Check here if you are not familiar with suffix automaton :[e-maxx's blog](http://e-maxx.ru/algo/suffix_automata)
+
+### [235D - Graph Game](/contest/235/problem/D "Codeforces Round 146 (Div. 1)")
+
+First of all, let us consider the simpler case of trees.
+
+Let us use Event(A,B) to denote the following event "when we select A as the deleting point, B is connected to A".
+
+Clearly, if Event(A,B) happens, it would add 1 to *totolCost*.
+
+So we can just simply calculate the probability of every Event(A,B), and add them up.
+
+Let us consider how to calculate the probability of Event(A,B).
+
+Assume there are n vertices in the path between A and B, we claim that the probability is simply 1 / *n*.
+
+Let us try to prove it using induction.
+
+First let us assume there's a connected sub-graph of the tree containing both A and B, if the sub-graph only has n vertices, then the event happens only if we select vertex A, so the probability is 1 / *n*.
+
+Otherwise, assume it has x vertices there is two cases: whether the selected vertex is on the path between A and B or not.
+
+In the first case, the probability of Event(A,B) happen is 1 / *x* because if we don't select A, Event(A,B) will never happen.
+
+In the second case, the sub-graph containing A,B has become smaller, so the probability is (*x* - *n*) / *xn*.
+
+So add them up we can prove this statement.
+
+Then we can solve the tree case by simply add up the inverse of every path's length in the tree.
+
+And for the original case, there's at most 2 paths between A and B.
+
+If there's only one path, then everything is the same with the tree case.
+
+Otherwise, the path between A and B should pass the cycle in the graph.
+
+Let us examine this case, you can see that there 2 types of vertex:
+
+Vertex on the path of A to cycle or B to cycle, they should not be selected before A because once they're selected, A and B lost connectivity, let us call them X.
+
+Vertex on the cycle, the two paths from A to B, each path contains a path in the cycle, let us call them Y and Z.
+
+So there are two possibilities: X and Y are free when A is selected, X and Z are free when A is selected.
+
+And we should subtract the case that X and Y, Z are all free when A is selected because it double-counts before.
+
+So the probability is 1 / (*X* + *Y* + 1) + 1 / (*X* + *Z* + 1) - 1 / (*X* + *Y* + *Z* + 1).
+
+Check [Petr](/profile/Petr "Legendary Grandmaster Petr") 's solution for the details: [2401228](/contest/235/submission/2401228 "Submission 2401228 by Petr")
+
+And my C++ implementation: [2403938](/contest/235/submission/2403938 "Submission 2403938 by YuukaKazami")
+
+### [235E - Number Challenge](/contest/235/problem/E "Codeforces Round 146 (Div. 1)")
+
+Let us consider each prime in one step, the upper limit for *a*, *b*, *c* is recorded.
+
+So if we fixed the power of 2 in each *i*, *j*, *k* like 2*x*, 2*y*, 2*z*, then their upper limit becomes *a* / 2*x*, *b* / 2*y*, *c* / 2*z*, and the power of 2 in their multiplication is just x+y+z.
+
+Let us denote *dp*(*a*, *b*, *c*, *p*) for the answer to the original problem that *i*, *j*, *k* 's upper limit is *a*, *b*, *c*. And their can only use the prime factors which are not less than *p*.
+
+Let the next prime to be *q*, so we can try to fix the power of *p* in *i*, *j*, *k* and get the new upper limit.
+
+So we can do transform like this: *dp*(*a*, *b*, *c*, *p*) = sum of *dp*(*a* / *p**x*, *b* / *p**y*, *c* / *p**z*, *q*)·(*x* + *y* + *z* + 1)
+
+Check my code here: [2404223](/contest/235/submission/2404223 "Submission 2404223 by YuukaKazami")
+
+Also you can check [rng_58](/profile/rng_58 "International Grandmaster rng_58") solution here: [http://codeforces.com/blog/entry/5600](https://codeforces.com/blog/entry/5600)
+
+If you have any problems, you can ask here :)
diff --git a/editorials/236.md b/editorials/236.md
@@ -0,0 +1,113 @@
+Source: https://codeforces.com/blog/entry/5592
+
+### [236A - Boy or Girl](/contest/236/problem/A "Codeforces Round 146 (Div. 2)")
+
+It is a very simple problem, just count how many distinct chars in the input and output the correct answer.
+
+### [236B - Easy Number Challenge](/contest/236/problem/B "Codeforces Round 146 (Div. 2)")
+
+First of all, we can make a table of size a*b*c to store every number's d value. Then we can just brute force through every tripe to calculate the answer.
+
+### [235A - LCM Challenge](/contest/235/problem/A "Codeforces Round 146 (Div. 1)")
+
+It is a simple problem, but many competitors used some wrong guesses and failed. First of all, we should check if n is at most 3 and then we can simply output 1,2,6.
+
+Now there are two cases: When n is odd, the answer is obviously n(n-1)(n-2). When n is even, we can still get at least (n-1)(n-2)(n-3), so these three numbers in the optimal answer would not be very small compared to n. So we can just iterate every 3 number triple in [n-50,n] and update the answer.
+
+### [235B - Let's Play Osu!](/contest/235/problem/B "Codeforces Round 146 (Div. 1)")
+
+Let us take a deep look at how this score is calculated. For an *n* long 'O' block, it contributes *n*2 to the answer.
+
+Let us reformat this problem a bit and consider the following alternative definition of the score: (1) For each two 'O' pair which there is no 'X' between them, they add 2 to the score. (2) For each 'O', it adds 1 to the score.
+
+We claim that this new definition of the score is equivalent to the definition in the problem statement.
+
+Proof of the claim: For an *n* long 'O' block, there are *C**n*2 pairs of 'O' in it and *n* 'O' in it. Note that 2*C**n*2 + *n* = *n*2.
+
+So now we work with the new definition of the score. For each event(i,j) (which means s[i] and s[j] are 'O', and there is no 'X' between them). If event(i,j) happens, it adds 2 to the score.
+
+So we only need to sum up the probabilities of all events and multiply them by 2, and our task becomes how to calculate the sum of probabilities of all the event(i,j). Let P(i,j) be the probability of event(i,j).
+
+We can see that P(i,j) can be computed by . Then we denote P(j) as the sum of all event(i,j) for i<j. We have dp(0)=0 and dp(j)=(dp(j-1)+*p**j* - 1)**p**j*
+
+### [235C - Cyclical Quest](/contest/235/problem/C "Codeforces Round 146 (Div. 1)")
+
+This problem can be solved by many suffix structures. Probably using suffix automaton is the best way to solve it since suffix automaton is simple and clear.
+
+Let us build a suffix automaton of the input string S, and consider the query string x.
+
+Let us also build a string t as x concatenated with x dropping the last char. One can see that every consecutive sub-string of t with length |x| is a rotation of x.
+
+Let us read the string t with suffix automaton we have build, and every time take the first char out and add a new char, add the answer by the number of string equal to this current sub-string of t (which is a rotation of x).
+
+And one more thing, we should consider the repetend of x as well, check my solution here:[2403375](/contest/235/submission/2403375 "Submission 2403375 by YuukaKazami").
+
+Check here if you are not familiar with suffix automaton :[e-maxx's blog](http://e-maxx.ru/algo/suffix_automata)
+
+### [235D - Graph Game](/contest/235/problem/D "Codeforces Round 146 (Div. 1)")
+
+First of all, let us consider the simpler case of trees.
+
+Let us use Event(A,B) to denote the following event "when we select A as the deleting point, B is connected to A".
+
+Clearly, if Event(A,B) happens, it would add 1 to *totolCost*.
+
+So we can just simply calculate the probability of every Event(A,B), and add them up.
+
+Let us consider how to calculate the probability of Event(A,B).
+
+Assume there are n vertices in the path between A and B, we claim that the probability is simply 1 / *n*.
+
+Let us try to prove it using induction.
+
+First let us assume there's a connected sub-graph of the tree containing both A and B, if the sub-graph only has n vertices, then the event happens only if we select vertex A, so the probability is 1 / *n*.
+
+Otherwise, assume it has x vertices there is two cases: whether the selected vertex is on the path between A and B or not.
+
+In the first case, the probability of Event(A,B) happen is 1 / *x* because if we don't select A, Event(A,B) will never happen.
+
+In the second case, the sub-graph containing A,B has become smaller, so the probability is (*x* - *n*) / *xn*.
+
+So add them up we can prove this statement.
+
+Then we can solve the tree case by simply add up the inverse of every path's length in the tree.
+
+And for the original case, there's at most 2 paths between A and B.
+
+If there's only one path, then everything is the same with the tree case.
+
+Otherwise, the path between A and B should pass the cycle in the graph.
+
+Let us examine this case, you can see that there 2 types of vertex:
+
+Vertex on the path of A to cycle or B to cycle, they should not be selected before A because once they're selected, A and B lost connectivity, let us call them X.
+
+Vertex on the cycle, the two paths from A to B, each path contains a path in the cycle, let us call them Y and Z.
+
+So there are two possibilities: X and Y are free when A is selected, X and Z are free when A is selected.
+
+And we should subtract the case that X and Y, Z are all free when A is selected because it double-counts before.
+
+So the probability is 1 / (*X* + *Y* + 1) + 1 / (*X* + *Z* + 1) - 1 / (*X* + *Y* + *Z* + 1).
+
+Check [Petr](/profile/Petr "Legendary Grandmaster Petr") 's solution for the details: [2401228](/contest/235/submission/2401228 "Submission 2401228 by Petr")
+
+And my C++ implementation: [2403938](/contest/235/submission/2403938 "Submission 2403938 by YuukaKazami")
+
+### [235E - Number Challenge](/contest/235/problem/E "Codeforces Round 146 (Div. 1)")
+
+Let us consider each prime in one step, the upper limit for *a*, *b*, *c* is recorded.
+
+So if we fixed the power of 2 in each *i*, *j*, *k* like 2*x*, 2*y*, 2*z*, then their upper limit becomes *a* / 2*x*, *b* / 2*y*, *c* / 2*z*, and the power of 2 in their multiplication is just x+y+z.
+
+Let us denote *dp*(*a*, *b*, *c*, *p*) for the answer to the original problem that *i*, *j*, *k* 's upper limit is *a*, *b*, *c*. And their can only use the prime factors which are not less than *p*.
+
+Let the next prime to be *q*, so we can try to fix the power of *p* in *i*, *j*, *k* and get the new upper limit.
+
+So we can do transform like this: *dp*(*a*, *b*, *c*, *p*) = sum of *dp*(*a* / *p**x*, *b* / *p**y*, *c* / *p**z*, *q*)·(*x* + *y* + *z* + 1)
+
+Check my code here: [2404223](/contest/235/submission/2404223 "Submission 2404223 by YuukaKazami")
+
+Also you can check [rng_58](/profile/rng_58 "International Grandmaster rng_58") solution here: [http://codeforces.com/blog/entry/5600](https://codeforces.com/blog/entry/5600)
+
+If you have any problems, you can ask here :)
diff --git a/editorials/237.md b/editorials/237.md
@@ -0,0 +1,45 @@
+Source: https://codeforces.com/blog/entry/5648
+
+Приветствую всех участников раунда!
+
+## [237A - Free Cash](/contest/237/problem/A "Codeforces Round 147 (Div. 2)")
+
+Из условия задачи легко понять, что если в некоторую минуту придут *k* человек, то Валере нужно иметь в кафе не менее *k* касс. Значит, требуется найти максимальное количество людей, которые придут в одну и ту же минуту, а это делается очень просто множеством способов, например, просто насчитав в массив *cnt*[*h*][*m*] количество людей, которые придут в час *h* и минуту *m*, а потом найдя в этом массиве максимум.
+
+## [237B - Young Table](/contest/237/problem/B "Codeforces Round 147 (Div. 2)")
+
+Решение, которое опишем ниже, почти никак не использует хитрую форму таблицы (кстати, такая таблица называется диаграммой Юнга). Заполним таблицу числами от 1 до *s* следующим способом: будем идти по строкам таблицы начиная с первой слева направо, после конца текущей строки переходим на начало следующей, и в процессе каждой из клеточек присвоим число по порядку обхода от 1 до *s*. Очень просто показать, что такой порядок чисел удовлетворяет оба неравенства из условия.
+
+Теперь опишем алгоритм приведения таблицы из того вида, как она нам дана во входных данных, в описанный выше вид.
+
+Возьмем число 1 и посмотрим, где оно находится в этих двух таблицах. Если это число стоит не на своем месте, то поставим его на свое место, соответственно то число, которое там стояло, встанет на старое место единицы. Аналогично сделаем для 2, 3, ..., *s*. Очевидно, что этот алгоритм сделает не более *s* шагов и приведет таблицу в вид, описанный в первом абзаце.
+
+## [237C - Primes on Interval](/contest/237/problem/C "Codeforces Round 147 (Div. 2)")
+
+Для начала с помощью решета Эратосфена выделим все простые числа от 1 до *b* и пометим их единичками в массиве *d*, то есть если *p* — простое, то *d*[*p*] = 1, иначе *d*[*p*] = 0.
+
+Заметим, что если *l* — корректное число, то *l* + 1 тоже корректно. В самом деле, для позиций *x* от *a* до *b* - *l* количество простых в отрезке с началом в *x* могло лишь увеличиться (мы же длину отрезка увеличили, а значит, количество простых в нем никак не могло уменьшиться). А кроме того исчез из рассмотрения один отрезок с началом в точке *b* - *l* + 1, так как при увеличении длины его правый конец стал больше, чем число *b*.
+
+Таким образом, мы показали, что функция *f*(*l*), возвращающая *TRUE* или *FALSE* (корректно число или нет) монотонна, а значит, мы можем с помощью бинарного поиска найти наименьшее *l*, для которого *f*(*l*) = *TRUE*, или ответить, что такого не существует.
+
+Функция *f*(*l*) считается очень просто — можно проитерироваться по всем числам от *a* до *b* - *l* + 1 и найти для каждого начала количество простых чисел в соответствующем отрезке длины *l*, это можно сделать с помощью частичных сумм, насчитанных по массиву *d*.
+
+## [237D - T-decomposition](/contest/237/problem/D "Codeforces Round 147 (Div. 2)")
+
+Возьмем любое ребро начального графа, очевидно два его конца принадлежат некоторому множеству *x**i*, значит, вес любой его Д-декомпозиции как минимум 2. Покажем, как постороить декомпозицию именно такого веса. Для этого каждое из ребер исходного графа превратим в отдельное множество *x**i*, то есть все они будут состоять из двух элементов.
+
+Очевидно, что первые два условия выполняются. Для выполнения третьего условия для начала соединим все множества по принципу: добавим ребро между двуми множествами, если их пересечение не пусто. Однако построенный таким образом граф не является деревом, покажем другой способ соединения вершин.
+
+Для того, чтобы сделать из него дерево, достаточно для каждой вершины *v* начального дерева выделить все *x**i*, в которых она содержится, и соединить их в цепочку в любом порядке, добавив нужное количество ребер.
+
+Несложно понять, что такой граф не будет содержать циклов, будет связен, а значит является деревом. Постоенная Д-декомпозиция будет иметь вес 2, и количество вершин *n* - 1.
+
+## [237E - Build String](/contest/237/problem/E "Codeforces Round 147 (Div. 2)")
+
+Эта задача несложно решается алгоритмом поиска максимального потока минимальной стоимости на трехслойном графе:
+
+1. первый слой состоит из *n* вершин, каждая из которых отвечает за свою строку из входных данных; в *i*-ую вершину этого слоя входит по одному ребру из истока с пропускной способностью *c**i* и стоимостью *i*;
+2. второй стой состоит за 26·*n* вершин, каждая из которых отвечает за количество определенных букв в каждой из строк из входных данных; в вершины этого слоя входят ребра только из первого слоя стоимостью 0 и пропускной способностью равной количеству соответствующих букв в соответствующей строке;
+3. третий слой состоит из 26 вершин, каждая из которых отвечает за количество соответствующих букв в строке *t*; в вершины этого слоя входят ребра только из второго слоя стоимостью 0 и бесконечной пропускной способностью; кроме того, из вершин третьего слоя выходят ребра в сток стоимостью 0 и пропускной способностью, равной количеству соответствующих букв в строке *t*.
+
+Если максимальный поток в этой сети меньше, чем |*t*|, то ответ равен - 1, а иначе — минимальной стоимости максимального потока.
diff --git a/editorials/238.md b/editorials/238.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/5765
+
+Hi :)
+
+Here is the editorial for round #148. I just tried to explain the ideas rather than detailed implementation explanation. I'm sorry for my bad English, so please tell me if something is not clear in the descriptions.
+
+### Two Bags of Potatoes
+
+The author of this problem is [Gerald](/profile/Gerald "Мастер Gerald"). The total number of potatoes is a multiple of *k* and constraint  there will be at most 105 multiples of *k* in range 1 to *n*. So you can iterate on multiples of *k* and print the ones that satisfy the problem.
+
+### Easy Tape Programming
+
+In this problem you just need to simulate every thing which is written in the statement step by step. You can see a simple implementation of this here: [http://www.codeforces.com/contest/239/submission/2512422](//www.codeforces.com/contest/239/submission/2512422)
+
+### Not Wool Sequences
+
+Let *a*1, ..., *a**n* be a not-wool-sequence. We define another sequence called *b* in which *b**i* is xor of the first *i* elements of *a*, 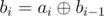 and *b*0 = 0.
+
+Now xor of elements of a consecutive subsequence like *a**i*, ..., *a**j* will be equal to . So we know that all elements of *b* should be different. Therefore *b* is a sequence of **distinct** integers of length *n* + 1 starting with 0 made of numbers 0 to 2*m* - 1. The number of such sequences is  and this is the answer to problem.
+
+### Boring Partition
+
+Coming soon...
+
+### World Eater Brothers
+
+Consider we only want to change direction of minimum number of roads so that all other countries are reachable from a specific country *x*. This problem can be solved in *O*(*n*) and it's exactly what [219D - Выбор столицы Древляндии](/contest/219/problem/D "Codeforces Round 135 (Div. 2)") asks for. If you don't know how to solve it you can read the [editorial of that contest](//codeforces.com/blog/entry/5160).
+
+Consider two countries *A* and *B* which can be chosen by world eater brothers to achieve the minimum number of road direction changes. After changing the direction of roads, there exists a country on the undirected path between *A* and *B* which is reachable from both *A* and *B* using roads. We call such country a *middle-country*.
+
+We want to iterate on middle-countries and find the best two countries for ruling for each middle-country. For each neighbor of the current middle-country calculate the minimum number of road changes in the subtree rooted at that neighbor so that all countries will be reachable from some country in that subtree. Then from two of these subtrees we need to pick *A* and *B* and all other subtrees will have edges pointing to the root of subtree. This can be computed in *O*(*n*) for each middle-city. So the overall complexity will be *O*(*n*2).
+
+### Tape Programming
+
+This problem was my favorite in the problemset. The primary point is that at any moment during the interpretation of a program only a prefix of the program is modified and used by IP.
+
+Consider we want to calculate the output of subsequence *s**l*, ..., *s**r*. While running the original program *s*1, ..., *s**n* if at any moment CP enters the interval [*l*, *r*] it should be pointing to position *l* and the direction of DP should be *right*. So it's like we have started interpreting *s**l*, ..., *s**r* independently. The termination of execution of *s**l*, ..., *s**r* is the first time CP points to somewhere outside interval [*l*, *r*].
+
+Therefore what we need to solve the problem is to run the original program. And after each termination if the program is nonempty then run it again until program is empty. Then we should keep a log of positions we have visited and the time of each visit and the number of printed digits of each type until then. After this preprocessing the to calculate the answer of query (*l**i*, *r**i*) its enough to find the first time CP visited *s**l**i* and the first time CP visited *s**r**i* + 1 or *s**l**i* - 1 after that.
+
+The described approach can be implemented in *O*(*nlog*(*n*) + *qlog*(*n*)).
+
+### Meeting her
+
+Consider a bus passing a shortest path from *s**i* to *t**i*. There are some points that are necessary to pass in order to obtain a shortest path. Firstly we compute them. This can be done in *O*(*n*3) with Floyd-Warshall and some processing after that. Urpal is sure that a bus from *i*-th company always passes such vertices on his path from *s**i* to *t**i*. So he can get on a bus from *i*-th company only at vertices the bus surely passes.
+
+At any moment Urpal's status can be uniquely determined by his position on the map and the bus he's traveling with. So we have *nk* states (*position*, *bus*).
+
+Our goal is to reach some (*b*, ...) state from a (*a*, *v*) state which bus *v* surely passes *a* (source states). So let's find all states that can reach a goal state. We call such states *good* states.
+
+Consider Urpal is at junction *x* and he's traveling with a bus of type *y*. Let *v*1, *v*2, ..., *v**w* be the list of junctions the bus might go on its shortest path from *s**y* to *t**y*. And let *c*1, *c*2, ..., *c**l* be the list of companies that their bus surely passes junction *x*, excluding *y*-th company. For state (*x*, *y*) we know we can reach junction *b* (it's a good state) if one of the following is true:
+
+* *x* = *b*, the minimum cost of solving the problem will be 0.
+* All states (*v*1, *y*), (*v*2, *y*), ... and (*v**w*, *y*) are good states, the minimum cost of solving the problem will be the maximum of all these states.
+* At least one of states (*x*, *c*1), (*x*, *c*2), ... or (*x*, *c**l*) is a good state, the minimum cost of solving the problem will be the minimum the good ones plus one.
+
+At first the only good states we know are states with junction *b*, (*b*, ...). Now some new states might have become good states. So we add those states to the list of known good states. We do this until no state becomes good anymore.
+
+At the end we print the minimum cost of source states which are good, and if they don't exist we print -1.
+
+The process thing can be implemented in *O*(*n*4). :)
diff --git a/editorials/239.md b/editorials/239.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/5765
+
+Hi :)
+
+Here is the editorial for round #148. I just tried to explain the ideas rather than detailed implementation explanation. I'm sorry for my bad English, so please tell me if something is not clear in the descriptions.
+
+### Two Bags of Potatoes
+
+The author of this problem is [Gerald](/profile/Gerald "Мастер Gerald"). The total number of potatoes is a multiple of *k* and constraint  there will be at most 105 multiples of *k* in range 1 to *n*. So you can iterate on multiples of *k* and print the ones that satisfy the problem.
+
+### Easy Tape Programming
+
+In this problem you just need to simulate every thing which is written in the statement step by step. You can see a simple implementation of this here: [http://www.codeforces.com/contest/239/submission/2512422](//www.codeforces.com/contest/239/submission/2512422)
+
+### Not Wool Sequences
+
+Let *a*1, ..., *a**n* be a not-wool-sequence. We define another sequence called *b* in which *b**i* is xor of the first *i* elements of *a*, 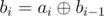 and *b*0 = 0.
+
+Now xor of elements of a consecutive subsequence like *a**i*, ..., *a**j* will be equal to . So we know that all elements of *b* should be different. Therefore *b* is a sequence of **distinct** integers of length *n* + 1 starting with 0 made of numbers 0 to 2*m* - 1. The number of such sequences is  and this is the answer to problem.
+
+### Boring Partition
+
+Coming soon...
+
+### World Eater Brothers
+
+Consider we only want to change direction of minimum number of roads so that all other countries are reachable from a specific country *x*. This problem can be solved in *O*(*n*) and it's exactly what [219D - Выбор столицы Древляндии](/contest/219/problem/D "Codeforces Round 135 (Div. 2)") asks for. If you don't know how to solve it you can read the [editorial of that contest](//codeforces.com/blog/entry/5160).
+
+Consider two countries *A* and *B* which can be chosen by world eater brothers to achieve the minimum number of road direction changes. After changing the direction of roads, there exists a country on the undirected path between *A* and *B* which is reachable from both *A* and *B* using roads. We call such country a *middle-country*.
+
+We want to iterate on middle-countries and find the best two countries for ruling for each middle-country. For each neighbor of the current middle-country calculate the minimum number of road changes in the subtree rooted at that neighbor so that all countries will be reachable from some country in that subtree. Then from two of these subtrees we need to pick *A* and *B* and all other subtrees will have edges pointing to the root of subtree. This can be computed in *O*(*n*) for each middle-city. So the overall complexity will be *O*(*n*2).
+
+### Tape Programming
+
+This problem was my favorite in the problemset. The primary point is that at any moment during the interpretation of a program only a prefix of the program is modified and used by IP.
+
+Consider we want to calculate the output of subsequence *s**l*, ..., *s**r*. While running the original program *s*1, ..., *s**n* if at any moment CP enters the interval [*l*, *r*] it should be pointing to position *l* and the direction of DP should be *right*. So it's like we have started interpreting *s**l*, ..., *s**r* independently. The termination of execution of *s**l*, ..., *s**r* is the first time CP points to somewhere outside interval [*l*, *r*].
+
+Therefore what we need to solve the problem is to run the original program. And after each termination if the program is nonempty then run it again until program is empty. Then we should keep a log of positions we have visited and the time of each visit and the number of printed digits of each type until then. After this preprocessing the to calculate the answer of query (*l**i*, *r**i*) its enough to find the first time CP visited *s**l**i* and the first time CP visited *s**r**i* + 1 or *s**l**i* - 1 after that.
+
+The described approach can be implemented in *O*(*nlog*(*n*) + *qlog*(*n*)).
+
+### Meeting her
+
+Consider a bus passing a shortest path from *s**i* to *t**i*. There are some points that are necessary to pass in order to obtain a shortest path. Firstly we compute them. This can be done in *O*(*n*3) with Floyd-Warshall and some processing after that. Urpal is sure that a bus from *i*-th company always passes such vertices on his path from *s**i* to *t**i*. So he can get on a bus from *i*-th company only at vertices the bus surely passes.
+
+At any moment Urpal's status can be uniquely determined by his position on the map and the bus he's traveling with. So we have *nk* states (*position*, *bus*).
+
+Our goal is to reach some (*b*, ...) state from a (*a*, *v*) state which bus *v* surely passes *a* (source states). So let's find all states that can reach a goal state. We call such states *good* states.
+
+Consider Urpal is at junction *x* and he's traveling with a bus of type *y*. Let *v*1, *v*2, ..., *v**w* be the list of junctions the bus might go on its shortest path from *s**y* to *t**y*. And let *c*1, *c*2, ..., *c**l* be the list of companies that their bus surely passes junction *x*, excluding *y*-th company. For state (*x*, *y*) we know we can reach junction *b* (it's a good state) if one of the following is true:
+
+* *x* = *b*, the minimum cost of solving the problem will be 0.
+* All states (*v*1, *y*), (*v*2, *y*), ... and (*v**w*, *y*) are good states, the minimum cost of solving the problem will be the maximum of all these states.
+* At least one of states (*x*, *c*1), (*x*, *c*2), ... or (*x*, *c**l*) is a good state, the minimum cost of solving the problem will be the minimum the good ones plus one.
+
+At first the only good states we know are states with junction *b*, (*b*, ...). Now some new states might have become good states. So we add those states to the list of known good states. We do this until no state becomes good anymore.
+
+At the end we print the minimum cost of source states which are good, and if they don't exist we print -1.
+
+The process thing can be implemented in *O*(*n*4). :)
diff --git a/editorials/24.md b/editorials/24.md
@@ -0,0 +1,37 @@
+Source: https://codeforces.com/blog/entry/557
+
+## Task A
+
+This is pretty simple task - we have cycle and must direct all edges on it in one of 2 directions. We need to calculate cost of both orientation and print smallest of them.
+
+There is a small trick - we can calculate cost of only one orientation and then cost of the other will be sum of costs of all edges minus cost of first orientation.
+
+## Task B
+
+Also very simple - we need literary do what we asked. We put all data in a map where for each pilot we have number of points and array of 50 elements - number of times pilot finished at corresponding place. Then we just need to find maximum in this array according to 2 given criteria.
+
+## Task C
+
+Reflection over 2 points is just a parallel shift for a doubled vector between them. So *M*2*n* = *M*0 because sequence of reflections may be replaced with sequence of shifts with doubled vectors *A*0*A*2, *A*2*A*4, ..., *A**n* - 2*A*0 - and their sum is 0. So we can replace j with *j*' = *jmod*2*N*. Now we can just perform j' reflections. Suppose we need to find M' (x', y') - reflection of M(x, y) witch center at A(*x*0, *y*0). Then *x*' = 2*x*0 - *x*, *y*' = 2*y*0 - *y*.
+
+## Task D
+
+If robot is at last row then answer is 0. Suppose that for every cell of the next row we now expected number of steps to reach last row - *z**i*. Let *x**i* be expected value of steps to reach the last row from current row. Then we have following system of equations:
+
+*x*1 = 1 + *x*1 / 3 + *x*2 / 3 + *z*1 / 3
+
+*x**i* = 1 + *x**i* / 4 + *x**i* - 1 / 4 + *x**i* + 1 / 4 + *z**i* / 4 for i from 2 to M - 1
+
+*x**M* = 1 + *x**M* / 3 + *x**M* - 1 / 3 + *z**M* / 3
+
+This is tridiagonal system, it can be solved using [tridiagonal matrix algorithm](https://en.wikipedia.org/wiki/Tridiagonal_matrix_algorithm) in linear time.
+
+So we just have to solve this for each row starting from N - 1 and ending at i and then take x[j].
+
+For M = 1 the answer is 2(N - i) because expected number of steps to go down is 2 - on each turn we either go down or stay
+
+## Task E
+
+At first we need to exclude answer -1. Answer is -1 if and only if first part of particles moves left and second part moves right (any of this parts may be empty)
+
+Let's use binary search. Maximal answer is 1e9. Suppose we need to unserstand - whether answer is more then t or less then t. Let's itirate particles from left to right and maintain maximal coordinate that particle moving right would achive. Then of we will meet particle moving left that will move to the left of that coordinate in time t that we have 2 particles that will collide before time t. Otherwise we won't have such pair of particles.
diff --git a/editorials/242.md b/editorials/242.md
@@ -0,0 +1,38 @@
+Source: https://codeforces.com/blog/entry/5837
+
+## [242A - Heads or Tails](/contest/242/problem/A "Codeforces Round 149 (Div. 2)")
+
+This problem was very easy, we should only use two cycles with *i* and with *j* (*a* ≤ *i* ≤ *x*, *b* ≤ *j* ≤ *y*), iterate all possible outcomes of the game and print such in that *i* > *j*. The time is *O*(*x*·*y*).
+
+## [242B - Big Segment](/contest/242/problem/B "Codeforces Round 149 (Div. 2)")
+
+At first, we must note that the answer is always unique, because if segment *i* covers segment *j*, that segment *j* can't cover segment *i*. It possible if and only if there are coincide segments in the set, but it's not permissible by the statement. Let's pay attention the answer covers the most left point of all segments and the most right point of all points too. Now then we should found *L* = *min*(*l**i*) and *R* = *max*(*r**i*) and print index of segment [*L*, *R*], or - 1 if there is no such segment in the set. The time is *O*(*n*).
+
+## [242C - King's Path](/contest/242/problem/C "Codeforces Round 149 (Div. 2)")
+
+The most important thing for accepted solution is that it is guaranteed that the total length of all given segments doesn't exceed 105. We should use this feature, let's number allowed cells and found shortest path by BFS. It's easiest to use associative array such as map in C++ for numbering. The time is *O*(*n*·*log*(*n*)).
+
+## [242D - Dispute](/contest/242/problem/D "Codeforces Round 149 (Div. 2)")
+
+Denote current value of counter number *i* as *b**i*. Let's describe an algorithm. It takes any counter *i* such that *b**i* = *a**i* and presses its button. The algorithm finishes if there is no such *i*.
+
+Let's proof correctness of the algorithm:
+
+1. Why does Valera win the game? Because there is no such counter which has *b**i* = *a**i* else we must press the button.
+2. Why doesn't algorithm press some button multiple times? Because it presses button number *i* only if *b**i* = *a**i*, and after this pressing the value *b**i* is increased and the equation will be true never.
+3. Why is the algorithm fast? Because of paragraph 2 it does no more *n* pressings which produces no more *n* + 2·*m* increases of the counters. We should use queue for fast seaching counters which has *b**i* = *a**i* like this: every time we change value of the counter numbered *i* we check equation *b**i* = *a**i* and if it's true then we push value *i* to the queue. It's easy to understand that all indexes *i* will be in queue no more one time.
+
+Also these paragraphs proof that the answer always exists. You must print - 1 never. The time is *O*(*n* + *m*).
+
+## [242E - XOR on Segment](/contest/242/problem/E "Codeforces Round 149 (Div. 2)")
+
+Let's write numbers *a*1, *a*2, ..., *a**n* as a table which has size *n* × 20, and *b**i*, *j* is *j*th bit in *a**i*. Then sum of numbers on segment [*l*, *r*] equals 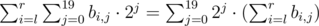. The last notation helps us to process queries.
+
+For fast implementation we should use 20 binary trees like cartesian trees or range trees. Every tree matchs one of bits (and matchs one of the columns of the table *b**i*, *j*).
+
+1. calculation of sum is equal to counting 1-s from *l*-th to *r*-th.
+2. operation "xor" equals reversing all bits from *l*-th to *r*-th (i.e. 0 changes to 1, 1 changes to 0).
+
+The first operation executes for all bit numbers, the second executes only for bits in which input number *x**i* has ones.
+
+These operations may be easy implemented with binary trees. The time is *O*(*m*·*log*(*n*)·20).
diff --git a/editorials/243.md b/editorials/243.md
@@ -0,0 +1,92 @@
+Source: https://codeforces.com/blog/entry/5895
+
+**Adiv2.** Consider an array *A* of integers in range from 1 to *nk*. Let's remove from *A* all numbers *a**i* and all other numbers store into an array *B*. The array *B* will have (*n* - 1)*k* elements. Now for *i*-th kid you should output numbers *a**i*, *B*[(*n* - 1) * (*i* - 1) + 1], *B*[(*n* - 1) * (*i* - 1) + 2], ... *B*[(*n* - 1) * (*i* - 1) + *n* - 1] (*B* is 1-based).
+
+Author is [Gerald](/profile/Gerald "Master Gerald") .
+
+**Bvid2.** Solution 1. You should write some bruteforce solution over all numbers with no more than 9 digits (number 109 should be considered separately). Bruteforce algo seems like this:
+
+```
+dfs( int num ) // run it as dfs(0)
+ if (num > 0 && num <= n) ans++
+ if (num >= 10^8) return
+ for a = 0..9 do
+ if num*10+a>0 then
+ if number num*10+a has no more than 2 different digits then
+ dfs( num*10+a )
+```
+
+ans will store the answer. After that you wrote bruteforce, you can run it and see that it works fast (that is same time for any testcase).
+
+Solution 2. Let's build all undoubdetly lucku numbers using bitmasks. You can iterate over length of number *L*, pair of digits *x* and *y*, and bitmask *m* of length *L*. If the *i*-th bit of *m* is 1, the *i*-th digit of number should be *x*; otherwise it should be *y*. So about 103 × 210 numbers will be generated (it is very rough estimate, count of numbers will be more than 10 times less).
+
+In this solution you should accurately process the case of leading zeroes and the case when all digits of number are same.
+
+Author is [Gerald](/profile/Gerald "Master Gerald")
+
+**Adiv1, Cdiv2** Let's see how function *f* changes for all suffixes of sequence *a*. Values of *f* will increase when you will increase length of suffix. For every increase all 1-bits will stay 1-bits, but some 0-bits will be changed by 1-bits. So, you can see that no more than *k* increasing will be, where *k* number of bits (in this problem *k* = 20). Among all suffixes will be no more that *k* + 1 values of function *f*.
+
+Now you can run over sequence *a* trom left to right and support an array *m* (or a set) of values of *f* for all subsegments that end in the current position. Size of *m* always no more than *k* + 1. When you go from position *i* - 1 into position *i*, you should replace *m* = {*m*1, *m*2, ..., *m**t*} by *m*' = {*a**i*, *m*1|*a**i*, *m*2|*a**i*, ... *m**t*|*a**i*}. After that you should remove from *m* repeated values (if you use set, set will do this dirty work itself). Then you should mark all numbers from *m* in some global array (or put them into some global set). At the end you should calculate answer from the global array (or set).
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") , [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Bdiv1, Ddiv2** You should check for every edge: this one can be body of hydra or not. Let's fix some edge (*u*, *v*) (order of vertices is important, i.e. you should also check edge (*v*, *u*)). Now you should chose some set of *h* vertices connected with *u* and some set of *t* vertices connected with *v*. These sets should not contain vertices *u* and *v*. Also, these two sets should have no common vertices.
+
+If 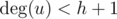 and 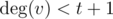, there is no any hydra here.
+
+Orherwise, if 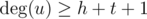 or 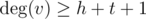, there is some hydra in any case. Even if all vertices connected with *u* and with *v* are common, number of them so big, that you always can split them into groups of size ≥ *h* and size ≥ *t*.
+
+The last case is 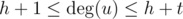 and 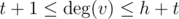. Here you can find all common vertices in *O*(*h* + *t*), using array of flags. When you find the common subset, you can easy check existence of hydra.
+
+**UPD** How to find common vertices in O(h + t) using array of flgs? You should initailize that array in the beginning of program. For every check you should do following actions. Firstly in  you should mark in the array all neighbours of *u*. After that you should iterate over all adjacent to *v* vertices and check value of flag in the array for every of them (in ). Vertices that have "thue" in the array will be common. Finally you should clear the array in : you should iterate over all adjacent to *u* vertices again and mark these vertices in the array as "false". Because 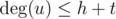 and , the total complexity will be O(h + t).
+
+All edges can be checked in time *O*(*m*(*h* + *t*)). So you either find reqired edge or find that there is no required edge. Also in time *O*(*m*) you can build hydra with fixed body-edge.
+
+This problem also has solution in  independent from values of *h* and *t*, but this solution is more complex.
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Cdiv1, Ediv2** Firstly tou should emulate all process in "idle mode". Let farmer was in points (*x*0 + 1 / 2, *y*0 + 1 / 2), (*x*1 + 1 / 2, *y*1 + 1 / 2), ... , (*x**n* + 1 / 2, *y**n* + 1 / 2). Coordinates *x*0, *x*0 + 1, *x*1, *x*1 + 1, ... *x**n*, *x**n* + 1 on axis *x* are interesting for us. Coordinates *y*0, *y*0 + 1, *y*1, *y*1 + 1, ... *y**n*, *y**n* + 1 on axis *y* are interesting too. You should store all of them into two arrays. Also you should add to these coordinates bounds of the field.
+
+Then you should build "compressed" field: every cell of this field means rectangle of the starting field that placed between neighbour interesting coordinates. Size of the compressed field is *O*(*n*) × *O*(*n*). Let's initally all cells painted into the white color. Now you should emulate all process again and paint all visited cells in the compressed field by the black color. During every move you will paint *O*(*n*) cells, so all process will be done in *O*(*n*2).
+
+Now you should emulate bugs' actions. You should run DFS (ot BFS) from some border cell of the compressed field and paint all reached cells be red color.
+
+At the end you should iterate over all compressed field and find sum of areas of rectengles corresponding to black and white cells. So, you will receive the answer.
+
+This solution works in *O*(*n*2).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Ddiv1** You need for every column find the lowermost cube that you can see. You will see all cubes above this cube.
+
+Consider the city from above. You will see drid of size *n* × *n*. Now you should draw the line through every node of the grid parallel to vector *v*. We need know only that happens in every strip between two neighbour lines. Every column cover segment of *O*(*n*) adjacent strips.
+
+Now you should create an array *a*; every element of *a* corresponding to one strip. This array will store maximal height of considered columns.
+
+Then you should sort all columns in order if increasing distance from observer. In that order you should do following queries of 2 types:
+
+1. Minimum on segment. This query is needed when you want find the lowermost visible cube.
+2. Replace *a**i* → *max*(*a**i*, *h*) on segment. You need this query for "drawing" column in the array.
+
+That is all solution. You just need choose some data structure that can fast do queries. You can select from: block decomposition (length of every block should be ; because length of every query about *O*(*n*), total complexity of solution will be *O*(*n*5 / 2)), segment tree (), stupid array (it's *O*(*n*3), cache optimized implementaton fits in the time limit).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Ediv1** We will build the matrix constructively. At any step we will have array of groups of columns. Order of groups is defined but order of columns inside every group is unknown.
+
+During building we will change order of rows because it is doesn't affect the answer (we can build answer using order of columns only).
+
+Consider the way of building of the matrix. Firstly you should find the row that has maximal number of ones. You should swap this row with the first row. Aftar that two groups of columns should be created. Into the first group you should put columns that have "1" in the firts row; all other columns should be stored into the second group. The second group is "special" — see about it below.
+
+Now you should more times search the row that has "1" in at least two groups. For every of that rows you can determine positions of all ones no more than only way. If you determined no ways, you should output NO and finish execution. After that you determined positions of ones, you should split some groups of columns into two subgroups.
+
+About "special" group. You should take into account case when you should drop some columns from this group and insert them before all groups. You will never face with situation when it is not clear which columns should be dropped and which should not, because in the beginning you chose the row with maximal number of ones.
+
+After repeating process than described above sevaral times, "good" rows may end. I.e. for every row all ones will be placed in no more than one group. Now you should recursively do solution described above inside every of groups of columns.
+
+The solution works in *O*(*n*3). It can be upgraded to , but it was not required.
+
+**UPD** Also here some *O*(*n*2) solution exists based on PQ-trees, as said [mugurelionut](/profile/mugurelionut "International Master mugurelionut"). More information [here](https://codeforces.com/blog/entry/5895#comment-112518).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
diff --git a/editorials/244.md b/editorials/244.md
@@ -0,0 +1,92 @@
+Source: https://codeforces.com/blog/entry/5895
+
+**Adiv2.** Consider an array *A* of integers in range from 1 to *nk*. Let's remove from *A* all numbers *a**i* and all other numbers store into an array *B*. The array *B* will have (*n* - 1)*k* elements. Now for *i*-th kid you should output numbers *a**i*, *B*[(*n* - 1) * (*i* - 1) + 1], *B*[(*n* - 1) * (*i* - 1) + 2], ... *B*[(*n* - 1) * (*i* - 1) + *n* - 1] (*B* is 1-based).
+
+Author is [Gerald](/profile/Gerald "Master Gerald") .
+
+**Bvid2.** Solution 1. You should write some bruteforce solution over all numbers with no more than 9 digits (number 109 should be considered separately). Bruteforce algo seems like this:
+
+```
+dfs( int num ) // run it as dfs(0)
+ if (num > 0 && num <= n) ans++
+ if (num >= 10^8) return
+ for a = 0..9 do
+ if num*10+a>0 then
+ if number num*10+a has no more than 2 different digits then
+ dfs( num*10+a )
+```
+
+ans will store the answer. After that you wrote bruteforce, you can run it and see that it works fast (that is same time for any testcase).
+
+Solution 2. Let's build all undoubdetly lucku numbers using bitmasks. You can iterate over length of number *L*, pair of digits *x* and *y*, and bitmask *m* of length *L*. If the *i*-th bit of *m* is 1, the *i*-th digit of number should be *x*; otherwise it should be *y*. So about 103 × 210 numbers will be generated (it is very rough estimate, count of numbers will be more than 10 times less).
+
+In this solution you should accurately process the case of leading zeroes and the case when all digits of number are same.
+
+Author is [Gerald](/profile/Gerald "Master Gerald")
+
+**Adiv1, Cdiv2** Let's see how function *f* changes for all suffixes of sequence *a*. Values of *f* will increase when you will increase length of suffix. For every increase all 1-bits will stay 1-bits, but some 0-bits will be changed by 1-bits. So, you can see that no more than *k* increasing will be, where *k* number of bits (in this problem *k* = 20). Among all suffixes will be no more that *k* + 1 values of function *f*.
+
+Now you can run over sequence *a* trom left to right and support an array *m* (or a set) of values of *f* for all subsegments that end in the current position. Size of *m* always no more than *k* + 1. When you go from position *i* - 1 into position *i*, you should replace *m* = {*m*1, *m*2, ..., *m**t*} by *m*' = {*a**i*, *m*1|*a**i*, *m*2|*a**i*, ... *m**t*|*a**i*}. After that you should remove from *m* repeated values (if you use set, set will do this dirty work itself). Then you should mark all numbers from *m* in some global array (or put them into some global set). At the end you should calculate answer from the global array (or set).
+
+Authors are [Gerald](/profile/Gerald "Master Gerald") , [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Bdiv1, Ddiv2** You should check for every edge: this one can be body of hydra or not. Let's fix some edge (*u*, *v*) (order of vertices is important, i.e. you should also check edge (*v*, *u*)). Now you should chose some set of *h* vertices connected with *u* and some set of *t* vertices connected with *v*. These sets should not contain vertices *u* and *v*. Also, these two sets should have no common vertices.
+
+If  and , there is no any hydra here.
+
+Orherwise, if  or 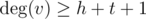, there is some hydra in any case. Even if all vertices connected with *u* and with *v* are common, number of them so big, that you always can split them into groups of size ≥ *h* and size ≥ *t*.
+
+The last case is 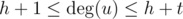 and 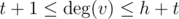. Here you can find all common vertices in *O*(*h* + *t*), using array of flags. When you find the common subset, you can easy check existence of hydra.
+
+**UPD** How to find common vertices in O(h + t) using array of flgs? You should initailize that array in the beginning of program. For every check you should do following actions. Firstly in  you should mark in the array all neighbours of *u*. After that you should iterate over all adjacent to *v* vertices and check value of flag in the array for every of them (in ). Vertices that have "thue" in the array will be common. Finally you should clear the array in : you should iterate over all adjacent to *u* vertices again and mark these vertices in the array as "false". Because 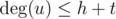 and 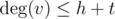, the total complexity will be O(h + t).
+
+All edges can be checked in time *O*(*m*(*h* + *t*)). So you either find reqired edge or find that there is no required edge. Also in time *O*(*m*) you can build hydra with fixed body-edge.
+
+This problem also has solution in  independent from values of *h* and *t*, but this solution is more complex.
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Cdiv1, Ediv2** Firstly tou should emulate all process in "idle mode". Let farmer was in points (*x*0 + 1 / 2, *y*0 + 1 / 2), (*x*1 + 1 / 2, *y*1 + 1 / 2), ... , (*x**n* + 1 / 2, *y**n* + 1 / 2). Coordinates *x*0, *x*0 + 1, *x*1, *x*1 + 1, ... *x**n*, *x**n* + 1 on axis *x* are interesting for us. Coordinates *y*0, *y*0 + 1, *y*1, *y*1 + 1, ... *y**n*, *y**n* + 1 on axis *y* are interesting too. You should store all of them into two arrays. Also you should add to these coordinates bounds of the field.
+
+Then you should build "compressed" field: every cell of this field means rectangle of the starting field that placed between neighbour interesting coordinates. Size of the compressed field is *O*(*n*) × *O*(*n*). Let's initally all cells painted into the white color. Now you should emulate all process again and paint all visited cells in the compressed field by the black color. During every move you will paint *O*(*n*) cells, so all process will be done in *O*(*n*2).
+
+Now you should emulate bugs' actions. You should run DFS (ot BFS) from some border cell of the compressed field and paint all reached cells be red color.
+
+At the end you should iterate over all compressed field and find sum of areas of rectengles corresponding to black and white cells. So, you will receive the answer.
+
+This solution works in *O*(*n*2).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Ddiv1** You need for every column find the lowermost cube that you can see. You will see all cubes above this cube.
+
+Consider the city from above. You will see drid of size *n* × *n*. Now you should draw the line through every node of the grid parallel to vector *v*. We need know only that happens in every strip between two neighbour lines. Every column cover segment of *O*(*n*) adjacent strips.
+
+Now you should create an array *a*; every element of *a* corresponding to one strip. This array will store maximal height of considered columns.
+
+Then you should sort all columns in order if increasing distance from observer. In that order you should do following queries of 2 types:
+
+1. Minimum on segment. This query is needed when you want find the lowermost visible cube.
+2. Replace *a**i* → *max*(*a**i*, *h*) on segment. You need this query for "drawing" column in the array.
+
+That is all solution. You just need choose some data structure that can fast do queries. You can select from: block decomposition (length of every block should be ; because length of every query about *O*(*n*), total complexity of solution will be *O*(*n*5 / 2)), segment tree (), stupid array (it's *O*(*n*3), cache optimized implementaton fits in the time limit).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
+
+**Ediv1** We will build the matrix constructively. At any step we will have array of groups of columns. Order of groups is defined but order of columns inside every group is unknown.
+
+During building we will change order of rows because it is doesn't affect the answer (we can build answer using order of columns only).
+
+Consider the way of building of the matrix. Firstly you should find the row that has maximal number of ones. You should swap this row with the first row. Aftar that two groups of columns should be created. Into the first group you should put columns that have "1" in the firts row; all other columns should be stored into the second group. The second group is "special" — see about it below.
+
+Now you should more times search the row that has "1" in at least two groups. For every of that rows you can determine positions of all ones no more than only way. If you determined no ways, you should output NO and finish execution. After that you determined positions of ones, you should split some groups of columns into two subgroups.
+
+About "special" group. You should take into account case when you should drop some columns from this group and insert them before all groups. You will never face with situation when it is not clear which columns should be dropped and which should not, because in the beginning you chose the row with maximal number of ones.
+
+After repeating process than described above sevaral times, "good" rows may end. I.e. for every row all ones will be placed in no more than one group. Now you should recursively do solution described above inside every of groups of columns.
+
+The solution works in *O*(*n*3). It can be upgraded to , but it was not required.
+
+**UPD** Also here some *O*(*n*2) solution exists based on PQ-trees, as said [mugurelionut](/profile/mugurelionut "International Master mugurelionut"). More information [here](https://codeforces.com/blog/entry/5895#comment-112518).
+
+Author is [Ripatti](/profile/Ripatti "Master Ripatti")
diff --git a/editorials/245.md b/editorials/245.md
@@ -0,0 +1,97 @@
+Source: https://codeforces.com/blog/entry/5921
+
+Hello,
+
+It's my first Blog post and I decided to dedicate it to [CROC-MBTU 2012, Elimination Round](//codeforces.com/contest/245/). I tried to do my best and explain ideas completely. Bear in mind that solutions aren't unique and they're only my ideas. At the end of each explanation, there exists a link to **C++** implementation of problem. I hope this editorial will be useful. Any constructive criticism is appreciated. Please report any bug and/or mistake you encounter here in comments.
+
+#### [A. System Administrator](//codeforces.com/contest/245/problem/A)
+
+Let's define following variables:
+
+*A**Reached* : Number of packets that reached *A*.
+
+*A**Lost* : Number of packets which didn't reach *A*.
+
+*B**Reached* : Number of packets that reached *B*.
+
+*B**Lost* : Number of packets which didn't reach *B*.
+
+We iterate over input and update each variable accordingly. Now answer for server *A* is `LIVE` if and only if *A**Reached* ≥ *A**Lost* otherwise it's `DEAD`. Also answer for server *B* is `LIVE` if and only if *B**Reached* ≥ *B**Lost* otherwise it's `DEAD`.
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2605304)
+
+#### [B. Internet Address](//codeforces.com/contest/245/problem/B)
+
+Problem guarantees that there exists an Internet resource address from which we can obtain our input. At first, let's find **Protocol** of address. It's sufficient to only check first letter of input, if it's *h* then protocol is *http* otherwise, it's *ftp*. Now, let's find position of .*ru*. We can iterate over our string from right to left and greedily choose the first occurrence of .*ru* as [TLD](https://en.wikipedia.org/wiki/Top-level_domain). Now the rest of Internet address can be obtained easily as we have positions of **Protocol** and **TLD**. Just note that we should check whether < *context* > is present after .*ru* or not. Also picking .*ru* greedily from left to right fails following testcase, hence it's incorrect.
+
+Input: `httpruru`
+
+Incorrect output: `http://.ru/ru`
+
+Correct output: `http://ru.ru`
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2607393)
+
+#### [C. Game with Coins](//codeforces.com/contest/245/problem/C)
+
+First note that if *n* ≤ 2 or  then answer is - 1. It's because of the following 2 facts:
+
+**1**. 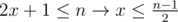 and  so *n* ≥ 3 otherwise *x* won't be a natural number.
+
+**2**. If  then *n* = 2*k* and  which means *x* ≤ *k* - 1 hence 2*x* + 1 ≤ 2*k* - 1 so there doesn't exist a *x* such that it satisfies problem's conditions and can be used to reduce *a*[*n*]
+
+In other situations, there always exists a sequence which can finish the game. We now propose a greedy algorithm and then prove it's correctness.
+
+**Algorithm**: Iterate from *n* to 2. Suppose that you're in position *i*. If  then take  otherwise, take  and execute operations with obtained *x* as long as *a*[*i*] > 0 and increase *ans* for each execution. At the end, increase *ans* by *a*[1] and output it. Remember to check if an element you're going to decrease by 1 is positive beforehand.
+
+**Correctness**: Let's prove correctness of algorithm by induction on *n*. Base case is *n* = 3 in which *ans* = *max*(*a*[1], *a*[2], *a*[3]) and algorithm correctly computes it. Now take *n* ≥ 5 and consider it's of the form 2*k* + 1. To change *a*[*n*] and *a*[*n* - 1] into 0, we need to take *x* = *k* as it's the only possible *x* which affects their values and perform operations exactly *max*(*a*[*n*], *a*[*n* - 1]) number of times. It's both necessary and sufficient in order to change both of them into 0. After that, we can ignore both *a*[*n*] and *a*[*n* - 1] from the list and induction hypothesis ensures that executing algorithm on remaining elements finishes the game in the least number of moves. 
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2605462)
+
+#### [D. Restoring Table](//codeforces.com/contest/245/problem/D)
+
+Consider *a*[*i*], *a*[*j*] and *b*[*i*][*j*] = *a*[*i*]&*a*[*j*]. Now consider binary representation of *b*[*i*][*j*]. For each 1-bit of *b*[*i*][*j*] at position *k*, (0-indexed) we conclude that *k*-th bit of *a*[*i*] and *a*[*j*] equals 1 so we set *a*[*i*] = *a*[*i*]|2*k* and *a*[*j*] = *a*[*j*]|2*k*. Now let's describe algorithm. We use *i* to iterate from 1 to *n* and for each *i*, we iterate over all *b*[*i*][*j*] such that *i* ≠ *j* and assign *a*[*i*] = *a*[*i*]|*b*[*i*][*j*]. At the end, we'll have sequence *a* constructed. Now we prove correctness of algorithm.
+
+**Correctness**: Consider 2 indices *i* and *j* such that *a*[*i*]&*a*[*j*] ≠ *b*[*i*][*j*]. Consider that *k*-th bit of *a*[*i*]&*a*[*j*] differs from *k*-th bit of *b*[*i*][*j*]. If *k*-th bit of their *AND* equals 0, we face contradiction as *k*-th bit of *b*[*i*][*j*] has to be 1 and algorithm ensures that in this situation, *k*-th bit of both numbers will be set as 1. On the other hand, if *k*-th bit of their *AND* equals 1 then we conclude that *k*-th bit of both numbers equals 1 hence when calculating *AND* of them, we get 1 in *k*-th bit which is a contradiction with our preliminary hypothesis. So we proved correctness of algorithm. 
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2607190)
+
+#### [E. Mishap in Club](//codeforces.com/contest/245/problem/E)
+
+Consider following interpretation of problem. We're standing in (0, 0) at the center of Cartesian coordinate system. We iterate over the given sequence, for each + , we move from (*x*, *y*) to (*x* + 1, *y* + 1) and for each - , we move from (*x*, *y*) to (*x* + 1, *y* - 1). Consider the maximum *y* coordinate we visit during our movement as *MAX* and minimum *y* we visit as *MIN*. It's obvious that we need at least *MAX* - *MIN* people. It can be proved that we can take our moves in such a way that we exactly need *MAX* - *MIN* people. For each + , if there exists a person out of cafe who had entered cafe once or was in cafe once, we move him in, otherwise, we need a new person. The same argument holds for each - we see in sequence.
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2607200)
+
+#### [F. Log Stream Analysis](//codeforces.com/contest/245/problem/F)
+
+First note that *"MESSAGE"* is useless and can be ignored. Year is always 2012 so it can be ignored too. Now convert each date and time to seconds past from beginning of 2012. Maintain a list, such as a vector, *V*, for storing seconds. Define pointer *head* to be head of your vector. Define *sec* to be conversion of date and time in seconds for the most recent log. As long as *head* ≤ *Size*[*V*] and *V*[*head*] + *n* ≤ *sec*, increase *head*. After that, push *sec* into *V*. If *Size*[*V*] - *head* ≥ *m* then answer is the current log. If at the end, no time was found, answer will be - 1.
+
+**Implementation Note**: You may use *stringstream* in order to ease implementation part. More information can be found [here](http://www.cplusplus.com/reference/iostream/stringstream/) and [here](http://faculty.virginia.edu/comp-phys/phys2660/html/references/www.cppreference.com/cppsstream/all.html).
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2610570)
+
+#### [G. Suggested Friends](//codeforces.com/contest/245/problem/G)
+
+Use *map* in order to map people to numbers. Construct the given graph using adjacency list. Now, let's find answer for each vertex *v*. Mark all of *v*'s neighbors. After that iterate over all other vertices, and iterate over their adjacency list and count their mutual neighbors with *v* and update answer for *v*. Complexity is *O*(*m*) for each vertex *v*. Summing up all complexities, we conclude that our algorithm is of *O*(*nm*) and as *n* is of *O*(*m*), we can conclude that overall complexity is *O*(*m*2).
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2610800)
+
+#### [H. Queries for Number of Palindromes](//codeforces.com/contest/245/problem/H)
+
+**Note**: Strings and arrays are considered 0-based in the following solution.
+
+Let *isPal*[*i*][*j*] be 1 if *s*[*i*...*j*] is palindrome, otherwise, set it 0. Let's define *dp*[*i*][*j*] to be number of palindrome substrings of *s*[*i*...*j*]. Let's calculate *isPal*[*i*][*j*] and *dp*[*i*][*j*] in *O*(|*S*|2). First, initialize *isPal*[*i*][*i*] = 1 and *dp*[*i*][*i*] = 1. After that, loop over *len* which states length of substring and for each specific *len*, loop over *start* which states starting position of substring. *isPal*[*start*][*start* + *len* - 1] can be easily calculated by the following formula:
+
+```
+isPal[start][start+len-1] = isPal[start+1][start+len-2] & (s[start] == s[start+len-1])
+```
+
+After that, *dp*[*start*][*start* + *len* - 1] can be calculated by the following formula which is derived from [Inc-Exc Principle](https://en.wikipedia.org/wiki/Inclusion-exclusion_principle).
+
+```
+dp[start][start+len-1] = dp[start][start+len-2] + dp[start+1][start+len-1] - dp[start+1][start+len-2] + isPal[start][start+len-1]
+```
+
+After preprocessing, we get queries *l**i* and *r**i* and output *dp*[*l**i* - 1][*r**i* - 1]. Overall complexity is *O*(|*S*|2).
+
+**Implementation**: [C++](//codeforces.com/contest/245/submission/2622404)
diff --git a/editorials/246.md b/editorials/246.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/5934
+
+[246A - Buggy Sorting](/contest/246/problem/A "Codeforces Round 151 (Div. 2)")
+
+In this problem you should hack the sorting algorithm, of course it was incorrect. It was correct only for arrays with *n* < = 2. In other cases you could print *n*, *n*–1, ..., 1 as a counter-example. To make the sorting right, the second cycle should be from 1 but not from *i*.
+
+[246B - Increase and Decrease](/contest/246/problem/B "Codeforces Round 151 (Div. 2)")
+
+Note, that you can always get the answer *n*–1. To get this result you should make first *n*–1 equal using the last element as the second element in pair of given operation. But after it, the whole array could become equal. It could happen if the sum of array’s elements is divisible by *n*. So the answer is *n*–1 or *n*.
+
+[246C - Beauty Pageant](/contest/246/problem/C "Codeforces Round 151 (Div. 2)")
+
+This problem was rather mathematical. The correct solution is: firstly take every element once, then take the maximum and any other, then two maximums and any other, then three maximums and any other and so on. In this case, you get as many sets as you need in this problem. It is easy to check, that all sums will be different.
+
+[246D - Colorful Graph](/contest/246/problem/D "Codeforces Round 151 (Div. 2)")
+
+This problem could be solved in this way: create new graph where vertices are the colors of the given graph. The edge between vertices *u* and *v* belongs this new graph if there are two vertices *a* and *b* in the given graph such that *c*[*a*] = *u* and *c*[*b*] = *v*. So, the answer is such color *k* with minimum number, that the degree of the vertex *k* in the new graph is maximum (without multiple edges). Such solution could be written using *O*(*M*·*log*(*N*)) time.
+
+[246E - Blood Cousins Return](/contest/246/problem/E "Codeforces Round 151 (Div. 2)")
+
+This problem had little in common with problem [208E - Blood Cousins](/contest/208/problem/E "Codeforces Round 130 (Div. 2)"). In comments to this problem there was given a solution using structure deque (array in which you can add or delete elements from both endings). Let’s describe solution using this structure.
+
+Firstly all different names change with different integers and for every vertex *v* save all queries with this vertex. Then for every vertex, which is root of some tree make dfs, the parameters of dfs are vertex *v* and deque <set > *z*. This deque for every depth *i* of the subtree of *v* save set — all different names (integers) on depth *i*.
+
+This deque could be calculated simply. Consider all sons of *v* and calculate such deque for them. Obviously, the size of our deque *z* will be maximum of sizes of descendants’ deques. Then consider every descendants’ deques and merge appropriate sets of integers. Of course, we will merge smaller set to a larger set. After that you should insert to the beginning of deque *z* the set of size 1 — color of vertex *v*.
+
+After this, you can at once answer all queries of vertex *v*. Answer is 0 if *v* has no descendants on the depth *k* or the size of *z*[*k*]. It is known that such method has good asymptotic, the author’s solution works about one second. The asymptotic is *O*(*N*·*log*2(*N*)).
+
+The solution should be realized carefully. You must not copy every element of your set or deque. You should do swap of smaller and greater set or deque without copying elements ant than merge smaller to greater.
diff --git a/editorials/248.md b/editorials/248.md
@@ -0,0 +1,77 @@
+Source: https://codeforces.com/blog/entry/5979
+
+**Задача A (div2) — Шкафы**
+
+Автор: [max777alex](/profile/max777alex "Specialist max777alex")
+
+В этой задаче можно рассмотреть независимо все левые дверцы шкафов и, аналогично, все правые. Очевидно, чтобы привести все левые дверцы шкафов в одинаковое положение, нужно определить какое из двух состояний ("левая дверца открыта" или "левая дверца закрыта") встречается чаще. Все левые дверцы, которые находятся в другом состоянии требуется привести к этому. Аналогично надо поступить и с правыми дверцами. Если аккуратно посчитать в таком случае количество операций изменения состояния дверцы, то это оно и будет ответом.
+
+**Задача B (div2) — Котенок Гав**
+
+Авторы: [max777alex](/profile/max777alex "Specialist max777alex"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+В данной задаче требовалось найти минимальное положительное *N*-значное число, которое делится без остатка на 2, 3, 5 и 7. Очевидно, раз все эти четыре числа являются простыми, то число, которое делится на все эти четыре числа, должно делиться на их произведение 2·3·5·7 = 210. Для *N* < 3 такого числа не существует. Для *N* = 3, конечно же, ответ равен 210. Для *N* > 3 следуем следующему алгоритму.
+
+Найдем остаток *R* от деления 10*N* - 1 на 210. Далее требуется добавить 210 - *R* к 10*N* - 1, чтобы получилось число, кратное 210. Учитывая, что 0 ≤ *R* < 210, получаем, что последние три разряда числа определяются значением *R*, а оставшиеся разряды — совпадают с соответствующими разрядами числа 10*N* - 1.
+
+Можно также было заметить закономерность для последних трех разрядов с изменением *N* и заменить вычисления остатков аккуратным разбором случаев.
+
+**Задача A (Div1), C (div2) — Электроник-футболист**
+
+Авторы: [am-real](/profile/am-real "Expert am-real")
+
+Для начала временно избавимся от радиуса мяча — сдвинем верхнюю стену на радиус вниз. Мяч, в таком случае, можно считать материальной точкой. Штанги не трогаем. Отразим центр мяча относительно сдвинутой верхней стены. Соединим полученный отраженный центр мяча и точку (0, *y*1 + *r*).
+
+Далее остается аккуратно определить, не касается ли мяч левой стены. Очевидно, что точкой стены, наиболее близко лежащей к траектории центра мяча, будет штанга (0, *y*2). Таким образом достаточно проверить расстояние от этой точки до траектории мяча. Если оно меньше радиуса, значит ответа нет, иначе — точка пересечения проведенной ранее линии и сдвинутой на радиус вниз стеной и будет ответом.
+
+Если целиться выше точки (0, *y*1 + *r*), траектория центра мяча только приблизится к штанге (0, *y*2), поэтому целиться в другие точки смысла не имеет.
+
+**Задача B (Div1), D (div2) — Конфеты — каждому!**
+
+Автор: [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+В задаче предполагалось, что друзья из Простоквашино могут закончить свой путь на любом участке улицы. Давайте изначально предположим, что заканчивать свой маршрут друзьям можно только на последнем участке улицы. В таком случае решение более, чем очевидно.
+
+С ростом количества изначально имеющихся с собой конфет, время, которое требуется для угощения всех жителей может либо не изменяться, либо уменьшаться. Следовательно, здесь применим бинарный поиск по количеству конфет. С помощью бинарного поиска закрепим количество конфет, которые мы изначально взяли с собой. Идем слева направо (от первого участка, до последнего). Если находимся на участке с магазином — обязательно покупаем конфеты (денег у нас бесконечно много, значит, нет смысла не покупать конфеты). Если мы находимся на участке с домом, то при наличии конфет — угощаем жителей этого дома. Если же конфет у нас нет, то пропускам этот дом. Несложно доказать, что возвращаться назад выгодно только тогда, когда у нас достаточно конфет, чтобы угостить жителей всех пропущенных домов. Пусть первый пропущенный дом оказался на участке *L*. На участке *R* мы купили конфеты, и теперь их достаточно, чтобы угостить жителей всех пропущенных домов. Тогда участок от *L* до *R* мы дополнительно пройдем еще на два раза. Если попытаться угостить жителей пропущенных домов раньше, чем мы достигнем участка *R* (на участке *T*), то участок от *L* до *T* нам так же придется преодолеть дополнительно на два раза. Однако, так как мы не можем угостить всех жителей на отрезке от *L* до *T*, это говорит о том, что придется преодолеть некоторую часть этого интервала еще два раза, для чего нам еще на два раза придется преодолеть отрезок от *T* + 1 до *R*. Очевидно, что преодолев на два раза отрезки (*L*, *T*) и (*T* + 1, *R*) мы, фактически, преодолели на два раза отрезок от *L* до *R*. Помимо этого, какую-то часть отрезка от *L* до *T* нам потребуется преодолеть еще два раза. Получается, что количество времени, которое нам потребуется, будет строго больше, чем в первом случае. Аккуратно моделируем процесс за *O*(*N*), чтобы определить минимальное количество времени, которое потребуется на выполнение прохода по улице.
+
+Теперь предложим модификацию для случая, когда закончить свое путешествие друзья могут на любом участке. В таком случае некоторую часть *P* улицы вовсе не обязательно посещать. Такая часть улицы представляет собой несколько (возможно ноль) последних участков этой улицы и не содержит домов. Определить такую часть можно за *O*(*N*) для каждого имеющегося изначально количества конфет на руках у друзей. Назовем улицу за вычетом ее части *P* полезной частью. В какой-то момент времени может оказаться так, что выгоднее дойти до конца полезной части и пойти обратно до тех пор, пока жители всех пропущенных домов не получат свои конфеты, после чего раздача сладостей прекращается. Такую проверку можно осуществлять за *O*(1) на каждом шаге вышеописанного решения.
+
+Результирующая асимптотика *O*(*N*·*logN*) (логарифм возникает из-за использования бинарного поиска).
+
+**Задача C (Div1), E (div2) — День рождения ослика Иа-Иа**
+
+Авторы: [am-real](/profile/am-real "Expert am-real"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Сформулируем ряд утверждений, которые помогут нам решить задачу. При любом действии Винни-Пуха количество нетронутых горшков на любой из полок не может быть увеличено. Таким образом, если на полке с номером *i* изначально находилось *A**i* горшков, то в любой момент времени нетронутых горшков на этой полке будет *C*, причем 0 ≤ *C* ≤ *A**i*. Несложно поддерживать вероятность *P*(*i*, *C*) того, что на полке с номером *i* находится *C* нетронутых горшков для всех возможных значений *i* и *C*. Это можно сделать с помощью динамического программирования.
+
+Очевидно, ответом после каждой операции будет сумма *P*(*i*, 0) по всем возможным значениям *i*. Заметим, что после каждой операции число нетронутых горшков может измениться только на полке, с которой Винни-Пух берет горшки. Формулы для переходов между состояниями динамического программирования достаточно тривиальны. Какие-то трудности могут возникнуть при выводе формул для *k**i* ≠ 1. Этих трудностей можно избежать, если разбивать запросы с *k**i* ≠ 1 на *k**i* запросов с *k**i* = 1, ведь 1 ≤ *k**i* ≤ 5, и, следовательно, время выполнения существенно увеличено не будет. Допустим и вариант, когда запросы не разбиваются. Для этого требуется аккуратно вывести несложные формулы переходов.
+
+Несложно заметить, что перед первым запросом можно посчитать сумму *P*(*i*, 0) по всем значениям *i*. Далее, при выполнении каждого запроса *u**i*, *v**i*, *k**i*, до его выполнения отнимать *P*(*u**i*, 0) от ответа, а после его выполнения — добавлять новое значение *P*(*u**i*, 0) к ответу.
+
+Если обозначить наибольшее значение *A**i* по всем *i*, как *MaxA*, то асимптотика такого решения, очевидно, будет *O*(*N*·*MaxA*). Памяти такое решение так же требует *O*(*N*·*MaxA*).
+
+**Задача D (Div1) — Ежик и звезды**
+
+Авторы: [am-real](/profile/am-real "Expert am-real"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Для начала заметим, что задачу можно свести к более простому варианту аналогичной задачи. В первую очередь, можно избавиться от точек, которые не находятся между двумя заданными во входных данных лучами, выходящими из начала координат. После чего можно повернуть все точки относительно начала координат на такой угол, чтобы один из лучей совпал с одной из осей координат. Для определенности положим, что мы повернули все точки на угол α1 так, чтобы луч, который был пущен под этим углом совпал с осью *O**X*.
+
+Теперь задача существенно упрощается. Все точки лежат в первой координатной четверти (то есть все координаты строго положительны), и имеется прямая *L*0 под углом α2 - α1, которая проходит через начало координат и все точки лежат ниже нее. Добавим точку начала координат в наш набор, как фиктивную. Проведем через каждую из точек прямую *L**i* параллельную прямой *L*0. Отсортируем точки в порядке убывания ординаты пересечения прямой *L**i* с осью *O**y*. Пойдем с конца. Для каждой точки *i* будем считать длину наибольшей цепочки *MaxL*(*i*), которая начинается из этой точки (смотреть будем на те точки, которые уже рассмотрены в нашем обратном порядке обхода). Для каждой точки *i* мы будем рассматривать все точки *j* между заданными лучами и выбирать такую, что *MaxL*(*j*) максимально, после чего полагать *MaxL*(*i*) = *MaxL*(*j*) + 1.
+
+Чтобы рассмотреть только те точки, которые находятся в области между лучами выходящими из точки *i*, требуется выбрать такие точки *j*, для которых *L**i* пересекает ось *O**y* выше, чем *L**j*, и ордината *Y**j* не меньше, чем ордината *Y**i*. Заметим, что из-за порядка сортировки первое условие всегда выполняется, если аккуратно обработать точки с одинаковыми прямыми *L**i*. Для соблюдения оставшегося ограничения достаточно воспользоваться стандартной идеей с деревом интервалов. Но гораздо лучше заметить, что эта задача эквивалентна задаче нахождения поиска наибольшей возрастающей последовательности. Ответом будет значение *MaxL* для фиктивной точки начала координат.
+
+Как результат, имеем решение с асимптотикой *O*(*N*·*logN*) и *O*(*N*) затратами памяти.
+
+**Задача E (Div1) — Бесконечная матрица**
+
+Автор: [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Несложно заметить ряд закономерностей. Для начала обратим внимание на первую строку матрицы. В *i*-ом столбце первой строки находится элемент со значением (*i* - 1)2 + 1. Несложно найти закономерность для первого столбца — там в чистом виде квадраты натуральных чисел. Диагональ тоже задается легкой закономерностью *i*2 - *i* + 1.
+
+Дальше несложно заметить, что в любом столбце до элемента главной диагонали значения увеличиваются с шагом в единицу. После элемента главной диагонали элемент в *i*-ой строке равен *i*2 - *i* + 1. Как видим, можно и диагональный элемент отнести к этой же закономерности.
+
+Для подматрицы, в которой нужно найти сумму, выполняем разбиение на участки над главной диагональю и под ней и производим вычисления согласно приведенным закономерностям. В авторском решении использовались суммы для квадратов первых *N* чисел, для суммы сумм квадратов первых *N* чисел и (выраженная через них) сумма кубов первых *N* чисел. Существуют и другие варианты формул.
+
+Теперь стоит выполнить все вычисления по модулю 1010. Для того, чтобы отследить, имеет ли число более десяти знаков, будем хранить (помимо остатка) частное от деления на 1010 по модулю нескольких различных простых чисел порядка 109. На практике достаточно и одного простого числа, но для генерации тестов использовалось сразу четыре.
+
+Для решения задачи также можно использовать и типы данных, связанные с длинной арифметикой. Много решений с такой реализацией проходили. Однако, стоит отметить, что нельзя погарантировать хорошее быстродействие такому решению.
diff --git a/editorials/249.md b/editorials/249.md
@@ -0,0 +1,77 @@
+Source: https://codeforces.com/blog/entry/5979
+
+**Задача A (div2) — Шкафы**
+
+Автор: [max777alex](/profile/max777alex "Specialist max777alex")
+
+В этой задаче можно рассмотреть независимо все левые дверцы шкафов и, аналогично, все правые. Очевидно, чтобы привести все левые дверцы шкафов в одинаковое положение, нужно определить какое из двух состояний ("левая дверца открыта" или "левая дверца закрыта") встречается чаще. Все левые дверцы, которые находятся в другом состоянии требуется привести к этому. Аналогично надо поступить и с правыми дверцами. Если аккуратно посчитать в таком случае количество операций изменения состояния дверцы, то это оно и будет ответом.
+
+**Задача B (div2) — Котенок Гав**
+
+Авторы: [max777alex](/profile/max777alex "Specialist max777alex"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+В данной задаче требовалось найти минимальное положительное *N*-значное число, которое делится без остатка на 2, 3, 5 и 7. Очевидно, раз все эти четыре числа являются простыми, то число, которое делится на все эти четыре числа, должно делиться на их произведение 2·3·5·7 = 210. Для *N* < 3 такого числа не существует. Для *N* = 3, конечно же, ответ равен 210. Для *N* > 3 следуем следующему алгоритму.
+
+Найдем остаток *R* от деления 10*N* - 1 на 210. Далее требуется добавить 210 - *R* к 10*N* - 1, чтобы получилось число, кратное 210. Учитывая, что 0 ≤ *R* < 210, получаем, что последние три разряда числа определяются значением *R*, а оставшиеся разряды — совпадают с соответствующими разрядами числа 10*N* - 1.
+
+Можно также было заметить закономерность для последних трех разрядов с изменением *N* и заменить вычисления остатков аккуратным разбором случаев.
+
+**Задача A (Div1), C (div2) — Электроник-футболист**
+
+Авторы: [am-real](/profile/am-real "Expert am-real")
+
+Для начала временно избавимся от радиуса мяча — сдвинем верхнюю стену на радиус вниз. Мяч, в таком случае, можно считать материальной точкой. Штанги не трогаем. Отразим центр мяча относительно сдвинутой верхней стены. Соединим полученный отраженный центр мяча и точку (0, *y*1 + *r*).
+
+Далее остается аккуратно определить, не касается ли мяч левой стены. Очевидно, что точкой стены, наиболее близко лежащей к траектории центра мяча, будет штанга (0, *y*2). Таким образом достаточно проверить расстояние от этой точки до траектории мяча. Если оно меньше радиуса, значит ответа нет, иначе — точка пересечения проведенной ранее линии и сдвинутой на радиус вниз стеной и будет ответом.
+
+Если целиться выше точки (0, *y*1 + *r*), траектория центра мяча только приблизится к штанге (0, *y*2), поэтому целиться в другие точки смысла не имеет.
+
+**Задача B (Div1), D (div2) — Конфеты — каждому!**
+
+Автор: [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+В задаче предполагалось, что друзья из Простоквашино могут закончить свой путь на любом участке улицы. Давайте изначально предположим, что заканчивать свой маршрут друзьям можно только на последнем участке улицы. В таком случае решение более, чем очевидно.
+
+С ростом количества изначально имеющихся с собой конфет, время, которое требуется для угощения всех жителей может либо не изменяться, либо уменьшаться. Следовательно, здесь применим бинарный поиск по количеству конфет. С помощью бинарного поиска закрепим количество конфет, которые мы изначально взяли с собой. Идем слева направо (от первого участка, до последнего). Если находимся на участке с магазином — обязательно покупаем конфеты (денег у нас бесконечно много, значит, нет смысла не покупать конфеты). Если мы находимся на участке с домом, то при наличии конфет — угощаем жителей этого дома. Если же конфет у нас нет, то пропускам этот дом. Несложно доказать, что возвращаться назад выгодно только тогда, когда у нас достаточно конфет, чтобы угостить жителей всех пропущенных домов. Пусть первый пропущенный дом оказался на участке *L*. На участке *R* мы купили конфеты, и теперь их достаточно, чтобы угостить жителей всех пропущенных домов. Тогда участок от *L* до *R* мы дополнительно пройдем еще на два раза. Если попытаться угостить жителей пропущенных домов раньше, чем мы достигнем участка *R* (на участке *T*), то участок от *L* до *T* нам так же придется преодолеть дополнительно на два раза. Однако, так как мы не можем угостить всех жителей на отрезке от *L* до *T*, это говорит о том, что придется преодолеть некоторую часть этого интервала еще два раза, для чего нам еще на два раза придется преодолеть отрезок от *T* + 1 до *R*. Очевидно, что преодолев на два раза отрезки (*L*, *T*) и (*T* + 1, *R*) мы, фактически, преодолели на два раза отрезок от *L* до *R*. Помимо этого, какую-то часть отрезка от *L* до *T* нам потребуется преодолеть еще два раза. Получается, что количество времени, которое нам потребуется, будет строго больше, чем в первом случае. Аккуратно моделируем процесс за *O*(*N*), чтобы определить минимальное количество времени, которое потребуется на выполнение прохода по улице.
+
+Теперь предложим модификацию для случая, когда закончить свое путешествие друзья могут на любом участке. В таком случае некоторую часть *P* улицы вовсе не обязательно посещать. Такая часть улицы представляет собой несколько (возможно ноль) последних участков этой улицы и не содержит домов. Определить такую часть можно за *O*(*N*) для каждого имеющегося изначально количества конфет на руках у друзей. Назовем улицу за вычетом ее части *P* полезной частью. В какой-то момент времени может оказаться так, что выгоднее дойти до конца полезной части и пойти обратно до тех пор, пока жители всех пропущенных домов не получат свои конфеты, после чего раздача сладостей прекращается. Такую проверку можно осуществлять за *O*(1) на каждом шаге вышеописанного решения.
+
+Результирующая асимптотика *O*(*N*·*logN*) (логарифм возникает из-за использования бинарного поиска).
+
+**Задача C (Div1), E (div2) — День рождения ослика Иа-Иа**
+
+Авторы: [am-real](/profile/am-real "Expert am-real"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Сформулируем ряд утверждений, которые помогут нам решить задачу. При любом действии Винни-Пуха количество нетронутых горшков на любой из полок не может быть увеличено. Таким образом, если на полке с номером *i* изначально находилось *A**i* горшков, то в любой момент времени нетронутых горшков на этой полке будет *C*, причем 0 ≤ *C* ≤ *A**i*. Несложно поддерживать вероятность *P*(*i*, *C*) того, что на полке с номером *i* находится *C* нетронутых горшков для всех возможных значений *i* и *C*. Это можно сделать с помощью динамического программирования.
+
+Очевидно, ответом после каждой операции будет сумма *P*(*i*, 0) по всем возможным значениям *i*. Заметим, что после каждой операции число нетронутых горшков может измениться только на полке, с которой Винни-Пух берет горшки. Формулы для переходов между состояниями динамического программирования достаточно тривиальны. Какие-то трудности могут возникнуть при выводе формул для *k**i* ≠ 1. Этих трудностей можно избежать, если разбивать запросы с *k**i* ≠ 1 на *k**i* запросов с *k**i* = 1, ведь 1 ≤ *k**i* ≤ 5, и, следовательно, время выполнения существенно увеличено не будет. Допустим и вариант, когда запросы не разбиваются. Для этого требуется аккуратно вывести несложные формулы переходов.
+
+Несложно заметить, что перед первым запросом можно посчитать сумму *P*(*i*, 0) по всем значениям *i*. Далее, при выполнении каждого запроса *u**i*, *v**i*, *k**i*, до его выполнения отнимать *P*(*u**i*, 0) от ответа, а после его выполнения — добавлять новое значение *P*(*u**i*, 0) к ответу.
+
+Если обозначить наибольшее значение *A**i* по всем *i*, как *MaxA*, то асимптотика такого решения, очевидно, будет *O*(*N*·*MaxA*). Памяти такое решение так же требует *O*(*N*·*MaxA*).
+
+**Задача D (Div1) — Ежик и звезды**
+
+Авторы: [am-real](/profile/am-real "Expert am-real"), [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Для начала заметим, что задачу можно свести к более простому варианту аналогичной задачи. В первую очередь, можно избавиться от точек, которые не находятся между двумя заданными во входных данных лучами, выходящими из начала координат. После чего можно повернуть все точки относительно начала координат на такой угол, чтобы один из лучей совпал с одной из осей координат. Для определенности положим, что мы повернули все точки на угол α1 так, чтобы луч, который был пущен под этим углом совпал с осью *O**X*.
+
+Теперь задача существенно упрощается. Все точки лежат в первой координатной четверти (то есть все координаты строго положительны), и имеется прямая *L*0 под углом α2 - α1, которая проходит через начало координат и все точки лежат ниже нее. Добавим точку начала координат в наш набор, как фиктивную. Проведем через каждую из точек прямую *L**i* параллельную прямой *L*0. Отсортируем точки в порядке убывания ординаты пересечения прямой *L**i* с осью *O**y*. Пойдем с конца. Для каждой точки *i* будем считать длину наибольшей цепочки *MaxL*(*i*), которая начинается из этой точки (смотреть будем на те точки, которые уже рассмотрены в нашем обратном порядке обхода). Для каждой точки *i* мы будем рассматривать все точки *j* между заданными лучами и выбирать такую, что *MaxL*(*j*) максимально, после чего полагать *MaxL*(*i*) = *MaxL*(*j*) + 1.
+
+Чтобы рассмотреть только те точки, которые находятся в области между лучами выходящими из точки *i*, требуется выбрать такие точки *j*, для которых *L**i* пересекает ось *O**y* выше, чем *L**j*, и ордината *Y**j* не меньше, чем ордината *Y**i*. Заметим, что из-за порядка сортировки первое условие всегда выполняется, если аккуратно обработать точки с одинаковыми прямыми *L**i*. Для соблюдения оставшегося ограничения достаточно воспользоваться стандартной идеей с деревом интервалов. Но гораздо лучше заметить, что эта задача эквивалентна задаче нахождения поиска наибольшей возрастающей последовательности. Ответом будет значение *MaxL* для фиктивной точки начала координат.
+
+Как результат, имеем решение с асимптотикой *O*(*N*·*logN*) и *O*(*N*) затратами памяти.
+
+**Задача E (Div1) — Бесконечная матрица**
+
+Автор: [pkhaustov](/profile/pkhaustov "Candidate Master pkhaustov")
+
+Несложно заметить ряд закономерностей. Для начала обратим внимание на первую строку матрицы. В *i*-ом столбце первой строки находится элемент со значением (*i* - 1)2 + 1. Несложно найти закономерность для первого столбца — там в чистом виде квадраты натуральных чисел. Диагональ тоже задается легкой закономерностью *i*2 - *i* + 1.
+
+Дальше несложно заметить, что в любом столбце до элемента главной диагонали значения увеличиваются с шагом в единицу. После элемента главной диагонали элемент в *i*-ой строке равен *i*2 - *i* + 1. Как видим, можно и диагональный элемент отнести к этой же закономерности.
+
+Для подматрицы, в которой нужно найти сумму, выполняем разбиение на участки над главной диагональю и под ней и производим вычисления согласно приведенным закономерностям. В авторском решении использовались суммы для квадратов первых *N* чисел, для суммы сумм квадратов первых *N* чисел и (выраженная через них) сумма кубов первых *N* чисел. Существуют и другие варианты формул.
+
+Теперь стоит выполнить все вычисления по модулю 1010. Для того, чтобы отследить, имеет ли число более десяти знаков, будем хранить (помимо остатка) частное от деления на 1010 по модулю нескольких различных простых чисел порядка 109. На практике достаточно и одного простого числа, но для генерации тестов использовалось сразу четыре.
+
+Для решения задачи также можно использовать и типы данных, связанные с длинной арифметикой. Много решений с такой реализацией проходили. Однако, стоит отметить, что нельзя погарантировать хорошее быстродействие такому решению.
diff --git a/editorials/25.md b/editorials/25.md
@@ -0,0 +1,101 @@
+Source: https://codeforces.com/blog/entry/594
+
+### Problem A - IQ Test
+
+We can store two values, *count**odd* and *count**even*, as the number of odd or even elements in the series. We can also store *last**odd* and *last**even* as the index of the last odd/even item encountered. If only one odd number appears --- output *last**odd*; otherwise only one even number appears, so output *last**even*.
+
+
+
+### Problem B - Telephone Numbers
+
+There are many ways of separating the string into clusters of 2 or 3 characters. One easy way is to output 2 characters at a time, until you have only 2 or 3 characters remaining. Here is a possible C++ solution:
+
+<code>
+for( i=0; i<n; i++ )
+{
+ putchar(buf[i]);
+ if( i%2 && i<n-(n%2)-2 ) putchar('-');
+}
+</code>
+
+
+
+### Problem C - Roads in Berland
+
+If you are familiar with the [Floyd-Warshall algorithm](https://en.wikipedia.org/wiki/Floyd-Warshall_algorithm), then this solution may be easier to see.
+
+Initially, we are given a matrix *D*, where *D*[*i*][*j*] is the distance of shortest path between city *i* and city *j*. Suppose we build a new road between *a* and *b* with length shorter than *D*[*a*][*b*]. How do we update the rest of the graph accordingly?
+
+Define a new matrix *D*', whose entries *D*'[*i*][*j*] are the minimum path distance between *i* and *j* while taking into account the new road *ab*. There are three possibilities for each *i*, *j*:
+
+* *D*'[*i*][*j*] remains unchanged by the new road. In this case *D*'[*i*][*j*] = *D*[*i*][*j*]
+* *D*'[*i*][*j*] is shorter if we use the new road *ab*. This means that the new path *i*, *v*1, *v*2, ..., *v**n*, *j* must include the road *a*, *b*. If we connect the vertices *i*, *a*, *b*, *j* together in a path, then our new distance will be *D*[*i*][*a*] + *length*(*ab*) + *D*[*b*][*j*].
+* Lastly, we may have to use the road *ba*. (Note that this may *not* be the same as road *ab*.) In this case, we have *D*'[*i*][*j*] = *D*[*i*][*b*] + *length*(*ab*) + *D*[*a*][*j*].
+
+Thus, for each new road that we build, we must update each path *i*, *j* within the graph. Then we must sum shortest distances between cities. Updating the matrix and summing the total distance are both *O*(*N*2), so about 3002 operations. Lastly, there are at most 300 roads, so in total there are about 3003 operations.
+
+One thing to note is that the sum of all shortest distances between cities may be larger than an int; thus, we need to use a long when calculating the sum.
+
+
+
+### Problem D - Roads not only in Berland
+
+Before we start this problem, it is helpful to know about the [union find](https://en.wikipedia.org/wiki/Disjoint-set_data_structure) data structure. The main idea is this: given some elements *x*1, *x*2, *x*3, ..., *x**n* that are partitioned in some way, we want to be able to do the following:
+
+* merge any two sets together quickly
+* find the parent set of any *x**i*
+
+This is a general data structure that sometimes appears in programming competitions. There are a lot of ways to implement it; one good example is written by Bruce Merry (aka BMerry) [here](https://www.google.com/url?sa=t&source=web&cd=7&ved=0CC8QFjAG&url=http%3A%2F%2Folympiad.cs.uct.ac.za%2Fpresentations%2Fcamp1_2006%2Funionfind-handout.pdf&ei=UydjTKqaJIW8lQfZ0IjCDw&usg=AFQjCNGNSiYFJv4MADuMR4EgCkLln5Blmg).
+
+Back to the problem: Every day we are allowed to build exactly 1 road, and close exactly 1 road. Thus, we can break the problem into two parts:
+
+* How do we connect the parts of the graph that are disconnected?
+* How do we remove roads in a way that does not disconnect parts of the graph?
+
+Let *build* be the list all roads that need to be built, and let *close* be the list of nodes that need to be closed. We can show that in fact, these lists are of the same size. This is because the connected graph with *n* nodes is a tree if and only if it has *n* - 1 edges. Thus, if we remove more roads than than we build, then the graph is disconnected. Also, if we build more roads than we remove, then we have some unnecessary roads (the graph is no longer a tree).
+
+Now consider the format of the input data:
+*a*1, *b*1
+*a*2, *b*2
+...
+*a**n* - 1, *b**n* - 1
+We can show that edge (*a**i*, *b**i*) is unnecessary if and only if the nodes *a**i*, *b**i* have already been connected by edges (*a*1, *b*1), (*a*2, *b*2), ..., (*a**i* - 1, *b**i* - 1). In other words, if the vertices *a**i*, *b**i* are in the same connected component *before* we, add (*a**i*, *b**i*) then we do not need to add (*a**i*, *b**i*). We can use union-find to help us solve this problem:
+
+<code>
+for( i from 1 to n-1 )
+{
+ if( find(*a**i*)=find(*b**i*) ) close.add(*a**i*, *b**i*);
+ else merge(*a**i*, *b**i*);
+}
+</code>
+
+In other words, we treat each connected component as a set. Union find allows us to find the connected component for each node. If the two connected components are the same, then our new edge is unnecessary. If they are different, then we can merge them together (with union find). This allows us to find the edges that we can remove.
+
+In order to find the edges that we need to add to the graph, we can also use union-find: whenever we find a component that is disconnected from component 1, then we just add an edge between them.
+
+<code>
+for( i from 2 to n )
+ if( find(*v**i*)!=find(*v*1) )
+ {
+ then merge(*v*1, *v**i*);
+ build.add(*v*1, *v**i*);
+ }
+</code>
+
+We just need to store the lists of roads that are unnecessary, and the roads that need to be built.
+
+
+
+### Problem E - Test
+
+The way I solved this problem is with a [hash function](https://en.wikipedia.org/wiki/Hash_code). Hash functions can fail on certain cases, so in fact, my solution is not 'correct'. However, it passed all the test cases =P
+
+Let the input strings be *s*0, *s*1, *s*2. We can build the shortest solution by permuting the strings and then trying to 'attach' them to each other. I.e., we need to find the longest overlapping segments at the end of string *a* and the beginning of string *b*. The obvious brute force solution won't run in time. However, we can use a hash function to help us calculate the result in *O*(*n*) time, where *n* is *min*(*len*(*a*), *len*(*b*)). The hash function that I used was the polynomial *hash*(*x*0, *x*1, ..., *x**n*) = *x*0 + *ax*1 + *a*2*x*2 + ... + *a**n**x**n*. This polynomial is a good hash function in this problem because it has the following useful property:
+Given *hash*(*x**i*, ..., *x**j*), we can calculate the following values in *O*(1) time:
+
+* *hash*(*x**i* - 1, *x**i*, ..., *x**j*) = *x**i* - 1 + *a* × *hash*(*x**i*, ..., *x**j*)
+* *hash*(*x**i*, ..., *x**j*, *x**j* + 1) = *hash*(*x**i*, ..., *x**j*) + *a**j* + 1 - *i* × *x**j* + 1
+
+In other words, if we know the hash for some subsequence, we can calculate the hash for the subsequence and the previous element, or the subsequence and the next element. Given two strings *a*, *b*, we can calculate the hash functions starting from the end of *a* and starting from the beginning of *b*. If they are equal for length *n*, then that means that (maybe) *a* and *b* overlap by *n* characters.
+
+Thus, we can try every permutation of *s*0, *s*1, *s*2, and try appending the strings to each other. There is one last case: if *s**i* is a substring of *s**j* for some *i* ≠ *j*, then we can just ignore *s**i*. We can use hash functions to check that one string is contained within another one.
diff --git a/editorials/250.md b/editorials/250.md
@@ -0,0 +1,35 @@
+Source: https://codeforces.com/blog/entry/5973
+
+[250A - Paper Work](/contest/250/problem/A "CROC-MBTU 2012, Final Round (Online version, Div. 2)"). For every folder you should take reports as much as possible. In other words, you should stop forming a folder either before the third bad report or in the end of sequence. You can easily prove that this strategy is optimal. This solution works in *O*(*n*).
+
+Author is [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov")
+
+. [250B - Restoring IPv6](/contest/250/problem/B "CROC-MBTU 2012, Final Round (Online version, Div. 2)"). Firstly you should split string into substrings using ":" as separator. All empty substrings will go in the row; you should leave only one of them. Then you should calculate number of nonempty substrings and determine number of zero-blocks whicр will replace empty substring. After replacing you should increase every substring to length 4 inserting leading zeros. After all you should output the answer.
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
+
+[250C - Movie Critics](/contest/250/problem/C "CROC-MBTU 2012, Final Round (Online version, Div. 2)"). Consider some maximal by inclusion segment of movies of some genre *x* (this number from 1 to *k*). Now let's see how changes number of stresses after removing this segment. If the segment adjoins to the end of all sequence *a*, improvement will be +1. Segment cannot adjoin to both ends of sequence because *k* > 1. For some seqment [*i*, *j*] inside of sequence consider values *a**i* - 1 and *a**j* + 1. If they are equal, after deleting segment improvement will be +2; otherwise it will be +1.
+
+Now you should iterate over all maximal be inclusion segments and find improvement for every of them. After that you should group all segments by genre and calculate sum of improvements inside every group. Answer will be number of genre of group that has maximal total improvement (if there are many of them, you should chose minimal number of genre).
+
+You can implement this solution in in *O*(*n*).
+
+Authors are [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov") [Gerald](/profile/Gerald "Master Gerald") [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
+
+[250D - Building Bridge](/contest/250/problem/D "CROC-MBTU 2012, Final Round (Online version, Div. 2)"). For every point of the east river bank you should find optimal point of the west bank. After that you should chose optimal pair over all considered east points.
+
+Well, let's fix *j*-th east point (1 ≤ *j* ≤ *m*). Now consider how changes total distance depending on chosing the west point. The best point is intersection of lines *OB**j* и *x* = *a*: , but this point can be not present among all west points. You can see that if you will move from point *Z* up or down, total distance will increase. So only nearest to *Z* points may be considered.
+
+You can find that points using binary search. Also you can observe that after every increasing of *j* point *Z* will move in same direction; so you can support nearest points to *Z* usins some pointer. The third way is using such fact that during moving point over the west bank total distance initially will decrease and then increase; so you can use ternary search here.
+
+Considered solutions work in *O*(*m* + *n*) and .
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
+
+[250E - Mad Joe](/contest/250/problem/E "CROC-MBTU 2012, Final Round (Online version, Div. 2)"). You should emulate the process. You can catch case of infinity walk if you will observe hits with concrete wall from the left and the right side. If for some floor both types of hits happened, you should output "Never".
+
+Stupid emulation is very slow. It has complexity *O*(*nm*2) and answer can be about 1010. You should speed up stupid emulation using following way.
+
+For every floor you should store segment of visited cells (two integers — L and R bounds). We know that under every cell of this segment all cells are non-empty. Therefore after every changing of move direction you can go through all the segment in *O*(1). After every one or two "teleportations" through segment you either expand bounds of the segnent or change some brick-cell into empty-cell or fall down. But actions of every type you can do no more than *nm* times, so this optimization improves complexety to *O*(*nm*).
+
+Author is [Ripatti](/profile/Ripatti "Candidate Master Ripatti").
diff --git a/editorials/251.md b/editorials/251.md
@@ -0,0 +1,105 @@
+Source: https://codeforces.com/blog/entry/6054
+
+This is a complete English version of the editorial of Codeforces Round #153. If you have any questions or suggestions, feel free to post them in the comments.
+
+### [252A - Little Xor](/contest/252/problem/A "Codeforces Round 153 (Div. 2)") (A div 2)
+
+Let's iterate over all segments in our array. For each of them we'll find the *xor* of all its elements. Then we need to output the maximal *xor* we've seen.
+
+### [252B - Unsorting Array](/contest/252/problem/B "Codeforces Round 153 (Div. 2)") (B div 2)
+
+If all elements in the array are equal then there's no pair of numbers we are looking for. Now we can assume that there exist at least 2 different numbers in the array. Let's iterate over all pairs of different numbers in the array and for each such pair we'll check if it can be the answer. If some pair indeed can be the answer, we'll output it and terminate the program. Otherwise, there is no pair of numbers we are looking for, so we need to output -1.
+
+It may seem that the complexity of described algorithm is *O*(*N*3). Actually it's not true and the real complexity is *O*(*N*). One may notice that in every array of length greater than 3 there are at least 3 pairs of different numbers (remember we assumed that there exist at least one pair of different numbers in the array). Note that these 3 pairs lead to 3 different resulting arrays. On the other hand, there are only 2 possible sorted arrays. According to the pigeonhole principle one of these 3 resulting arrays is unsorted.
+
+### [252C - Points on Line](/contest/252/problem/C "Codeforces Round 153 (Div. 2)") (C div 2)
+
+### [251A - Points on Line](/contest/251/problem/A "Codeforces Round 153 (Div. 1)") (A div 1)
+
+Let's select the rightmost point of our triplet. In order to do this we can iterate over all points in ascending order of their X-coordinate. At the same time we'll maintain a pointer to the leftmost point which lays on the distance not greater than *d* from the current rightmost point. We can easily find out the number of points in the segment between two pointers, excluding the rightmost point. Let's call this number *k*. Then there exist exactly *k* * (*k* - 1) / 2 triplets of points with the fixed rightmost point. The only thing left is to sum up these values for all rightmost points.
+
+### [252D - Playing with Permutations](/contest/252/problem/D "Codeforces Round 153 (Div. 2)") (D div 2)
+
+### [251B - Playing with Permutations](/contest/251/problem/B "Codeforces Round 153 (Div. 1)") (B div 1)
+
+First, we need to theck whether permutation *s* is the identity permutation. If it is, then the answer is "NO".
+
+Now we'll describe an algorithm which works in all cases except for one. We'll tell about this case later.
+
+Let's apply our permutation *q* until either the current permutation becomes equal to *s* or we make exactly *k* steps. If the current permutation is equal to *s* and we've made *t* steps before this happened, then we need to look at the parity of *k* - *t*. If this number is even, then we can select any two consequent permutations in the sequence and apply (*k* - *t*) / 2 times the following two permutations in this order: *q* and *inv*(*q*), where *inv*(*q*) is the inversed permutation *q*. Actually, we don't need to build the sequence itself, it's enough to check only the parity of *k* - *t*. So, if it is even, then the answer is "YES".
+
+Analogically, we can replace *q* with *inv*(*q*) and repeat described process again. If we still didn't print "YES", then the answer is "NO".
+
+The algorithm we've just described works for all cases except for one: when the permutation *q* is equal to *inv*(*q*) and at the same time *s* is reachable within one step. In this case the answer is "YES" iff *k* = 1.
+
+The complexity of described solution is *O*(*N*2).
+
+### [252E - Number Transformation](/contest/252/problem/E "Codeforces Round 153 (Div. 2)") (E div 2)
+
+### [251C - Number Transformation](/contest/251/problem/C "Codeforces Round 153 (Div. 1)") (C div 1)
+
+Let *L* be the least common multiple of all numbers from 2 to *k*, inclusive. Note that if *a* is divisible by *L*, then we can't decrease it with applying an operation of the second type. It means that any optimal sequence of transformations will contain all numbers divisible by *L* which are located between *b* and *a*. Let's split our interval from *b* to *a* into several intervals between the numbers divisible by *L*. It may happen that the first and the last intervals will have length less than *L*. Now we can solve the problem for the first interval, the last interval and for any interval between them. After that we need to multiply the last result by the total number of intervals excluding the first and the last ones. The only thing left is to add up obtained 3 values.
+
+In order to solve the problem for one interval one can simply use bfs.
+
+Be careful in the cases when we have only 1 or 2 intervals.
+
+The complexity of described solution is *O*(*L*).
+
+### [251D - Two Sets](/contest/251/problem/D "Codeforces Round 153 (Div. 1)") (D div 1)
+
+Let *X* be the *xor* of all numbers in the input. Also let *X*1 be the *xor* of all numbers in the first collection and *X*2 be the *xor* of all numbers in the second collection. Note, if the *i*-th bit in *X* is equal to 1 then the same bit in numbers *X*1 and *X*2 is either equal 0 and 1 or 1 and 0, respectively. Analogically, if the *i*-th bit in *X* is equal to 0 then this bit in numbers *X*1 and *X*2 is either equal 0 and 0 or 1 and 1, respectively. As we can see, if the *i*-th bit in *X* is equal to 1 then it doesn't affect on the sum *X*1 + *X*2 in any way. For now, let's forget about the second condition in the statement which asks us to minimize *X*1 in case of tie.
+
+In order to find the optimal value of *X*1 + *X*2 we need to make one more observation. Let's look at the most significant bit of number *X* which is equal to 0. If there exist such partitions of the initial collection in which this bit is equal to 1 in *X*1 then the optimal partition should be one of them. To prove this one should remember that the respective bit in number *X*2 is also equal to 1. Let this bit correspond to 2*L*. If the bit we are looking at is equal to 1 in both *X*1 and *X*2 then the smallest possible value of *X*1 + *X*2 is 2*L* + 1. On the other hand, if both *X*1 and *X*2 have zero in this bit, then the maximal possible value of *X*1 + *X*2 is 2*L* + 1 - 2 which is strictly smaller than 2*L* + 1.
+
+We'll be solving the initial problem with a greedy algorithm. Let's iterate over all bits which are equal to 0 in number *X* from highest to lowest. We'll try to put 1 to the number *X*1 in this position and then check if there exists at least one partition which satisfies the current condition together with all conditions we've already set up. If such partition exists, then we can leave our newly added condition and move to lower bits. If there is no such condition, then we need to move to lower bits without adding any new conditions. At the end we'll find the maximal value of *X*1 + *X*2.
+
+So, we have a set of conditions and we want to check if there exist at least one partition which satisfies all of them. For each condition for *i*-th bit we'll create an equation over the field *Z*2 with *n* variables, where the coefficient at the *j*-th variable is equal to the *i*-th bit of the *j*-th number. If some variable is equal to one then we take the corresponding number into the first set, otherwise -- into the second one. This system of equations can be solved with Gaussian elimination. Note that we don't need to solve the complete system from scratch every time we add a new equation. It's sufficient to recalculate the matrix from the previous state, which can be done in *O*(*NK*). Here *K* is the number of equations in the system.
+
+Now we need to minimize *X*1 while keeping the value of *X*1 + *X*2 unchanged. It can be done in the similar way as finding the optimal value of *X*1 + *X*2. We'll iterate over all bits which are equal to 1 in number *X* starting from the highest one. For the current bit we'll try to put 0 in the corresponding position of *X*1. If after adding this condition our system of equations becomes incompatible, then we need to put 1 in this position of *X*1.
+
+The complexity of this algorithm is *O*(*NL*2), where *L* -- is the length of binary notation of the largest number. For further optimization one can use *bitset* in Gaussian elimination, although it wasn't necessary for getting AC during the contest.
+
+### [251E - Tree and Table](/contest/251/problem/E "Codeforces Round 153 (Div. 1)") (E div 1)
+
+If *N* = 1, then the answer is 2.
+
+If there is a node with degree greater than 3 in the tree, then the answer is 0. That's because every cell of the table has at most 3 neighbors.
+
+If there is no vertex of degree 3 in the tree, then the answer is 2*n*2 - 2*n* + 4. This formula can be derieved in natural way during the solution of other parts of the problem. Also, one could write a simple DP to calculate the answer in this case. Anyway, let's prove this formula.
+
+At first, let's solve slightly different problem, which will be also used in the solution of main case of the initial problem. We want to find the number of ways to place a tree in which all nodes have degree smaller than 3 on the table so that one node of degree 1 is attached to the upper-left corner of the table (let it be node number 1). It can be shown that if the table has size 2xK, then the number of placements of the tree is equal to *K*. The last formula can be proven by mathematical induction. If *K* = 1 then the above statement is obviously true. Suppose *K* > 1 and let's assume that the table is oriented horizontally so that we have 2 rows and *K* columns. If we put a vertex adjacent to the first one to the right from upper-left corner then we have only 1 way to complete the placement of the tree. If we put this vertex to the bottom-left corner, than the next vertex should be put to (2, 2) and the problem is reduced to the same one with *K* smaller by one. We have a recurrent relation *f*(*K*) = *f*(*K* - 1) + 1 and we know that *f*(1) = 1. This means that *f*(*K*) = *K*.
+
+Let's come back to the initial problem of counting the nymber of ways to put a tree without vertices of degree 3 on the table 2xN. Without loss of generality let's assume that the first vertex has degree 1. We'll consider only placements in which the first vertex is laying in the first row and at the end we'll multiply our answer by 2. If the first vertex is laying in the first or the last column then then there are *N* ways to complete the tree (see the previous paragraph). If the first vertex is laying in the *i*-th column than there are *i* - 1 ways of placing our tree in which a vertex adjacent to the first one (let it be vertex 2) is laying to the left of it. Also there are *N* - *i* ways in which the second vertex is laying to the right of vertex 1. Adding up these values for all columns and multiplying the answer by 2 we get the final formula: 2*n*2 - 2*n* + 4.
+
+Now we have only one case left in which there exists a vertex of degree 3 in our tree. Let's declare this vertex to be a root. If there are several vertices of degree 3, any of them can be chosen to be a root. We'll assume that the root is laying in the first row and at the end we'll multiply our answer by 2. Obviously, the root should be put to a cell with 3 neighbors. Each descendant of the root should be put either to the left, to the right or to the bottom from the cell which contains the root. Let's fix this ordering (to do this we need to iterate over 6 permutations). Also if the "bottom" son of the root has degree greater than 1, then we'll also fix the ordering of its adjacent vertices (there are 2 ways to do this). Now the column which contains the root is fully occupied. The last statement means that regardless of the way we place the rest of vertices, the ones to the right from the root will stay there. The same for all vertices which lay to the left from the root. Moreover, we have the fixed number of vertices to the left from the root, which means that there's at most one way to place the root on our table. Note that if the number of vertices to the left from the root is odd, then we won't be able to complete the placement. In order to find the number of vertices to the left from the root we need to sum up sizes of subtrees of its left descendant and of the left descendant of its bottom son.
+
+So, we have two separate subproblems (for vertices laying to the left from the root and to the right from the root) and for each of them we need to calculate the number of trees to place the rest of our tree in the table. There are only two possible situations:
+
+1) We need to place a subtree with its root in vertex *v* on the rectangular table in such way that vertex *v* is laying in the corner (let it be upper-left corner).
+
+2) We need to place subtrees with roots in *v*1 and *v*2 on the rectangular table in such way that vertex *v*1 is laying in the upper-left corner and vertex *v*2 is laying in bottom-left corner.
+
+Obviously, each of these two problems has non-zero answer only if total size of subtrees is even.
+
+Let's show how to reduce a problem of the second type to a problem of the first type. So, if either *v*1 or *v*2 has two descendants, then the answer is 0. If both of them have one descendant, then we can solve the same problem for their children which'll have the same answer. If both *v*1 and *v*2 have no children, then the answer is 1. At last, if one of these two vertices has 1 descendant and the other vertice doesn't have any descendants, we have a problem of the first type for this only child of vertices *v*1 and *v*2.
+
+The only thing left is to solve a problem of the first type. Let *f*(*v*) be the number of ways to place a subtree having vertex *v* as its root on the rectangular table. The size of this table is determined uniquely by the size of subtree. Let's consider two cases:
+
+a) Vertex *v* has degree 2.
+
+b) Vertex *v* has degree 3.
+
+In the case when vertex *v* has degree 2 and there are no vertices of degree 3 in its subtree, then *f*(*v*) = *s*(*x*) / 2, where *s*(*v*) is the size of subtree with its root in vertex *v*. We've already proven this formula above. Now let's suppose that there's at least one vertex of size 3 in the subtree with root *v*. If there are several vertices with degree 3, we'll chose the one that is closer to vertex *v*. Let it be vertex *w*. We have 2 possible cases for it:
+
+a.1) Path from vertex *v* to vertex *w* will go in such way that the vertex which lays before vertex *w* in this path is located to the left from vertex *w* on the table.
+
+а.2) Path from vertex *v* to vertex *w* will go in such way that the vertex which lays before vertex *w* in this path is located to the top from vertex *w* on the table.
+
+Its easy to show that there's no third option.
+
+In each of two cases a.1) and a.2) we'll fix directions of descendants of number *w* (one direction is taken by the parent of vertex *w*, so there are exactly 2 possible directions). In case if descendant of degree greater than 1 is located in the same column with *w*, we need to fix directions of its descendants, too. After this we have problem of type 1) or 2) to the right of vertex *w*. To the left from *w* we have a tree which either can't be put on the table or can be put in exactly 1 way. In order to check this we need to look on the length of path from *v* to *w* and the size of subtree of grandson of *w*, which is located to the right from *w* (of course, if it exists). Now we need to sup up answers for all possible variants.
+
+So we know how to solve problem of type a), when vertex *v* has degree w. The only thing left is to solve problem b), when *v* has degree 3. To do this we need to fix directions of its descendants and after that we'll have either a problem of type 1) or a problem of type 2), which were formulated above.
+
+The complexity of solution is *O*(*N*).
diff --git a/editorials/252.md b/editorials/252.md
@@ -0,0 +1,105 @@
+Source: https://codeforces.com/blog/entry/6054
+
+This is a complete English version of the editorial of Codeforces Round #153. If you have any questions or suggestions, feel free to post them in the comments.
+
+### [252A - Little Xor](/contest/252/problem/A "Codeforces Round 153 (Div. 2)") (A div 2)
+
+Let's iterate over all segments in our array. For each of them we'll find the *xor* of all its elements. Then we need to output the maximal *xor* we've seen.
+
+### [252B - Unsorting Array](/contest/252/problem/B "Codeforces Round 153 (Div. 2)") (B div 2)
+
+If all elements in the array are equal then there's no pair of numbers we are looking for. Now we can assume that there exist at least 2 different numbers in the array. Let's iterate over all pairs of different numbers in the array and for each such pair we'll check if it can be the answer. If some pair indeed can be the answer, we'll output it and terminate the program. Otherwise, there is no pair of numbers we are looking for, so we need to output -1.
+
+It may seem that the complexity of described algorithm is *O*(*N*3). Actually it's not true and the real complexity is *O*(*N*). One may notice that in every array of length greater than 3 there are at least 3 pairs of different numbers (remember we assumed that there exist at least one pair of different numbers in the array). Note that these 3 pairs lead to 3 different resulting arrays. On the other hand, there are only 2 possible sorted arrays. According to the pigeonhole principle one of these 3 resulting arrays is unsorted.
+
+### [252C - Points on Line](/contest/252/problem/C "Codeforces Round 153 (Div. 2)") (C div 2)
+
+### [251A - Points on Line](/contest/251/problem/A "Codeforces Round 153 (Div. 1)") (A div 1)
+
+Let's select the rightmost point of our triplet. In order to do this we can iterate over all points in ascending order of their X-coordinate. At the same time we'll maintain a pointer to the leftmost point which lays on the distance not greater than *d* from the current rightmost point. We can easily find out the number of points in the segment between two pointers, excluding the rightmost point. Let's call this number *k*. Then there exist exactly *k* * (*k* - 1) / 2 triplets of points with the fixed rightmost point. The only thing left is to sum up these values for all rightmost points.
+
+### [252D - Playing with Permutations](/contest/252/problem/D "Codeforces Round 153 (Div. 2)") (D div 2)
+
+### [251B - Playing with Permutations](/contest/251/problem/B "Codeforces Round 153 (Div. 1)") (B div 1)
+
+First, we need to theck whether permutation *s* is the identity permutation. If it is, then the answer is "NO".
+
+Now we'll describe an algorithm which works in all cases except for one. We'll tell about this case later.
+
+Let's apply our permutation *q* until either the current permutation becomes equal to *s* or we make exactly *k* steps. If the current permutation is equal to *s* and we've made *t* steps before this happened, then we need to look at the parity of *k* - *t*. If this number is even, then we can select any two consequent permutations in the sequence and apply (*k* - *t*) / 2 times the following two permutations in this order: *q* and *inv*(*q*), where *inv*(*q*) is the inversed permutation *q*. Actually, we don't need to build the sequence itself, it's enough to check only the parity of *k* - *t*. So, if it is even, then the answer is "YES".
+
+Analogically, we can replace *q* with *inv*(*q*) and repeat described process again. If we still didn't print "YES", then the answer is "NO".
+
+The algorithm we've just described works for all cases except for one: when the permutation *q* is equal to *inv*(*q*) and at the same time *s* is reachable within one step. In this case the answer is "YES" iff *k* = 1.
+
+The complexity of described solution is *O*(*N*2).
+
+### [252E - Number Transformation](/contest/252/problem/E "Codeforces Round 153 (Div. 2)") (E div 2)
+
+### [251C - Number Transformation](/contest/251/problem/C "Codeforces Round 153 (Div. 1)") (C div 1)
+
+Let *L* be the least common multiple of all numbers from 2 to *k*, inclusive. Note that if *a* is divisible by *L*, then we can't decrease it with applying an operation of the second type. It means that any optimal sequence of transformations will contain all numbers divisible by *L* which are located between *b* and *a*. Let's split our interval from *b* to *a* into several intervals between the numbers divisible by *L*. It may happen that the first and the last intervals will have length less than *L*. Now we can solve the problem for the first interval, the last interval and for any interval between them. After that we need to multiply the last result by the total number of intervals excluding the first and the last ones. The only thing left is to add up obtained 3 values.
+
+In order to solve the problem for one interval one can simply use bfs.
+
+Be careful in the cases when we have only 1 or 2 intervals.
+
+The complexity of described solution is *O*(*L*).
+
+### [251D - Two Sets](/contest/251/problem/D "Codeforces Round 153 (Div. 1)") (D div 1)
+
+Let *X* be the *xor* of all numbers in the input. Also let *X*1 be the *xor* of all numbers in the first collection and *X*2 be the *xor* of all numbers in the second collection. Note, if the *i*-th bit in *X* is equal to 1 then the same bit in numbers *X*1 and *X*2 is either equal 0 and 1 or 1 and 0, respectively. Analogically, if the *i*-th bit in *X* is equal to 0 then this bit in numbers *X*1 and *X*2 is either equal 0 and 0 or 1 and 1, respectively. As we can see, if the *i*-th bit in *X* is equal to 1 then it doesn't affect on the sum *X*1 + *X*2 in any way. For now, let's forget about the second condition in the statement which asks us to minimize *X*1 in case of tie.
+
+In order to find the optimal value of *X*1 + *X*2 we need to make one more observation. Let's look at the most significant bit of number *X* which is equal to 0. If there exist such partitions of the initial collection in which this bit is equal to 1 in *X*1 then the optimal partition should be one of them. To prove this one should remember that the respective bit in number *X*2 is also equal to 1. Let this bit correspond to 2*L*. If the bit we are looking at is equal to 1 in both *X*1 and *X*2 then the smallest possible value of *X*1 + *X*2 is 2*L* + 1. On the other hand, if both *X*1 and *X*2 have zero in this bit, then the maximal possible value of *X*1 + *X*2 is 2*L* + 1 - 2 which is strictly smaller than 2*L* + 1.
+
+We'll be solving the initial problem with a greedy algorithm. Let's iterate over all bits which are equal to 0 in number *X* from highest to lowest. We'll try to put 1 to the number *X*1 in this position and then check if there exists at least one partition which satisfies the current condition together with all conditions we've already set up. If such partition exists, then we can leave our newly added condition and move to lower bits. If there is no such condition, then we need to move to lower bits without adding any new conditions. At the end we'll find the maximal value of *X*1 + *X*2.
+
+So, we have a set of conditions and we want to check if there exist at least one partition which satisfies all of them. For each condition for *i*-th bit we'll create an equation over the field *Z*2 with *n* variables, where the coefficient at the *j*-th variable is equal to the *i*-th bit of the *j*-th number. If some variable is equal to one then we take the corresponding number into the first set, otherwise -- into the second one. This system of equations can be solved with Gaussian elimination. Note that we don't need to solve the complete system from scratch every time we add a new equation. It's sufficient to recalculate the matrix from the previous state, which can be done in *O*(*NK*). Here *K* is the number of equations in the system.
+
+Now we need to minimize *X*1 while keeping the value of *X*1 + *X*2 unchanged. It can be done in the similar way as finding the optimal value of *X*1 + *X*2. We'll iterate over all bits which are equal to 1 in number *X* starting from the highest one. For the current bit we'll try to put 0 in the corresponding position of *X*1. If after adding this condition our system of equations becomes incompatible, then we need to put 1 in this position of *X*1.
+
+The complexity of this algorithm is *O*(*NL*2), where *L* -- is the length of binary notation of the largest number. For further optimization one can use *bitset* in Gaussian elimination, although it wasn't necessary for getting AC during the contest.
+
+### [251E - Tree and Table](/contest/251/problem/E "Codeforces Round 153 (Div. 1)") (E div 1)
+
+If *N* = 1, then the answer is 2.
+
+If there is a node with degree greater than 3 in the tree, then the answer is 0. That's because every cell of the table has at most 3 neighbors.
+
+If there is no vertex of degree 3 in the tree, then the answer is 2*n*2 - 2*n* + 4. This formula can be derieved in natural way during the solution of other parts of the problem. Also, one could write a simple DP to calculate the answer in this case. Anyway, let's prove this formula.
+
+At first, let's solve slightly different problem, which will be also used in the solution of main case of the initial problem. We want to find the number of ways to place a tree in which all nodes have degree smaller than 3 on the table so that one node of degree 1 is attached to the upper-left corner of the table (let it be node number 1). It can be shown that if the table has size 2xK, then the number of placements of the tree is equal to *K*. The last formula can be proven by mathematical induction. If *K* = 1 then the above statement is obviously true. Suppose *K* > 1 and let's assume that the table is oriented horizontally so that we have 2 rows and *K* columns. If we put a vertex adjacent to the first one to the right from upper-left corner then we have only 1 way to complete the placement of the tree. If we put this vertex to the bottom-left corner, than the next vertex should be put to (2, 2) and the problem is reduced to the same one with *K* smaller by one. We have a recurrent relation *f*(*K*) = *f*(*K* - 1) + 1 and we know that *f*(1) = 1. This means that *f*(*K*) = *K*.
+
+Let's come back to the initial problem of counting the nymber of ways to put a tree without vertices of degree 3 on the table 2xN. Without loss of generality let's assume that the first vertex has degree 1. We'll consider only placements in which the first vertex is laying in the first row and at the end we'll multiply our answer by 2. If the first vertex is laying in the first or the last column then then there are *N* ways to complete the tree (see the previous paragraph). If the first vertex is laying in the *i*-th column than there are *i* - 1 ways of placing our tree in which a vertex adjacent to the first one (let it be vertex 2) is laying to the left of it. Also there are *N* - *i* ways in which the second vertex is laying to the right of vertex 1. Adding up these values for all columns and multiplying the answer by 2 we get the final formula: 2*n*2 - 2*n* + 4.
+
+Now we have only one case left in which there exists a vertex of degree 3 in our tree. Let's declare this vertex to be a root. If there are several vertices of degree 3, any of them can be chosen to be a root. We'll assume that the root is laying in the first row and at the end we'll multiply our answer by 2. Obviously, the root should be put to a cell with 3 neighbors. Each descendant of the root should be put either to the left, to the right or to the bottom from the cell which contains the root. Let's fix this ordering (to do this we need to iterate over 6 permutations). Also if the "bottom" son of the root has degree greater than 1, then we'll also fix the ordering of its adjacent vertices (there are 2 ways to do this). Now the column which contains the root is fully occupied. The last statement means that regardless of the way we place the rest of vertices, the ones to the right from the root will stay there. The same for all vertices which lay to the left from the root. Moreover, we have the fixed number of vertices to the left from the root, which means that there's at most one way to place the root on our table. Note that if the number of vertices to the left from the root is odd, then we won't be able to complete the placement. In order to find the number of vertices to the left from the root we need to sum up sizes of subtrees of its left descendant and of the left descendant of its bottom son.
+
+So, we have two separate subproblems (for vertices laying to the left from the root and to the right from the root) and for each of them we need to calculate the number of trees to place the rest of our tree in the table. There are only two possible situations:
+
+1) We need to place a subtree with its root in vertex *v* on the rectangular table in such way that vertex *v* is laying in the corner (let it be upper-left corner).
+
+2) We need to place subtrees with roots in *v*1 and *v*2 on the rectangular table in such way that vertex *v*1 is laying in the upper-left corner and vertex *v*2 is laying in bottom-left corner.
+
+Obviously, each of these two problems has non-zero answer only if total size of subtrees is even.
+
+Let's show how to reduce a problem of the second type to a problem of the first type. So, if either *v*1 or *v*2 has two descendants, then the answer is 0. If both of them have one descendant, then we can solve the same problem for their children which'll have the same answer. If both *v*1 and *v*2 have no children, then the answer is 1. At last, if one of these two vertices has 1 descendant and the other vertice doesn't have any descendants, we have a problem of the first type for this only child of vertices *v*1 and *v*2.
+
+The only thing left is to solve a problem of the first type. Let *f*(*v*) be the number of ways to place a subtree having vertex *v* as its root on the rectangular table. The size of this table is determined uniquely by the size of subtree. Let's consider two cases:
+
+a) Vertex *v* has degree 2.
+
+b) Vertex *v* has degree 3.
+
+In the case when vertex *v* has degree 2 and there are no vertices of degree 3 in its subtree, then *f*(*v*) = *s*(*x*) / 2, where *s*(*v*) is the size of subtree with its root in vertex *v*. We've already proven this formula above. Now let's suppose that there's at least one vertex of size 3 in the subtree with root *v*. If there are several vertices with degree 3, we'll chose the one that is closer to vertex *v*. Let it be vertex *w*. We have 2 possible cases for it:
+
+a.1) Path from vertex *v* to vertex *w* will go in such way that the vertex which lays before vertex *w* in this path is located to the left from vertex *w* on the table.
+
+а.2) Path from vertex *v* to vertex *w* will go in such way that the vertex which lays before vertex *w* in this path is located to the top from vertex *w* on the table.
+
+Its easy to show that there's no third option.
+
+In each of two cases a.1) and a.2) we'll fix directions of descendants of number *w* (one direction is taken by the parent of vertex *w*, so there are exactly 2 possible directions). In case if descendant of degree greater than 1 is located in the same column with *w*, we need to fix directions of its descendants, too. After this we have problem of type 1) or 2) to the right of vertex *w*. To the left from *w* we have a tree which either can't be put on the table or can be put in exactly 1 way. In order to check this we need to look on the length of path from *v* to *w* and the size of subtree of grandson of *w*, which is located to the right from *w* (of course, if it exists). Now we need to sup up answers for all possible variants.
+
+So we know how to solve problem of type a), when vertex *v* has degree w. The only thing left is to solve problem b), when *v* has degree 3. To do this we need to fix directions of its descendants and after that we'll have either a problem of type 1) or a problem of type 2), which were formulated above.
+
+The complexity of solution is *O*(*N*).
diff --git a/editorials/253.md b/editorials/253.md
@@ -0,0 +1,27 @@
+Source: https://codeforces.com/blog/entry/6073
+
+Sorry for the short tutorial: we are too busy preparing and conducting school competition.
+
+[253A - Boys and Girls](/contest/253/problem/A "Codeforces Round 154 (Div. 2)")
+
+Lets assume that we have more boys than girls (the other case is solved similarly). Then we can construct one of the optimal solutions in the following way: we add pairs consisting of a boy and a girl (BG, in that order) to the end of the line until we don't have girls any more. Then add remaining boys to the end of the line. For instance, with 7 boys and 4 girls we will come to the solution BGBGBGBGBBB.
+
+[253B - Physics Practical](/contest/253/problem/B "Codeforces Round 154 (Div. 2)")
+
+For each *x* from 1 to 5000 calculate *count*(*x*) — the number of measurements equal to *x*. The iterate over all possible minimal values *m* (from 1 to 5000). For a fixed *m* we can easily figure out which numbers we have to erase: we should erase every number *k* that *k* < *m* or *k* > 2·*m*. To find out the number of such values in the given sequence, we should sum up values *count*(*k*) for all such *k*.
+
+[253C - Text Editor](/contest/253/problem/C "Codeforces Round 154 (Div. 2)")
+
+One of the solutions to the problem is breadth-first-search (BFS). Vertices of the graph correspond to all possible pairs (*r*, *c*), denoting the row and the position of the cursor. Each vertex has at most four arcs leaving it (these arcs correspond to pressing the buttons). So we need to find the shortest path from one vertex to the other. There are at most 107 vertices and at most 4·107 arcs. This problem can also be solved with some greedy observations.
+
+[253D - Table with Letters - 2](/contest/253/problem/D "Codeforces Round 154 (Div. 2)")
+
+Lets iterate over all pairs of rows *i*, *j* (*i* < *j*), that bounds the sub-table from the top and from the bottom. Then for each character *ch* make a list of such column numbers *k* that *T*[*i*, *k*] = *T*[*j*, *k*] = *ch*. Consider such list for some fixed character *ch*. All we need to count is the number of pairs *l*, *r* (*l* < *r*) in this list such that the sub-table with corners at (*i*, *l*) and (*j*, *r*) contains not more than *k* characters "*a*". This can be done using two standard techniques: two-pointer method and calculating partial sums.
+
+[253E - Printer](/contest/253/problem/E "Codeforces Round 154 (Div. 2)")
+
+First lets learn how to simulate the process with all priorities known. We will keep the priority queue of tasks. The task enters the queue when the printer receives this task, and leaves the queue when the printer finishes it. Then every change in the queue happens when one of the two possible events occurs: the printer receives some task or finishes printing some task. Between the consecutive events printer just prints pages from the tasks with the highest priority. So, if we maintain a set of events, the simulation can be done in *O*(*NlogN*).
+
+To solve the problem, make an obvious observation: the higher priority the task has, the sooner the printer finishes it. Then the required missing priority can be found using binary search. Also we can search the missing priority among *O*(*N*) values. The overall complexity is *O*(*Nlog*2(*N*)).
+
+This problem also has *O*(*NlogN*) solution, which will be described later.
diff --git a/editorials/254.md b/editorials/254.md
@@ -0,0 +1,21 @@
+Source: https://codeforces.com/blog/entry/6085
+
+[254A - Cards with Numbers](/contest/254/problem/A "Codeforces Round 155 (Div. 2)")
+
+For each *x* from 1 to 5000 store a list *L*(*x*) of such indexes *i* that *a**i* = *x*. Then just check that all lists have even size and output the elements of each list in pairs.
+
+[254B - Jury Size](/contest/254/problem/B "Codeforces Round 155 (Div. 2)")
+
+One of the possible solutions is: for each Olympiad find the period of the preparation. This can be done by iterating the days back from the day of the Olympiad. For each day *d* of the preparation add *p**i* to the number of distinct jury members that have to work on problems on day *d*. Then the answer is maximum calculated sum over all days. Be careful with the year 2012.
+
+[254C - Anagram](/contest/254/problem/C "Codeforces Round 155 (Div. 2)")
+
+Lets denote the number of character *x* in *s* by *C**s*(*x*). Similarly *C**t*(*x*) is defined. Then the minimum number of changes required to get anagram of *t* from *s* is equal to 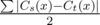. Now we need to obtain lexicographically minimum solution. Lets iterate through the positions in *s* from the left to the right. For a fixed position, look through all characters from 'a' to 'z' and for each character decide whether the optimal answer can contain this character in that position. If it can, put this character in that position and continue with the next position. To check if the given character is suitable quickly, we maintain the values *C**s*(*x*) and *C**t*(*x*) while iterating through positions.
+
+[254D - Rats](/contest/254/problem/D "Codeforces Round 155 (Div. 2)")
+
+Choose arbitrary rat (for say, the leftmost of the upmost). It's cell should be cleared. Make a BFS that never goes further than *d* from this cell (we will call such a BFS by d-BFS). It will visit approximately 2*d*2 cells in the worst case. So, we have to blow the first grenade in one of the visited cells. Lets check every visited cell as a candidate. Make a d-BFS from the candidate cell. Some cells with the rats will not be visited. That means that they should be cleared by the second grenade. Choose arbitrary cell with a rat that was not cleared by the first grenade. Make a d-BFS from it. All cells visited by this BFS are candidates to blow the second grenade. Lets check every such cell. Checking a cell again means making a d-BFS from it. If this BFS visits all cells that were not cleared by the first grenade, that we have found a solution. As every d-BFS visits at most 2*d*2, the overall number of steps is approximately 8*d*6.
+
+[254E - Dormitory](/contest/254/problem/E "Codeforces Round 155 (Div. 2)")
+
+The problem can be solved by dynamic programming: denote as *D*(*n*, *r*) the maximum rating that we can achieve in the first *n* days with the condition that we have *r* kilos of food remaining from the day *n* - 1. It is obvious that if we decide to feed *k* friends on some day, the better way is to feed *k* friends with the lowest *f**j* (of course we consider only friends that live with Vasya on that day). So we need to sort all available students in the order of increasing *f**j* and try to feed 0, 1, 2, \ldots first students in this order. We have 4002 states and 400 transitions from each state.
diff --git a/editorials/255.md b/editorials/255.md
@@ -0,0 +1,40 @@
+Source: https://codeforces.com/blog/entry/6161
+
+### [255A - Greg's Workout](/contest/255/problem/A "Codeforces Round 156 (Div. 2)")
+
+It is not hard problem. We must calculate sums of numbers for each group and print group with maximum count.
+
+### [255B - Code Parsing](/contest/255/problem/B "Codeforces Round 156 (Div. 2)")
+
+Not hard to see that after few operations of first type string will become: x..xy..y. After fer operations of second type, there will be only letters of one type, count of this letters will be: |count(x) — count(y)|
+
+### [256A - Almost Arithmetical Progression](/contest/256/problem/A "Codeforces Round 156 (Div. 1)")
+
+Заметим, что ответ это длина последовательности: a, b, a, b, ... где a и b — некоторые целые числа. Зафиксируем одно число (допустим a), будем перебирать число b, и считать какой мы получим ответ, если это будет последнее число в последовательности. Заметим, что для фиксированных a, b — ответ считается жадно. Так же будем действовать и тут. Будем искать последнее вхождение числа b до зафиксированного, что между ними есть число a, и будем брать ответ как длина до найденного числа +2 (икасть будем с помощью метода двух указателей). Так же нужно рассмотреть случай, когда это будет 1е или 2е вхождение в последовательность.
+Так же существует решение с помощью динамического программирования.
+Асимптотика обоих решений O(n^2).
+Буду очень рад, если кто то напишет решение с лучшей асимптотикой.
+
+### [256B - Mr. Bender and Square](/contest/256/problem/B "Codeforces Round 156 (Div. 1)")
+
+Solution — binary search for answer. Next we have to calculate the area of a truncated square set at 45 degrees. This can be done as follows: Calculate its total area. Subtract area that cuts off the top line. Similarly, for the lower, left and right line. Add parts that are cutted by corners. You can write a function that finds the length of the truncation desired area, for that would not write a lot of code.
+
+### [256C - Furlo and Rublo and Game](/contest/256/problem/C "Codeforces Round 156 (Div. 1)")
+
+Note that after the first move any pile turns into a pile no larger than 1000000. We assume Grundy function for numbers less than 1 million. Grundy function is very small, you can start on the partial sums for each type of function that would quickly tell what function is in the interval, and which are not present. Knowing the answer is not difficult to find small response for all piles.
+
+### [256D - Liars and Serge](/contest/256/problem/D "Codeforces Round 156 (Div. 1)")
+
+If person say number x, and at all x was said by x persons, then we cannot tell anything about fixed person.
+
+Now we understand which sequence are good for us. We will calculate their count wuth dynamic programming dp[n][m][k], n — which persons answers we set to the sequence right now, m — how mant persons gived theis answers, k — how many persons from them are liers.
+Transfer:
+dp[n][m][k]*cnk[N-m][n] -> dp[n+1][m+n][k]
+dp[n][m][k]*cnk[N-m][p] -> dp[n+1][m+p][k+p] p = 1 .. N, p != n.
+We assume, that N — total number of the persons. This solution get TLE, becouse complexity if O(N^4). We need to use precalc. It will not be so big, as N is power of 2.
+
+### [256E - Lucky Arrays](/contest/256/problem/E "Codeforces Round 156 (Div. 1)")
+
+Solution is — interval tree. We will save dynamic programming f[i,j] in each vertex, this dp means: in how many ways we can change all 0 to some numbers on interval, such that it will be valid and first element will be i and last will be j.
+
+With normal implementation its easy to pass system tests.
diff --git a/editorials/256.md b/editorials/256.md
@@ -0,0 +1,40 @@
+Source: https://codeforces.com/blog/entry/6161
+
+### [255A - Greg's Workout](/contest/255/problem/A "Codeforces Round 156 (Div. 2)")
+
+It is not hard problem. We must calculate sums of numbers for each group and print group with maximum count.
+
+### [255B - Code Parsing](/contest/255/problem/B "Codeforces Round 156 (Div. 2)")
+
+Not hard to see that after few operations of first type string will become: x..xy..y. After fer operations of second type, there will be only letters of one type, count of this letters will be: |count(x) — count(y)|
+
+### [256A - Almost Arithmetical Progression](/contest/256/problem/A "Codeforces Round 156 (Div. 1)")
+
+Заметим, что ответ это длина последовательности: a, b, a, b, ... где a и b — некоторые целые числа. Зафиксируем одно число (допустим a), будем перебирать число b, и считать какой мы получим ответ, если это будет последнее число в последовательности. Заметим, что для фиксированных a, b — ответ считается жадно. Так же будем действовать и тут. Будем искать последнее вхождение числа b до зафиксированного, что между ними есть число a, и будем брать ответ как длина до найденного числа +2 (икасть будем с помощью метода двух указателей). Так же нужно рассмотреть случай, когда это будет 1е или 2е вхождение в последовательность.
+Так же существует решение с помощью динамического программирования.
+Асимптотика обоих решений O(n^2).
+Буду очень рад, если кто то напишет решение с лучшей асимптотикой.
+
+### [256B - Mr. Bender and Square](/contest/256/problem/B "Codeforces Round 156 (Div. 1)")
+
+Solution — binary search for answer. Next we have to calculate the area of a truncated square set at 45 degrees. This can be done as follows: Calculate its total area. Subtract area that cuts off the top line. Similarly, for the lower, left and right line. Add parts that are cutted by corners. You can write a function that finds the length of the truncation desired area, for that would not write a lot of code.
+
+### [256C - Furlo and Rublo and Game](/contest/256/problem/C "Codeforces Round 156 (Div. 1)")
+
+Note that after the first move any pile turns into a pile no larger than 1000000. We assume Grundy function for numbers less than 1 million. Grundy function is very small, you can start on the partial sums for each type of function that would quickly tell what function is in the interval, and which are not present. Knowing the answer is not difficult to find small response for all piles.
+
+### [256D - Liars and Serge](/contest/256/problem/D "Codeforces Round 156 (Div. 1)")
+
+If person say number x, and at all x was said by x persons, then we cannot tell anything about fixed person.
+
+Now we understand which sequence are good for us. We will calculate their count wuth dynamic programming dp[n][m][k], n — which persons answers we set to the sequence right now, m — how mant persons gived theis answers, k — how many persons from them are liers.
+Transfer:
+dp[n][m][k]*cnk[N-m][n] -> dp[n+1][m+n][k]
+dp[n][m][k]*cnk[N-m][p] -> dp[n+1][m+p][k+p] p = 1 .. N, p != n.
+We assume, that N — total number of the persons. This solution get TLE, becouse complexity if O(N^4). We need to use precalc. It will not be so big, as N is power of 2.
+
+### [256E - Lucky Arrays](/contest/256/problem/E "Codeforces Round 156 (Div. 1)")
+
+Solution is — interval tree. We will save dynamic programming f[i,j] in each vertex, this dp means: in how many ways we can change all 0 to some numbers on interval, such that it will be valid and first element will be i and last will be j.
+
+With normal implementation its easy to pass system tests.
diff --git a/editorials/257.md b/editorials/257.md
@@ -0,0 +1,48 @@
+Source: https://codeforces.com/blog/entry/6357
+
+## [257A - Sockets](/contest/257/problem/A "Codeforces Round 159 (Div. 2)")
+
+Очевидно, что выгоднее использовать сетевые фильтры с наибольшим количеством розеток на них. Поэтому сначала отсортируем их по убыванию этой величины. Теперь переберем ответ, то есть, сколько фильтров мы будем использовать, пусть это значение равно *p*, а фильтры имеют *a*1, *a*2, ..., *a**p* розеток. Очевидно, что если соединить эти фильтры, то итого будет доступно *k* - *p* + *a*1 + *a*2 + ... + *a**p* розеток. Это значение надо сравнить с *m* и выбрать минимальное подходящее *p*. Если ни одно значение *p* не подходит, то следует вывести - 1.
+
+## [257B - Playing Cubes](/contest/257/problem/B "Codeforces Round 159 (Div. 2)")
+
+Для начала переберем цвет первого кубика, который поставит Петя. Вася следующим ходом захочет поставить кубик противоположного цвета, затем Петя захочет поставить кубик такого же цвета, как и поставленный Васей и т.д. Так мы можем проэмулировать всю последовательность ходов обоих мальчиков и найти их счет.
+
+Единственное, что может изменить Петя в игре – это цвет первого кубика, и он его поставит так, чтобы его счет был как можно больше.
+
+## [257C - View Angle](/contest/257/problem/C "Codeforces Round 159 (Div. 2)")
+
+Сначала давайте избавимся от координат точек, а именно, заменим все точки лучами от (0, 0) до каждой из точек.
+
+Тогда очевидно, что искомые стороны угла – это пара соседних лучей, причем из двух углов, образованных выбранными лучами, надо выбрать тот, который покрывает все остальные лучи. Получается, что выгоднее всего выбрать такую пару соседних лучей, между которыми наибольший угол, пусть он равен *a*, и вывести величину 360 - *a* (в градусах).
+
+Отдельный случай — когда все точки лежат на одном луче, в этом случае ответ равен 0.
+
+## [257D - Sum](/contest/257/problem/D "Codeforces Round 159 (Div. 2)")
+
+У нас есть последовательность переменных *a*1, *a*2, …, *a**n*. Возьмем две переменные с максимальными значениеми (допустим, *i* и *i* + 1), удалим их и вставим в последовательность новую переменную *x* = *a**i* + 1 - *a**i* так, чтобы сохранилось свойство неубывания последовательности. Так будем делать до тех пор, пока не останется единственное число *s*, которое и будет искомой суммой. Очевидно, что если мы будем разворачивать последовательность замен с учетом знаков, то в итоге узнаем, какой знак стоит у каждой из начальных переменных так, чтобы их сумма была равна *s*.
+
+Теперь осталось понять, почему число *s* подходит под ограничения 0 ≤ *s* ≤ *a*1. Очевидно, что оно не может быть отрицательным, так как при всех заменах мы из большего числа вычитаем меньшее. Также несложно понять, что при всех заменах минимальное число в последовательности не может увеличиваться, значит, оно до последней замены будет максимум *a*1. Аналогично, второе число в последовательности также не может перед последним шагом быть больше *a*2 и так далее. Несложно понять, что при последней замене мы получим *s* ≤ *a*2 - *a*1 ≤ *a*1.
+
+## [257E - Greedy Elevator](/contest/257/problem/E "Codeforces Round 159 (Div. 2)")
+
+Эта задача решается классическим методом – событиями во времени. Событиями являются: «человек встал в очередь к лифту», «человек вошел в лифт», «человек вышел из лифта».
+
+Будем поддерживать множество будущих событий, текущее время *T* и текущее положение лифта *x*.
+
+В каждый момент времени будем выполнять следующие действия:
+
+1. если есть люди, которые в текущее время *T* пришли к лифту, то поставим их в очередь на их стартовом этаже;
+2. если на текущем этаже есть люди, то посадим их в лифт, таким образом очередь на этом этаже опустеет;
+3. если в лифте есть люди, которые должны выйти на текущем этаже, то высадим их и запомним для них ответ – текущее время *T*;
+4. найдем количество людей, которые ждут выше этажа *x* или которые едут выше, а также найдем количество людей, которые ждут ниже этажа *x* или едут ниже, и согласно условию выберем направление движения.
+
+Однако если мы на каждой итерации будем увеличивать текущее время *T* лишь на единицу, то решение будет работать слишком долго. Надо научиться переходить сразу к следующему моменту времени, когда появится какое-либо новое событие, и лифт передвигать сразу на несколько этажей вверх или вниз. Очевидно, что между событиями направление движения лифта не меняется.
+
+Понятно, что нам достаточно посмотреть на следующий момент времени, когда придет какой-либо человек и встанет в очередь на этаже, а кроме того найти следующий этаж по направлению движения, на котором кто-либо выйдет или зайдет.
+
+Это можно сделать с помощью структуры «множество» с операциями «найти следующее число в множестве после данного» и «найти предыдущее число в множестве перед данным». Это умеет стандартные структуры set в С++ или TreeSet в Java.
+
+Также для действия номер 4 нам понадобятся две структуры данных, которые умеют находить сумму чисел на определенном отрезке в массиве, для этого можно использовать, например, деревья отрезков или деревья Фенвика. Одна из структур хранит, сколько людей ждут лифта на каждом из этажей, а вторая – сколько людей в лифте хочет выйти на каждом из этажей. В принципе, эти две структуры можно объединить в одну.
+
+Таким образом, для каждого из людей мы будем обрабатывать ровно по три события, и итоговое время решения будет равно *O*(*n*·*log*(*n*)).
diff --git a/editorials/258.md b/editorials/258.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/6213
+
+### [259A - Little Elephant and Chess](/contest/259/problem/A "Codeforces Round 157 (Div. 2)")
+
+Obviously, the only correct rows are rows WBWBWBWB and BWBWBWBW. Only thing you need to do is to check whether each string is one of these. If yes then print YES, else print NO.
+
+### [259B - Little Elephant and Magic Square](/contest/259/problem/B "Codeforces Round 157 (Div. 2)")
+
+Since each number is less than or equal to 105, you can loop all possible *a*1, 1 values, the rest of cells can be calculated from this.
+
+### [258A - Little Elephant and Bits](/contest/258/problem/A "Codeforces Round 157 (Div. 1)")
+
+It's pretty easy to notice that you need to delete the first (from the left) 0-digit. The only catchy case is 111...111 — here you need to delete any of 1-digits.
+
+### [258B - Little Elephant and Elections](/contest/258/problem/B "Codeforces Round 157 (Div. 1)")
+
+First of all, lets think about the problem of finding array *c**i* — the number of integers from 1 to *m* such, that the number of lucky digits is equal to *i*. It's pretty standart dynamic programminc problem, which can be solved with state [position][less][count].
+
+It can be solved directly using DP, but to simplify a bit you can use brute force (recursion) to brute all possible assignments of numbers of lucky digits in for all paries (up to 9 digits). Now you can divide all parties in several indepentent groups, each of which should contain the same number of lucky digits. Consider that the party of Litte Elephant is with number 1. Than assignment for the first position should have more digits than the sum of the rest (because of the statement). Since all groups are indepented (because there is no number that can have different number of lucky digits, obviously) you can find the number of resulting assignments for each group and find the final result by multiplying these all numbers and taking modulo 109 + 7.
+
+Consider that you have group of size *t*, each number of which should contain *l* lucky digits. That it's pretty easy to understand that the number of assignment is equal to (*c**l*) * (*c**l* - 1) * (*c**l* - 2) * ... * (*c**l* - *t* + 1).
+
+### [258C - Little Elephant and LCM](/contest/258/problem/C "Codeforces Round 157 (Div. 1)")
+
+The complexity of the possible solution is *O*(*n* * *sqrt*(*n*) * *log*(*n*)). You can see that statement *lcm*(*b*1, *b*2, ..., *b**n*) = *max*(*b*1, *b*2, ..., *b**n*) is equal to statement "All the numbers *b*1, *b*2, ..., *b**n* must divide *max*(*b*1, *b*2, ..., *b**n*)". You can iterate that *max*(*b*1, *b*2, ..., *b**n*), let it be equal to *m*. Find all divisors of *m* and sort them — *p*1, *p*2, ..., *p**k*. For each *i* between 1 and *k* you can find (using simple DP) the number of numbers *a**j* that *p**i* ≤ *a**j* < *p**i* + 1 (if *i* = *k* than *p**i* + 1 = *max*(*a*1, *a*2, ..., *a**n*) + 1), denote it as *q**i*. Then the reuslt is equal to 1*q*1 * 2*q*2 * 3*q*3 * ... * *p**q**p*, because for each of the *q*1 numbers there is 1 way to assign, for each of *q*2 numbers there is 2 ways of assignments, and so on. But you should notice that if doing this problem in such way, you need to garantee that there is some *i* such *b**i* = *m*. Hance you need from the last multiplier (*p**q**p*) subtract (*p* - 1)*q**p* — all the ways that there is no number equal to *m*.
+
+### [258D - Little Elephant and Broken Sorting](/contest/258/problem/D "Codeforces Round 157 (Div. 1)")
+
+### [258E - Little Elephant and Tree](/contest/258/problem/E "Codeforces Round 157 (Div. 1)")
+
+Very useful thing in this problem is ordering all vertices in DFS order (preorped). After that any subtree can be represented as a some sequence of continuous vertices. Consider that we have some fixed vertex *v*. Which vertices should be included in *c**v*? Obviously, if in the path from the root to *v* is some non-empty vertex (i. e. such that has at least one integer in its list) than each vertex from substree *v* should be included in *c**i*, but since we now working with preorder traversal of the tree, we consider that every vertex from some segment [*l**v*, *r**v*] must be included to *c**i*. More generally, let for each vertex keep some set of segments (*l**k*;*r**k*). If on the *i*-th operation we have two vertices *a* and *b*, we add segment (*l**b*;*r**b*) to vertex *a*, and (*l**a*;*r**a*) to vertex *b*. Also for each vertex *i* (*i* = 1..*n*) we add segment (*l**i*;*r**i*), where (*l**i*;*r**i*) is a segment in our preored traversal for subtree *i*. After that, you can see that, if we unite all segments from all vertices on the path from the root to some vertex *v*, we find the result for *v*, which will be the size of the resulting set.
+
+So now we need some data structure that would support three operations: add(l, r), subtract(l, r), count(). The first one should add 1 to all positions from *l* to *r*, inclusive. The second should subtract 1 from all positions from *l* to *r*, inclusive. The last should count the number of non-zero element. This all can be done either with segment tree or sqrt-decomposition.
diff --git a/editorials/259.md b/editorials/259.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/6213
+
+### [259A - Little Elephant and Chess](/contest/259/problem/A "Codeforces Round 157 (Div. 2)")
+
+Obviously, the only correct rows are rows WBWBWBWB and BWBWBWBW. Only thing you need to do is to check whether each string is one of these. If yes then print YES, else print NO.
+
+### [259B - Little Elephant and Magic Square](/contest/259/problem/B "Codeforces Round 157 (Div. 2)")
+
+Since each number is less than or equal to 105, you can loop all possible *a*1, 1 values, the rest of cells can be calculated from this.
+
+### [258A - Little Elephant and Bits](/contest/258/problem/A "Codeforces Round 157 (Div. 1)")
+
+It's pretty easy to notice that you need to delete the first (from the left) 0-digit. The only catchy case is 111...111 — here you need to delete any of 1-digits.
+
+### [258B - Little Elephant and Elections](/contest/258/problem/B "Codeforces Round 157 (Div. 1)")
+
+First of all, lets think about the problem of finding array *c**i* — the number of integers from 1 to *m* such, that the number of lucky digits is equal to *i*. It's pretty standart dynamic programminc problem, which can be solved with state [position][less][count].
+
+It can be solved directly using DP, but to simplify a bit you can use brute force (recursion) to brute all possible assignments of numbers of lucky digits in for all paries (up to 9 digits). Now you can divide all parties in several indepentent groups, each of which should contain the same number of lucky digits. Consider that the party of Litte Elephant is with number 1. Than assignment for the first position should have more digits than the sum of the rest (because of the statement). Since all groups are indepented (because there is no number that can have different number of lucky digits, obviously) you can find the number of resulting assignments for each group and find the final result by multiplying these all numbers and taking modulo 109 + 7.
+
+Consider that you have group of size *t*, each number of which should contain *l* lucky digits. That it's pretty easy to understand that the number of assignment is equal to (*c**l*) * (*c**l* - 1) * (*c**l* - 2) * ... * (*c**l* - *t* + 1).
+
+### [258C - Little Elephant and LCM](/contest/258/problem/C "Codeforces Round 157 (Div. 1)")
+
+The complexity of the possible solution is *O*(*n* * *sqrt*(*n*) * *log*(*n*)). You can see that statement *lcm*(*b*1, *b*2, ..., *b**n*) = *max*(*b*1, *b*2, ..., *b**n*) is equal to statement "All the numbers *b*1, *b*2, ..., *b**n* must divide *max*(*b*1, *b*2, ..., *b**n*)". You can iterate that *max*(*b*1, *b*2, ..., *b**n*), let it be equal to *m*. Find all divisors of *m* and sort them — *p*1, *p*2, ..., *p**k*. For each *i* between 1 and *k* you can find (using simple DP) the number of numbers *a**j* that *p**i* ≤ *a**j* < *p**i* + 1 (if *i* = *k* than *p**i* + 1 = *max*(*a*1, *a*2, ..., *a**n*) + 1), denote it as *q**i*. Then the reuslt is equal to 1*q*1 * 2*q*2 * 3*q*3 * ... * *p**q**p*, because for each of the *q*1 numbers there is 1 way to assign, for each of *q*2 numbers there is 2 ways of assignments, and so on. But you should notice that if doing this problem in such way, you need to garantee that there is some *i* such *b**i* = *m*. Hance you need from the last multiplier (*p**q**p*) subtract (*p* - 1)*q**p* — all the ways that there is no number equal to *m*.
+
+### [258D - Little Elephant and Broken Sorting](/contest/258/problem/D "Codeforces Round 157 (Div. 1)")
+
+### [258E - Little Elephant and Tree](/contest/258/problem/E "Codeforces Round 157 (Div. 1)")
+
+Very useful thing in this problem is ordering all vertices in DFS order (preorped). After that any subtree can be represented as a some sequence of continuous vertices. Consider that we have some fixed vertex *v*. Which vertices should be included in *c**v*? Obviously, if in the path from the root to *v* is some non-empty vertex (i. e. such that has at least one integer in its list) than each vertex from substree *v* should be included in *c**i*, but since we now working with preorder traversal of the tree, we consider that every vertex from some segment [*l**v*, *r**v*] must be included to *c**i*. More generally, let for each vertex keep some set of segments (*l**k*;*r**k*). If on the *i*-th operation we have two vertices *a* and *b*, we add segment (*l**b*;*r**b*) to vertex *a*, and (*l**a*;*r**a*) to vertex *b*. Also for each vertex *i* (*i* = 1..*n*) we add segment (*l**i*;*r**i*), where (*l**i*;*r**i*) is a segment in our preored traversal for subtree *i*. After that, you can see that, if we unite all segments from all vertices on the path from the root to some vertex *v*, we find the result for *v*, which will be the size of the resulting set.
+
+So now we need some data structure that would support three operations: add(l, r), subtract(l, r), count(). The first one should add 1 to all positions from *l* to *r*, inclusive. The second should subtract 1 from all positions from *l* to *r*, inclusive. The last should count the number of non-zero element. This all can be done either with segment tree or sqrt-decomposition.
diff --git a/editorials/26.md b/editorials/26.md
@@ -0,0 +1,40 @@
+Source: https://codeforces.com/blog/entry/610
+
+### A. [Almost Prime](../../../contest/26/problem/A)
+
+This is a straightforward implementation problem: factor every number from 1 to n into product of primes and count the number of distinct prime divisors.
+
+
+### B. [Regular Bracket Sequence](../../../contest/26/problem/B)
+
+Read the string from left to right and calculate the balance of brackets at each step (i.e., the difference between the number of "(" and ")" characters written out). We need to keep this balance non-negative. Hence, every time when the balance equals 0 and we read the ")" character, we must omit it and not write it out. The answer to the problem is twice the number of ")" characters that we wrote out.
+
+
+### C. [Parquet](../../../contest/26/problem/C)
+
+We'll derive several necessary conditions for the parquet to be possible. If some of them is not fulfilled, the answer is "IMPOSSIBLE".
+**1.** m*n must be even, because it equals the total area of the parquet, and the area of each plank is even.
+**2.** Suppose m (the number of columns) is odd. Paint the living room in two colors — black and white — in the following way: the first column is black, the second one is white, the third one is black, ..., the last one is black. The number of black squares is *n* greater than the number of white squares. The planks 1x2 and 2x2 contain an equal number of black and white squares, so we must compensate the difference with 2x1 planks, and their number must be at least n/2. In this case we can parquet the last column with these planks, decrease *b* by n/2 and decrease *m* by one.
+**3.** If *n* is odd, then by similar reasoning *a* ≥ *m* / 2.
+**4.** Now *m* and *n* are even. A similar reasoning shows that the number of 1x2 planks used must be even, and the number of 2x1 planks used must be even. So, if *a* is odd, we decrease it by 1, and the same with *b*.
+**5.** Now we must have *mn* ≤ 2*a* + 2*b* + 4*c*, because otherwise the total area of planks would not be enough.
+**6.** If all the conditions were fulfilled, we can finish the parquet: divide it into 2x2 squares, and use one 2x2 plank, two 1x2 planks, or two 2x1 planks to cover each square.
+
+
+### D. [Tickets](../../../contest/26/problem/D)
+
+If we picture the graph of the number of 10-euro banknotes, it will be a broken line, starting at the point (0, k) and ending at the point (m+n, n+k-m). Exactly *m* segments on the line are 'going down', and other *n* segments are 'going up'. Hence the total number of possible graphs is *C*(*m* + *n*, *m*) (the binomial coefficient). We need to find out the number of graphs which don't go under the X axis. To do that, we'll calculate the complementary number: the number of graphs which go under the X axis, or, equivalently, intersect the line y=-1.
+
+Here we'll use the so-called 'reflection principle'. Consider any graph that intersects the line y=-1, and take the last point of intersection. Reflect the part of the graph from this point to the end with respect to the line y=-1. We'll have a new graph, ending at the point (*m* + *n*, - 2 - *n* - *k* + *m*). Conversely, any graph ending at this point will intersect the line y=-1, and we can apply the same operation to it. Hence, the number of graphs we're interested in equals the number of graphs starting at the point (0, *k*) and ending at the point (*m* + *n*, - 2 - *n* - *k* + *m*). Let *a* and *b* be the number of segments in such a graph which go up and down, respectively. Then *a* + *b* = *m* + *n*, *a* - *b* + *k* = - 2 - *n* - *k* + *m*. It follows that *a* = *m* - *k* - 1, and there are *C*(*m* + *n*, *m* - *k* - 1) such graphs.
+
+So, the probability that the graph will go down the X axis is *C*(*m* + *n*, *m* - *k* - 1) / *C*(*m* + *n*, *m*) = (*m*!*n*!) / ((*n* + *k* + 1)!(*m* - *k* - 1)!) = (*m*(*m* - 1)... (*m* - *k*)) / ((*n* + 1)(*n* + 2)... (*n* + *k* + 1)). The answer to the problem is 1 - (*m*(*m* - 1)... (*m* - *k*)) / ((*n* + 1)(*n* + 2)... (*n* + *k* + 1)).
+
+
+### E. [Multithreading](../../../contest/26/problem/E)
+
+It's clear that we must have 1 ≤ *w* ≤ *Σ**i* *n**i*. If this condition is true, we show how to achieve the desired result in the following cases:
+**1.** *N* = 1, *w* = *n*1. Obvious.
+**2.** *N* ≥ 2, *w* ≥ 2. For *w* = 2, the schedule is the following: 1, all loops of processes 3..N, *n*2 - 1 loops of the second process, 1, 2, *n*1 - 1 loops of the first process, 2. For *w* > 2, we just need to move several loops from the middle of the sequence to the end.
+**3.** *N* ≥ 2, *w* = 1, and there exists an index *i* such that *n**i* = 1. Then the schedule is the following: *i*, all loops of other processes, *i*.
+
+Now we'll show that in any other case the result *w* is impossible. The case *N* = 1, *w* ≠ *n*1 is obvious. We have one more case left: *N* ≥ 2, *w* = 1, and *n**i* > 1 for each *i*. Suppose that there exists a schedule which results in *y* = 1. Consider the last writing operation in this schedule; suppose it is executed by the process *i*. Then the corresponding reading operation should have read the value y=0. This means that there were no writing operations before. But this is impossible, since *n**i* > 1, and this process executed *n**i* - 1 read/write loops.
diff --git a/editorials/260.md b/editorials/260.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/6263
+
+[260A - Adding Digits](/contest/260/problem/A "Codeforces Round 158 (Div. 2)")
+
+At first try to add to the right one digit from 0 to 9. If it is impossible write -1. In other case, the remaining *n*–1 digits can be 0 because divisibility doesn’t change.
+
+[260B - Ancient Prophesy](/contest/260/problem/B "Codeforces Round 158 (Div. 2)")
+
+In this problem you have to consider every date from 2013 to 2015 year (there is no leap years in this interval), count occurrences of this date and find maximum. In one year there is 365 days, so the complexity of the solution (3·365·*N*).
+
+[260C - Balls and Boxes](/contest/260/problem/C "Codeforces Round 158 (Div. 2)")
+
+Firstly describe simple solution. We will get by one ball from boxes (we begin from box *x*) from right to left (action back). At some moment there will be 0 balls in current box. This box is the first box in our initial problem (from which we took all balls and begun to put). In this box we put all balls, which we get from all boxes.
+
+But we can’t solve the problem in such a way, because it is too long. Note, that before we meet the situation when in some box will be 0 balls, we will go through every element of array several times and subtract 1. So we can make our solution faster. We can subtract from every element of array *minv* - 1, where *minv* — minimum in array. After that you should do *O*(*N*) operations, that were mentioned above.
+
+[260D - Black and White Tree](/contest/260/problem/D "Codeforces Round 158 (Div. 2)")
+
+The problem can be solved constructively maintaining the following invariant (rule) — the sum of the white vertices equals to the sum of the black vertices. The tree is a bipartite graph, so we build bipartite graph with no cycles, which will satisfy the conditions of the problem. Parts of graph will be black and white vertices.
+
+On each step we will choose vertex *v* with minimum sum from white and black vertices. Then find any vertex of opposite color *u* and add edge (*u*, *v*) with weight *s*[*v*], and subtract from sum of *u* sum of *v*, that is *s*[*u*] = *s*[*u*]–*s*[*v*]. After each step one vertex is deleted. That’s why there will be no cycles in constructed graph. When we delete last vertex of one of colors, all other vertices can be joined in any correct way with edges of weight 0.
+
+[260E - Dividing Kingdom](/contest/260/problem/E "Codeforces Round 158 (Div. 2)")
+
+Consider 9! variants of location of integers *a*[*i*] on 9 areas. When we consider some location (some grid), we can easily find amount of cities to the left of the left vertical line, to the right of the right vertical line, below the lower horizontal line and above the upper horizontal line. All these numbers is sum of three values *a*[*i*].
+
+We assume that the lines of the answer are always in half-integer coordinates. Then, knowing the above 4 numbers, we can uniquely determine separately for *x* and *y* how to accommodate all the 4 lines. It remains only to check that in all areas there is desired number of points.
+
+For each of four zones (to the left of the left vertical line, to the right of the right vertical line, below the lower horizontal line and above the upper horizontal line) separately check, that all three areas have correct number of cities. It can be done offline using scan-line and segment-tree, which can find sum on interval and change value in some point. You should put all queries in some array, sort them and process from left to right. Note, when you check 8 from 9 areas for every 9! variants of location, the last area (central) could not be checked, it will be correct automatically.
diff --git a/editorials/261.md b/editorials/261.md
@@ -0,0 +1,32 @@
+Source: https://codeforces.com/blog/entry/6398
+
+[262A - Roma and Lucky Numbers](/contest/262/problem/A "Codeforces Round 160 (Div. 2)")
+
+This problem just need to simulate everithing that was given in statment.
+
+[262B - Roma and Changing Signs](/contest/262/problem/B "Codeforces Round 160 (Div. 2)")
+
+We will "reverse" numbers from the begining to the end while numebrers are negative and we did't spend all k operations.
+In the end there can leave some operetions, and we will "reverse" only one numeber, with minimal value k(that remains) times.
+
+[261A - Maxim and Discounts](/contest/261/problem/A "Codeforces Round 160 (Div. 1)")
+
+Ofcourse the most optimal way is to use discount with minimal q_i. We will sort our numbers and will go from the end to begin of the array. We will by use our discount as soon as it will be possible. It's not hard to see that we will buy all the items with numbers I (zero-numeration from the end of the sorted array) such, that I%(q+2)<q.
+
+[261B - Maxim and Restaurant](/contest/261/problem/B "Codeforces Round 160 (Div. 1)")
+If all people can come, we will return answer as n.
+If it is impossible, there will be finded some person that will be the last to come. We will brtueforce this value. Then we will detrminate dp[i,j,s] in how many ways j persons from the first i with total length s can be in the resturant. It is easy to calculate.
+Then we will add to the answer values dp[n][i][s]*i!*(n-1-i)! for all i,s such that s+p[h]>P. Where P — total length of the table, p[h] — length of the fixed person.
+
+[261C - Maxim and Matrix](/contest/261/problem/C "Codeforces Round 160 (Div. 1)")
+For fixed m, the sum in the last row will be 2^(bit_count(m+1)-1). So now if T is not power of 2, answer is 0. Else we can find number of bits that we need. And know we have stndart problem. How many numbers form 2 to n+1 have exactly P bits in binary presentation of the number. It is well known problem can be done using binomial cooficients. We will count number of numebers smaller then out number with fixed prefix.
+
+[261D - Maxim and Increasing Subsequence](/contest/261/problem/D "Codeforces Round 160 (Div. 1)")
+
+This problem can be done using dp[i,j] where we can end our increasing sequence with length i and last number j. Its not hard to understand that number of states will be n*b. To make a tranfer we need to know array first[j] — first position of the number j in the sequence b, next[i][j] — first position of the number j in the sequence b after position i.
+
+Now its easy to calculate all values.
+
+[261E - Maxim and Calculator](/contest/261/problem/E "Codeforces Round 160 (Div. 1)")
+
+I will add tutorial later. But I will give you a hint: number of numbers with maximal prime divisor<=100 is near 3000000 numbers.
diff --git a/editorials/262.md b/editorials/262.md
@@ -0,0 +1,32 @@
+Source: https://codeforces.com/blog/entry/6398
+
+[262A - Roma and Lucky Numbers](/contest/262/problem/A "Codeforces Round 160 (Div. 2)")
+
+This problem just need to simulate everithing that was given in statment.
+
+[262B - Roma and Changing Signs](/contest/262/problem/B "Codeforces Round 160 (Div. 2)")
+
+We will "reverse" numbers from the begining to the end while numebrers are negative and we did't spend all k operations.
+In the end there can leave some operetions, and we will "reverse" only one numeber, with minimal value k(that remains) times.
+
+[261A - Maxim and Discounts](/contest/261/problem/A "Codeforces Round 160 (Div. 1)")
+
+Ofcourse the most optimal way is to use discount with minimal q_i. We will sort our numbers and will go from the end to begin of the array. We will by use our discount as soon as it will be possible. It's not hard to see that we will buy all the items with numbers I (zero-numeration from the end of the sorted array) such, that I%(q+2)<q.
+
+[261B - Maxim and Restaurant](/contest/261/problem/B "Codeforces Round 160 (Div. 1)")
+If all people can come, we will return answer as n.
+If it is impossible, there will be finded some person that will be the last to come. We will brtueforce this value. Then we will detrminate dp[i,j,s] in how many ways j persons from the first i with total length s can be in the resturant. It is easy to calculate.
+Then we will add to the answer values dp[n][i][s]*i!*(n-1-i)! for all i,s such that s+p[h]>P. Where P — total length of the table, p[h] — length of the fixed person.
+
+[261C - Maxim and Matrix](/contest/261/problem/C "Codeforces Round 160 (Div. 1)")
+For fixed m, the sum in the last row will be 2^(bit_count(m+1)-1). So now if T is not power of 2, answer is 0. Else we can find number of bits that we need. And know we have stndart problem. How many numbers form 2 to n+1 have exactly P bits in binary presentation of the number. It is well known problem can be done using binomial cooficients. We will count number of numebers smaller then out number with fixed prefix.
+
+[261D - Maxim and Increasing Subsequence](/contest/261/problem/D "Codeforces Round 160 (Div. 1)")
+
+This problem can be done using dp[i,j] where we can end our increasing sequence with length i and last number j. Its not hard to understand that number of states will be n*b. To make a tranfer we need to know array first[j] — first position of the number j in the sequence b, next[i][j] — first position of the number j in the sequence b after position i.
+
+Now its easy to calculate all values.
+
+[261E - Maxim and Calculator](/contest/261/problem/E "Codeforces Round 160 (Div. 1)")
+
+I will add tutorial later. But I will give you a hint: number of numbers with maximal prime divisor<=100 is near 3000000 numbers.
diff --git a/editorials/263.md b/editorials/263.md
@@ -0,0 +1,47 @@
+Source: https://codeforces.com/blog/entry/6419
+
+[263A - Beautiful Matrix](/contest/263/problem/A "Codeforces Round 161 (Div. 2)")
+
+If the single 1 is located on the intersection of the *r*-th row and the *c*-th column (1-based numeration), then the answer is |3 - *r*| + |3 - *c*|.
+
+[263B - Squares](/contest/263/problem/B "Codeforces Round 161 (Div. 2)")
+
+If *k* > *n*, then the answer doesn't exist. Otherwise let's sort the squares by descending of their sizes. Now you can print any point that belongs to the *k*-th square and doesn't belong to the *k* + 1-th square. One of the possible answers is (*a**k*, 0).
+
+[263C - Circle of Numbers](/contest/263/problem/C "Codeforces Round 161 (Div. 2)")
+
+First of all, we have to check that each number occurs in the input exactly 4 times. If it's not true, then the answer definitely doesn't exist.
+
+Otherwise, let's try to restore the circle. As cyclic shift of circle doesn't matter, let 1 to be the first number. As the second and the third number must be connected to each other and to 1, there are only few possibilities. So let's try them all. And when we know first three numbers, the rest of the circle could be easily and unambiguously restored in *O*(*n*). Just find a number, which is not included in the circle yet, and is connected to the last two numbers of the circle. Add this number to the resulting circle (as new last number), and repeat the procedure while possible. If we succeeded to add all the numbers to the circle, than the resulting circle is the answer.
+
+[263D - Cycle in Graph](/contest/263/problem/D "Codeforces Round 161 (Div. 2)")
+
+Consider any simple path *v*1, *v*2, ..., *v**r* which cannot be increased immediately (by adding a node to it's end, *v**r*). In other words, all the neighbours of *v**r* are already included in the path. Let's find the first node of the path (say, *v**l*), which is connected to *v**r*. It is clear that *v**l*, *v**l* + 1, ..., *v**r* is a cycle and it contains all the neighbours of *v**r*. But according to the problem's statement, each node has at least *k* neighbours. So length of the cycle is at least *k* + 1 ( + 1 is for node *v**r* itself).
+
+[263E - Rhombus](/contest/263/problem/E "Codeforces Round 161 (Div. 2)")
+
+Divide the rhombus of size *k* into 4 right-angled triangles as shown on a picture below. One of them has size *k*, two — size *k* - 1, and another one — size *k* - 2.
+
+
+
+Let's solve the problem separately for each triangle. The most convenient way to do that is to rotate the input 4 times and run the same solving function 4 times. The result of this function will be a 2D array. Cell (*x*, *y*) indicates the answer we get if the right-angled vertex of triangle is located at cell (*x*, *y*). So it will be easy to combine 4 such arrays (just rotating and shifting properly) to get the actual answer for rhombus.
+
+The main idea of the solution for triangle is the following. If we know the answer for a cell, we can easily move our triangle by one cell in any direction (right, down, left, or up) and recalculate the answer for that new cell in constant time. In fact, we need only 2 directions: right and down. And the values for top left corner should be calculated with straightforward cycles in *O*(*k*2) time.
+
+
+
+More precisely, let's define 5 functions:
+
+1. The sum on diagonal segment of *k* elements: 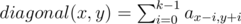
+2. The sum on vertical segment of *k* elements: 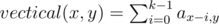
+3. The weighted sum on vertical segment of *k* elements: 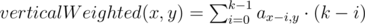
+4. The sum on a triangle: 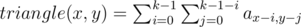
+5. The weighted sum on a triangle: 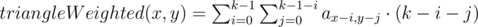
+
+Calculating the first 3 functions in *O*(*nm*) in total is quite obvious. Formulas for the others are following:
+
+*triangle*(*x*, *y* + 1) = *triangle*(*x*, *y*) - *diagonal*(*x*, *y* - *k* + 1) + *vertical*(*x*, *y* + 1)
+
+*triangleWeighted*(*x*, *y* + 1) = *triangleWeighted*(*x*, *y*) - *triangle*(*x*, *y*) + *verticalWeighted*(*x*, *y* + 1)
+
+Formulas for moving in other directions are similar.
diff --git a/editorials/264.md b/editorials/264.md
@@ -0,0 +1,80 @@
+Source: https://codeforces.com/blog/entry/6478
+
+#### [Div2 A Colorful Stones (Simplified Edition)](//codeforces.com/problemset/problem/265/A) (Author: [rng_58](/profile/rng_58 "International Grandmaster rng_58"))
+
+In this problem you just need to implement what is written in the statement. Make a variable that holds the position of Liss, and simulate the instructions one by one.
+
+#### [Div2 B Roadside Trees (Simplified Edition)](//codeforces.com/problemset/problem/265/B) (Author: [snuke](/profile/snuke "Expert snuke"))
+
+The optimal path of Liss is as follows: First she starts from the root of tree 1. Walk up the tree to the top and eat a nut. Walk down to the height *min*(*h*1, *h*2). Jump to the tree 2. Walk up the tree to the top and eat a nut. Walk down to the height *min*(*h*2, *h*3), ... and so on.
+
+#### [Div1 A / Div2 C Escape from Stones](//codeforces.com/problemset/problem/264/A) (Author: [DEGwer](/profile/DEGwer "Expert DEGwer"))
+
+In this problem, there are many simple algorithms which works in *O*(*n*). One of them (which I intended) is following:
+
+You should prepare 2 vectors. If *s*[*i*] = '*l*', you should push i to the first vector, and if *s*[*i*] = '*r*', you should push i to the second vector. Finally, you should print the integers in the second vector by default order, after that, you should print the integers in the first vector in the reverse order.
+
+This algorithm works because if Liss divides an interval into two intervals *A* and *B* and she enters *A*, she will never enter *B*.
+
+#### [Div1 B / Div2 D Good Sequences](//codeforces.com/problemset/problem/264/B) (Author: [DEGwer](/profile/DEGwer "Expert DEGwer"))
+
+The main idea is DP. Let's define *dp*[*x*] as the maximal value of the length of the good sequence whose last element is *x*, and define *d*[*i*] as the (maximal value of *dp*[*x*] where *x* is divisible by *i*).
+
+You should calculate *dp*[*x*] in the increasing order of x. The value of *dp*[*x*] is (maximal value of *d*[*i*] where *i* is a divisor of *x*) + 1. After you calculate *dp*[*x*], for each divisor *i* of *x*, you should update *d*[*i*] too.
+
+This algorithm works in *O*(*nlogn*) because the sum of the number of the divisor from 1 to *n* is *O*(*nlogn*).
+
+Note that there is a corner case. When the set is {1}, you should output 1.
+
+#### [Div1 C / Div2 E Choosing Balls](//codeforces.com/problemset/problem/264/C) (Author: [hogloid](/profile/hogloid "Master hogloid"))
+
+There are many *O*(*Q* * *N* * *logN*) solutions using segment trees or other data structures, but probably they will get time limit exceeded.
+
+We can solve each query independently. First, let's consider the following DP algorithm.
+
+*dp*[*c*] := the maximal value of a sequence whose last ball's color is *c*
+
+For each ball *i*, we want to update the array. Let the *i*-th ball's color be *col*[*i*], the *i*-th ball's value be *val*[*i*], and the maximal value of dp array other than *dp*[*col*[*i*]] be *otherMAX*. We can update the value of *dp*[*col*[*i*]] to *dp*[*col*[*i*]] + *val*[*i*] × *a* or *otherMAX* + *val*[*i*] × *b*. Here, we only need to know *dp*[*col*[*i*]] and *otherMAX*. If we remember the biggest two values of *dp* array in that time and their indexes in the array, *otherMAX* can be calculated using the biggest two values, which always include maximal values of dp array other than any particular color.
+
+Since the values of dp array don't decrease, we can update the biggest two values in *O*(1). Finally, the answer for the query is the maximal value of *dp* array.
+
+The complexity of the described algorithm is *O*(*QN*).
+
+#### [Div1 D Colorful Stones](//codeforces.com/problemset/problem/264/D) (Author: [rng_58](/profile/rng_58 "International Grandmaster rng_58"))
+
+First, let's consider a simpler version of the problem: You are given a start state and a goal state. Check whether the goal state is reachable from the start state.
+
+Define *A*, *B*, *C*, and *D* as in the picture below, and let *I* be the string of your instructions. *A* and *B* are substrings of *s*, and *C* and *D* are substrings of *t*.
+
+
+
+It is possible to reach the goal state from the start state if there exists an instruction *I* such that:
+
+* 1 *A* is a subsequence of *I*.
+* 2 *B* is not a subsequence of *I*.
+* 3 *C* is a subsequence of *I*.
+* 4 *D* is not a subsequence of *I*.
+
+So we want to check if such string *I* exists. (string *s*1 is called a subsequence of *s*2 if it is possible to get *s*2 by removing some characters of *s*1)
+
+There are some obvious "NO" cases. When *D* is a subsequence of *A*, it is impossible to satisfy both conditions 1 and 4. Similarly, *B* must not be a subsequence of *C*. Are these sufficient conditions? Let's try to prove this hypothesis.
+
+To simplify the description we will introduce some new variables. Let *A*', *B*', *C*', and *D*' be strings that can be obtained by removing the first characters of *A*, *B*, *C*, and *D*. Let *c*1 and *c*2 be the first characters of *A* and *C*.
+
+
+
+Suppose that currently the conditions are satisfied (i.e. *D* is not a subsequence of *A* and *B* is not a subsequence of *C*).
+
+* If *c*1 = *c*2, you should perform the instruction *c*1 = *c*2. The new quatruplet will be (*A*', *B*', *C*', *D*') and this also satisies the conditions.
+* If *c*1 ≠ *c*2 and *B*' is not a subsequnce of *C*, you should perform the instruction *c*1. The new quatruplet will be (*A*', *B*', *C*, *D*) and this also satisies the conditions.
+* If *c*1 ≠ *c*2 and *D*' is not a subsequnce of *A*, you should perform the instruction *c*2. The new quatruplet will be (*A*, *B*, *C*', *D*') and this also satisies the conditions.
+
+What happens if all of the above three conditions don't hold? In this case *A* and *C* have the same length and *A* = *c*1*c*2*c*1*c*2..., *B* = *c*2*c*1*c*2*c*1. In particular the last two characters of *A* and *B* are swapped: there are different characters *x* and *y* and *A* = ...*xy*, *B* = ...*yx*. Now you found a new necessary condition! Generally, if *A* and *B* are of the form *A* = ...*xy* and *B* = ...*yx*, the goal state is unreachable. If the last instruction is *x*, Vasya must be in the goal before the last instruction, but then Vasya will go further after the last instruction. If the last instruction is *y*, we will also get a contradiction.
+
+Finally we have a solution. The goal state is reachable from the start state if and only if *D* is not a subsequence of *A*, *B* is not a subsequnce of *C*, and *A* and *C* are not of the form *A* = ...*xy*, *C* = ...*yx*. The remaining part is relatively easy, so I'll leave it as an exercise for readers.
+
+#### [Div1 E Roadside Trees](//codeforces.com/problemset/problem/264/E) (Author: [snuke](/profile/snuke "Expert snuke"))
+
+For this problem there are slides: Please check [here](https://speakerdeck.com/snuke/codeforces162-div1-e).
+
+UPD: Thank you for pointing out mistakes. They are fixed.
diff --git a/editorials/265.md b/editorials/265.md
@@ -0,0 +1,80 @@
+Source: https://codeforces.com/blog/entry/6478
+
+#### [Div2 A Colorful Stones (Simplified Edition)](//codeforces.com/problemset/problem/265/A) (Author: [rng_58](/profile/rng_58 "International Grandmaster rng_58"))
+
+In this problem you just need to implement what is written in the statement. Make a variable that holds the position of Liss, and simulate the instructions one by one.
+
+#### [Div2 B Roadside Trees (Simplified Edition)](//codeforces.com/problemset/problem/265/B) (Author: [snuke](/profile/snuke "Expert snuke"))
+
+The optimal path of Liss is as follows: First she starts from the root of tree 1. Walk up the tree to the top and eat a nut. Walk down to the height *min*(*h*1, *h*2). Jump to the tree 2. Walk up the tree to the top and eat a nut. Walk down to the height *min*(*h*2, *h*3), ... and so on.
+
+#### [Div1 A / Div2 C Escape from Stones](//codeforces.com/problemset/problem/264/A) (Author: [DEGwer](/profile/DEGwer "Expert DEGwer"))
+
+In this problem, there are many simple algorithms which works in *O*(*n*). One of them (which I intended) is following:
+
+You should prepare 2 vectors. If *s*[*i*] = '*l*', you should push i to the first vector, and if *s*[*i*] = '*r*', you should push i to the second vector. Finally, you should print the integers in the second vector by default order, after that, you should print the integers in the first vector in the reverse order.
+
+This algorithm works because if Liss divides an interval into two intervals *A* and *B* and she enters *A*, she will never enter *B*.
+
+#### [Div1 B / Div2 D Good Sequences](//codeforces.com/problemset/problem/264/B) (Author: [DEGwer](/profile/DEGwer "Expert DEGwer"))
+
+The main idea is DP. Let's define *dp*[*x*] as the maximal value of the length of the good sequence whose last element is *x*, and define *d*[*i*] as the (maximal value of *dp*[*x*] where *x* is divisible by *i*).
+
+You should calculate *dp*[*x*] in the increasing order of x. The value of *dp*[*x*] is (maximal value of *d*[*i*] where *i* is a divisor of *x*) + 1. After you calculate *dp*[*x*], for each divisor *i* of *x*, you should update *d*[*i*] too.
+
+This algorithm works in *O*(*nlogn*) because the sum of the number of the divisor from 1 to *n* is *O*(*nlogn*).
+
+Note that there is a corner case. When the set is {1}, you should output 1.
+
+#### [Div1 C / Div2 E Choosing Balls](//codeforces.com/problemset/problem/264/C) (Author: [hogloid](/profile/hogloid "Master hogloid"))
+
+There are many *O*(*Q* * *N* * *logN*) solutions using segment trees or other data structures, but probably they will get time limit exceeded.
+
+We can solve each query independently. First, let's consider the following DP algorithm.
+
+*dp*[*c*] := the maximal value of a sequence whose last ball's color is *c*
+
+For each ball *i*, we want to update the array. Let the *i*-th ball's color be *col*[*i*], the *i*-th ball's value be *val*[*i*], and the maximal value of dp array other than *dp*[*col*[*i*]] be *otherMAX*. We can update the value of *dp*[*col*[*i*]] to *dp*[*col*[*i*]] + *val*[*i*] × *a* or *otherMAX* + *val*[*i*] × *b*. Here, we only need to know *dp*[*col*[*i*]] and *otherMAX*. If we remember the biggest two values of *dp* array in that time and their indexes in the array, *otherMAX* can be calculated using the biggest two values, which always include maximal values of dp array other than any particular color.
+
+Since the values of dp array don't decrease, we can update the biggest two values in *O*(1). Finally, the answer for the query is the maximal value of *dp* array.
+
+The complexity of the described algorithm is *O*(*QN*).
+
+#### [Div1 D Colorful Stones](//codeforces.com/problemset/problem/264/D) (Author: [rng_58](/profile/rng_58 "International Grandmaster rng_58"))
+
+First, let's consider a simpler version of the problem: You are given a start state and a goal state. Check whether the goal state is reachable from the start state.
+
+Define *A*, *B*, *C*, and *D* as in the picture below, and let *I* be the string of your instructions. *A* and *B* are substrings of *s*, and *C* and *D* are substrings of *t*.
+
+
+
+It is possible to reach the goal state from the start state if there exists an instruction *I* such that:
+
+* 1 *A* is a subsequence of *I*.
+* 2 *B* is not a subsequence of *I*.
+* 3 *C* is a subsequence of *I*.
+* 4 *D* is not a subsequence of *I*.
+
+So we want to check if such string *I* exists. (string *s*1 is called a subsequence of *s*2 if it is possible to get *s*2 by removing some characters of *s*1)
+
+There are some obvious "NO" cases. When *D* is a subsequence of *A*, it is impossible to satisfy both conditions 1 and 4. Similarly, *B* must not be a subsequence of *C*. Are these sufficient conditions? Let's try to prove this hypothesis.
+
+To simplify the description we will introduce some new variables. Let *A*', *B*', *C*', and *D*' be strings that can be obtained by removing the first characters of *A*, *B*, *C*, and *D*. Let *c*1 and *c*2 be the first characters of *A* and *C*.
+
+
+
+Suppose that currently the conditions are satisfied (i.e. *D* is not a subsequence of *A* and *B* is not a subsequence of *C*).
+
+* If *c*1 = *c*2, you should perform the instruction *c*1 = *c*2. The new quatruplet will be (*A*', *B*', *C*', *D*') and this also satisies the conditions.
+* If *c*1 ≠ *c*2 and *B*' is not a subsequnce of *C*, you should perform the instruction *c*1. The new quatruplet will be (*A*', *B*', *C*, *D*) and this also satisies the conditions.
+* If *c*1 ≠ *c*2 and *D*' is not a subsequnce of *A*, you should perform the instruction *c*2. The new quatruplet will be (*A*, *B*, *C*', *D*') and this also satisies the conditions.
+
+What happens if all of the above three conditions don't hold? In this case *A* and *C* have the same length and *A* = *c*1*c*2*c*1*c*2..., *B* = *c*2*c*1*c*2*c*1. In particular the last two characters of *A* and *B* are swapped: there are different characters *x* and *y* and *A* = ...*xy*, *B* = ...*yx*. Now you found a new necessary condition! Generally, if *A* and *B* are of the form *A* = ...*xy* and *B* = ...*yx*, the goal state is unreachable. If the last instruction is *x*, Vasya must be in the goal before the last instruction, but then Vasya will go further after the last instruction. If the last instruction is *y*, we will also get a contradiction.
+
+Finally we have a solution. The goal state is reachable from the start state if and only if *D* is not a subsequence of *A*, *B* is not a subsequnce of *C*, and *A* and *C* are not of the form *A* = ...*xy*, *C* = ...*yx*. The remaining part is relatively easy, so I'll leave it as an exercise for readers.
+
+#### [Div1 E Roadside Trees](//codeforces.com/problemset/problem/264/E) (Author: [snuke](/profile/snuke "Expert snuke"))
+
+For this problem there are slides: Please check [here](https://speakerdeck.com/snuke/codeforces162-div1-e).
+
+UPD: Thank you for pointing out mistakes. They are fixed.
diff --git a/editorials/266.md b/editorials/266.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/6499
+
+[266A - Stones on the Table](/contest/266/problem/A "Codeforces Round 163 (Div. 2)")
+
+In this problem you should count number of consecutive pairs of equal letters. It can be done using one cycle and *O*(*N*) time.
+
+[266B - Queue at the School](/contest/266/problem/B "Codeforces Round 163 (Div. 2)")
+
+In this you should realize the given process. You should *t* times swap elements *i* and *i* + 1 if on the place *i* was a girl and on the place *i* + 1 was a boy. You should not push some girl to the left multiple times at once. The solution can be written using *O*(*N*·*T*) time.
+
+[266C - Below the Diagonal](/contest/266/problem/C "Codeforces Round 163 (Div. 2)")
+
+This problem can be solved using constructive algorithm. We will use inductive approach. At first, we have matrix of size *n* and *n* - 1 ones in it. Therefore, there is a column with no ones in it. So, we put this column to *n*-th place. In this case, the lower right element will be 0. Then find any row with at least one integer one and put it to the *n*-th place.
+
+After these operations the element in cell (*n*, *n*) equals to 0 and the last row has at least one integer one. Therefore, we can reduce the dimension of our problem, that is *n*: = *n* - 1. In our new problem we have no more than *n* - 2 ones. So, we can solve this problem using the same algorithm. When *n* equals to 1 you should finish algorithm, because there is no ones left. This algorithm uses *O*(*N*) swap operations, no more than two for every *n*.
+
+[266D - BerDonalds](/contest/266/problem/D "Codeforces Round 163 (Div. 2)")
+
+I'll tell a few ideas how to solve this problem. Firstly, describe the solution with time *O*(*N*4). Consider every edge (*u*, *v*) of length *len* where could be the answer point. Let this point lie at a distance *x* from vertex *u*. So, the distance from this point to vertex *i* would be *min*(*x* + *d*[*u*][*i*], *len*–*x* + *d*[*v*][*i*]), where *d*[*x*][*y*] — distance between vertices *x* and *y*. Equate these values and get the critical value *x* for vertex *i*, *x* = (*len* + *d*[*v*][*i*]–*d*[*u*][*i*]) / 2. It follows that the answer to the problem is half-integer. So, for every edge and every other vertex we get set of critical points. We should check them all include the vertices of the graph (ends of the segments). This solution may probably pass with some optimizations.
+
+Another solution with complexity *O*(*N*3·*log*2). Multiply all weights by 2. Consider every edge where should be the answer and make binary search for the answer (in integers). To check some current value you should consider every vertex *i* and assume that the answer is achieved in this vertex. In this case, the answer point must lie on this edge <= some value *l*[*i*] or >= some value *r*[*i*]. This subproblem is solved using offline algorithm using sorting events and maintaining the balance.
+
+Also, you can use ternary search on every edge of the graph. But you should divide every edge on several segments and find the answer on every segment, because the ternary search is incorrect in this problem.
+
+The last two solutions can provide accepted, if you realize them carefully. Also note, that there is the solution with complexity *O*(*N*3) by the author [RAD](/profile/RAD "International Master RAD").
+
+[266E - More Queries to Array...](/contest/266/problem/E "Codeforces Round 163 (Div. 2)")
+
+This problem can be solved using data structure. We would use segment tree, we will support *k* segment trees for every power. At every vertex we will calculate weighted sum of the appropriate power, also we will save some number that indicates the color of the whole segment, if any.
+
+User [Egor](/profile/Egor "International Grandmaster Egor") in comments to the post and user [mexmans](/profile/mexmans "Candidate Master mexmans") in comments to the tutorial tell their formula to get the answer. I try to describe how to get them by yourself. Firstly, you should write what value your segment tree gives. The tree can calculate the sum . You need to calculate the sum 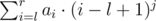, you can write it also as 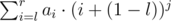. Then you should write the last sum for some first powers (at least three) (at piece of paper) and subtract the second sum (what you need) from the first sum (what your tree can calculate). You get an expression that describes what should be subtracted to get the answer from the value what you tree can calculate. This is just the Newton binomial without the highest power.
+
+So, the answer for power *j* is expressed as the subtraction of the value of query to your segment tree and the Newton binomial, with all powers that are less than *j* (these values can also calculated using your segment tree). Partial sum of the powers and binomial coefficients can be precalced. The solution has the complexity *O*(*N*·*K*·*log*(*N*)).
diff --git a/editorials/268.md b/editorials/268.md
@@ -0,0 +1,114 @@
+Source: https://codeforces.com/blog/entry/6545
+
+## [268A - Games](/contest/268/problem/A "Codeforces Round 164 (Div. 2)")
+
+With only 30 teams, the simplest solution is simulating all the matches:
+
+```
+for i = 1 to N
+ for j = 1 to N
+ if i != j and h[i] = a[j] then
+ ++ans
+```
+
+An `O(N + M)` solution is also possible, where `M` is the length of colors' range (i.e. 100 under the given constraints). First, you need to count for each color i the number of teams `cntH[i]` which have the home uniform of color i and the number of teams `cntA[i]` which have the away uniform of color i. The answer is the sum of products of these quantities for each color, i.e. sum of `cntH[i] * cntA[i]` over all i.
+
+## [268B - Buttons](/contest/268/problem/B "Codeforces Round 164 (Div. 2)")
+
+Let us first detect the worst case scenario. It is more or less apparent that when Manao tries to guess the i-th (1 <= i <= n) button in order, he will make `n-i` mistakes in the worst case. After that the correct button is evident.
+
+Now let's count the total number of presses Manao might need before he guesses the whole sequence. When he is guessing the first button he makes `n-1` mistakes, but the "mistake cost", i.e. the number of presses before the mistake is made, is equal to 1. When Manao goes for the second button, the mistake cost becomes 2, because each time Manao needs to press the first (already guessed) button. Continuing like this, we obtain that when Manao tries to guess the i-th button in order, he will perform `(n-i) * i` button presses.
+
+After Manao guessed the correct sequence, he needs to enter it once, which is another `n` presses.
+
+So we already have an `O(n)` algorithm: sum up `(n-i)*i` for i=1, ..., n-1 and add `n` to the sum obtained.
+
+When n is anything that fits in 32-bit integer type, the task is solvable in `O(1)`*. The sum `(n-i)*i` is two separate sums: the sum of `n*i` and the sum of `i*i`. The first sum is `n*(1+...+n-1)`, which can be computed with the sum of arithmetic progression. The second sum is the sum of squares from 1 to n-1, which can be evaluated with a polynom of degree 3: <http://pirate.shu.edu/~wachsmut/ira/infinity/answers/sm_sq_cb.html>
+
+*The only problem is that the answer for large `n`-s does not fit even in 64-bit integer type, but at least we can compute its remainder from division by anything.
+
+## [268C - Beautiful Sets of Points](/contest/268/problem/C "Codeforces Round 164 (Div. 2)")
+
+Obviously, if a set contains a point `(x', y')`, it can not contain any other point with `x=x'` or `y=y'`, because these two points would be an integer distance apart. There are only `n+1` distinct x-coordinates and `m+1` distinct y-coordinates. Therefore, the size of the set sought can not exceed `min(n, m) + 1`.
+
+If the constraint `x+y>0` was not present, the set of points `(i, i)` (0 <= i <= min(n, m)) would do nicely. The distance between two points `(i, i)` and `(j, j)` is equal to `|i-j|*sqrt(2)` and can only be integer when i=j. On the other hand, there are `min(n, m) + 1` points and we already know that we can't take more than that.
+
+Since point `(0, 0)` is restricted, we can take the other "diagonal", i.e. use points `(i, min(n, m) - i)`.
+
+## [268D - Wall Bars](/contest/268/problem/D "Codeforces Round 164 (Div. 2)")
+
+Those who are well experienced at dynamic programming can scroll down to "Overall solution" right away. Those who have some experience in DPs can read my attempt to explain how you can come up with that solution. Those with no experience probably shouldn't read this at all :)
+
+Imagine a solution which considers all possible designs, adding the bar-steps one by one. Consider any sequence, like 2123412413. There are 4 ways to continue this sequence by appending '1', '2', '3' or '4' to it. For each of the `4^n` wall bars / strings we need to check that for at least one of {'1', '2', '3', '4'} character the following is true: its first entry in the string is at position no more than `h`, each next one differs from the previous by no more than `h` and the last one is beyond position `n-h`.
+
+Surely, such a solution won't work for large `n`-s in any reasonable time, but we can start from it in the search of a better approach. First, let's note that we can check the feasibility of the string after each character addition: if somewhere in the middle of string we noticed that for each of the characters the necessary conditions are broken, there is no reason to complete the string. Also, note that we don't need the whole prefix to check the validity of the conditions after each character addition. All we need to know is when each of the '1', '2', '3' and '4' characters occured last, and whether the conditions for each of the characters have been fulfilled up to this point. It turns out that two prefixes in which [each of the characters last occured at the same position] and [the validity of the conditions for each character are equal], are absolutely equivalent for the brute force algorithm's further operation. That is, for example for h=4 these two prefixes can be completed (up to length `n`) in the same number of ways:
+
+```
+44123424132
+12424224132
+```
+
+The last time each of the characters have occured at the same positions, characters '1' and '3' are already "lost" (the conditions are already broken for them), characters '2' and '4' can still turn the string into a valid one.
+
+With the help of the observations made, we can already build a polynomial-time algorithm based on dynamic programming principle. Let `ways[curN][i][j][k][l][ii][jj][kk][ll]` be the number of designs of height `curN`, where the last step in direction 1 was at height `i`, the last step in direction 2 — at height `j` and so on; `ii, jj, kk, ll` are boolean parameters which indicate whether the conditions are valid in the corresponding direction. When we choose the direction for the step at height `curN+1`, we obtain a design with `curN+1` steps, the last step in the direction we chose is now at height `curN+1` and rest stay where they were. Conditions validity can also be reassessed. Since `curN` is always one of `{i, j, k, l}`, we can obtain a `O(n^4)` algorithm. However, this is still too slow.
+
+Another observation: if we are looking at a bar at height `curN` and the last step in this direction was earlier than `curN-h` steps ago, we don't really care which height was it exactly at, since this direction is not valid any more. Therefore, the number of states in our algorithm can be only `O(n*h^3)`. Moreover, those `ii,jj,kk,ll` parameters correlate with the heights of the latest steps in the corresponding directions, so we can (almost) get rid of them, thus reducing the number of states in a number of times.
+
+On the base of these observations we can probably build different solutions. I will tell mine.
+
+#### Overall solution
+
+We will keep a 5-dimensional DP :) Let `ways[curN][alive][last1][last2][last3]` be the number of designs where:
+
+* There are exactly `curN` steps.
+* If the direction of the latest step if still "alive", then `alive` = 1, otherwise it's equal to 0. A direction is alive if its first step was not higher than `h` and each subsequent one was higher than the previous by at most distance `h`.
+* `last1`, `last2` and `last3` keep the information about the other directions in any order. `lasti` can be zero in two cases: if there were no steps in the corresponding direction, or if the latest one was earlier than h steps before. Otherwise, `lasti` is the number of steps between the current step and the latest step in the corresponding direction.
+
+We can optimize by keeping `last1<=last2<=last3`, which reduces the number of states in roughly 6 times. However, this complicates the code and doesn't have a significant effect (since the transitions processing becomes costly). Thus I will not consider it at all.
+
+What transitions can be made from state `[curN][alive][last1][last2][last3]`? We shall process the states in order from curN=1 to curN=N-1. `ways[1][1][0][0][0]` (i.e. a single step) is equal to 4 as a base case. So we have:
+
+* If we add a step in the same direction as the latest (i.e. the one at height `curN`), then we obtain state `[curN+1][alive][last1+1][last2+1][last3+1]` (roughly): `curN` has increased by 1; the "livingness" of the direction of the last step could not change; all the `lasti`-s have increased by 1. However, note that for `lasti=0` it should not be incremented (the corresponding step either does not exist at all, or is way below). Also, for `lasti=h-1` it turns to zero (the last step is now too low).
+* If we put the step in the same direction as the one which was at height last1, we obtain state `[curN+1][last1 > 0 || curN < h][alive][last2+1][last3+1]`. This decyphers in the following way: if last1>0, then this condition is alive. `last1` could also be 0, but the number of already built steps less than h — in which case this is the first step and the direction becomes alive by putting it. The direction denoted by `last1` has been replaced (in the state parameters) by the one in which the `curN`-th step was sticked out. Therefore, it was 1 step ago and we should write [1] there. On the other hand, that direction could already be dead and we would need to write [0]. It turns out that the value coincides with value of `alive`. `last2` and `last3` change in the same way as in the previous case.
+* Directions `last2` and `last3` are treated in the same way as `last1`.
+
+When we process a transition, the number of designs corresponding to the new state increments by `ways[curN][alive][last1][last2][last3]`. So the overall answer is sum of all `[n][1][a][b][c]`, where `0<=a,b,c<h` plus sum of all `[n][0][a][b][c]`, where at least one of a, b, c is non-zero. So we have an algorithm of `O(n*h^3)` complexity which needs asymptotically the same amount of memory. Its implementation could catch ML (especially on Java). This can be handled through the following observation: since we only need values `[i-1][][][][]` to compute `[i][][][][]`-s, only `O(h^3)` states need to be kept at any given moment.
+
+Well, before writing this analysis I didn't realize it was so huge :)
+
+You can check [SteamTurbine](/profile/SteamTurbine "Master SteamTurbine")'s solution at [3027309](/contest/268/submission/3027309 "Submission 3027309 by SteamTurbine") for a very compact implementation of a similar idea.
+
+## [268E - Playlist](/contest/268/problem/E "Codeforces Round 164 (Div. 2)")
+
+Let us first find the answer for a fixed sequence of songs. Consider any two songs which are at positions i and j (i < j) in the playlist. If Manao liked song i and disliked song j, then song i will be listened to again. Therefore, with probability `p[i]*(1-p[j])` the process length will increase by `L[i]`. The sum of `L[i]*p[i]*(1-p[j])` over all pairs (plus the length of all songs since Manao listens to them at least once) is the expected length for the fixed sequence.
+
+So we have that if there are two songs (l1, p1) and (l2, p2), the first one should be placed earlier in the playlist if `l1*p1*(1-p2)>l2*p2*(1-p1)` and later otherwise. This is obviously true if there are only two songs. But suppose that we have more and you ask, why can't there be another song (l3, p3) such that the above inequality rules out that the first song should be after this one and the second song should be before it? Then it's unclear which of the orders results in the maximum expected value. Consider this case in details:
+
+```
+l1*p1*(1-p2)>l2*p2*(1-p1)
+l1*p1*(1-p3)<l3*p3*(1-p1)
+l2*p2*(1-p3)>l3*p3*(1-p2)
+<=>
+l1*p1/(1-p1)>l2*p2/(1-p2)
+l1*p1/(1-p1)<l3*p3/(1-p3)
+l2*p2/(1-p2)>l3*p3/(1-p3)
+```
+
+(this is not quite true if any pi is equal to 0 or 1, but that's not important here)
+
+We have a contradicting system of inequations, so such a case is impossible.
+
+Next, let's consider some order of songs `(l[1], p[1]), ..., (l[n], p[n])`, in which there is a pair of neighbouring songs i and i+1, for which the condition `l[i] * p[i] * (1 - p[i + 1]) >= l[i + 1] * p[i + 1] * (1 - p[i])` does not hold, and assume that this order is optimal. Evidently, if we interchange songs i and i+1, the answer will only change by the value contributed by this pair (i.e. `l[i] * p[i] * (1 - p[i + 1])`). The rest of the songs keep their order towards song i and song i+1. But `l[i] * p[i] * (1 - p[i + 1]) < l[i + 1] * p[i + 1] * (1 - p[i])`, therefore if we put song i+1 before song i, we obtain a larger value. So we have a contradiction — the order chosen is not optimal.
+
+So it turns out that the permutation with maximum possible expected value is obtained when sorting the songs in decreasing order of `l[i]*p[i]/(1-p[i])`. But we still have a problem of computing the answer for a fixed permutation: we only learned how to do this in `O(n^2)`, which is too slow with n=50000. We can use an idea which is probably a yet another dynamic programming example. Suppose we have fixed j and are counting the contribution of song j towards the answer if Manao dislikes it. This value is `(l1*p1 + l2*p2 + ... + l[j-1]*p[j-1])`. For j+1, the corresponding value will be `(l1*p1+...+l[j-1]*p[j-1]+l[j]*p[j])`. It turns out that these values differ in only a single summand, so we can compute each of them in `O(1)` if we consider j-th one by one in increasing order. This idea can be expressed as follows:
+
+```
+lovedLenExp = 0.
+answerExp = 0.
+for j = 1 to N
+ answerExp += l[j]
+ answerExp += lovedLenExp * (1 - p[j])
+ lovedLenExp += l[j] * p[j]
+```
+
+That's all :)
diff --git a/editorials/269.md b/editorials/269.md
@@ -0,0 +1,227 @@
+Source: https://codeforces.com/blog/entry/6596
+
+### [Div II A — Fancy Fence](/contest/270/problem/A "270A - Fancy Fence")
+
+#### Problem
+
+The problem is to tell whether there exists a regular polygon with angle equal to *a*.
+
+#### Solution
+
+Consider all supplementary angles of the regular *n*-polygon with angle *a*, which are equal to . Their sum is equal to , because the polygon is convex. Then the following equality holds: *n*·(180 - *a*) = 360, which means that there is an answer if and only if 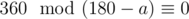.
+
+
+
+Time: *O*(*t*).
+
+Memory: *O*(1).
+
+Implementation: [C++](http://ideone.com/xnq9Iu), [Java](http://ideone.com/D2hHEL)
+
+#### Comments
+
+The problem can be also solved by rotating vector (1, 0) by angle  until it returns in this position (but at most 360 times), and checking that only one full turn has been made (implementation example: C++).
+
+It is also a rare problem on Codeforces that contains just 1 sample test, 1 pretest and 1 full test.
+
+### [Div II B — Multithreading](/contest/270/problem/B "270B - Multithreading")
+
+#### Problem
+
+In this problem we are asked to find the number of *n*-permutation elements that definitely have been moved after performing any sequence of move-to-front element operations. Equally, we should find the maximum possible number of elements that could have not been moved.
+
+#### Solution
+
+If some *a**i* is greater than *a**i* + 1, it is clear that *a**i* definitely contains a new message because the order of these two elements has changed. Let the last such element be *a**k*. Then all of the elements *a**k* + 1, *a**k* + 2, ..., *a**n* can contain no new messages, since their order has not changed. The answer to the problem is *n* - *k*. If there is no such *a**k* the order hasn’t changed at all and there may be no new messages.
+
+Time: *O*(*n*).
+
+Memory: *O*(*n*) / *O*(1).
+
+Implementation: [C++](http://ideone.com/PJFbnJ), [Java](http://ideone.com/0DR19E)
+
+#### Comments
+
+The problem was born while staring at the Codeforces main page and trying to think up an easy Div II problem. =)
+
+### [Div II C / Div I A — Magical Boxes](/contest/269/problem/A "269A - Magical Boxes")
+
+#### Problem
+
+We are given *a**i* squares with side length 2*k**i*. It is allowed to insert squares only inside larger ones, and no two squares should overlap. We must determine the minimum *p* so we can place all the given squares inside a square with side length 2*p*.
+
+#### Solution
+
+Suppose we can put all the squares inside a square with side length 2*p*. Then we can insert each *k**i* type squares independently along the grid as shown in the picture. No two squares will overlap, since 2*x* divides 2*y*, if *x* < *y*. That means that we can find the smallest square that can hold all the given squares with side length 2*k**i* for each *k**i* separately. The answer will be the side length of the largest such square.
+
+
+
+To be able to put *a**i* squares with side length 2*k**i* inside a square with side length 2*s*, the following should hold:
+
+(2*s*)2 ≥ (2*k**i*)2·*a**i* 4*s* ≥ 4*k**i*·*a**i* 4*s* - *k**i* ≥ *a**i*
+
+We can then find the minimum *s*:
+
+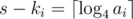 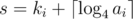
+
+In a special case, if we obtain *s* = *k**i*, *s* should be increased by 1.
+
+Time: 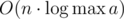.
+
+Memory: *O*(1).
+
+Implementation: [C++](http://ideone.com/NORd3X), [Java](http://ideone.com/Zp7Nno)
+
+#### Comments
+
+The problem can be also solved using binary search on *p*. However, we can see that each square with side length 2*k* + 15 holds any number of squares with side length less than 2*k*, since 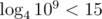. So it is enough to find the first square that fits from range 2*max*{*k*} + 1 to 2*max*{*k*} + 15.
+
+### [Div II D / Div I B — Greenhouse Effect](/contest/269/problem/B "269B - Greenhouse Effect")
+
+#### Problem
+
+There are *n* points on the line, each of type from 1 to *m*. We can freely divide the line into *m* - 1 intervals and replace some points so each point with type *i* is inside the *i*-th interval numbered 1 to *m* from left to right. We must find the minimum number of points to replace.
+
+#### Solution
+
+First, observe that the coordinates don’t matter: only the order of the points is important. Let there be some number of points we can replace to achieve the good arrangement. Then all the other points remain in their positions, so their values must be in increasing order from left to right. Then we must find the maximum number of points that can remain in their positions, which is the longest non-decreasing subsequence of types in the input. If it is of length *l*, the answer is *n* - *l*.
+
+In this problem it was enough to implement a quadratic solution. We count *dp*[*i*][*j*] — the length of the longest non-decreasing subsequence on prefix [1;*i*], with element of type *j* being the last in subsequence. The transition is as follows:
+
+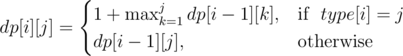
+
+For easy implementation, we can maintain only array *dp*[*j*], and skip the second case.
+
+Time: *O*(*n*2) / .
+
+Memory: *O*(*n*2) / *O*(*n*).
+
+Implementation: [C++](http://ideone.com/8uzrrr)
+
+#### Comments
+
+We had to solve this problem during the work on our project, the origin lies in arranging some rectangular table borders. Our original project dp implementation actually runs in *O*(*nm*).
+
+### [Div II E / Div I C — Flawed Flow](/contest/269/problem/C "269C - Flawed Flow")
+
+#### Problem
+
+In this problem we are given an undirected graph and its flow, and we must reconstruct the edge directions of this flow.
+
+#### Solution
+
+The key element to solving the task is the following observation: if we know all the incoming edges of a vertex, all the remaining edges must be outgoing. The source has no incoming edges, so we already know that all its edges are outgoing. For all other vertices except the sink the amount of incoming and outcoming flow is the same, and is equal to half of the sum of the flow along its incident edges. The algorithm then is to repeatedly direct all the flow from the vertices for which all the incoming edges are known. This can be done with a single BFS:
+
+```
+for all v from 2 to n-1
+ f[v] := sum(flow(v,u))/2;
+put source in queue
+while queue is not empty
+ v := pop(queue)
+ for all edges (v, u)
+ if (v, u) is not directed yet
+ direct v -> u
+ f[u] = f[u] - flow(v,u)
+ if u not sink and f[u] = 0
+ push(queue, u)
+```
+
+As the flow contains no cycles, we can sort the vertices topologically. Then we can be sure that, until all edge directions are known, we can put at least the first vertex with unknown edges in the queue, as all of its incoming edges will be from vertices with lower indices, but we took the first vertex with unknown edges.
+
+Time: *O*(*n* + *m*)
+
+Memory: *O*(*n* + *m*)
+
+Implementation: [C++](http://ideone.com/ePdlwd), [Java](http://ideone.com/qE3vYO)
+
+#### Comments
+
+The obvious "easy" solution is to run some maxflow algorithm and get the answer. However, such implementations failed on anti-maxflow pretest #6.
+
+### [Div I D — Maximum Waterfall](/contest/269/problem/D "269D - Maximum Waterfall")
+
+#### Problem
+
+We are given *n* horizontal segments on a plane, and 2 extra topmost and bottommost segments. These two segments are the source and the sink of the flow. A flow can pass from one segment to a lower segment, if their horizontal projections overlap and there is no other segment between them so their projections overlap. The value of the flow on such segment edge is equal to the length of the horizontal projection overlap. We must find the maximum possible value of the flow along a single segment path.
+
+#### Solution
+
+We will use a sweepline algorithm to solve this task. This horizontal sweepline runs from bottom to top, and holds the parts of the segments that are visible from the line this sweepline is currently at. Each part also holds the reference to its original segment. The sweepline itself is implemented with a binary search tree.
+
+The events of the sweep are the segments. When a new segment is found, we want to find all the lower segments that we can direct the flow onto from this segment. These can be only the original segments of the parts currently in the sweepline whose projections overlap with this segment. Then we iterate over all such parts *p* (finding the first such part is an  operation). How do we know that we can direct the flow onto *p*? Observe that if there is some segment that prevents this, there should be also a part *q* in the sweepline that also can be seen from the current segment. And since the projections of all three segments overlap, this part can only be directly to the left or to the right of *p* in the binary search tree. So we just check whether the original segments of the two parts next to *p* prevent the flow from the current segment to the original segment of *p*.
+
+Afterwards, we remove all such parts from the sweepline, and insert a new part corresponding to the new segment. If the new segment only partially covered an existing part, we reinsert the remaining portion of that part. There are at most two such portions — one on each side of the segment. Thus each segment inserts at most 3 new parts and the size of the sweepline is *O*(*n*). Each part is handled just once before removal, so the total time of such operations is .
+
+Once we know we can direct the flow through  we can immediately update the maximum downwards flow of *a*:
+
+*f**a* = *max*(*f**a*, *min*(*f**b*, *min*(*r**a*, *r**b*) - *max*(*l**a*, *l**b*)))
+
+When we reach the top, *f**top* will be the answer.
+
+
+
+Time: 
+
+Memory: *O*(*n*)
+
+Implementation: [C++](http://ideone.com/bka28U), [Java](http://ideone.com/frmAwe)
+
+#### Comments
+
+Another problem from our project. You can also first build a graph from the segments using the same sweepline and then find the path with the maximum flow in that graph. In the original problem you have to find this graph and there are no top and bottom segments.
+
+### [Div I E — String Theory](/contest/269/problem/E "269E - String Theory")
+
+#### Problem
+
+In this problem we have an *n* × *m* rectange. Each unit midpoint is connected with a segment to some other midpoint not on the same side of the rectangle. We can change the order of the columns and rows, but the segments must remain attached to their midpoints. We should find such a rearrangement that no two segments intersect, or tell that there is no solution.
+
+#### Solution
+
+There are overall 6 types of segments that connect the sides:
+
+1. left-top;
+2. top-right;
+3. right-bottom;
+4. bottom-left;
+5. left-right;
+6. top-bottom;
+
+If there are both left-right and top-bottom segments, there is no solution. Otherwise there remain only 5 types of segments. Without loss of generality suppose there are no left-right segments. Let’s take a closer look at what should the end picture of the rectangle be:
+
+
+
+All left-top segments should be at the left top corner connecting positions (L,i) and (T,i), otherwise they surely would cross some other segment. Similarly must be positioned top-right, right-bottom, bottom-left segments. Finally, all top-bottom segments should be parallel. We also observe that the number of left-top segments must be equal to the number of right-bottom segments and the number of top-right segments should be equal to the number of bottom-right segments. Thus the important observation: the picture of the end arrangement is unique and can be determined from the input simply by counting the number of segments of each type.
+
+Next we define a cycle to be the sequence of segments, where the second midpoint of some segment in the cycle is equal to the first midpoint in the next segment in the cycle. In the given example there are two such cycles (but the direction of each cycle actually matters):
+
+
+
+Then we observe that the set of the cycles does not change with any permutation by the definition of the cycle. We can make a sketch of the solution: we should find the cycle sets in the given arrangement and in the end arrangement, and compare them for equality.
+
+At this point we actually find all the cycles in both arrangements. There are only two types of cycles:
+
+1. (left-top)  (top-right)  (right-bottom)  (bottom-left);
+2. other cycles.
+
+We can easily check whether the sets of first type cycles match, since the length of such cycles is 4. If they match, we rearrange the columns and rows involved to match the end arrangement.
+
+How to compare the remaining cycles. Consider a following example:
+
+
+
+Let the difference in the number of left-top and left-bottom segments be *i*, and this number plus the number of top-bottom segments *s*. If we enumerate the midpoints as in the figure, we can see that each top midpoint *k* is connected to the bottom midpoint 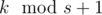 (top-right segments continue as corresponding left-bottom segments). Thus we can describe it as a permutation
+
+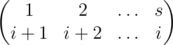
+
+Our cycles correspond to the cycles in this permutation, with top-right segment continuation to left-bottom segment corresponding to the case where permutation cycle element decreases. It is known that the number of such permutations is  and their length is . So all these cycles have the same length. Denote the remaining segment types as some letters (in picture A, B, C). Then not only the length, but the strings describing the cycles are also the same, but can be shifted cyclically (here the direction of the cycles also is important). Besides, we know this string from the correct arrangement cycle. Thus we need to compare all the remaining given arrangement cycle strings to this string, considering cyclic shifts as invariant transformations. For each string this can be done in linear time, for example, using the Knuth-Morris-Pratt algorithm. When we find a cyclical shift for each cycle, we can position its relevant columns and rows according to the end arrangement.
+
+Time: *O*(*n* + *m*).
+
+Memory: *O*(*n* + *m*).
+
+Implementation: [C++](http://ideone.com/bm0GQP), [Java](http://ideone.com/QYJR6c)
+
+#### Comments
+
+This is a total killer task for coding. It took both of us around 5 hours to code the implementation. Congratulations again to [kelvin](/profile/kelvin "Grandmaster kelvin"), at the time of writing still the only one to solve the problem (and of course to anyone who will get this difficult problem accepted =) ).
diff --git a/editorials/27.md b/editorials/27.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/653
+
+**A. [Next Test](https://codeforces.com/contest/27/problem/A)**
+ We will create an array of boolean used[1..3001] ans fill it with "false" values. For each of n given number, we will assign corresponding used value to "true". After that, the index of first element of used with "false" value is the answer to the problem.
+
+ **B. [Tournament](https://codeforces.com/contest/27/problem/B)**
+ To solve this problem first of all we should find such numbers A and B that occur in the input data not (n - 1) times, but (n - 2). We can notice, that winner-loser relation in this problem is transitive. This means that if X wins against Y and Y wins against Z, than X wins against Z. So to find out who is harsher A or B, let's look for such C, that the results of the match A with C and B with C are distinct. If such C exists, than the one, who wins against C should be printed first. If there is no such C, than both results of the match A versus B satisfy problem's statement.
+
+ **C. [Unordered Subsequence](https://codeforces.com/contest/27/problem/C)**
+ First of all, we should notice, that if answer exists, it consist of 3 elements. Here is linear time solution.
+ Let's path with for-loop through the given array and on each iteration let's store current minimul and maximun elements positions. When we are looking at some element, it is enough to check, whereas this element makes unordered subsequence along with min and max elements of the previous part of the array. It is not obvious, but not very difficult to prove. You should try it yourself.
+
+ **D. [Ring Road 2](https://codeforces.com/contest/27/problem/D)**
+ Consider all m given roads as segments on numeric axis. Road from town a to town b should correspond to segment [min(a, b), max(a, b)]. For each pair of segments there are three types of positions: both ends of one segment are inside of the other one, both ends of one segment are outside of the other one and only one end of one segment is inside of the other one. In the first two cases positions of corresponding roads(inside circle or outside) are independend. But in the third case this positions must be opposite
+ Let's build the graph. Vertexes will correspond to segments/roads and edge between vertexes i and j will mean that positions of this roads should be opposite. Now we have another problem: for given undirected graph, we must paint all vertexes in 2 colours such that for each edge, corresponding vertexes will have different colours. This problem can be solved using DFS algorithm. First, we will paint all vertexes in -1 colour. Let's begin for-loop through vertexes. If loop finds -1-vertex, assing colour 0 to the vertex and run DFS from it. DFS from vertex V should look through all neighbor vertex. If neighbor has colour -1, than assing to that neighbor colour, opposite to the colour of V and run DFS from it. If neighbor already has non-negative colour, we should check whereas this colour is opposite, because if it is not, answer is "Impossible". Such DFS will either build the correct answer or prove that it is impossible.
+
+ **E. [Number With The Given Amount Of Divisors](https://codeforces.com/contest/27/problem/E)**
+ Consider the number, that is our answer and factorize it. We will get such product *p*1*a*1· *p*2*a*2· ... · *p**k**a**k*. Product through each i *a**i* + 1 will be the number of divisors. So, if we will take first 10 prime numbers, their product will have 1024 divisors. This means that we need only first 10 primes to build our answer.
+ Let's do it with dynamic programming: d[i][j] - the minimal number with i divisors that can be built with first j prime numbers. To calculate the answer for state (i, j) let's look over all powers of j-th prime number in the answer. If j-th prime number has power k in the answer, than *d*[*i*][*j*] = *d*[*i* / (*k* + 1)][*j* - 1] * *prime*[*j*]*k*. For each power of j-th prime we must select the power, that gives us minimal d[i][j].
+ You should be extremely careful during the implementation, because all calculations are made on the edge of overflow.
+
+ This is it for now. I hope, you will puzzle out all problems, upsolve them and after next contest will get to the division 1. All questions and remarks you can post in the comments.
+ With best regards, Ivan
diff --git a/editorials/270.md b/editorials/270.md
@@ -0,0 +1,227 @@
+Source: https://codeforces.com/blog/entry/6596
+
+### [Div II A — Fancy Fence](/contest/270/problem/A "270A - Fancy Fence")
+
+#### Problem
+
+The problem is to tell whether there exists a regular polygon with angle equal to *a*.
+
+#### Solution
+
+Consider all supplementary angles of the regular *n*-polygon with angle *a*, which are equal to . Their sum is equal to , because the polygon is convex. Then the following equality holds: *n*·(180 - *a*) = 360, which means that there is an answer if and only if 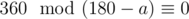.
+
+
+
+Time: *O*(*t*).
+
+Memory: *O*(1).
+
+Implementation: [C++](http://ideone.com/xnq9Iu), [Java](http://ideone.com/D2hHEL)
+
+#### Comments
+
+The problem can be also solved by rotating vector (1, 0) by angle  until it returns in this position (but at most 360 times), and checking that only one full turn has been made (implementation example: C++).
+
+It is also a rare problem on Codeforces that contains just 1 sample test, 1 pretest and 1 full test.
+
+### [Div II B — Multithreading](/contest/270/problem/B "270B - Multithreading")
+
+#### Problem
+
+In this problem we are asked to find the number of *n*-permutation elements that definitely have been moved after performing any sequence of move-to-front element operations. Equally, we should find the maximum possible number of elements that could have not been moved.
+
+#### Solution
+
+If some *a**i* is greater than *a**i* + 1, it is clear that *a**i* definitely contains a new message because the order of these two elements has changed. Let the last such element be *a**k*. Then all of the elements *a**k* + 1, *a**k* + 2, ..., *a**n* can contain no new messages, since their order has not changed. The answer to the problem is *n* - *k*. If there is no such *a**k* the order hasn’t changed at all and there may be no new messages.
+
+Time: *O*(*n*).
+
+Memory: *O*(*n*) / *O*(1).
+
+Implementation: [C++](http://ideone.com/PJFbnJ), [Java](http://ideone.com/0DR19E)
+
+#### Comments
+
+The problem was born while staring at the Codeforces main page and trying to think up an easy Div II problem. =)
+
+### [Div II C / Div I A — Magical Boxes](/contest/269/problem/A "269A - Magical Boxes")
+
+#### Problem
+
+We are given *a**i* squares with side length 2*k**i*. It is allowed to insert squares only inside larger ones, and no two squares should overlap. We must determine the minimum *p* so we can place all the given squares inside a square with side length 2*p*.
+
+#### Solution
+
+Suppose we can put all the squares inside a square with side length 2*p*. Then we can insert each *k**i* type squares independently along the grid as shown in the picture. No two squares will overlap, since 2*x* divides 2*y*, if *x* < *y*. That means that we can find the smallest square that can hold all the given squares with side length 2*k**i* for each *k**i* separately. The answer will be the side length of the largest such square.
+
+
+
+To be able to put *a**i* squares with side length 2*k**i* inside a square with side length 2*s*, the following should hold:
+
+(2*s*)2 ≥ (2*k**i*)2·*a**i* 4*s* ≥ 4*k**i*·*a**i* 4*s* - *k**i* ≥ *a**i*
+
+We can then find the minimum *s*:
+
+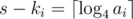 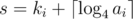
+
+In a special case, if we obtain *s* = *k**i*, *s* should be increased by 1.
+
+Time: 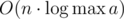.
+
+Memory: *O*(1).
+
+Implementation: [C++](http://ideone.com/NORd3X), [Java](http://ideone.com/Zp7Nno)
+
+#### Comments
+
+The problem can be also solved using binary search on *p*. However, we can see that each square with side length 2*k* + 15 holds any number of squares with side length less than 2*k*, since 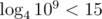. So it is enough to find the first square that fits from range 2*max*{*k*} + 1 to 2*max*{*k*} + 15.
+
+### [Div II D / Div I B — Greenhouse Effect](/contest/269/problem/B "269B - Greenhouse Effect")
+
+#### Problem
+
+There are *n* points on the line, each of type from 1 to *m*. We can freely divide the line into *m* - 1 intervals and replace some points so each point with type *i* is inside the *i*-th interval numbered 1 to *m* from left to right. We must find the minimum number of points to replace.
+
+#### Solution
+
+First, observe that the coordinates don’t matter: only the order of the points is important. Let there be some number of points we can replace to achieve the good arrangement. Then all the other points remain in their positions, so their values must be in increasing order from left to right. Then we must find the maximum number of points that can remain in their positions, which is the longest non-decreasing subsequence of types in the input. If it is of length *l*, the answer is *n* - *l*.
+
+In this problem it was enough to implement a quadratic solution. We count *dp*[*i*][*j*] — the length of the longest non-decreasing subsequence on prefix [1;*i*], with element of type *j* being the last in subsequence. The transition is as follows:
+
+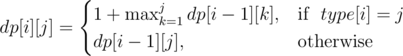
+
+For easy implementation, we can maintain only array *dp*[*j*], and skip the second case.
+
+Time: *O*(*n*2) / .
+
+Memory: *O*(*n*2) / *O*(*n*).
+
+Implementation: [C++](http://ideone.com/8uzrrr)
+
+#### Comments
+
+We had to solve this problem during the work on our project, the origin lies in arranging some rectangular table borders. Our original project dp implementation actually runs in *O*(*nm*).
+
+### [Div II E / Div I C — Flawed Flow](/contest/269/problem/C "269C - Flawed Flow")
+
+#### Problem
+
+In this problem we are given an undirected graph and its flow, and we must reconstruct the edge directions of this flow.
+
+#### Solution
+
+The key element to solving the task is the following observation: if we know all the incoming edges of a vertex, all the remaining edges must be outgoing. The source has no incoming edges, so we already know that all its edges are outgoing. For all other vertices except the sink the amount of incoming and outcoming flow is the same, and is equal to half of the sum of the flow along its incident edges. The algorithm then is to repeatedly direct all the flow from the vertices for which all the incoming edges are known. This can be done with a single BFS:
+
+```
+for all v from 2 to n-1
+ f[v] := sum(flow(v,u))/2;
+put source in queue
+while queue is not empty
+ v := pop(queue)
+ for all edges (v, u)
+ if (v, u) is not directed yet
+ direct v -> u
+ f[u] = f[u] - flow(v,u)
+ if u not sink and f[u] = 0
+ push(queue, u)
+```
+
+As the flow contains no cycles, we can sort the vertices topologically. Then we can be sure that, until all edge directions are known, we can put at least the first vertex with unknown edges in the queue, as all of its incoming edges will be from vertices with lower indices, but we took the first vertex with unknown edges.
+
+Time: *O*(*n* + *m*)
+
+Memory: *O*(*n* + *m*)
+
+Implementation: [C++](http://ideone.com/ePdlwd), [Java](http://ideone.com/qE3vYO)
+
+#### Comments
+
+The obvious "easy" solution is to run some maxflow algorithm and get the answer. However, such implementations failed on anti-maxflow pretest #6.
+
+### [Div I D — Maximum Waterfall](/contest/269/problem/D "269D - Maximum Waterfall")
+
+#### Problem
+
+We are given *n* horizontal segments on a plane, and 2 extra topmost and bottommost segments. These two segments are the source and the sink of the flow. A flow can pass from one segment to a lower segment, if their horizontal projections overlap and there is no other segment between them so their projections overlap. The value of the flow on such segment edge is equal to the length of the horizontal projection overlap. We must find the maximum possible value of the flow along a single segment path.
+
+#### Solution
+
+We will use a sweepline algorithm to solve this task. This horizontal sweepline runs from bottom to top, and holds the parts of the segments that are visible from the line this sweepline is currently at. Each part also holds the reference to its original segment. The sweepline itself is implemented with a binary search tree.
+
+The events of the sweep are the segments. When a new segment is found, we want to find all the lower segments that we can direct the flow onto from this segment. These can be only the original segments of the parts currently in the sweepline whose projections overlap with this segment. Then we iterate over all such parts *p* (finding the first such part is an  operation). How do we know that we can direct the flow onto *p*? Observe that if there is some segment that prevents this, there should be also a part *q* in the sweepline that also can be seen from the current segment. And since the projections of all three segments overlap, this part can only be directly to the left or to the right of *p* in the binary search tree. So we just check whether the original segments of the two parts next to *p* prevent the flow from the current segment to the original segment of *p*.
+
+Afterwards, we remove all such parts from the sweepline, and insert a new part corresponding to the new segment. If the new segment only partially covered an existing part, we reinsert the remaining portion of that part. There are at most two such portions — one on each side of the segment. Thus each segment inserts at most 3 new parts and the size of the sweepline is *O*(*n*). Each part is handled just once before removal, so the total time of such operations is .
+
+Once we know we can direct the flow through  we can immediately update the maximum downwards flow of *a*:
+
+*f**a* = *max*(*f**a*, *min*(*f**b*, *min*(*r**a*, *r**b*) - *max*(*l**a*, *l**b*)))
+
+When we reach the top, *f**top* will be the answer.
+
+
+
+Time: 
+
+Memory: *O*(*n*)
+
+Implementation: [C++](http://ideone.com/bka28U), [Java](http://ideone.com/frmAwe)
+
+#### Comments
+
+Another problem from our project. You can also first build a graph from the segments using the same sweepline and then find the path with the maximum flow in that graph. In the original problem you have to find this graph and there are no top and bottom segments.
+
+### [Div I E — String Theory](/contest/269/problem/E "269E - String Theory")
+
+#### Problem
+
+In this problem we have an *n* × *m* rectange. Each unit midpoint is connected with a segment to some other midpoint not on the same side of the rectangle. We can change the order of the columns and rows, but the segments must remain attached to their midpoints. We should find such a rearrangement that no two segments intersect, or tell that there is no solution.
+
+#### Solution
+
+There are overall 6 types of segments that connect the sides:
+
+1. left-top;
+2. top-right;
+3. right-bottom;
+4. bottom-left;
+5. left-right;
+6. top-bottom;
+
+If there are both left-right and top-bottom segments, there is no solution. Otherwise there remain only 5 types of segments. Without loss of generality suppose there are no left-right segments. Let’s take a closer look at what should the end picture of the rectangle be:
+
+
+
+All left-top segments should be at the left top corner connecting positions (L,i) and (T,i), otherwise they surely would cross some other segment. Similarly must be positioned top-right, right-bottom, bottom-left segments. Finally, all top-bottom segments should be parallel. We also observe that the number of left-top segments must be equal to the number of right-bottom segments and the number of top-right segments should be equal to the number of bottom-right segments. Thus the important observation: the picture of the end arrangement is unique and can be determined from the input simply by counting the number of segments of each type.
+
+Next we define a cycle to be the sequence of segments, where the second midpoint of some segment in the cycle is equal to the first midpoint in the next segment in the cycle. In the given example there are two such cycles (but the direction of each cycle actually matters):
+
+
+
+Then we observe that the set of the cycles does not change with any permutation by the definition of the cycle. We can make a sketch of the solution: we should find the cycle sets in the given arrangement and in the end arrangement, and compare them for equality.
+
+At this point we actually find all the cycles in both arrangements. There are only two types of cycles:
+
+1. (left-top)  (top-right)  (right-bottom)  (bottom-left);
+2. other cycles.
+
+We can easily check whether the sets of first type cycles match, since the length of such cycles is 4. If they match, we rearrange the columns and rows involved to match the end arrangement.
+
+How to compare the remaining cycles. Consider a following example:
+
+
+
+Let the difference in the number of left-top and left-bottom segments be *i*, and this number plus the number of top-bottom segments *s*. If we enumerate the midpoints as in the figure, we can see that each top midpoint *k* is connected to the bottom midpoint 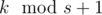 (top-right segments continue as corresponding left-bottom segments). Thus we can describe it as a permutation
+
+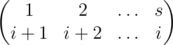
+
+Our cycles correspond to the cycles in this permutation, with top-right segment continuation to left-bottom segment corresponding to the case where permutation cycle element decreases. It is known that the number of such permutations is  and their length is . So all these cycles have the same length. Denote the remaining segment types as some letters (in picture A, B, C). Then not only the length, but the strings describing the cycles are also the same, but can be shifted cyclically (here the direction of the cycles also is important). Besides, we know this string from the correct arrangement cycle. Thus we need to compare all the remaining given arrangement cycle strings to this string, considering cyclic shifts as invariant transformations. For each string this can be done in linear time, for example, using the Knuth-Morris-Pratt algorithm. When we find a cyclical shift for each cycle, we can position its relevant columns and rows according to the end arrangement.
+
+Time: *O*(*n* + *m*).
+
+Memory: *O*(*n* + *m*).
+
+Implementation: [C++](http://ideone.com/bm0GQP), [Java](http://ideone.com/QYJR6c)
+
+#### Comments
+
+This is a total killer task for coding. It took both of us around 5 hours to code the implementation. Congratulations again to [kelvin](/profile/kelvin "Grandmaster kelvin"), at the time of writing still the only one to solve the problem (and of course to anyone who will get this difficult problem accepted =) ).
diff --git a/editorials/271.md b/editorials/271.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/6662
+
+[271A - Beautiful Year](/contest/271/problem/A "Codeforces Round 166 (Div. 2)")
+
+This is a very straight forward problem. Just add 1 to a year number while it still has equal digits.
+
+[271B - Prime Matrix](/contest/271/problem/B "Codeforces Round 166 (Div. 2)")
+
+Precalculate the next prime for every integer from 1 to 105. You can do that in any way. The main thing is to test all the divisors up to square root when you are checking if a number is prime.
+
+Now for each *a**ij* (element of the given matrix) we can easily calculate *add**ij* — how many do we have to add in order to make *a**ij* prime. After that all we need to do is to find row or column with minimal sum in this new matrix.
+
+[271C - Secret](/contest/271/problem/C "Codeforces Round 166 (Div. 2)")
+
+If 3*k* > *n* there is no solution (because each of the *k* sets must have at least 3 elements). Otherwise we can divide first 3*k* words in the following way:
+
+`1 1 2 2 3 3 ... k k 1 2 3 ... k`
+
+For each of the *k* sets, the difference between the first and the second elements will be 1. And the difference between the second and the third elements is definitely not 1 (more precisely, it is 2*k* - *i* - 1 for the *i*-th set). So each set doesn't form an arithmetic progression for sure.
+
+For this solution it doesn't matter how we divide the rest *n* - 3*k* words.
+
+[271D - Good Substrings](/contest/271/problem/D "Codeforces Round 166 (Div. 2)")
+
+At first, build a [trie](https://en.wikipedia.org/wiki/Trie) containing all suffixes of given string (this structure is also called explicit suffix tree). Let's iterate over all substrings in order of indexes' increasing, i. e. first [1...1], then [1...2], [1...3], ..., [1...*n*], [2...2], [2...3], ..., [2...*n*], ... Note, that moving from a substring to the next one is just adding a single character to the end. So we can easily maintain the number of bad characters, and also the "current" node in the trie. If the number of bad characters doesn't exceed *k*, then the substring is good. And we need to mark the corresponding node of trie, if we never did this before. The answer will be the number of marked nodes in the trie.
+
+There is also an easier solution, where instead of trie we use [Rabin-Karp rolling hash](https://en.wikipedia.org/wiki/Rolling_hash) to count substrings that differ by content. Just sort the hashes of all good substrings and find the number of unique hashes (equal hashes will be on adjacent positions after sort). But these hashes are unreliable in general, so it's always better to use precise algorithm.
+
+[271E - Three Horses](/contest/271/problem/E "Codeforces Round 166 (Div. 2)")
+
+It could be proved, that a card (*x*, *y*) (*x* < *y*) can be transformed to any card (1, 1 + *k*·*d*), where *d* is the maximal odd divisor of *y* - *x*, and *k* is just any positive integer. So every (*a**i* - 1) must be divisible by *d*, i. e. *d* is a divisor of *gcd*(*a*1 - 1, ..., *a**n* - 1), and we can just iterate over all possible divisors. Let's take a look at all the initial cards (*x*, *y*), which have have *d* as their maximal odd divisor: these are cards with *y* - *x* equal to *d*, or 2*d*, or 4*d*, 8*d*, 16*d*, ... Don't forget that the numbers *x* and *y* must not exceed *m*. It means that the total number of cards with some fixed difference *t* = *y* - *x* is exactly *m* - *t*.
+
+The resulting solution: sum up (*m* - 2*l**d*), where *d* is any odd divisor of *gcd*(*a*1 - 1, ..., *a**n* - 1), and *l* is such, that 2*l**d* ≤ *m*.
diff --git a/editorials/272.md b/editorials/272.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/6625
+
+[272A - Dima and Friends](/contest/272/problem/A "Codeforces Round 167 (Div. 2)")
+
+We will bruteforce number of fingers that will be show Dima, then if total sum of fingers = 1 modulo (n+1), Dima will clean the room. So we should increase answer if the remaining part after division by (n+1) is not 1.
+
+[272B - Dima and Sequence](/contest/272/problem/B "Codeforces Round 167 (Div. 2)")
+First of all — f(i) is number of ones in binary presentation of number. We will repair all numbers to functions of them. Now we have to find number of pairs of equal numbers. Lets Q[i] — number of numbers with i bits, the answer will be sum of values Q[i]*(Q[i]-1)/2 for all i.
+
+[273A - Dima and Staircase](/contest/273/problem/A "Codeforces Round 167 (Div. 1)")
+Lets L will be the answer after last block, last block was (w1, h1), next block is (w2, h2). Next answer will be max(L+h1, A[w2]), where A — given array. At the beggining we can suppose that L = 0, w1 = 0, h1 = 0.
+
+[273B - Dima and Two Sequences](/contest/273/problem/B "Codeforces Round 167 (Div. 1)")
+Not hard to understand that answer will be (number of numbers with first coordinate = 1)! * (number of numbers with first coordinate = 2)! * ... * (number of numbers with first coordinate = 10^9)!/(2^(number of such i = 1..n, that Ai=Bi)). The only problem was to divide number with non prime modulo, it can be easely done if we will count number of prime mulpiplies=2 in all factorials. Then we can simply substract number that we need and multiply answer for some power of 2.
+
+[273C - Dima and Horses](/contest/273/problem/C "Codeforces Round 167 (Div. 1)")
+Not hard to understand that we have undirected graph. Lets color all vetexes in one color. Then we will find some vertex that is incorrect. We will change color of this vertex, and repeat our search, while it is possible. After every move number of bad edges will be decrease by 1 or 2, so our cycle will end in not more then M operations. So solutions always exists and we need to change some vertex not more then M times, so we will take queue of bad vertexes and simply make all operations of changes.
+
+[273D - Dima and Figure](/contest/273/problem/D "Codeforces Round 167 (Div. 1)")
+Good picture is connected figure that saticfy next condition: most left coordinates in every row of figure vere we have some cells will be almost-ternary, we have the same situation with right side, but here we have another sign. So it is not hard to write dp[i][j1][j2][m1][m2] numbr of figures printed of field size i*m, where last row contain all cells from j1 to j2, the most left coordinate will be m1, the most right coordinate will be m2. But it is not enough. We have to rewrite it in way that m1 will mean — was there some rows j and j+1 that most left coordinate if row j is bigger then most left coordinate in j+1. So now it is not hard to write solution with coplexity O(n*m*m*m*m). But we should optimize transfer to O(1), is can be done using precalculations of sums on some rectangels.
+
+[273E - Dima and Game](/contest/273/problem/E "Codeforces Round 167 (Div. 1)")
+will be added soon.
diff --git a/editorials/273.md b/editorials/273.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/6625
+
+[272A - Dima and Friends](/contest/272/problem/A "Codeforces Round 167 (Div. 2)")
+
+We will bruteforce number of fingers that will be show Dima, then if total sum of fingers = 1 modulo (n+1), Dima will clean the room. So we should increase answer if the remaining part after division by (n+1) is not 1.
+
+[272B - Dima and Sequence](/contest/272/problem/B "Codeforces Round 167 (Div. 2)")
+First of all — f(i) is number of ones in binary presentation of number. We will repair all numbers to functions of them. Now we have to find number of pairs of equal numbers. Lets Q[i] — number of numbers with i bits, the answer will be sum of values Q[i]*(Q[i]-1)/2 for all i.
+
+[273A - Dima and Staircase](/contest/273/problem/A "Codeforces Round 167 (Div. 1)")
+Lets L will be the answer after last block, last block was (w1, h1), next block is (w2, h2). Next answer will be max(L+h1, A[w2]), where A — given array. At the beggining we can suppose that L = 0, w1 = 0, h1 = 0.
+
+[273B - Dima and Two Sequences](/contest/273/problem/B "Codeforces Round 167 (Div. 1)")
+Not hard to understand that answer will be (number of numbers with first coordinate = 1)! * (number of numbers with first coordinate = 2)! * ... * (number of numbers with first coordinate = 10^9)!/(2^(number of such i = 1..n, that Ai=Bi)). The only problem was to divide number with non prime modulo, it can be easely done if we will count number of prime mulpiplies=2 in all factorials. Then we can simply substract number that we need and multiply answer for some power of 2.
+
+[273C - Dima and Horses](/contest/273/problem/C "Codeforces Round 167 (Div. 1)")
+Not hard to understand that we have undirected graph. Lets color all vetexes in one color. Then we will find some vertex that is incorrect. We will change color of this vertex, and repeat our search, while it is possible. After every move number of bad edges will be decrease by 1 or 2, so our cycle will end in not more then M operations. So solutions always exists and we need to change some vertex not more then M times, so we will take queue of bad vertexes and simply make all operations of changes.
+
+[273D - Dima and Figure](/contest/273/problem/D "Codeforces Round 167 (Div. 1)")
+Good picture is connected figure that saticfy next condition: most left coordinates in every row of figure vere we have some cells will be almost-ternary, we have the same situation with right side, but here we have another sign. So it is not hard to write dp[i][j1][j2][m1][m2] numbr of figures printed of field size i*m, where last row contain all cells from j1 to j2, the most left coordinate will be m1, the most right coordinate will be m2. But it is not enough. We have to rewrite it in way that m1 will mean — was there some rows j and j+1 that most left coordinate if row j is bigger then most left coordinate in j+1. So now it is not hard to write solution with coplexity O(n*m*m*m*m). But we should optimize transfer to O(1), is can be done using precalculations of sums on some rectangels.
+
+[273E - Dima and Game](/contest/273/problem/E "Codeforces Round 167 (Div. 1)")
+will be added soon.
diff --git a/editorials/274.md b/editorials/274.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/6759
+
+Hi :)
+
+Here's the editorial for round #168. This time I tried to do my best to prepare a good contest. In some parts I failed but I still learned many things which will surely help me to do better next times! ^.^ I hope you've liked the problems. :)
+
+## [275A - Lights Out](/contest/275/problem/A "Codeforces Round 168 (Div. 2)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+For each light you should count the number of times it’s been toggled. Consider a light is toggled *k* times. If *k* is even then the final state of the light is ‘on’ otherwise it’s ‘off’. The implementation would be easy. You may look at the accepted solutions as reference.
+
+## [275B - Convex Shape](/contest/275/problem/B "Codeforces Round 168 (Div. 2)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+Consider a pair of black cells. There exist at most two different valid paths we can take between these two cells. The naïve solution would be to check the existence of at least one of these paths for each pair of black cells. There are *O*(*n*2*m*2) such pairs and each pair can be checked in *O*(*n* + *m*). So the time complexity will be *O*(*n*2*m*2(*n* + *m*)) which is enough to get accepted.
+
+But there exists a *O*(*nm*) approach. It’s obvious that each row of the grid either doesn’t have any black cell or the black cells are a consecutive part of the row. The same holds for every column. For every non-empty row consider the interval of its black cells. The intersection of intervals of all non-empty rows should be non-empty. If the same holds for all columns then our grid is convex. The proof of this solution is not hard and is left for the reader.
+
+## [274A - k-Multiple Free Set](/contest/274/problem/A "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+Consider an integer *x* which is divisible by *k*. At most one of the integers *x* and *x* / *k* can appear in the maximum *k*-multiple free subset. Also for any integer *y* at most one of the numbers *y* and *yk* appears in the answer. If you look like this you can see the input as chains of numbers so that for each chain no two adjacent elements can appear in the output. For example, If *k* = 2 then 6, 12, 24, 48, 96 forms a chain. It’s easy to see that from a chain of length *l* we can choose at most (*l* + 1) / 2 elements in the answer. So the solution would be to compute the lengths of the chains and pick as much numbers as we can from each chain. You can sort all the numbers and do binary search or similar things to find the length of chains. Here’s a cute greedy solution which picks numbers greedily from the chains:
+
+First sort all the numbers. Also consider an empty set of integers *S*, which represents the output. For each integer *x* in the sequence, If it’s not divisible by *k*, just pick it and insert it into *S*. Otherwise if it’s divisible by *k* check if *x* / *k* is in *S* or not. If it’s not in *S* insert *x* into *S* otherwise skip *x*.
+
+I’d also like to note that this problem comes from an old problem in UVa Online Judge, with the same the name.
+
+## [274B - Zero Tree](/contest/274/problem/B "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+In the problem statement vertex 1 is not mentioned as root of the tree. But it seems if we make it the root of the tree we can figure out the solution easier. For the leaves of the tree we can see the least number of steps needed to make each of them equal to zero. Consider a vertex which all its children are leaves. The minimum number of times that we should increase this vertex is at least as the maximum times one of the children of this vertex is increased. Also the minimum number of times this vertex is decreased is at least as maximum times one of the children of this vertex is decreased. Now we know some necessary plus or minus steps that this vertex is included in them. So after all of the children of this vertex reached zero, this vertex itself has some new value. If the current value of the vertex is positive we should decrease this vertex certain times otherwise we should decrease it. So we can find the minimum number of times this vertex should be decreased and the minimum number of times this vertex should be increased. As we showed above if we know these pair of numbers for each child of a vertex then we can calculate these numbers for that vertex too.
+
+This can be implemented using a simple DFS on the rooted tree. And the answer to the problem would be the sum of increments and decrements of vertex 1. The time complexity of the solution is *O*(*n*).
+
+## [274C - The Last Hole!](/contest/274/problem/C "Codeforces Round 168 (Div. 1)")
+
+Author: [haas](/profile/haas "Candidate Master haas")
+
+In the solution we will try to find the position of all points which are the last moments in holes. Here we claim that each minimal potential hole is one of these two forms:
+
+1. For each three centers that form an acute triangle it’s obvious that they form a potential hole. The last point in this hole would be the in triangle’s circumcenter.
+2. For each four centers which are sides of a square it’s also obvious there’s a potential hole with last point being the square’s center.
+
+For each potential hole we should check if the last point is not covered with any other circle in the last moment. The solution would be the hole with maximum distance from the centers which won’t be covered by anything else.
+
+Let’s remind some geometry facts. We know that circumcenter of a triangle is the point where the three perpendicular bisectors of the triangle meet. Also the circumcenter of the triangle lies inside the triangle if and only if the triangle is acute. Circumcenter is the point which has equal distance from each vertex of the triangle.
+
+Using above information it’s easy to prove that three circles make a hole if and only if the triangle they form is acute. Now what remains is to prove that in the last moment which the hole is disappearing there are 3 triangles or four forming a square enclosing the hole. I’m not going into details but the proof would be like this. Consider the last point of a hole. There are some circles which form the border of the hole in the last moment. These centers have the same distance from the last point. We need to prove that only three of the centers or four of them which form a square do the same job. And all others can be ignored. Consider the circle which these centers lie on its perimeter. Here’s a way to pick at most four of these points which make that hole. As long as there are three consecutive points which form make a obtuse triangle delete the middle point (why?). It’s easy to see what will remain at the end is either a square or an acute triangle.
+
+The implementation can be done in *O*(*n*4) with iterating through all triangles in *O*(*n*3) and checking them in *O*(*n*). Also there are at most *O*(*n*3) squares, because once you’ve picked three of its vertices the fourth will be unique.
+
+We’ve seen other coders implementing this solution or other solutions in better time complexities. So please share your solutions in the comments. :)
+
+## [274D - Lovely Matrix](/contest/274/problem/D "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+The naïve solution for this problem would be to make a graph were each vertex represents a column of the grid. Then for each two not erased integers *x* and *y* in the same row where *x* < *y* we can add an edge from the column of *x* to the column of *y* in our graph. Then topological sorting on the built graph would give us the sought order of the rows. But there can be as much as O(m^2) edges in our graph and thus a *O*(*nm*2) solution won’t pass the time limit.
+
+But still the idea to solve this problem is to implement topological sort in a such way that the graph we make has less edges or to make less processing to find the topological sort. Here I present two solutions which use topological sorting. One implements topological sorting explicitly in a graph of columns as its vertices with some extra vertices but fewer edges. The other one does some kind of topological sorting without building the graph and by deciding which column can come as the first column of our ordering, and doing the same thing until all columns come in order.
+
+The first solution relies on decreasing the number of edges we used in the graph of our naïve solution. Consider the numbers of a row sorted. We insert an extra vertex between each pair of adjacent different numbers. Then each column gets connected to the next extra vertex and each extra vertex gets connected to the columns before the next extra vertex. In this way the sorted order of this row would be preserved in topological sorting. We do the same thing for each row, so topological sort on the final graph would give us the sought ordering of columns. This can be implemented in *O*(*nmlgm*).
+
+In the second solution for each row we color all the minimum not erased elements of that row. The first column in the output permutation should be a column where all of its non erased elements are colored. So we put this column as the first column. Now the rest of the columns can be ordered by the same way. If at some point we can’t find a suitable column then there’s no solution. This also can be implemented in *O*(*nmlgm*).
+
+It seems the problem was easier than a usual D problem, but before the contest I didn’t think so. I myself found the idea to solve this problem after some time, so I thought it wouldn’t be suitable for a C. Any ideas on how to measure the hardness of a problem better for next times? Because it doesn’t feel so good not to see the problems solved according to the foreseen difficulty level! :D
+
+## [274E - Mirror Room](/contest/274/problem/E "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+The blocked cells can make lots of complicated patterns. So it’s obvious that the solution in includes simulating the path the laser beam goes. But the dimensions of the gird are large and the beam might travel a long path before entering a loop. So naïve simulation will surely time out (See note!).
+
+It’s kind of obvious that the beam finally comes back to its initial position and direction. Here were going to prove that the maximum number of times the beam might reflect until it reaches its first state is *O*(*n* + *m* + *k*). Consider an empty grid, It has *O*(*n* + *m*) maximal empty diagonal segments. When we block a cell, the two diagonal segments which pass this cell split. So the number of maximal empty diagonal segments increases by two. There for there are *O*(*n* + *m* + *k*) of these segments. Also If you look at the behavior of the beam it passes some of the segments one after another. So if you simulate the beam, it reflects *O*(*n* + *m* + *k*) times. Instead of naïve simulation we can find the next position the beam reflects.
+
+Now we’re going to prove that no cell will be visited twice. A cell gets visited twice in the cycle if we pass it in both NE-SW direction and NW-SE direction. Consider the grid colored in black and white like a chessboard. There are two types of diagonal segments the NE-SW ones and NW-SE ones (property 1). At each reflection we alternate between these two. Also there are two types of segments in another way, black segments and white segments (property 2). As you can see each time one of the properties changes the other one also changes. As a result we’ll never pass a black cell in both directions, and the same is for a white cell.
+
+So this problem can be solved with simulation in *O*((*n* + *m* + *k*)*lgk*).
+
+You'd like to read [Petr](/profile/Petr "International Grandmaster Petr")'s solution for a clean implementation of this approach. [3162462](/contest/274/submission/3162462 "Submission 3162462 by Petr")
+
+**Note:** The random tests I had generated before the contest were weak and I didn’t notice that naïve simulation solutions would pass the test. Now the tests are more powerful. :)
diff --git a/editorials/275.md b/editorials/275.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/6759
+
+Hi :)
+
+Here's the editorial for round #168. This time I tried to do my best to prepare a good contest. In some parts I failed but I still learned many things which will surely help me to do better next times! ^.^ I hope you've liked the problems. :)
+
+## [275A - Lights Out](/contest/275/problem/A "Codeforces Round 168 (Div. 2)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+For each light you should count the number of times it’s been toggled. Consider a light is toggled *k* times. If *k* is even then the final state of the light is ‘on’ otherwise it’s ‘off’. The implementation would be easy. You may look at the accepted solutions as reference.
+
+## [275B - Convex Shape](/contest/275/problem/B "Codeforces Round 168 (Div. 2)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+Consider a pair of black cells. There exist at most two different valid paths we can take between these two cells. The naïve solution would be to check the existence of at least one of these paths for each pair of black cells. There are *O*(*n*2*m*2) such pairs and each pair can be checked in *O*(*n* + *m*). So the time complexity will be *O*(*n*2*m*2(*n* + *m*)) which is enough to get accepted.
+
+But there exists a *O*(*nm*) approach. It’s obvious that each row of the grid either doesn’t have any black cell or the black cells are a consecutive part of the row. The same holds for every column. For every non-empty row consider the interval of its black cells. The intersection of intervals of all non-empty rows should be non-empty. If the same holds for all columns then our grid is convex. The proof of this solution is not hard and is left for the reader.
+
+## [274A - k-Multiple Free Set](/contest/274/problem/A "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+Consider an integer *x* which is divisible by *k*. At most one of the integers *x* and *x* / *k* can appear in the maximum *k*-multiple free subset. Also for any integer *y* at most one of the numbers *y* and *yk* appears in the answer. If you look like this you can see the input as chains of numbers so that for each chain no two adjacent elements can appear in the output. For example, If *k* = 2 then 6, 12, 24, 48, 96 forms a chain. It’s easy to see that from a chain of length *l* we can choose at most (*l* + 1) / 2 elements in the answer. So the solution would be to compute the lengths of the chains and pick as much numbers as we can from each chain. You can sort all the numbers and do binary search or similar things to find the length of chains. Here’s a cute greedy solution which picks numbers greedily from the chains:
+
+First sort all the numbers. Also consider an empty set of integers *S*, which represents the output. For each integer *x* in the sequence, If it’s not divisible by *k*, just pick it and insert it into *S*. Otherwise if it’s divisible by *k* check if *x* / *k* is in *S* or not. If it’s not in *S* insert *x* into *S* otherwise skip *x*.
+
+I’d also like to note that this problem comes from an old problem in UVa Online Judge, with the same the name.
+
+## [274B - Zero Tree](/contest/274/problem/B "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+In the problem statement vertex 1 is not mentioned as root of the tree. But it seems if we make it the root of the tree we can figure out the solution easier. For the leaves of the tree we can see the least number of steps needed to make each of them equal to zero. Consider a vertex which all its children are leaves. The minimum number of times that we should increase this vertex is at least as the maximum times one of the children of this vertex is increased. Also the minimum number of times this vertex is decreased is at least as maximum times one of the children of this vertex is decreased. Now we know some necessary plus or minus steps that this vertex is included in them. So after all of the children of this vertex reached zero, this vertex itself has some new value. If the current value of the vertex is positive we should decrease this vertex certain times otherwise we should decrease it. So we can find the minimum number of times this vertex should be decreased and the minimum number of times this vertex should be increased. As we showed above if we know these pair of numbers for each child of a vertex then we can calculate these numbers for that vertex too.
+
+This can be implemented using a simple DFS on the rooted tree. And the answer to the problem would be the sum of increments and decrements of vertex 1. The time complexity of the solution is *O*(*n*).
+
+## [274C - The Last Hole!](/contest/274/problem/C "Codeforces Round 168 (Div. 1)")
+
+Author: [haas](/profile/haas "Candidate Master haas")
+
+In the solution we will try to find the position of all points which are the last moments in holes. Here we claim that each minimal potential hole is one of these two forms:
+
+1. For each three centers that form an acute triangle it’s obvious that they form a potential hole. The last point in this hole would be the in triangle’s circumcenter.
+2. For each four centers which are sides of a square it’s also obvious there’s a potential hole with last point being the square’s center.
+
+For each potential hole we should check if the last point is not covered with any other circle in the last moment. The solution would be the hole with maximum distance from the centers which won’t be covered by anything else.
+
+Let’s remind some geometry facts. We know that circumcenter of a triangle is the point where the three perpendicular bisectors of the triangle meet. Also the circumcenter of the triangle lies inside the triangle if and only if the triangle is acute. Circumcenter is the point which has equal distance from each vertex of the triangle.
+
+Using above information it’s easy to prove that three circles make a hole if and only if the triangle they form is acute. Now what remains is to prove that in the last moment which the hole is disappearing there are 3 triangles or four forming a square enclosing the hole. I’m not going into details but the proof would be like this. Consider the last point of a hole. There are some circles which form the border of the hole in the last moment. These centers have the same distance from the last point. We need to prove that only three of the centers or four of them which form a square do the same job. And all others can be ignored. Consider the circle which these centers lie on its perimeter. Here’s a way to pick at most four of these points which make that hole. As long as there are three consecutive points which form make a obtuse triangle delete the middle point (why?). It’s easy to see what will remain at the end is either a square or an acute triangle.
+
+The implementation can be done in *O*(*n*4) with iterating through all triangles in *O*(*n*3) and checking them in *O*(*n*). Also there are at most *O*(*n*3) squares, because once you’ve picked three of its vertices the fourth will be unique.
+
+We’ve seen other coders implementing this solution or other solutions in better time complexities. So please share your solutions in the comments. :)
+
+## [274D - Lovely Matrix](/contest/274/problem/D "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+The naïve solution for this problem would be to make a graph were each vertex represents a column of the grid. Then for each two not erased integers *x* and *y* in the same row where *x* < *y* we can add an edge from the column of *x* to the column of *y* in our graph. Then topological sorting on the built graph would give us the sought order of the rows. But there can be as much as O(m^2) edges in our graph and thus a *O*(*nm*2) solution won’t pass the time limit.
+
+But still the idea to solve this problem is to implement topological sort in a such way that the graph we make has less edges or to make less processing to find the topological sort. Here I present two solutions which use topological sorting. One implements topological sorting explicitly in a graph of columns as its vertices with some extra vertices but fewer edges. The other one does some kind of topological sorting without building the graph and by deciding which column can come as the first column of our ordering, and doing the same thing until all columns come in order.
+
+The first solution relies on decreasing the number of edges we used in the graph of our naïve solution. Consider the numbers of a row sorted. We insert an extra vertex between each pair of adjacent different numbers. Then each column gets connected to the next extra vertex and each extra vertex gets connected to the columns before the next extra vertex. In this way the sorted order of this row would be preserved in topological sorting. We do the same thing for each row, so topological sort on the final graph would give us the sought ordering of columns. This can be implemented in *O*(*nmlgm*).
+
+In the second solution for each row we color all the minimum not erased elements of that row. The first column in the output permutation should be a column where all of its non erased elements are colored. So we put this column as the first column. Now the rest of the columns can be ordered by the same way. If at some point we can’t find a suitable column then there’s no solution. This also can be implemented in *O*(*nmlgm*).
+
+It seems the problem was easier than a usual D problem, but before the contest I didn’t think so. I myself found the idea to solve this problem after some time, so I thought it wouldn’t be suitable for a C. Any ideas on how to measure the hardness of a problem better for next times? Because it doesn’t feel so good not to see the problems solved according to the foreseen difficulty level! :D
+
+## [274E - Mirror Room](/contest/274/problem/E "Codeforces Round 168 (Div. 1)")
+
+Author: [havaliza](/profile/havaliza "Candidate Master havaliza")
+
+The blocked cells can make lots of complicated patterns. So it’s obvious that the solution in includes simulating the path the laser beam goes. But the dimensions of the gird are large and the beam might travel a long path before entering a loop. So naïve simulation will surely time out (See note!).
+
+It’s kind of obvious that the beam finally comes back to its initial position and direction. Here were going to prove that the maximum number of times the beam might reflect until it reaches its first state is *O*(*n* + *m* + *k*). Consider an empty grid, It has *O*(*n* + *m*) maximal empty diagonal segments. When we block a cell, the two diagonal segments which pass this cell split. So the number of maximal empty diagonal segments increases by two. There for there are *O*(*n* + *m* + *k*) of these segments. Also If you look at the behavior of the beam it passes some of the segments one after another. So if you simulate the beam, it reflects *O*(*n* + *m* + *k*) times. Instead of naïve simulation we can find the next position the beam reflects.
+
+Now we’re going to prove that no cell will be visited twice. A cell gets visited twice in the cycle if we pass it in both NE-SW direction and NW-SE direction. Consider the grid colored in black and white like a chessboard. There are two types of diagonal segments the NE-SW ones and NW-SE ones (property 1). At each reflection we alternate between these two. Also there are two types of segments in another way, black segments and white segments (property 2). As you can see each time one of the properties changes the other one also changes. As a result we’ll never pass a black cell in both directions, and the same is for a white cell.
+
+So this problem can be solved with simulation in *O*((*n* + *m* + *k*)*lgk*).
+
+You'd like to read [Petr](/profile/Petr "International Grandmaster Petr")'s solution for a clean implementation of this approach. [3162462](/contest/274/submission/3162462 "Submission 3162462 by Petr")
+
+**Note:** The random tests I had generated before the contest were weak and I didn’t notice that naïve simulation solutions would pass the test. Now the tests are more powerful. :)
diff --git a/editorials/276.md b/editorials/276.md
@@ -0,0 +1,139 @@
+Source: https://codeforces.com/blog/entry/6779
+
+[**A. Lunch Rush**](//codeforces.com/contest/276/problem/A)
+
+Let’s look at all restraunts, where Rabbits can have their lunch. Let’s calculate the answer for all restraunts and choose the maximulm value among of them. We need to use formula descrbed in problem statement to calculate the answer for some particular restraunt. Time complexity of this solution is *O*(*N*).
+
+[C++ code](http://pastebin.com/cJK5K017)
+
+[Java code](http://pastebin.com/D800mDax)
+
+[**B. Little Girl and Game**](//codeforces.com/contest/276/problem/B)
+
+Let’s calculate the number of letters with odd number of occurrences in *s*. Let this value be equal to *k*.
+
+If *k* = 0, then first player can win immediately: he can easily build palindrome, placing equal letters in different sides of resulting string (he always can do it, because total number of all letters is even).
+
+If *k* = 1 then first player can win immediately again; at first he builds palindrome from letters with even number of occurrences in *s*; after that he inserts the rest of the letters in the middle of built in previous step string.
+
+Let’s proof very useful statement. If *k* > 1 our problem has the following solution: if *k* is even, than second player is winner; otherwise, first player is winner.
+
+Let *k* = 2. At the beginning of the game first player can make move of two types.
+
+Using move of first type first player can decrease *k* to 1 by erasing one appearance of letter with odd number of occurrences. But this move leads him to defeat, because after this move second player can build palindrome.
+
+Using move of second type first player can increase *k* to 3 by erasing one appearance of letter with even number of occurrences. In this case second player can make similar move — he will erase the same letter. Since the number of moves of this type is finite, sooner or later first player will have to make a move of first type. After this move he loses immediately.
+
+So, if *k* = 2, than second player is a winner.
+
+Let *k* = 3. First player can decrease *k* to 2 by erasing the letter with odd number of occurrences. If second player will try to increase *k* to 3 again by erasing the similar letter, first player can decrease *k* to 2 again (he erases the same letter again). It’s easy to see that the last move in this sequence of moves will be the move of first player. So, first player always can change the game in such a way that *k* = 2. This position is losing position for second player and winning position for first player.
+
+Now we can easily proof our statement for any *k* using mathematical induction.
+
+So, we have quite easy solution with time complexity *О*(|*S*|).
+
+[C++ code](http://pastebin.com/FMDivpxx)
+
+[Java code](http://pastebin.com/AR641CLa)
+
+[**C. Little Girl and Maximum Sum**](//codeforces.com/contest/276/problem/C)
+
+Lets calculate for each cell of the initial array the number of queries that cover this cell. It’s claimed, that we should associate the cell with bigger value to the cell with bigger value in initial array. More formally: suppose *b* is an array, in *i* - *th* cell of which is written the number of queries that cover *i* - *th* cell. Suppose *а* is an initial array. Let’s sort those arrays. It’s claimed, that the answer in this case can be calculated with following formula: 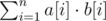
+
+Let’s proof this statements. We will take a look at some indexes *i* < *j*, and at elements, corresponding to shis indexes *a*[*i*], *a*[*j*] , *b*[*i*], *b*[*j*] (*a*[*i*] ≤ *a*[*j*], *b*[*i*] ≤ *b*[*j*]). Those elements add to the answer the following value: *a*[*i*]·*b*[*i*] + *a*[*j*]·*b*[*j*]. Let’s swap *a*[*i*] and *a*[*j*]. Now those elements elements add to the answer the following value *a*[*i*]·*b*[*j*] + *a*[*j*]·*b*[*i*]. Let’s take a look at the following difference:
+
+*a*[*i*]·*b*[*j*] + *a*[*j*]·*b*[*i*] - *a*[*i*]·*b*[*i*] - *a*[*j*]·*b*[*j*] = *b*[*j*]·(*a*[*i*] - *a*[*j*]) + *b*[*i*]·(*a*[*j*] - *a*[*i*]) = (*b*[*j*] - *b*[*i*])·(*a*[*i*] - *a*[*j*]) ≤ 0.
+
+So, swapping of two elements leads us to nonincreasing of the total result. This means, that our arrangement is optimal.
+
+Now we need to calculate array *b* fast enough.
+
+For this purpose one can use different data structures, which support segment modifications (segment tree, Cartesian tree and so on). But there exists much easier method.
+
+Let’s create some array *d*. When we have query *l**i*, *r**i*, we should increase value *d*[*l**i*] by 1 and decrease value *d*[*r**i* + 1] by 1. In such a tricky way we increase all elements in segment [*l**i*;*r**i*] by 1 After processing all of the queries we need to make a loop, which visit every element of array *d*. In this loop we can easily calculate all elements of array *b*.
+
+Now we are ready to get the final answer. The complexity of author’s solution is *O*(*NlogN* + *Q*)
+
+[C++ code](http://pastebin.com/XL7hmXfp)
+
+[Java code](http://pastebin.com/kwFK35YC)
+
+**[D. Little Girl and Maximum XOR](https://codeforces.com/contest/276/problem/D)**
+
+To be honest, I am surprised that problem D had so many accepted solution during the contest. The author’s solution uses dynamic programming. In this editorial I’ll explain this solution.
+
+First of all we should convert *L* and *R* to the binary numeral system. Now we can solve our problem with dynamic programming, using the following state *d*[*p*][*fl*1][*fr*1][*fl*2][*fr*2], where *p* is current position in binary representation of our numbers *a* and *b* (this parameter is in range from 0 to number of bits in *R*), *fl* (0 or 1) is a variable, which shows if current value of *а* is strictly greater than *L*, *fr*1 (от 0 до 1) is a variable, which shows if current value of *а* is strictly less then *R*, *fl*2, *fr*2 are variables, which show the similar things for *b*.
+
+Let’s use recursion with memorization for our solution.
+
+Let’s define the base of recursion. If we have looked through all the bits, we should return 0.
+
+Let’s define a recursive transition. We need to know, which bits we can place into binary representation of number *а* in *p*-th position. We can place 0 if the following condition is true: *p*-th bit of *L* is equal to 0, or *p*-th bit of *L* is equal to 1 and variable *fl*1 shows that current value of *a* is strictly greater then *L*. Similarly, we can place 1 if the following condition is true: *p*-th bit of *R* is equal to 1, or *p*-th bit of *R* is equal to 0 and variable *fr*1 shows that current value of *a* is strictly less then *R*. Similarly, we can obtain, which bits we can place into binary representation of number *b* in *p*-th position.
+
+Let’s iterate through all possible bits’ values and check the result of xor operation. If it is equal to 1, we should add to the answer corresponding power of 2. We also need carefully recalculate values of variables *fl*1, *fr*1, *fl*2, *fr*2. We should choose maximum answer from all valid options.
+
+Initial state for our recursion is (*P*,0,0,0,0), where *P* is number of bits in *R*.
+
+I hope, my code will clarify all the obscure points.
+
+I also want to say, that this approach is in some sense universal and can be applied to many similar problems, [like this one](//codeforces.com/contest/261/problem/C)
+
+The complexity of algorithm is *O*(*logR*)
+
+[C++ code](http://pastebin.com/T58pdAzc)
+
+[Java code](http://pastebin.com/t3cTWuCn)
+
+In Russian thread I saw another really nice solution, so I decided to include this solution to the editorial.
+
+First of all, if *L* = *R*, than the answer is 0.
+
+Now let’s consider case with *L* ≠ *R*. Let *R**i* be the *i*-th bit of *R*, *L**i* be the *i*-th bit of *L*. Let’s define *p* as largest number such as *R**p* ≠ *L**p* (we use 0-based indexation). Let’s take a look at all numbers in range [*L*;*R*]. It’s easy to see, that bits, that are higher than bit with index *p* are equal for all this numbers. Thus, those bits can not affect our answer, because their xor will always equal to 0.
+
+Let’s build numbers *a* and *b* in the following way:
+
+1) *a*: bits which are higher than bit with index *p* are equal to the corresponding bits of *L*, *p*-th bit is equal to 0, the rest of bits are equal to 1.
+
+1) *b*: bits which are higher than bit with index *p* are equal to the corresponding bits of *L*, *p*-th bit is equal to 1, the rest of bits are equal to 0.
+
+It’s easy to see, that *a* and *b* both lie in range [*L*;*R*]. It’s also easy to see, that xor of this numbers sets all bits, that are not higher than bit with index *p* to 1. So, our answer is maximum possible and is equal to 2*p* + 1 - 1
+
+The complexity of algorithm is *O*(*logR*)
+
+[Java solution](https://codeforces.com/contest/276/submission/3184866) from [AlexanderBolshakov](/profile/AlexanderBolshakov "Candidate Master AlexanderBolshakov")
+
+We can iterate through value of *p* using binary search. We can achieve time complexity *O*(*log*(*logR*)) in this way, but it wasn’t required during the contest.
+
+**[E. Little Girl and Problem on Trees](//codeforces.com/contest/276/problem/E)**
+
+One can see, that our tree is a set of chains, each of which starts in the root.
+
+First of all we need to decompose our tree in chains using, for example, depth first search. For each vertex we should find out it’s depth and number of chain, which contain this vertex. For each chain we’ll use some data structure, which can fast enough change it’s elements and fast enough answer to the range sum query. For example, we canuse Binary Indexed Tree (BIT). We also need to create one BIT for root. This BIT is global: it’s information is actual for all the chains
+
+Let’s remember problem *С*. In that problem we used array *d* for processing all the queries. We need to know values of elements of array *b* in that problem after processing all the queries. In this problem queries are online. That’s why we need to use BIT; it allows to change element and answer range sum query in *O*(*logN*) time.
+
+Let’s learn, how to process queries, which require modification and queries, which require finding the element, using BIT.
+
+BIT can make two types of operations:
+
+*add*(*x*, *y*) — add value *y* to element with index *x*
+
+*find*(*x*) – finds sum in range from 1 to *x*
+
+Let’s consider, that we need to add value *val* to all elements in range from *l* to *r* . Than we should just make operations *add*(*l*, *val*) and *add*(*r* + 1, - *val*).
+
+Let’s consider, that we have query which require printing the value of element with index *v*. Then we should just make operation *find*(*v*).
+
+Now let’s go back to the initial problem.
+
+During the processing query of type 0 we should check, if it affects the root. If query affects the root, we should carefully process this query in our chain and make necessary changes in root’s BIT. Otherwise we just process query in our chain.
+
+During the processing query of type 1 we should just find corresponding sums in root’s BIT and in BIT for our chain. We should print the sum of this values.
+
+Time complexity of this solution is *O*(*N* + *QlogN*)
+
+[C++ code](http://pastebin.com/w8ybNR2z)
+
+[Java code](http://pastebin.com/NDt1DXyx)
+
+That’s all. I’ll be very glad to answer to your question in comments.
diff --git a/editorials/277.md b/editorials/277.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/6815
+
+[278B - New Problem](/contest/278/problem/B "Codeforces Round 170 (Div. 2)")
+
+The total number of different strings of 2 letters is 262 = 676, but the total length of the input strings is no more than 600. It means that the length of answer is no more than 2. So just check all the strings of length 1 and 2.
+
+[277A - Learning Languages](/contest/277/problem/A "Codeforces Round 170 (Div. 1)")
+
+Build bipartite graph with *n* nodes for employees and *m* nodes for languages. If an employee initially knows a language, than there will be an edge between corresponding nodes. Now the problem is simple: add the minimal number of edges in such a way, that all the *n* employees will be in the same connected component. Obviously, this number equals to the number of initially connected components, containing at least one employee, minus one. But there is one exception (pretest #4): if initially everyone knows no languages, we'll have to add *n* edges, because we can't add the edges between employees (remember that the graph is bipartite).
+
+[277B - Set of Points](/contest/277/problem/B "Codeforces Round 170 (Div. 1)")
+
+For *m* = 3, *n* = 5 and *m* = 3, *n* = 6 there is no solution.
+
+Let's learn how to construct the solution for *n* = 2*m*, where *m* ≥ 5 and is odd. Set up *m* points on a circle of sufficiently large radius. This will be the inner polygon. The outer polygon will be the inner polygon multiplied by 2. More precisely (1 ≤ *i* ≤ *m*):
+
+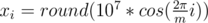
+
+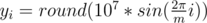
+
+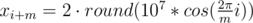
+
+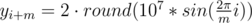
+
+If *m* is even, construct the solution for *m* + 1 and then delete one point from each polygon. If *n* < 2*m*, delete 2*m* - *n* points from the inner polygon.
+
+Unfortunately, this solution doesn't work for *m* = 4, *n* = 7 and *m* = 4, *n* = 8.
+
+Another approach is to set up *m* points on a convex function (for example, *y* = *x*2 + 107), and set up the rest *n* - *m* points on a concave function (for example, *y* = - *x*2 - 107). Take a look at [rng_58](/profile/rng_58 "Legendary Grandmaster rng_58")'s solution — [3210150](/contest/277/submission/3210150 "Submission 3210150 by rng_58").
+
+[277C - Game](/contest/277/problem/C "Codeforces Round 170 (Div. 1)")
+
+At first, notice that horizontal and vertical cuts are independent. Consider a single horizontal line. It contains *m* unit segments. And in any game state it's always possible to decrease the number of uncut units as the player wants. Imagine, that she starts growing a segment from a border, increasing it's length by 1 at a time. Each time the total uncut length decreases by either 0 or 1. In the end it obviously reaches 0.
+
+The same holds for vertical lines as well. So if there are no initial cuts, the game is a nim with *n* - 1 piles of *m* stones and *m* - 1 piles of *n* stones. Could be solved with simple formula.
+
+Initial *k* cuts should be just a technical difficulty. For any vertical/horizontal line, which contains at least one of the cuts, it's pile size should be decreased by the total length of all segments on this line.
+
+How to make a first move in nim: let *res* is the result of state (grundy function), and *a**i* is the size of the *i*-th pile. Then the result of the game without *i*-th pile is . We want to replace *a**i* with some *x*, so that 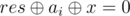. Obviously, the only possible . The resulting solution: find a pile for which 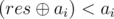, and decrease it downto .
+
+[277D - Google Code Jam](/contest/277/problem/D "Codeforces Round 170 (Div. 1)")
+
+Suppose we have fixed set of inputs that we have to solve. Let's learn how to determine the optimal order. Obviously, Small inputs (and Large inputs with *probFail* = 0) won't fail in any case. It means that our penalty time is no less than submission time of last such ``safe'' inputs. So we will solve such inputs before all the others. Inputs with *probFail* = 1 are just a waste of time, we won't solve such inputs. Now we have only inputs with 0 < *probFail* < 1. Let *i* and *j* be two problems that we are going to solve consecutively at some moment. Let's check, if it is optimal to solve them in order *i*, *j*, or in reversed order. We can discard all the other inputs, because they don't affect on the relative order of these two.
+
+(*timeLarge**i* + *timeLarge**j*)(1 - *probFail**j*) + *timeLarge**i*(1 - *probFail**i*)*probFail**j* < (*timeLarge**i* + *timeLarge**j*)(1 - *probFail**i*) + *timeLarge**j*(1 - *probFail**j*)*probFail**i*
+
+ - *probFail**j*·*timeLarge**j* - *timeLarge**i*·*probFail**j*·*probFail**i* < - *probFail**i*·*timeLarge**i* - *timeLarge**j*·*probFail**i*·*probFail**j*
+
+*timeLarge**i*·*probFail**i*(1 - *probFail**j*) < *timeLarge**j*·*probFail**j*(1 - *probFail**i*)
+
+*timeLarge**i*·*probFail**i* / (1 - *probFail**i*) < *timeLarge**j*·*probFail**j* / (1 - *probFail**j*)
+
+Now we've got a comparator for sort, which will give us the optimal order. Note, that inputs with *probFail* = 0, 1 will be sorted by the comparator correctly as well, so it's not a corner case.
+
+Let's return to the initial problem. First of all, sort problems with the optimal comparator (it's clear that any other order won't be optimal by time, and the score doesn't depend on the order). Calculate the DP: *z*[*i*][*j*] = pair of maximal expected total score and minimal expected penalty time with this score, if we've already decided what to do with the first *i* problems, and we've spent *j* real minutes from the contest's start. There are 3 options for the *i*-the problem:
+
+1. skip: update *z*[*i* + 1][*j*] with the same expected values
+2. solve the Small input: update *z*[*i* + 1][*j* + *timeSmall**i*], the expected total score increases by *scoreSmall**i*, and the expected penalty time increases by *timeSmall**i* (we assume that this input is solved in the very beggining of the contest)
+3. solve both inputs: update *z*[*i* + 1][*j* + *timeSmall**i* + *timeLarge**i*], the expected total score increases by *scoreSmall**i* + (1 - *probFail**i*)*scoreLarge**i*, and the expected penalty time becomes *timeSmall**i* + (1 - *probFail**i*)(*j* + *timeLarge**i*) + *probFail**i*·*penaltyTime*(*z*[*i*][*j*]), where *penaltyTime*(*z*[*i*][*j*]) is the expected penalty time from DP
+
+The resulting answer is the best of *z*[*n*][*i*], (0 ≤ *i* ≤ *t*).
+
+The expected total score could be a number around 1012 with 6 digits after decimal point. So it can't be precisely stored in double. And any (even small) error in calculating score may lead to completely wrong expected time (pretest #7). For example, you can multiply all the probabilities by 106 and store the expected score as integer number to avoid this error.
+
+[277E - Binary Tree on Plane](/contest/277/problem/E "Codeforces Round 170 (Div. 1)")
+
+If there is no "binary" restriction, the solution is simple greedy. Each node of the tree (except the root) must have exactly 1 parent, and each node could be parent for any number of nodes.
+
+Let's assign for each node *i* (except the root) such a node *p**i* as a parent, so that *y**p**i* > *y**i* and distance between *i* and *p**i* is minimal possible. Renumerate all the nodes in order of non-increasing of *y*. Now it's clear that *p**i* < *i* (2 ≤ *i* ≤ *n*). So we've just built a directed tree with all the arcs going downwards. And it has minimal possible length.
+
+Let's recall the "binary" restriction. And realize that it doesn't really change anything: greedy transforms to min-cost-max-flow on the same distance matrix as edge's costs, but each node must have no more than 2 incoming flow units.
diff --git a/editorials/278.md b/editorials/278.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/6815
+
+[278B - New Problem](/contest/278/problem/B "Codeforces Round 170 (Div. 2)")
+
+The total number of different strings of 2 letters is 262 = 676, but the total length of the input strings is no more than 600. It means that the length of answer is no more than 2. So just check all the strings of length 1 and 2.
+
+[277A - Learning Languages](/contest/277/problem/A "Codeforces Round 170 (Div. 1)")
+
+Build bipartite graph with *n* nodes for employees and *m* nodes for languages. If an employee initially knows a language, than there will be an edge between corresponding nodes. Now the problem is simple: add the minimal number of edges in such a way, that all the *n* employees will be in the same connected component. Obviously, this number equals to the number of initially connected components, containing at least one employee, minus one. But there is one exception (pretest #4): if initially everyone knows no languages, we'll have to add *n* edges, because we can't add the edges between employees (remember that the graph is bipartite).
+
+[277B - Set of Points](/contest/277/problem/B "Codeforces Round 170 (Div. 1)")
+
+For *m* = 3, *n* = 5 and *m* = 3, *n* = 6 there is no solution.
+
+Let's learn how to construct the solution for *n* = 2*m*, where *m* ≥ 5 and is odd. Set up *m* points on a circle of sufficiently large radius. This will be the inner polygon. The outer polygon will be the inner polygon multiplied by 2. More precisely (1 ≤ *i* ≤ *m*):
+
+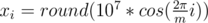
+
+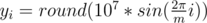
+
+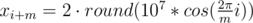
+
+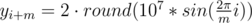
+
+If *m* is even, construct the solution for *m* + 1 and then delete one point from each polygon. If *n* < 2*m*, delete 2*m* - *n* points from the inner polygon.
+
+Unfortunately, this solution doesn't work for *m* = 4, *n* = 7 and *m* = 4, *n* = 8.
+
+Another approach is to set up *m* points on a convex function (for example, *y* = *x*2 + 107), and set up the rest *n* - *m* points on a concave function (for example, *y* = - *x*2 - 107). Take a look at [rng_58](/profile/rng_58 "Legendary Grandmaster rng_58")'s solution — [3210150](/contest/277/submission/3210150 "Submission 3210150 by rng_58").
+
+[277C - Game](/contest/277/problem/C "Codeforces Round 170 (Div. 1)")
+
+At first, notice that horizontal and vertical cuts are independent. Consider a single horizontal line. It contains *m* unit segments. And in any game state it's always possible to decrease the number of uncut units as the player wants. Imagine, that she starts growing a segment from a border, increasing it's length by 1 at a time. Each time the total uncut length decreases by either 0 or 1. In the end it obviously reaches 0.
+
+The same holds for vertical lines as well. So if there are no initial cuts, the game is a nim with *n* - 1 piles of *m* stones and *m* - 1 piles of *n* stones. Could be solved with simple formula.
+
+Initial *k* cuts should be just a technical difficulty. For any vertical/horizontal line, which contains at least one of the cuts, it's pile size should be decreased by the total length of all segments on this line.
+
+How to make a first move in nim: let *res* is the result of state (grundy function), and *a**i* is the size of the *i*-th pile. Then the result of the game without *i*-th pile is . We want to replace *a**i* with some *x*, so that 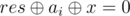. Obviously, the only possible . The resulting solution: find a pile for which 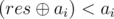, and decrease it downto .
+
+[277D - Google Code Jam](/contest/277/problem/D "Codeforces Round 170 (Div. 1)")
+
+Suppose we have fixed set of inputs that we have to solve. Let's learn how to determine the optimal order. Obviously, Small inputs (and Large inputs with *probFail* = 0) won't fail in any case. It means that our penalty time is no less than submission time of last such ``safe'' inputs. So we will solve such inputs before all the others. Inputs with *probFail* = 1 are just a waste of time, we won't solve such inputs. Now we have only inputs with 0 < *probFail* < 1. Let *i* and *j* be two problems that we are going to solve consecutively at some moment. Let's check, if it is optimal to solve them in order *i*, *j*, or in reversed order. We can discard all the other inputs, because they don't affect on the relative order of these two.
+
+(*timeLarge**i* + *timeLarge**j*)(1 - *probFail**j*) + *timeLarge**i*(1 - *probFail**i*)*probFail**j* < (*timeLarge**i* + *timeLarge**j*)(1 - *probFail**i*) + *timeLarge**j*(1 - *probFail**j*)*probFail**i*
+
+ - *probFail**j*·*timeLarge**j* - *timeLarge**i*·*probFail**j*·*probFail**i* < - *probFail**i*·*timeLarge**i* - *timeLarge**j*·*probFail**i*·*probFail**j*
+
+*timeLarge**i*·*probFail**i*(1 - *probFail**j*) < *timeLarge**j*·*probFail**j*(1 - *probFail**i*)
+
+*timeLarge**i*·*probFail**i* / (1 - *probFail**i*) < *timeLarge**j*·*probFail**j* / (1 - *probFail**j*)
+
+Now we've got a comparator for sort, which will give us the optimal order. Note, that inputs with *probFail* = 0, 1 will be sorted by the comparator correctly as well, so it's not a corner case.
+
+Let's return to the initial problem. First of all, sort problems with the optimal comparator (it's clear that any other order won't be optimal by time, and the score doesn't depend on the order). Calculate the DP: *z*[*i*][*j*] = pair of maximal expected total score and minimal expected penalty time with this score, if we've already decided what to do with the first *i* problems, and we've spent *j* real minutes from the contest's start. There are 3 options for the *i*-the problem:
+
+1. skip: update *z*[*i* + 1][*j*] with the same expected values
+2. solve the Small input: update *z*[*i* + 1][*j* + *timeSmall**i*], the expected total score increases by *scoreSmall**i*, and the expected penalty time increases by *timeSmall**i* (we assume that this input is solved in the very beggining of the contest)
+3. solve both inputs: update *z*[*i* + 1][*j* + *timeSmall**i* + *timeLarge**i*], the expected total score increases by *scoreSmall**i* + (1 - *probFail**i*)*scoreLarge**i*, and the expected penalty time becomes *timeSmall**i* + (1 - *probFail**i*)(*j* + *timeLarge**i*) + *probFail**i*·*penaltyTime*(*z*[*i*][*j*]), where *penaltyTime*(*z*[*i*][*j*]) is the expected penalty time from DP
+
+The resulting answer is the best of *z*[*n*][*i*], (0 ≤ *i* ≤ *t*).
+
+The expected total score could be a number around 1012 with 6 digits after decimal point. So it can't be precisely stored in double. And any (even small) error in calculating score may lead to completely wrong expected time (pretest #7). For example, you can multiply all the probabilities by 106 and store the expected score as integer number to avoid this error.
+
+[277E - Binary Tree on Plane](/contest/277/problem/E "Codeforces Round 170 (Div. 1)")
+
+If there is no "binary" restriction, the solution is simple greedy. Each node of the tree (except the root) must have exactly 1 parent, and each node could be parent for any number of nodes.
+
+Let's assign for each node *i* (except the root) such a node *p**i* as a parent, so that *y**p**i* > *y**i* and distance between *i* and *p**i* is minimal possible. Renumerate all the nodes in order of non-increasing of *y*. Now it's clear that *p**i* < *i* (2 ≤ *i* ≤ *n*). So we've just built a directed tree with all the arcs going downwards. And it has minimal possible length.
+
+Let's recall the "binary" restriction. And realize that it doesn't really change anything: greedy transforms to min-cost-max-flow on the same distance matrix as edge's costs, but each node must have no more than 2 incoming flow units.
diff --git a/editorials/279.md b/editorials/279.md
@@ -0,0 +1,302 @@
+Source: https://codeforces.com/blog/entry/95148
+
+[Continuing](https://codeforces.com/blog/entry/83942) with the theme of absent editorials for old rounds, here is an editorial for [Codeforces Round 171 (Div. 2)](/contest/279 "Codeforces Round 171 (Div. 2)"). Even though there is an official editorial, it is only in russian and doesn't have solution for the last problem.
+
+A
+
+**Editorial**
+
+### [279A - Point on Spiral](/contest/279/problem/A "Codeforces Round 171 (Div. 2)")
+
+Since constraints are small, you can just simulate the whole process, but I'll explain an $O(1)$ solution. Let's look at the path
+
+
+
+Now it's easy to see that the plane can be divided into four parts
+
+
+
+And then we can calculate answer for each part separately, just be careful with borders. For example, for the right part the answer is $4x - 3$.
+
+**Code**
+
+```
+#include "bits/stdc++.h"
+
+using namespace std;
+
+int main() {
+ int x, y;
+ cin >> x >> y;
+ if (x == 0 && y == 0) {
+ cout << 0 << '\n';
+ } else if (-x + 1 < y && y <= x) {
+ cout << 1 + (x - 1) * 4 << '\n';
+ } else if (-y <= x && x < y) {
+ cout << 2 + (y - 1) * 4 << '\n';
+ } else if (x <= y && y < -x) {
+ cout << 3 + (-x - 1) * 4 << '\n';
+ } else {
+ cout << 4 + (-y - 1) * 4 << '\n';
+ }
+
+ return 0;
+}
+```
+
+B
+
+**Editorial**
+
+### [279B - Books](/contest/279/problem/B "Codeforces Round 171 (Div. 2)")
+
+The problem can be written in the following way: for each index $i$ denote $r_i$ as the largest index such that $a_i + \ldots + a_{r_i} \leqslant t$. The problem is to find $max(r_i - i + 1)$.
+
+One can see that $r_i$ are nondecreasing, so the problem can be solved with two pointers: iterate over $i$ and keep a pointer to corresponding $r_i$.
+
+**Code**
+
+```
+#include "bits/stdc++.h"
+
+using namespace std;
+
+int main() {
+ int n, t;
+ cin >> n >> t;
+ vector<int> a(n);
+ for (int& k : a)
+ cin >> k;
+
+ int r = 0;
+ int sm = 0;
+ int ans = 0;
+ for (int i = 0; i < n; ++i) {
+ while (r < n && sm + a[r] <= t) {
+ sm += a[r];
+ ++r;
+ }
+ ans = max(ans, r - i);
+ sm -= a[i];
+ }
+
+ cout << ans << '\n';
+
+ return 0;
+}
+```
+
+C
+
+**Editorial**
+
+### [279C - Ladder](/contest/279/problem/C "Codeforces Round 171 (Div. 2)")
+
+Let's calculate two arrays before answering queries. $tol[i]$ is the smallest index such that $[b_{tol[i]},\, \ldots,\, b_{i}]$ is nonincreasing, and $tor[i]$ is the largest index such that $[b_{i},\, \ldots,\, b_{tor[i]}]$ is nondecreasing. Then for each query we can take $tor[l]$ and $tol[r]$ and compare them. The answer is "Yes" iff $tor[l] \geqslant tol[r]$. In other words, we are checking if the largest nondecreasing segment from $l$ and largest nonincreasing segment from $r$ are intersecting.
+
+To calculate $tol[i]$, go over $i$ from $1$ to $n$ and maintain largest nonincreasing suffix. For $tor$ do the same in reverse.
+
+**Code**
+
+```
+#include "bits/stdc++.h"
+
+using namespace std;
+
+int main() {
+ int n, m;
+ cin >> n >> m;
+ vector<int> a(n);
+ for (int& k : a)
+ cin >> k;
+
+ vector<int> tor(n), tol(n);
+ iota(tol.begin(), tol.end(), 0);
+ iota(tor.begin(), tor.end(), 0);
+
+ tol[0] = 0;
+ for (int i = 1; i < n; ++i)
+ if (a[i - 1] >= a[i])
+ tol[i] = tol[i - 1];
+
+ tor[n - 1] = n - 1;
+ for (int i = n - 2; i >= 0; --i)
+ if (a[i] <= a[i + 1])
+ tor[i] = tor[i + 1];
+
+ while (m--) {
+ int l, r;
+ cin >> l >> r;
+ --l; --r;
+ cout << (tol[r] <= tor[l] ? "Yes" : "No") << '\n';
+ }
+
+ return 0;
+}
+```
+
+D
+
+**Editorial**
+
+### [279D - The Minimum Number of Variables](/contest/279/problem/D "Codeforces Round 171 (Div. 2)")
+
+You can notice that when we want to perform some operation, we are only interested in a subset of current values of variables (including zeros). So let's create $dp[i][mask] = bool$, which is $1$ if we can perform first $i$ operations and end up with the values from $mask$. Here $k$-bit in the mask corresponds to the value $vals[k]$, where array $vals$ stores all numbers in $a$ and a zero, and $k$-th bit is set iff the value of one of the variables is $vals[k]$.
+
+To make transition from $dp[i][mask]$ to $dp[i + 1][new\_mask]$, let's look at the operation. We have to find two values in the $mask$ such that their sum is $a[i + 1]$. Then to calculate $new\_mask$ we have to set $k$-th bit in the $mask$, where $k$ is such that $vals[k] = a[i + 1]$. Also, while writing new variable we can overwrite any existing variable, so we have an option to disable any bit in the $mask$.
+
+Now it looks like we have $O(2^nn)$ states and $n$ transitions from each state (disabling each bit). But actually if we only make transition from $dp[i][mask] = 1$, the complexity will be $O(2^nn)$, because for each $i$ there are at most $2^{i+1}$ masks that we can achieve, since there are only $i$ distinct numbers on the current prefix plus an additional zero. And $\sum_{i=1}^n 2^{i+1}\cdot n = O(2^nn)$.
+
+The only problem left is to check if we can build some number $y$ from $vals$ using numbers from $mask$. This can be precomputed in $O(2^nn)$: let's calculate array $possible[mask] = x$, where $i$-th bit in $x$ is set iff we can get number $vals[i]$ from mask on the next step. To calculate it, first for each $mask$ with at most $2$ bits just calculate all possible $x$ with any straightforward approach, since there are only $O(n^2)$ such masks. For any other mask notice that we can get $y$ iff sum of some two values equals to $y$. So we can iterate over all submasks such that they differ from $mask$ in exactly one bit and update $possible[mask]$ with $possible[submask]$. And since $mask$ has at least $3$ bits, if there is a pair which sums up to $y$, this pair will be included into at least one of the submasks. One can even notice that we only need any $3$ such submasks to cover every pair of bits.
+
+The answer is minimum number of bits over all masks such that $dp[n][mask] = 1$.
+
+**Code**
+
+```
+#include "bits/stdc++.h"
+
+using namespace std;
+
+int main() {
+ int n;
+ cin >> n;
+ vector<int> a(n);
+ for (int& k : a)
+ cin >> k;
+
+ auto vals = a;
+ vals.push_back(0);
+ sort(vals.begin(), vals.end());
+ vals.erase(unique(vals.begin(), vals.end()), vals.end());
+
+ vector<int> pos(n);
+ for (int i = 0; i < n; ++i) {
+ pos[i] = lower_bound(vals.begin(), vals.end(), a[i]) - vals.begin();
+ }
+
+ vector<int> possible(1 << vals.size(), 0);
+ for (int i = 1; i < possible.size(); ++i) {
+ int k = 0;
+ for (int j = 0; j < vals.size() && k < 3; ++j) {
+ if ((i >> j) & 1) {
+ possible[i] |= possible[i ^ (1 << j)];
+ ++k;
+ }
+ }
+ if (__builtin_popcount(i) <= 2) {
+ for (int j = 0; j < vals.size(); ++j) {
+ if (!((i >> j) & 1)) continue;
+ for (int k = 0; k < vals.size(); ++k) {
+ if (!((i >> k) & 1)) continue;
+ int val = vals[j] + vals[k];
+ int ind = lower_bound(vals.begin(), vals.end(), val) - vals.begin();
+ if (ind < vals.size() && vals[ind] == val)
+ possible[i] |= (1 << ind);
+ }
+ }
+ }
+ }
+
+ vector<char> dp_cur(1 << vals.size(), 0);
+ dp_cur[1 << pos[0]] = 1;
+ dp_cur[(1 << pos[0]) | (1 << 0)] = 1;
+
+ auto can_sum = [&](int mask, int pos) {
+ return (possible[mask] >> pos) & 1;
+ };
+
+ vector<char> dp_next;
+ for (int i = 1; i < n; ++i) {
+ dp_next.assign(dp_cur.size(), false);
+ for (int j = 0; j < dp_cur.size(); ++j) {
+ if (dp_cur[j] && can_sum(j, pos[i])) {
+ int mask = j;
+ mask |= (1 << pos[i]);
+ dp_next[mask] = 1;
+ for (int k = 0; k < vals.size(); ++k)
+ if (((mask >> k) & 1) && vals[k] != a[i])
+ dp_next[mask ^ (1 << k)] = 1;
+ }
+ }
+ swap(dp_cur, dp_next);
+ }
+
+ int ans = -1;
+ for (int i = 0; i < dp_cur.size(); ++i) {
+ if (!dp_cur[i]) continue;
+ int sz = __builtin_popcount(i);
+ if (ans == -1 || ans > sz)
+ ans = sz;
+ }
+ cout << ans << '\n';
+
+ return 0;
+}
+```
+
+E
+
+**Editorial**
+
+### [279E - Beautiful Decomposition](/contest/279/problem/E "Codeforces Round 171 (Div. 2)")
+
+First of all it's easy to notice that we will use each power of $2$ at most once.
+
+Let's look at the highest bit in the current number, suppose it's $2^k$. Since the sum of all powers of $2$ below $k$ is less than $2^k$, we will have to add at least one power of two $2^x$ with $x \geqslant k$. One can see that adding $2^{k+2}$ is not optimal, since then we will have to subtract at least $2^{k+1}$ and $2^{k+2} - 2^{k+1}$ can be replaced with $2^{k+1}$. So the only choices are $2^k$ or $2^{k+1}$. If we add $2^k$, we have to solve a problem for remaining number, which is a suffix or our current binary string. Otherwise, $2^{k+1}$ is larger than our current number, so we just need the answer for $m = 2^{k+1} - n$. Let's call such $m$ a complement for a number $n$ (notice that we don't need $k$ in the definition because $k$ is defined as largest bit in $n$)
+
+Now let's look at $m$. To calculate it, we have to flip all bits in $n$ and add $1$ to the result. Now it's easy to see that if $m$ is a complement for $n$, then for any suffix of $n$ (in binary form), the corresponding suffix of $m$ is a complement for it. Also, $n$ is a complement for $m$.
+
+So during our calculations we will only deal with $n$, $m$, suffixes of $n$ and suffixes of $m$. And this leads to a following dp solution: let $v[1] = n$, $v[2] = m$. Then $dp[ind][suf]$ is the smallest answer for a binary number represented by a suffix of number $v[ind]$ starting from index $suf$. We can calculate this $dp$ starting from $dp[\ldots][n]$ and the answer will be $dp[1][1]$.
+
+**Code**
+
+```
+#include "bits/stdc++.h"
+
+using namespace std;
+
+int main() {
+ string n;
+ cin >> n;
+ string m = n;
+ {
+ for (char& c : m) {
+ c ^= '1' ^ '0';
+ }
+ int ind = m.size() - 1;
+ while (ind >= 0 && m[ind] == '1') {
+ m[ind] = '0';
+ --ind;
+ }
+ if (ind == -1) {
+ m.insert(m.begin(), '1');
+ n.insert(n.begin(), '0');
+ } else {
+ m[ind] = '1';
+ }
+ }
+
+ int sz = n.size();
+
+ vector<string> v = {n, m};
+ vector<array<int, 2>> dp(sz);
+
+ dp[sz - 1][0] = (v[0].back() == '1');
+ dp[sz - 1][1] = (v[1].back() == '1');
+
+ for (int i = sz - 2; i >= 0; --i) {
+ for (int b = 0; b < 2; ++b) {
+ if (v[b][i] == '0') {
+ dp[i][b] = dp[i + 1][b];
+ } else {
+ dp[i][b] = min(dp[i + 1][b] + 1, dp[i + 1][b ^ 1] + 1);
+ }
+ }
+ }
+
+ cout << dp[0][0] << '\n';
+
+ return 0;
+}
+```
diff --git a/editorials/28.md b/editorials/28.md
@@ -0,0 +1,45 @@
+Source: https://codeforces.com/blog/entry/685
+
+**A. [Bender Problem](https://codeforces.com/contest/28/problem/A)**
+ Solution by [Polichka](https://codeforces.com/profile/Polichka)
+ Let's look at the first nail. If it is occupied by the fold place, then Bender will put next fold place on the third nail, then on fifth and so on. Else, is the first nail occupied by end, than second, fourth, sixth and so on nail will be occupied by the fold places.
+ Let's see, if we can complete our polyline with the first nail, occupied by rhe fold place. It means we should check, if we have an unused pod with length *dist*(*nails*[*n*], *nails*[1]) + *dist*(*nails*[1], *nails*[2]). Then check the third nail and so on.
+ If we have completed the polyline, then we have an answer. Else repeat previous procedure, but starting from the second nail.
+
+ **B. [pSort](https://codeforces.com/contest/28/problem/B)**
+ Solution by [Polichka](https://codeforces.com/profile/Polichka)
+ Let's consider a graph. Vertexes will correspond to place of the permutation. Places will be connected by an edge if and only if we can swap theirs values. Our problem has a solution when for every i, vertex p[i] can be reached from vertex i.
+
+ **C. [Bath Queue](https://codeforces.com/contest/28/problem/C)**
+ Solution by [Fefer](https://codeforces.com/profile/Fefer)
+ This problem is solved by dynamic programming
+ Consider the following dynamics: *d*[*i*][*j*][*k*].
+ *i* --- number of not yet processed students,
+ *j* --- number of not yet processed rooms,
+ *k* --- maximum queue in the previous rooms.
+ The value we need is in state *d*[*n*][*m*][0]. Let's conside some state (*i*, *j*, *k*) and search through all *c* from 0 to *i*. If *c* students will go to *j*th room, than a probability of such event consists of factors: *C**c**i* --- which students will go to *j*th room.
+ (1 / *j*)*c*· ((*j* - 1) / *j*)*i* - *c* --- probability, that *c* students will go to *j*th room,and the rest of them will go to the rooms from first to *j* - 1th.
+ Sum for all *ñ* from 0 to *i* values of
+ (1 / *j*)*c*· ((*j* - 1) / *j*)*i* - *c*· *C**c**i*· *d*[*i* - *c*][*j* - 1][*mx*]. Do not forget to update maximum queue value and get the accepted.
+
+ **D. [Do not fear, DravDe is kind](https://codeforces.com/contest/28/problem/D)**
+ Solution by [RAD](https://codeforces.com/profile/RAD)
+ Let's split all trucks into different classes by the sum of *l**i* + *c**i* + *r**i*. Answer sequence consists of trucks from only one class, so let's solve problem for different classes independently.
+ Let's loop through trucks from fixed class in the order, then follow in the motorcade and update values in dynamics *z*[*k*] - maximum profit we can get, if last truck has *r**i* = *k*.
+ Truck with number i can update two values:
+ it can update value *z*[*r**i*] with value *z*[*r**i* + *c**i*] + *v**i*. It means this truck continued some motorcade, started from some previous truck.
+ if *l**i* = 0 it can update value *z*[*r**i*] with *v**i*. It means this truck started motorcade. Answer will be in *z*[0]
+ To restore the trucks included in the answer, we can keep with the maximal sum in z the index of last truck that updated this sum. Also we store the ancestor p for each truck that updated something in z. This ancestor is calculated when we consider i-th truck and doesn't change further: p[i] = -1 if truck i became beginning of the motorcade, otherwise p[i] = last truck that updated *z*[*r**i* + *c**i*]. We start restore of the answer from last truck updated z[0]. After that we restore everything using only p.
+
+**E. [DravDe saves the world](https://codeforces.com/contest/28/problem/E)**
+ Solution by [Gerald](https://codeforces.com/profile/Gerald)
+ Problem by [RAD](https://codeforces.com/profile/RAD)
+ Let's look at geometrical locus where DravDe can land. It can be eigher an angle or a line(half-line).
+ 1. Locus is an angle if and only if projection of vector *v* and vector *u* on Oxy plane is not collinear. This angle is easy to calculate. Angular vertex is DravDe starting point and one of half-lines is collinear with place speed vector projection. Second half-line is easy to calculate:
+ *A**z* + *V**z*· *tv* + *U**z*· *tu* = 0
+ *A**x* + *V**x*· *tv* + *U**x*· *tu* = *B**x*
+ *A**y* + *V**y*· *tv* + *U**y*· *tu* = *B**y*
+ where A - starting point, B - landing point. Consider tv equal to 1 and calculate tu from first equation. From second and third calculate point B. This point lies on the second half-line of the angle.
+ 2. If plane speed projection and wind speed projection is collinear, locus is half-line or line, depending on the difference between this two speeds.
+ If the answer exist, than polygon and locus have at least onecommon point. And t1 and t2 is minimal on edge points. So now let's cross all segments with locus, calculate t1 and t2 for each intersection point and select minimal answer. Thank you for your participation. Good luck with upsolving and incoming contests. Luck - is very useful and it is good to have it.
+ With best regards, Ivan.
diff --git a/editorials/280.md b/editorials/280.md
@@ -0,0 +1,63 @@
+Source: https://codeforces.com/blog/entry/6939
+
+# Overview ...
+
+In DIV 1, there are 3 normal tasks accompanied with 2 challenge tasks. About 40 competitors solve first three tasks during the contest and I believe there will be more if we extended the duration a little bit.
+
+Task D is a standard data-structure problem hidden behind a classical maximum cost flow model. This kind of problem are usually trick-less, but hard to implement especially under the pressure. Because of this, it becomes tonight's draw-breaker.
+
+Task E is a extended version on a classical DP && Math problem. There are many solutions to the original problem, one is giving a global view under the state transition, and using a data structure to handle it carefully. However, this one is even more harder, few people have ever tried it except [Jacob](/profile/Jacob "Candidate Master Jacob"). (Although is wrong.)
+
+As a seasoned competitor, [Petr](/profile/Petr "International Grandmaster Petr") took the C-B-A order which proved to be the best choice through out the night. And after quickly solved C and B, he has sunk into problem A, it takes him about 45 minutes to cut-the-knot and got 2 **Successful Hacking Attempt** as a reward.
+
+On the other hand, [peter50216](/profile/peter50216 "International Grandmaster peter50216") gave his response to Problem A straightly! It only took him about 15 minutes to write a code which is full of trigonometric function and if-else. And on top of this is another 15 minutes to solve the successors. After that, he gave 2 **Successful Hacking Attempt** on A and 1 **Successful Hacking Attempt** on B as the end.
+
+While we were marvelling at [peter50216](/profile/peter50216 "International Grandmaster peter50216") for his solid skill in geometry, [al13n](/profile/al13n "Grandmaster al13n") gave the first attempt to problem D among the game. Unfortunately his solution get **TLE** on the pretests.
+
+This is a **O(mk^2logn)** algorithm, and we think it is hard to optimize it to pass the pretests even for our setter. And abandoned the **O(mk^2logn)** solution and totally reconstructed the **O(mklogn)** from the sketch now became more difficult and audacious.
+
+While we were praying to [al13n](/profile/al13n "Grandmaster al13n"), [Jacob](/profile/Jacob "Candidate Master Jacob") gave the first solution and the only solution for Problem E among the whole game! It cost all of his time and led him no time to solve others. It sounds like a miracle ..
+
+We were all sooooooo excited and opened his code and look carefully, but, actually I myself got quite confused by his solution, and didn't know why it can work at all.
+
+While all we setter and tester were checking the solution carefully. [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne") **(XHXJ)** gave the first correct solution among the game for problem D. It is a huge code more than 12kb, and perform as same as our std solution. Although he haven't solve A && B, this break-through has already establish his winner position.
+
+After the contest, I interview her to "how can you solve this problem so quick", and replied as “I have solved the simplified problem, and have thought about this method before.”
+
+At the same time, we found that [Jacob](/profile/Jacob "Candidate Master Jacob")'s solution was wrong, we generated a few maximal random data, and it return **WA** about one-quarter of them. After some discussion we decided to add one of them into the tests.
+
+In both problem D and E, our pretests intended to be as strong as possible. How I wish to let [Jacob](/profile/Jacob "Candidate Master Jacob") know about his solution is wrong so he can quickly get out of the impasses and get **Accepted** in the end... .
+
+[al13n](/profile/al13n "Grandmaster al13n") also pass from the pretests after [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne"), we are relieved to hear about it at first, but found it is a **O(mk^2logn)** solution with a wrong optimization soon, this solution will definitely fail in system test, but he may didn't aware of it at the time.
+
+There are other three correct solutions for Problem D near the end of the game, among them [FattyPenguin](/profile/FattyPenguin "International Master FattyPenguin")'s solution is the fastest one, and he make it in ten minutes ago before the contest end and [liouzhou_101](/profile/liouzhou_101 "International Master liouzhou_101")'s solution actually is a **O(mk^2logn)** one but with some dramatic optimizations. It is hard to block this kind of solution or it could cause some trouble for our Java Users.
+
+# Tutorial ...
+
+[http://assets.codeforces.com/statements/280-281/Tutorial.pdf](//assets.codeforces.com/statements/280-281/Tutorial.pdf)
+
+* [Problem 2A. Word Capitalization](https://codeforces.com/problemset/problem/281/A)
+* [Problem 2B. Nearest Fraction](https://codeforces.com/problemset/problem/281/B)
+* [Problem A. Rectangle Puzzle](https://codeforces.com/problemset/problem/280/A)
+* [Problem B. Maximum Xor Secondary](https://codeforces.com/problemset/problem/280/B)
+* [Problem C. Game on Tree](https://codeforces.com/problemset/problem/280/C)
+* [Problem D. k-Maximum Subsequence Sum](//codeforces.com/problemset/problem/280/D)
+* [Problem E. Sequence Transformation](//codeforces.com/problemset/problem/280/E)
+* [Backstage](http://www.bilibili.tv/video/av500562/): The screencast of my screen during the contest, you can see what happened behind the scene if you are interested, just have fun ~.
+* [CMHJT's tutorial](http://www.13331.org/420.html): Another tutorial written by one of the setters for C, D, E.(Chinese!)
+* [roosephu's tutorial for D](//codeforces.com/blog/entry/6957): Tester's tutorial for Problem D.
+* [Seter's tutorial for E](//codeforces.com/blog/entry/6952): Tester's tutorial for Problem E.
+* [......](http://blog.renren.com/blog/271960376/897411882): A brief overview release after the contest end.(Chinese!)
+
+# Sidelights ...
+
+* There are some disputes about the problem A, but personally I like it very much, this is a basic problem(surely it is evil), can be described in one picture, and all of us could solve it if they are careful. Some people say it is harder than A so it should be swap with Problem C, but I insist on put it at A, because, we all think Problem B && C needs some idea, but A needs only basic knowledge we learned in middle school. And it can be solved in a different style if you have a well-implemented Geometry Template. Some competitors are just good at this kind of problem while others are not. And after all, this is the only problem which has trick in this contest. :)
+* In problem B, some people got confused in “bitwise excluding OR = XOR or OR?”, they are only familiar with "XOR" but get into confused with something like "bitwise excluding OR". Well, as a Non-English speaker, I can only expressed my understanding, we didn't intend to do that. In the original statement we write "XOR" but during the translate process it became "bitwise excluding OR", and I did not think it could cause such trouble. Here we can only recommend you read more English book, because such things will occur from now on and keep up.
+* [tourist](/profile/tourist "Legendary Grandmaster tourist") lost his target (Rating above 3000) after the contest. But we all think he'll return soon.
+* [rng_58](/profile/rng_58 "Legendary Grandmaster rng_58") didn't participate in the contest but took a virtual participation on the next day. He can't solve D && E and get Rank 5 along after [Petr](/profile/Petr "International Grandmaster Petr").
+* [tclsm2012](/profile/tclsm2012 "Expert tclsm2012") as a purple, also solve Problem D during the contest, but failed at A && C at the expense.
+* Both the winner and the runner-up failed on problem A.
+* [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne")'s A solution was hacked by [scottai1](/profile/scottai1 "International Master scottai1"), the latter, also failed at the system test after a while.
+* One of our setter ... came in the hospital after setting problems.
+* We were adding tests against submitted solutions during the contest.
+* **Daniel Sleator** (A professor at CMU who invented many data structures such as [splay trees](v), [link-cut trees](https://en.wikipedia.org/wiki/Link/cut_tree), [skew heap](https://en.wikipedia.org/wiki/Skew_heap) and discovered [amortized analysis](https://en.wikipedia.org/wiki/Amortized_analysis), [see Wikipedia ...](https://en.wikipedia.org/wiki/Daniel_Sleator))participated in Div 2 and get promotion to Div 1 after the contest. And he checked our Div 1. E and write a miraculous DP solution[1](//codeforces.com/contest/280/submission/3297237) [2](//codeforces.com/contest/280/submission/3313283) in [Ocaml](https://en.wikipedia.org/wiki/Ocaml) which based on a conclusion.
diff --git a/editorials/281.md b/editorials/281.md
@@ -0,0 +1,63 @@
+Source: https://codeforces.com/blog/entry/6939
+
+# Overview ...
+
+In DIV 1, there are 3 normal tasks accompanied with 2 challenge tasks. About 40 competitors solve first three tasks during the contest and I believe there will be more if we extended the duration a little bit.
+
+Task D is a standard data-structure problem hidden behind a classical maximum cost flow model. This kind of problem are usually trick-less, but hard to implement especially under the pressure. Because of this, it becomes tonight's draw-breaker.
+
+Task E is a extended version on a classical DP && Math problem. There are many solutions to the original problem, one is giving a global view under the state transition, and using a data structure to handle it carefully. However, this one is even more harder, few people have ever tried it except [Jacob](/profile/Jacob "Candidate Master Jacob"). (Although is wrong.)
+
+As a seasoned competitor, [Petr](/profile/Petr "International Grandmaster Petr") took the C-B-A order which proved to be the best choice through out the night. And after quickly solved C and B, he has sunk into problem A, it takes him about 45 minutes to cut-the-knot and got 2 **Successful Hacking Attempt** as a reward.
+
+On the other hand, [peter50216](/profile/peter50216 "International Grandmaster peter50216") gave his response to Problem A straightly! It only took him about 15 minutes to write a code which is full of trigonometric function and if-else. And on top of this is another 15 minutes to solve the successors. After that, he gave 2 **Successful Hacking Attempt** on A and 1 **Successful Hacking Attempt** on B as the end.
+
+While we were marvelling at [peter50216](/profile/peter50216 "International Grandmaster peter50216") for his solid skill in geometry, [al13n](/profile/al13n "Grandmaster al13n") gave the first attempt to problem D among the game. Unfortunately his solution get **TLE** on the pretests.
+
+This is a **O(mk^2logn)** algorithm, and we think it is hard to optimize it to pass the pretests even for our setter. And abandoned the **O(mk^2logn)** solution and totally reconstructed the **O(mklogn)** from the sketch now became more difficult and audacious.
+
+While we were praying to [al13n](/profile/al13n "Grandmaster al13n"), [Jacob](/profile/Jacob "Candidate Master Jacob") gave the first solution and the only solution for Problem E among the whole game! It cost all of his time and led him no time to solve others. It sounds like a miracle ..
+
+We were all sooooooo excited and opened his code and look carefully, but, actually I myself got quite confused by his solution, and didn't know why it can work at all.
+
+While all we setter and tester were checking the solution carefully. [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne") **(XHXJ)** gave the first correct solution among the game for problem D. It is a huge code more than 12kb, and perform as same as our std solution. Although he haven't solve A && B, this break-through has already establish his winner position.
+
+After the contest, I interview her to "how can you solve this problem so quick", and replied as “I have solved the simplified problem, and have thought about this method before.”
+
+At the same time, we found that [Jacob](/profile/Jacob "Candidate Master Jacob")'s solution was wrong, we generated a few maximal random data, and it return **WA** about one-quarter of them. After some discussion we decided to add one of them into the tests.
+
+In both problem D and E, our pretests intended to be as strong as possible. How I wish to let [Jacob](/profile/Jacob "Candidate Master Jacob") know about his solution is wrong so he can quickly get out of the impasses and get **Accepted** in the end... .
+
+[al13n](/profile/al13n "Grandmaster al13n") also pass from the pretests after [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne"), we are relieved to hear about it at first, but found it is a **O(mk^2logn)** solution with a wrong optimization soon, this solution will definitely fail in system test, but he may didn't aware of it at the time.
+
+There are other three correct solutions for Problem D near the end of the game, among them [FattyPenguin](/profile/FattyPenguin "International Master FattyPenguin")'s solution is the fastest one, and he make it in ten minutes ago before the contest end and [liouzhou_101](/profile/liouzhou_101 "International Master liouzhou_101")'s solution actually is a **O(mk^2logn)** one but with some dramatic optimizations. It is hard to block this kind of solution or it could cause some trouble for our Java Users.
+
+# Tutorial ...
+
+[http://assets.codeforces.com/statements/280-281/Tutorial.pdf](//assets.codeforces.com/statements/280-281/Tutorial.pdf)
+
+* [Problem 2A. Word Capitalization](https://codeforces.com/problemset/problem/281/A)
+* [Problem 2B. Nearest Fraction](https://codeforces.com/problemset/problem/281/B)
+* [Problem A. Rectangle Puzzle](https://codeforces.com/problemset/problem/280/A)
+* [Problem B. Maximum Xor Secondary](https://codeforces.com/problemset/problem/280/B)
+* [Problem C. Game on Tree](https://codeforces.com/problemset/problem/280/C)
+* [Problem D. k-Maximum Subsequence Sum](//codeforces.com/problemset/problem/280/D)
+* [Problem E. Sequence Transformation](//codeforces.com/problemset/problem/280/E)
+* [Backstage](http://www.bilibili.tv/video/av500562/): The screencast of my screen during the contest, you can see what happened behind the scene if you are interested, just have fun ~.
+* [CMHJT's tutorial](http://www.13331.org/420.html): Another tutorial written by one of the setters for C, D, E.(Chinese!)
+* [roosephu's tutorial for D](//codeforces.com/blog/entry/6957): Tester's tutorial for Problem D.
+* [Seter's tutorial for E](//codeforces.com/blog/entry/6952): Tester's tutorial for Problem E.
+* [......](http://blog.renren.com/blog/271960376/897411882): A brief overview release after the contest end.(Chinese!)
+
+# Sidelights ...
+
+* There are some disputes about the problem A, but personally I like it very much, this is a basic problem(surely it is evil), can be described in one picture, and all of us could solve it if they are careful. Some people say it is harder than A so it should be swap with Problem C, but I insist on put it at A, because, we all think Problem B && C needs some idea, but A needs only basic knowledge we learned in middle school. And it can be solved in a different style if you have a well-implemented Geometry Template. Some competitors are just good at this kind of problem while others are not. And after all, this is the only problem which has trick in this contest. :)
+* In problem B, some people got confused in “bitwise excluding OR = XOR or OR?”, they are only familiar with "XOR" but get into confused with something like "bitwise excluding OR". Well, as a Non-English speaker, I can only expressed my understanding, we didn't intend to do that. In the original statement we write "XOR" but during the translate process it became "bitwise excluding OR", and I did not think it could cause such trouble. Here we can only recommend you read more English book, because such things will occur from now on and keep up.
+* [tourist](/profile/tourist "Legendary Grandmaster tourist") lost his target (Rating above 3000) after the contest. But we all think he'll return soon.
+* [rng_58](/profile/rng_58 "Legendary Grandmaster rng_58") didn't participate in the contest but took a virtual participation on the next day. He can't solve D && E and get Rank 5 along after [Petr](/profile/Petr "International Grandmaster Petr").
+* [tclsm2012](/profile/tclsm2012 "Expert tclsm2012") as a purple, also solve Problem D during the contest, but failed at A && C at the expense.
+* Both the winner and the runner-up failed on problem A.
+* [UESTC_Nocturne](/profile/UESTC_Nocturne "Grandmaster UESTC_Nocturne")'s A solution was hacked by [scottai1](/profile/scottai1 "International Master scottai1"), the latter, also failed at the system test after a while.
+* One of our setter ... came in the hospital after setting problems.
+* We were adding tests against submitted solutions during the contest.
+* **Daniel Sleator** (A professor at CMU who invented many data structures such as [splay trees](v), [link-cut trees](https://en.wikipedia.org/wiki/Link/cut_tree), [skew heap](https://en.wikipedia.org/wiki/Skew_heap) and discovered [amortized analysis](https://en.wikipedia.org/wiki/Amortized_analysis), [see Wikipedia ...](https://en.wikipedia.org/wiki/Daniel_Sleator))participated in Div 2 and get promotion to Div 1 after the contest. And he checked our Div 1. E and write a miraculous DP solution[1](//codeforces.com/contest/280/submission/3297237) [2](//codeforces.com/contest/280/submission/3313283) in [Ocaml](https://en.wikipedia.org/wiki/Ocaml) which based on a conclusion.
diff --git a/editorials/282.md b/editorials/282.md
@@ -0,0 +1,59 @@
+Source: https://codeforces.com/blog/entry/6999
+
+Hi, Here's the editorial.
+
+Please note that not all the codes presented below belong to me. (It's a combination of codes from our problemsetters and testers) -- And I borrowed [AKGMA](/profile/AKGMA "Specialist AKGMA")'s account since I wasn't able to link to my own submissions somehow!
+
+Note: It seems that the Codeforces mark-up is not functioning. To see a submission go to: [http://www.codeforces.com/contest/282/submission/submission-number](//www.codeforces.com/contest/282/submission/submission-number)
+
+#### A: **Bit++**
+
+Just use a simple loop. (Take a look at the Python code)
+
+GNU C++: [3314442](/contest/282/submission/3314442 "Submission 3314442 by AKGMA"), [3314464](/contest/282/submission/3314464 "Submission 3314464 by AKGMA")
+
+GNU C: [3314471](/contest/282/submission/3314471 "Submission 3314471 by AKGMA")
+
+Python: [3314475](/contest/282/submission/3314475 "Submission 3314475 by AKGMA")
+
+#### B: **Painting Eggs**
+
+This one can be solved by a greedy algorithm. Start from the 1st egg and each time give the egg to A if and only if giving it to A doesn't make the difference > 500, otherwise give it to G.
+
+To prove the correctness, one can use induction. The base case is trivial. Suppose that we've assigned the first *n* - 1 eggs such that the total money given to A is *S**a* and total money given to G is *S**g*. We can assume *S**a* ≥ *S**g*. Now we must either add *g**n* to *S**g* or add *a**n* to *S**a*. If we can't add *g**n* to *S**g*, then *S**g* + *g**n* > *S**a* + 500, so - 500 > *S**a* - *S**g* - *g**n*, adding 1000 to both sides gives us the inequality 500 > *S**a* + (1000 - *g**n*) - *S**g* which is exactly what we need to make sure that we can add *a**n* = 1000 - *g**n* to *S**a*.
+
+GNU C++: [3314480](/contest/282/submission/3314480 "Submission 3314480 by AKGMA"), [3314484](/contest/282/submission/3314484 "Submission 3314484 by AKGMA")
+
+GNU C: [3314488](/contest/282/submission/3314488 "Submission 3314488 by AKGMA")
+
+Python: [3314492](/contest/282/submission/3314492 "Submission 3314492 by AKGMA")
+
+#### C: **XOR and OR**
+
+First of all, check the length of the two strings to be equal. Then with a little try and guess, you can find out that the zero string (00...0) can't be converted to anything else and nothing else can be converted to zero. All other conversions are possible.
+
+GNU C++: [3314503](/contest/282/submission/3314503 "Submission 3314503 by AKGMA"), [3314504](/contest/282/submission/3314504 "Submission 3314504 by AKGMA"), [3314509](/contest/282/submission/3314509 "Submission 3314509 by AKGMA"), [3314512](/contest/282/submission/3314512 "Submission 3314512 by AKGMA"), [3314514](/contest/282/submission/3314514 "Submission 3314514 by AKGMA")
+
+#### D: **Yet another Number Game**
+
+For n=1, everything is clear. If *a*1 = 0 then BitAryo wins, otherwise BitLGM is the winner.
+
+For n=2: define win[i][j] = (Whether i,j is a Winning position). It's easy to calculate win[i][j] for all i and j, using a loop (Checking all possible moves). This leads us to an O(*n*3) solution.
+
+For n=3: Everything is similar to [NIM](https://en.wikipedia.org/wiki/Nim_Game), With the same statement of proof as for NIM, i,j,k is a winning position if and only if (i xor j xor k) ≠ 0.[Don't forget the parentheses in code :) ] Complexity: O(1)
+
+One can also solve this case using DP. We define lose[i][j]= (Least k, such that i,j,k is a losing position) ,lose2[i][j]=(Least k, such that k,k+i,k+i+j is a losing position) and win[i][j][k] just as the case with n=2. As in the codes below, one can calculate all these values in O(*n*3).
+
+Using the same DP strategy for n=2 and the O(1) algorithm for n=3 and n=1, leads us to a total complexity of O(*n*2) which was not necessary in this contest.
+
+GNU C++: [3314578](/contest/282/submission/3314578 "Submission 3314578 by AKGMA"), [3314580](/contest/282/submission/3314580 "Submission 3314580 by AKGMA"), [3314585](/contest/282/submission/3314585 "Submission 3314585 by AKGMA"), [3314588](/contest/282/submission/3314588 "Submission 3314588 by AKGMA")
+
+#### E: **Sausage Maximization**
+
+Can be solved using a trie in O(n log (max{*a**i*})).
+
+Start with a prefix of size n, and decrease the size of prefix in each step. For each new prefix calculate the XOR of elements in that prefix and add the XOR of the newly available suffix (which does not coincide with the new prefix) to the trie, then query the trie for the best possible match for the XOR of the new prefix. (Try to get 1 as the first digit if possible, otherwise put 0, then do the same thing for the second digit and so on). Get a maximum over all answers you've found, and it's all done. [By digit, I mean binary digit]
+
+GNU C++: [3314616](/contest/282/submission/3314616 "Submission 3314616 by AKGMA"), [3314619](/contest/282/submission/3314619 "Submission 3314619 by AKGMA")
+
+We hope you enjoyed the tasks.
diff --git a/editorials/283.md b/editorials/283.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/7037
+
+Hi Guys,
+
+Hope you enjoyed Round 174. :) I would like to add a few comments on some of the problems, beyond the [editorial.](//codeforces.com/blog/entry/7036)
+
+**div 2 A** ****
+
+If you know some math, you can actually solve this problem in  (!!!) You can show that the answer is φ (*p* - 1) where φ (*n*) is the number of positive integers *i* less than to *n* with *gcd*(*i*, *n*) = 1. To prove this we first show that there is always at least one primitive root  for all primes *p*. (This is a fairly well known result so I won’t prove it here, but you can find many proofs online) So now assume *g* is a primitive root  Then, the set {*g*, *g*2, ... *g**p* - 1} is congruent to the set {1, 2, ... , *p* - 1}. Furthermore, its not hard to show that *g**i* is a primitive root if and only if *gcd*(*i*, *p* - 1) = 1, (try it!) hence our formula φ (*p* - 1). φ (*n*) can be computed by getting the prime factors of *n*, since 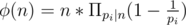 so this gives us our  algorithm. :)
+
+**div 1 D** ****
+
+Here is a full solution to Codeforces #174 div 1 D.
+
+Let ν2(*n*) denote the exponent of the largest power of 2 that divides *n*. For example ν2(5) = 0, ν2(96) = 5. Let *f*(*n*) denote the largest odd factor of *n*.
+
+Note the following formula for sum of arithmetic series:
+
+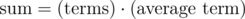
+
+I claim that the pair (*x*, *y*) is cool if and only if  and one of the following is true \begin{enumerate} \item ν2(*x*) + 1 = ν2(*y*) \item ν2(*y*) = 0 \end{enumerate} This can be proven by casework on the number on the parity of *y*.
+
+If *y* is odd, the average term of the arithmetic sequence is an integer, so *f*(*y*) = *y* divides *f*(*x*) and ν2(*y*) = 0.
+
+If *y* is even, the average is of the form .5·*k* where *k* is odd, so  so it follows that *y* divides *x* so *f*(*y*) divides *f*(*x*), and furthermore 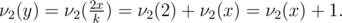
+
+From this observation it follows that for fixed *a**i*, *a**j*(*i* < *j*), we can construct a cool sequence *a**i* = *b**i*, *b**i* + 1, ... *b**j* - 1, *b**j* = *a**j* if and only if  and either ν2(*a**i*) + *j* - *i* = ν2(*a**j*) or ν2(*a**j*) ≤ *j* - *i* - 1.
+
+Now that we have this observation, we can finish the problem using dynamic programming where the *k*th state is the maximum number of *a**i* (*i* ≤ *k*) we can keep so that it is possible to make *a*1, ... *a**k* cool. Then the answer is just *n* - *max* (*dp*[1], *dp*[2], ..., *dp*[*n*]).
+
+**div 1 E** ****
+
+Here is a full solution to Codeforces 174 div 1 E. I find this problem beautiful. :)
+
+The first thing to note, is that, if you interpret the problem as a graph, you can compute the answer if you have the degrees (i.e. number of wins) of every cow. Call three cows ``unbalanced’’ if the is one cow that beats the other two. Note that every three cows is either unbalanced or balanced (there are no other configurations of three cows). Thus,
+
+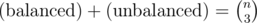
+
+So to count the number of balanced it suffices to count the number of unbalanced. But it is easy to show that 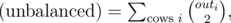 so 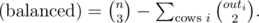
+
+So now we have reduced the problem to computing the number of wins for each cow. If we do this the dumb way, this is O(MN^2), still way too slow.
+
+Sort the skill levels of the cows (the order of the *s**i* doesn’t actually matter). *s*1 is lowest skill Now consider an *n* × *n* grid where the *i*th row and *j*th column of the grid is a 1 if the match between cow *i* and cow *j* is flipped. The grid is initially all zeros and Farmer John’s query simply flips a rectangle of the form [*a*, *b*] × [*a*, *b*], and the outdegree (#wins) of cow *i* is just (Number of 1’s in range [1,i — 1]) + (Number of 0’s in range [i + 1, N]) = (Number of 1’s in range [1,i — 1]) + (N — i — (Number of 1’s in range [i + 1, N]))
+
+We can process these queries and compute outdegrees using a sweep line with a seg tree on the interval [1,N]. The seg tree needs to handle queries of the form
+
+1. Flip all numbers (0->1, 1->0) in a range [*a*, *b*].
+2. Query number of 1’s in a range [*a*, *b*].
+
+Note that the seg tree needed to handle this is the same seg tree you need for problem ‘lites’ on USACO 2008 Gold <http://tjsct.wikidot.com/usaco-nov08-gold>.
+
+Once again, thanks for participating!
+
+abacadaea
diff --git a/editorials/284.md b/editorials/284.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/7037
+
+Hi Guys,
+
+Hope you enjoyed Round 174. :) I would like to add a few comments on some of the problems, beyond the [editorial.](//codeforces.com/blog/entry/7036)
+
+**div 2 A** ****
+
+If you know some math, you can actually solve this problem in  (!!!) You can show that the answer is φ (*p* - 1) where φ (*n*) is the number of positive integers *i* less than to *n* with *gcd*(*i*, *n*) = 1. To prove this we first show that there is always at least one primitive root  for all primes *p*. (This is a fairly well known result so I won’t prove it here, but you can find many proofs online) So now assume *g* is a primitive root  Then, the set {*g*, *g*2, ... *g**p* - 1} is congruent to the set {1, 2, ... , *p* - 1}. Furthermore, its not hard to show that *g**i* is a primitive root if and only if *gcd*(*i*, *p* - 1) = 1, (try it!) hence our formula φ (*p* - 1). φ (*n*) can be computed by getting the prime factors of *n*, since 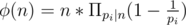 so this gives us our  algorithm. :)
+
+**div 1 D** ****
+
+Here is a full solution to Codeforces #174 div 1 D.
+
+Let ν2(*n*) denote the exponent of the largest power of 2 that divides *n*. For example ν2(5) = 0, ν2(96) = 5. Let *f*(*n*) denote the largest odd factor of *n*.
+
+Note the following formula for sum of arithmetic series:
+
+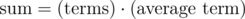
+
+I claim that the pair (*x*, *y*) is cool if and only if  and one of the following is true \begin{enumerate} \item ν2(*x*) + 1 = ν2(*y*) \item ν2(*y*) = 0 \end{enumerate} This can be proven by casework on the number on the parity of *y*.
+
+If *y* is odd, the average term of the arithmetic sequence is an integer, so *f*(*y*) = *y* divides *f*(*x*) and ν2(*y*) = 0.
+
+If *y* is even, the average is of the form .5·*k* where *k* is odd, so  so it follows that *y* divides *x* so *f*(*y*) divides *f*(*x*), and furthermore 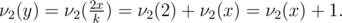
+
+From this observation it follows that for fixed *a**i*, *a**j*(*i* < *j*), we can construct a cool sequence *a**i* = *b**i*, *b**i* + 1, ... *b**j* - 1, *b**j* = *a**j* if and only if  and either ν2(*a**i*) + *j* - *i* = ν2(*a**j*) or ν2(*a**j*) ≤ *j* - *i* - 1.
+
+Now that we have this observation, we can finish the problem using dynamic programming where the *k*th state is the maximum number of *a**i* (*i* ≤ *k*) we can keep so that it is possible to make *a*1, ... *a**k* cool. Then the answer is just *n* - *max* (*dp*[1], *dp*[2], ..., *dp*[*n*]).
+
+**div 1 E** ****
+
+Here is a full solution to Codeforces 174 div 1 E. I find this problem beautiful. :)
+
+The first thing to note, is that, if you interpret the problem as a graph, you can compute the answer if you have the degrees (i.e. number of wins) of every cow. Call three cows ``unbalanced’’ if the is one cow that beats the other two. Note that every three cows is either unbalanced or balanced (there are no other configurations of three cows). Thus,
+
+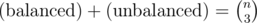
+
+So to count the number of balanced it suffices to count the number of unbalanced. But it is easy to show that 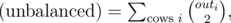 so 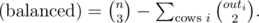
+
+So now we have reduced the problem to computing the number of wins for each cow. If we do this the dumb way, this is O(MN^2), still way too slow.
+
+Sort the skill levels of the cows (the order of the *s**i* doesn’t actually matter). *s*1 is lowest skill Now consider an *n* × *n* grid where the *i*th row and *j*th column of the grid is a 1 if the match between cow *i* and cow *j* is flipped. The grid is initially all zeros and Farmer John’s query simply flips a rectangle of the form [*a*, *b*] × [*a*, *b*], and the outdegree (#wins) of cow *i* is just (Number of 1’s in range [1,i — 1]) + (Number of 0’s in range [i + 1, N]) = (Number of 1’s in range [1,i — 1]) + (N — i — (Number of 1’s in range [i + 1, N]))
+
+We can process these queries and compute outdegrees using a sweep line with a seg tree on the interval [1,N]. The seg tree needs to handle queries of the form
+
+1. Flip all numbers (0->1, 1->0) in a range [*a*, *b*].
+2. Query number of 1’s in a range [*a*, *b*].
+
+Note that the seg tree needed to handle this is the same seg tree you need for problem ‘lites’ on USACO 2008 Gold <http://tjsct.wikidot.com/usaco-nov08-gold>.
+
+Once again, thanks for participating!
+
+abacadaea
diff --git a/editorials/285.md b/editorials/285.md
@@ -0,0 +1,21 @@
+Source: https://codeforces.com/blog/entry/7093
+
+[285A - Slightly Decreasing Permutations](/contest/285/problem/A "Codeforces Round 175 (Div. 2)")
+
+As the answer you can print such permutation: *n*, *n* - 1, ..., *n* - *k* + 1, 1, 2, ..., *n* - *k*. For example, if *n* = 5, *k* = 2, then the answer is: 5, 4, 1, 2, 3. If *k* = 0, you should print 1, 2, ..., *n*. Such solution can be written in two loops.
+
+[285B - Find Marble](/contest/285/problem/B "Codeforces Round 175 (Div. 2)")
+
+It is known that a permutation can be considered as set of cycles. The integer *i* moves to *p*[*i*] for all *i* (1 ≤ *i* ≤ *n*). You can start moving from integer *s* along the cycle. If you find integer *t*, then print the length of the path. If you return to *s*, then print - 1.
+
+[285C - Building Permutation](/contest/285/problem/C "Codeforces Round 175 (Div. 2)")
+
+The solution of the problem is rather simple. Sort all integers *a* and then make from integer *a*[1] integer 1, from integer *a*[2] integer 2 and so on. So, integer *a*[*i*] adds to the answer the value |*a*[*i*] - *i*|. The answer should be count in 64-bit type. You can simply guess why such solution is correct.
+
+[285D - Permutation Sum](/contest/285/problem/D "Codeforces Round 175 (Div. 2)")
+
+For a start, describe bruteforce solution. Firstly, we will always assume, that *a* is identity permutation, that is *a*[*i*] = *i*. In this case, the answer should be multiplied by *n*!. Or in other way your bruteforce will not be counted. Secondly, using our bruteforce we can see, that for even *n* the answer is 0.
+
+What do you also need to get accepted? First case is to calculate answers for all *n* on your computer and write them in constant array. In other words you can make precalc. Second case is to make you solution faster. The soltuion using meet-in-the-middle idea works fast for *n* ≤ 15. If you remember that for even *n* answer is 0 then you can get accepted using such solution. But other simple bruteforces and dynamic programmings on maps work slower than 3 seconds.
+
+[285E - Positions in Permutations](/contest/285/problem/E "Codeforces Round 175 (Div. 2)")
diff --git a/editorials/288.md b/editorials/288.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/7241
+
+Hi!
+
+##### [289A - Polo the Penguin and Segments](/contest/289/problem/A "Codeforces Round 177 (Div. 2)")
+
+**Solution.** First of all, we need to count, how many integers are inside given segments at the beginning. Since they don't intersect and even touch, no integer point can belong to more than one segment at the same time. This mans that starting value of segments is 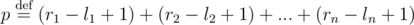.
+
+If *k* divides *p*, then answer is 0 — we don't need to do anything, it's already done. But if it's not true, we need to know the minimal number of turns to make *k* divisor of *p*. Since we can in single turn increase *p* by 1 (by decreasing the left point of the leftmost segment), this number is equal to 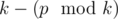.
+
+**Note.** Note that just output 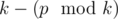 is not enough: you need to pay attention for case when , or just output 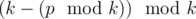.
+
+##### [289B - Polo the Penguin and Matrix](/contest/289/problem/B "Codeforces Round 177 (Div. 2)")
+
+**Solution.** First of all, we need to know when the answer is -1. For that you should notice that after any operation on number *z*, value  doesn't change. Indeed, 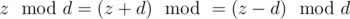. This means that there is not answer if there are two different points for which  is diffrent.
+
+Now we can transform our problem a bit. We can just write down all integers from matrix *n* × *m* to one array *b* of size *k* = *n* × *m* and sort them all in non-decreasing order. It is not hard to notice that in some of the optimal solutions, all number are at the end equal to one of the number for starting array. But also, it is optimal to make all number equal to  (median element). Why to median? Suppose that we make all numbers equal to non-median element with index *x*. Then if |*x* - (*k* - *x*)| > 1 (i. e. from one side there are more elements than from another + 1). So, by moving out element more to median, we can make result better.
+
+After we know, to which number we should bring all, the answer is just 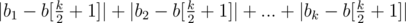, divided by *d*.
+
+**Note.** There is also full solution with complexity *O*(*n*2*m*2).
+
+##### [288A - Polo the Penguin and Strings](/contest/288/problem/A "Codeforces Round 177 (Div. 1)")
+
+**Solution.** To solve this problem we need to find out some contruction of resulting string. But first of all, we need find out when there is no result. Obviously, if *k* > *n*, there is not result — you cannot build string of length *n* with more than *n* characters. Another one case is when *k* = 1 and *n* > 1 — there is no answer in that case also.
+
+Consider that *k* = 2. It's really easy to see that answer for such case is a string of form *abababab*.... To construct string for *k* > 2 you need to add some extra characters — *c*, *d*, *e*.... To make string lexicographically smallest, you need to add that characters as close to the end as we can. And the best bet here is *abbabab*...*abacdefgh*.... So, we need just to add characters *c*, *d*, *e*, *f*... (i. e. *k* - 2 characters from *c*) to the end of the string.
+
+##### [288B - Polo the Penguin and Houses](/contest/288/problem/B "Codeforces Round 177 (Div. 1)")
+
+**Solution.** Since *k* ≤ 8 you can solve this problem using brute force. This means that you can recursively construct all possible *k**k* possibilities of first *k* assignments. (For *k* = 8 this is equal to 16 777 216.) For each of that assignments you need to check whether it is correct or not (by problem statement). Ths can be simply done using loops.
+
+When you know the number of assignment for the first *k* tables (let it be *f*(*k*)), all you need to do is to count the number of assignment for the rest *n* - *k* plaques. Since there should bo no path to 1, there should be no path to any of first *k* houses, so at each plaque for houses from *k* + 1 to *n* there can be any number from *k* + 1 to *n*, inclusive. There are (*n* - *k*)*n* - *k* such possibilities. And hence the total answer is *f*(*k*)(*n* - *k*)*n* - *k*.
+
+**Note.** There also exists solution with dynamic programming, and also there exists formula for *f*(*x*). You can read about it more [here](//codeforces.com/blog/entry/7225), [here](//codeforces.com/blog/entry/7237) и [here](//codeforces.com/blog/entry/7227).
+
+##### [288C - Polo the Penguin and XOR operation](/contest/288/problem/C "Codeforces Round 177 (Div. 1)")
+
+**Solution.** Since we need to maximize the result, we need to find such permutation, for which the least number of bit disappear. (We consider bit disappeared if it was 1 both in *i* and *p**i*, so in  it is 0). It turns out that for each *n* there is such permutation that no bit disappear. How to build it? We will be solving problem by iterations while *n* > 0. On each iteration, we need to find the biggest (the leftmost in binary representation) bit which is not 0 in binary representation of *n* and denote it position (bits are numbered from 0) by *b*. Now we need to find integer *m* — minimal integer from 0 to *n*, inclusive, such that *b*-th bit is also 1 in it. After that you can see (look image below), that at  no bit disappear, at 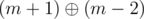 no bit disappear, ..., at 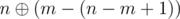 no bit disappear. So, it is good to assign exactly that integers to our permutation, i. e. *p**m* = *m* - 1 and *p**m* - 1 = *m*, *p**m* + 1 = *m* - 2 and *p**m* - 2 = *m* + 1 and so on. After that assign value *m* - (*n* - *m* + 1) - 1 to *n* and go to next iteration.
+
+
+
+Now when we know how to build permutation and that no bit disappear, the value of the answer is equal to 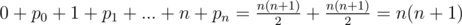.
+
+##### [288D - Polo the Penguin and Trees](/contest/288/problem/D "Codeforces Round 177 (Div. 1)")
+
+**Solution.** As always in such problems, root our tree at some vertex, for example vertex with number 1. We need to find out, what will happen when we have already chosen one path. Obviously, after deleting all vertices and their edges from that path, tree will disintegrate in some set of trees. Denote their sizes by *c*1, *c*2, ..., *c**k*, where *k* is the number of trees. Then the number of ways to choose the second path is equal to 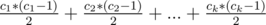. This gives us *O*(*n*2) solution — just to brute force all pathes and count the number of second paths by this formula. We need to do it in *O*(*n*). To do so, dfs our graph and fix some vertex during dfs, we will consider this vertex as the last vertex in the first path. Now we need to find the sum of above formula for the rest of the vertex. Here you can separately solve this problem for all vertex inside subtree of current vertex and for the rest of the vertices. For subtree vertices, you can, after finding the answers for all vertices of subtree, find the answer for root of subtree. To do so, you need to iterate all edges from current vertex and sum up results for that vetices. Also you need to add the sum of values  multiplied by the number of vertices in subtree, where *d**i* are all sizes of subtrees of vertices from current vertex, not including from current edge). You can use some partial sums of something like that to make it linear. For the rest of the vertices (not in subtree) it is actually similar, but a bit harder. Here you need to keep current result as a parameter of dfs and when you entering some vertex you should add some additional counts to the current sum (similarly as in first case).
+
+**Note.** Also, you can find the number of bad pairs of pathes and subtract it from the total number. Also some divide and coquer solution exists, you can think about it.
+
+##### [288E - Polo the Penguin and Lucky Numbers](/contest/288/problem/E "Codeforces Round 177 (Div. 1)")
+
+**Solution.** In this problem there are a lot of different formulas, most of them are for optimizing solution and making it lenear. Editorial shows just a general idea because it's pretty hard to explain all of them and good for you to derive it by yourself. If you have any questions — write them all in comments.
+
+Denote by *a*1, *a*2, ..., *a**n* all lucky number from segment. First of all, we need to do reduce the problem a bit. Let we have some fixed digit (*pos*, *d*), i. e. position of this digit is *pos* (from 0 from right to left) and value is *d* (4 or 7). Then, for all *a**i* (1 ≤ *i* < *n*) such that *pos*-th digit of *a**i* is equal to *d*, we need to add *a**i* + 1 × *d* × 10*pos* to the answer. Now we can see that problem can be reduced to the following. For each fixed digit (*pos*, *d*) find the sum of all *a**i* such that *a**i* + 1 on the *pos*-th position has digit *d*. Obviously, we can solve the problem for 1..*l* and 1..*r* separately and then subtract the first from the second — that will be the answer.
+
+How to find such sum among all lucky numbers of some length but less than some lucky number *x*? We will describe the general idea. Any lucky number, less than *x* has some common prefix with *x*, then one digit is less than the corresponing in *x* (i. e. it is 7 in *x* and 4 in another integer) and the rest of the digits are arbitrary. So, by iterating all such positions where is the first digit less than in *x*, we can, using the fact that the rest of the digits are arbitrary and some formulas and precomputations, compute the results for each position and digit.
diff --git a/editorials/289.md b/editorials/289.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/7241
+
+Hi!
+
+##### [289A - Polo the Penguin and Segments](/contest/289/problem/A "Codeforces Round 177 (Div. 2)")
+
+**Solution.** First of all, we need to count, how many integers are inside given segments at the beginning. Since they don't intersect and even touch, no integer point can belong to more than one segment at the same time. This mans that starting value of segments is 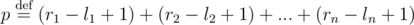.
+
+If *k* divides *p*, then answer is 0 — we don't need to do anything, it's already done. But if it's not true, we need to know the minimal number of turns to make *k* divisor of *p*. Since we can in single turn increase *p* by 1 (by decreasing the left point of the leftmost segment), this number is equal to 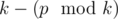.
+
+**Note.** Note that just output 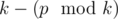 is not enough: you need to pay attention for case when , or just output 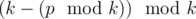.
+
+##### [289B - Polo the Penguin and Matrix](/contest/289/problem/B "Codeforces Round 177 (Div. 2)")
+
+**Solution.** First of all, we need to know when the answer is -1. For that you should notice that after any operation on number *z*, value  doesn't change. Indeed, 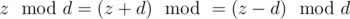. This means that there is not answer if there are two different points for which  is diffrent.
+
+Now we can transform our problem a bit. We can just write down all integers from matrix *n* × *m* to one array *b* of size *k* = *n* × *m* and sort them all in non-decreasing order. It is not hard to notice that in some of the optimal solutions, all number are at the end equal to one of the number for starting array. But also, it is optimal to make all number equal to  (median element). Why to median? Suppose that we make all numbers equal to non-median element with index *x*. Then if |*x* - (*k* - *x*)| > 1 (i. e. from one side there are more elements than from another + 1). So, by moving out element more to median, we can make result better.
+
+After we know, to which number we should bring all, the answer is just 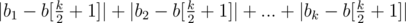, divided by *d*.
+
+**Note.** There is also full solution with complexity *O*(*n*2*m*2).
+
+##### [288A - Polo the Penguin and Strings](/contest/288/problem/A "Codeforces Round 177 (Div. 1)")
+
+**Solution.** To solve this problem we need to find out some contruction of resulting string. But first of all, we need find out when there is no result. Obviously, if *k* > *n*, there is not result — you cannot build string of length *n* with more than *n* characters. Another one case is when *k* = 1 and *n* > 1 — there is no answer in that case also.
+
+Consider that *k* = 2. It's really easy to see that answer for such case is a string of form *abababab*.... To construct string for *k* > 2 you need to add some extra characters — *c*, *d*, *e*.... To make string lexicographically smallest, you need to add that characters as close to the end as we can. And the best bet here is *abbabab*...*abacdefgh*.... So, we need just to add characters *c*, *d*, *e*, *f*... (i. e. *k* - 2 characters from *c*) to the end of the string.
+
+##### [288B - Polo the Penguin and Houses](/contest/288/problem/B "Codeforces Round 177 (Div. 1)")
+
+**Solution.** Since *k* ≤ 8 you can solve this problem using brute force. This means that you can recursively construct all possible *k**k* possibilities of first *k* assignments. (For *k* = 8 this is equal to 16 777 216.) For each of that assignments you need to check whether it is correct or not (by problem statement). Ths can be simply done using loops.
+
+When you know the number of assignment for the first *k* tables (let it be *f*(*k*)), all you need to do is to count the number of assignment for the rest *n* - *k* plaques. Since there should bo no path to 1, there should be no path to any of first *k* houses, so at each plaque for houses from *k* + 1 to *n* there can be any number from *k* + 1 to *n*, inclusive. There are (*n* - *k*)*n* - *k* such possibilities. And hence the total answer is *f*(*k*)(*n* - *k*)*n* - *k*.
+
+**Note.** There also exists solution with dynamic programming, and also there exists formula for *f*(*x*). You can read about it more [here](//codeforces.com/blog/entry/7225), [here](//codeforces.com/blog/entry/7237) и [here](//codeforces.com/blog/entry/7227).
+
+##### [288C - Polo the Penguin and XOR operation](/contest/288/problem/C "Codeforces Round 177 (Div. 1)")
+
+**Solution.** Since we need to maximize the result, we need to find such permutation, for which the least number of bit disappear. (We consider bit disappeared if it was 1 both in *i* and *p**i*, so in  it is 0). It turns out that for each *n* there is such permutation that no bit disappear. How to build it? We will be solving problem by iterations while *n* > 0. On each iteration, we need to find the biggest (the leftmost in binary representation) bit which is not 0 in binary representation of *n* and denote it position (bits are numbered from 0) by *b*. Now we need to find integer *m* — minimal integer from 0 to *n*, inclusive, such that *b*-th bit is also 1 in it. After that you can see (look image below), that at  no bit disappear, at  no bit disappear, ..., at 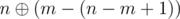 no bit disappear. So, it is good to assign exactly that integers to our permutation, i. e. *p**m* = *m* - 1 and *p**m* - 1 = *m*, *p**m* + 1 = *m* - 2 and *p**m* - 2 = *m* + 1 and so on. After that assign value *m* - (*n* - *m* + 1) - 1 to *n* and go to next iteration.
+
+
+
+Now when we know how to build permutation and that no bit disappear, the value of the answer is equal to 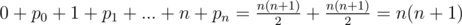.
+
+##### [288D - Polo the Penguin and Trees](/contest/288/problem/D "Codeforces Round 177 (Div. 1)")
+
+**Solution.** As always in such problems, root our tree at some vertex, for example vertex with number 1. We need to find out, what will happen when we have already chosen one path. Obviously, after deleting all vertices and their edges from that path, tree will disintegrate in some set of trees. Denote their sizes by *c*1, *c*2, ..., *c**k*, where *k* is the number of trees. Then the number of ways to choose the second path is equal to 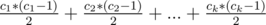. This gives us *O*(*n*2) solution — just to brute force all pathes and count the number of second paths by this formula. We need to do it in *O*(*n*). To do so, dfs our graph and fix some vertex during dfs, we will consider this vertex as the last vertex in the first path. Now we need to find the sum of above formula for the rest of the vertex. Here you can separately solve this problem for all vertex inside subtree of current vertex and for the rest of the vertices. For subtree vertices, you can, after finding the answers for all vertices of subtree, find the answer for root of subtree. To do so, you need to iterate all edges from current vertex and sum up results for that vetices. Also you need to add the sum of values  multiplied by the number of vertices in subtree, where *d**i* are all sizes of subtrees of vertices from current vertex, not including from current edge). You can use some partial sums of something like that to make it linear. For the rest of the vertices (not in subtree) it is actually similar, but a bit harder. Here you need to keep current result as a parameter of dfs and when you entering some vertex you should add some additional counts to the current sum (similarly as in first case).
+
+**Note.** Also, you can find the number of bad pairs of pathes and subtract it from the total number. Also some divide and coquer solution exists, you can think about it.
+
+##### [288E - Polo the Penguin and Lucky Numbers](/contest/288/problem/E "Codeforces Round 177 (Div. 1)")
+
+**Solution.** In this problem there are a lot of different formulas, most of them are for optimizing solution and making it lenear. Editorial shows just a general idea because it's pretty hard to explain all of them and good for you to derive it by yourself. If you have any questions — write them all in comments.
+
+Denote by *a*1, *a*2, ..., *a**n* all lucky number from segment. First of all, we need to do reduce the problem a bit. Let we have some fixed digit (*pos*, *d*), i. e. position of this digit is *pos* (from 0 from right to left) and value is *d* (4 or 7). Then, for all *a**i* (1 ≤ *i* < *n*) such that *pos*-th digit of *a**i* is equal to *d*, we need to add *a**i* + 1 × *d* × 10*pos* to the answer. Now we can see that problem can be reduced to the following. For each fixed digit (*pos*, *d*) find the sum of all *a**i* such that *a**i* + 1 on the *pos*-th position has digit *d*. Obviously, we can solve the problem for 1..*l* and 1..*r* separately and then subtract the first from the second — that will be the answer.
+
+How to find such sum among all lucky numbers of some length but less than some lucky number *x*? We will describe the general idea. Any lucky number, less than *x* has some common prefix with *x*, then one digit is less than the corresponing in *x* (i. e. it is 7 in *x* and 4 in another integer) and the rest of the digits are arbitrary. So, by iterating all such positions where is the first digit less than in *x*, we can, using the fact that the rest of the digits are arbitrary and some formulas and precomputations, compute the results for each position and digit.
diff --git a/editorials/29.md b/editorials/29.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/686
+
+Problem A:
+Check whether exist a pair i and j,they satisfy xi+di = xj && xj+dj = xi;
+
+Problem B:
+Pay attention to Just Right or Red. use Div and Mod can solve it easily;
+
+Problem C:
+As we know, there are only two path -- forward and reverse, so we can do DFS from the one-degree nodes (only two nodes).
+As their index may be very larger, so I used map<int,int> to do hash.
+
+void dfs(int i)
+{
+ int sz = mat[i].size()-1, j;
+ UF(j,0,sz)
+ if (!vis[mat[i][j]])
+ {
+ vis[mat[i][j]] = 1;
+ printf(" %d",val[mat[i][j]]);
+ dfs(mat[i][j]);
+ }
+}
+
+Problem D:
+Floyd.
+First, Floyd pretreat the path from I to J, and save the path.
+Then get the answer.
+The order is a1,a2...ak, K is the number of the leaves, we can assume a0 = ak+1 = 1, the root.
+then, answer push_back the path[ai][ai+1].
+
+if the ans.size() > 2*N-1 , cout -1;
+else cout the answer.
diff --git a/editorials/290.md b/editorials/290.md
@@ -0,0 +1,50 @@
+Source: https://codeforces.com/blog/entry/7216
+
+The contest is over; I hope you've enjoyed it. 1465 participants submitted at least one problem correctly. Unfortunately, nobody managed to solve all 6 problems; congratulations to [ShadowSong](/profile/ShadowSong "Expert ShadowSong") who won the contest by solving 5 first problems with the lowest penalty time!
+
+#### [290A - Mysterious strings](/contest/290/problem/A "April Fools Day Contest 2013")
+
+Last year we've verified that a lack of problem statement doesn't prevent participants from solving and submitting the problem successfully and at the same time saves the problem setter some writing effort. This year we've ascertained this again. Well, I could've invented a long and knotty legend about you, a young but very promising software developer, were summoned to White House and given a task of utmost importance: to deliver an interactive list of USA presidents from founding fathers to our days. It could have featured a dramatic time-consuming search for necessary info, pursuits, firefights, a wounded teammate whose dying words were "Eight is Van Buren, don't forget... print Van, just Buren... doesn't pass". But what for? Three samples and a favorite search engine (I won't name it for the sake of political correctness) are all you need to figure out the dependency between input and output: index number N — surname of N-th USA president, as well as to find all necessary data.
+
+#### [290B - QR code](/contest/290/problem/B "April Fools Day Contest 2013")
+
+A statement consisting of a single image looks a bit funnier. One can invent countless functions which convert a pair of integers into a third integers and fit the set of samples from the statement, starting with "0 if numbers have the same parity and 1 otherwise". To avoid trying them all (since that would take much longer than the contest duration) one has to look for a clue in the image. Any online QR-code decoder will give you a link hidden in the code, which will point you to a text file consisting of 0 and 1. If you take a closer look at the file, you'll recognize the same QR-code in it, written block-by-block — 1 for black blocks and 0 for white ones. A hint which points to itself... Maybe that is the statement? Input ranges from 0 to 32, and what are the dimensions of the image, 33 x 33?
+
+Indeed, the problem asked to return the color of the image block in the given row (first number) and column (second number). The text file is given mostly to save people who have already figured out the task the trouble of generating this array.
+
+#### [290C - WTF?](/contest/290/problem/C "April Fools Day Contest 2013")
+
+Finally, a real problem statement in plain text! Reading... WTF?
+
+To decode this statement, one has either to recall who the problemsetter is and how much I love weird programming languages, or to extract a couple of keywords from the statement and look for them online. HAI and KTHXBYE are enough of a pointer to [Lolcode](http://progopedia.com/language/lolcode/) esoteric language; all you have to do is to figure out what this program does, and to replicate this in any regular language. Once again, there are two ways to do this: find a list of language commands and read through the code, or find an online interpreter and try to run the program on various inputs.
+
+If this problem was to have a proper legend, it would be as follows. You are given a sequence of duels a game character had; there were no ties, so every duel ended in a victory or defeat. Character's rating is defined as a ratio "victories number" / "total duels number". Find the highest rating the character ever had.
+
+#### [290D - Orange](/contest/290/problem/D "April Fools Day Contest 2013")
+
+Here goes another picture instead of a statement, this time in lovely shades of orange. A person with some experience of contests written by me might reasonably guess that this is another programming language, but even less known than usual: [Baltie](http://progopedia.com/language/baltie/). Baltie interpreter exists for Windows only, and doesn't really allow copying this program into it, so it might be easier to make a guess about the meaning of individual command icons. Boxes are variables, arrow certainly looks like assignment, loop and if-then-else are inscribed, but the rest of them will require an effort...
+
+One might also choose another way (which, I suspect, most people did) and figure out the task from the single sample. The contents of the string evidently doesn't change, only the case of certain letters... A bit of magic — and we realize that one has to convert first N letters of English alphabet to uppercase and the rest of them — to lowercase.
+
+#### [290E - HQ](/contest/290/problem/E "April Fools Day Contest 2013")
+
+This problem made you think twice: before understanding the statement and after that. A quick glance at [HQ9+](http://progopedia.com/language/hq9-plus/) reveals that H and Q are commands which print "Hello, World!" and the source code of the program being executed, respectively. One can reasonably guess that HQ language consists of the same two commands which do more-or-less the same thing. To advance further, one has to put in quite some thought: theories like "given program source, return Yes if the output has even length" turn out to be very wrong. Actually things are the other way around: you are given program output instead of its source (H command prints just H, no extra letters), and you have to figure out whether there exists a program which can generate this output. Alas, only a few people managed to guess this and appreciate the beauty of the problem. Once again congratulations to [ShadowSong](/profile/ShadowSong "Expert ShadowSong") who was first to submit the problem only after one hour of the contest!
+
+How to solve this? First of all, make several useful observations. If the original program has nH characters H and nQ characters Q, each H will print one H, and each Q will print nH Hs and nQ Qs. So the number of Qs in the output must be an exact square of nQ (possibly 0), and you can either immediately conclude that the output is impossible to generate or get to know nQ. Similarly the number of Hs in output equals nH * (nQ + 1), and either the output is impossible or you get to know nH.
+
+With smaller constraint this would be enough to solve the problem by trying all possible permutations of known quantities of H and Q and comparing the output of each permutation with the given one. But having output up to 10^6 rules this approach out, and one has to keep thinking. Find the first Q in the output; evidently, it appeared there as a result of executing the first Q command. Half of preceding Hs will appear as a result of executing this very Q, the other half — as a result of executing individual H commands. So again, we can either mark the output as impossible (if the number of Hs before first Q is odd) or get to know the number of H before first Q in the original program. Exactly the same logic allows to figure out the number of H after last Q in the program.
+
+And finally one last step. First nQ Qs appear in the output as a result of executing the same Q command. So if we take first and nQ-th Q characters of the output, the piece of output between them and prefix and suffix of Hs of known lengths, we'll get the original program! You just have to verify that this program really generates necessary output (the difference can creep in after first nQ Qs).
+
+#### [290F - Greedy Petya](/contest/290/problem/F "April Fools Day Contest 2013")
+
+This problem was contributed by [Gerald](/profile/Gerald "Master Gerald") and reveals a different aspect of problemsetters' sense of humor. We spent most of the second hour of the contest feeling more and more disappointed about underestimating the complexity of the task, but [Deamon](/profile/Deamon "Candidate Master Deamon") saved us by submitting the only solution barely three minutes before the contest end.
+
+The task was to guess and reproduce the exact wrong solution written by Petya for finding Hamiltonian path (the third sample showed quite clearly that his solution is in fact wrong). Petya turned out to use a well-known greedy approach:
+
+1. Store the graph as adjacency lists.
+2. Remove all multiple edges and self-edges.
+3. Sort vertices in lists in increasing order of vertex degrees (vertices with equal degrees get sorted by index).
+4. Try all possible candidates for the starting vertex of the path and try to move from current vertex to a yet unvisited vertex in order of corresponding adjacency list.
+
+If the algorithm doesn't find a loop, output "No".
diff --git a/editorials/292.md b/editorials/292.md
@@ -0,0 +1,32 @@
+Source: https://codeforces.com/blog/entry/7371
+
+[292A - SMS-центр](/contest/292/problem/A "Чемпионат КРОК 2013 - Раунд 1")
+
+Для каждого момента *i* времени запомним количество сообщений *z*[*i*], которое нужно отправить в момент времени *i*. Теперь пройдем по каждому моменту времени от 1 до 106, поддерживая текущий размер очереди *sz*. На каждой итерации попробуем уменьшить размер очереди на 1, то есть выполним *sz* = *max*(*sz* - 1, 0), затем прибавим сообщения, которые нужно отправить в эту секунду, то есть выполним *sz* = *sz* + *z*[*i*]. На каждом шаге будем обновлять максимальное значение очереди и текущее время, если *sz* > 0. После выполнения цикла, если в очереди остались неотправленные сообщения, то нужно еще раз обновить ответ.
+
+[292B - Топология сети](/contest/292/problem/B "Чемпионат КРОК 2013 - Раунд 1")
+
+В этой задаче нужно было посчитать степени каждой вершины и найти ответ. Замечу, поскольку *n* > = 4, *m* > = 3 и граф связный, то ответ однозначный.
+
+1) все степени 2 и у двух вершин степень 1 — шина.
+2) все степени 2 — кольцо
+3) все степени 1 и у одной степень > 2 — звезда
+4) иначе неизвестно
+
+[292C - Красивые IP-адреса](/contest/292/problem/C "Чемпионат КРОК 2013 - Раунд 1")
+
+Задача решается перебором. Для начала переберем сколько цифр в каждом четверти мы возьмем, например *AAA*.*B*.*CC*.*DDD*. Теперь посчитаем количество символов в этой строке (*AAABCCDDD*) и переберем цифры на первой половине этой строки (поскольку строка должна быть палиндромом, то вторая половина однозначно восстанавливается). После этого проверим, что такой ip-адрес является корректным и содержит правильный набор цифр. Если ip-адрес удовлетворяет всем условиям задачи, то добавим его к ответу.
+
+[292D - Компоненты связности](/contest/292/problem/D "Чемпионат КРОК 2013 - Раунд 1")
+
+Ограничения в задаче были не слишком удачными и провоцировали писать решение за квадрат, мы постарались максимально не позволить таким решениям пройти.
+
+У этой задачи много правильных решений. Изначально планировалось решение, которое предподсчитывает частичные *dsu* (структура данных disjoint set union) на префиксах и на суффиксах, то есть массивы *ldsu*[*M*][*N*] и *rdsu*[*M*][*N*]. После этого на запрос [*lf* ; *rg*] легко ответить за время *O*(*N*·*A*- 1), если объединить множества *ldsu*[*lf* - 1] и *rdsu*[*rg* + 1], где *A*- 1 -- обратная функция Аккермана (константа от dsu).
+
+[292E - Копирование данных](/contest/292/problem/E "Чемпионат КРОК 2013 - Раунд 1")
+
+У этой задачи много правильных решений. Изначально предполагалось решение, использующие корневую эвристику. Разобьем все запросы на *sqrt*(*m*) блоков. Будем поддерживать текущий массив *b* в виде отрезков в массиве *z*, который хранит четверки (*lf*, *rg*, *type*, *start*), где *lf*, *rg* — отрезок индексов массива *b*, *type* — 0 или 1, означающее из какого массива взяты числа для этого отрезка, *start* — позиция начала этого отрезка в массиве типа *type*.
+
+На запросы будем отвечать в тупую, то есть честно пересчитывать как изменится массив *z* от запроса копирования и отвечать на запросы значения в позициях. Однако, каждые *sqrt*(*m*) запросов будем сливать данные из массива *z* в массив *b*, для того чтобы сам массив *z* сильно не разрастался.
+
+Есть простое решение с деревом отрезков, которое умеет делать покраску на отрезке. Пусть пришел запрос копирования [*lf* ; *rg*], , тогда покрасим отрезок запроса [*lf* ; *rg*] в цвет, равный номеру запросу. Все запросы будем сохранять. Пусть пришел запрос значения в позиции *x*, тогда найдем цвет в дереве в этой позиции. Если такого цвета нет, значит мы находимся в исходном массиве *b* (выведем *b*[*x*]), иначе посчитаем смещение *dx* от начала этого запроса до нашей позиции *x* и выведем *a*[*x* + *dx*].
diff --git a/editorials/293.md b/editorials/293.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/7516
+
+Here you can find the solutions for the problems from the past round. You can ask questions in the comments below.
+
+**[A Div 2](//codeforces.com/contest/299/problem/A)**
+
+If *a**i* divide *a**j* than *a**i* ≤ *a**j*. So the number which will divide every other number should be less than or equal to every other number, so the only possible candidate — it's the minimum in the array. So just check whether all elements are divisible by the minimal one.
+
+**[B Div 2](//codeforces.com/contest/299/problem/B)**
+
+Easy to see, that Ksusha is unable to complete her journey if there is a sequence of consecutive # with length more than k.
+
+**[C Div 2](//codeforces.com/contest/299/problem/C) / [A Div 1](//codeforces.com/contest/293/problem/A)**
+
+The first observation — we don't care about the actual strings, all information we need — number of pairs {0,0}, {0,1}, {1,0}, {1,1}. Count that and then just follow the greedy algorithm, for the first player: try to get a index with {1,1} if there are some, than {1,0}, than {0,1} and than {0,0}.
+
+For the second player similar strategy: first {1,1}, than {0,1}, than {1,0}, than {0,0}.
+
+After that just compare who has more 1.
+
+**[D Div 2](//codeforces.com/contest/299/problem/D) / [B Div 1](//codeforces.com/contest/293/problem/B)**
+
+Every path from the topleft cell to the bottomright cell contain exactly *n* + *m* - 1 cells. And all of the should be of different color. So *n* + *m* - 1 ≤ *k*. Due to the small constraints for k we may assume that bruteforce might work. The only optimization to get the correct solution is some canonization of the colors. So let's go over all of the cells in some order and color them but with following condition. If i > j, than color i appeared later than color j. If we bruteforce in such way we will have about 1 million different patterns for max case. Than just match them with already painted cells and calculate for each pattern how many different permutations of color we can apply to it.
+
+**[E Div 2](//codeforces.com/contest/299/problem/E) / [C Div 1](//codeforces.com/contest/293/problem/C)**
+
+After reading the problem statement one can understand that all we need is to calculate the number of positive integer solutions of equation: (*a* + *b* + *c*)3 - *a*3 - *b*3 - *c*3 = *n*.
+
+The key observation is: 3(*a* + *b*)(*a* + *c*)(*b* + *c*) = (*a* + *b* + *c*)3 - *a*3 - *b*3 - *c*3, after that simply calculate all divisors of  and then first go over all *x* = *a* + *b*, such that  then go over all *y* = (*a* + *c*) ≥ *x*, such that  and then determine *z* = (*b* + *c*), such that . After that we need to solve the system *a* + *b* = *x*, *a* + *c* = *y*, *b* + *c* = *z* and find out how many solutions it adds.
+
+**[D Div 1](//codeforces.com/contest/293/problem/D)**
+
+We can see that we asked to calculate 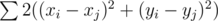 for all integer points inside the polygon or on its border. We can see that we can process Xs and Ys independently.
+
+For each *x* determine *y**left*, *y**right*, such that all points (*x*, *y*) where *y**left* ≤ *y* ≤ *y**right* are inside the polygon and the range [*y**left*, *y**right*] is as maximal as possible. Now let's assume that we have *a*1, *a*2, ..., *a**k* different points with fixed x coordinate (*a*1 stands for *x* = - 106, *a*2 for *x* = - 106 + 1 and so on).
+
+Now the required answer is *a*2*a*1 + *a*3(*a*2 + 22*a*1) + *a*4(*a*3 + 22*a*2 + 32*a*1) + ...
+
+We can see that:
+
+(*a*2 + 22*a*1) - *a*1 = *a*2 + 3*a*1,
+
+(*a*3 + 22*a*2 + 32*a*1) - (*a*2 + 22*a*1) = *a*3 + 3*a*2 + 5*a*1,
+
+and so on.
+
+So we can precalculate partial sums like *a*2 + 3*a*1, *a*3 + 3*a*2 + 5*a*1, *a*4 + 3*a*3 + 5*a*2 + 7*a*1 (the difference between two consecutive sums is 2(*a**i* + ... + *a*1), so we can do that in *O*(*k*) time).
+
+After this precomputation we just need to sum the results.
+
+**[E Div 1](//codeforces.com/contest/293/problem/E)**
+
+Let's assume that we have a data structure which can perform such operations as: — add point (x,y) to the structure;
+
+* shift all points in the structure by vector (dx,dy);
+* answer how many point (x,y) are in the structure where *x* ≤ *x**bound*, *y* ≤ *y**bound*;
+* get all elements which are now in the structure;
+
+For every vertex of the tree we will store the pointer to such structure.
+
+How we update the structures. We will proceed all the vertices in dfs order, if we are in a leaf node, than we create structure which contains only one element (0,0).
+
+Otherwise we will sort the children structures by it's size in decreasing order and assign the pointer of the biggest structure to the pointer of the current vertex (Don't forget to shift the structure by (1, weight of edge)).
+
+After that we will go over all other children one by one and do the following thing:
+
+* Shift the structure by (1, weight of edge);
+* Get all elements from the structure;
+* For every element (x,y) answer the query *x**bound* = *L* - *x*, *y**bound* = *W* - *y* (we use parent's structure);
+* Add elements one by one into the structure;
+
+After that answer the query *x**bound* = *L*, *y**bound* = *W* and add element (0,0).
+
+The sum of the results of all the queries is our answer. It's easy to see that there will be no more than  queries and add operations.
+
+The remaining part is designing the structure.
+
+It can be done in many ways. One of the ways:
+
+* We have small structures with sizes equals to powers of two;
+* Each structure — it's two-dimensional segments tree;
+* We can add one element in a following way: if there is no substructure with size 1, than add it; else get structures with sizes 1, 2, 4, ..., 2*k* and all its' elements and rebuild the structure with size 2*k* + 1;
+* Shifting — just remember shifting vector for every substructure;
+* Answering the query — go over all substructures and add the results.
+
+Editorial was prepared by [sdya](/profile/sdya "International Grandmaster sdya") and [Seyaua](/profile/Seyaua "International Master Seyaua")
diff --git a/editorials/294.md b/editorials/294.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/7287
+
+#### [294A - Shaass and Oskols](/contest/294/problem/A "Codeforces Round 178 (Div. 2)")
+
+Although Oskol is not really name of a specie of birds, In Iran it's known as a kind of bird which is very forgetful and can't even remember his way back to home when he flies away! It's commonly used instead of the word "stupid" among the kids! :D
+
+In this problem you just have to now how many birds are there on each wire after each shot. A good trick for the first and the last wire would be to define wires 0 and *n* + 1. In this way the birds that fly away sit on these wires and you don't need to worry about accessing some element outside the range of your array.
+
+Here is a neat implementation in C++ from contestant [rpslive](/profile/rpslive "Newbie rpslive"): [3484601](/contest/294/submission/3484601 "Submission 3484601 by rpslive")
+
+#### [294B - Shaass and Bookshelf](/contest/294/problem/B "Codeforces Round 178 (Div. 2)")
+
+As said in the statement, the thickness of each book is either 1 or 2. Think about when we want to arrange *v*1 books of thickness 1 and *v*2 books of thickness 2 vertically and arrange all other *n* - *v*1 - *v*2 books horizontally above them to achieve a configuration with total thickness of vertical books equal to *v*1 + 2*v*2. Is it possible to find such arrangement? Because the total thickness of vertical books is fixed it's good to calculate the minimum possible total width of horizontal books. As the width of a book doesn't matter in vertical arrangement it's good to use the books with shorter width horizontally and the ones with longer width vertically. So pick out *v*1 books with longest width among books of thickness 1 and do the same with books of thickness 2. The sum of width of *n* - *v*1 - *v*2 remaining books should be at most *v*1 + 2*v*2.
+
+The solution would be to try the things we explained above for all possible values of *v*1 and *v*2. And print the best answer. :)
+
+There exists other ways to solve this problem mostly using dynamic programming but this was the intended solution of the problem.
+
+Here is a nice implementation in C++ from contestant [bayram](/profile/bayram "Expert bayram"): [3485189](/contest/294/submission/3485189 "Submission 3485189 by bayram") (You should also know that 'bir' means 'one' in Turkish and 'iki' means two!)
+
+#### [294C - Shaass and Lights](/contest/294/problem/C "Codeforces Round 178 (Div. 2)")
+
+I just want to solve the third sample of this problem for you and you can figure out the rest by yourself. :)
+
+The third sample is `...#...#...` where `#` is a switched on lamp and `.` is a switched off lamp. As you can see we have three different types of lights. The first three lights (Type A), the 5th to 8th lights (Type B) and the last three lights (Type C). We have to switch on the lights three times for each type of lights. Aside from the order of moves for each type there are  possible permutations of the string AAABBBCCC which tells us how to combine the steps of different types. Switching on the lights is done uniquely for types 1 and 3. But for type 2 each time we have to possible options until we're left with one off light. So there are 23 - 1 ways to do this. So the answer would be `1680*1*4*1 = 6720`.
+
+The general solution would be to find all groups off consecutive switched off lamps and calculate the number of ways to combine all these groups. Then for each group you should calculate in how many ways it can be solved.
+
+The implementation needs some standard combinatorial computations which you can see here: [3485187](/contest/294/submission/3485187 "Submission 3485187 by alex20030190")
+
+#### [294D - Shaass and Painter Robot](/contest/294/problem/D "Codeforces Round 178 (Div. 2)")
+
+TODO
+
+#### [294E - Shaass the Great](/contest/294/problem/E "Codeforces Round 178 (Div. 2)")
+
+TODO
+
+I promise the editorial will be completed come soon soon soon! :)
diff --git a/editorials/295.md b/editorials/295.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/7329
+
+[296A - Yaroslav and Permutations](/contest/296/problem/A "Codeforces Round 179 (Div. 2)")
+Note that after applying the operations of the exchange, we can get any permutation of numbers. Not difficult to understand that the answer is "YES", if you can place a single number that it would not stand in the neighboring cells. Thus, if a some number is meeted C times, it must fulfill the condition C <= (n+1) / 2.
+[296B - Yaroslav and Two Strings](/contest/296/problem/B "Codeforces Round 179 (Div. 2)")
+Будем решать обратную задачу: посчитать количество способов сделать сравнимые пары.
+Для начала посчитаем количество способов сделать первую строку меньше равной второй.
+Это количество равно произведению количества способов сделать это для каждой позиции по отдельности,так как они все позиции независимы. Посчитаем такую же величину, но когда вторая строка меньше-равна первой. И аналогично посчитаем количество способов сделать две строки равными. Для каждого символа величины можно считать простым циклом.
+Теперь возьмем величину 10 в степени количества знаков вопроса во входном файле и отнимем полученный ответ на обратную задачу, это и будет ответом.
+[295A - Greg and Array](/contest/295/problem/A "Codeforces Round 179 (Div. 1)")
+Для того, что бы прибавить значение d на отрезке [x,y] достаточно завести массив b и поставить значения
+b[x] += d
+b[y+1] -= d
+Дальше за один проход по массиву легко восстанавливаются все числа.
+Применим данный метод дважды: сначала для запросов, а потом для операций(зная сколько раз мы ее выполним).
+[295B - Greg and Graph](/contest/295/problem/B "Codeforces Round 179 (Div. 1)")
+Для решения задачи нужно хорошо понимать принцип работы алгоритма Флойда.
+Общий вид алгоритма Флойда:
+for (k=1;k<=n;k++)
+ for (i=1;i<=n;i++)
+ for (j=1;j<=n;j++)
+ a[i][j] = min(a[i][j], a[i][k]+a[k][j]);
+То есть на каждом шаге мы пытаемся пропустить путь через вершину К.
+Будем не удалять вершины, а добавлять(идя с конца).
+На каждом шаге будем пробовать пропустить путь между всеми вершинами через новую.
+Таким образом мы получим решение, работающее за кубическое время.
+[295C - Greg and Friends](/contest/295/problem/C "Codeforces Round 179 (Div. 1)")
+Заметим, что на каждом шаге нас интересует только положение лодки(номер берега) и количество людей веса 50 и 100 на каждом береге. При чем количество людей на одном береге полностью определяется через другой.
+Для поиска минимального количества переправ будем использовать волновой алгоритм, основанный на этом состоянии.
+Для нахождения количества способов просто добавим сумму всех переходов в состояние при переходе будем переносить все способы из одного состояния в другое умножая на количество способов выбрать людей, которые нужны для перехода из одного состояний в другое.
+[295D - Greg and Caves](/contest/295/problem/D "Codeforces Round 179 (Div. 1)")
+Будем пользоваться динамическим программированием: dp[i][j] — сколько существует способов построить фигуру, что в строке i будет ровно j столбцов занятыми черными клетками и всем, что между ними. При этом фигура должная не убывать (иными словами мы берем только верхнюю часть фигуры).
+Как делать переход? Заметим, что dp[i][j] = 1+dp[i-1][2] * (j-2+1)+ ... +dp[i-1][l] * (j-l+1)+ ... +dp[i-1][j].
+Распишем это: dp[i][j] = 1+dp[i-1][2] * j+ ... +dp[i-1][l] * j+ ... +dp[i-1][j] * j — dp[i-1][2] * 1 — dp[i-1][3] * 2 — ... — dp[i-1][j] * (j-1).
+Понятно, что если завести частичные сумму, то данные величины считать становится очень просто.
+Как посчитать полный ответ: будем перебирать номер максимального подходящего t(обозначенного в условии).
+Теперь единственное отличие, это то что следующая строка должна содержать строго меньше столбцов. То есть имеем аналогичный переход, с -1 слагаемым.
+Так же заметим, что зафиксировав "основу" мы должны домножить количество способов на число способов разместить ее на плоскости, то есть основу шириной j мы можем поставить (m-j+1) способами.
+[295E - Yaroslav and Points](/contest/295/problem/E "Codeforces Round 179 (Div. 1)")
+Научимся решать задачу: найти сумму расстояний между точками.
+Если расписать, что происходит при добавлении одной точки, то получим формулу: x_i*(2*i-n) Где x_i — отсортированные координаты, а n общее количество точек.
+Научимся зная ответы для двух отрезков точек знать ответ для их объединения.
+Понятно, что для подсчета такой информации нужно всего лишь сложить два ответа,
+и добавить сумму координат первого множества умноженное на некоторое число и
+и добавить сумму координат второго множества умноженное на некоторое, возможно другое, число.
+Таким образом зная ответы для некоторых отрезков общий ответ.
+Будем использовать корневую декомпозицию или декартово дерево для хранения таких отрезков.
+Не сложно понять, что вставка и удаление делается достаточно быстро для этих структур.
+Например для корневой декомпозиции можно каждый раз просто вырезать и вставлять точку в нужные отрезки, а если множество стало содержать длинные отрезки или много отрезков, то просто перестроим его заново. Асимптотика решения не меняется.
diff --git a/editorials/296.md b/editorials/296.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/7329
+
+[296A - Yaroslav and Permutations](/contest/296/problem/A "Codeforces Round 179 (Div. 2)")
+Note that after applying the operations of the exchange, we can get any permutation of numbers. Not difficult to understand that the answer is "YES", if you can place a single number that it would not stand in the neighboring cells. Thus, if a some number is meeted C times, it must fulfill the condition C <= (n+1) / 2.
+[296B - Yaroslav and Two Strings](/contest/296/problem/B "Codeforces Round 179 (Div. 2)")
+Будем решать обратную задачу: посчитать количество способов сделать сравнимые пары.
+Для начала посчитаем количество способов сделать первую строку меньше равной второй.
+Это количество равно произведению количества способов сделать это для каждой позиции по отдельности,так как они все позиции независимы. Посчитаем такую же величину, но когда вторая строка меньше-равна первой. И аналогично посчитаем количество способов сделать две строки равными. Для каждого символа величины можно считать простым циклом.
+Теперь возьмем величину 10 в степени количества знаков вопроса во входном файле и отнимем полученный ответ на обратную задачу, это и будет ответом.
+[295A - Greg and Array](/contest/295/problem/A "Codeforces Round 179 (Div. 1)")
+Для того, что бы прибавить значение d на отрезке [x,y] достаточно завести массив b и поставить значения
+b[x] += d
+b[y+1] -= d
+Дальше за один проход по массиву легко восстанавливаются все числа.
+Применим данный метод дважды: сначала для запросов, а потом для операций(зная сколько раз мы ее выполним).
+[295B - Greg and Graph](/contest/295/problem/B "Codeforces Round 179 (Div. 1)")
+Для решения задачи нужно хорошо понимать принцип работы алгоритма Флойда.
+Общий вид алгоритма Флойда:
+for (k=1;k<=n;k++)
+ for (i=1;i<=n;i++)
+ for (j=1;j<=n;j++)
+ a[i][j] = min(a[i][j], a[i][k]+a[k][j]);
+То есть на каждом шаге мы пытаемся пропустить путь через вершину К.
+Будем не удалять вершины, а добавлять(идя с конца).
+На каждом шаге будем пробовать пропустить путь между всеми вершинами через новую.
+Таким образом мы получим решение, работающее за кубическое время.
+[295C - Greg and Friends](/contest/295/problem/C "Codeforces Round 179 (Div. 1)")
+Заметим, что на каждом шаге нас интересует только положение лодки(номер берега) и количество людей веса 50 и 100 на каждом береге. При чем количество людей на одном береге полностью определяется через другой.
+Для поиска минимального количества переправ будем использовать волновой алгоритм, основанный на этом состоянии.
+Для нахождения количества способов просто добавим сумму всех переходов в состояние при переходе будем переносить все способы из одного состояния в другое умножая на количество способов выбрать людей, которые нужны для перехода из одного состояний в другое.
+[295D - Greg and Caves](/contest/295/problem/D "Codeforces Round 179 (Div. 1)")
+Будем пользоваться динамическим программированием: dp[i][j] — сколько существует способов построить фигуру, что в строке i будет ровно j столбцов занятыми черными клетками и всем, что между ними. При этом фигура должная не убывать (иными словами мы берем только верхнюю часть фигуры).
+Как делать переход? Заметим, что dp[i][j] = 1+dp[i-1][2] * (j-2+1)+ ... +dp[i-1][l] * (j-l+1)+ ... +dp[i-1][j].
+Распишем это: dp[i][j] = 1+dp[i-1][2] * j+ ... +dp[i-1][l] * j+ ... +dp[i-1][j] * j — dp[i-1][2] * 1 — dp[i-1][3] * 2 — ... — dp[i-1][j] * (j-1).
+Понятно, что если завести частичные сумму, то данные величины считать становится очень просто.
+Как посчитать полный ответ: будем перебирать номер максимального подходящего t(обозначенного в условии).
+Теперь единственное отличие, это то что следующая строка должна содержать строго меньше столбцов. То есть имеем аналогичный переход, с -1 слагаемым.
+Так же заметим, что зафиксировав "основу" мы должны домножить количество способов на число способов разместить ее на плоскости, то есть основу шириной j мы можем поставить (m-j+1) способами.
+[295E - Yaroslav and Points](/contest/295/problem/E "Codeforces Round 179 (Div. 1)")
+Научимся решать задачу: найти сумму расстояний между точками.
+Если расписать, что происходит при добавлении одной точки, то получим формулу: x_i*(2*i-n) Где x_i — отсортированные координаты, а n общее количество точек.
+Научимся зная ответы для двух отрезков точек знать ответ для их объединения.
+Понятно, что для подсчета такой информации нужно всего лишь сложить два ответа,
+и добавить сумму координат первого множества умноженное на некоторое число и
+и добавить сумму координат второго множества умноженное на некоторое, возможно другое, число.
+Таким образом зная ответы для некоторых отрезков общий ответ.
+Будем использовать корневую декомпозицию или декартово дерево для хранения таких отрезков.
+Не сложно понять, что вставка и удаление делается достаточно быстро для этих структур.
+Например для корневой декомпозиции можно каждый раз просто вырезать и вставлять точку в нужные отрезки, а если множество стало содержать длинные отрезки или много отрезков, то просто перестроим его заново. Асимптотика решения не меняется.
diff --git a/editorials/297.md b/editorials/297.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/7437
+
+[298A - Snow Footprints](/contest/298/problem/A "Codeforces Round 180 (Div. 2)")
+
+The starting position can be anywhere with a footprint. The footprints can be categorized into 3 types.
+
+1. only *L* s
+2. only *R* s
+3. *R* s followed by *L* s
+
+In case 1, we end in the left of all footprints. In case 2, we end in the right of all footprints. In case 3, we either end in the rightmost *R* or the leftmost *L*
+
+[298B - Sail](/contest/298/problem/B "Codeforces Round 180 (Div. 2)")
+
+We can simply move by greedy method — only moves when it takes the boat closer to the destination.
+
+[297A - Parity Game](/contest/297/problem/A "Codeforces Round 180 (Div. 1)")
+
+**Obv 1**: If *a* has odd parity, we can apply operation 1 to increase its number of 1s by 1.
+
+**Obv 2**: If *a* has even parity, its number of 1s cannot increase anymore.
+
+**Claim**: If the number of 1s in *a* is not fewer than those in *b*, we can always turn *a* to *b*
+
+The idea is to make a copy of *b* at the right of *a*. Lets assume *a* starts with even parity. If we need a 0, simply apply operation 1. If we need a 1, keep remove from the head until we removed an 1. Notice that we never remove digits from 'new part' of *a*. Now the parity of *a* will be odd and we can apply operation 1. After that, the parity of *a* becomes even again, the number of 1 in the 'old part' of *a* decrease by 1 and we handle a 1 in *b*. Finally, remove the remaining old part of *a* and we get *b*.
+
+Combine all those facts, we can conclude that we can turn *a* into *b* if and only if
+
+*countOnes*(*a*) + *parity*(*countOnes*(*a*)) ≥ *countOnes*(*b*)
+
+[297B - Fish Weight](/contest/297/problem/B "Codeforces Round 180 (Div. 1)")
+
+First we sort *a* and *b* in non-increasing order. We claim that the answer is YES if and only if exists *a* is lexicographically larger than *b*.
+
+ If *a* is not lexicographcally larger than *b*, that means for every *i*, *a**i* ≤ *b**i*. That implies for every fish Alice has, there is a corresponding fish Bob has and is as heavy as Alice's.
+
+ Let *i* be the smallest index such that *a**i* > *b**i*. We can amplify the gap between *w**a**i* and *w**b**i* as large as we want to make Alice wins.
+
+[297C - Splitting the Uniqueness](/contest/297/problem/C "Codeforces Round 180 (Div. 1)")
+
+An equivalent definition for *almost unique*, is an array with at least ⌊ 2*n* / 3⌋ different elements. The idea is to split *s* into three parts: In the first part, we give uniqueness to *a*. In the second part, we give uniqueness to *b*. In the third part, we give uniqueness to both.
+
+Lets assume *s* is sorted. Since *s* is an unique array, we know *s**i* ≥ *i* for all *i* (0-based). The image below will give some intuition on how we are going to split it. *a* is red, *b* is blue, the length of the bar represent the magnitude of the number. In the first and second part, we do not care about the array that we are not giving uniqueness to.
+
+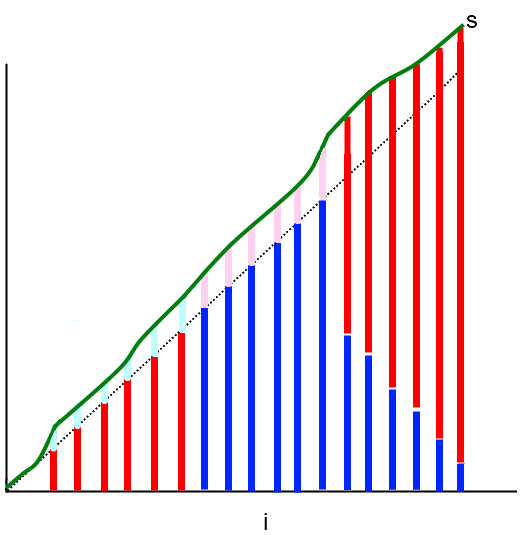
+
+For exampmle, if *n* = 30:
+
+*i* = 0... 9: assign *a**i* = *i* (do not care values of *b*)
+
+*i* = 10... 19: assign *b**i* = *i* (do not care values of *a*)
+
+*i* = 20... 29: assign *b**i* = 29 - *i* and set *a**i* = *s**i* - *b**i*. From *i* = 20, *a* will have strictly increasing values starting from at least 11.
+
+[297D - Color the Carpet](/contest/297/problem/D "Codeforces Round 180 (Div. 1)")
+
+For *k* = 1 there is only one coloring so we just need to check the number of = constraints. When *k* ≥ 2, it turns out that using only 2 colors is always sufficient to satisfy at least 3 / 4 of the constraints.
+
+Lets assume *w* ≥ *h* (rotate if not). We will call the constraints that involves cells in different row "vertical constraints", and similar for "horizontal constraints".
+
+First we color the first row such that all horizontal constraints in row 1 are satisfied. We will color the remaining rows one by one.
+
+To color row *i*, first we color it such that all horizontal constraints in row *i* are satisfied. Then consider the vertical constraints between row *i* and row *i* - 1. Count the number of satisfied and unsatisfied vertical constraints. If there are more unsatisfied constraints than satisfied constraints, flip the coloring of row *i*. Flipping a row means turning 2211212 → 1122121, for example.
+
+If we flip the coloring of row *i*, all horizontal constraints in row *i* are still satisfied, but for the vertical constraints between row *i* and row *i* - 1, satisfied will turn to unsatisfied, unsatisfied will turn to satisfied. Therefore, we can always satisfy at least half the vertical constraints between row *i* and row *i* - 1.
+
+The number of unsatisfied constraints is at most (*h* - 1) × ⌊ *w* / 2⌋, which is at most 1 / 4 of the total number of constraints (recall *w* ≥ *h*).
+
+[297E - Mystic Carvings](/contest/297/problem/E "Codeforces Round 180 (Div. 1)")
+
+Problem and editorial written by [AEtheReal](/profile/AEtheReal "Expert AEtheReal"). [Link to editorial](//www.codeforces.com/blog/AEtheReal).
diff --git a/editorials/298.md b/editorials/298.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/7437
+
+[298A - Snow Footprints](/contest/298/problem/A "Codeforces Round 180 (Div. 2)")
+
+The starting position can be anywhere with a footprint. The footprints can be categorized into 3 types.
+
+1. only *L* s
+2. only *R* s
+3. *R* s followed by *L* s
+
+In case 1, we end in the left of all footprints. In case 2, we end in the right of all footprints. In case 3, we either end in the rightmost *R* or the leftmost *L*
+
+[298B - Sail](/contest/298/problem/B "Codeforces Round 180 (Div. 2)")
+
+We can simply move by greedy method — only moves when it takes the boat closer to the destination.
+
+[297A - Parity Game](/contest/297/problem/A "Codeforces Round 180 (Div. 1)")
+
+**Obv 1**: If *a* has odd parity, we can apply operation 1 to increase its number of 1s by 1.
+
+**Obv 2**: If *a* has even parity, its number of 1s cannot increase anymore.
+
+**Claim**: If the number of 1s in *a* is not fewer than those in *b*, we can always turn *a* to *b*
+
+The idea is to make a copy of *b* at the right of *a*. Lets assume *a* starts with even parity. If we need a 0, simply apply operation 1. If we need a 1, keep remove from the head until we removed an 1. Notice that we never remove digits from 'new part' of *a*. Now the parity of *a* will be odd and we can apply operation 1. After that, the parity of *a* becomes even again, the number of 1 in the 'old part' of *a* decrease by 1 and we handle a 1 in *b*. Finally, remove the remaining old part of *a* and we get *b*.
+
+Combine all those facts, we can conclude that we can turn *a* into *b* if and only if
+
+*countOnes*(*a*) + *parity*(*countOnes*(*a*)) ≥ *countOnes*(*b*)
+
+[297B - Fish Weight](/contest/297/problem/B "Codeforces Round 180 (Div. 1)")
+
+First we sort *a* and *b* in non-increasing order. We claim that the answer is YES if and only if exists *a* is lexicographically larger than *b*.
+
+ If *a* is not lexicographcally larger than *b*, that means for every *i*, *a**i* ≤ *b**i*. That implies for every fish Alice has, there is a corresponding fish Bob has and is as heavy as Alice's.
+
+ Let *i* be the smallest index such that *a**i* > *b**i*. We can amplify the gap between *w**a**i* and *w**b**i* as large as we want to make Alice wins.
+
+[297C - Splitting the Uniqueness](/contest/297/problem/C "Codeforces Round 180 (Div. 1)")
+
+An equivalent definition for *almost unique*, is an array with at least ⌊ 2*n* / 3⌋ different elements. The idea is to split *s* into three parts: In the first part, we give uniqueness to *a*. In the second part, we give uniqueness to *b*. In the third part, we give uniqueness to both.
+
+Lets assume *s* is sorted. Since *s* is an unique array, we know *s**i* ≥ *i* for all *i* (0-based). The image below will give some intuition on how we are going to split it. *a* is red, *b* is blue, the length of the bar represent the magnitude of the number. In the first and second part, we do not care about the array that we are not giving uniqueness to.
+
+
+
+For exampmle, if *n* = 30:
+
+*i* = 0... 9: assign *a**i* = *i* (do not care values of *b*)
+
+*i* = 10... 19: assign *b**i* = *i* (do not care values of *a*)
+
+*i* = 20... 29: assign *b**i* = 29 - *i* and set *a**i* = *s**i* - *b**i*. From *i* = 20, *a* will have strictly increasing values starting from at least 11.
+
+[297D - Color the Carpet](/contest/297/problem/D "Codeforces Round 180 (Div. 1)")
+
+For *k* = 1 there is only one coloring so we just need to check the number of = constraints. When *k* ≥ 2, it turns out that using only 2 colors is always sufficient to satisfy at least 3 / 4 of the constraints.
+
+Lets assume *w* ≥ *h* (rotate if not). We will call the constraints that involves cells in different row "vertical constraints", and similar for "horizontal constraints".
+
+First we color the first row such that all horizontal constraints in row 1 are satisfied. We will color the remaining rows one by one.
+
+To color row *i*, first we color it such that all horizontal constraints in row *i* are satisfied. Then consider the vertical constraints between row *i* and row *i* - 1. Count the number of satisfied and unsatisfied vertical constraints. If there are more unsatisfied constraints than satisfied constraints, flip the coloring of row *i*. Flipping a row means turning 2211212 → 1122121, for example.
+
+If we flip the coloring of row *i*, all horizontal constraints in row *i* are still satisfied, but for the vertical constraints between row *i* and row *i* - 1, satisfied will turn to unsatisfied, unsatisfied will turn to satisfied. Therefore, we can always satisfy at least half the vertical constraints between row *i* and row *i* - 1.
+
+The number of unsatisfied constraints is at most (*h* - 1) × ⌊ *w* / 2⌋, which is at most 1 / 4 of the total number of constraints (recall *w* ≥ *h*).
+
+[297E - Mystic Carvings](/contest/297/problem/E "Codeforces Round 180 (Div. 1)")
+
+Problem and editorial written by [AEtheReal](/profile/AEtheReal "Expert AEtheReal"). [Link to editorial](//www.codeforces.com/blog/AEtheReal).
diff --git a/editorials/299.md b/editorials/299.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/7516
+
+Here you can find the solutions for the problems from the past round. You can ask questions in the comments below.
+
+**[A Div 2](//codeforces.com/contest/299/problem/A)**
+
+If *a**i* divide *a**j* than *a**i* ≤ *a**j*. So the number which will divide every other number should be less than or equal to every other number, so the only possible candidate — it's the minimum in the array. So just check whether all elements are divisible by the minimal one.
+
+**[B Div 2](//codeforces.com/contest/299/problem/B)**
+
+Easy to see, that Ksusha is unable to complete her journey if there is a sequence of consecutive # with length more than k.
+
+**[C Div 2](//codeforces.com/contest/299/problem/C) / [A Div 1](//codeforces.com/contest/293/problem/A)**
+
+The first observation — we don't care about the actual strings, all information we need — number of pairs {0,0}, {0,1}, {1,0}, {1,1}. Count that and then just follow the greedy algorithm, for the first player: try to get a index with {1,1} if there are some, than {1,0}, than {0,1} and than {0,0}.
+
+For the second player similar strategy: first {1,1}, than {0,1}, than {1,0}, than {0,0}.
+
+After that just compare who has more 1.
+
+**[D Div 2](//codeforces.com/contest/299/problem/D) / [B Div 1](//codeforces.com/contest/293/problem/B)**
+
+Every path from the topleft cell to the bottomright cell contain exactly *n* + *m* - 1 cells. And all of the should be of different color. So *n* + *m* - 1 ≤ *k*. Due to the small constraints for k we may assume that bruteforce might work. The only optimization to get the correct solution is some canonization of the colors. So let's go over all of the cells in some order and color them but with following condition. If i > j, than color i appeared later than color j. If we bruteforce in such way we will have about 1 million different patterns for max case. Than just match them with already painted cells and calculate for each pattern how many different permutations of color we can apply to it.
+
+**[E Div 2](//codeforces.com/contest/299/problem/E) / [C Div 1](//codeforces.com/contest/293/problem/C)**
+
+After reading the problem statement one can understand that all we need is to calculate the number of positive integer solutions of equation: (*a* + *b* + *c*)3 - *a*3 - *b*3 - *c*3 = *n*.
+
+The key observation is: 3(*a* + *b*)(*a* + *c*)(*b* + *c*) = (*a* + *b* + *c*)3 - *a*3 - *b*3 - *c*3, after that simply calculate all divisors of  and then first go over all *x* = *a* + *b*, such that  then go over all *y* = (*a* + *c*) ≥ *x*, such that  and then determine *z* = (*b* + *c*), such that . After that we need to solve the system *a* + *b* = *x*, *a* + *c* = *y*, *b* + *c* = *z* and find out how many solutions it adds.
+
+**[D Div 1](//codeforces.com/contest/293/problem/D)**
+
+We can see that we asked to calculate 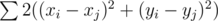 for all integer points inside the polygon or on its border. We can see that we can process Xs and Ys independently.
+
+For each *x* determine *y**left*, *y**right*, such that all points (*x*, *y*) where *y**left* ≤ *y* ≤ *y**right* are inside the polygon and the range [*y**left*, *y**right*] is as maximal as possible. Now let's assume that we have *a*1, *a*2, ..., *a**k* different points with fixed x coordinate (*a*1 stands for *x* = - 106, *a*2 for *x* = - 106 + 1 and so on).
+
+Now the required answer is *a*2*a*1 + *a*3(*a*2 + 22*a*1) + *a*4(*a*3 + 22*a*2 + 32*a*1) + ...
+
+We can see that:
+
+(*a*2 + 22*a*1) - *a*1 = *a*2 + 3*a*1,
+
+(*a*3 + 22*a*2 + 32*a*1) - (*a*2 + 22*a*1) = *a*3 + 3*a*2 + 5*a*1,
+
+and so on.
+
+So we can precalculate partial sums like *a*2 + 3*a*1, *a*3 + 3*a*2 + 5*a*1, *a*4 + 3*a*3 + 5*a*2 + 7*a*1 (the difference between two consecutive sums is 2(*a**i* + ... + *a*1), so we can do that in *O*(*k*) time).
+
+After this precomputation we just need to sum the results.
+
+**[E Div 1](//codeforces.com/contest/293/problem/E)**
+
+Let's assume that we have a data structure which can perform such operations as: — add point (x,y) to the structure;
+
+* shift all points in the structure by vector (dx,dy);
+* answer how many point (x,y) are in the structure where *x* ≤ *x**bound*, *y* ≤ *y**bound*;
+* get all elements which are now in the structure;
+
+For every vertex of the tree we will store the pointer to such structure.
+
+How we update the structures. We will proceed all the vertices in dfs order, if we are in a leaf node, than we create structure which contains only one element (0,0).
+
+Otherwise we will sort the children structures by it's size in decreasing order and assign the pointer of the biggest structure to the pointer of the current vertex (Don't forget to shift the structure by (1, weight of edge)).
+
+After that we will go over all other children one by one and do the following thing:
+
+* Shift the structure by (1, weight of edge);
+* Get all elements from the structure;
+* For every element (x,y) answer the query *x**bound* = *L* - *x*, *y**bound* = *W* - *y* (we use parent's structure);
+* Add elements one by one into the structure;
+
+After that answer the query *x**bound* = *L*, *y**bound* = *W* and add element (0,0).
+
+The sum of the results of all the queries is our answer. It's easy to see that there will be no more than  queries and add operations.
+
+The remaining part is designing the structure.
+
+It can be done in many ways. One of the ways:
+
+* We have small structures with sizes equals to powers of two;
+* Each structure — it's two-dimensional segments tree;
+* We can add one element in a following way: if there is no substructure with size 1, than add it; else get structures with sizes 1, 2, 4, ..., 2*k* and all its' elements and rebuild the structure with size 2*k* + 1;
+* Shifting — just remember shifting vector for every substructure;
+* Answering the query — go over all substructures and add the results.
+
+Editorial was prepared by [sdya](/profile/sdya "International Grandmaster sdya") and [Seyaua](/profile/Seyaua "International Master Seyaua")
diff --git a/editorials/30.md b/editorials/30.md
@@ -0,0 +1,17 @@
+Source: https://codeforces.com/blog/entry/696
+
+# Tutorial for problem "A. Accounting"
+
+### First solution: naive brute
+
+Let's brute all possible values of *X*, and check each of them. It's easy to understand, that *X* will be constrained in the same limits as values *A* and *B*, that is, from -1000 to 1000 inclusive (obviously, there exists a test for each such *X*, so we can't decrease these limits).
+
+When we have some fixed value of *X*, we check it simply by multiplying *A* by *X* *n* times. But, you should be careful with possible integer (and even 64-bit integer :) ) overflow. For example, you should stop multiplying by *X* if the currect result exceeds 1000 by absolute value already.
+
+### Second solution: formula
+
+It's easy to note, that if solution exists, then it is *n*-th root from |*B*| / |*A*| fraction, with changed sign if *A* and *B* have different signs and if *n* is odd (if *n* is even, then no solution exists). That's why we could just use pow() function (or some analog in your language) to calculate 1 / *n*-th power of the fraction, and after that we just have to check - is the result integer number or not. Of course, we have to check it with taking into account precision errors: that is, number is integer if it is within 10- 9 (or some another number) from nearest integer.
+
+Moreover, in this solution you should be careful with zeroes. The worst case is when *A* = 0, and this case should be checked manually (you should note the difference between *B* = 0 and *B* ≠ 0 cases).
+
+It should be told that many of the solutions failed on tests with *A* = 0, or *B* = 0, and if these tests were not included in the pretestset, I think, about half of participants would fail to solve this problem :)
diff --git a/editorials/300.md b/editorials/300.md
@@ -0,0 +1,91 @@
+Source: https://codeforces.com/blog/entry/7497
+
+### [300A - Array](/contest/300/problem/A "Codeforces Round 181 (Div. 2)")
+
+In this problem you just need to implement following algorithm. Split input data into 3 vectors: first will contain negative numbers, second positive numbers, third zeroes. If size of first vector is even move one number from it to the third vector. If second vector is empty, then move two numbers from first vector to the second vector. This solution works in *O*(*n*).
+
+[Аuthor's solution](http://pastebin.com/8aVCeRYx)
+
+### [300B - Coach](/contest/300/problem/B "Codeforces Round 181 (Div. 2)")
+
+Input data represents a graph. If there is a connected component with at least 4 vertexes, then answer is - 1. Every connected component with 3 vertexes is a complete team. Other teams are made from 1 or 2-vertex components. If amount of 2-vertex components is greater than 1-vertex answer is - 1. Otherwise match 2-vertex components with 1-vertex. If there are some 1-vertex components left then split them into groups of three. This algorithm works in *O*(*n* + *m*). Also you could implement *O*(*n*4) solution.
+
+[Аuthor's solution](http://pastebin.com/2q8CThPh)
+
+### [300C - Beautiful Numbers](/contest/300/problem/C "Codeforces Round 181 (Div. 2)")
+
+Let's *MOD* = 1000000007. Let's precalc factorial values modulo *MOD*. *fact*[*i*] = *i*!%*MOD*, 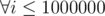. Let *i* be an amount of digits equal to *a* in current excellent number. In this case we can find sum of digits in this number: *sum* = *ai* + *b*(*n* - *i*). If *sum* is good, then add *C*[*n*][*i*] to answer. In this problem it's impossible to calculate binomial coefficients using Pascal's triangle, because of large *n*. However it can be done this way *C*[*n*][*i*] = *fact*[*n*]*inv*(*fact*[*n* - *i*]*fact*[*i*]). *inv*(*a*) is multiplicative inverse element(modulo *MOD*). *MOD* is a prime number, so *inv*(*a*) = *a**MOD* - 2. Calculating this values for each *i* from 0 to *n* will give correct answer in *O*(*nlog*(*MOD*)).
+
+[Аuthor's solution](http://pastebin.com/XwP7MmEa)
+
+### [300D - Painting Square](/contest/300/problem/D "Codeforces Round 181 (Div. 2)")
+
+This picture is helpful for understanding.
+
+
+
+Let's consider problem *D* in graph terms:
+
+We have matrix *n* × *n*, which represents a graph:
+
+1. It is tree.
+2. Every vertex, except leaves, has 4 children.
+3. There are 4*k* distinct vertexes, with distance *k* from root.
+
+We need to color *k* vertexes of this graph. By that we mean also to color all vertexes on path from *i* to 1(root).
+
+Knowing *height* of tree we can build it in unique way. Let's find height of tree in this way:
+
+```
+int height = 0;
+while (n > 1 && n % 2 == 1) {
+ n /= 2; height++;
+}
+```
+
+Let's consider following DP: *z*[*i*][*j*] — number of ways to color graph height *i* in *j* steps.
+
+Naive solution in *O*(*k*4*log*(*n*)):
+
+```
+z[0][0] = 1; z[0][i] = 0, i > 0; z[i][0] = 1, i > 0
+z[i][j] = 0;
+for(int k1 = 0; k1 <= j - 1; k1++)
+ for(int k2 = 0; k2 <= j - 1 - k1; k2++)
+ for(int k3 = 0; k3 <= j - 1 - k1 - k2; k3++)
+ {
+ int k4 = j - 1 - k1 - k2 - k3;
+ z[i][j] += z[i-1][k1] * z[i-1][k2] * z[i-1][k3] * z[i-1][k4];
+ z[i][j] %= mod;
+ }
+```
+
+But it is not what we whant in time terms. Let's consider current DP as polynomial coefficients: *z*[*i*][*j*] — coefficient of power *j* of polynomial *i*. In that case *z*[*i* + 1][*j* + 1] — coefficient of power *j* of polynomial *i* to the 4-th power. This approach allows to solve problem in *O*(*k*2*log*(*n*)). However this solution is quite slow, because of modulo operations. As you see, this modulo is not so big ( ≤ 107), that allows us to reduce number of modulo operations, thus giving huge perfomance boost. Also it is possible to use FFT to solve in *O*(*klog*(*k*)*log*(*n*)).
+
+[Аuthor's solution. Uses FFT](http://pastebin.com/iXMrR6Cd)
+
+[Аuthor's solution. Without FFT](http://pastebin.com/RfMiXe6K)
+
+### [300E - Empire Strikes Back](/contest/300/problem/E "Codeforces Round 181 (Div. 2)")
+
+Let's 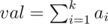. *val* is upper bound for answer. *val*! is divisible by 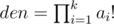, you can easily prove it using facts about prime powers in factorial and following inequality 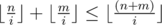. By the way,  is called multinomial coefficient. So answer can't exceed 1013.
+
+If *n*! divisible by *den*, then (*n* + 1)! is also divisible by *den*. That means that function of divisibility is monotonic and we can use binary search.
+
+For every *i*, *i* = 2..., 107, let's precalc max prime in *i* using linear sieve of Eratosthenes. For *i* it will be *lp*[*i*]. After that let's create a vector, with all primes less then 107.
+
+Now let's calculate following values *cnt*[*i*] — amount of numbers *a*, *i* < = *a*.
+
+Now me can factorize denominator like this:
+
+```
+for(int i = max; i>=2; i--) {
+ if (lp[i] != i)
+ cnt[lp[i]] += cnt[i];
+ cnt[i / lp[i]] += cnt[i];
+}
+```
+
+Finally we use binary search from *lf* = 1 to 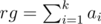.
+
+[Аuthor's solution](http://pastebin.com/71vYY41X)
diff --git a/editorials/301.md b/editorials/301.md
@@ -0,0 +1,24 @@
+Source: https://codeforces.com/blog/entry/7560
+
+[302A - Eugeny and Array](/contest/302/problem/A "Codeforces Round 182 (Div. 2)")
+If the length of the given segment is even and count of 1 in input is not lower then half of the length of the segment and count of -1 in the input is not lower then half of the length of the segment so we have answer 1, otherwise 0.
+
+[302B - Eugeny and Play List](/contest/302/problem/B "Codeforces Round 182 (Div. 2)")
+For each song we will count moment of time, when it will be over (some sums on the prefixes, for example). Further, we will use binary search of two itaratos method to solve the problem.
+
+[301A - Yaroslav and Sequence](/contest/301/problem/A "Codeforces Round 182 (Div. 1)")
+Using dfs we will find number of numbers that we can set as positive. Note that we can either set all of the numbers as positive or leave one number(any) as negative. If we can obtain all numbers as positive, we just return sum of modules of the numbers, but if we cannot we will count the same sum and will subtract minimal modular value multiple 2 from sum.
+
+[301B - Yaroslav and Time](/contest/301/problem/B "Codeforces Round 182 (Div. 1)")
+We will use binary search to find the answer. Further we will use Ford-Bellman algorithm. On each step we will have an array of maximum values on timer, when we stand in some point. On in transfer we will check: will our player stay alive after travelling beetwen points. If we can make transfer, we will update value of the final destination point. Becouse of a_i<=d and integer coordinates we haven't optimal cycles, and solution exists.
+
+[301C - Yaroslav and Algorithm](/contest/301/problem/C "Codeforces Round 182 (Div. 1)")
+We will use ? as iterator. In the begin we will set ? before the number. Then we will move it to the end of the string. Then we will change ? to ?? and we will move it to the begin, while we have 9 before ??. If we have another digit, we just increase it, and finish the algorithm. If we have ?? at the begin, we change it to 1, and end the algorithm.
+
+Look for accepted solutions for better understanding.
+
+[301D - Yaroslav and Divisors](/contest/301/problem/D "Codeforces Round 182 (Div. 1)")
+Lets add all pair: (x,y) ((d[x]%d[y]==0) || (d[y]%d[x]==0)) to some lest. We can count such pairs using Eretosphen algorithm. Here will be O(n*log(n)) sych pairs using fact, that we have permutation. We will sort all this paairs using counting-sort. Also we will sort given in input intervals. For each given interval we should count number of pairs that countained in given them . Such problem we can solve using Fenvik tree. On each step we will add segments(that are sorted by right side). On each step we will update Fenfick-tree that count number of added pairs on some suffix. Using such tree if it easy to count the answer. So we have O(n*log^2(n)) solution.
+
+[301E - Yaroslav and Arrangements](/contest/301/problem/E "Codeforces Round 182 (Div. 1)")
+We will build the needed arrays sequentially adding numbers. Let's look at what states we need. First, it is obvious that you need to keep the number of ways to build an array of already added numbers, secondly you need to know the total amount of added numbers. Now let's look at what happens when we add a new number (that is greater than all of the previous in a certain amount). It is clear that the added numbers should stand between the numbers 1 to less. In this case, if we put two new numbers in a row, between them should stand more (since we already have placed less). It is obvious that you need to cover all the previous numbers (among which must stand newly added). Thus, we have another state: the number of integers between which we should put the new ones. Thus we have the dynamics of the four parameters: dp [all] [ways] [lastnumber] [counttoadd]. Transfer. It is clear that you need to add at least counttoadd numbers, but how will this affect the number of ways to arrange the numbers? It's simple. Suppose we added number x, then the number of ways to be multiplied by the value of Q (x-counttoadd, counttoadd), where Q (x, y) — the number of ways to assign the same x balls in y different boxes. Q (x, y) = C (x + y-1, y-1) where C (x, y) — binomial coefficient.
diff --git a/editorials/302.md b/editorials/302.md
@@ -0,0 +1,24 @@
+Source: https://codeforces.com/blog/entry/7560
+
+[302A - Eugeny and Array](/contest/302/problem/A "Codeforces Round 182 (Div. 2)")
+If the length of the given segment is even and count of 1 in input is not lower then half of the length of the segment and count of -1 in the input is not lower then half of the length of the segment so we have answer 1, otherwise 0.
+
+[302B - Eugeny and Play List](/contest/302/problem/B "Codeforces Round 182 (Div. 2)")
+For each song we will count moment of time, when it will be over (some sums on the prefixes, for example). Further, we will use binary search of two itaratos method to solve the problem.
+
+[301A - Yaroslav and Sequence](/contest/301/problem/A "Codeforces Round 182 (Div. 1)")
+Using dfs we will find number of numbers that we can set as positive. Note that we can either set all of the numbers as positive or leave one number(any) as negative. If we can obtain all numbers as positive, we just return sum of modules of the numbers, but if we cannot we will count the same sum and will subtract minimal modular value multiple 2 from sum.
+
+[301B - Yaroslav and Time](/contest/301/problem/B "Codeforces Round 182 (Div. 1)")
+We will use binary search to find the answer. Further we will use Ford-Bellman algorithm. On each step we will have an array of maximum values on timer, when we stand in some point. On in transfer we will check: will our player stay alive after travelling beetwen points. If we can make transfer, we will update value of the final destination point. Becouse of a_i<=d and integer coordinates we haven't optimal cycles, and solution exists.
+
+[301C - Yaroslav and Algorithm](/contest/301/problem/C "Codeforces Round 182 (Div. 1)")
+We will use ? as iterator. In the begin we will set ? before the number. Then we will move it to the end of the string. Then we will change ? to ?? and we will move it to the begin, while we have 9 before ??. If we have another digit, we just increase it, and finish the algorithm. If we have ?? at the begin, we change it to 1, and end the algorithm.
+
+Look for accepted solutions for better understanding.
+
+[301D - Yaroslav and Divisors](/contest/301/problem/D "Codeforces Round 182 (Div. 1)")
+Lets add all pair: (x,y) ((d[x]%d[y]==0) || (d[y]%d[x]==0)) to some lest. We can count such pairs using Eretosphen algorithm. Here will be O(n*log(n)) sych pairs using fact, that we have permutation. We will sort all this paairs using counting-sort. Also we will sort given in input intervals. For each given interval we should count number of pairs that countained in given them . Such problem we can solve using Fenvik tree. On each step we will add segments(that are sorted by right side). On each step we will update Fenfick-tree that count number of added pairs on some suffix. Using such tree if it easy to count the answer. So we have O(n*log^2(n)) solution.
+
+[301E - Yaroslav and Arrangements](/contest/301/problem/E "Codeforces Round 182 (Div. 1)")
+We will build the needed arrays sequentially adding numbers. Let's look at what states we need. First, it is obvious that you need to keep the number of ways to build an array of already added numbers, secondly you need to know the total amount of added numbers. Now let's look at what happens when we add a new number (that is greater than all of the previous in a certain amount). It is clear that the added numbers should stand between the numbers 1 to less. In this case, if we put two new numbers in a row, between them should stand more (since we already have placed less). It is obvious that you need to cover all the previous numbers (among which must stand newly added). Thus, we have another state: the number of integers between which we should put the new ones. Thus we have the dynamics of the four parameters: dp [all] [ways] [lastnumber] [counttoadd]. Transfer. It is clear that you need to add at least counttoadd numbers, but how will this affect the number of ways to arrange the numbers? It's simple. Suppose we added number x, then the number of ways to be multiplied by the value of Q (x-counttoadd, counttoadd), where Q (x, y) — the number of ways to assign the same x balls in y different boxes. Q (x, y) = C (x + y-1, y-1) where C (x, y) — binomial coefficient.
diff --git a/editorials/303.md b/editorials/303.md
@@ -0,0 +1,92 @@
+Source: https://codeforces.com/blog/entry/7641
+
+# Overview ...
+
+。。。(; Д ;) 。
+
+# Tutorial ...
+
+* [Problem 2A. Pythagorean Theorem II](//codeforces.com/problemset/problem/304/A)
+
+Math, implementation
+
+This problem can be solve by brute-force, but it come up with a nicer solution if we involve some math.
+
+Check the following article if you are interested.
+
+[http://en.wikipedia.org/wiki/Pythagorean_triple#Generating_a_triple](https://en.wikipedia.org/wiki/Pythagorean_triple#Generating_a_triple)
+
+* [Problem 2B. Calender](//codeforces.com/problemset/problem/304/B)
+
+Math, implementation
+
+This problem can be solve by brute-force, but it come up with a nicer solution if we involve some math.
+
+Check [kabar](/profile/kabar "Эксперт kabar")'s code if you are interested.
+
+[http://codeforces.com/contest/304/submission/3715756](//codeforces.com/contest/304/submission/3715756)
+
+* [Problem A. Lucky Permutation Triple](//codeforces.com/problemset/problem/303/A)
+
+Math, Constructive algorithms, Congruent
+
+* when n is odd, A[i] = B[i] = i
+* when n is even, there is no solution. So why? Because:
+
+S = \Sum_{i=0}^{n-1} i = n/2 (mod n) but 2*S = 0 (mod n)
+
+See also at:
+
+[http://codeforces.com/blog/entry/7499#comment-133446](//codeforces.com/blog/entry/7499#comment-133446)
+
+* [Problem B. Rectangle Puzzle II](//codeforces.com/problemset/problem/303/B)
+
+Math, Geometry
+
+Give you *n*, *m*, *x*, *y*, *a*, *b*.
+
+Find a maximum sub-rectangle within (0, 0) — (*n*, *m*), so that it contains the given point(*x*, *y*) and its length-width radio is exactly (*a*, *b*). If there are multiple solutions, find the rectangle which is closest to (*x*, *y*). If there are still multiple solutions, find the lexicographically minimum one.
+
+Split the problem into *x*-axis and *y*-axis. Then you can solve the sub tasks in *O*(1).
+
+```
+d = gcd(a,b)
+a /= d
+b /= d
+t = min(n/a, m/b)
+a *= t
+b *= t
+```
+
+Be careful, when the length is outside the original rectangle.
+
+* [Problem C. Minimum Modular](//codeforces.com/problemset/problem/303/C)
+
+Math, Graph theory, Brute-force, Congruent
+
+It is hard to solve this problem at once, so at first, let us consider on k = 0, this easier case can be solved by enumerate on the *ans*. Let us define a bool array diff[], which diff[x] is weather there are two number, *a**i*, *a**j*, such that *abs*(*a**i* - *a**j*) = *x*.
+
+So *ans* is legal <=> diff[ans], diff[2*ans] … are false.
+
+The time-complexity *O*(*n*2 + *mlogm*). Here *m* is the maximum *a**i*.
+
+Consider on *k* > 0, we need to know how many pairs which has difference x. Store them in
+`vector<pair <int, int> > diff[x];`
+
+Then use a [dsu](https://en.wikipedia.org/wiki/Disjoint_sets) to maintain the how many a_i are congruent when enumerate on the *ans*.
+
+* [Problem D. Rotatable Number](//codeforces.com/problemset/problem/303/D)
+
+Math, Number theory
+
+(Coming Soon...)
+
+[http://codeforces.com/blog/entry/7499#comment-133342](//codeforces.com/blog/entry/7499#comment-133342)
+
+* [Problem E. Random Ranking](//codeforces.com/problemset/problem/303/E)
+
+Math, Probability
+
+(Coming After D...)
+
+[http://codeforces.com/blog/entry/7499#comment-133488](//codeforces.com/blog/entry/7499#comment-133488)
diff --git a/editorials/304.md b/editorials/304.md
@@ -0,0 +1,92 @@
+Source: https://codeforces.com/blog/entry/7641
+
+# Overview ...
+
+。。。(; Д ;) 。
+
+# Tutorial ...
+
+* [Problem 2A. Pythagorean Theorem II](//codeforces.com/problemset/problem/304/A)
+
+Math, implementation
+
+This problem can be solve by brute-force, but it come up with a nicer solution if we involve some math.
+
+Check the following article if you are interested.
+
+[http://en.wikipedia.org/wiki/Pythagorean_triple#Generating_a_triple](https://en.wikipedia.org/wiki/Pythagorean_triple#Generating_a_triple)
+
+* [Problem 2B. Calender](//codeforces.com/problemset/problem/304/B)
+
+Math, implementation
+
+This problem can be solve by brute-force, but it come up with a nicer solution if we involve some math.
+
+Check [kabar](/profile/kabar "Эксперт kabar")'s code if you are interested.
+
+[http://codeforces.com/contest/304/submission/3715756](//codeforces.com/contest/304/submission/3715756)
+
+* [Problem A. Lucky Permutation Triple](//codeforces.com/problemset/problem/303/A)
+
+Math, Constructive algorithms, Congruent
+
+* when n is odd, A[i] = B[i] = i
+* when n is even, there is no solution. So why? Because:
+
+S = \Sum_{i=0}^{n-1} i = n/2 (mod n) but 2*S = 0 (mod n)
+
+See also at:
+
+[http://codeforces.com/blog/entry/7499#comment-133446](//codeforces.com/blog/entry/7499#comment-133446)
+
+* [Problem B. Rectangle Puzzle II](//codeforces.com/problemset/problem/303/B)
+
+Math, Geometry
+
+Give you *n*, *m*, *x*, *y*, *a*, *b*.
+
+Find a maximum sub-rectangle within (0, 0) — (*n*, *m*), so that it contains the given point(*x*, *y*) and its length-width radio is exactly (*a*, *b*). If there are multiple solutions, find the rectangle which is closest to (*x*, *y*). If there are still multiple solutions, find the lexicographically minimum one.
+
+Split the problem into *x*-axis and *y*-axis. Then you can solve the sub tasks in *O*(1).
+
+```
+d = gcd(a,b)
+a /= d
+b /= d
+t = min(n/a, m/b)
+a *= t
+b *= t
+```
+
+Be careful, when the length is outside the original rectangle.
+
+* [Problem C. Minimum Modular](//codeforces.com/problemset/problem/303/C)
+
+Math, Graph theory, Brute-force, Congruent
+
+It is hard to solve this problem at once, so at first, let us consider on k = 0, this easier case can be solved by enumerate on the *ans*. Let us define a bool array diff[], which diff[x] is weather there are two number, *a**i*, *a**j*, such that *abs*(*a**i* - *a**j*) = *x*.
+
+So *ans* is legal <=> diff[ans], diff[2*ans] … are false.
+
+The time-complexity *O*(*n*2 + *mlogm*). Here *m* is the maximum *a**i*.
+
+Consider on *k* > 0, we need to know how many pairs which has difference x. Store them in
+`vector<pair <int, int> > diff[x];`
+
+Then use a [dsu](https://en.wikipedia.org/wiki/Disjoint_sets) to maintain the how many a_i are congruent when enumerate on the *ans*.
+
+* [Problem D. Rotatable Number](//codeforces.com/problemset/problem/303/D)
+
+Math, Number theory
+
+(Coming Soon...)
+
+[http://codeforces.com/blog/entry/7499#comment-133342](//codeforces.com/blog/entry/7499#comment-133342)
+
+* [Problem E. Random Ranking](//codeforces.com/problemset/problem/303/E)
+
+Math, Probability
+
+(Coming After D...)
+
+[http://codeforces.com/blog/entry/7499#comment-133488](//codeforces.com/blog/entry/7499#comment-133488)
diff --git a/editorials/305.md b/editorials/305.md
@@ -0,0 +1,36 @@
+Source: https://codeforces.com/blog/entry/7712
+
+## [305A - Strange Addition](/contest/305/problem/A "Codeforces Round 184 (Div. 2)")
+
+All you have to do is implement following algorithm:
+
+1. If we have numbers 0 or 100, we take them to needed subset.
+2. If we got number greater than 0 and less than 10, we take it.
+3. If we got number  divisible by 10 we take it.
+4. In case we have no numbers of second and third type, we take a number  that is not divisible by 10
+
+[Solution](http://pastebin.com/nQXi0Khh)
+
+## [305B - Continued Fractions](/contest/305/problem/B "Codeforces Round 184 (Div. 2)")
+
+There are at most two ways to represent rational fraction as continued. Using Euclid algorithm you can do that for  and then check equality of corresponding *a**i*.
+
+[Solution](http://pastebin.com/x4rXtxen)
+
+## [305C - Ivan and Powers of Two](/contest/305/problem/C "Codeforces Round 184 (Div. 2)")
+
+First of all, let's carry over all powers of two in the following way: if we have *a**i* = *a**j*, *i* ≠ *j*, carry 1 to *a**i* + 1. Now as all of *a**i* are distinct, the answer is *max*(*a**i*) — *cnt*(*a**i*) + 1, where *max*(*a**i*) — maximal value of *a**i*,*cnt*(*a**i*) — size of *a*
+
+[Solution](http://pastebin.com/RrRe5ffR)
+
+## [305D - Olya and Graph](/contest/305/problem/D "Codeforces Round 184 (Div. 2)")
+
+First of all let's consider a graph on a number line. It's neccesary to have edges *i* - > *i* + 1(first type). Also you can edges like *i* - > *i* + *k* + 1 (second type). Other edges are forbidden. This allows us to understand whether the answer is 0 or not. Also answer is 0 when all edges of second type doesn't intersect, considering them to be segments of number line, except when *k* ≥ *n* - 1 — in this case answer is 1. Now we know that answer != 0. Frow all edges we have let's use only second type edges. If there aren't any of this edges we can add 1 to the answer, because of possibility of adding 0 edges to graph. For every vertex *i*, that has possibility of adding second type edges, let's add to answer 2*cnt*, *cnt* — amount of vertexes on [i, min(i + k, n — k — 1)] without edges of second type out of them. Also it is necessary for all the second type edges to start in this segment.
+
+[Solution O(n + m)](http://pastebin.com/JaL2y2Gc) [Solution O(m + log(n))](http://pastebin.com/GRKqSsmH)
+
+## [305E - Playing with String](/contest/305/problem/E "Codeforces Round 184 (Div. 2)")
+
+Let's consider substring of *s* *s*[*i*... *j*], that all characters from *i* to *j* are palindrome centers, and *i* - 1, *j* + 1 are not. Every such substring can be treated independently from the others, and as we don't need to know it'sstructure let's consider only it length *len*. Let's calculate *grundy*[*len*] — Grundy function. If we want to cut character at position *i* 0 ≤ *i* < *len* then our game splits in to independent ones: first will have length *i* - 1, second — *len* - *i* - 2, as *s*[*i* - 1] and *s*[*i* + 1] are not centers of palindrome any more.
+
+[Solution](http://pastebin.com/niiD2WDM)
diff --git a/editorials/309.md b/editorials/309.md
@@ -0,0 +1,78 @@
+Source: https://codeforces.com/blog/entry/7749
+
+## [Problem A. Morning run](//codeforces.com/contest/308/problem/A)
+
+We were asked to find the expected value of meetings between the runners. How to do that? As the first step, expected value is lineal, so we can split the initial problems into the different ones: find the expected value of meetings between the fixed pair of runners. We will solve these problems. To do that we need to make some observations:
+
+1. Let *x* be the distance between the two runners and they run face to face for infinite amount of time (probability of that obviously equals to 0.5·0.5 = 0.25). Then the first meeting will happen at time , the next one — , the next —  and so on.
+2. Let us assume that every run ran for *l* time units. Then if two runners meet — they meet exactly two times. The probability of the meeting equals to 0.5, because in two cases they run in the same direction and in two cases in the different ones.
+
+We will build our solution based on these two observations. As the first step let us represent *t* as *t* = *k*·*l* + *p*, where 0 ≤ *p* < *l*. Then each runner will run *k* full laps. What does that mean? Because we have  pairs of runners, then in those *k* laps each pair will have 2*k* meetings with probability equals to 0.5. So, we need to add 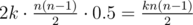 to the answer.
+
+Now we need to take into account *p* seconds of running. Let us assume that the distance between two runners is *x* and they run towards each other. Then they will meet if , or *x* ≤ 2*t*. They will meet once more if , ir *x* ≤ 2*t* - *l*. They cannot meet more than twice, because *p* < *l*.
+
+Let us fix one of the runners, then using binary search we can find all other runners at distance no more than *x* from the fixed one. Let us choose *x* as *x* = 2*t*, and then the number of runners at the distance no more than *x* stands for the number of runners which meet with the fixed one at least once. If *x* = 2*t* - *l*, we will find the number of runners which meet with the fixed one exactly two times. Multiplying these numbers by 0.25 — probability of the meeting, and add it to the answer.
+
+The complexity of this solution is . We can reduce it using two pointers method.
+
+## [Problem B. Context Advertising](//codeforces.com/contest/308/problem/B)
+
+We were asked to find the maximal number of words we can fit into the block of size *r* × *c*. Let's first solve such problem: what is the maximal number of consecutive words which can fit in a row of lenth *c*, if the first word has index *i*. We can solve it using binary search or moving the pointer. Now let us build a graph, where vertices are the words and there is a directional edge between *i* and *j*, if words from *i* to *j* - 1 fit in one row of length *c*, but words from *i* to *j* don't. The weight of the edge is *j* - *i*. The we have the following problem: we need to find the path of length *k*, which has the maximal weight. Easy to solve it with complexity  saving weights of all the paths with lengthes equal to the powers of two, or in *O*(*n*) time using dfs.
+
+The other problems competitors faced — that we were asked to print the whole text, not only the length.
+
+## [Problem C. Memory for Arrays](//codeforces.com/contest/308/problem/C)
+
+We were asked to find the maximal number of arrays we can fit into the memory. A small observation first, let the answer be *k*, then one of the optimal solutions fits the *k* smallest arrays into the memory. We can assume that we have arrays of size 1 and we want to arrange the memory for the maximal arrays as possible. Then if we have parts of memory of odd size, if we fit array of size 1 at this part we will obtain part of even size. From other hand, if we put arrays of bigger size we will not change the parity and if we don't fill it with arrays of size one and initially it's of odd size then in the end we will have at least one empty cell. So it's reasonable to put the arrays of size one into the memory of odd size. Let's do it until we can do it. We have three possible situations:
+
+1. We don't have memory parts of odd size anymore.
+2. We don't have arrays of size 1 anymore.
+3. We don't have neither arrays of size 1 neither memory parts of size 1.
+
+Let us start from the first case. Suppose that there are some arrays of size 1 left, but there are no memory parts of odd size. Easy to see then in such case we need to group arrays of size 1 in pairs and then consider them as the same array. So we can divide every number by two and reduce the problem to the initial one.
+
+In the second case if we divide every number by two we will obtain the same problem (and that cannot increase the answer).
+
+The third case is similar to the second one.
+
+When implementing this we need to remember that first we have to fill the memory with arrays which are build from the maximal numbers of initial arrays.
+
+The complexity of the given algorithm is .
+
+## [Problem D. Tennis Rackets](//codeforces.com/contest/308/problem/D)
+
+We were asked to find the number of obtuse triangles which satisfy the problem statement. Author's solution has complexity *O*(*n*2), but it has some optimizations, so it easily works under the TL.
+
+Every triangle has only one obtuse angle. Due to symmetry reasons we can fix one of the sides and assume that obtuse angle is tangent to this side. Then we only need to find the number of such triangles and multiple the answer by 3.
+
+Every side is also symmetric, so we can consider only one half of it and then multiple the answer by 2.
+
+Let us assume that vertex *A* of the triangle has coordinates (0,0). Vertex *B* (0,) and *C*(2,0). Then we can find the coordinates of every single point at each of the sides and apply cosine theorem. We obtain the inequality which guarantee us that the triangle is obtuse. It can be written in many ways, on of them is following: If 1 ≤ *i*, *j*, *k* ≤ *n* — indices of points which are fixed at each of the sides, then triangle is obtuse iff: *f*(*i*, *j*, *k*) = 2*i*2 - *i*(*n* + 1) + 2*j*(*n* + 1) - *ij* - *k*(*i* + *j*) < 0. We can see that 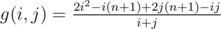 monotonically increases, so we can use moving pointer method applied to variable *k*. Then just go over all *i* from *m* + 1 to , then *j* from *m* + 1 till upper bound for *k* is less than or equal to *n* - *m* + 1 and just sum the results.
+
+We should mention that all of the operations have to be done in int type, it significantly increases the speed.
+
+## [Problem E. Sheep](//codeforces.com/contest/308/problem/E)
+
+Author's supposed greedy algorithm as a solution for this problem. Let us follow this algorithm. Let us create to label for every interval *Position**v* and *MaximalPosition**v*.
+
+*Position**v* — stands for position of *v* in the required permutation.
+
+*MaximalPosition**v* — stands for maximal possible position of *v* in the particular moment of the algorithm.
+
+Also let's consider *count* as a counter with initial value of 0 and set of unprocessed vertices *S*. The algorithm is following.
+
+1. Using binary search we find the maximal possible distance between the farthest sheep. And then check whether exists the permutation with maximal distance no more than *K*.
+2. Sort all the intervals in the increasing order of *r**i*.
+3. *Position**i* = 0, 1 ≤ *i* ≤ *n*, *MaximalPosition**i* = *n*, 1 ≤ *i* ≤ *n*, *current* = 1, *count* = 0.
+4. Do *count* = *count* + 1, *Position**current* = *count*, erase *current* from *S*, if *S* — is empty, required permutation has been found.
+5. Look at every interval connected to *current*, and update *MaximalPosition**v* = *min*(*MaximalPosition**v*, *Position**current* + *K*)
+6. Build sets *S*(*count*, *j*) = {*v*|*MaximalPosition**v* ≤ *count* + *j*}. If for every *j* ≥ *K* - *count* + 1 holds |*S*(*count*, *j*)| ≤ *j* go to the step 7, otherwise there is no such permutation.
+7. Choose the minimal *j* such that |*S*(*count*, *j*)| = *j*. Choose from it the interval with the smallest *r**i* and consider it as a new value for *current*, go to the step 4.
+
+First let us discuss the complexity. Let us fix *K* (in total there are  iterations with fixed *K*).
+
+Every step from 4 to 7 will be done at most *n* times (every time size of *S* decreases by one). Every step can be implemented in *O*(*n*) time. The most difficult one — step 6. But we can see that it's not necessary to actually build the sets, all we need to know — their sizes. This can be done in linear time just counting the number of intervals that *MaximalPosition**v* = *i*. Let if be *C**i* — then size of *S*(*count*, *j*) equals to *C*1 + *C*2 + ... + *C**count* + *j*, which can be easily calculated with partial sums.
+
+Now let us discuss why this algorithm works. If we have *Position* labels for every interval — we obviously have the solution. Now let us assume that we ended up earlier. Then we will show that there is no such permutation. If algorithm ended, it means that for some *count* (consider the smallest such *count*), exists *j*0, that |*S*(*count*, *j*0)| > *j*0 at this step. Then |*S*(*count*, *k*)| > *k*. Let us prove that from contradiction. From the definition of *count* we have |*S*(*count* - 1, *j*)| ≤ *j* for every *j* ≥ *k* - *count* + 2. Then |*S*(*count*, *j*)| = |*S*(*count* - 1, *j* + 1)| - 1 ≤ *j* for every *j* ≤ *k* - 1. And *S*(*count*, *j*) = *S*(*count*, *k*) for *k* ≤ *j* < *n* - *count* = |*S*(*count*, *j*)| = |*S*(*count*, *k*)| ≤ *j*. Finally |*S*(*count*, *n* - *count*)| = *n* - *count*. Then |*S*(*count*, *j*)| ≤ *j* for every *j*, so we obtain contradiction. That means if algorithm stops at step 6 we have |*S*(*count*, *k*)| > *k*. So exist at least *k* + 1 interval, which still don't have assigned label *Position* and they should be assigned after *count*. So one of the intervals in *S*(*count*, *k*) has to have the value of *Position* at least *count* + *k* + 1. But every intervals in *S*(*count*, *k*) connected to at least one interval with *Position* ≤ *count*. So, we obtain that there is now such permutation.
+
+Editorial was prepared by [sdya](/profile/sdya "International Grandmaster sdya") and [Seyaua](/profile/Seyaua "International Master Seyaua").
diff --git a/editorials/311.md b/editorials/311.md
@@ -0,0 +1,68 @@
+Source: https://codeforces.com/blog/entry/7785
+
+#### [311A - The Closest Pair](/contest/311/problem/A "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7787](//codeforces.com/blog/entry/7787)
+
+#### [311B - Cats Transport](/contest/311/problem/B "Codeforces Round 185 (Div. 1)")
+
+P.S. I feel very sorry that I thought it was a traditional DP problem with only 800B code and didn't realize some participants were not familiar with such kind of problems, so I said it was easy.
+
+Let a[i] be the distance from hill 1 to hill i, s[i]=a[1]+a[2]+…+a[i].
+
+Firstly, we sort the cats by (Ti-a[i]). Then we can divide the cats into P consecutive parts, and plan a feeder for each part. **Dynamic Programming** can solve this problem.
+
+Let f[i,j] indicates the minimum sum of waiting time with i feeders and j cats.
+
+f[i,j] = f[i-1,k]+a[j]*(j-k)-s[j]+s[k] = a[j]*j-s[j] + f[i-1,k]+s[k]-a[j]*k
+
+That’s O(PM^2). It’ll get TLE.
+
+Let p>q, if p is "better" than q, then:
+
+f[i-1,p]+s[p]-a[j]*p>f[i-1,q]+s[q]-a[j]*q
+
+(f[i-1,p]+s[p])-(f[i-1,q]+s[q])>a[j]*(p-q)
+
+g[p]-g[q]>a[j]*(p-q)
+
+So we can use **Convex hull trick** with a queue. Then we get O(MP), which can pass the problem.
+
+#### [311C - Fetch the Treasure](/contest/311/problem/C "Codeforces Round 185 (Div. 1)")
+
+Firstly, we solve such a problem: if we can go exactly k,k1,k2……or kp cells forward each step, what cells can we reach?
+
+We divide the H cells into k groups: Group 0,1……k-1. The i-th cell should be in Group (i mod k).
+
+* If we reach Cell x in Group (x mod k), we can also reach Cell (x+kj , 1<=j<=p) in Group ((x+kj)mod k).
+* If we reach Cell x in Group (x mod k), we can also reach Cell (x+k) in the same group.
+
+Let D[i] be the minimum cell we can reach in Group i. Then we can reach all the cells which number are bigger then D[i] in Group i.
+
+Regard the groups as points. Regard k,k1,k2……kp as edges. And use a Shortest-Path Algorithm to calculate all D[i].
+
+Notice that there are at most 20 operations of type 1, we are able to run such an algorithm after each of these operations. The total time complexity is O(20*k*20*log(k)) with Dijkstra.
+
+Secondly, we build a binary-heap to solve operations of type 2 and 3.
+
+* Type1 – If a D[i] becomes smaller, we put the new cells we can reach into the heap.
+* Type2 – Decrease a value of a node in the heap, or a cell in the “Treasure Cell” array.
+* Type3 – Ask the biggest node in the heap and delete it.
+
+These are basic operations of binary-heap. The time complexity is O(NlogN). In C++, you can also use priority_queue from STL and lazy-tags. So we can solve the whole problem in O(400klogk+NlogN).
+
+#### [311D - Interval Cubing](/contest/311/problem/D "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7787](//codeforces.com/blog/entry/7787)
+
+#### [311E - Biologist](/contest/311/problem/E "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7847](//codeforces.com/blog/entry/7847)
+
+#### [312A - Whose sentence is it?](/contest/312/problem/A "Codeforces Round 185 (Div. 2)")
+
+We only need to find out if “miao.” is a prefix of the sentence, and if “lala.” is a suffix of the sentence. Pay attention to the situation when both conditions are satisfied.
+
+#### [312B - Archer](/contest/312/problem/B "Codeforces Round 185 (Div. 2)")
+
+[http://codeforces.com/blog/entry/7847](//codeforces.com/blog/entry/7847)
diff --git a/editorials/312.md b/editorials/312.md
@@ -0,0 +1,68 @@
+Source: https://codeforces.com/blog/entry/7785
+
+#### [311A - The Closest Pair](/contest/311/problem/A "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7787](//codeforces.com/blog/entry/7787)
+
+#### [311B - Cats Transport](/contest/311/problem/B "Codeforces Round 185 (Div. 1)")
+
+P.S. I feel very sorry that I thought it was a traditional DP problem with only 800B code and didn't realize some participants were not familiar with such kind of problems, so I said it was easy.
+
+Let a[i] be the distance from hill 1 to hill i, s[i]=a[1]+a[2]+…+a[i].
+
+Firstly, we sort the cats by (Ti-a[i]). Then we can divide the cats into P consecutive parts, and plan a feeder for each part. **Dynamic Programming** can solve this problem.
+
+Let f[i,j] indicates the minimum sum of waiting time with i feeders and j cats.
+
+f[i,j] = f[i-1,k]+a[j]*(j-k)-s[j]+s[k] = a[j]*j-s[j] + f[i-1,k]+s[k]-a[j]*k
+
+That’s O(PM^2). It’ll get TLE.
+
+Let p>q, if p is "better" than q, then:
+
+f[i-1,p]+s[p]-a[j]*p>f[i-1,q]+s[q]-a[j]*q
+
+(f[i-1,p]+s[p])-(f[i-1,q]+s[q])>a[j]*(p-q)
+
+g[p]-g[q]>a[j]*(p-q)
+
+So we can use **Convex hull trick** with a queue. Then we get O(MP), which can pass the problem.
+
+#### [311C - Fetch the Treasure](/contest/311/problem/C "Codeforces Round 185 (Div. 1)")
+
+Firstly, we solve such a problem: if we can go exactly k,k1,k2……or kp cells forward each step, what cells can we reach?
+
+We divide the H cells into k groups: Group 0,1……k-1. The i-th cell should be in Group (i mod k).
+
+* If we reach Cell x in Group (x mod k), we can also reach Cell (x+kj , 1<=j<=p) in Group ((x+kj)mod k).
+* If we reach Cell x in Group (x mod k), we can also reach Cell (x+k) in the same group.
+
+Let D[i] be the minimum cell we can reach in Group i. Then we can reach all the cells which number are bigger then D[i] in Group i.
+
+Regard the groups as points. Regard k,k1,k2……kp as edges. And use a Shortest-Path Algorithm to calculate all D[i].
+
+Notice that there are at most 20 operations of type 1, we are able to run such an algorithm after each of these operations. The total time complexity is O(20*k*20*log(k)) with Dijkstra.
+
+Secondly, we build a binary-heap to solve operations of type 2 and 3.
+
+* Type1 – If a D[i] becomes smaller, we put the new cells we can reach into the heap.
+* Type2 – Decrease a value of a node in the heap, or a cell in the “Treasure Cell” array.
+* Type3 – Ask the biggest node in the heap and delete it.
+
+These are basic operations of binary-heap. The time complexity is O(NlogN). In C++, you can also use priority_queue from STL and lazy-tags. So we can solve the whole problem in O(400klogk+NlogN).
+
+#### [311D - Interval Cubing](/contest/311/problem/D "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7787](//codeforces.com/blog/entry/7787)
+
+#### [311E - Biologist](/contest/311/problem/E "Codeforces Round 185 (Div. 1)")
+
+[http://codeforces.com/blog/entry/7847](//codeforces.com/blog/entry/7847)
+
+#### [312A - Whose sentence is it?](/contest/312/problem/A "Codeforces Round 185 (Div. 2)")
+
+We only need to find out if “miao.” is a prefix of the sentence, and if “lala.” is a suffix of the sentence. Pay attention to the situation when both conditions are satisfied.
+
+#### [312B - Archer](/contest/312/problem/B "Codeforces Round 185 (Div. 2)")
+
+[http://codeforces.com/blog/entry/7847](//codeforces.com/blog/entry/7847)
diff --git a/editorials/313.md b/editorials/313.md
@@ -0,0 +1,44 @@
+Source: https://codeforces.com/blog/entry/7826
+
+[313A - Ilya and Bank Account](/contest/313/problem/A "Codeforces Round 186 (Div. 2)")
+
+This problem is the easiest one. You need to use only div and mod functions. If *n*>0, then answer is *n*, else you need to delete one of two digits.
+
+For better understanding you can look at [solution](//codeforces.com/contest/313/submission/3794963).
+
+[313B - Ilya and Queries](/contest/313/problem/B "Codeforces Round 186 (Div. 2)")
+
+Precalculate some array *A**i*, that *A**i* = 1, if *s**i* = *s**i* + 1, else *A**i* = 0. Now for any query (*l*, *r*), you need to find sum of *A**i*, that (*l* ≤ *i* < *r*). It is standart problem. For solving this problem you can precalcutate some another array Sum, where *Sum**i* = *A*1 + *A*2 + ... + *A**i*. Then sum of interval (*l*, *r*) is Sum_r — Sum_{l-1}.
+
+For better understanding you can look at [solution](//codeforces.com/contest/313/submission/3798187).
+
+[313C - Ilya and Matrix](/contest/313/problem/C "Codeforces Round 186 (Div. 2)")
+
+At the start sort array. Let *C**i* — number of times of entering the number in *A**і* optimal placement. Answer is sum of *A**i* * *C**i* for all *i* (1 ≤ *i* ≤ 4*n*). If we look at the array *C*, we can see that for maximal element *C* = *n* + 1 (for array with size 4*n*), then for second, third and fourth maximum elements *C* = *n*. On this basis we can see, that for array with non-increasing order answer calculate like *Sum*(1, 1) + *Sum*(1, 4) + *Sum*(1, 16) + ... + *Sum*(1, 4*n*). So, for solve this problem you have to know only sort.
+
+For better understanding you can look at [solution](//codeforces.com/contest/313/submission/3798779)
+
+[313D - Ilya and Roads](/contest/313/problem/D "Codeforces Round 186 (Div. 2)")
+
+To solve this problem you need to use dynamic programming. Let *Full**i*, *j* — minimal cost of covering interval (*i*, *j*). Fix left border and move right. You can solve this subtask with complexity *O*(*nm*) or *O*(*nmlogn*). Now we need to solve the standart problem of dynamic programming. Cover *K* points with intervals that have not intersect. This problem with square dynamic. *dp**i*, *j* — minimal cost of covering *j*-points, if you look some prefix length *i*. Answer for all problem is minimal integer from *dp**i*, *j*, (*k* ≤ *j* ≤ *n*).
+To solve second part:
+
+1) *dp**i* + 1, *j* = *min*(*dp**i* + 1, *j*, *dp**i*, *j*) — skip point with number *i* + 1
+
+2) *dp**k*, *j* + *len* = *min*(*dp**k*, *j* + *len*, *dp**i*, *j* + *Cost*); *Cost* — cost of interval with length *len*, that ending at point k. We precalculate *Cost* at first part of solution.
+
+For better understanding you can look at [solution](//codeforces.com/contest/313/submission/3800042)
+
+[313E - Ilya and Two Numbers](/contest/313/problem/E "Codeforces Round 186 (Div. 2)")
+
+Author solution is harder than that which is offered by [MrDindows](/profile/MrDindows "Candidate Master MrDindows"). It is solution of [MrDindows](/profile/MrDindows "Candidate Master MrDindows").
+
+1) Get the number of our sequences in sorted by frequencies. Thus from the first sequence (hereinafter — the first type) — in a direct order from the second — to the contrary.
+
+2) These numbers are put on the stack, where if, recording onto the stack of the second type, we find the number at the top of the first type, then this pair of extract and add to the answer.
+
+3) At the end, obviously the stack we can find a number of properties of the second type and the first bottom — on. Then their grouping in response pairs with the start and end.
+
+For better understanding you can look at [solution](//codeforces.com/contest/313/submission/3803538).
+
+*Sorry* *for* *waiting*.
diff --git a/editorials/314.md b/editorials/314.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/7905
+
+[315A - Sereja and Bottles](/contest/315/problem/A "Codeforces Round 187 (Div. 2)")
+Just check for each bottle, can I open it with another. In this task can pass absolutely any solutions.
+
+[315B - Sereja and Array](/contest/315/problem/B "Codeforces Round 187 (Div. 2)")
+We will support all of the elements in the array, but also we will supprt additionally variable add: how much to add to all the elements. Then to add some value to every element we simply increase the add. In the derivation we deduce the value of the array element + add. When you update the item we put to a value, value that you need to put minus the current value of add.
+
+[314A - Sereja and Contest](/contest/314/problem/A "Codeforces Round 187 (Div. 1)")
+Note that if we remove some of the participants, we never remove the participants with lower numbers as theirs amount will only increase. So just consider the sequence of all the participants, and if the participant does not fit we delete him.
+
+[314B - Sereja and Periods](/contest/314/problem/B "Codeforces Round 187 (Div. 1)")
+It is clear that we can use greedy algorithm to look for the number of occurrences of the 2nd string in the first string, but it works too slow. To speed up the process, you can look at the first line of the string that specifies the second period. And the answer is divided into how many string you need to set the second string. Next, we consider our greedy algorithm. We are going by the first string, till we find the first character of the second string, then the second, third and so on until the last, then again find the first, second, and so the cycle. It is clear that if we stand in the same twice in a state in which the positions in the first string corresponds to one character string that determines the period and the position of the second string are the same, then we obtain the period. When we find this period, we can just repeat it as many times as possible.
+
+To better understand, I advise you to read any accepted solution.
+
+[314C - Sereja and Subsequences](/contest/314/problem/C "Codeforces Round 187 (Div. 1)")
+It is clear that we need to calculate the sum of the products of elements of all the different non-decreasing subsequences of given sequence. Let's go through the sequence from left to right and maintain the array q[i]: what means the sum of all relevant sub-sequences, such that their last element is equal to i. Clearly, if the next number is x, then you need to put q[x] = sum (q[1] + q[2] + ... + q[x]) * x + x. The answer to the problem is the sum of q[i]. To find all the amounts you can use Fenwick tree.
+
+[314D - Sereja and Straight Lines](/contest/314/problem/D "Codeforces Round 187 (Div. 1)")
+Roll all at 45 degrees using the transformation: (x, y) -> (x ', y'): x '= x + y, y' = x-y. Next you need to place two lines parallel to the coordinate axes. Sort the points by the first coordinate. Next, we use a binary search for the answer. May we have fixed a number, you now need to check whether it is enough or not. Note that now we need to put two strips of width 2 * fixed amount that they would have to cover all the points. Suppose that some point should be close to the left side of the vertical strip, then for all points that do not belong to the strip we find the minimum and maximum second coordinate. If the difference between the found coordinates no more then 2 * fixed quantity, the strip can be placed, otherwise — no.
+
+soon...
diff --git a/editorials/315.md b/editorials/315.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/7905
+
+[315A - Sereja and Bottles](/contest/315/problem/A "Codeforces Round 187 (Div. 2)")
+Just check for each bottle, can I open it with another. In this task can pass absolutely any solutions.
+
+[315B - Sereja and Array](/contest/315/problem/B "Codeforces Round 187 (Div. 2)")
+We will support all of the elements in the array, but also we will supprt additionally variable add: how much to add to all the elements. Then to add some value to every element we simply increase the add. In the derivation we deduce the value of the array element + add. When you update the item we put to a value, value that you need to put minus the current value of add.
+
+[314A - Sereja and Contest](/contest/314/problem/A "Codeforces Round 187 (Div. 1)")
+Note that if we remove some of the participants, we never remove the participants with lower numbers as theirs amount will only increase. So just consider the sequence of all the participants, and if the participant does not fit we delete him.
+
+[314B - Sereja and Periods](/contest/314/problem/B "Codeforces Round 187 (Div. 1)")
+It is clear that we can use greedy algorithm to look for the number of occurrences of the 2nd string in the first string, but it works too slow. To speed up the process, you can look at the first line of the string that specifies the second period. And the answer is divided into how many string you need to set the second string. Next, we consider our greedy algorithm. We are going by the first string, till we find the first character of the second string, then the second, third and so on until the last, then again find the first, second, and so the cycle. It is clear that if we stand in the same twice in a state in which the positions in the first string corresponds to one character string that determines the period and the position of the second string are the same, then we obtain the period. When we find this period, we can just repeat it as many times as possible.
+
+To better understand, I advise you to read any accepted solution.
+
+[314C - Sereja and Subsequences](/contest/314/problem/C "Codeforces Round 187 (Div. 1)")
+It is clear that we need to calculate the sum of the products of elements of all the different non-decreasing subsequences of given sequence. Let's go through the sequence from left to right and maintain the array q[i]: what means the sum of all relevant sub-sequences, such that their last element is equal to i. Clearly, if the next number is x, then you need to put q[x] = sum (q[1] + q[2] + ... + q[x]) * x + x. The answer to the problem is the sum of q[i]. To find all the amounts you can use Fenwick tree.
+
+[314D - Sereja and Straight Lines](/contest/314/problem/D "Codeforces Round 187 (Div. 1)")
+Roll all at 45 degrees using the transformation: (x, y) -> (x ', y'): x '= x + y, y' = x-y. Next you need to place two lines parallel to the coordinate axes. Sort the points by the first coordinate. Next, we use a binary search for the answer. May we have fixed a number, you now need to check whether it is enough or not. Note that now we need to put two strips of width 2 * fixed amount that they would have to cover all the points. Suppose that some point should be close to the left side of the vertical strip, then for all points that do not belong to the strip we find the minimum and maximum second coordinate. If the difference between the found coordinates no more then 2 * fixed quantity, the strip can be placed, otherwise — no.
+
+soon...
diff --git a/editorials/316.md b/editorials/316.md
@@ -0,0 +1,44 @@
+Source: https://codeforces.com/blog/entry/7937
+
+Dear all, ABBYY Cup 3.0 online-part is over!
+
+Thank you for participating! We are sorry for inconveniences with testings. [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov") has informed us about plans to buy new testing machins. So we hope that there won't be such cases in the future.
+
+Solutions are the following:
+
+[Problem "Special task"](//codeforces.com/contest/316/problem/A1)
+
+It was one of the easiest problems in the contest. A solution consists of considering several cases. The initial answer equals one. Firstly, let’s note that if there is a "?" in a string, so the number of every possible codes increases in 10 times. With the exception when "?" is at the beginning if a string so the number of every possible codes increases in 9 times. Next let’s consider the case when the letters are found in the strings. There are two cases here:
+
+- The first symbol of the string is not a letter. So one should multiply the answer by number of the arrangements of 10 figures for the number of different letters in the string.
+- The first symbol of the string is a letter. So one should multiply the answer by 9 and the number of the arrangements of 9 figures for the *N* - 1, where *N* is the number of different letters in the string.
+
+ It is no need to realize long arithmetic here. As all the operations (with the exception of multiplying be 10 because of the "?" can be done by standard arithmetic. For multiplying by 10 you can simply output the number of required zeros.
+
+ [Problem "PE Lesson"](//codeforces.com/contest/316/problem/D1)
+
+ To begin with the term “order of balls” conforms to commutation. And the constraint to number of kicking a ball conforms to the number of transpositions. The problem is to calculate the number of “suitable” commutations. The commutation is “suitable” means the following: if to divide the commutation into the loops then every loop will consist of no more than two elements with the maximum number of inversions equals 1. So you can solve the problem with the help on dynamic programming. For this purpose the function *f*(*a*, *b*) should be calculated, where *a* — is the digit 1 and *b* — is the digit 2 used in the problem. *f*(*a*, *b*) is the number of “suitable” commutations. One should note here that *f*(*a*, *b*) can be calculated using the following formula: 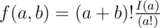, where *I*(*n*) = *I*(*n* - 1) + (*n* - 1) * *I*(*n* - 2) You can prove it yourselves.
+
+ [Problem "Suns and Rays"](//codeforces.com/contest/316/problem/F1)
+
+ This problem has different solutions. Let’s consider one of them. Denote the initial image as *T*. There are two operations for *T*: erosion and delation. Erosion is an operation of substitution of all the pixels which refer to image and are contiguous with pixels of background for the pixels of background. Dilation is an operation which is similar to inverse erosion: we substitute the pixels of background which are contiguous with pixels of image for the pixels of image. For determination neighbouring pixels you can use 4-connected neighborhood. The beams will vanish and the sun will stay as only a circle after applying erosion operation to *T* for several times. Then we should apply dilation operation for several times. Note that number of applied dilation operation should be more than number of applied erosion operation. Denote the obtained image as *P*. Then let’s consider initial image *T* and sort out connected components corresponding to the suns. After that you should sort out parts corresponding to the beams. How do it? The pixels which are in the image *T* and which are not *P* are corresponding to the beams.
+
+ [Problem "EKG"](//codeforces.com/contest/316/problem/B1)
+
+ Firstly one should sort out the chains in the waiting line. The chain is a sequence of the beavers which stay one after another. After that the length of all the chains and the chain in which are Smart Beaver are known. Secondly one can simply apply methods of dynamic programming for further calculation.
+
+ [Problem "Tidying up"](//codeforces.com/contest/316/problem/C1)
+
+ Let’s move from initial matrix to the bipartite graph. The matrix elements (*i*, *j*) for which *i* + *j* are even should be place to one part, the matrix elements (*i*, *j*) for which *i* + *j* are uneven should be place to another part. The edges are corresponding to squares which are situated side by side. After that let’s weigh the edges. The edges which connect equal elements of matrix have weights 0, for unequal elements – weight 1. After that the problem is reduced to finding of the maximum independent edge set with minimal weight. Substantiation of above-stated is following: an answer to the problem represents a partitioning of initial matrix for pairs. Note that for any partitioning minimal number of changing matrix elements corresponds to the number of pairs on unequal elements. So in the optimal partitioning the number of pairs of equal elements is maximum. For solving minimum-cost flow problem is needed to use some effective algorithm. For example, Dijkstra algorithm with heap adding conversion of edges weights from Johnson's algorithm.
+
+ [Problem "Summer Homework"](//codeforces.com/contest/316/problem/E1)
+
+ To solve this problem one should use segment tree. Let’s consider line segment [*l*;*r*] on this tree. For this purpose let’s introduce *S*(*x*), where *x* is integer. *S*(*x*) = *F*0 + *xA**l* + *F*1 + *xA**l* + 1 + … + *F**r* - *l* + *xA**r*, where *F**i* – *i*-th Fibonacci number, *A**i* – the array which consists of even numbers. One should note that *S*(*x*) with *x* = 0, 1, 2… are similar to Fibonacci numbers. Id est *S*(*x*) = *S*(*x* - 1) + *S*(*x* - 2) for *x* ≥ 2. This means that for every line segment [*l*;*r*] one should memorize *S*(0) and *S*(1). To calculate *S*(*x*) for *x* ≤ 2 one could use the formula: *S*(*x*) = *S*(0)*F**x* - 2 + *S*(1)*F**x* - 1. So solving 2-type query is reduced to calculation no more than  values if *S*(*x*) for different segment lines. The 1-type modification can be done by walking down the tree. For 3-type query one should use additional information in the tree and partial sums of Fibonacci number.
+
+ [Prblem "Good substrings"](//codeforces.com/contest/316/problem/G1)
+
+ For a start one needs to learn to compare quickly any two substrings, which could be taken from the source string or from one of the strings, which corresponds to the rules. It can be done, for example, with the help of suffix array, that contains every possible input strings. After construction of such an array and calculation of LCP (longest common prefix) values the problem of comparison of two substrings reduces to computation the number of identical characters and comparison the characters, that come after identical blocks. Computation the numbers of identical characters are equivalent to a problem of calculation of minimum on the interval of an array of LCP values. Because the LCP array does not change, efficient resolution of such requests can be earned with help of RMQ algorithms. Thus, in time *O*(1) we can compare any two substrings. Note, that time of precomputing depends on algorithms used for suffix array building and construction of RMQ.
+
+ Further we need to find the number of entries of a certain substring from the source string into the string of one of the rules. It can be done with help of binary search of string of rule in suffix array. Note, that we are able to compare two substrings in time *O*(1). Therefore complexity of search of the number of entries of a substring into a string will be 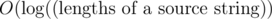.
+
+ Now let’s consider a certain suffix of a source string. We know its LCP with the previous suffix. This is the lower limit for the number of the characters, which we are considering in this suffix. Note, that the number of entries of a certain prefix of considered suffix monotonously depends on length of this prefix. Therefore for each rule one can define by binary search what minimum and maximum length of a prefix can be, to fit this prefix for the rule. After, it is essential to cross all received intervals. It is likely that using another structures of data on strings can get a simpler solution. Technical realization of considered solution is fairly laborious.
diff --git a/editorials/317.md b/editorials/317.md
@@ -0,0 +1,66 @@
+Source: https://codeforces.com/blog/entry/7956
+
+Problem analysis v 0.9.
+
+[318A - Even Odds](/contest/318/problem/A "Codeforces Round 188 (Div. 2)")
+
+In this problem we need to understand how exactly numbers from 1 to *n* rearrange when we write firstly all odd numbers and after them all even numbers. To find out which number stands at position *k* one needs to find the position where even numbers start and output either the position of the odd number from the first half of the sequence or for the even number from the second half of the sequence.
+
+[318B - Strings of Power](/contest/318/problem/B "Codeforces Round 188 (Div. 2)")
+
+In the heavy metal problem one needs to find the number of the substrings in the string S with a given prefix A and given suffix B. If we mark black all the starting positions of the entries of the string A in S, and white all the starting positions of the entries of the string B, then we come to the following problem: count the number of pairs <black position, white position> (in this order). To solve this it is enough to iterate from left to right counting the number of the passed black positions. Meeting black position we increment this number by one, meeting white position we add to the answer the number of pairs with this white position, which is exactly our memorized number of the already passed black positions.
+
+[317A - Perfect Pair](/contest/317/problem/A "Codeforces Round 188 (Div. 1)")
+
+[318C - Perfect Pair](/contest/318/problem/C "Codeforces Round 188 (Div. 2)")
+
+This problem were more about accuracy then about ideas or coding. It is important to not forget any cases here.
+
+On each step we replace one of the numbers *x*, *y* by their sum *x* + *y* until the pair becomes *m*-perfect (id est one of them becomes not lesser than *m*). It is clear that one sould replace lesser number from the pair *x*, *y*. Indeed lets say the pair *x*1 ≤ *y*1 *dominates* the pair *x*2 ≤ *y*2, if *y*1 ≥ *y*2 and *x*1 ≥ *y*2. In this case if one can get *m*-perfect pair from *x*2, *y*2 by certain sequence of actions, then one can get *m*-perfect pair from *x*1, *y*1 by the same or shorter sequence of actions. If *x* ≤ *y*, then the pair *x* + *y*, *y* dominates the pair *x* + *y*, *x*. Hence path from *x* + *y*, *y* to *m*-perfect is not longer than from *x* + *y*, *x*, and we may assume that we choose exactly this pair.
+
+Consider following cases:
+
+1. *x* ≤ 0, *y* ≤ 0 In this case our numbers do not increase in the process. Hence either the pair is alredy *m*-perfect or it will never be.
+2. *x* > 0 and *y* > 0 In this case for each *m* pair will after several steps become *m*-perfect. To count precise number of those steps one needs to launch emulation. If *x* > 0 and *y* > 0, then pair "grows exponentionaly>> (more formally: easy to show that starting from secnd step sum *x* + *y* grows in at least 3 / 2 times each step) and emulation works pretty fast. However in the case *x* < 0 and *y* > 0 (or vice versa) pair might change very slowly. Most bright example is *x* = - 1018, *y* = 1. Thus one needs to count number of steps until both numbers becomes positive before launching emulationt. For *x* < 0 and *y* > 0 number of those steps is exactly .
+
+[317B - Ants](/contest/317/problem/B "Codeforces Round 188 (Div. 1)")
+
+[318D - Ants](/contest/318/problem/D "Codeforces Round 188 (Div. 2)")
+
+One may reformulate the problem ass follows. Non-negative integers *A*(*x*, *y*) are placed in the vertices of two-dimensional lattice  We may imagine this construction as a function . On each step for each vertex *P* = (*x*, *y*) with *A*(*x*, *y*) ≥ 4 we perform operation φ*P*, which substracts 4 from *A*(*x*, *y*) and adds 1 to *A*(*x*, *y* - 1), *A*(*x*, *y* + 1), *A*(*x* - 1, *y*), *A*(*x* + 1, *y*). We may think that operation φ*P* applies to the whole function *A*. We need to find values of *A* after the iterations stops.
+
+Key idea is that operactions φ*P* and φ*Q* for all points *P* and *Q* *commutes*, that is φ*P*(φ*Q*(*A*)) = φ*Q*(φ*P*(*A*)). This means that the order of operations is unimportant. In particular, we may assume that from each given vertex run all possible four-groups of ants and not only one. After this observation one may run full emulation of the process. As an exercise contestants may check that ants will never leave square 200 × 200 with center in the origin 0 with given constraints.
+
+[317C - Balance](/contest/317/problem/C "Codeforces Round 188 (Div. 1)")
+
+[318E - Balance](/contest/318/problem/E "Codeforces Round 188 (Div. 2)")
+
+In this problem we need to find 2*n*2 transfusions from initial configuration to the desired one. First of all we propose the following: if in each connected component overall volume of the water in initial configuration is the same as in desired one, then answer exist. We call the vessel *ready*, if current volume of its water equals desired one. Let us describe solution which is probably easier to code. We will make vessels ready one by one. Consider the pair of non-ready vessels s and t (there is more water in s than desired, and less water in t than desired), such that they are connected by the path P, and if one transfuses d litres from s to t then one of the vessels becomes ready. Now we need to find a way to transfuse d litres by path P from s to t. One may write recursive function pour(s, t, d) for this aim. Let t' stand before t in this path, then function works as follows: transfuses from t' to t as many water as possible (not more than d of course), then calls pour(s, t', d) and on the final step transfuses from t' to t all that left. It is easy to check that all such transfusions are correct. This algorithm makes 2*len* transfusions on the path of length *len*, so total number of transfusions is not greater than 2*n*2.
+
+[317D - Game with Powers](/contest/317/problem/D "Codeforces Round 188 (Div. 1)")
+
+For each numner *x* denote sequence of its powers within [1..*n*] as *Pow*(*x*): 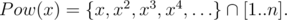
+
+Game proceeds as follows: on each step one player takes still available number *x* from 1 to *n* and prohibits whole set *Pow*(*x*). Who can't make his turn loses.
+
+This game may be decomposed in the sum of lesser games. Indeed, lets call number *x* *simple* (and corresponding sequence *Pow*(*x*) *simple*), if it is not a power of any number *y* < *x*. Then: 1. for each  there is simple *x*, such that ; 2. for each simple distinct *x* and *y* sets *Pow*(*x*) and *P*(*y*) do not intersect. Indeed, for a given *k* there is exactly one simple *x* such that *k* is power of *x*. This may be showed from fundamental theorem of arithmetic: if 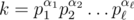 and *d* = *gcd*(α1, α2, ..., α*n*), then 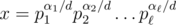.
+
+Hence set [1..*n*] decomposes into primitive sets *Pow*(*x*), on each of those *Pow*(*x*) game proceeds independetly. Now one may use Sprague–Grundy theory to see that mexx of our game is just xor of all mexx of games on simple *Pow*(*x*). For fixed *x*, if *Pow*(*x*) = {*x*, *x*2, ..., *x**s*}, then mexx of the game on *Pow*(*x*) depends only on *s*, but not on *x*. In our case *s* runs from 1 to 29, mexx for all such *s* may be directly precalculated. Now it is enough to find numbers *q*(*s*) of simple *x* with a given size of *Pow*(*x*) equal to *s* (actually we are interested in parity of *q*(*s*) not in *q*(*s*) itself).
+
+Our constraints allows to do it directly: run *x* from 2 to , if it is not crossed out, determine the size *Pow*(*x*) [increment corresponding *q*(*s*)], and cross out all numbers from *Pow*(*x*).
+
+This cycle finds all simple sequences of length at least 2. Quantity of non-crossed numbers is the number of all simple sequences of length 1. Now it is enough to look at parities of *q*(*s*) and xor coressponding mexx.
+
+However one may find all *q*(*s*) for . Indeed lets look at the number  and sequence {*x*, *x*2, *x*3, *x*4, ..., *x**s*}. This sequence is not simple iff it is containd in some larger simple sequence. But number of subsequenes of size *s* in a given sequence of size *t* > *s* is easy to find: it is just [*t* / *s*]. Recalling that simple sequences do not intersect one gets the reccurent formula:
+
+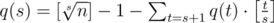.
+
+Now it is easy to find all *q*(*s*) from *q*(29) to *q*(1).
+
+*Remark:* while coding it is important to remeber simple number *x* = 1.
+
+[317E - Princess and Her Shadow](/contest/317/problem/E "Codeforces Round 188 (Div. 1)")
+
+In this problem princess Vlada should simply catch the Shadow. Here is the idea of a solution. If there is only one tree, then using it as a barrier to the shadow it is not hard to catch the shadow. Similar technique works if Vlada and Shadow are far from the square where all the trees grow. But what can she do in the dark depths of the forest? If there is no path at all between Vlada and Shadow, then there is no way to catch it. Otherwise consider a shortest path from Vlada to the Shadow and make Vlada follow it. This path gives Vlada a queue of the steps that she should perform. Additionaly if shadow moves, then we add her move to the queue (simply speaking Vlada follows the shadow). This is where the algorithmic part ends. Now we state that either Vlada catches the shadow in the desired number of steps, or steps out of the "forest square". To proof this we note that the length of the path between Vlada and Shadow may only decrease. And if it does not decrease long enough, then once in *k* steps (*k* is the length of the path) Vlada and Shadow shifts at the same vector over and over, and at some moment leaves the "forest square". Note that if the trees allow our heroes to step out of the "forest square" at the beginning, then we may just get them out from the start. But taking this approach we still need to catch the Shadow in a "labyrinth forest".
+
+Apologies for the delay. There are probably misprints and mistakes here (thousands of them!), please feel free to point them out.
diff --git a/editorials/318.md b/editorials/318.md
@@ -0,0 +1,66 @@
+Source: https://codeforces.com/blog/entry/7956
+
+Problem analysis v 0.9.
+
+[318A - Even Odds](/contest/318/problem/A "Codeforces Round 188 (Div. 2)")
+
+In this problem we need to understand how exactly numbers from 1 to *n* rearrange when we write firstly all odd numbers and after them all even numbers. To find out which number stands at position *k* one needs to find the position where even numbers start and output either the position of the odd number from the first half of the sequence or for the even number from the second half of the sequence.
+
+[318B - Strings of Power](/contest/318/problem/B "Codeforces Round 188 (Div. 2)")
+
+In the heavy metal problem one needs to find the number of the substrings in the string S with a given prefix A and given suffix B. If we mark black all the starting positions of the entries of the string A in S, and white all the starting positions of the entries of the string B, then we come to the following problem: count the number of pairs <black position, white position> (in this order). To solve this it is enough to iterate from left to right counting the number of the passed black positions. Meeting black position we increment this number by one, meeting white position we add to the answer the number of pairs with this white position, which is exactly our memorized number of the already passed black positions.
+
+[317A - Perfect Pair](/contest/317/problem/A "Codeforces Round 188 (Div. 1)")
+
+[318C - Perfect Pair](/contest/318/problem/C "Codeforces Round 188 (Div. 2)")
+
+This problem were more about accuracy then about ideas or coding. It is important to not forget any cases here.
+
+On each step we replace one of the numbers *x*, *y* by their sum *x* + *y* until the pair becomes *m*-perfect (id est one of them becomes not lesser than *m*). It is clear that one sould replace lesser number from the pair *x*, *y*. Indeed lets say the pair *x*1 ≤ *y*1 *dominates* the pair *x*2 ≤ *y*2, if *y*1 ≥ *y*2 and *x*1 ≥ *y*2. In this case if one can get *m*-perfect pair from *x*2, *y*2 by certain sequence of actions, then one can get *m*-perfect pair from *x*1, *y*1 by the same or shorter sequence of actions. If *x* ≤ *y*, then the pair *x* + *y*, *y* dominates the pair *x* + *y*, *x*. Hence path from *x* + *y*, *y* to *m*-perfect is not longer than from *x* + *y*, *x*, and we may assume that we choose exactly this pair.
+
+Consider following cases:
+
+1. *x* ≤ 0, *y* ≤ 0 In this case our numbers do not increase in the process. Hence either the pair is alredy *m*-perfect or it will never be.
+2. *x* > 0 and *y* > 0 In this case for each *m* pair will after several steps become *m*-perfect. To count precise number of those steps one needs to launch emulation. If *x* > 0 and *y* > 0, then pair "grows exponentionaly>> (more formally: easy to show that starting from secnd step sum *x* + *y* grows in at least 3 / 2 times each step) and emulation works pretty fast. However in the case *x* < 0 and *y* > 0 (or vice versa) pair might change very slowly. Most bright example is *x* = - 1018, *y* = 1. Thus one needs to count number of steps until both numbers becomes positive before launching emulationt. For *x* < 0 and *y* > 0 number of those steps is exactly .
+
+[317B - Ants](/contest/317/problem/B "Codeforces Round 188 (Div. 1)")
+
+[318D - Ants](/contest/318/problem/D "Codeforces Round 188 (Div. 2)")
+
+One may reformulate the problem ass follows. Non-negative integers *A*(*x*, *y*) are placed in the vertices of two-dimensional lattice  We may imagine this construction as a function . On each step for each vertex *P* = (*x*, *y*) with *A*(*x*, *y*) ≥ 4 we perform operation φ*P*, which substracts 4 from *A*(*x*, *y*) and adds 1 to *A*(*x*, *y* - 1), *A*(*x*, *y* + 1), *A*(*x* - 1, *y*), *A*(*x* + 1, *y*). We may think that operation φ*P* applies to the whole function *A*. We need to find values of *A* after the iterations stops.
+
+Key idea is that operactions φ*P* and φ*Q* for all points *P* and *Q* *commutes*, that is φ*P*(φ*Q*(*A*)) = φ*Q*(φ*P*(*A*)). This means that the order of operations is unimportant. In particular, we may assume that from each given vertex run all possible four-groups of ants and not only one. After this observation one may run full emulation of the process. As an exercise contestants may check that ants will never leave square 200 × 200 with center in the origin 0 with given constraints.
+
+[317C - Balance](/contest/317/problem/C "Codeforces Round 188 (Div. 1)")
+
+[318E - Balance](/contest/318/problem/E "Codeforces Round 188 (Div. 2)")
+
+In this problem we need to find 2*n*2 transfusions from initial configuration to the desired one. First of all we propose the following: if in each connected component overall volume of the water in initial configuration is the same as in desired one, then answer exist. We call the vessel *ready*, if current volume of its water equals desired one. Let us describe solution which is probably easier to code. We will make vessels ready one by one. Consider the pair of non-ready vessels s and t (there is more water in s than desired, and less water in t than desired), such that they are connected by the path P, and if one transfuses d litres from s to t then one of the vessels becomes ready. Now we need to find a way to transfuse d litres by path P from s to t. One may write recursive function pour(s, t, d) for this aim. Let t' stand before t in this path, then function works as follows: transfuses from t' to t as many water as possible (not more than d of course), then calls pour(s, t', d) and on the final step transfuses from t' to t all that left. It is easy to check that all such transfusions are correct. This algorithm makes 2*len* transfusions on the path of length *len*, so total number of transfusions is not greater than 2*n*2.
+
+[317D - Game with Powers](/contest/317/problem/D "Codeforces Round 188 (Div. 1)")
+
+For each numner *x* denote sequence of its powers within [1..*n*] as *Pow*(*x*): 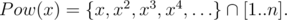
+
+Game proceeds as follows: on each step one player takes still available number *x* from 1 to *n* and prohibits whole set *Pow*(*x*). Who can't make his turn loses.
+
+This game may be decomposed in the sum of lesser games. Indeed, lets call number *x* *simple* (and corresponding sequence *Pow*(*x*) *simple*), if it is not a power of any number *y* < *x*. Then: 1. for each  there is simple *x*, such that ; 2. for each simple distinct *x* and *y* sets *Pow*(*x*) and *P*(*y*) do not intersect. Indeed, for a given *k* there is exactly one simple *x* such that *k* is power of *x*. This may be showed from fundamental theorem of arithmetic: if 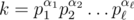 and *d* = *gcd*(α1, α2, ..., α*n*), then 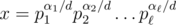.
+
+Hence set [1..*n*] decomposes into primitive sets *Pow*(*x*), on each of those *Pow*(*x*) game proceeds independetly. Now one may use Sprague–Grundy theory to see that mexx of our game is just xor of all mexx of games on simple *Pow*(*x*). For fixed *x*, if *Pow*(*x*) = {*x*, *x*2, ..., *x**s*}, then mexx of the game on *Pow*(*x*) depends only on *s*, but not on *x*. In our case *s* runs from 1 to 29, mexx for all such *s* may be directly precalculated. Now it is enough to find numbers *q*(*s*) of simple *x* with a given size of *Pow*(*x*) equal to *s* (actually we are interested in parity of *q*(*s*) not in *q*(*s*) itself).
+
+Our constraints allows to do it directly: run *x* from 2 to , if it is not crossed out, determine the size *Pow*(*x*) [increment corresponding *q*(*s*)], and cross out all numbers from *Pow*(*x*).
+
+This cycle finds all simple sequences of length at least 2. Quantity of non-crossed numbers is the number of all simple sequences of length 1. Now it is enough to look at parities of *q*(*s*) and xor coressponding mexx.
+
+However one may find all *q*(*s*) for . Indeed lets look at the number  and sequence {*x*, *x*2, *x*3, *x*4, ..., *x**s*}. This sequence is not simple iff it is containd in some larger simple sequence. But number of subsequenes of size *s* in a given sequence of size *t* > *s* is easy to find: it is just [*t* / *s*]. Recalling that simple sequences do not intersect one gets the reccurent formula:
+
+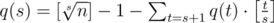.
+
+Now it is easy to find all *q*(*s*) from *q*(29) to *q*(1).
+
+*Remark:* while coding it is important to remeber simple number *x* = 1.
+
+[317E - Princess and Her Shadow](/contest/317/problem/E "Codeforces Round 188 (Div. 1)")
+
+In this problem princess Vlada should simply catch the Shadow. Here is the idea of a solution. If there is only one tree, then using it as a barrier to the shadow it is not hard to catch the shadow. Similar technique works if Vlada and Shadow are far from the square where all the trees grow. But what can she do in the dark depths of the forest? If there is no path at all between Vlada and Shadow, then there is no way to catch it. Otherwise consider a shortest path from Vlada to the Shadow and make Vlada follow it. This path gives Vlada a queue of the steps that she should perform. Additionaly if shadow moves, then we add her move to the queue (simply speaking Vlada follows the shadow). This is where the algorithmic part ends. Now we state that either Vlada catches the shadow in the desired number of steps, or steps out of the "forest square". To proof this we note that the length of the path between Vlada and Shadow may only decrease. And if it does not decrease long enough, then once in *k* steps (*k* is the length of the path) Vlada and Shadow shifts at the same vector over and over, and at some moment leaves the "forest square". Note that if the trees allow our heroes to step out of the "forest square" at the beginning, then we may just get them out from the start. But taking this approach we still need to catch the Shadow in a "labyrinth forest".
+
+Apologies for the delay. There are probably misprints and mistakes here (thousands of them!), please feel free to point them out.
diff --git a/editorials/319.md b/editorials/319.md
@@ -0,0 +1,97 @@
+Source: https://codeforces.com/blog/entry/8166
+
+## [320A - Magic Numbers](/contest/320/problem/A "Codeforces Round 189 (Div. 2)")
+
+Although the input number is very small, solving the problem for arbitrary length numbers using strings is easier. It's easy to prove that a number meeting the following conditions is magical:
+
+* The number should only consist of digits 1 and 4.
+* The number should begin with digit 1.
+* The number should not contain three consecutive fours (i.e. 444).
+
+Here is a sample implementation in C++:
+
+```
+#include <iostream>
+#include <string>
+
+using namespace std;
+
+bool is_magical(string number) {
+ for (int i = 0; i < (int)number.size(); i++)
+ if (number[i] != '1' && number[i] != '4')
+ return false;
+
+ if (number[0] == '4')
+ return false;
+
+ if (number.find("444") != number.npos)
+ return false;
+
+ return true;
+}
+
+int main() {
+ string number;
+ cin >> number;
+
+ if (is_magical(number))
+ cout << "YES" << endl;
+ else
+ cout << "NO" << endl;
+
+ return 0;
+}
+```
+
+## [320B - Ping-Pong (Easy Version)](/contest/320/problem/B "Codeforces Round 189 (Div. 2)")
+
+Imagine the intervals as nodes of a graph and draw directed edges between them as defined in the statement. Now answering the second query would be trivial if you are familiar with graph traversal algorithms like DFS or BFS or even Floyd-Warshall!
+
+Here's an implementation using DFS: [3951145](/contest/320/submission/3951145 "Submission 3951145 by jishen")
+
+And here's an implementation using BFS: [3947426](/contest/320/submission/3947426 "Submission 3947426 by sister_what_hate_most")
+
+Finally an implementation using Floyd-Warshall: [3945330](/contest/320/submission/3945330 "Submission 3945330 by toi333")
+
+## [319A - Malek Dance Club](/contest/319/problem/A "Codeforces Round 189 (Div. 1)")
+
+Solving this problem was easy when you modeled the assignment with two sets of points numbered from 0 to 2*n* - 1 (inclusive) paired with 2*n* line segments. Each line segment corresponds to a dance pair. And each pair of intersecting lines increase the complexity by one.
+
+Imagine you now the solution for binary string *x*. Now we want to calculate the answer for 1*x* and 0*x* easily. Look at the figure below:
+
+
+
+The figure shows what happens in a simple case. Whenever you append 0 before *x* the same structure appears twice in the result. But whenever you append 1 before *x* the same structure appears twice but the first half of points in right column are swapped with the second half. This increases the number of intersections by size of first half times size of the second half.
+
+So if *x* has length *n* and *f*(*x*) is the complexity of the assignment then we have:
+
+* *f*(0*x*) = 2*f*(*x*)
+* *f*(1*x*) = 2*f*(*x*) + 22*n*
+
+An interesting fact is that *f*(*x*) is equal to *x*2*n* - 1.
+
+## [319B - Psychos in a Line](/contest/319/problem/B "Codeforces Round 189 (Div. 1)")
+
+Will be fixed :)
+
+Let's find the murderer! Well, if you look close you see that each psycho is murdered by the nearest psycho on his left which has a greater id.
+
+Now let *t**i* be the number of the step which *i*-th psycho in the line is murdered (not the psycho with id equal to *i*). Assume *j*-th psycho in the line be the nearest psycho with a larger id than *i*-th psycho in the line in his left. As we know *j*-th psycho kills the *i*-th psycho. We also now that this happens when all psychos between *j* and *i* have been killed. So *t**i* = *max*(*t**j* + 1, ..., *t**i* - 1) + 1.
+
+Now we have a simple *O*(*n*2) solution using the above observations. To make things run faster you should be familiar with a classic problem. This problem asks to find the nearest greater element to the left of each element in a array. This problem has a *O*(*n*) solution. You can solve it yourself or read about it [here](http://stackoverflow.com/a/9495815).
+
+After knowing about all these things it wouldn't be hard to figure out a way to solve this problem efficiently. Here is a cute implementation of what is described above: [3945963](/contest/319/submission/3945963 "Submission 3945963 by pauldb")
+
+## [319C - Kalila and Dimna in the Logging Industry](/contest/319/problem/C "Codeforces Round 189 (Div. 1)")
+
+This problem is equal to finding the minimum cost to cut the last tree completely. Because any cutting operation can be done with no cost afterward. Let *dp**i* be the minimum cost to cut the *i*-th tree completely. It's easy to figure out that we can calculate *dp**i* if we know the index of the last tree which has been cut completely (*j*-th tree). Knowing this *dp**i* would be equal to *dp**j* + *b**j**a**i*. So *dp**i* = *min**j* = 1..*i* - 1(*dp**j* + *b**j**a**i*).
+
+Using the above information the problem has an easy dynamic programming solution in *O*(*n*2). There's a known method which can be used to improve recursive relations with similar form. It's called Convex Hull Trick. You can read about it [here](http://wcipeg.com/wiki/Convex_hull_trick).
+
+## [319D - Have You Ever Heard About the Word?](/contest/319/problem/D "Codeforces Round 189 (Div. 1)")
+
+TODO
+
+## [319E - Ping-Pong](/contest/319/problem/E "Codeforces Round 189 (Div. 1)")
+
+TODO
diff --git a/editorials/320.md b/editorials/320.md
@@ -0,0 +1,97 @@
+Source: https://codeforces.com/blog/entry/8166
+
+## [320A - Magic Numbers](/contest/320/problem/A "Codeforces Round 189 (Div. 2)")
+
+Although the input number is very small, solving the problem for arbitrary length numbers using strings is easier. It's easy to prove that a number meeting the following conditions is magical:
+
+* The number should only consist of digits 1 and 4.
+* The number should begin with digit 1.
+* The number should not contain three consecutive fours (i.e. 444).
+
+Here is a sample implementation in C++:
+
+```
+#include <iostream>
+#include <string>
+
+using namespace std;
+
+bool is_magical(string number) {
+ for (int i = 0; i < (int)number.size(); i++)
+ if (number[i] != '1' && number[i] != '4')
+ return false;
+
+ if (number[0] == '4')
+ return false;
+
+ if (number.find("444") != number.npos)
+ return false;
+
+ return true;
+}
+
+int main() {
+ string number;
+ cin >> number;
+
+ if (is_magical(number))
+ cout << "YES" << endl;
+ else
+ cout << "NO" << endl;
+
+ return 0;
+}
+```
+
+## [320B - Ping-Pong (Easy Version)](/contest/320/problem/B "Codeforces Round 189 (Div. 2)")
+
+Imagine the intervals as nodes of a graph and draw directed edges between them as defined in the statement. Now answering the second query would be trivial if you are familiar with graph traversal algorithms like DFS or BFS or even Floyd-Warshall!
+
+Here's an implementation using DFS: [3951145](/contest/320/submission/3951145 "Submission 3951145 by jishen")
+
+And here's an implementation using BFS: [3947426](/contest/320/submission/3947426 "Submission 3947426 by sister_what_hate_most")
+
+Finally an implementation using Floyd-Warshall: [3945330](/contest/320/submission/3945330 "Submission 3945330 by toi333")
+
+## [319A - Malek Dance Club](/contest/319/problem/A "Codeforces Round 189 (Div. 1)")
+
+Solving this problem was easy when you modeled the assignment with two sets of points numbered from 0 to 2*n* - 1 (inclusive) paired with 2*n* line segments. Each line segment corresponds to a dance pair. And each pair of intersecting lines increase the complexity by one.
+
+Imagine you now the solution for binary string *x*. Now we want to calculate the answer for 1*x* and 0*x* easily. Look at the figure below:
+
+
+
+The figure shows what happens in a simple case. Whenever you append 0 before *x* the same structure appears twice in the result. But whenever you append 1 before *x* the same structure appears twice but the first half of points in right column are swapped with the second half. This increases the number of intersections by size of first half times size of the second half.
+
+So if *x* has length *n* and *f*(*x*) is the complexity of the assignment then we have:
+
+* *f*(0*x*) = 2*f*(*x*)
+* *f*(1*x*) = 2*f*(*x*) + 22*n*
+
+An interesting fact is that *f*(*x*) is equal to *x*2*n* - 1.
+
+## [319B - Psychos in a Line](/contest/319/problem/B "Codeforces Round 189 (Div. 1)")
+
+Will be fixed :)
+
+Let's find the murderer! Well, if you look close you see that each psycho is murdered by the nearest psycho on his left which has a greater id.
+
+Now let *t**i* be the number of the step which *i*-th psycho in the line is murdered (not the psycho with id equal to *i*). Assume *j*-th psycho in the line be the nearest psycho with a larger id than *i*-th psycho in the line in his left. As we know *j*-th psycho kills the *i*-th psycho. We also now that this happens when all psychos between *j* and *i* have been killed. So *t**i* = *max*(*t**j* + 1, ..., *t**i* - 1) + 1.
+
+Now we have a simple *O*(*n*2) solution using the above observations. To make things run faster you should be familiar with a classic problem. This problem asks to find the nearest greater element to the left of each element in a array. This problem has a *O*(*n*) solution. You can solve it yourself or read about it [here](http://stackoverflow.com/a/9495815).
+
+After knowing about all these things it wouldn't be hard to figure out a way to solve this problem efficiently. Here is a cute implementation of what is described above: [3945963](/contest/319/submission/3945963 "Submission 3945963 by pauldb")
+
+## [319C - Kalila and Dimna in the Logging Industry](/contest/319/problem/C "Codeforces Round 189 (Div. 1)")
+
+This problem is equal to finding the minimum cost to cut the last tree completely. Because any cutting operation can be done with no cost afterward. Let *dp**i* be the minimum cost to cut the *i*-th tree completely. It's easy to figure out that we can calculate *dp**i* if we know the index of the last tree which has been cut completely (*j*-th tree). Knowing this *dp**i* would be equal to *dp**j* + *b**j**a**i*. So *dp**i* = *min**j* = 1..*i* - 1(*dp**j* + *b**j**a**i*).
+
+Using the above information the problem has an easy dynamic programming solution in *O*(*n*2). There's a known method which can be used to improve recursive relations with similar form. It's called Convex Hull Trick. You can read about it [here](http://wcipeg.com/wiki/Convex_hull_trick).
+
+## [319D - Have You Ever Heard About the Word?](/contest/319/problem/D "Codeforces Round 189 (Div. 1)")
+
+TODO
+
+## [319E - Ping-Pong](/contest/319/problem/E "Codeforces Round 189 (Div. 1)")
+
+TODO
diff --git a/editorials/321.md b/editorials/321.md
@@ -0,0 +1,190 @@
+Source: https://codeforces.com/blog/entry/8192
+
+**Update 1** Added links to my code.
+
+**Update 2** The links to my code seems not work, so I push my codes on github, and you find all of them here: <https://github.com/cgy4ever/cf190>
+
+**Update 3** Fixed my solution of Div1-C (Div2-E). In this problem, we must find [centroid of tree](http://acm.sgu.ru/problem.php?contest=0&problem=134) instead of [center of tree](http://stackoverflow.com/questions/4020122/finding-center-of-the-tree). Thanks [RomaWhite](/profile/RomaWhite "Master RomaWhite") for pointing this out and provide test case. And it seems that many solutions can pass the system test will fail on his test case (including my model solution). I feel apologetic for the weak test cases and wrong solution.
+
+**Update 4** Reformat the passage, I hope it would looks better.
+
+[322A - Ciel and Dancing](/contest/322/problem/A "Codeforces Round 190 (Div. 2)")
+
+Let's define remainNew = # of people haven't danced before. So at beginning remainNew = n+m, and we have:
+
+* During the 1st song, remainNew must decreased by at least 2. (Because the boy and girl must haven't danced before.)
+* During the k-th (k>1) song, remainNew must decreased by at least 1. (Because one of the boy or girl must haven't danced before.) So the answer must be no more than n+m-1.
+
+And it's not hard to construct one schedule get this maximal possible answer:
+
+```
+1 1
+1 2
+...
+1 m
+2 1
+3 1
+...
+n 1
+```
+
+[322B - Ciel and Flowers](/contest/322/problem/B "Codeforces Round 190 (Div. 2)")
+
+If there are no "mixing bouquet" then the answer will be r/3 + g/3 + b/3. One important observation is that: There always exist an optimal solution with less than 3 mixing bouquet.
+
+The proof is here: Once we get 3 mixing bouquet, we can change it to (1 red bouquet + 1 green bouquet + 1 blue bouquet)
+
+So we can try 0, 1, 2 mixing bouquet and make the remain 3 kind of bouquets use above greedy method. Output one with largest outcome.
+
+[322C - Ciel and Robot](/contest/322/problem/C "Codeforces Round 190 (Div. 2)") [321A - Ciel and Robot](/contest/321/problem/A "Codeforces Round 190 (Div. 1)")
+
+Note that after Ciel execute string s, it will moves (dx, dy). And for each repeat, it will alway moves (dx, dy). So the total movement will be k * (dx, dy) + (dx[p], dy[p]) which (dx[p], dy[p]) denotes the movement after execute first p characters. We can enumerate p since (0 <= p < |s| <= 100), and check if there are such k exists.
+
+Note that there are some tricks:
+
+* We can divide dx or dy directly because they both can become zero.
+* Another trick is that k must be non-negative.
+
+Many people failed on this test case (which no included in the pretest):
+
+```
+-1 -1
+UR
+```
+
+[322D - Ciel and Duel](/contest/322/problem/D "Codeforces Round 190 (Div. 2)") [321B - Ciel and Duel](/contest/321/problem/B "Codeforces Round 190 (Div. 1)")
+
+We have 3 solutions to this problem:
+
+= 1. greedy =
+
+There are 2 cases: we killed all Jiro's cards, or not.
+
+If we are not killed all of Jiro's cards, then:
+
+1. 1. We never attack his DEF cards, it's meaningless.
+2. Suppose we make k attacks, then it must be: use Ciel's k cards with highest strength to attack Jiro's k cards with lowest strength, and we can sort the both k cards by strength to make attack one by one. (If there are an invalid attack, then we can't have k attack)
+
+If we kill all Jiro's card: Then for all DEF cards, we consider it from lower strength to higher: if its strength is L, then we find a card of Ciel with strength more than L (If there are many, we choose one with lowest strength). Then we can know if we can kill all DEF cards. And then we choose |x| cards with highest strength of Ciel, try to kill Jiro's remain card.
+
+Note that if we could kill all ATK cards, the order doesn't matter: the total damage will be (sum of strength of Ciel's remain card) — (sum of strength of Jiro's remain card).
+
+= 2. DP =
+
+Above solution looks complicated, can we solve it with few observation? Yes we can. The only observation is that:
+
+There always exist an optimal solution that: If Ciel's two card X's strength > Y's strength, and X, Y attacks on A and B with the same position, then A's strength > B's strength. We already use this observation in above solution.
+
+Then what can we do? Yes, we can sort all Ciel's card, all ATK card of Jiro, all DEF card of Jiro.
+
+Let's DP[pCiel][pATK][pJiro][killAll] be the state that next unconsidered card of Ciel, Jiro's ATk, Jiro's DEF are pCiel, pATK, pJiro, and killAll=1 if and only if we assume at the end we can kill all Jiro's card.
+
+Then we have 4 choice:
+
+1. Skip, this card don't attack.
+2. Attack on the next ATK card.
+3. Attack on the next DEF card.
+4. Assume Jiro has no cards and make a direct attack.
+
+= 3. MinCostMaxFlow =
+
+Well, what if we want to solve this problem with no observation?
+
+Ok, if you are good at construct flow algorithm, it's an easy thing to solve this by flow.
+
+Please see my solution for details. It just considered the matching relationship.
+
+[322E - Ciel the Commander](/contest/322/problem/E "Codeforces Round 190 (Div. 2)") [321C - Ciel the Commander](/contest/321/problem/C "Codeforces Round 190 (Div. 1)")
+
+This is a problem with construction on trees. And for these kind of problems, we usually use two method: up-down or down-up. So we have 1 solution for each method:
+
+= 1. up-down construction =
+
+Suppose we assign an officer with rank A at node x. Then for two distinct subtree rooted by x, says T1 and T2: There can't be any invalid path cross T1 and T2, because it is blocked by node x. (It's clear that we can't make 2 rank A officer.)
+
+So we can solve these subtree independently: the only different is that we can't use rank A anymore.
+
+Then the question is: which node should x be? It could be good if any subtree will has a small size. And if you have the knowledge of "centroid of tree", then you can quickly find that if x be the centroid of this tree, the subtree's size will be no more than half of the original tree. So we only needs about log2(n) nodes and 26 is enough.
+
+= 2. down-up construction =
+
+The above solution involves the concept of "centroid of tree" but you might not heard about that, don't worry, we have another solution can solve this problem without knowing that, and it's easier to implement.
+
+Suppose we choose 1 as the root and consider it as a directed tree, and on some day we have the following problem:
+
+We have some subtree rooted at T1, T2, ..., Tk, and they are already assigned an officer, we need to assign an officer to node x and link them to this node. Well, a normal idea is: we choose one with lowest possible rank.
+
+The rank of x should satisfy:
+
+1. If there are a node with rank t exposes at Ti and a node with t exposes at Tj (i!=j), then rank of x must be higher than t. (Otherwise the path between them will be invalid.)
+2. If there are a node with rank t exposes at Ti, then the rank of x can't be t.
+
+So we can use this rule to choose the lowest possible rank. But can it passes? Yes, it can, but the proof is not such easy, I'll introduce the main idea here:
+
+* We assign each node a potential: p(x) = {2^('Z' — w) | w is exposed}. For example, if 'Y' and 'Z' are exposed, then p(x) = 1 + 2 = 3.
+* We can proof p(x) <= |# of nodes of the subtree rooted by x| by proof this lemma: When we synthesis x with T1, T2, ..., Tk, p(x) <= 1 + p(T1) + ... + p(Tk). It's not hard to proof, but might have some cases to deal with.
+
+[321D - Ciel and Flipboard](/contest/321/problem/D "Codeforces Round 190 (Div. 1)")
+
+For this problem we need a big "observation": what setup of "flips" are valid? What means set up of "flips", well, for example, after the 1st step operation of example 1, we get:
+
+```
+1 1 0
+1 1 0
+0 0 0
+```
+
+It means the left top 2x2 cells are negatived.
+
+Given a 0-1 matrix of a set up of "flips", how can you determine if we can get it by some N x N (I use N instead of x here, it don't make sense to write something like x x x.) flips.
+
+To solve this problem, we need the following observation:
+
+1. For any i, any j<=x: setUp[i][j]^setUp[i][x]^setUp[i][j+x] will be 0.
+2. For any i, any j<=x: setUp[j][i]^setUp[x][i]^setUp[j+x][i] will be 0.
+
+It's quite easy to proof than find that: after each operation, there always be 0 or 2 cells lay in {setUp[i][j], setUp[i][x], setUp[i][j+x]} or {setUp[j][i], setUp[x][i], setUp[j+x][i]}.
+
+So what? Well, then there must be no more than 2^(N*N) solutions, since if we determine the left top N x N cells, we can determine others by above equations.
+
+And then? Magically we can proof if one set up meets all above equations, we can get it. And the proof only needs one line: think the operation as addition of vectors in GF2, then we have N*N independent vector, so there must be 2^(N*N) different setups we can get. (Yes, I admit it need some knowledge, or feeling in linear algebra)
+
+Then the things are easy: we enumerate {setUp[1][N], setUp[2][N], ..., setUp[N][N]}, and determine others by greedy. (More detailed, by columns.)
+
+You can find details in my code.
+
+[321E - Ciel and Gondolas](/contest/321/problem/E "Codeforces Round 190 (Div. 1)")
+
+This problem may jog your memory of OI times (if you have been an OIer and now grows up, like me). Maybe some Chinese contestants might think this problem doesn't worth 2500, but DP optimization is an advanced topic in programming contest for many regions. It's quite easy to find an O(N^2 K) DP:
+
+* dp[i][j] = max{ k | dp[i-1][k] + cost(k+1...j)}
+
+(dp[i][j] means the minimal cost if we divide 1...j foxes into i groups)
+
+There are many ways to optimize this kind of dp equation, but a large part of them based one the property of cost function. So we need to find some property independent of cost function.
+
+Let opt[i][j] = the smallest k such that dp[i][j] = dp[i][k] + cost(k+1...j) Then intuitively we have opt[i][1] <= opt[i][2] <= ... <= opt[i][n]. (I admit some people don't think it's intuitively correct, but it can proof by some high school algebra)
+
+Then how to use this stuff?
+
+Let n = 200 and suppose we already get dp[i][j] for i<=3 and now we have to compute dp[4][j]: If we first compute dp[4][100], then we can have opt[4][100] at the same time.
+
+And when we compute dp[4][1] ... dp[4][99], we know that the k must lay in 1...opt[4][100]. When we compute dp[4][101] ... dp[4][200], we know that k must lay in opt[4][100]...n.
+
+Let's formalize this thing: We use compute(d, L, R, optL, optR) to denote we are computing dp[d][L...R], and we know the k must be in range optL...optR.
+
+Then we have:
+
+```
+compute(d, L, R, optL, optR) =
+
+ 1. special case: L==R.
+
+ 2. let M = (L+R) / 2, we solve dp[d][M] as well as opt[d][M]. Uses about (optR-optL+1) operations.
+
+ 3. compute(d, L, M-1, optL, opt[d][M])
+
+ 4. compute(d, M+1, R, opt[d][M], optR)
+```
+
+One can show that this solution will run in O(NlogN * K). Note that we don't need opt[d][M] at the center of interval optL...optR. We can proof at each recursive depth, the total cost by line 2 will be no more than 2n. And there are at most O(log(n)) depths.
diff --git a/editorials/322.md b/editorials/322.md
@@ -0,0 +1,190 @@
+Source: https://codeforces.com/blog/entry/8192
+
+**Update 1** Added links to my code.
+
+**Update 2** The links to my code seems not work, so I push my codes on github, and you find all of them here: <https://github.com/cgy4ever/cf190>
+
+**Update 3** Fixed my solution of Div1-C (Div2-E). In this problem, we must find [centroid of tree](http://acm.sgu.ru/problem.php?contest=0&problem=134) instead of [center of tree](http://stackoverflow.com/questions/4020122/finding-center-of-the-tree). Thanks [RomaWhite](/profile/RomaWhite "Master RomaWhite") for pointing this out and provide test case. And it seems that many solutions can pass the system test will fail on his test case (including my model solution). I feel apologetic for the weak test cases and wrong solution.
+
+**Update 4** Reformat the passage, I hope it would looks better.
+
+[322A - Ciel and Dancing](/contest/322/problem/A "Codeforces Round 190 (Div. 2)")
+
+Let's define remainNew = # of people haven't danced before. So at beginning remainNew = n+m, and we have:
+
+* During the 1st song, remainNew must decreased by at least 2. (Because the boy and girl must haven't danced before.)
+* During the k-th (k>1) song, remainNew must decreased by at least 1. (Because one of the boy or girl must haven't danced before.) So the answer must be no more than n+m-1.
+
+And it's not hard to construct one schedule get this maximal possible answer:
+
+```
+1 1
+1 2
+...
+1 m
+2 1
+3 1
+...
+n 1
+```
+
+[322B - Ciel and Flowers](/contest/322/problem/B "Codeforces Round 190 (Div. 2)")
+
+If there are no "mixing bouquet" then the answer will be r/3 + g/3 + b/3. One important observation is that: There always exist an optimal solution with less than 3 mixing bouquet.
+
+The proof is here: Once we get 3 mixing bouquet, we can change it to (1 red bouquet + 1 green bouquet + 1 blue bouquet)
+
+So we can try 0, 1, 2 mixing bouquet and make the remain 3 kind of bouquets use above greedy method. Output one with largest outcome.
+
+[322C - Ciel and Robot](/contest/322/problem/C "Codeforces Round 190 (Div. 2)") [321A - Ciel and Robot](/contest/321/problem/A "Codeforces Round 190 (Div. 1)")
+
+Note that after Ciel execute string s, it will moves (dx, dy). And for each repeat, it will alway moves (dx, dy). So the total movement will be k * (dx, dy) + (dx[p], dy[p]) which (dx[p], dy[p]) denotes the movement after execute first p characters. We can enumerate p since (0 <= p < |s| <= 100), and check if there are such k exists.
+
+Note that there are some tricks:
+
+* We can divide dx or dy directly because they both can become zero.
+* Another trick is that k must be non-negative.
+
+Many people failed on this test case (which no included in the pretest):
+
+```
+-1 -1
+UR
+```
+
+[322D - Ciel and Duel](/contest/322/problem/D "Codeforces Round 190 (Div. 2)") [321B - Ciel and Duel](/contest/321/problem/B "Codeforces Round 190 (Div. 1)")
+
+We have 3 solutions to this problem:
+
+= 1. greedy =
+
+There are 2 cases: we killed all Jiro's cards, or not.
+
+If we are not killed all of Jiro's cards, then:
+
+1. 1. We never attack his DEF cards, it's meaningless.
+2. Suppose we make k attacks, then it must be: use Ciel's k cards with highest strength to attack Jiro's k cards with lowest strength, and we can sort the both k cards by strength to make attack one by one. (If there are an invalid attack, then we can't have k attack)
+
+If we kill all Jiro's card: Then for all DEF cards, we consider it from lower strength to higher: if its strength is L, then we find a card of Ciel with strength more than L (If there are many, we choose one with lowest strength). Then we can know if we can kill all DEF cards. And then we choose |x| cards with highest strength of Ciel, try to kill Jiro's remain card.
+
+Note that if we could kill all ATK cards, the order doesn't matter: the total damage will be (sum of strength of Ciel's remain card) — (sum of strength of Jiro's remain card).
+
+= 2. DP =
+
+Above solution looks complicated, can we solve it with few observation? Yes we can. The only observation is that:
+
+There always exist an optimal solution that: If Ciel's two card X's strength > Y's strength, and X, Y attacks on A and B with the same position, then A's strength > B's strength. We already use this observation in above solution.
+
+Then what can we do? Yes, we can sort all Ciel's card, all ATK card of Jiro, all DEF card of Jiro.
+
+Let's DP[pCiel][pATK][pJiro][killAll] be the state that next unconsidered card of Ciel, Jiro's ATk, Jiro's DEF are pCiel, pATK, pJiro, and killAll=1 if and only if we assume at the end we can kill all Jiro's card.
+
+Then we have 4 choice:
+
+1. Skip, this card don't attack.
+2. Attack on the next ATK card.
+3. Attack on the next DEF card.
+4. Assume Jiro has no cards and make a direct attack.
+
+= 3. MinCostMaxFlow =
+
+Well, what if we want to solve this problem with no observation?
+
+Ok, if you are good at construct flow algorithm, it's an easy thing to solve this by flow.
+
+Please see my solution for details. It just considered the matching relationship.
+
+[322E - Ciel the Commander](/contest/322/problem/E "Codeforces Round 190 (Div. 2)") [321C - Ciel the Commander](/contest/321/problem/C "Codeforces Round 190 (Div. 1)")
+
+This is a problem with construction on trees. And for these kind of problems, we usually use two method: up-down or down-up. So we have 1 solution for each method:
+
+= 1. up-down construction =
+
+Suppose we assign an officer with rank A at node x. Then for two distinct subtree rooted by x, says T1 and T2: There can't be any invalid path cross T1 and T2, because it is blocked by node x. (It's clear that we can't make 2 rank A officer.)
+
+So we can solve these subtree independently: the only different is that we can't use rank A anymore.
+
+Then the question is: which node should x be? It could be good if any subtree will has a small size. And if you have the knowledge of "centroid of tree", then you can quickly find that if x be the centroid of this tree, the subtree's size will be no more than half of the original tree. So we only needs about log2(n) nodes and 26 is enough.
+
+= 2. down-up construction =
+
+The above solution involves the concept of "centroid of tree" but you might not heard about that, don't worry, we have another solution can solve this problem without knowing that, and it's easier to implement.
+
+Suppose we choose 1 as the root and consider it as a directed tree, and on some day we have the following problem:
+
+We have some subtree rooted at T1, T2, ..., Tk, and they are already assigned an officer, we need to assign an officer to node x and link them to this node. Well, a normal idea is: we choose one with lowest possible rank.
+
+The rank of x should satisfy:
+
+1. If there are a node with rank t exposes at Ti and a node with t exposes at Tj (i!=j), then rank of x must be higher than t. (Otherwise the path between them will be invalid.)
+2. If there are a node with rank t exposes at Ti, then the rank of x can't be t.
+
+So we can use this rule to choose the lowest possible rank. But can it passes? Yes, it can, but the proof is not such easy, I'll introduce the main idea here:
+
+* We assign each node a potential: p(x) = {2^('Z' — w) | w is exposed}. For example, if 'Y' and 'Z' are exposed, then p(x) = 1 + 2 = 3.
+* We can proof p(x) <= |# of nodes of the subtree rooted by x| by proof this lemma: When we synthesis x with T1, T2, ..., Tk, p(x) <= 1 + p(T1) + ... + p(Tk). It's not hard to proof, but might have some cases to deal with.
+
+[321D - Ciel and Flipboard](/contest/321/problem/D "Codeforces Round 190 (Div. 1)")
+
+For this problem we need a big "observation": what setup of "flips" are valid? What means set up of "flips", well, for example, after the 1st step operation of example 1, we get:
+
+```
+1 1 0
+1 1 0
+0 0 0
+```
+
+It means the left top 2x2 cells are negatived.
+
+Given a 0-1 matrix of a set up of "flips", how can you determine if we can get it by some N x N (I use N instead of x here, it don't make sense to write something like x x x.) flips.
+
+To solve this problem, we need the following observation:
+
+1. For any i, any j<=x: setUp[i][j]^setUp[i][x]^setUp[i][j+x] will be 0.
+2. For any i, any j<=x: setUp[j][i]^setUp[x][i]^setUp[j+x][i] will be 0.
+
+It's quite easy to proof than find that: after each operation, there always be 0 or 2 cells lay in {setUp[i][j], setUp[i][x], setUp[i][j+x]} or {setUp[j][i], setUp[x][i], setUp[j+x][i]}.
+
+So what? Well, then there must be no more than 2^(N*N) solutions, since if we determine the left top N x N cells, we can determine others by above equations.
+
+And then? Magically we can proof if one set up meets all above equations, we can get it. And the proof only needs one line: think the operation as addition of vectors in GF2, then we have N*N independent vector, so there must be 2^(N*N) different setups we can get. (Yes, I admit it need some knowledge, or feeling in linear algebra)
+
+Then the things are easy: we enumerate {setUp[1][N], setUp[2][N], ..., setUp[N][N]}, and determine others by greedy. (More detailed, by columns.)
+
+You can find details in my code.
+
+[321E - Ciel and Gondolas](/contest/321/problem/E "Codeforces Round 190 (Div. 1)")
+
+This problem may jog your memory of OI times (if you have been an OIer and now grows up, like me). Maybe some Chinese contestants might think this problem doesn't worth 2500, but DP optimization is an advanced topic in programming contest for many regions. It's quite easy to find an O(N^2 K) DP:
+
+* dp[i][j] = max{ k | dp[i-1][k] + cost(k+1...j)}
+
+(dp[i][j] means the minimal cost if we divide 1...j foxes into i groups)
+
+There are many ways to optimize this kind of dp equation, but a large part of them based one the property of cost function. So we need to find some property independent of cost function.
+
+Let opt[i][j] = the smallest k such that dp[i][j] = dp[i][k] + cost(k+1...j) Then intuitively we have opt[i][1] <= opt[i][2] <= ... <= opt[i][n]. (I admit some people don't think it's intuitively correct, but it can proof by some high school algebra)
+
+Then how to use this stuff?
+
+Let n = 200 and suppose we already get dp[i][j] for i<=3 and now we have to compute dp[4][j]: If we first compute dp[4][100], then we can have opt[4][100] at the same time.
+
+And when we compute dp[4][1] ... dp[4][99], we know that the k must lay in 1...opt[4][100]. When we compute dp[4][101] ... dp[4][200], we know that k must lay in opt[4][100]...n.
+
+Let's formalize this thing: We use compute(d, L, R, optL, optR) to denote we are computing dp[d][L...R], and we know the k must be in range optL...optR.
+
+Then we have:
+
+```
+compute(d, L, R, optL, optR) =
+
+ 1. special case: L==R.
+
+ 2. let M = (L+R) / 2, we solve dp[d][M] as well as opt[d][M]. Uses about (optR-optL+1) operations.
+
+ 3. compute(d, L, M-1, optL, opt[d][M])
+
+ 4. compute(d, M+1, R, opt[d][M], optR)
+```
+
+One can show that this solution will run in O(NlogN * K). Note that we don't need opt[d][M] at the center of interval optL...optR. We can proof at each recursive depth, the total cost by line 2 will be no more than 2n. And there are at most O(log(n)) depths.
diff --git a/editorials/325.md b/editorials/325.md
@@ -0,0 +1,139 @@
+Source: https://codeforces.com/blog/entry/8353
+
+**[Square and Rectangles](//codeforces.com/problemset/problem/325/A)**
+
+Author: [AlexSkidanov](/profile/AlexSkidanov "Master AlexSkidanov")
+
+What happens if the rectangles form an *N* × *N* square? Then these two conditions are necessary.
+
+1) The area must be exactly *N* × *N*.
+
+2) The length of its sides must be *N*. That means, the difference between the right side of the rightmost rectangle — the left side of the leftmost rectangle is *N*. Same for topmost and bottommost rectangles.
+
+We claim that, since the rectangles do not intersect, those two conditions are also sufficient.
+
+This is since if there are only *N* × *N* space inside the box bounded by the leftmost, rightmost, topmost, and bottommost rectangles.
+
+Thus if the sum of the area is exactly *N* × *N*, all space must be filled -- which forms a square.
+
+**[Stadium and Games](//codeforces.com/problemset/problem/325/B)**
+
+Author: nika
+
+Suppose the "divide-by-two" stage happens exactly *D* times, and the round robin happens with *M* people.
+
+Then, the number of games held is: 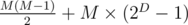
+
+We would like that 
+
+This is an equation with two variables -- to solve it, we can enumerate the value of one of the variables and calculate the value of the other one. We cannot enumerate the possible values of *M*, since *M* can vary from 1 to 10^9. However, we can enumerate D, since the number scales exponentially with *D* -- that is, we should only enumerate 0 ≤ *D* ≤ 62.
+
+Thus, the equation is reduced to 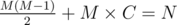
+
+Since this function is increasing, this can be solved via binary search on M.
+
+**[Monsters and Diamonds](//codeforces.com/problemset/problem/325/C)**
+
+Author: [AlexSkidanov](/profile/AlexSkidanov "Master AlexSkidanov")
+
+First part of the problem is to find minimum number of diamonds one can achieve by starting with a given monster. To do so, we will be using Dijkstra algorithm. Originally we don't know the minimum for any monster. For every rule we will maintain how many monsters with unknown minimums it has (let's call it *k**i* for the *i*-th rule). Let's take every rule that has only diamonds in it (i.e. which has *k**i* = 0), and assign number of diamonds in that rule as a tentative minimum for the monster (if a monster has several diamonds-only rules, take the smallest one). Then take the monster, that has the smallest tentative minimum currently assigned. For that monster the tentative value is the actual minimum due to the same reasoning we use when we prove correctness of Dijkstra algorithm. Now, since we know the minimum for that monster, for every rule *i* that has that monster in its result subtract 1 from *k**i* for every occurrence of the monster in the result of that rule. If for any rule the value of *k**i* becomes zero, update the tentative minimum for the monster that rule belongs to with the sum of minimum values for each monster that rule generates plus the number of diamonds that rule generates. Then from all the monsters for which we don't known the minimum yet, but for which we know the tentative minimum, pick the one with the smallest tentative minimum, and continue on.
+
+At the end we will end up in a state, when each monster either has an actual minimum value assigned, or has no tentative value assigned. The latter monsters will have - 1 - 1 as their answer. For the former monsters we know the minimum, but don't know the maximum yet.
+
+The second part of the problem is to find all the rules, after applying which we are guaranteed to never get rid of all the monsters. We will call such a rule bad. It is easy to show, that the rule bad if and only if it generates at least one monster with minimum value of -1. Remove all the bad rules from the set of rules.
+
+When bad rules are removed, finding maximums is trivial. Starting from every node for which maximum is not assigned yet, we traverse all the monsters in a DFS order. For a given monster, we consider every rule. For a given rule, for each monster it generates, we call DFS to find its maximum value, and then sum them up, add number of diamonds for the rule, and check if this rule gives bigger max value than the one currently known for the monster. If we ever call DFS for a monster, for which we already have a DFS call on the stack, that means that that monster has some way of producing itself (directly or indirectly) and some non-zero number of diamonds (this is why problem statement has a constraint that every rule generates at least one diamond), so the answer for the monster is -2. If, processing any rule, we encounter a monster with max value -2, we immediately assign -2 as a max value for the monster the rule belongs to and return from the DFS.
+
+As an exercise, think of a solution for the same problem, if rules are not guarantee to have at least one diamond in them.
+
+**[Reclamation](//codeforces.com/problemset/problem/325/D)**
+
+Author: [dolphinigle](/profile/dolphinigle "International Master dolphinigle")
+
+Assume there's an extra sea cells on a row above the topmost row, and a row below the bottom most row. Hence, we can assume that the top and bottom row consists entirely of sea.
+
+We claim that: There does not exist a sea route if and only if there exists a sequence of land cells that circumfere the planet (2 cells are adjacent if they share at least one point).
+
+The "sufficient" part of the proof is easy -- since there exists such a sequence, it separates the sea into the northern and southern hemisphere and this forms a barrier disallowing passage between the two.
+
+The "necessary" part. Suppose there does not exist such route. Then, if you perform a flood fill from any of the sea cell in the top row, you obtain a set of sea cells.
+
+Trace the southern boundary of these set of cells, and you obtain the sequence of land circumfering the planet.
+
+Thus, the algorithm works by simulating the reclamations one by one. Each time a land is going to be reclamated, we check if it would create a circumefering sequence. We will show that there's a way to do this check very quickly -- thus the algorithm should work within the time limit.
+
+Stick two copies of the grid together side-by-side, forming a Rx(2*C) grid. The leftmost and rightmost cells of any row in this new grid are also adjacent, similar to the given grid.
+
+Each time we're going to reclamate a land in row r and column c, we check if by doing so we would create a path going from (r, c) to (r, c + C). If it would, then we cancel the reclamation. Otherwise, we perform it, and add a land in cell (r, c) and (r, c+C).
+
+This "is there a path from node X to node Y" queries can be answered very very quickly using union find -- we check whether is it possible to go from one of the 8 neighbors of (r, c) to one of the 8 neighbors of (r, c+C).
+
+Correctness follows from the following: There exists a circumefering sequence IFF there exists a path from (r, c) to (r, c+C). Sufficient is easy. Suppose there exist a path from (r, c) to (r, c+C). We can form our circumfering sequence by overlapping the path from (r, c) to (r, c+C) with the same path, but going from (r, c+C) to (r, c) (we can do this since the grid is a two copies of the same grid sticked together).
+
+Necessary. Suppose there exists a circumfering sequence. We claim that there must exist a path to go from (r, c) to (r, c+C). Consider the concatenation of an infinite number of our initial grid, forming an Rx(infinite * C) grid. If there exists a circumfering sequence, we claim that within this grid, there exists a path from (r, c) to (r, c+C).
+
+Suppose there does not exist such a path. Since there exists a circumfering sequence, it must be possible to go from (r, c) to (r, c+ t * C), where t is an integer >= 2. Now, you should overlap all the paths taken to go from (r, c) to (r, c+t*C) in the grid (r', c' + C) (the grid immediately to the right of the grid where (r, c) is located). There must be a path from (r, c) to (r, c+C) in this new overlapped path.
+
+Proofing the final part is difficult without interactive illustration -- basically since t >= 2, there exists a path that goes from the left side to the right side of the grid (r', c' + C). This path must intersect with one of the overlapping paths, and that path must be connected to (r, c+C). The details are left as... exercise :p.
+
+**[The Red Button](//codeforces.com/problemset/problem/325/E)**
+
+Author: nika
+
+In this part of editorial, all numbers we speak are in modulo *N*. So, if I say 10, it actually means 10 modulo *N*.
+
+First, observe that this problem asks us to find a cycle that visits each node exactly once, i.e., a hamiltonian cycle. Thus, for each node *X*, there exists one other node that we used to go to node *X*, and one node that we visit after node *X*. We call them bef(X) and aft(X) (shorthand for before and after).
+
+First we will show that if *N* is odd, then the answer is - 1.
+
+Proof...? Consider node 0. What nodes points to node 0? Such node *H* must satisfy either of the following conditions:
+
+2*H* = 0
+
+2*H* + 1 = 0
+
+The first condition is satisfied only by *H* = 0. The second condition is satisfied only by one value of *H*: *floor*(*N* / 2).
+
+So, since we need a hamiltonian cycle, pre[0] must be floor(N/2), and aft[floor(N/2)] = 0
+
+Now, consider node *N* - 1. What nodes points to node *N* - 1?
+
+2*H* = *N* - 1
+
+2*H* + 1 = *N* - 1
+
+The second condition is satisfied only by *H* = *N* - 1. The first condition is satisfied only by *H* = *floor*(*N* / 2)
+
+But we need a hamiltonian cycle, so aft[floor(N/2)] must be *N* - 1. This is a contradiction with that aft[floor(N/2)] must be 0.
+
+Now, *N* is even. This case is much more interesting.
+
+Consider a node *X*. It is connected to 2*X* and 2*X* + 1. Consider the node *X* + *N* / 2. It is connected to 2*X* + *N* and 2*X* + 1 + *N*, which reduces to 2*X* and 2*X* + 1.
+
+So, apparently node *X* and node *X* + *N* / 2 are connected to the same set of values.
+
+Now, notice that each node *X* will have exactly two nodes pointing to it. This is since such node *H* must satisfy
+
+2*H* = *X*
+
+2*H* + 1 = *X*
+
+modulo *N*, each of those two equations have exactly one solution.
+
+So, this combined with that node *X* and *X* + *N* / 2 have the same set of connected nodes means that the only way to go to node 2*X* or 2*X* + 1 is from nodes *X* and *X* + *N* / 2.
+
+Thus, if you choose to go from node *X* to node 2*X*, you HAVE to go from node *X* + *N* / 2 to node 2*X* + 1 (or vice versa).
+
+Now, try to follow the rule above and generate any such configuration. This configuration will consists of cycles, possibly more than 1. Can we join them into a single large cycle, visiting all nodes?
+
+Yes we can, since those cycles are special.
+
+Weird theorem: If there are 2 + cycles, then there must exist *X* and such node *X* and node *X* + *N* / 2 are in different cycles.
+
+Proof: Suppose not. We show that there must exist one cycle in that case. Since node *X* and *X* + *N* / 2 are in the same cycle, they must also be in the same cycle as node 2*X* and 2*X* + 1. In particular, node *X* and 2*X* and 2*X* + 1 are all in the same cycle. It is possible to go from any node *X* to any node *Y* by following this pattern (left as exercise). Now, consider the *X* such that node *X* and node *X* + *N* / 2 are in different cycles. Suppose we go from node *X* to node 2*X* + *A*, and from *X* + *N* / 2 to 2*X* + *B* (such that *A* + *B* = 1). Switch the route -- we go from node *X* to 2*X* + *B* and *X* + *N* / 2 to 2*X* + *A* instead. This will merge the two cycles -- very similar to how we merge two cycles when finding an eulerian path. Thus, we can keep doing this to obtain our cycle!
+
+...It's not entirely obvious to do that in *O*(*N*) time. An example solution: use DFS. DFS from node 0. For each node *X*:
+
+* if it has been visited, return
+* if *X* + *N* / 2 has been visited, go to either 2*X* or 2*X* + 1 and recurse, depending on which route used by node *X* + *N* / 2
+* otherwise, we go to node 2*X* and recurse. Then, check if *X* + *N* / 2 was visited in the recursion. If it was not, then the two of them forms two different cycles. We merge them by switching our route to 2*X* + 1 instead, and recurse again.
diff --git a/editorials/327.md b/editorials/327.md
@@ -0,0 +1,136 @@
+Source: https://codeforces.com/blog/entry/8274
+
+[327A - Flipping Game](/contest/327/problem/A "Codeforces Round 191 (Div. 2)")
+
+I’ll present here the O(N ^ 3) algorithm, which is enough to solve this task. Then, for those interested, I’ll show a method to achieve O(N) complexity.
+
+**O(N ^ 3) method:** The first thing to observe is that constrains are slow enough to allow a brute force algorithm. Using brute force, I can calculate for each possible single move the number of 1s resulting after applying it and take maximum. For consider each move, I can just generate with 2 FOR loops all indices i, j such as i <= j. So far we have O(N ^ 2) complexity. Suppose I have now 2 fixed vaIues i and j. I need to calculate variable cnt (initially 0) representing the number of ones if I do the move. For do this, I choose another indice k to go in a[] array (taking O(N) time, making the total of O(N ^ 3) complexity). We have two cases: either k is in range [i, j] (this means i <= k AND k <= j) or not (if that condition is not met). If it’s in range, then it gets flipped, so we add to count variable 1 – a[k] (observe that it makes 0 to 1 and 1 to 0). If it’s not in range, we simply add to cnt variable a[k]. The answer is maximum of all cnt obtained.
+
+**O(N) method:** For achieve this complexity, we need to make an observation. Suppose I flip an interval (it does not matter what interval, it can be any interval). Also suppose that S is the number of ones before flipiing it. What happens? Every time I flip a 0 value, S increases by 1 (I get a new 1 value). Every time I flip a 1 value, S decreases by 1 (I loose a 1 value). What would be the “gain” from a flip? I consider winning “+1” when I get a 0 value and “-1” when I get a 1 value. The “gain” would be simply a sum of +1 and -1. This gives us idea to make another vector b[]. B[i] is 1 if A[i] is 0 and B[i] is -1 if A[i] is 1. We want to maximize S + gain_after_one_move sum. As S is constant, I want to maximize gain_after_one_move. In other words, I want to find a subsequence in b[] which gives the maximal sum. If I flip it, I get maximal number of 1s too. This can be founded trivially in O(N ^ 2). How to get O(N)? A relative experienced programmer in dynamic programming will immediately recognize it as a classical problem “subsequence of maximal sum”. If you never heard about it, come back to this approach after you learn it.
+
+[327B - Hungry Sequence](/contest/327/problem/B "Codeforces Round 191 (Div. 2)")
+
+We’ll present two different solutions for this task.
+
+**Solution 1.** What if we solve a more general task? What if each hungry number from the solution isn’t allowed to be divided by any number smaller than it (except 1, which is divides every natural number). If this more general condition would be met, then the “hungry” condition would be met, too (as a[i] won’t be divided by a number smaller than it (except 1), it won’t be divided by a[j], too, with j < i, assuming that a[j] is different from 1). Now how to find numbers for this more general condition? We can rephrase it as: each number from more general condition has 2 divisors: 1 and itself. So if we print N numbers with 2 divisors in increasing order, that would be a good solution. As you probably know, numbers with 2 divisors are called “prime numbers”. The task reduces to finding first N prime numbers. This can be done via brute force, or via Sieve of Eratosthenes (however, not necessarily to get an AC solution).
+
+**Solution 2.** Suppose we are given the number N. We can observe that for big enough consecutive numbers, the array is always hungry. For example, we can print 3 * N + 0, 3 * N + 1, 3 * N + 2, …, 3 * N + (N – 1). Magic, isn’t it? Why does it work now? Pick an arbitrary a[i]. The solution would be bad if one of numbers 2 * a[i], 3 * a[i], 4 * a[i] and so on would be in a[] array. However, it will never happen. The smallest multiple from that ones will be 2 * 3 * N = 6 * N. There is not possible to obtain a smallest multiple than that one. On the other hand, the biggest number from a[] array would be 3 * N + N – 1 = 4 * N — 1. Since smallest multiple is bigger than biggest term of the array, it (and of course other multiples bigger than it) will never exist in a[] array. So the above solution is correct also.
+
+[327C - Magic Five](/contest/327/problem/C "Codeforces Round 191 (Div. 2)")
+
+**Property:** A number is divisible by 5 if and only if its last digit is either 0 or 5.
+
+**A first solution:** Suppose you’re given a plate S, not so big, so we can iterate all its elements. Can we get the answer? I build a new array sol[]. In explanation, both S and sol will be 1-based. Denote N = size of S. Also, denote sol[i] = the number of ways to delete digits from plate S such as we obtain a magic number which has the last digit on position i. The answer is sol[1] + sol[2] + … + sol[N]. Let’s focus now on calculating sol[i]. If S[i] (digit of the plate corresponding to ith position) is different than 0 or 5, then sol[i] is 0 (see “property”). Otherwise we have to ask ourself: in how many ways I can delete digits in “left” and in “right” of position i. In the “right”, we have only one way: delete all digits (if one digit from right still stands, then the number isn’t ending at position i). Now in the “left”: there are digits on positions 1, 2, …, i – 1. We can either delete a digit or keep it – anyhow he’d do we still get a magic number. So on position 1 I have 2 ways (delete or keep it), on position 2 I have also 2 ways, …, on position i – 1 I have also 2 ways. Next, we apply what mathematics call “rule of product” and we get 2 * 2 * 2 … * 2 (i – 1 times) = 2 ^ (i – 1). Applying “rule of product” on both “left” and “right” I get 2 ^ (i – 1) * 1 = 2 ^ (i – 1). To sum it up: If S[i] is 0 or 5 we add to the answer 2 ^ (i – 1). Otherwise, we add nothing. The only problem remained for this simple version is how we calculate A ^ B modulo one number. This is a well known problem as well, called “Exponentiation by squaring”.
+
+**Coming back to our problem:** So what’s different in our problem? It’s the fact that we can’t iterate all elements of plate. However, we can use “concatenation” property. We know that if an element is a position i in the first copy, it will also be on positions i + n, i + 2 * n, i + 3 * n, …, i + (k – 1) * n (we don’t call here about trivial case when k = 1). What if iterate only one copy and calculate for all K copies. If in the first copy, at the position i is either 0 or 5, we have to calculate the sum 2 ^ i + 2 ^ (i + n) + 2 ^ (i + 2 * n) + … + 2 ^ (i + (k – 1) * n). By now on, in calculus I'll denote i as i — 1 (it's a simple mathematical substitution). A first idea would be just to iterate each term and calculate it with exponentiation by squaring. However, it takes in the worst case the same complexity as iterating all plate. We need to find something smarter.
+
+2 ^ i + 2 ^ (i + n) + 2 ^ (i + 2 * n) + … + 2 ^ (i + (k – 1) * n) =
+
+= 2 ^ i * 1 + 2 ^ i * 2 ^ n + 2 ^ i * 2 ^ (2 * n) + … + 2 ^ i * 2 ^ ((k – 1) * N) =
+
+= 2 ^ i * (2 ^ 0 + 2 ^ n + 2 ^ (2 * n) + … + 2 ^ ((k – 1) * n)
+
+We reduced the problem to calculate sum S = 2 ^ 0 + 2 ^ n + 2 ^ (2 * n) + … + 2 ^ (X * n).
+
+What’s the value of 2 ^ n * S ? It is 2 ^ n + 2 ^ (2 * n) + 2 ^ (3 * n) + … + 2 ^ ((X + 1) * n). And what you get by making 2 ^ n * S – S ?
+
+2 ^ n * S – S = 2 ^ ((X + 1) * n) – 1
+
+S * (2 ^ n – 1) = 2 ^ ((X + 1) * n) – 1
+
+S = (2 ^ ((X + 1) * n) – 1) / (2 ^ n – 1).
+
+We can calculate both 2 ^ i and S with exponentiation by squaring and the problem is done. For "/" operator, we can use multiplicative inverse (you can read about that and about Fermat Little's theorem, taking care that 10^9 + 7 is a prime number). The time complexity is O(N * logK). Note: that kind of reduction of powers is called “power series” in math.
+
+**Alternative solution:** For this alternative solution, we don't need to use any special properties of 5. In fact, we can replace 5 by any integer p and still have the same solution. So for now, I shall write p in place of 5.
+
+This suggests a dynamic programming solution: denote dp(x,y) be the number of ways of deleting some digits in the first x digits to form a number that has remainder y (modulo p). For simplicity, we accept “empty” plate be a number that is divisible by p. Writing the DP formula is not difficult. We start with dp(0,0) = 1, and suppose we already have the value dp(x,y). We shall use dp(x,y) to update for dp(x + 1,*), which has two possible cases: either keeping the (x + 1)-th digit or by deleting it. I won't go into much detail here. The answer is therefore dp(N,0).
+
+Clearly, applying this DP directly would time out. For a better algorithm, we resort on the periodicity of the actual plate. The key idea is that, we imagine each digit in the plate as a linear transformation from (x0, x1, .., x(p – 1)) to (y0, y1, y(p-1)). Obviously, (x0, x1, .., x(p — 1)) corresponds to some dp(i, 0), dp(i, 1) .. dp(i, p — 1) and (y0, y1, y(p-1)) corresponds to some (dp(i + 1, 0)), dp((i + 1), 1), ..., dp(i + 1, p — 1) .So we can write X * M(d) = Y, where X and Y are vectors of length p, and M(d) is the matrix of size p * p representing digit d (note that M(d) is independent from X and Y). By multiplying all |a|.K such matrices together, we obtain a transformation from (1, 0, 0, .., 0) to (T0, T1, .., T(p – 1)) where T0 is actually our answer (including the empty plate).
+
+What's the difference? We can group the matrices in groups of length |a|, and lift to the exponent K. That leads to an algorithm with time complexity O(p^3(|a| + log K)), which could be risky. To improve, we should go back to our original DP function and observe that it is actually a linear transformation from (1, 0, 0, .., 0) to (R0, R1, …, R(p – 1)), if we restrict ourselves in the first fragment of length |a|. So instead of multiplying |a| matrices together, we can run DP p times with initial conditions (0, 0, .., 0, 1, 0, .., 0) to obtain the matrix transformation. The overall time complexity becomes O(|a| * p^2 + p^3 log K) .
+
+[327D - Block Tower](/contest/327/problem/D "Codeforces Round 191 (Div. 2)")
+
+In case you want to try some examples on your own, you may play this game, which is the origin of this problem: [http://en.wikipedia.org/wiki/Tower_Bloxx](https://en.wikipedia.org/wiki/Tower_Bloxx)
+
+Now back to the analysis :)
+
+The restriction given in the problem poses you to think of building as many Red Towers as possible, and fill the rest with Blue Towers (since there is no profit of letting cells empty, such cells can be filled by Blue Towers). Also, it's quite obvious to see that each connected component (containing empty cells only) is independent from each other, so we shall iterate the component one by one. Denote the current component be S.
+
+*Lemma 1* is impossible to build S so that it contains all Red Towers only.
+
+*Proof* Suppose there exists such a way. Look up the last cell that is built (denote by x). Clearly x is a Red Tower, so at the moment it is built, x must be adjacent to a cell than contains a Blue Tower. However, it's obvious that there's no such cell (if there is, it must belong to S, which is impossible).
+
+As it's impossible to have all Red Towers, it's natural to look up at the next best solution: the one with exactly one Blue Tower, and among them, we need to find the least lexicographic solution. Fortunately, we can prove that such a configuration is always possible. Such proof is quite tricky, indeed:
+
+*Lemma 2* Pick any cell b in S. It is possible to build a configuration that has all but b be Red Towers, and b is a Blue Tower.
+
+*Proof* Construct a graph whose vertices correspond to the cells of S, and the edges correspond to cells that are adjacent. Since S is connected, it is possible to build a tree that spans to all vertices of S. Pick b as the root and do the following:
+
+1. Build all cells of S blue
+2. Move from the leaf to the root. At each cell (except the root), destroy the Blue Tower and rebuild with the Red Tower. To be precise, u can be destroyed (and rebuilt) if all vertices in the subtree rooted at u have already been rebuilt.
+
+How can it be the valid solution? Take any vertex u which is about to be rebuilt. Clearly u is not b, and u has its parent to be blue, so the condition for rebuilding can be met. When the building is completed, only b remains intact, while others have been transformed into Red Towers.
+
+So we get the following algorithm: do a BFS / DFS search to find connected components. Then, apply Lemma 2 to build a valid configuration.
+
+[327E - Axis Walking](/contest/327/problem/E "Codeforces Round 191 (Div. 2)")
+
+Usually when dealing with complicated problems, a good idea is to solve them for small cases. Let’s try this here.
+
+**First case:** K = 0. The answer is obviously N! (each permutation of p1, p2, …, pn would be good).
+
+**Next case:** K = 1. The answer of this one is N! – |L1|. By L1 I denote all routes for which a prefix sum is equal to first lucky number. Obviously, if from all routes I exclude the wrong ones, I get my answer. If we can find an algorithm to provide |L1| in good time, then problem is solved for K = 1.
+
+1. We can just try all N! permutations. Despite this method is simple, it has complexity O(N!), too much for the constraints.
+2. Suppose we’ve founded a set of positions p1, p2, .., pk such as a[p1] + a[p2] + ..+ a[pk] = U1 (first unlucky number). How many permutations can we make? The first k positions need to be p1, p2, .., pk, but in any order. Hence we get k! . The not used positions can also appeared in any order, starting from k + 1 position. As they are n – k, we can permute them in (n – k)! ways. Hence, the answer is k! * (n – k)! Instead of permuting {1, 2, .., n}, now we need to find subsets of it. Hence, the running time becomes O(2^n). This is still too much.
+3. Meet in the middle. We make all subsets for first half of positions (from 1 to N / 2) and them for second half (from N / 2 + 1 to N). For each subset we keep 2 information: (sum, cnt) representing that there is a subset of sum “sum” containing “cnt” elements. For each (X, Y) from left we iterate in the right. After choosing one element from the left and one from the right we just “split” them. To split 2 states (A, B) and (C, D), the new state becomes (A + C, B + D). But we know that A + C = U1. This comes us to the idea: for each (X, Y) in the left, I check (U1 – X, 1), (U1 – X, 2), … , (U1 – X, K) from the right. For each of them, the answer would be (Y + K)! * (N – Y – K)! . I can store (using any data structure that allows this operations, I suggest a hash) how(C, D) = how many times does state (C, D) appear in the right. So, for a state (A, B) the answer becomes a sum of how(U1 — A, K) * (B + K)! * (N — B — K)!. Doing the sum for all states (A, B), we get our answer. The complexity of this method is O(2 ^ (N / 2) * N).
+
+**Final Case: K = 2** The whole "meet in the middle" explanation worthed. We will do something very similar to solve this case. Suppose U1 and U2 are the unlucky numbers. Without loosing the generality, let's assume U1 <= U2.
+
+Following "Principle of inclusion and exclusion" paradigm (google about it if you never heard before) we can write our solution as N! — |L1| — |L2| + |intersection between L1 and L2|. Again, by L1,2 I denote the number of routes which have a prefix sum equal to number U1,2. The |X| is again the cardinal of this set. Basically we can calculate |X| as for K = 1. The only problem remained is calculating |intersection between L1 and L2|.
+
+The |intersection between L1 and L2| is the number of permutations which have a prefix sum equal to U1 and a prefix sum equal to U2. Since U1 <= U2, we can split a permutation from this set in 3 parts:
+
+1/ p1, p2, ...pk such as a[p1] + a[p2] + ... + a[pk] = U1.
+
+2/ pk+1, pk+2, ..., pm such as a[pk+1], a[pk+2], ..., a[pm] = U2 — U1. Note that a[p1] + a[p2] + ... + a[pm] = U2.
+
+3/ The rest of elements until position n.
+
+By a perfectly identical logic from K = 1 case, the number of permutations given those p[] would be k! * (m — k)! * (n — m)!.
+
+So the problem reduces to: find all indices set p1, p2, ... and q1, q2, .. such as a[p1] + a[p2] + ... + a[pn1] = U1 and a[q1] + a[q2] + ... + a[qn2] = U2 — U1. Then, we can apply formula using n1 and n2 described above.
+
+The first idea would be O(3 ^ N) — for each position from {1, 2, .., n} atribute all combinations of {0, 1, 2}. 0 means that position i is 1/, 1 means that position i is in 2/ and 2 means that position i is in 3/ . This would time out.
+
+Happily, we can improve it with meet in the middle principle. The solution is very similar with K = 1 case. I won't fully explain it here, if you understood principle from K = 1 this shouldn't be a problem. The base idea is to keep (S1, S2, cnt1, cnt2) for both "left" and "right". (S1, S2, cnt1, cnt2) represents a subset which has sum of elements from 1/ equal to S1, sum of elements from 2/ equal to S2, in 1/ we have cnt1 element and in 2/ we get cnt2 elements. For a (S1, S2, cnt1, cnt2) state from "left" we are looking in the right for something like (U1 — S1, U2 — U1 — S2, i, j). We get O(3 ^ (N / 2) * N ^ 2) complexity.
+
+**Unexpected solution** During the round, we saw a lot of O(2 ^ N * N) solutions passing. This was totally out of expectations. I believe if would make tests stronger, this solution won't pass and round would be more challenging. That's it, nothing is perfect. As requested, I'll explain that solution here.
+
+Before explaining the solution, I assume you have some experience with "bitmask dp" technique. If you don't, please read before:
+
+<http://community.topcoder.com/tc?module=Static&d1=tutorials&d2=bitManipulation>
+
+[http://codeforces.com/blog/entry/337](//codeforces.com/blog/entry/337)
+
+In this problem we'll assume that a is 0-based. For a mask, consider bits from right to left, noting them bit 0, bit 1 and so on. Bit i is 1 if and only if a[i] is in the subset which is in a bijective replation with the mask. For example, for mask 100011101 the subset is {a0, a2, a3, a4, a8}. I'll call from now on the subset "subset of mask". Also, the sum of all elements in a subset will be called "sum of mask" (i.e. a0 + a2 + a3 + a4 + a8). We'll explain the solution based by [watashi](/profile/watashi "Grandmaster watashi")'s submission. [4017915](/contest/327/submission/4017915 "Submission 4017915 by watashi")
+
+First step of the algorithm is to calculate sum of each mask. Let dp[i] the sum of mask i. Remove exactly one element from the subset of mask. Suppose the new mask obtained is k and removed element is j. Then, dp[i] = dp[k] + a[j]. dp[k] is always calculated before dp[i] (to proof, write both k and i in base 10. k is always smaller than i). Having j an element from subset of mask i, we can compute mask k by doing i ^ (1 << j). Bit j is 1, and by xor-ing it with another 1 bit, it becomes 0. Other bits are unchanged by being xor-ed by 0. This method works very fast to compute sum of each mask.
+
+From now on, let's denote a new array dp2[i] = how many good routes can I obtain with elements from subset of mask i. Watashi uses same dp[] array, but for making it clear, in editorial I'll use 2 separate arrays. Suppose that CNT(i) is number of elements from subset of mask i. We are interested in how many ways we can fill positions {1, 2, ..., CNT(i)} with elements from subset of mask i such as each prefix sum is different by each unlucky number.
+
+Next step of the algorithm is to see which sum of masks are equal to one of unlucky numbers. We mark them as "-1" in dp2[]. Suppose we founded a subset {a1, a2, ..., ax} for which a1 + a2 + ... + ax = one of unlucky numbers. Then, none permutation of {a1, a2, ..., ax} is allowed to appear on first x positions. When we arrive to a "-1" state, we know that the number of good routes for its subset of mask is 0.
+
+Now, finally the main dp recurrence. If for the current mask i, dp2[i] = -1, then dp2[i] = 0 and continue (we discard the state as explained above). Otherwise, we know that there could exist at least one way to complete positions {1, 2, ... CNT(i)} with elements of subset of mask i. But how to calculate it? We fix the last element (the element from the position CNT(I)) with some j from subset of mask i. The problem reduces now with how many good routes can I fill in positions {1, 2, ..., CNT(i) — 1} with elements from subset of mask i, from which we erased element j. With same explanation of sum of mask calculations, this is already calculated in dp2[i ^ (1 << j)].
+
+The result is dp2[(1 << N) — 1] (number of good routes containing all positions).
+
+Editorial has been made by me and [ll931110](/profile/ll931110 "Master ll931110").
+
+The authors of the problems:
+
+Div.2 A & Div.2 B — me
+
+Div.2 C & Div.2 D & Div.2 E — [ll931110](/profile/ll931110 "Master ll931110")
diff --git a/editorials/329.md b/editorials/329.md
@@ -0,0 +1,267 @@
+Source: https://codeforces.com/blog/entry/8417
+
+So! We hope you enjoyed the round. Internally, we called this round **Trollforces**, because as you knew, most solutions should be unexpected :)
+
+Some fun fact: there are ~ 30 pictures in this round, totaling ~ 144 KB.
+
+Here is the editorial, written with mixed point of views of all writers (hence "I" may refer to any of us).
+
+---
+
+[330A - Тортминатор](/contest/330/problem/A "Codeforces Round 192 (Div. 2)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+**Long solution:**
+
+* Once an evil strawberry, always an evil strawberry (since they can’t be eaten).
+* Thus, if a row cannot be eaten before any eat is performed, it can never be eaten.
+* Same with column.
+* Thus, you can know which columns and which rows you can eat.
+* Just try to eat them all and calculate how many cells you actually eat.
+
+**Short solution:**
+
+* A row or a column cannot be eaten if it has at least one strawberry.
+* A cell cannot be eaten if both its row and its column cannot be eaten -- otherwise you can eat the row/column and eat it!
+
+If there are r' rows that cannot be eaten, and c' columns that cannot be eaten, then there are r' * c' cells that cannot be eaten -- a cell such that both its row and columns cannot be eaten.
+
+Since all other cells can be eaten, answer is R * C — r' * c'.
+
+---
+
+[330B - Строим дорогу](/contest/330/problem/B "Codeforces Round 192 (Div. 2)") by [jonathanirvings](/profile/jonathanirvings "Кандидат в мастера jonathanirvings")
+
+* Since m < n/2, there exists at least one node that is not incident to any edge.
+* The constraints can be satisfied if and only if the graph is a star graph: [http://en.wikipedia.org/wiki/Star_(graph_theory)](https://en.wikipedia.org/wiki/Star_(graph_theory)). We can just create a star graph centered with the node and connect it to all other nodes.
+
+---
+
+[330C - Очищение](/contest/330/problem/C "Codeforces Round 192 (Div. 2)") / [329A - Очищение](/contest/329/problem/A "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+* Obviously the minimum possible answer is n (why?). But is it always possible to purify all the cells with n spells?
+* If there exist a row consisting of entirely "E" cells and a column consisting of entirely "E" cells, then the answer is -1. This is since the cell with that row and that column cannot be purifed.
+* Otherwise, without loss of generality let's suppose there is no row consisting entirely of "E". Then, for each row, find any "." cell. Purify it. The case with no column consisting entirely of "E" is similar.
+
+---
+
+[330D - Биридианский лес](/contest/330/problem/D "Codeforces Round 192 (Div. 2)") / [329B - Биридианский лес](/contest/329/problem/B "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+The only non ad hoc problem in the round! ...sort of. Despite the very long problem statement, the solution is really simple.
+
+* We should take **any** shortest path from S to E (yes, any!). We will see why this is optimal at the end.
+* If a breeder can reach E faster than or equal to us, then he will battle us. This is since he can simply walk to E and waits for us there.
+* Otherwise, they can never battle us by contradiction. Assume they battled us, but they cannot reach cell E from their location faster or equal to us. If the battle us in cell X, then cell X is part of the shortest path from S to E that you are travelling. Since he is able to battle us there, he must be able to arrive at cell X <= us. But then, that means he can walk from X to E and reach E before or equal to us! Contradiction.
+* This is optimal, since any breeder that we battle in this solution must also be battled in any other solution (the other breeders should immediately go to E and wait).
+* You can use Breadth-First Search once from exit cell to obtain the shortest paths from each breeder to it.
+
+**Thoughts**
+
+I tried to make this clearer by separating the paragraphs by topic. Did it work well?
+
+Btw, mikemon is pronounced "mi-ke-mon", not "mike"-mon -- similar to how Pokemon is pronounced "po-ke-mon" not "poke"-mon >:).
+
+---
+
+[330E - Перестроим граф](/contest/330/problem/E "Codeforces Round 192 (Div. 2)") / [329C - Перестроим граф](/contest/329/problem/C "Codeforces Round 192 (Div. 1)") by [fushar](/profile/fushar "Кандидат в мастера fushar")
+
+First, I would like to apologize the missing node 3 in the picture of the first example. It was a mistake :(
+
+**Intended, deterministic solution:**
+
+* If n <= 7, brute force all possible subsets of the edges (at most 2^(7 * (7 — 1) / 2)), and check if they satisfy the constraint.
+* Otherwise, a solution always exists. Here is how to construct one.
+* Partition the nodes into connected components. Note that each component will be either a cycle or a chain. List the nodes of each component in order of the cycle/chain. For example, for the first example, the partition would be { <1, 2, 3>, <4, 5, 6, 8, 7> }. For each component, we do not care whether it is a cycle or a chain.
+* For each component, reorder the nodes such that all nodes in the odd positions are in the front. For example, component ABCDEFGHI is reordered into ACEGIBDFH. (Each letter represent a node.)
+* Pick any component with the largest number of nodes. If the number of nodes in it is even, **swap the first two nodes**. For example, ABCDEFGH -> ACEGBDFH -> CAEGBDFH.
+* For each other component, insert the nodes alternately between the largest component. For example, if the other components are acebd and 1324, insert them as follows: CAEGBDFH -> C **a** A **c** E **e** G **b** B **d** DFH -> C **1** a **3** A **2** c **4** EeGbBdDFH.
+* Connect adjacent nodes so that the number of edges is m, connecting the last with the first nodes if necessary.
+
+The deterministic solution is very tricky. Therefore, I made the pretest quite strong. Some tricky cases:
+
+* 4-cycle and 1-chain (covered in the example)
+* 3-cycle and 3-cycle
+* 4-cycle and 3-cycle (very tricky! many submissions failed on this case)
+
+Actually, we can do brute force when n <= 6, but this requires a special handling: when the largest component has 4 nodes, we should swap the first node with the third node (not the second). This is to handle the 4-cycle-and-3-cycle case.
+
+**Troll solution, nondeterministic:**
+
+Do the following many times:
+
+```
+x = [1, 2, 3, ..., n]
+random_shuffle(x)
+for i = 1 to m:
+ if the edge (x[i], x[(i+1)%n]) is in input:
+ // fail this iteration, repeat the entire procedure
+
+if didn’t fail:
+ // we obtain a solution!
+ for i = 1 to m:
+ print x[i], x[(i+1)%n]
+
+If didn’t obtain solution:
+ print -1
+```
+
+So, the question is, for large n what is the probability that a permutation is not "bad"? This can be computed (or at least approximated) similar to computing derangement probability -- I obtained a result above 0.1, which means in 100 iterations it should succeed if there was a solution. ...There is a solution if n > 7, so it should work.
+
+---
+
+[329D - Злой храм и двигающиеся камни](/contest/329/problem/D "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+Post your solution in the comment! Here's mine for the last case! (approximately 120,000 sounds). You can get the number of sounds your solution produces when submitting it to the server.
+
+```
+1 copy of
+v<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<
+v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v^
+
+24 copies of
+v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.
+v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^
+
+24 copies of
+v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^
+.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^
+
+1 copy of
+>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^
+....................................................................................................
+
+1 1
+```
+
+I wonder if there’s a solution with ~150,000 sounds or more... the (theoretical) upper bound is 100^3 / something, so it may be feasible...?
+
+---
+
+[329E - Зло](/contest/329/problem/E "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+The solution to this problem is actually **quite simple**: [4122927](/contest/329/submission/4122927 "Посылка 4122927 от dolphinigle")
+
+This problem asks us to prove something very long (the proof below is of 80+ lines).
+
+Assume that the number of cities is at least 4. The case where it's less than 4 is trivial.
+
+First, we will assume that no two cities will have same X or Y coordinates. To get this assumption, we can juxtapose every city very slightly that it will not change the answer.
+
+The keys are : A) "Manhattan Distance", B) the tour starts and ends at the same city. Suppose we know a tour. The total distance traveled will be |X1 — X2| + |Y1 — Y2| + |X3 — X2| + |Y3 — Y2| ...
+
+Let's separate the X and Y coordinates for simplicity. Note that each city will contribute twice to this value, for example X2 was in |X1 — X2| and |X3 — X2| in the example above. Manhattan distance implies that each of these values will either be multiplied by +1 or -1, depending on the other coordinate being compared in the absolute term. Furthermore, the number of values that are multiplied by +1 must equal the number of values that are multiplied by -1 (since in each absolute term, one is multiplied by +1 and the other by -1). This directly implies an upper bound on the maximum length of the tour.
+
+If we list all the X coordinates of the cities, and we put each of them twice in this list, and sort them, the maximum will be gained if we multiply the last half by +1 and the first half by -1, and finally summing them up. Note that all of these reasoning applies to the Y coordinate, and summing both maximum of X and Y, we receive an upper bound on the length of the tour.
+
+If we can find a tour with this length, our job is done. In some case, it's possible. Let's investigate!
+
+First, if we have the medians of the X and the Ys as in the list above, we can separated the field like below :
+
+```
+ A | B
+ |
+---------
+ |
+ C | D
+```
+
+The lines corresponds to the median for both X and Y.
+
+At most one city will lie on each of the median lines (recall our assumption that X and Ys are distinct).
+
+Let's call each A B C and D as boxes. Below, we will refer box A as simply A (applies to B, C, and D too)
+
+To obtain the value above, from a city in B we must go to a city in C. Same reasoning yields : B->C, C->B, A->D, D->A. Here, pairs of cities become apparrent, A and D are paired as well as B and C.
+
+First, if either A+D is empty or B+C is empty, then we can obtain the upper bound above. We simply alternates between the two remaining pair. So let's assume that A+D is not empty and B+C is not empty.
+
+First, let's investigate the relationship between B and C (A and B will also exhibits this relationship).
+
+**Theorem 1:**
+
+|B — C| <= 1.
+
+Why:
+
+First, if there are no cities in the medians or there is a single city in the center of the median :
+
+A median divides the region into two areas with the same number of cities, so we have:
+
+```
+a) A+B = C+D
+b) A+C = B+D
+```
+
+substituting A from a to b yields :
+
+```
+(C+D-B)+C = B+D
+2C = 2B
+B = C
+```
+
+And the theorem follows.
+
+Next, suppose there are two cities in the median, one for each median line :
+
+Let's suppose the median is one above and one on the right. All other cases will be similar. By definition of median...
+
+```
+a) (A + B + 1) = (C + D)
+b) (A + C) = (B + D + 1)
+```
+
+Substituing a into b yields
+
+```
+(C + D - B - 1 + C) = (B + D + 1)
+2C = 2B + 2
+C = B + 1
+```
+
+which also implies A = D
+
+Applying the same technique to other cases will give:
+
+```
+C = B and A = D+1
+C = B-1 and A = D
+C = B and A = D-1
+```
+
+And the theorem follows.
+
+Note also that the one with the extra 1 city will be the one that is not adjacent to any median city (adjacent being the city lies in the boundary of the box)
+
+OK, so in the following observations, we will assume the upper bound (that is, the sorted list of both X and Ys have their first half multiplied by -1 while the rest by +1), and trying to find a solution that's as close as possible to this upper bound.
+
+The following will be another case analysis.
+
+**Theorem 2:**
+
+If there are two cities in the medians (that is, one in each median line), then the upper bound can be achieved.
+
+Why:
+
+We use pair of boxes to denote either A and D or B and C. From the second part of the proof for theorem 1, there will be a pair of boxes that contain different number of cities. Let's pick this pair, and start at the one with the most boxes. We keep alternating with its pair until we end up back in our starting box. Then, we simply move to either of the median city. From there we move to the other pair of box, the farthest one of the two. Alternate between the two, go to the other median city, and return to the starting city. It's easy to see that this will be optimal and have the upper bound as its value.
+
+Now, let's see if there are no cities in the medians. First of all, this implies that the number of cities is even. Second, this implies that our upper bound which has the X and Y lists as -1 -1 -1 ... -1 1 ... 1 1 1 will not work (since this implies we have to continuously alternate between the two pairs of boxes, however, we can't switch between the pair of boxes). So, at least a modification would be required. The smallest possible modification is obtained by swapping the medians, that is, it becomes : -1 -1 -1 ... -1 -1 1 -1 1 1 ... 1 1 1. This is sufficient. Why? So, there are two cities that changes since the number of cities is even. Furthermore, these two cities will be the closest to the median line (let's assume these coordinates are X, that is, they're the closest to the vertical median line) and lies at two different boxes. Then, we proceed as follows. We start at one of these two cities. Alternate and end at the other side. If the other city is at that box, we make it so that we end at that city, and in this case, we can move to a city in the other box pair while respecting the list of X coordinates (we can do so since this city is the closest to the median line). Otherwise, the city will be in the other pair of boxes. We simply move there and it can be shown that we still respect the list of X coordinates. Alternate and at the end, go back to the starting city. All of these can be shown to still respect the list above.
+
+This is optimal since this is the next largest possible upper bound if upper bound cannot be achieved.
+
+Now, if there is a single city in the center of both medians, then the upper bound cannot be achieved. To see this, the upper bound can only be achieved if from a city in a box we move to another city in its box pair or to the center city. However, since both pair of boxes contains a city, we will need to move at least twice between them. Since there's only one center city, this is not possible.
+
+Observe that this case implies an odd number of cities. Hence, we can't simply swap the median since it swaps the x coordinates of the same median city. Instead, we do this :
+
+-1 -1 ... -1 -1 1 1 -1 1 ... 1 1
+
+or
+
+-1 -1 ... -1 1 -1 -1 1 1 ... 1 1
+
+That is, we swap to either one of the neighboring city. With the same reasoning as above, we can show that we respect this list of X coordinates.
+
+To achieve O(N) expected performance, note that the only operations we need are : grouping elements into boxes and median finding. Both can be done in expected O(N) time (expected since although there is a worst-case O(N) selection algorithm, it's ugly).
+
+**Thoughts:**
+
+Actually I intended to reword this into a three-paragraph weird story, but that seems a little too evil >:), so it was left out.
diff --git a/editorials/33.md b/editorials/33.md
@@ -0,0 +1,9 @@
+Source: https://codeforces.com/blog/entry/731
+
+## Analysis of problem "A. What is for dinner?"
+
+The solution of the problem is rather trivial. It was needed to make an array, where for each row of teeth the value of residual viability of the sickest thooth in this row would have kept (sickest tooth in the row is called the one with the lowest residual viability).
+
+Thus we define for each row of teeth the maximum number of crucians, which Valery able to eat, using this row (Valeria can not eat more crucians, because the residual viability of the sickest tooth will become negative).
+
+Knowing these values, you just need to sum them and to give the minimum of the sum and total amount of crucians in Valerie's portion for dinner as answer.
diff --git a/editorials/330.md b/editorials/330.md
@@ -0,0 +1,267 @@
+Source: https://codeforces.com/blog/entry/8417
+
+So! We hope you enjoyed the round. Internally, we called this round **Trollforces**, because as you knew, most solutions should be unexpected :)
+
+Some fun fact: there are ~ 30 pictures in this round, totaling ~ 144 KB.
+
+Here is the editorial, written with mixed point of views of all writers (hence "I" may refer to any of us).
+
+---
+
+[330A - Тортминатор](/contest/330/problem/A "Codeforces Round 192 (Div. 2)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+**Long solution:**
+
+* Once an evil strawberry, always an evil strawberry (since they can’t be eaten).
+* Thus, if a row cannot be eaten before any eat is performed, it can never be eaten.
+* Same with column.
+* Thus, you can know which columns and which rows you can eat.
+* Just try to eat them all and calculate how many cells you actually eat.
+
+**Short solution:**
+
+* A row or a column cannot be eaten if it has at least one strawberry.
+* A cell cannot be eaten if both its row and its column cannot be eaten -- otherwise you can eat the row/column and eat it!
+
+If there are r' rows that cannot be eaten, and c' columns that cannot be eaten, then there are r' * c' cells that cannot be eaten -- a cell such that both its row and columns cannot be eaten.
+
+Since all other cells can be eaten, answer is R * C — r' * c'.
+
+---
+
+[330B - Строим дорогу](/contest/330/problem/B "Codeforces Round 192 (Div. 2)") by [jonathanirvings](/profile/jonathanirvings "Кандидат в мастера jonathanirvings")
+
+* Since m < n/2, there exists at least one node that is not incident to any edge.
+* The constraints can be satisfied if and only if the graph is a star graph: [http://en.wikipedia.org/wiki/Star_(graph_theory)](https://en.wikipedia.org/wiki/Star_(graph_theory)). We can just create a star graph centered with the node and connect it to all other nodes.
+
+---
+
+[330C - Очищение](/contest/330/problem/C "Codeforces Round 192 (Div. 2)") / [329A - Очищение](/contest/329/problem/A "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+* Obviously the minimum possible answer is n (why?). But is it always possible to purify all the cells with n spells?
+* If there exist a row consisting of entirely "E" cells and a column consisting of entirely "E" cells, then the answer is -1. This is since the cell with that row and that column cannot be purifed.
+* Otherwise, without loss of generality let's suppose there is no row consisting entirely of "E". Then, for each row, find any "." cell. Purify it. The case with no column consisting entirely of "E" is similar.
+
+---
+
+[330D - Биридианский лес](/contest/330/problem/D "Codeforces Round 192 (Div. 2)") / [329B - Биридианский лес](/contest/329/problem/B "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+The only non ad hoc problem in the round! ...sort of. Despite the very long problem statement, the solution is really simple.
+
+* We should take **any** shortest path from S to E (yes, any!). We will see why this is optimal at the end.
+* If a breeder can reach E faster than or equal to us, then he will battle us. This is since he can simply walk to E and waits for us there.
+* Otherwise, they can never battle us by contradiction. Assume they battled us, but they cannot reach cell E from their location faster or equal to us. If the battle us in cell X, then cell X is part of the shortest path from S to E that you are travelling. Since he is able to battle us there, he must be able to arrive at cell X <= us. But then, that means he can walk from X to E and reach E before or equal to us! Contradiction.
+* This is optimal, since any breeder that we battle in this solution must also be battled in any other solution (the other breeders should immediately go to E and wait).
+* You can use Breadth-First Search once from exit cell to obtain the shortest paths from each breeder to it.
+
+**Thoughts**
+
+I tried to make this clearer by separating the paragraphs by topic. Did it work well?
+
+Btw, mikemon is pronounced "mi-ke-mon", not "mike"-mon -- similar to how Pokemon is pronounced "po-ke-mon" not "poke"-mon >:).
+
+---
+
+[330E - Перестроим граф](/contest/330/problem/E "Codeforces Round 192 (Div. 2)") / [329C - Перестроим граф](/contest/329/problem/C "Codeforces Round 192 (Div. 1)") by [fushar](/profile/fushar "Кандидат в мастера fushar")
+
+First, I would like to apologize the missing node 3 in the picture of the first example. It was a mistake :(
+
+**Intended, deterministic solution:**
+
+* If n <= 7, brute force all possible subsets of the edges (at most 2^(7 * (7 — 1) / 2)), and check if they satisfy the constraint.
+* Otherwise, a solution always exists. Here is how to construct one.
+* Partition the nodes into connected components. Note that each component will be either a cycle or a chain. List the nodes of each component in order of the cycle/chain. For example, for the first example, the partition would be { <1, 2, 3>, <4, 5, 6, 8, 7> }. For each component, we do not care whether it is a cycle or a chain.
+* For each component, reorder the nodes such that all nodes in the odd positions are in the front. For example, component ABCDEFGHI is reordered into ACEGIBDFH. (Each letter represent a node.)
+* Pick any component with the largest number of nodes. If the number of nodes in it is even, **swap the first two nodes**. For example, ABCDEFGH -> ACEGBDFH -> CAEGBDFH.
+* For each other component, insert the nodes alternately between the largest component. For example, if the other components are acebd and 1324, insert them as follows: CAEGBDFH -> C **a** A **c** E **e** G **b** B **d** DFH -> C **1** a **3** A **2** c **4** EeGbBdDFH.
+* Connect adjacent nodes so that the number of edges is m, connecting the last with the first nodes if necessary.
+
+The deterministic solution is very tricky. Therefore, I made the pretest quite strong. Some tricky cases:
+
+* 4-cycle and 1-chain (covered in the example)
+* 3-cycle and 3-cycle
+* 4-cycle and 3-cycle (very tricky! many submissions failed on this case)
+
+Actually, we can do brute force when n <= 6, but this requires a special handling: when the largest component has 4 nodes, we should swap the first node with the third node (not the second). This is to handle the 4-cycle-and-3-cycle case.
+
+**Troll solution, nondeterministic:**
+
+Do the following many times:
+
+```
+x = [1, 2, 3, ..., n]
+random_shuffle(x)
+for i = 1 to m:
+ if the edge (x[i], x[(i+1)%n]) is in input:
+ // fail this iteration, repeat the entire procedure
+
+if didn’t fail:
+ // we obtain a solution!
+ for i = 1 to m:
+ print x[i], x[(i+1)%n]
+
+If didn’t obtain solution:
+ print -1
+```
+
+So, the question is, for large n what is the probability that a permutation is not "bad"? This can be computed (or at least approximated) similar to computing derangement probability -- I obtained a result above 0.1, which means in 100 iterations it should succeed if there was a solution. ...There is a solution if n > 7, so it should work.
+
+---
+
+[329D - Злой храм и двигающиеся камни](/contest/329/problem/D "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+Post your solution in the comment! Here's mine for the last case! (approximately 120,000 sounds). You can get the number of sounds your solution produces when submitting it to the server.
+
+```
+1 copy of
+v<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<.<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<<
+v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v>v^
+
+24 copies of
+v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.v.
+v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^
+
+24 copies of
+v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^v^
+.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^.^
+
+1 copy of
+>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^>^
+....................................................................................................
+
+1 1
+```
+
+I wonder if there’s a solution with ~150,000 sounds or more... the (theoretical) upper bound is 100^3 / something, so it may be feasible...?
+
+---
+
+[329E - Зло](/contest/329/problem/E "Codeforces Round 192 (Div. 1)") by [dolphinigle](/profile/dolphinigle "Международный мастер dolphinigle")
+
+The solution to this problem is actually **quite simple**: [4122927](/contest/329/submission/4122927 "Посылка 4122927 от dolphinigle")
+
+This problem asks us to prove something very long (the proof below is of 80+ lines).
+
+Assume that the number of cities is at least 4. The case where it's less than 4 is trivial.
+
+First, we will assume that no two cities will have same X or Y coordinates. To get this assumption, we can juxtapose every city very slightly that it will not change the answer.
+
+The keys are : A) "Manhattan Distance", B) the tour starts and ends at the same city. Suppose we know a tour. The total distance traveled will be |X1 — X2| + |Y1 — Y2| + |X3 — X2| + |Y3 — Y2| ...
+
+Let's separate the X and Y coordinates for simplicity. Note that each city will contribute twice to this value, for example X2 was in |X1 — X2| and |X3 — X2| in the example above. Manhattan distance implies that each of these values will either be multiplied by +1 or -1, depending on the other coordinate being compared in the absolute term. Furthermore, the number of values that are multiplied by +1 must equal the number of values that are multiplied by -1 (since in each absolute term, one is multiplied by +1 and the other by -1). This directly implies an upper bound on the maximum length of the tour.
+
+If we list all the X coordinates of the cities, and we put each of them twice in this list, and sort them, the maximum will be gained if we multiply the last half by +1 and the first half by -1, and finally summing them up. Note that all of these reasoning applies to the Y coordinate, and summing both maximum of X and Y, we receive an upper bound on the length of the tour.
+
+If we can find a tour with this length, our job is done. In some case, it's possible. Let's investigate!
+
+First, if we have the medians of the X and the Ys as in the list above, we can separated the field like below :
+
+```
+ A | B
+ |
+---------
+ |
+ C | D
+```
+
+The lines corresponds to the median for both X and Y.
+
+At most one city will lie on each of the median lines (recall our assumption that X and Ys are distinct).
+
+Let's call each A B C and D as boxes. Below, we will refer box A as simply A (applies to B, C, and D too)
+
+To obtain the value above, from a city in B we must go to a city in C. Same reasoning yields : B->C, C->B, A->D, D->A. Here, pairs of cities become apparrent, A and D are paired as well as B and C.
+
+First, if either A+D is empty or B+C is empty, then we can obtain the upper bound above. We simply alternates between the two remaining pair. So let's assume that A+D is not empty and B+C is not empty.
+
+First, let's investigate the relationship between B and C (A and B will also exhibits this relationship).
+
+**Theorem 1:**
+
+|B — C| <= 1.
+
+Why:
+
+First, if there are no cities in the medians or there is a single city in the center of the median :
+
+A median divides the region into two areas with the same number of cities, so we have:
+
+```
+a) A+B = C+D
+b) A+C = B+D
+```
+
+substituting A from a to b yields :
+
+```
+(C+D-B)+C = B+D
+2C = 2B
+B = C
+```
+
+And the theorem follows.
+
+Next, suppose there are two cities in the median, one for each median line :
+
+Let's suppose the median is one above and one on the right. All other cases will be similar. By definition of median...
+
+```
+a) (A + B + 1) = (C + D)
+b) (A + C) = (B + D + 1)
+```
+
+Substituing a into b yields
+
+```
+(C + D - B - 1 + C) = (B + D + 1)
+2C = 2B + 2
+C = B + 1
+```
+
+which also implies A = D
+
+Applying the same technique to other cases will give:
+
+```
+C = B and A = D+1
+C = B-1 and A = D
+C = B and A = D-1
+```
+
+And the theorem follows.
+
+Note also that the one with the extra 1 city will be the one that is not adjacent to any median city (adjacent being the city lies in the boundary of the box)
+
+OK, so in the following observations, we will assume the upper bound (that is, the sorted list of both X and Ys have their first half multiplied by -1 while the rest by +1), and trying to find a solution that's as close as possible to this upper bound.
+
+The following will be another case analysis.
+
+**Theorem 2:**
+
+If there are two cities in the medians (that is, one in each median line), then the upper bound can be achieved.
+
+Why:
+
+We use pair of boxes to denote either A and D or B and C. From the second part of the proof for theorem 1, there will be a pair of boxes that contain different number of cities. Let's pick this pair, and start at the one with the most boxes. We keep alternating with its pair until we end up back in our starting box. Then, we simply move to either of the median city. From there we move to the other pair of box, the farthest one of the two. Alternate between the two, go to the other median city, and return to the starting city. It's easy to see that this will be optimal and have the upper bound as its value.
+
+Now, let's see if there are no cities in the medians. First of all, this implies that the number of cities is even. Second, this implies that our upper bound which has the X and Y lists as -1 -1 -1 ... -1 1 ... 1 1 1 will not work (since this implies we have to continuously alternate between the two pairs of boxes, however, we can't switch between the pair of boxes). So, at least a modification would be required. The smallest possible modification is obtained by swapping the medians, that is, it becomes : -1 -1 -1 ... -1 -1 1 -1 1 1 ... 1 1 1. This is sufficient. Why? So, there are two cities that changes since the number of cities is even. Furthermore, these two cities will be the closest to the median line (let's assume these coordinates are X, that is, they're the closest to the vertical median line) and lies at two different boxes. Then, we proceed as follows. We start at one of these two cities. Alternate and end at the other side. If the other city is at that box, we make it so that we end at that city, and in this case, we can move to a city in the other box pair while respecting the list of X coordinates (we can do so since this city is the closest to the median line). Otherwise, the city will be in the other pair of boxes. We simply move there and it can be shown that we still respect the list of X coordinates. Alternate and at the end, go back to the starting city. All of these can be shown to still respect the list above.
+
+This is optimal since this is the next largest possible upper bound if upper bound cannot be achieved.
+
+Now, if there is a single city in the center of both medians, then the upper bound cannot be achieved. To see this, the upper bound can only be achieved if from a city in a box we move to another city in its box pair or to the center city. However, since both pair of boxes contains a city, we will need to move at least twice between them. Since there's only one center city, this is not possible.
+
+Observe that this case implies an odd number of cities. Hence, we can't simply swap the median since it swaps the x coordinates of the same median city. Instead, we do this :
+
+-1 -1 ... -1 -1 1 1 -1 1 ... 1 1
+
+or
+
+-1 -1 ... -1 1 -1 -1 1 1 ... 1 1
+
+That is, we swap to either one of the neighboring city. With the same reasoning as above, we can show that we respect this list of X coordinates.
+
+To achieve O(N) expected performance, note that the only operations we need are : grouping elements into boxes and median finding. Both can be done in expected O(N) time (expected since although there is a worst-case O(N) selection algorithm, it's ugly).
+
+**Thoughts:**
+
+Actually I intended to reword this into a three-paragraph weird story, but that seems a little too evil >:), so it was left out.
diff --git a/editorials/331.md b/editorials/331.md
@@ -0,0 +1,25 @@
+Source: https://codeforces.com/blog/entry/8397
+
+Hello!
+
+ABBYY Cup 3.0 is finished! Many thanks to everyone: participants, people who created and prepared problems and etc! The post about ABBYY Open Day will be later but now let's consider finals' solutions:
+
+#### Problem A
+
+Claim: If the walk starts from tree *i* and ends at tree *j*, then we need to cut down all trees before *i*, all trees after *j* and all trees with negative esthetic appeal between *i* and *j*. In order to solve subproblem A1 we could use the claim for each pair of trees with equal aesthetic appeal and choose the maximum; the constraints allowed to do this either at *O*(*n*2) or *O*(*n*3). In order to solve subproblem A2 we could use the following claim: whichever is the number of trees with equal esthetic appeal, we are always better off if we consider only a pair of the leftmost and rightmost of such trees. Then the number of the pairs of trees considered is reduced from *O*(*n*2) to *O*(*n*). Then we may proceed with either taking partial sums or calculating a sum on the interval.
+
+#### Problem B
+
+In order to solve subproblem B1 we may emulate the behavior of Beavershave as it is described in the problem. In order to solve subproblem B2 it is sufficient to store a raised unity-flag for each terminal beaver, where terminal beaver is such beaver *i* who does not have a beaver *i* + 1 on his right (that is, if we make a query which includes beavers *i* and *i* + 1, then we would have to run Beavershave one more time). If we swap beavers *i* and *j*, then we have four possible positions at which the status of the flag may change: *i* - 1, *i*, *j* - 1, *j*. A response to a query is then the number of the terminal beavers in the interval which is a classical problem.
+
+#### Problem C
+
+In order to solve subproblem C1 we could either calculate dynamics or subtract the largest number using greedy algorithm. It is easy to prove that it is always better to subtract the largest number. In subproblem C2 it is sufficient to calculate dynamics for the first million, divide (in head) the number into two groups of digits — low orders and high orders — and make not one subtraction, but a series of subtractions in order to instantly minimize low orders. In order to solve subproblem C3 it is necessary to store in dynamics parameters not the number itself, but only the number of digits.
+
+#### Problem D
+
+Obviously, the Beaveractor moving along the arrows will either get out or go round a cycle. If the latter is the case, we need to find the length of the cycle *l*, and then we need to find the remainder of dividing the time by the length of the cycle. Thus, we have solved this case. In order to solve subproblem D1 it is sufficient to emulate the behavior of the Beaveractor saving at each step the time of the visit of the current point (this way we will know the length of the cycle the moment we come to the point in the cycle from which we started). In order to solve subproblems D2 and D3 we need to construct a graph of Beaveractor's movements and then process each of the multiple tests. In D2 we may construct the graph in a straightforward way and find an answer to each test by going through the graph. In D3 we are supposed to use logarithmic data structures. The idea of the solution is, thus, clear. The problem is interesting from the technical point of view.
+
+#### Problem E
+
+In order to solve subproblem E1 we may use the following claim: If the edge *x* → *y* has marks *x* and *y* in succession, then such edge may generate the path of interest. Call such edge "initiating". It is easy to understand that the path in both directions is constructed unambiguously from the initiating edge. Now, it is sufficient to consider only initiating edges. Indeed, consider required path in a graph. It has *p* nodes and *p* - 1 edges. By pigeonhole principle at least one edge has two or more marks. Let some edge *x* → *y* have marks *a* *b*, (*a*, *b*) ≠ (*x*, *y*). Then cut this path in two by the edge *x* → *y* and note that one of the two subpaths has more marks than it has edges. Proceeding in a similar fashion we may come to the conclusion that there is at least one edge *x* → *y* with marks *x* and *y*. If there are no initiating edges, then the path of interest does not exist. The path which is generated by the initiating edge is the shortest valid path for a given initiating edge. We may add to this path incoming and outgoing tails in such a way that the path becomes longer. The tails should not contain initiating edges, because initiating edges generate their own paths. Any valid path is a path consisting of three parts (incoming tail, path of the initiating edge, outgoing tail) which are connected by edges without marks. In order to solve subproblem E2 we may count all tails and paths generated by initiating edges beforehand and then count the number of paths with a fixed length by dynamics.
diff --git a/editorials/332.md b/editorials/332.md
@@ -0,0 +1,47 @@
+Source: https://codeforces.com/blog/entry/8447
+
+Any suggestions, remarks and information about mistakes are welcomed. If you can improve the quality of this tutorial, please write me a private message :)
+
+**[332A - Down the Hatch!](/contest/332/problem/A "Codeforces Round 193 (Div. 2)")**
+
+Since *n* ≥ 4, one Vasya’s turn does not affect his other turns. Consequently, you should find just the number of positions (0-indexed) in the given string, which indexes are multiples of *n* and before which there are at least three same symbols.
+
+Asymptotics of the solution — *O*(|*s*|)
+
+[Code](http://pastebin.com/hn4wzXj0)
+
+**[332B - Maximum Absurdity](/contest/332/problem/B "Codeforces Round 193 (Div. 2)")**
+
+Let’s build the array of partial sums, which will permit to find the sum in any segment of the array in *O*(1). Let's iterate through the number *a* (the left edge of the leftmost segment) in descending order. Now we need to find among segments of length *k*, starting from position which index is greater than or equal to *a* + *k*, a segment with the maximum sum. Since we search *a* in descending order, we can maintain this segment during the transition from *a* to *a* - 1.
+
+Asymptotics of the solution — *O*(*n*).
+
+[Code](http://pastebin.com/FJrik8jC)
+
+**[332C - Students' Revenge](/contest/332/problem/C "Codeforces Round 193 (Div. 2)")**
+
+Let’s sort orders ascending *b**i*, and by equality of *b**i* — descending *a**i*. One can assume that in an optimal solution all the orders obeyed by the chairperson go in the sorted list after orders that she hasn’t obeyed (it may be wrong if there are several same orders, but it doesn’t affect parameters of an answer). Let’s iterate through *i* — the position of the first order in the sorted list, which the chairperson will obey. To the left of this order we should choose *p* - *k* orders which the chairperson won’t obey. As we should choose orders with the maximum sum of *b**i*, we can just choose *p* - *k* orders that immediately precede the *i*-th order. To the right of the *i*-th order we should choose *k* - 1 orders which the chairperson will obey. These orders should have the maximum sum of *a**i*. If we iterate *i* by descending, we can keep these *k* - 1 orders in some data structure that can perform basic operations with sets in logarithmic time (for example, multiset in C++).
+
+Asymptotics of the solution — *O*(*nlogn*)
+
+[Code](http://pastebin.com/CzB1v72v)
+
+**[332D - Theft of Blueprints](/contest/332/problem/D "Codeforces Round 193 (Div. 2)")**
+
+In the problem is given the weighted undirected graph without loops and multiple edges satisfying the following property: for every set *S* containing *k* vertices there is exactly one vertex adjacent to all vertices from this set (*) (this vertex is called “adjacent with *S*”). For any *k*-element set of vertices we can calculate the special characteristic: the sum of the weights of edges that connect vertices from *S* with vertex, adjacent with S. It is required to find the mathematical average of the characteristics of all *k*-element sets of vertices.
+
+One can solve this problem using the following fact (the proof is now available only in the Russian version of this post): if *k* ≥ 3, only complete graph containing *k* + 1 vertices satisfies the problem statement. For complete graphs answer is equal to doubled sum of weights of all edges, divided by *n*. The same way one can calculate answer if *k* = 1. Now let’s consider the case *k* = 2. Let’s iterate through the vertex *i* which is adjacent with our two-element set. Let’s write in ascending order all such numbers *j* that *c**i*, *j* ≠ - 1. Any two different vertices of this list form the set for which vertex *i* is adjacent, and there are no other such sets of vertices. Looking over all pairs of vertices in this list, we can add characteristics of all these sets to the answer. Since it’s guaranteed that the graph satisfies the property (*), each pair of vertices will be analyzed only once. A similar approach is used in the validator for this problem.
+
+Asymptotics of the solution — *O*(*n*2).
+
+[Code](http://pastebin.com/cdmkTAxA)
+
+**[332E - Binary Key](/contest/332/problem/E "Codeforces Round 193 (Div. 2)")**
+
+Let’s iterate through the number of ones in the key (*cnt*). One can note that *cnt* can’t be large than *min*(|*s*|, *k*), as the keys containing more than |*s*| ones can’t be lexicographically minimal.
+
+Let’s consider the solution of this problem with the fixed *cnt*. Any complete pass on the key corresponds to the extracting *cnt* of *k* scanned symbols of the container, i. e. container is divided into blocks of length *k*, and the message is divided into blocks of length *cnt* (last blocks may be shorter). We’ll number the characters in each block of the message from 0 to *cnt* - 1. We’ll call **(*q*, *j*)-suffix** suffix of *q*-th block of the message that starts from a position *j* in this block. Let’s solve the problem with dynamic programming: *d**i*, *j* is true if there exists a key, the first *i* characters of which are zeros and which corresponds to the extracting from container the string that is the result of concatenation of all (*q*, *j*)-suffixes of the message. The transitions are based on the filling of i-th position of the key with zero or one (we need to choose the minimum acceptable character). To restore the key you can keep chosen characters for each subtask.
+
+Asymptotics of the solution — *O*(*k*·|*s*|2 + |*p*|).
+
+[Code](http://pastebin.com/zPmfJJdV)
diff --git a/editorials/333.md b/editorials/333.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/8418
+
+[334A - Candy Bags](/contest/334/problem/A "Codeforces Round 194 (Div. 2)")
+
+In this problem one must divide all natural numbers from 1 to *n*2 to groups size of *n* with the same sums.
+
+Lets divide all this numbers to pairs 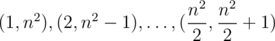. We can to do it since *n* is even and therefore *n*2 is even too. Then we can just make *n* groups consists of  of these pairs.
+
+[334B - Eight Point Sets](/contest/334/problem/B "Codeforces Round 194 (Div. 2)")
+
+In this problem you must to do only what's written — you must to define does this set of points sutisfies to decribed conditions.
+
+There are many ways to define it. For instance:
+
+1. Check if there are exactly 3 discinct *x*'s and *y*'s. One can put all *x*'s to set and then get it size to find amount of distinct *x*'s (as well as *y*'s). Then print ``ugly'' if this amount isn't equals to 3.
+2. Finally we have *x*1, *x*2 и *x*3 as well as *y*1, *y*2 и *y*3. Now lets check if for every pair (*x**i*, *y**j*) (except (*x*2, *y*2)) such point exist in given set of points.
+
+But I think that to read editoral of this problem is not good idea. It is better to just look at the implementation.
+
+[334C - Secrets](/contest/334/problem/C "Codeforces Round 194 (Div. 2)") / [333A - Secrets](/contest/333/problem/A "Codeforces Round 194 (Div. 1)")
+
+Actually we are looking for longest sequence of natural number *a*1, *a*2, ..., *a**k*, so that every number in it sequence is the power of three, sum of all numbers is more then *n* and if we remove any number sum will be less then *n*. To be precise we are looking for length of this sequence.
+
+Consider minimal number *a**i* = *A* in the sequence. All this numbers are divides to *A* since them all are powers of 3. And then, sum *S* of all this number is divides to *A* too. Suppose that *n* is divide to *A* too. Then, since *S* > *n*, then *S* - *A* ≥ *n*. And then if we remove *A* from sequence, sum of other number not less then *n* — contradist with second condition.
+
+Well, we now that *n* is not divide to none element in sequence. Now lets find minimal *k* so that 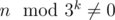, and answer is .
+
+[334D - Chips](/contest/334/problem/D "Codeforces Round 194 (Div. 2)") / [333B - Chips](/contest/333/problem/B "Codeforces Round 194 (Div. 1)")
+
+At first lets make two remarks:
+
+1. On every (vertical of horizontal) line we can put only one chip.
+2. If there is at least one forbidden cell on the line then we can't put chip on this line.
+
+Follow last remark we will avoid hits chip on forbidden cells. Lets avoid ``collisions'' of chips.
+
+Lets consider these four line: vertical lines number *i* and *n* + 1 - *i* and horizontal lines with the same numbers. Chips on these lines can collides together, but con't collides to another chip. Therefore we can solve the problem for these four line independently. And finally lets observe that we can put the chip on each of these lines without cillisions as well as on the picture.
+
+
+
+So, we can iterate all possible fours and put chip on every possible line. And don't fogot about case of two middle line in case of *n* is odd.
+
+[334E - Lucky Tickets](/contest/334/problem/E "Codeforces Round 194 (Div. 2)") / [333C - Lucky Tickets](/contest/333/problem/C "Codeforces Round 194 (Div. 1)")
+
+In this problem we can find the right amount of lucky tickets.
+
+Lets consider amount of different numbers we can get from one four-digit ticket number. It is easy to iterate all this tickets, since it amount only 104. It happened that we can get almost 60 numbers from ticket on the average.
+
+Suppose we can get number *x* from ticket *n*. It is clearly that either *x* - *k* ≥ 0 or *k* - *x* ≥ 0. If *k* - *x* ≥ 0 we can write eight-digit ticket number who will have *k* - *x* in the first four digits and *n* in the last four digits. It is clearly that such ticket is *k*-lucky. This method allows us to get almost 600 000 lucky tickets and it is enough.
+
+[333D - Characteristics of Rectangles](/contest/333/problem/D "Codeforces Round 194 (Div. 1)")
+
+In this problem we must to find maximal value of minimum of values on four intersections of two rows and two columns of table.
+
+In another words, we are looking for maximum value of *min*(*a**i*1, *j*1, *a**i*1, *j*2, *a**i*2, *j*1, *a**i*2, *j*2) for all *i*1, *i*2, *j*1, *j*2 such that 1 ≤ *i*1, *i*2 ≤ *n*, 1 ≤ *j*1, *j*2 ≤ *m*, *i*1 ≠ *i*2, *j*1 ≠ *j*2. Lets us binary search of the answer. For us it we must can define is there two rows and two colums with ones on all four its intersections; in other words, integers *i*1, *i*2, *j*1, *j*2 so that *a**i*1, *j*1 = *a**i*1, *j*2 = *a**i*2, *j*1 = *a**i*2, *j*2 = 1.
+
+Lets consider all pair of natural numbers (*i*1, *i*2) so that there exist nutural number *j* so that *a**i*1, *j* = *a**i*2, *j* = 1. Existence of two equals such pairs is equals to existence of above four numbers. But it is can be only  such pairs. Therefore we can make the array where we will mark pair who were meets. Lets iterate all pairs in any order until we meet repeated pair or pairs are ends. So we have solution of time .
+
+[333E - Summer Earnings](/contest/333/problem/E "Codeforces Round 194 (Div. 1)")
+
+In this problem it is need to draw three circle equals together with maximum possible radius with centers in given points. In another words it is need to find triangle wich minimum side is maximal.
+
+Unfortunately solution with bit optimize is not expected for us.
+
+Lets call to memory two simple geometric facts. Firstly, sum of alnges of trianle is equals to . Secondly, minimal angle is opposit to minimal side of triangle.
+
+Since, at leats one side of angles of triangle not less then  and this anlge is not least one. And side opposite to it is not least side. Therefore, if in  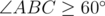 then *min*(|*AB*|, |*BC*|, |*CA*|) = *min*(|*AB*|, |*BC*|).
+
+And then lets do the follows. Lets iterate apex *B* and for each *B* lets find triangle with maximal minimum of sides when *B* is the apex of triangle and . For it lets sort all other points by the angle relative to *B*, and for each point *A* lets find point *C* most distant to *B* among such points that 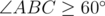. We have to use segment tree for maximum and two pointers or binary searsh to now left and right bound of possible points *C* during iterating *A*.
+
+Finally, we have solution of time .
diff --git a/editorials/334.md b/editorials/334.md
@@ -0,0 +1,71 @@
+Source: https://codeforces.com/blog/entry/8418
+
+[334A - Candy Bags](/contest/334/problem/A "Codeforces Round 194 (Div. 2)")
+
+In this problem one must divide all natural numbers from 1 to *n*2 to groups size of *n* with the same sums.
+
+Lets divide all this numbers to pairs 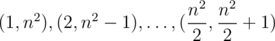. We can to do it since *n* is even and therefore *n*2 is even too. Then we can just make *n* groups consists of  of these pairs.
+
+[334B - Eight Point Sets](/contest/334/problem/B "Codeforces Round 194 (Div. 2)")
+
+In this problem you must to do only what's written — you must to define does this set of points sutisfies to decribed conditions.
+
+There are many ways to define it. For instance:
+
+1. Check if there are exactly 3 discinct *x*'s and *y*'s. One can put all *x*'s to set and then get it size to find amount of distinct *x*'s (as well as *y*'s). Then print ``ugly'' if this amount isn't equals to 3.
+2. Finally we have *x*1, *x*2 и *x*3 as well as *y*1, *y*2 и *y*3. Now lets check if for every pair (*x**i*, *y**j*) (except (*x*2, *y*2)) such point exist in given set of points.
+
+But I think that to read editoral of this problem is not good idea. It is better to just look at the implementation.
+
+[334C - Secrets](/contest/334/problem/C "Codeforces Round 194 (Div. 2)") / [333A - Secrets](/contest/333/problem/A "Codeforces Round 194 (Div. 1)")
+
+Actually we are looking for longest sequence of natural number *a*1, *a*2, ..., *a**k*, so that every number in it sequence is the power of three, sum of all numbers is more then *n* and if we remove any number sum will be less then *n*. To be precise we are looking for length of this sequence.
+
+Consider minimal number *a**i* = *A* in the sequence. All this numbers are divides to *A* since them all are powers of 3. And then, sum *S* of all this number is divides to *A* too. Suppose that *n* is divide to *A* too. Then, since *S* > *n*, then *S* - *A* ≥ *n*. And then if we remove *A* from sequence, sum of other number not less then *n* — contradist with second condition.
+
+Well, we now that *n* is not divide to none element in sequence. Now lets find minimal *k* so that 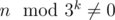, and answer is .
+
+[334D - Chips](/contest/334/problem/D "Codeforces Round 194 (Div. 2)") / [333B - Chips](/contest/333/problem/B "Codeforces Round 194 (Div. 1)")
+
+At first lets make two remarks:
+
+1. On every (vertical of horizontal) line we can put only one chip.
+2. If there is at least one forbidden cell on the line then we can't put chip on this line.
+
+Follow last remark we will avoid hits chip on forbidden cells. Lets avoid ``collisions'' of chips.
+
+Lets consider these four line: vertical lines number *i* and *n* + 1 - *i* and horizontal lines with the same numbers. Chips on these lines can collides together, but con't collides to another chip. Therefore we can solve the problem for these four line independently. And finally lets observe that we can put the chip on each of these lines without cillisions as well as on the picture.
+
+
+
+So, we can iterate all possible fours and put chip on every possible line. And don't fogot about case of two middle line in case of *n* is odd.
+
+[334E - Lucky Tickets](/contest/334/problem/E "Codeforces Round 194 (Div. 2)") / [333C - Lucky Tickets](/contest/333/problem/C "Codeforces Round 194 (Div. 1)")
+
+In this problem we can find the right amount of lucky tickets.
+
+Lets consider amount of different numbers we can get from one four-digit ticket number. It is easy to iterate all this tickets, since it amount only 104. It happened that we can get almost 60 numbers from ticket on the average.
+
+Suppose we can get number *x* from ticket *n*. It is clearly that either *x* - *k* ≥ 0 or *k* - *x* ≥ 0. If *k* - *x* ≥ 0 we can write eight-digit ticket number who will have *k* - *x* in the first four digits and *n* in the last four digits. It is clearly that such ticket is *k*-lucky. This method allows us to get almost 600 000 lucky tickets and it is enough.
+
+[333D - Characteristics of Rectangles](/contest/333/problem/D "Codeforces Round 194 (Div. 1)")
+
+In this problem we must to find maximal value of minimum of values on four intersections of two rows and two columns of table.
+
+In another words, we are looking for maximum value of *min*(*a**i*1, *j*1, *a**i*1, *j*2, *a**i*2, *j*1, *a**i*2, *j*2) for all *i*1, *i*2, *j*1, *j*2 such that 1 ≤ *i*1, *i*2 ≤ *n*, 1 ≤ *j*1, *j*2 ≤ *m*, *i*1 ≠ *i*2, *j*1 ≠ *j*2. Lets us binary search of the answer. For us it we must can define is there two rows and two colums with ones on all four its intersections; in other words, integers *i*1, *i*2, *j*1, *j*2 so that *a**i*1, *j*1 = *a**i*1, *j*2 = *a**i*2, *j*1 = *a**i*2, *j*2 = 1.
+
+Lets consider all pair of natural numbers (*i*1, *i*2) so that there exist nutural number *j* so that *a**i*1, *j* = *a**i*2, *j* = 1. Existence of two equals such pairs is equals to existence of above four numbers. But it is can be only  such pairs. Therefore we can make the array where we will mark pair who were meets. Lets iterate all pairs in any order until we meet repeated pair or pairs are ends. So we have solution of time .
+
+[333E - Summer Earnings](/contest/333/problem/E "Codeforces Round 194 (Div. 1)")
+
+In this problem it is need to draw three circle equals together with maximum possible radius with centers in given points. In another words it is need to find triangle wich minimum side is maximal.
+
+Unfortunately solution with bit optimize is not expected for us.
+
+Lets call to memory two simple geometric facts. Firstly, sum of alnges of trianle is equals to . Secondly, minimal angle is opposit to minimal side of triangle.
+
+Since, at leats one side of angles of triangle not less then  and this anlge is not least one. And side opposite to it is not least side. Therefore, if in  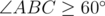 then *min*(|*AB*|, |*BC*|, |*CA*|) = *min*(|*AB*|, |*BC*|).
+
+And then lets do the follows. Lets iterate apex *B* and for each *B* lets find triangle with maximal minimum of sides when *B* is the apex of triangle and . For it lets sort all other points by the angle relative to *B*, and for each point *A* lets find point *C* most distant to *B* among such points that 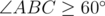. We have to use segment tree for maximum and two pointers or binary searsh to now left and right bound of possible points *C* during iterating *A*.
+
+Finally, we have solution of time .
diff --git a/editorials/335.md b/editorials/335.md
@@ -0,0 +1,165 @@
+Source: https://codeforces.com/blog/entry/8538
+
+This is the Editorial for [MemSQL start[c]up Round 2](/contest/326 "MemSQL start[c]up Round 2") and [MemSQL start[c]up Round 2 - онлайн-версия](/contest/335 "MemSQL start[c]up Round 2 - онлайн-версия"). Congratulations [RAD](/profile/RAD "Гроссмейстер RAD") for online round winner and [Petr](/profile/Petr "Международный гроссмейстер Petr") for onsite and overall score winner!
+
+This editorial is written jointly by the contest's coordinators (i.e., MemSQL engineers).
+
+[335A - Банан](/contest/335/problem/A "MemSQL start[c]up Round 2 - онлайн-версия") -- [AlexSkidanov](/profile/AlexSkidanov "Мастер AlexSkidanov")
+
+Reference solution: [Jimanbanashi](/profile/Jimanbanashi "Кандидат в мастера Jimanbanashi")'s [4222182](/contest/335/submission/4222182 "Посылка 4222182 от Jimanbanashi")
+
+Instead of calculating the smallest possible number of sheets given a fixed *n*, let us instead try to compute the smallest possible value of *n* given a fixed number of sheets. Let *k* denote the number of sheets. If a particular letter appears *p* times in *s*, then it must appear at least *ceil*(*p* / *k*) times in the sheet. Thus we can compute the smallest possible value of *n* by summing *ceil*(*p* / *k*) over all letters. Now the original problem can be solved using binary search on *k* (or brute force, since the constraints were small enough).
+
+[335B - Палиндром](/contest/335/problem/B "MemSQL start[c]up Round 2 - онлайн-версия") -- [AlexSkidanov](/profile/AlexSkidanov "Мастер AlexSkidanov")
+
+There’s a well known *O*(*n*2) solution that allows one to find a longest subsequence of a string which is a palindrome: for every pair of positions *l* and *r*, such that *l* ≤ *r*, find the length *d* of the longest palindrome subsequence between those positions.
+
+```
+d[l][r] = max(d[l][r-1], d[l + 1][r], s[l] == s[r] ? d[l + 1][r - 1] + 1 : 0).
+```
+
+There are two ways to solve this problem faster than O(*n*2) with the constraints given in the problem:
+
+1. Use dynamic programming. For every position *l* and length *k* find the leftmost position *r*, such that there’s a palindrome of length *k* in the substring of *s* starting at *l* and ending at *r*. For position *l* and length *k*
+
+```
+r[l][k] = min(r[l + 1][k], next(r[l + 1][k - 1], s[l])),
+```
+
+where next(pos, s) is the next occurrence of character *s* after position *pos*. Next can be precomputed for all the positions and all the characters in advance. See [DamianS](/profile/DamianS "Гроссмейстер DamianS")'s [4221965](/contest/335/submission/4221965 "Посылка 4221965 от DamianS").
+
+1. If length is less than 2600, use the well-known O(*n*2) dynamic programming approach. Otherwise by pigeonhole principle there’s at least one character that appears in the string at least 100 times -- find it and print it 100 times. See [SteamTurbine](/profile/SteamTurbine "Мастер SteamTurbine")'s [4224770](/contest/335/submission/4224770 "Посылка 4224770 от SteamTurbine").
+
+[335C - Графство и Королевство](/contest/335/problem/C "MemSQL start[c]up Round 2 - онлайн-версия") -- [AlexSkidanov](/profile/AlexSkidanov "Мастер AlexSkidanov")
+
+The most straightforward way to solve this problem is to use Grundy numbers. Define a segment as a maximal range of rows in which no cells have been reclaimed. Since segments have no bearing on other segments, they can be assigned Grundy numbers. There are 4 types of segments:
+
+1. The entire river.
+2. A section of river containing one of the ends.
+3. A section of river blocked at both ends in the same column
+4. A section of river blocked at both ends in different columns
+
+Each time a cell is reclaimed, it splits a segment into 2 segments (one of which may have size 0). We can compute the Grundy value for all possible segments in O(*r*2). Then after sorting the reclaimed cells by row number, we can find all segments and compute the Grundy number for the full state.
+
+See [Dmitry_Egorov](/profile/Dmitry_Egorov "Гроссмейстер Dmitry_Egorov")'s [4221888](/contest/335/submission/4221888 "Посылка 4221888 от Dmitry_Egorov").
+
+Alternatively, we can compute the result directly. Suppose the game is over. We can determine who won the game just by looking at the top row and the bottom row. Let us define “parity” as the modulo 2 remainder of (*r* + *n* + *c*0 + *c*1), where *c*0 is the column of the reclaimed cell with the lowest row, and *c*1 is the column of the reclaimed cell with the highest row. Claim: when the game is over, the parity is even. This can be seen by observing that the number of empty rows is equal to the number of times the column changes. In other words, if c0==c1, there are an even number of empty rows, otherwise an odd number of empty rows. Now, given r, c0, and c1, we can determine n, and therefore the winner.
+
+Let us consider the case where there are no reclaimed cells. If r is even, then the second city can win with a mirroring strategy. When the first city reclaims cell (a,b), the second city follows with (r+1-a,b). Similarly, if r is odd then the first city wins by a mirroring strategy, playing first in ((r+1)/2, 0), and subsequently following the strategy for even r.
+
+Now suppose there are reclaimed cells. Let us define *r*0 as the number of empty rows in the segment starting from one end, and *r*1 as the number of empty rows starting from the other end.
+
+Case 1: if r0==r1 and the parity is even, the state is losing. All available moves will either decrease r0, decrease r1, or make the parity odd. The other player can respond to the first two types of moves with a mirroring strategy, and the third by making the parity even again (there will always be such a move that doesn’t affect r0 or r1, based on the fact that the argument above).
+
+Case 2: if abs(r0-r1)>=2 then the state is winning. Suppose, without loss of generality, that r0-r1>=2. Then either of the cells (r1+1, 1) and (r1+1, 2) may be reclaimed, and one of them must lead to Case 1 (since they both result in r0==r1, and one will have even parity and the other odd).
+
+Case 3: if abs(r0-r1)<2 and the parity is odd, the state is winning. If r0==r1, then we can change the parity without affecting r0 or r1, leaving our opponent in Case 1. Otherwise, there is a unique move that leaves our opponent in Case 1.
+
+(note that cases 2 and 3 together imply that all states with odd parity are winning)
+
+Case 4: if abs(r0-r1)==1 and the parity is even, there is at most one move that doesn’t leave our opponent in Case 2 or Case 3. Suppose r0==r1+1. We must change either r0 or r1, since all other moves will change the parity to odd. Thus our only option is to decrease r0, since decreasing r1 would leave our opponent in Case 2. We could decrease r0 by 1, but doing so would change the parity. Thus we must decrease r0 by 2, and there is at most one move that does so and keeps the parity even. It follows that if floor(r0/2)+floor(r1/2) is even, then this is a losing position, otherwise a winning position.
+
+See [jill-jenn](/profile/jill-jenn "Специалист jill-jenn")'s extremely short [4225125](/contest/335/submission/4225125 "Посылка 4225125 от jill-jenn").
+
+[335D - Прямоугольники и Квадрат](/contest/335/problem/D "MemSQL start[c]up Round 2 - онлайн-версия") -- [AlexSkidanov](/profile/AlexSkidanov "Мастер AlexSkidanov")
+
+Even though constraints were allowing O(k^2) solutions, in this editorial we will describe an O(n log(n)) solution. This problem has a rather long solution, involving several very different ideas: On the first step, for every rectangle we want to determine, if we were to consider this rectangle as the top left corner of a square, how long could the top and left edge of the square be (see the picture).
+
+
+
+If there’s no rectangle that is adjacent to the current rectangle on the right, which has the same *y*1 coordinate, then the top edge length is just the width of the current rectangle. Otherwise it is the width of the current rectangle plus the max top edge computed for the rectangle adjacent on the right. Left edge length is computed likewise.
+
+When top and left edge lengths are computed, we want to compute the max bottom and right edge length if this rectangle was the bottom right corner of the square.
+
+On the second step, we want to find all possible square frames. Look at this picture to better understand what we mean by square frame:
+
+
+
+To find a frame, let’s sort all the points first by *x* - *y*, and then by *x* (or *y* -- both will yield the same result). This way all the points are sorted by the diagonal they belong to, and then by the position on that diagonal. Then we will maintain a stack of pairs (position, edge length), where edge length is min(top edge length, left edge length). Position could be either *x* or *y* (within a given diagonal relative differences in xs and ys are the same). Min edge length tells us what is the largest square that could start at that position.
+
+When we process a new point on a diagonal, first pop from the stack all the pairs such that their position + edge length is less than our position. If stack after that is empty, then the current point cannot be a bottom right corner of any square. If stack is not empty, then there could be some frames with the current point being bottom right corner.
+
+Here we need to make a very important observation. If a square frame is contained within some other square frame, we don’t need to consider the outer square frame, since if the outer square frame is then proves to be an actual square, then the inner frame also has to be an actual square, and it is enough to only check an inner frame.
+
+With this observation made, we can only check if the last point on the stack forms a frame with the current point, there’s no need to check any other point on the stack. Since we already know that last element on the stack reaches to the right and to the bottom further than our current position (otherwise we would have popped it from the stack), to see if we form a frame with that point it is enough to check if we can reach that far to the top and to the left. To do so, check, if position of the current point minus min(bottom edge length, right edge length) for the current point is smaller or equal than the position of the point that is at the top of the stack. If it is, we have a square frame.
+
+When we have a frame, we move to the third step, where we check if the frame is filled in. To do that we just want to check if area within that square that is filled in by rectangles is equal to the area of the square. For every corner of every rectangle we will compute the area covered by rectangles which are fully located to the left and top from that point. To do that we can sort all the corners by *x*, and then by *y*, and process them one by one. We will maintain an interval tree where value at every position *y* represents area covered by rectangles processed so far that are fully above *y*. Then when we process a corner, we first update the interval tree if the corner is a bottom right corner, and then query the interval tree to see the area covered by rectangles to the up and left from the current corner.
+
+Then, when we have these number precomputed, for every square frame *x*1, *y*1, *x*2, *y*2 we can just get the area for (*x*2, *y*2), add area for (*x*1, *y*1) and subtract for (*x*2, *y*1) and for (*x*1, *y*2). See the author ([AlexSkidanov](/profile/AlexSkidanov "Мастер AlexSkidanov"))'s [4234601](/contest/335/submission/4234601 "Посылка 4234601 от AlexSkidanov")
+
+A possible *O*(*k*2) solution is similar, but makes checking whether or not the frame is filled much and a bunch of other checks easier. See my [4234474](/contest/335/submission/4234474 "Посылка 4234474 от dolphinigle").
+
+[335E - Инвентаризация Небоскребов](/contest/335/problem/E "MemSQL start[c]up Round 2 - онлайн-версия") -- [pieguy](/profile/pieguy "Мастер pieguy")
+
+The skyscrapers in this problem depict a data structure called Skip List. Skip list is similar to AVL and red black trees in a sense that it allows O(log N) insertions, deletions and searches (including searching for lower and upper bounds), as well as moving to the next element in sorted order in constant time. Skiplist is different from any tree structures because it has a practical thread safe implementation without locks (so-called lock-free). Lock free skiplists are used as a main data structure to store data in MemSQL, and the algorithm that Bob uses to traverse the skyscrapers is an O(log N) approach, that allows one to estimate the size of the skiplist. Thus, if Bob ended up with an estimation of *n*, the actual skiplist size is expected to be *n* (so if the first line of the input file is Bob, one just needs to print the number from the second line to the output). Formal proof is rather simple, and is left to the reader. Curiously, the converse does not hold. If the skiplist size is *n*, the expected return value of the estimation algorithm could be bigger than *n*. For an *n* that is significantly bigger than 2*h* the estimate converges to *n* - 1 + 2*h*, but this problem included cases with smaller *n* as well.
+
+Let us build up the solution one level at a time. When *H* is 0, the expected sum is *N*. Now for each additional level, we can add the expected cost of the zip lines on that level, and subtract the expected cost of the zip lines immediately below them. In the end we’ll have the total expected cost.
+
+For some floor number *H*, let’s consider some left and right tower, and determine the probability that a zip line exists between them. Let *L* be the distance between the two towers. A potential zip line of length *L* and height *H* exists if the towers at both ends are tall enough (probability 1 / 2*H* for each one), and the *L* - 1 towers between them are all shorter (probability 1 - 1 / 2*H* for each). Thus the probability that such a zip line exists is 1 / 22 * *H* × (1 - 1 / 2*H*)*L* - 1.
+
+Now, assuming that such a zip line exists, what’s the expected number of zip lines immediately below it? This is simply one more than the number of towers of height *H* - 1. Each of the *L* - 1 towers has probability 1 / (2*H* - 1) of having height H-1 (given that it has height at most H-1) -- use conditional probability (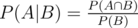) to calculate this. Thus the expected number of zip lines immediately below a zip line of length *L* and height *H* is 1 + (*L* - 1) / (2*H* - 1).
+
+For each length *L*, there are *N* - *L* possible zip lines with this length on each level. We multiply probability by cost for all possible zip lines to attain the expected value.
+
+The final answer is therefore
+
+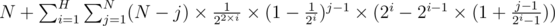
+
+It turns out the inner loop can be computed using matrix multiplication, for a running time of O(H log N). -- although the constraints is low enough that using matrix multiplication is an overkill -- O(H * N) will do.
+
+See the author ([pieguy](/profile/pieguy "Мастер pieguy"))'s [4234465](/contest/335/submission/4234465 "Посылка 4234465 от pieguy"). ...apparently this solution is much shorter than the "easier" problem's :)
+
+Congratulations [Petr](/profile/Petr "Международный гроссмейстер Petr") and [tourist](/profile/tourist "Легендарный гроссмейстер tourist") for the only persons solving this problem in-contest both on-site and off-site!
+
+[335F - Купи пирог, получи второй в подарок!](/contest/335/problem/F "MemSQL start[c]up Round 2 - онлайн-версия") -- [pieguy](/profile/pieguy "Мастер pieguy")
+
+This problem is equivalent to maximizing the total value of items that we can get for free.
+
+First, process the items into <#value, #number_of_items_with_that_value> tuples, which means we have #number_of_items_with_that_value items of value #value. Then, sort the tuples in descending order of #value.
+
+Iterate over those tuples and let #pieguy be an empty multi set()
+
+For each tuple <#val, #num>, we can calculate #max_free, the maximum number of items (not value) that we can get for free up to this point easily.
+
+So, we want to populate #pieguy so that it contains exactly #max_free “things”. #pieguy is special, in that we can compute the maximum price that we can get for free for n items by summing up the n most expensive items in #pieguy. How could #pieguy do that?
+
+For now, you may assume that each element of #pieguy contains the value of a single item that can be gotten for free. Thus, summing n items = value of n items that can be gotten for free. This is not correct, of course, since not all n arbitrary items can be simultaneously gotten for free in tandem, but we’ll come back to it later.
+
+We’re now at <#val, #num>, and we have #pieguy from previous iteration. #pieguy contains the previous #max_free elements. Assume that #num <= number of items more expensive than this value, for otherwise the remainder are ‘dead’ and useless for our current purpose. In particular, for the first tuple we process, we assume that #num is 0, since all of them cannot be gotten for free.
+
+Suppose we want to obtain exactly #max_free items. How many of the #num must we use?
+
+Let’s arrange the current members of #pieguy in descending order. For example, if #pieguy has 5 members:
+
+```
+A B C D E
+```
+
+Let’s arrange #num #val under #pieguy so that the rightmost one is located on position #max_free. For example, if #num is 6 and #max_free is 8 and #val is V....
+
+```
+A B C D E
+ V V V V V V
+```
+
+These 6 Vs will be competing for a spot in #pieguy.
+
+Now...
+
+1) what happens if C < V? This means, instead of making C free, we can make V free instead! (if you’re wondering why this is possible, remember that #pieguy definition I gave you was not entirely honest yet). So, we replace C, D and E with all Vs, and we get our new #pieguy! A B V V V V V V (this should be sorted again, but C++’s multiset does that automagically).
+
+2) otherwise, C > V. So, V cannot contend for the 3-th place in #pieguy, it has to contend for a place larger than or equal to the 4-th.
+
+Now the fun begins! If you want to contend for the 4-th place, any solution MUST HAVE AT LEAST 2 V s (remember that the 4-th place is used in a solution consisting of at least 4 free items). In general, if you want to contend for the #max_free — i -th place, you MUST HAVE AT LEAST #num — i Vs. #proof? is easy, exercise (i’m honest!)
+
+Okay, so back to contending for the 4-th place. If D is still > V, we proceed. Otherwise, we know that D < V. This means, E and any element after E is also < V! Thus, we can replace all elements after or equal to E with V! The problem would be the final element of #pieguy.
+
+When the final element of #pieguy is included in the sum, it is only included in the sum of all n elements of #pieguy. You do this when you want to calculate the maximum sum of values of free items you can get when getting exactly #max_free items. Any such solution must include all #num elements with value #val. We have included #num-2 Vs in #pieguy. Thus, the final element of #pieguy must somehow contains 2 Vs! So, elements of #pieguy actually can do this. Instead of containing a single elmeent, each element of #pieguy is more of an “operation” that adds several value and removes several value. In our case, we want to add 2 Vs and remove something. The something? The smallest element that we can remove (the ones that we haven't removed)! C! (if you're wondering why not D or E, it's because (again) #pieguy is special -- it only forms a solution if the most expensive t are summed, not if some are skipped. -- we cannot skip C if we want to use D).
+
+So, Insert 2V — C into #pieguy, and the rest, insert V into #pieguy. 2V — C is < V, so summing all elements of #pieguy correctly found out the max value when we receive #max_free free items!
+
+Right! Cool! ...except that 2V — C can be negative. Why would we want to insert negative stuffs into #pieguy? We don’t! Actually, we check if 2V — C is negative. If it is, we continue instead, and check 3V — C — D and so on, under the same reason.
+
+That’s it folks! I skipped some details of why this works (for example, that the number of V selected is always sufficient to guarantee solution in #pieguy), but they're easier to see once you get this large idea. The result is then #pieguy.last_element
+
+See [pieguy](/profile/pieguy "Мастер pieguy")'s beautiful [4234458](/contest/335/submission/4234458 "Посылка 4234458 от pieguy").
diff --git a/editorials/336.md b/editorials/336.md
@@ -0,0 +1,55 @@
+Source: https://codeforces.com/blog/entry/8574
+
+## [336A - Vasily the Bear and Triangle](/contest/336/problem/A "Codeforces Round 195 (Div. 2)")
+
+*val* = |*x*| + |*y*|. Then first point is (*val* * *sign*(*x*), 0), second — (0, *val* * *sign*(*y*)). Swap points if needed according to statement.
+
+Let's see why this is the answer. Conditions *x* ≠ 0 and *y* ≠ 0 give us that one point is on X-axis, and the other on Y-axis. Let's see how it works for *x* > 0 and *y* > 0. Other cases can be proved in similar way. We need to show, that (*x*, *y*) belongs to our triangle(including it's borders). In fact (*x*, *y*) belongs to segment, connecting (*x* + *y*, 0) with (0, *x* + *y*). Line through (*x* + *y*, 0) and (0, *x* + *y*) is *Y* = - *X* + *x* + *y*. Using coordinates (*x*, *y*) in this equation proves the statement.
+
+[Author's solution](http://pastebin.com/fNz05bHS)
+
+## [336B - Vasily the Bear and Fly](/contest/336/problem/B "Codeforces Round 195 (Div. 2)")
+
+Also you could iterate circles, adding distance for each of them and dividing by *m*2 in the end. Let's see how the *i*-th iteration works 1 ≤ *i* ≤ *m*. Distance to *m* + *i*-th circle is 2*R*. Distance to *m* + *j*-th circle, where |*j* - *i*| = 1, is . For other circles it's quite simple to calculate sum of distances. There are *i* - 2 circles which located to the left of current circle. So, sum of distances for these circles is 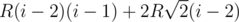. In the same manner we can calculate answer for cirlcles which are located to the right of the current circle
+
+
+
+[Author's solution](http://pastebin.com/iTr4213i)
+
+## [336C - Vasily the Bear and Sequence](/contest/336/problem/C "Codeforces Round 195 (Div. 2)")
+
+Let's check max beauty from 29 to 0. For every possible beauty *i* our aim is to find largest subset with such beauty. We will include in this subset all numbers, that have 1 at *i*-th bit. After that we do bitwise *and* as in statement, and if the resulting value is divisible by 2*i*, then there is the answer. Solution works in *O*(*n*).
+
+[Author's solution](http://pastebin.com/znNnQF1z)
+
+## [336D - Vasily the Bear and Beautiful Strings](/contest/336/problem/D "Codeforces Round 195 (Div. 2)")
+
+*any* — random binary string, *s* + *g* — concatenation of strings, *MOD* = 1000000007.
+
+String 1 + *any* always transforms into 0, string 1 — into 1. String 01 + *any* always transforms into 1, string 01 — into 0. String 001 + *any* transforms into 0, string 001 — into 1, and so on. Using these facts let's consider following solution.
+
+Cases like strings without ones or zeroes are easy. For every *i* (in zero-based numbering) let's assume that it is position of the first occurence of 1 in our string. Using already known facts we can understand what is the final result of transformations for such string. If the result equals to *g*, we add *C*(*cnt*[0] + *cnt*[1] - *i* - 1, *cnt*[1] - 1) to the answer. Calculation of binomial coefficients is following: *fact*[*i*] = *i*!%*MOD*, , *C*(*n*, *k*) = *fact*[*n*]*inv*(*fact*[*n* - *i*]*fact*[*i*]), where *inv*(*a*) — inverse element modulo *MOD*. *inv*(*a*) = *a**MOD* - 2, because *MOD* is prime number.
+
+[Author's solution](http://pastebin.com/2cZ2qefM)
+
+## [336E - Vasily the Bear and Painting Square](/contest/336/problem/E "Codeforces Round 195 (Div. 2)")
+
+Pretty tough problem. Consider following DP *dp*[*lvl*][*op*][*cur*][*type*] — number of ways to take *op* triangles, if we have 2*lvl* + 1 squares. *cur*, *type* — auxiliary values. Answer will be *dp*[*n*][*k*][0][2]*k*!. *type* means type of transitions we make. *cur* — amount of used quarters (*cur* = 4 — 2 quarters, *cur* < 4 — *cur* quarters). It is important to distinguish *cur* = 2 from *cur* = 4, because amount of consecutive pairs of unused quarters is different.
+
+
+
+About transitions. *type* = 2. Iterate amount of pairs (considering *cur*) of consecutive quarters that we will take. It is important for them to have no common quarters. We can get two pairs only in case *cur* = 0. Let's also take some quarters that are not in pairs. Calculate number of ways to select corresponding triangles and add to the current DP-state value *dp*[*lvl*][*op* - *choosen*][*newcur*][1] * *cntwaystochoose*. For better understanding of *type* = 2 check my solution (*calc*(*n*, *k*, *cur*, *type*) — *isfordp*[*n*][*k*][*cur*][*type*]).
+
+*type* = 1. Now we take triangles at the borders (number of squares is 2*lvl + 1). "at the borders" means marked X, see the picture.
+
+
+
+Iterate amount of pairs (considering *cur*) of consecutive triangles we take. It is important for pairs to have no common triangles. Let's also take some triangles that are not in pairs. Calculate number of ways to select corresponding triangles and add to the current DP-state value *dp*[*lvl*][*op* - *choosen*][*cur*][0] * *cntwaystochoose*.
+
+*type* = 0. We take triangles at the borders (number of squares is 2*lvl). "at the borders" means marked X, see the picture.
+
+
+
+Take some triangles, not in pairs. Calculate number of ways to select corresponding triangles and add to current DP-state value *dp*[*lvl* - 1][*op* - *choosen*][*cur*][2] * *cntwaystochoose*. Starting values: *dp*[0][0][*cur*][1] = 1, *dp*[0][*cnt*][*cur*][1] = 0, *cnt* > 0.
+
+[Author's solution](http://pastebin.com/z7zNRXHT)
diff --git a/editorials/337.md b/editorials/337.md
@@ -0,0 +1,105 @@
+Source: https://codeforces.com/blog/entry/8629
+
+## [337A - Puzzles](/contest/337/problem/A "Codeforces Round 196 (Div. 2)")
+
+First, let's sort the numbers `f[i]` in ascending order. Now assume that the smallest jigsaw puzzle which the teacher purchases consists of `f[k]` pieces. Obviously, she should buy the smallest `n` puzzles which are of size `f[k]` or greater to minimize the difference. These are the puzzles `f[k], f[k+1], ..., f[k+n-1]` (this is not correct when `f[i]` are not distinct and `f[k]=f[k-1]`, but such cases can be skipped). The difference between the greatest and the least size of the puzzles in such set is `f[k+n-1]-f[k]`.
+
+To choose the optimal `f[k]`, we can test every `k` between 1 and `m-n` and pick the one producing the least difference. The full algorithm is as follows:
+
+```
+read(n, m, f[1..m])
+sort(f[1..m])
+best = INFINITY
+for k = 1 to m-n
+ best = min(best, f[k+n-1] - f[k])
+print best
+```
+
+## [337B - Routine Problem](/contest/337/problem/B "Codeforces Round 196 (Div. 2)")
+
+Suppose that the width and height of the screen are `W` and `H` correspondingly. Since `W:H = a:b`, we have `H=W*b/a`. Similarly, the width and height of the film frame `w` and `h` are related as `h=w*d/c`. Imagine that Manao stretches/constricts the frame until it fits the screen horizontally or vertically, whichever happens first. There are three cases to consider: the horizontal to vertical ratio of the screen is less, equal or more than the corresponding ratio of the frame.
+
+In the first case (`a/b < c/d`) the stretching process ends when the frame reaches the same width as the screen. That is, the frame will enlarge in `W/w` times and its new width will be `W`. Thus, its new height is `h*W/w = w*c/d * W/w = W*d/c`. We are interested in the ratio of unoccupied portion of the screen to its full size, which is `(screen height - frame height) / (screen height) = (W*b/a - W*d/c) / (W*b/a) = (bc-ad)/bc`.
+
+In the second case (`a/b > c/d`) the process ends when the frame reaches the same height as the screen. Its height will become `H` and its width will become `w*H/h = w * W*b/a / (w*d/c) = W*b/a * c/d`. The unoccupied portion of the screen's horizontal is `(W - W*b/a * c/d)/W = (ad-bc)/ad`.
+
+In the third case, the frame fills the screen entirely and the answer will be 0.
+
+All that's left is to print the answer as an irreducible fraction. We need to find the greatest common divisor of its nominator and denominator for this. It can be done using [Euclidean algorithm](https://en.wikipedia.org/wiki/Euclidean_algorithm) or just through trial division by every number from 1 to `q`. Since `q` is no more than a product of two numbers from the input and these numbers are constrained by 1000, we need to try at most million numbers in the worst case.
+
+## [337C - Quiz](/contest/337/problem/C "Codeforces Round 196 (Div. 2)")
+
+Assume that Manao has doubled his score (i.e. gave `k` consecutive correct answers) exactly `X` times. Then the least possible score is obtained when this doublings happen in the beginning of the game, i.e., when he answers the first `X*k` questions and never manages to answer `k` consecutive questions after that. The correctness of this statement follows from the following: for any other scenario with `X` doublings, all of these doublings can be moved into the beginning and the total score will not increase. Hence, for `X=1` Manao's minimum score is `k*2+m-k`: he answers `k` consecutive questions, the score doubles, then he answers `m-k` questions. For `X=2` the minimum possible score is `(k*2+k)*2+m-2*k`, for `X=3` — `((k*2+k)*2+k)*2+m-3*k`. For the general case, a formula `(2^1+2^2+...+2^X)*k + m-X*k = (2^(X+1)-2)*k + m-X*k` is derived.
+
+The abovementioned observation shows that the minimum score grows monotonically when `X` is increased, so all we need is to find the minimum feasible `X`. It should satisfy the inequalities `X*k <= n` and `X + (n - n mod k) / k * (k-1) + n mod k >= m`. More on the second inequality: Manao answered the first `X*k` questions, thus there are `n-X*k` left. Now he can answer at most `k-1` question from each `k` questions. If `k` divides `n-X*k` (which is the same as `k` divides `n`), the inequality becomes `X*k + (n-X*k) / k * (k-1) >= m`, but the remainder complicates it a bit: `X*k + (n - X*k - (n - X*k) mod k) / k * (k-1) + (n - X*k) mod k >= m`. This formula can be simplified to the one written earlier. So, the minimum `X` is equal to `max(0, m - (n - n mod k) / k * (k-1) - n mod k)`. You'll need [exponentiation by squaring](https://en.wikipedia.org/wiki/Exponentiation_by_squaring) to compute the score corresponding to this value of `X`. Thus, the overall complexity of this solution is `O(log(n))`.
+
+## [337D - Book of Evil](/contest/337/problem/D "Codeforces Round 196 (Div. 2)")
+
+Obviously, in graph theory language our problem is: given a tree with `n` vertices, `m` of which are marked, find the number of vertices which are at most distance `d` apart from each of the marked vertices.
+
+Let us hang the tree by some vertex `r`, that is, assume that it is a rooted tree with root in vertex `r`. Let us also rephrase the condition imposed on sought vertices: we need to count such vertices `v` that the maximum distance from `v` to a marked vertex is at most `d`.
+
+For any inner vertex `v`, the marked vertex which is the farthest from it is either in the subtree of `v` or outside it — in the latter case the path from `v` to the farthest marked vertex traverses the parent of `v`. Using this observation, we can recompute the distances to the farthest marked vertices when transiting from a vertex to its child.
+
+First, we will compute the distance from every vertex `v` to the farthest marked vertex within the subtree of `v`. Let us call this distance `distDown[v]`. The values of `distDown[]` can be computed in a single depth-first search: for each leaf of the tree this distance is either 0 (when the leaf is marked) or nominal negative infinity (when the leaf is not marked), and for each inner vertex `v` `distDown[v]=max(distDown[child1], distDown[child2], ..., distDown[childK])+1`, where `childi` are the children of `v`.
+
+Now we will compute the distances from each vertex to the farthest marked vertex outside its subtree. Let's denote this distance with `distUp[v]`. We will use DFS again to compute values of `distUp[]`. For the root, `distUp[r]` is equal to nominal negative infinity, and for any other vertex `v` there are two cases: either the farthest marked vertex is located in the subtree of `v`-s parent `p`, or it is even "farther", i.e., the path to it traverses vertex `p`-s parent. In the first case, the distance from `v` to such vertex is equal to `max(distDown[sibling1], ..., distDown[siblingK])+2`, where `siblingi` are the brothers (other children of the parent) of vertex `v`. In the second case, it is equal to `distUp[p]+1`. Thus, `distUp[v]` is equal to the maximum of these two values. Note that you need to be clever to perform the computations in the first case in overall linear time. For this, you can find the maximum `max1` and second maximum `max2` of values `distDown[sibling1], ..., distDown[siblingK]`. After that, when `distDown[v] < max1`, we have `max(distDown[sibling1], ..., distDown[siblingK])=max1`, otherwise we have `distDown[v] = max1` and `max(distDown[sibling1], ..., distDown[siblingK])=max2`.
+
+After computing `distDown[]` и `distUp[]`, it is easy to derive the answers: it is the count of such vertices `v` that `distDown[v] <= d && distUp[v] <= d`.
+
+You can check [4302127](/contest/337/submission/4302127 "Submission 4302127 by gojira") for an implementation of the described approach.
+
+## [337E - Divisor Tree](/contest/337/problem/E "Codeforces Round 196 (Div. 2)")
+
+Let us first show that in an optimal divisor tree only the root or a leaf can hold a value other than one of `a[i]`. Suppose that we have an inner vertex different from the root which holds a number `X` not equal to any of `a[i]`. Then we can exclude this vertex from the tree and tie its children to its parent without violating any of the tree's properties.
+
+Hence, our tree consists of the root, vertices with numbers `a[i]` tied to each other or to the root, and leaves, which are tied to vertices with numbers `a[i]` and contain these numbers' prime factorizations. The exception is the case when one of `a[i]` is written in root itself, and the case when some `a[i]`-s are prime themselves. Also note that in general case it's easy to count how many leaves the tree will have. This count is equal to the sum of exponents of primes in prime factorizations of those `a[i]`-s which are the children of the root.
+
+Since `N <= 8`, we can build all divisor trees which satisfy the observations we made. Let's sort numbers `a[i]` in descending order and recursively choose a parent for each of them from the vertices already present in the tree. Of course, tying a number `X` to some vertex `v` is only possible if the product of `X` and the numbers in children of `v` divides the number in `v` itself. For `a[1]`, we have a choice — we can make it the root of the tree or a child of the root (in this case the root will hold a nominal infinity which is divisible by any number). For every next `a[i]`, the choice is whether to tie it to the root or a vertex containing one of the previous numbers. Therefore, we only consider `O(N!)` trees in total.
+
+You can check [4302171](/contest/337/submission/4302171 "Submission 4302171 by gojira") for an implementation of this idea.
+
+## [338D - GCD Table](/contest/338/problem/D "Codeforces Round 196 (Div. 1)")
+
+Observation 1. If the sequence `a` occurs in table `G`, then it should occur in row `i = LCM(a[1], ..., a[k])`. The proof follows. It is clear that theoretically it may only occur in rows with numbers which are multiple to `i`, since the row number should divide by each of `a[index]`. Consider some a row with number `i*x`, where `x>1`. The rows `i` and `i*x` differ only in such elements `j` that `i*x` and `j` both divide by some `p^q` (where p is prime) which does not divide `i` (hence, `G(i*x, j)` is divisible by `p^q`). But none of the `a[index]` may divide by such `p^q`, since then `i` would be also divisible by it. Therefore, if `a` occurs in row `i*x`, then it does not intersect with index `j`. Since it can only reside on indices where `i` and `i*x` coincide, checking only the `i`-th row is enough. It also clear that if `i > n`, the answer is `NO`.
+
+Observation 2. The sought index `j` should satisfy the following modular linear equations system:
+
+```
+j = 0 (mod a[1])
+j + 1 = 0 (mod a[2])
+...
+j + l = 0 (mod a[l + 1])
+...
+j + k - 1 = 0 (mod a[k])
+
+<=>
+
+{j = -l (mod a[l + 1])}
+```
+
+In other words, `j + l` must divide by `a[l+1]` for each `l=0..k-1`.
+
+According to [Chinese Remainder Theorem](https://en.wikipedia.org/wiki/Chinese_remainder_theorem), such a system has a solution iff for each pair of indices `x, y (0 <= x, y <= k-1)` we have `-x = -y (mod GCD(a[x+1], a[y+1]))`. Let's denote `L = LCM(a[1], ..., a[k])`. If the system has a solution, then it is singular on interval `[0, L)` and all the other solutions are congruent to it modulo `L`. Suppose that we have found the minimum non-negative `j` which satisfies the given system. Then, if `a` occurs in `G`, it will start from the `j`-th element of the `i`-th row. Theoretically, it may begin at any index of form `j+x*L, x>=0`, but since `i = L`, we have `G(i, j+X*L) = GCD(i, j+X*i) = GCD(i, j)`. So it is sufficient to check whether the `k` consecutive elements which begin at index `j` in row `i` coincide with sequence `a`. It is also clear that when `j > m-k+1`, the answer is `NO`.
+
+Finally, let's consider how to solve a system of modular linear equations. We can use an auxiliary method which, given `r1, m1, r2, m2`, finds minimum `X` such that `X = r1 (mod m1)` and `X = r2 (mod m2)`, or determines that such number does not exist. Let `X = m1*x + r1`, then we have `m1*x + r1 = r2 (mod m2)`. This can be represented as a Diophantine equation `m1*x + m2*y = r2-r1` and solved using [Extended Euclidean Algorithm](https://en.wikipedia.org/wiki/Extended_Euclidean_algorithm). The least non-negative `x`, if it exists, yields the sought `X = m1*x + r1`. Now this method can be used to find the minimum `X1` which satisfies the first two equations. After that, we can say that we have a system with `k-1` equation, where the first two old equations are replaced with a new `j = X1 (mod LCM(a[1], a[2]))`, and repeat the same procedure again. After using this method `k-1` times, we obtain the solution to the whole system.
+
+Also note that the proposed solution does not require long arithmetics: — The computation of `LCM(a[1], ..., a[k])` can be implemented with a check before each multiplication: if the result will become larger than `n`, the answer is `NO`; — When it comes to solving the system of equations, we already know that `L <= n <= 10^12`, thus all the intermediate moduli will also obide to this constraint; — The Extended Euclidean Algorithm can find a solution in the same bounds as its inputs, so it will also use numbers up to 10^12.
+
+The overall complexity of the algorithm is `O(k logn)`.
+
+## [338E - Optimize!](/contest/338/problem/E "Codeforces Round 196 (Div. 1)")
+
+Decyphering Manao's pseudocode, we unearth the following problem: you are given arrays `a[1..n]` and `b[1..len]` and a number `h`. Consider each subarray of `a` of length `L`. Let us call it `s`. Count how many of them have the property that the elements of `b` can be shuffled in such a way that each sum `s[i]+b[i] (1<=i<=L)` is at least `h`.
+
+First, let's solve a problem for one subarray. That is, we need to determine whether the elements of two arrays `s` and `b` can be matched in such a way that each sum is `h` or more. We can do the following: for each element of `s`, find the least element of `b` such that the two's sum is at least `h`, and erase the corresponding element from `b`. If we managed to pair each of the elements from `s`, then the arrays hold the property. Note that the elements of `s` can be processed in any order. If both `s` and `b` are sorted, then the idea described can be implemented in linear time.
+
+We can not achieve better complexity when considering each subarray separately, so we will try to solve the problem for several subarrays at the same time. Suppose that `b` is already sorted. We choose some `X < len` and consider a subarray `a[i..i+X-1]`. Let's process all the numbers from this subarray, i.e., for each of them find the least `b[j]` which pairs up with this number and erase it from `b`. The whole processing can be done in time `O(n)` if we have a sorted version of `a` and the corresponding indices computed beforehand.
+
+Now we can find the answer for every subarray `s` of length `len` which begins in segment `[i-Y, i]` using `O(YlogY)` operations, where `Y=len-X`. For this, we just take the `Y` elements which are in `s` but not in `a[i..i+X-1]` and process them against the numbers left in `b`. If each of them has been paired, then subarray `s` holds the required property, otherwise it does not. Moreover, since the subarrays we consider are overlapping, we can optimize even further and obtain amortized `O(Y)` complexity per subarray. To understand this, note that for processing a subarray in `O(Y)` time we only need to obtain its sorted version (to be more specific, the sorted version of the portion which does not overlap with `a[i..i+X-1]`). For the leftmost subarray we consider, we can sort its elements in usual way. For every next subarray (which differs from its predecessor in exactly two elements) we only need `O(Y)` operations to obtain its sorted version by updating the information from the previous subarray. Thus we have complexity `O(YlogY + Y^2)` of processing `Y` segments in total, which gives `O(Y)` per segment on average.
+
+Now let us take a look at the full picture. To process all subarrays of length `len`, we need to use the method given above for each of the segments `a[Y..Y+len-1], a[2Y+1..2Y+len], a[3Y+2..3Y+len+1], ...`. Therefore, we have `O(N/Y)` iterations of algorithm with comlexity `O(N+Y^2)`. We need to find a value of `Y` that minimizes `N*N/Y + N*Y`, which is `Y=~sqrt(N)`. The overall complexity is `O(Nsqrt(N))`. However, we need to consider the case `len < sqrt(N)` separately, since then `Y = len - X < len`. In this case, the problem can be solved in time `O(N*len)` with ideas similar to those described above.
+
+You can check the implementation of this idea in [4302344](/contest/338/submission/4302344 "Submission 4302344 by gojira").
+
+P.S. The statement of the "problem" that Manao is solving actually contains a Georgian fairy tale. You can copy almost the same text from [here](http://kartuli-zgaprebi.narod.ru/sami_tyuilis_zgapari.htm) and try to guess what he tale is about :)
diff --git a/editorials/338.md b/editorials/338.md
@@ -0,0 +1,105 @@
+Source: https://codeforces.com/blog/entry/8629
+
+## [337A - Puzzles](/contest/337/problem/A "Codeforces Round 196 (Div. 2)")
+
+First, let's sort the numbers `f[i]` in ascending order. Now assume that the smallest jigsaw puzzle which the teacher purchases consists of `f[k]` pieces. Obviously, she should buy the smallest `n` puzzles which are of size `f[k]` or greater to minimize the difference. These are the puzzles `f[k], f[k+1], ..., f[k+n-1]` (this is not correct when `f[i]` are not distinct and `f[k]=f[k-1]`, but such cases can be skipped). The difference between the greatest and the least size of the puzzles in such set is `f[k+n-1]-f[k]`.
+
+To choose the optimal `f[k]`, we can test every `k` between 1 and `m-n` and pick the one producing the least difference. The full algorithm is as follows:
+
+```
+read(n, m, f[1..m])
+sort(f[1..m])
+best = INFINITY
+for k = 1 to m-n
+ best = min(best, f[k+n-1] - f[k])
+print best
+```
+
+## [337B - Routine Problem](/contest/337/problem/B "Codeforces Round 196 (Div. 2)")
+
+Suppose that the width and height of the screen are `W` and `H` correspondingly. Since `W:H = a:b`, we have `H=W*b/a`. Similarly, the width and height of the film frame `w` and `h` are related as `h=w*d/c`. Imagine that Manao stretches/constricts the frame until it fits the screen horizontally or vertically, whichever happens first. There are three cases to consider: the horizontal to vertical ratio of the screen is less, equal or more than the corresponding ratio of the frame.
+
+In the first case (`a/b < c/d`) the stretching process ends when the frame reaches the same width as the screen. That is, the frame will enlarge in `W/w` times and its new width will be `W`. Thus, its new height is `h*W/w = w*c/d * W/w = W*d/c`. We are interested in the ratio of unoccupied portion of the screen to its full size, which is `(screen height - frame height) / (screen height) = (W*b/a - W*d/c) / (W*b/a) = (bc-ad)/bc`.
+
+In the second case (`a/b > c/d`) the process ends when the frame reaches the same height as the screen. Its height will become `H` and its width will become `w*H/h = w * W*b/a / (w*d/c) = W*b/a * c/d`. The unoccupied portion of the screen's horizontal is `(W - W*b/a * c/d)/W = (ad-bc)/ad`.
+
+In the third case, the frame fills the screen entirely and the answer will be 0.
+
+All that's left is to print the answer as an irreducible fraction. We need to find the greatest common divisor of its nominator and denominator for this. It can be done using [Euclidean algorithm](https://en.wikipedia.org/wiki/Euclidean_algorithm) or just through trial division by every number from 1 to `q`. Since `q` is no more than a product of two numbers from the input and these numbers are constrained by 1000, we need to try at most million numbers in the worst case.
+
+## [337C - Quiz](/contest/337/problem/C "Codeforces Round 196 (Div. 2)")
+
+Assume that Manao has doubled his score (i.e. gave `k` consecutive correct answers) exactly `X` times. Then the least possible score is obtained when this doublings happen in the beginning of the game, i.e., when he answers the first `X*k` questions and never manages to answer `k` consecutive questions after that. The correctness of this statement follows from the following: for any other scenario with `X` doublings, all of these doublings can be moved into the beginning and the total score will not increase. Hence, for `X=1` Manao's minimum score is `k*2+m-k`: he answers `k` consecutive questions, the score doubles, then he answers `m-k` questions. For `X=2` the minimum possible score is `(k*2+k)*2+m-2*k`, for `X=3` — `((k*2+k)*2+k)*2+m-3*k`. For the general case, a formula `(2^1+2^2+...+2^X)*k + m-X*k = (2^(X+1)-2)*k + m-X*k` is derived.
+
+The abovementioned observation shows that the minimum score grows monotonically when `X` is increased, so all we need is to find the minimum feasible `X`. It should satisfy the inequalities `X*k <= n` and `X + (n - n mod k) / k * (k-1) + n mod k >= m`. More on the second inequality: Manao answered the first `X*k` questions, thus there are `n-X*k` left. Now he can answer at most `k-1` question from each `k` questions. If `k` divides `n-X*k` (which is the same as `k` divides `n`), the inequality becomes `X*k + (n-X*k) / k * (k-1) >= m`, but the remainder complicates it a bit: `X*k + (n - X*k - (n - X*k) mod k) / k * (k-1) + (n - X*k) mod k >= m`. This formula can be simplified to the one written earlier. So, the minimum `X` is equal to `max(0, m - (n - n mod k) / k * (k-1) - n mod k)`. You'll need [exponentiation by squaring](https://en.wikipedia.org/wiki/Exponentiation_by_squaring) to compute the score corresponding to this value of `X`. Thus, the overall complexity of this solution is `O(log(n))`.
+
+## [337D - Book of Evil](/contest/337/problem/D "Codeforces Round 196 (Div. 2)")
+
+Obviously, in graph theory language our problem is: given a tree with `n` vertices, `m` of which are marked, find the number of vertices which are at most distance `d` apart from each of the marked vertices.
+
+Let us hang the tree by some vertex `r`, that is, assume that it is a rooted tree with root in vertex `r`. Let us also rephrase the condition imposed on sought vertices: we need to count such vertices `v` that the maximum distance from `v` to a marked vertex is at most `d`.
+
+For any inner vertex `v`, the marked vertex which is the farthest from it is either in the subtree of `v` or outside it — in the latter case the path from `v` to the farthest marked vertex traverses the parent of `v`. Using this observation, we can recompute the distances to the farthest marked vertices when transiting from a vertex to its child.
+
+First, we will compute the distance from every vertex `v` to the farthest marked vertex within the subtree of `v`. Let us call this distance `distDown[v]`. The values of `distDown[]` can be computed in a single depth-first search: for each leaf of the tree this distance is either 0 (when the leaf is marked) or nominal negative infinity (when the leaf is not marked), and for each inner vertex `v` `distDown[v]=max(distDown[child1], distDown[child2], ..., distDown[childK])+1`, where `childi` are the children of `v`.
+
+Now we will compute the distances from each vertex to the farthest marked vertex outside its subtree. Let's denote this distance with `distUp[v]`. We will use DFS again to compute values of `distUp[]`. For the root, `distUp[r]` is equal to nominal negative infinity, and for any other vertex `v` there are two cases: either the farthest marked vertex is located in the subtree of `v`-s parent `p`, or it is even "farther", i.e., the path to it traverses vertex `p`-s parent. In the first case, the distance from `v` to such vertex is equal to `max(distDown[sibling1], ..., distDown[siblingK])+2`, where `siblingi` are the brothers (other children of the parent) of vertex `v`. In the second case, it is equal to `distUp[p]+1`. Thus, `distUp[v]` is equal to the maximum of these two values. Note that you need to be clever to perform the computations in the first case in overall linear time. For this, you can find the maximum `max1` and second maximum `max2` of values `distDown[sibling1], ..., distDown[siblingK]`. After that, when `distDown[v] < max1`, we have `max(distDown[sibling1], ..., distDown[siblingK])=max1`, otherwise we have `distDown[v] = max1` and `max(distDown[sibling1], ..., distDown[siblingK])=max2`.
+
+After computing `distDown[]` и `distUp[]`, it is easy to derive the answers: it is the count of such vertices `v` that `distDown[v] <= d && distUp[v] <= d`.
+
+You can check [4302127](/contest/337/submission/4302127 "Submission 4302127 by gojira") for an implementation of the described approach.
+
+## [337E - Divisor Tree](/contest/337/problem/E "Codeforces Round 196 (Div. 2)")
+
+Let us first show that in an optimal divisor tree only the root or a leaf can hold a value other than one of `a[i]`. Suppose that we have an inner vertex different from the root which holds a number `X` not equal to any of `a[i]`. Then we can exclude this vertex from the tree and tie its children to its parent without violating any of the tree's properties.
+
+Hence, our tree consists of the root, vertices with numbers `a[i]` tied to each other or to the root, and leaves, which are tied to vertices with numbers `a[i]` and contain these numbers' prime factorizations. The exception is the case when one of `a[i]` is written in root itself, and the case when some `a[i]`-s are prime themselves. Also note that in general case it's easy to count how many leaves the tree will have. This count is equal to the sum of exponents of primes in prime factorizations of those `a[i]`-s which are the children of the root.
+
+Since `N <= 8`, we can build all divisor trees which satisfy the observations we made. Let's sort numbers `a[i]` in descending order and recursively choose a parent for each of them from the vertices already present in the tree. Of course, tying a number `X` to some vertex `v` is only possible if the product of `X` and the numbers in children of `v` divides the number in `v` itself. For `a[1]`, we have a choice — we can make it the root of the tree or a child of the root (in this case the root will hold a nominal infinity which is divisible by any number). For every next `a[i]`, the choice is whether to tie it to the root or a vertex containing one of the previous numbers. Therefore, we only consider `O(N!)` trees in total.
+
+You can check [4302171](/contest/337/submission/4302171 "Submission 4302171 by gojira") for an implementation of this idea.
+
+## [338D - GCD Table](/contest/338/problem/D "Codeforces Round 196 (Div. 1)")
+
+Observation 1. If the sequence `a` occurs in table `G`, then it should occur in row `i = LCM(a[1], ..., a[k])`. The proof follows. It is clear that theoretically it may only occur in rows with numbers which are multiple to `i`, since the row number should divide by each of `a[index]`. Consider some a row with number `i*x`, where `x>1`. The rows `i` and `i*x` differ only in such elements `j` that `i*x` and `j` both divide by some `p^q` (where p is prime) which does not divide `i` (hence, `G(i*x, j)` is divisible by `p^q`). But none of the `a[index]` may divide by such `p^q`, since then `i` would be also divisible by it. Therefore, if `a` occurs in row `i*x`, then it does not intersect with index `j`. Since it can only reside on indices where `i` and `i*x` coincide, checking only the `i`-th row is enough. It also clear that if `i > n`, the answer is `NO`.
+
+Observation 2. The sought index `j` should satisfy the following modular linear equations system:
+
+```
+j = 0 (mod a[1])
+j + 1 = 0 (mod a[2])
+...
+j + l = 0 (mod a[l + 1])
+...
+j + k - 1 = 0 (mod a[k])
+
+<=>
+
+{j = -l (mod a[l + 1])}
+```
+
+In other words, `j + l` must divide by `a[l+1]` for each `l=0..k-1`.
+
+According to [Chinese Remainder Theorem](https://en.wikipedia.org/wiki/Chinese_remainder_theorem), such a system has a solution iff for each pair of indices `x, y (0 <= x, y <= k-1)` we have `-x = -y (mod GCD(a[x+1], a[y+1]))`. Let's denote `L = LCM(a[1], ..., a[k])`. If the system has a solution, then it is singular on interval `[0, L)` and all the other solutions are congruent to it modulo `L`. Suppose that we have found the minimum non-negative `j` which satisfies the given system. Then, if `a` occurs in `G`, it will start from the `j`-th element of the `i`-th row. Theoretically, it may begin at any index of form `j+x*L, x>=0`, but since `i = L`, we have `G(i, j+X*L) = GCD(i, j+X*i) = GCD(i, j)`. So it is sufficient to check whether the `k` consecutive elements which begin at index `j` in row `i` coincide with sequence `a`. It is also clear that when `j > m-k+1`, the answer is `NO`.
+
+Finally, let's consider how to solve a system of modular linear equations. We can use an auxiliary method which, given `r1, m1, r2, m2`, finds minimum `X` such that `X = r1 (mod m1)` and `X = r2 (mod m2)`, or determines that such number does not exist. Let `X = m1*x + r1`, then we have `m1*x + r1 = r2 (mod m2)`. This can be represented as a Diophantine equation `m1*x + m2*y = r2-r1` and solved using [Extended Euclidean Algorithm](https://en.wikipedia.org/wiki/Extended_Euclidean_algorithm). The least non-negative `x`, if it exists, yields the sought `X = m1*x + r1`. Now this method can be used to find the minimum `X1` which satisfies the first two equations. After that, we can say that we have a system with `k-1` equation, where the first two old equations are replaced with a new `j = X1 (mod LCM(a[1], a[2]))`, and repeat the same procedure again. After using this method `k-1` times, we obtain the solution to the whole system.
+
+Also note that the proposed solution does not require long arithmetics: — The computation of `LCM(a[1], ..., a[k])` can be implemented with a check before each multiplication: if the result will become larger than `n`, the answer is `NO`; — When it comes to solving the system of equations, we already know that `L <= n <= 10^12`, thus all the intermediate moduli will also obide to this constraint; — The Extended Euclidean Algorithm can find a solution in the same bounds as its inputs, so it will also use numbers up to 10^12.
+
+The overall complexity of the algorithm is `O(k logn)`.
+
+## [338E - Optimize!](/contest/338/problem/E "Codeforces Round 196 (Div. 1)")
+
+Decyphering Manao's pseudocode, we unearth the following problem: you are given arrays `a[1..n]` and `b[1..len]` and a number `h`. Consider each subarray of `a` of length `L`. Let us call it `s`. Count how many of them have the property that the elements of `b` can be shuffled in such a way that each sum `s[i]+b[i] (1<=i<=L)` is at least `h`.
+
+First, let's solve a problem for one subarray. That is, we need to determine whether the elements of two arrays `s` and `b` can be matched in such a way that each sum is `h` or more. We can do the following: for each element of `s`, find the least element of `b` such that the two's sum is at least `h`, and erase the corresponding element from `b`. If we managed to pair each of the elements from `s`, then the arrays hold the property. Note that the elements of `s` can be processed in any order. If both `s` and `b` are sorted, then the idea described can be implemented in linear time.
+
+We can not achieve better complexity when considering each subarray separately, so we will try to solve the problem for several subarrays at the same time. Suppose that `b` is already sorted. We choose some `X < len` and consider a subarray `a[i..i+X-1]`. Let's process all the numbers from this subarray, i.e., for each of them find the least `b[j]` which pairs up with this number and erase it from `b`. The whole processing can be done in time `O(n)` if we have a sorted version of `a` and the corresponding indices computed beforehand.
+
+Now we can find the answer for every subarray `s` of length `len` which begins in segment `[i-Y, i]` using `O(YlogY)` operations, where `Y=len-X`. For this, we just take the `Y` elements which are in `s` but not in `a[i..i+X-1]` and process them against the numbers left in `b`. If each of them has been paired, then subarray `s` holds the required property, otherwise it does not. Moreover, since the subarrays we consider are overlapping, we can optimize even further and obtain amortized `O(Y)` complexity per subarray. To understand this, note that for processing a subarray in `O(Y)` time we only need to obtain its sorted version (to be more specific, the sorted version of the portion which does not overlap with `a[i..i+X-1]`). For the leftmost subarray we consider, we can sort its elements in usual way. For every next subarray (which differs from its predecessor in exactly two elements) we only need `O(Y)` operations to obtain its sorted version by updating the information from the previous subarray. Thus we have complexity `O(YlogY + Y^2)` of processing `Y` segments in total, which gives `O(Y)` per segment on average.
+
+Now let us take a look at the full picture. To process all subarrays of length `len`, we need to use the method given above for each of the segments `a[Y..Y+len-1], a[2Y+1..2Y+len], a[3Y+2..3Y+len+1], ...`. Therefore, we have `O(N/Y)` iterations of algorithm with comlexity `O(N+Y^2)`. We need to find a value of `Y` that minimizes `N*N/Y + N*Y`, which is `Y=~sqrt(N)`. The overall complexity is `O(Nsqrt(N))`. However, we need to consider the case `len < sqrt(N)` separately, since then `Y = len - X < len`. In this case, the problem can be solved in time `O(N*len)` with ideas similar to those described above.
+
+You can check the implementation of this idea in [4302344](/contest/338/submission/4302344 "Submission 4302344 by gojira").
+
+P.S. The statement of the "problem" that Manao is solving actually contains a Georgian fairy tale. You can copy almost the same text from [here](http://kartuli-zgaprebi.narod.ru/sami_tyuilis_zgapari.htm) and try to guess what he tale is about :)
diff --git a/editorials/339.md b/editorials/339.md
@@ -0,0 +1,45 @@
+Source: https://codeforces.com/blog/entry/8725
+
+[339A - Helpful Maths](/contest/339/problem/A "Codeforces Round 197 (Div. 2)")
+
+Tutorial by [Fefer_Ivan](/profile/Fefer_Ivan "Candidate Master Fefer_Ivan")
+
+To solve this problem we can count the number of digits 1, 2 and 3 in the input. If there are *c*1 digits 1, *c*2 digits 2 and *c*3 digits 3. Then we must print the sequence of *c*1 digits 1, *c*2 digits 2 and *c*3 digits 3. Digits must be separated by + sign.
+
+[339B - Xenia and Ringroad](/contest/339/problem/B "Codeforces Round 197 (Div. 2)")
+
+Tutorial by [Fefer_Ivan](/profile/Fefer_Ivan "Candidate Master Fefer_Ivan")
+
+To solve this problem we must learn how to calculate fast enought the time, needed to travel between houses *a* and *b*. Let's consider the case when *a* ≤ *b*. Than Xenia needs *b* - *a* seconds to get from *a* to *b*. Otherwise *a* > *b*, Xenia will have to go thought house number 1. So she will need *n* - *a* + *b* seconds.
+
+[339C - Xenia and Weights](/contest/339/problem/C "Codeforces Round 197 (Div. 2)")
+
+Tutorial by [Fefer_Ivan](/profile/Fefer_Ivan "Candidate Master Fefer_Ivan")
+
+Let's consider the definition of balance. Balance is the difference between sum of all weights on the left pan and sum of all weights on the right pan. At the beginning balance is equal to 0. Att each step Xenia puts one weight on the pan. It means she adds to or substracts from balance integer from 1 to 10. In each odd step, the integer is added and in each even step the integer is subtracted. From the statement we know, that after each step, balance must change it sign and must not be equal to 0. So if after some step the absolute value of balance is greater than 10, Xenia can not continue. Also, it is said in the statement that we can not use two equal weigths in a row. To solve the problem, let's consider a graph, where vertices are tuples of three numbers (*i*, *j*, *k*), where *i* is a current balance, *j* is a weight, used in the previous step, and *k* is the number of the current step. Arcs of the graph must correspond to Xenias actions, described in the statement. The solution of the problme is a path from vertex (0, 0, 1) to some vertex (*x*, *y*, *m*), where x, y are any numbers, and *m* is the requared number of steps.
+
+[339D - Xenia and Bit Operations](/contest/339/problem/D "Codeforces Round 197 (Div. 2)")
+
+Tutorial by [Gerald](/profile/Gerald "Master Gerald")
+
+The problem could be solved by using a typical data structure (segment tree).
+
+The leafs of the segment tree will store the values of *a**i*. At the vertices, the distance from which to the leafs is 1, we will store OR of the numbers from the leafs, which are the sons of this node in the segment tree. Similarly, vertices, the distance from which to the leafs is 2, we will store Xor of the numbers stored in their immediate sons. And so on. Then, the root of the tree will contain the required value *v*.
+
+There is no need to rebuild all the tree to perform an update operation. To do update, we should find a path from the root to the corresponding leaf and recalculate the values only at the tree vertices that are lying on that path. If everything is done correctly, then each update query will be executed in *O*(*n*) time. Also we need *O*(2*n*) memory.
+
+[339E - Three Swaps](/contest/339/problem/E "Codeforces Round 197 (Div. 2)")
+
+Tutorial by [Gerald](/profile/Gerald "Master Gerald")
+
+We will call the command *l*, *r* a reverse, also we will call the row of horses an array. Suddenly, right?
+
+The problem can be solved with clever bruteforcing all possible ways to reverse an array. To begin with, assume that the reverse with *l* = *r* is ok. Our solution can find an answer with such kind of reverses. It is clear that this thing doesn't affect the solution. Because such reverses can simply be erased from the answer.
+
+The key idea: reverses split an array into no more than seven segments of the original array. In other words, imagine that the array elements was originally glued together, and each reverse cuts a segment from the array. Then the array would be cut into not more than 7 pieces.
+
+Now you can come up with the wrong solution to the problem, and then come up with optimization that turns it into right. So, bruteforce all ways to cut array into 7 or less pieces. Then bruteforce reverse operations, but each reverse operation should contain only whole pieces. It is clear that this solution is correct, One thing it does not fit the TL.
+
+How to improve it? Note that the previous solution requires the exact partition of the array only at the very end of the bruteforce. It needed to check whether it is possible to get the given array *a*. So, let's assume that the array was originally somehow divided into 7 parts (we don't know the exact partition), the parts can be empty. Now try to bruteforce reverses as in naive solution. One thing, in the very end of bruteforce try to find such a partition of the array to get (with fixed reverses) the given array *a*.
+
+The search for such a partition can be done greedily (the reader has an opportunity to come up with it himself). Author's solution does this in time proportional to the number of parts, that is, 7 operations. However, this can be done for *O*(*n*) — this should fit in TL, if you write bruteforce carefully.
diff --git a/editorials/340.md b/editorials/340.md
@@ -0,0 +1,257 @@
+Source: https://codeforces.com/blog/entry/8755
+
+## [340A - The Wall](/contest/340/problem/A "Codeforces Round 198 (Div. 2)")
+
+You are given a range [*A*, *B*]. You're asked to compute fast how many numbers in the range are divisible by both *x* and *y*. I'll present here an *O*(*log*(*max*(*x*, *y*)) solution. We made tests low so other not optimal solutions to pass as well. The solution refers to the original problem, where *x*, *y* ≤ 109.
+
+Firstly, we can simplify the problem. Suppose we can calculate how many numbers are divisible in range [1, *X*] by both *x* and *y*. Can this solve our task? The answer is yes. All numbers in range [1, *B*] divisible by both numbers should be counted, except the numbers lower than *A* (1, 2, ..., A — 1). But, as you can see, numbers lower than A divisible by both numbers are actually numbers from range [1, A — 1]. So the answer of our task is f(B) — f(A — 1), where f(X) is how many numbers from 1, 2, ..., X are divisible by both x and y.
+
+For calculate in *O*(*log*(*max*(*x*, *y*)) the f(X) we need some math. If you don't know about it, please read firstly about least common multiple. Now, what will be the lowest number divisible by both x and y. The answer is least common multiple of x and y. Let's note it by *M*. The sequence of the numbers divisible by both x and y is *M*, 2 * *M*, 3 * *M* and so on. As a proof, suppose a number z is divisible by both x and y, but it is not in the above sequence. If a number is divisible by both x and y, it will be divisible by M also. If a number is divisible by M, it will be in the above sequence. Hence, the only way a number to be divisible by both x and y is to be in sequence *M*, 2 * *M*, 3 * *M*, ...
+
+The f(X) calculation reduces to finding the number of numbers from sequence *M*, 2 * *M*, 3 * *M*, ... lower or equal than X. It's obvious that if a number h * M is greater than X, so will be (h + 1) * M, (h + 2) * M and so on. We actually need to find the greatest integer number h such as *h* * *M* ≤ *X*. The numbers we're looking for will be 1 * *M*, 2 * *M*, ..., *h* * *M* (so their count will be *h*). The number h is actually [X / M], where [number] denotes the integer part of [number]. Take some examples on paper, you'll see why it's true.
+
+The only thing not discussed is how to calculate the number M given 2 number x and y. You can use this formula *M* = *x* * *y* / *gcd*(*x*, *y*). For calculate gcd(x, y) you can use Euclid's algorithm. Its complexity is *O*(*log*(*max*(*x*, *y*)), so this is the running time for the entire algorithm.
+
+Official solution: [4383403](/contest/340/submission/4383403 "Submission 4383403 by fchirica")
+
+## [340B - Maximal Area Quadrilateral](/contest/340/problem/B "Codeforces Round 198 (Div. 2)")
+
+I want to apologize for not estimating the real difficulty of this task. It turns out that it was more complicated than we thought it might be. Let's start explanation.
+
+Before reading this, you need to know what is signed area of a triangle (also called cross product or ccw function). Without it, this explanation will make no sense.
+
+The first thing we note is that a quadrilateral self intersecting won't have maximum area. I'll show you this by an image made by my "talents" in Paint :) As you can see, if a quadrilateral self intersects, it can be transformed into one with greater area.
+
+
+
+Each quadrilateral has 2 diagonals: connecting 1st and 3rd point and connecting 2nd and 4th point. A diagonal divides a plane into 2 subplanes. Suppose diagonal is AB. A point X can be in one of those two subplanes: that making cross product positive and that making cross product negative. A point is in "positive" subplane if ccw(X, A, B) > 0 and in "negative" subplane ccw(X, A, B) < 0. Note that according to the constraints of the task, ccw(X, A, B) will never be 0.
+
+Let's make now the key observation of the task. We have a quadrilateral. Suppose AB is one of diagonals and C and D the other points from quadrilateral different by A and B. If the current quadrilateral could have maximal area, then one of points from C and D needs to be in "positive subplane" of AB and the other one in "negative subplane". What would happen if C and D will be in the same subplane of AB? The quadrilateral will self intersect. If it will self intersect, it won't have maximal area. "A picture is worth a thousand words" — this couldn't fit better in this case :) Note that the quadrilateral from the below image is A-C-B-D-A.
+
+
+
+Out task reduces to fix a diagonal (this taking O(N ^ 2) time) and then choose one point from the positive and the negative subplane of the diagonal. I'll say here how to choose the point from the positive subplane. That from negative subplane can be chosen identically. The diagonal and 3rd point chosen form a triangle. As we want quadrilateral to have maximal area, we need to choose 3rd point such as triangle makes the maximal area. As the positive and negative subplanes are disjoint, the choosing 3rd point from each of them can be made independently. Hence we get O(N ^ 3) complexity. A tricky case is when you choose a diagonal but one of the subplanes is empty. In this case you have to disregard the diagonal and move to the next one.
+
+Official solution: [4383413](/contest/340/submission/4383413 "Submission 4383413 by fchirica")
+
+## [340C - Tourist Problem](/contest/340/problem/C "Codeforces Round 198 (Div. 2)")
+
+Despite this is a math task, the only math formula we'll use is that number of permutations with *n* elements is *n*!. From this one, we can deduce the whole task.
+
+The average formula is sum_of_all_routes / number_of_routes. As each route is a permutation with n elements, number_of_routes is *n*!. Next suppose you have a permutation of a: p1, p2, …, pn. The sum for it will be p1 + |p2 – p1| + … + |pn – pn-1|. The sum of routes will be the sum for each possible permutation.
+
+We can calculate sum_of_all routes in two steps: first time we calculate sums like “p1” and then we calculate sums like “|p2 – p1| + … + |pn – pn-1|” for every existing permutation.
+
+**First step** Each element of *a*1, *a*2, …, *a**n* can appear on the first position on the routes and needs to be added as much as it appears. Suppose I fixed an element X for the first position. I can fill positions 2, 3, .., n – 1 in (n – 1)! ways. Why? It is equivalent to permuting n – 1 elements (all elements except X). So sum_of_all = *a*1 * (n – 1)! + *a*2 * (n – 1)! + … * *a**n* * (n – 1)! = (n – 1)! * (*a*1 + *a*2 + … + *a**n*).
+
+**Second step** For each permutation, for each position j between 1 and n – 1 we need to compute |*p**j* — *p*(*j* + 1)|. Similarly to first step, we observe that only elements from *a* can appear on consecutive positions. We fix 2 indices i and j. We’re interested in how many permutations do *a**i* appear before *a**j*. We fix k such as on a permutation p, *a**i* appears on position k and *a**j* appears on a position k + 1. In how many ways can we fix this? n – 1 ways (1, 2, …, n – 1). What’s left? A sequence of (n – 2) elements which can be permuted independently. So the sum of second step is |*a**i* - *a**j*| * (n – 1) * (n – 2)!, for each i != j. If I note (*a*1 + *a*2 + … + *a**n*) by S1 and |*a**i* - *a**j*| for each i != j by S2, the answer is (N – 1)! * S1 + (N – 1)! * S2 / N!. By a simplification, the answer is (S1 + S2) / N.
+
+The only problem remained is how to calculate S2. Simple iteration won’t enter in time limit. Let’s think different. For each element, I need to make sum of differences between it and all smaller elements in the array a. As well, I need to make sum of all different between bigger elements than it and it. I’ll focus on the first part. I sort increasing array a. Suppose I’m at position *i*. I know that (i – 1) elements are smaller than *a**i*. The difference is simply (i — 1) * *a**i* — sum_of_elements_before_position_i. Sum of elements before position i can be computed when iterating i. Let’s call the obtained sum Sleft. I need to calculate now sum of all differences between an element and bigger elements than it. This sum is equal to Sleft. As a proof, for an element *a**i*, calculating the difference *a**j* — *a**i* when *a**j* > *a**i* is equivalent to calculating differences between *a**j* and a smaller element of it (in this case *a**i*). That’s why Sleft = Sright.
+
+As a conclusion, the answer is (S1 + 2 * Sleft) / N. For make fraction irreducible, you can use Euclid's algorithm. The complexity of the presented algorithm is *O*(*N* * *logN*), necessary due of sorting. Sorting can be implemented by count sort as well, having a complexity of O(maximalValue), but this is not necessary.
+
+Official solution: [4383420](/contest/340/submission/4383420 "Submission 4383420 by fchirica")
+
+## [340D - Bubble Sort Graph](/contest/340/problem/D "Codeforces Round 198 (Div. 2)")
+
+A good way to approach this problem is to notice that you can't build the graph. In worst case, the graph will be built in *O*(*N*2) complexity, which will time out. Also, notice that "maximal independent set" is a NP-Hard task, so even if you can build the graph you can't continue from there. So, the correct route to start is to think of graph's properties instead of building it. After sketching a little on the paper, you should find this property:
+
+**Lemma 1** Suppose we choose 2 indices i and j, such as i < j. We'll have an edge on the graph between vertices *a**i* and *a**j* if and only if *a**i* > *a**j*. We'll call that i and j form an inversion in the permutation.
+
+**Proof** We assume we know the proof that bubble sort does sort correctly an array. To proof lemma 1, we need to show two things.
+
+1. Every inversion will be swapped by bubble sort.
+2. For each i < j when *a**i* < *a**j*, bubble sort will NOT swap this elements.
+
+To proof 1, if bubble sort wouldn't swap an inversion, the sequence wouldn't be sorted. But we know that bubble sort always sorts a sequence, so all inversions will be swapped. Proofing 2 is trivial, just by looking at the code.
+
+So far we've got how the graph G is constructed. Let's apply it in maximal independent set problem.
+
+**Lemma 2** A maximal independent set of graph G is a longest increasing sequence for permutation a.
+
+**Proof**: Suppose we have a set of indices *i*1 < *i*2 < ... *ik* such as *a**i*1, *a**i*2, ..., *a**ik* form an independent set. Then, anyhow we'd choose *d* and *e*, there won't exist an edge between *a**id* and *a**ie*. According to proof 1, this only happens when *a**id* < *a**ie*. Hence, an independent set will be equivalent to an increasing sequence of permutation a. The maximal independent set is simply the maximal increasing sequence of permutation a.
+
+The task reduces to find longest increasing sequence for permutation *a*. This is a classical problem which can be solved in *O*(*N* * *logN*). [Here](//codeforces.com/blog/entry/8761) is an interesting discussion about how to do it.
+
+## [340E - Iahub and Permutations](/contest/340/problem/E "Codeforces Round 198 (Div. 2)")
+
+In this task, author's intended solution is an O(N ^ 2) dp. However, during testing [Gerald](/profile/Gerald "Master Gerald") fount a solution using principle of inclusion and exclusion. We've thought to keep both solutions. We're sorry if you say the problem was well-known, but for both me and the author of the task, it was first time we saw it.
+
+**Dynamic programming solution**
+
+After reading the sequence, we can find which elements are deleted. Suppose we have in a set D all deleted elements. I'll define from now on a "free position" a position which has -1 value, so it needs to be completed with a deleted element.
+
+We observe that some elements from D can appear on all free positions of permutation without creating a fixed point. The other elements from D can appear in all free positions except one, that will create the fixed point. It's intuitive that those two "classes" don't influence in the same way the result, so they need to be treated separated.
+
+So from here we can get the dp state. Let dp(n, k) = in how many ways can I fill (n + k) free positions, such as n elements from D can be placed anywhere in the free position and the other k elements can be placed in all free positions except one, which will create the fixed point. As we'll prove by the recurrences, we are not interested of the values from elements of D. Instead, we'll interested in their property: if they can(not) appear in all free positions.
+
+If k = 0, the problem becomes straight-forward. The answer for dp(n, 0) will be n!, as each permutation of (n + 0) = n numbers is valid, because all numbers can appear on all free positions. We can also calculate dp(n, 1). This means we are not allowed to place an element in a position out of (n + 1) free positions. However, we can place it in the other n positions. From now we get n elements which can be placed anywhere in the n free positions left. Hence, dp(n, 1) = n! * n.
+
+We want to calculate dp(n, k) now, k > 1. Our goal is to reduce the number k, until find something we know how to calculate. That is, when k becomes 0 or 1 problem is solved. Otherwise, we want to reduce the problem to a problem when k becomes 0 or 1. I have two cases. In a first case, I take a number from numbers which can be placed anywhere in order to reduce the numbers which can form fixed points. In the second case, I take a number from those which can form fixed points in order to make the same goal as in the first case. Let's analyze them.
+
+Case 1. Suppose X is the first free position, such as in the set of k numbers there exist one which cannot be placed there (because it will make a fixed point). Obviously, this position exist, otherwise k = 0. Also obviously, this position will need to be completed with a term when having a solution. In this case, I complete position X with one of n numbers. This will make number equal to X from the k numbers set to become a number which can be placed anywhere. So I "loose" one number which can be placed anywhere, but I also "gain" one. As well, I loose one number which can form a fixed point.
+
+Hence dp(n, k) += n * dp(n, k — 1).
+
+Case 2. In this case position X will be completed with one number from the k numbers set. All numbers which can form fixed points can appear there, except number having value equal to X. So there are k — 1 of them. I choose an arbitrary number Y from those k — 1 to place on the position X. This time I "loose" two numbers which could form fixed points: X and Y. As well, I "gain" one number which can be placed anywhere: X.
+
+Hence dp(n, k) += (k — 1) * dp(n + 1, k — 2).
+
+**TL;DR**
+
+dp[N][0]=N!
+
+dp[N][1]=N*dp[N][0]
+
+dp[N][K]=N*dp[N][K-1]+(K-1)*dp[N+1][K-2] for K>=2
+
+This recurrences can be computed by classical dp or by memoization. I'll present [DamianS](/profile/DamianS "Grandmaster DamianS")'s source, which used memoization. As you can see, it's very short and easy to implement. [Link](http://pastie.org/8286348)
+
+**Inclusion and exclusion principle**
+
+I'll present here an alternative to the dynamic programming solution. Let's calculate in *tot* the number of deleted numbers. Also, let's calculate in *fixed* the **maximal number of fixed points a permutation can have**. For calculate *fixed*, let's iterate with an index *i* each permutation position. We can have a fixed point on position *i* if element from position *i* was deleted (*a**i* = -1) and element i does not exist in sequence *a*. With other words, element *i* was deleted and now I want to add it back on position *i* to obtain maximal number of fixed points.
+
+We iterate now an index *i* from *fixed* to 0. Let sol[i] = the number of possible permutations having *exactly* *i* fixed points. Obviously, sol[0] is the answer to our problem. Let's introduce a [combination](https://en.wikipedia.org/wiki/Combination)  representing in how many ways I can choose k objects out of n. I have list of positions which can be transformed into fix points (they are *fixed* positions). I need to choose *i* of them. According to the above definition, I get sol[i] =  . Next, I have to fill *tot* - *i* positions with remained elements. We'll consider for this moment valid each permutation of not used values. So, sol[i] = 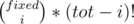 . Where is the problem to this formula?
+
+The problem is that it's possible, when permuting (tot — i) remained elements to be added, one (or more) elements to form more (new) fixed points. But if somehow I can exclude (subtract) the wrong choices from sol[i], sol[i] will be calculated correctly. I iterate another index *j* from i + 1 to *fixed*. For each j, I'll calculate how many permutations I considered in sol[i] having *i* fixed points but actually they have *j*. I'll subtract from sol[i] this value calculated for each j. If I do this, obviously sol[i] will be calculated correctly.
+
+Suppose we fixed a j. We know that exactly sol[j] permutations have j fixed points (as j > i, this value is calculated correctly). Suppose now I fix a permutation having j fixed points. For get the full result, I need to calculate for all sol[j] permutations. Happily, I can multiply result obtained for a single permutation with sol[j] and obtain the result for all permutations having j fixed points. So you have a permutation having j fixed points. The problem reduces to choosing i objects from a total of j. Why? Those i objects chosen are actually the positions considered in sol[i] to be ones having exactly i fixed points. But permutation has j fixed points. Quoting for above, "For each j, I'll calculate how many permutations I considered in sol[i] having *i* fixed points but actually they have *j*" . This is exactly what algorithm does.
+
+To sum up in a "LaTeX" way, 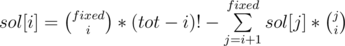
+
+We can compute binomial coefficients using Pascal's triangle. Using inclusion and exclusion principle, we get *O*(*N*2). Please note that there exist an *O*(*N*) solution for this task, using inclusion and exclusion principle, but it's not necessary to get AC. I'll upload [Gerald](/profile/Gerald "Master Gerald")'s source [here](http://pastie.org/8287332).
+
+## [341D - Iahub and Xors](/contest/341/problem/D "Codeforces Round 198 (Div. 1)")
+
+The motivation of the problem is that x ^ x = 0. x ^ x ^ x… ^ x (even times) = 0
+
+**Update per range, query per element**
+
+When dealing with complicated problems, it's sometimes a good idea to try solving easier versions of them. Suppose you can query only one element each time (x0 = x1, y0 = y1).
+
+To update a submatrix (x0, y0, x1, y1), I’ll do following operations. A[x0][y0] ^= val. A[x0][y1 + 1] ^= val. A[x1 + 1][y0] ^= val. A[x1 + 1][y1 + 1] ^= val.
+
+To query about an element (X, Y), that element’s value will be the xor sum of submatrix A(1, 1, X, Y). Let’s take an example. I have a 6x6 matrix and I want to xor all elements from submatrix (2, 2, 3, 4) with a value. The below image should be explanatory how the method works:
+
+
+
+Next, by (1, 1, X, Y) I’ll denote xor sum for this submatrix.
+
+“White” cells are not influenced by (2, 2, 3, 4) matrix, as matrix (1, 1, X, Y) with (X, Y) a white cell will never intersect it. “Red” cells are from the submatrix, the ones that need to be xor-ed. Note that for a red cell, (1, 1, X, Y) will contain the value we need to xor (as it will contain (2, 2)). Next, “blue” cells. For this ones (1, 1, X, Y) will contain the value we xor with, despite they shouldn’t have it. This is why both (2, 5) and (4, 2) will be xor-ed again by that value, to cancel the xor of (2, 2). Now it’s okay, every “blue” cell do not contain the xor value in their (1, 1, X, Y). Finally, the “green” cells. These ones are intersection between the 2 blue rectangles. This means, in their (1, 1, X, Y) the value we xor with appears 3 times (this means it is contained 1 time). For cancel this, we xor (4, 5) with the value. Now for every green cell (1, 1, X, Y) contains 4 equal values, which cancel each other.
+
+You need a data structure do to the following 2 operations:
+
+* Update an element (X, Y) (xor it with a value).
+* Query about xor sum of (1, 1, X, Y).
+
+Both operations can be supported by a Fenwick tree 2D. If you don't know this data structure, learn it and come back to this problem after you do this.
+
+**Coming back to our problem**
+
+Now, instead of finding an element, I want xor sum of a submatrix. You can note that xor sum of (x0, y0, x1, y1) is (1, 1, x1, y1) ^ (1, 1, x0 – 1, y1) ^ (1, 1, x1, y0 – 1) ^ (1, 1, x0 – 1, y0 – 1). This is a classical problem, the answer is (1, 1, x1, y1) from which I exclude what is not in the matrix: (1, 1, x0 – 1, y1) and (1, 1, x1, y0 – 1). Right now I excluded (1, 1, x0 – 1, y0 – 1) 2 times, so I need to add it one more time.
+
+How to get the xor sum of submatrix (1, 1, X, Y)? In brute force approach, I’d take all elements (x, y) with 1 <= x <= X and 1 <= y <= Y and xor their values. Recall the definition of the previous problem, each element (x, y) is the xor sum of A(1, 1, x, y). So the answer is xor sum of all xor sums of A(1, 1, x, y), with 1 <= x <= X and 1 <= y <= Y.
+
+We can rewrite that long xor sum. A number A[x][y] appears in exactly (X – x + 1) * (Y – y + 1) terms of xor sum. If (X – x + 1) * (Y – y + 1) is odd, then the value A[x][y] should be xor-ed to the final result exactly once. If (X — x + 1) * (Y — y + 1) is even, it should be ignored.
+
+Below, you'll find 4 pictures. They are matrixes with X lines and Y columns. Each picture represents a case: (X odd, Y odd) (X even, Y even) (X even Y odd) (X odd Y even). Can you observe a nice pattern? Elements colored represent those for which (X – x + 1) * (Y – y + 1) is odd.
+
+   
+
+Yep, that's right! There are 4 cases, diving the matrix into 4 disjoint areas. When having a query of form (1, 1, X, Y) you only need specific elements sharing same parity with X and Y. This method works in O(4 * logN * logN) for each operation and is the indented solution. We keep 4 Fenwick trees 2D. We made tests such as solutions having complexity greater than O(4 * logN * logN) per operation to fail.
+
+Here is our official solution: [4383473](/contest/341/submission/4383473 "Submission 4383473 by fchirica")
+
+## [341E - Candies Game](/contest/341/problem/E "Codeforces Round 198 (Div. 1)")
+
+**Key observation** Suppose you have 3 boxes containing A, B, C candies (A, B, C all greater than 0). Then, there will be always possible to empty one of boxes using some moves.
+
+**Proof** We can suppose that A <= B <= C. We need some moves such as the minimum from A, B, C will be zero. If we always keep the numbers in order A <= B <= C, it’s enough some moves such as A = 0. I’ll call this notation (A, B, C).
+
+How can we prove that always exist such moves? We can use reductio ad absurdum to prove it. Let’s suppose, starting from (A, B, C) we can go to a state (A2, B2, C2). We suppose A2 (A2 > 0) is minimal from every state we can obtain. Since A2 is minimal number of coins that can be obtained and A2 is not zero, the statement is equivalent with we can’t empty one chest from configuration (A, B, C). Then, we can prove that from (A2, B2, C2) we can go to a state (A3, B3, C3), where A3 < A2. Obviously, this contradicts our assumption that A2 is minimal of every possible states. If A2 would be minimal, then there won’t be any series of moves to empty one chest. But A2 isn’t minimal, hence there always exist some moves to empty one chest.
+
+Our algorithm so far:
+
+void emptyOneBox(int A, int B, int C) {
+
+if A is 0, then exit function.
+
+Make some moves such as to find another state (A2, B2, C2) with A2 < A.
+
+emptyOneBox (A2, B2, C2);
+
+}
+
+The only problem which needs to be proven now is: given a configuration (A, B, C) with A > 0, can we find another one (A2, B2, C2) such as A2 < A? The answer is always yes, below I’ll prove why.
+
+Firstly, let’s imagine we want to constantly move candies into a box. It doesn't matter yet from where come the candies, what matters is candies arrive into the box. The box has initially X candies. After 1 move, it will have 2 * X candies. After 2 moves, it will have 2 * (2 * X) candies = 4 * X candies. Generally, after K moves, the box will contain 2^K * X candies.
+
+We have A < B < C (if 2 numbers are equal, we can make a move and empty 1 box). If we divide B by A, we get from math that B = A * q + r. (obviously, always r < A). What if we can move exactly A * q candies from B to A? Then, our new state would be (r, B2, C2). We have now a number A2 = r, such as A2 < A.
+
+How can we move exactly A * q coins? Let’s write q in base 2. Making that, q will be written as a sum of powers of 2. Suppose lim is the maximum number such as 2 ^ lim <= q. We get every number k from 0 to lim. For each k, I push into the first box (the box containing initially A candies) a certain number of candies. As proven before, I'll need to push (2 ^ k) * A candies. Let's take a look at the k-th bit from binary representation of q. If k-th bit is 1, B will be written as following: B = A * (2 ^ k + 2 ^ (other_power_1) + 2 ^ (other_power_2) + ...) + r. Hence, I'll be able to move A * (2 ^ k) candies from "B box" to "A box". Otherwise, I'll move from "C box" to "A box". It will be always possible to do this move, as C > B and I could do that move from B, too.
+
+The proposed algorithm may look abstract, so let's take an example.
+
+Suppose A = 3, B = 905 and C = 1024. Can we get less than 3 for this state?
+
+B = 3 * 301 + 2. B = 3 * (100101101)2 + 2.
+
+K = 0: we need to move (2^0) * 3 coins into A. 0th bit of q is 1, so we can move from B to A.
+
+A = 6, B = 3 * (100101100)2 + 2 C = 1024
+
+K = 1: we need to move (2 ^ 1) * 3 coins into A. Since 1th bit of q is already 0, we have to move from C.
+
+A = 12, B = 3 * (100101100)2 + 2 C = 1018
+
+K = 2: we need to move (2 ^ 2) * 3 coins into A. 2nd bit of q is 1, so we can move from B.
+
+A = 24, B = 3 * (100101000)2 + 2 C = 1018
+
+K = 3: we need to move (2 ^ 3) * 3 coins into A. 3nd bit of q is 1, so we can move from B.
+
+A = 48, B = 3 * (100100000)2 + 2 C = 1018
+
+K = 4. we need to move (2 ^ 4) * 3 coins into A. 4th bit of q is 0, we need to move from C.
+
+A = 96, B = 3 * (100100000)2 + 2 C = 970
+
+K = 5. we need to move (2 ^ 5) * 3 coins into A. 5th bit of q is 1, so we need to move from B.
+
+A = 192, B = 3 * (100000000)2 + 2 C = 970
+
+K = 6 we need to move (2 ^ 6) * 3 coins into A. We mve them from C.
+
+A = 384 B = 3 * (100000000)2 + 2 C = 778
+
+K = 7 we need to move (2 ^ 7) * 3 coins into A. We move them from C
+
+A = 768 B = 3 * (100000000)2 + 2 C = 394
+
+K=8 Finally, we can move our last 1 bit from B to A.
+
+A = 1536 B = 3 * (000000000)2 + 2 C = 394
+
+A = 1536 B = (3 * 0 + 2) C = 394
+
+In the example, from (3, 905, 1024) we can arrive to (2, 394, 1536). Then, with same logic, we can go from (2, 394, 1536) to (0, X, Y), because 394 = 2 * 197 + 0.
+
+This is how you could write emptyOneBox() procedure. The remained problem is straight-forward: if initially there are zero or one boxes having candies, the answer is "-1". Otherwise, until there are more than 2 boxes having candies, pick 3 boxes arbitrary and apply emptyOneBox().
+
+Here is a source implementing the algorithm. [4383485](/contest/341/submission/4383485 "Submission 4383485 by fchirica")
+
+## BONUS
+
+Instead of a conclusion, I'll post here related problems to the ones used in the round. :) Please note that some of them might be more easier / complicated than level of difficulty used in the round. Feel free to think of them / ask help / discuss them in the comment section :)
+
+**Div2 A** Suppose *x*, *y*, *A*, *B* ≤ 109. Instead of being asked how many bricks are colored with both red and pink in range [*A*, *B*], you're asked how many bricks are colored with at least one color. After you solve this one, solve the same problem, but instead of having 2 persons painting, you have k persons (*k* ≤ 20). [Solution](//codeforces.com/blog/entry/8755#comment-144971) by [Enchom](/profile/Enchom "Candidate Master Enchom")
+
+**Div2 B** Given a very long list of special points, can you find quickly a convex special quadrilateral? Can you find very very quickly? :) Also, can you find maximal area of a special convex quadrilateral in time better than *O*(*N*4)? Solutions for [first problem](//codeforces.com/blog/entry/8755#comment-145790) and [second problem](//codeforces.com/blog/entry/8755#comment-145492) provided by [Xellos](/profile/Xellos "Candidate Master Xellos") and [Enchom](/profile/Enchom "Candidate Master Enchom")
+
+**Div2 D / Div1 B** Suppose the reverse problem. You are given a bubble sort graph having *N* vertices and *M* edges. Find its independent maximal set. Can you achieve *O*(*N*2) to do this? Does a solution in *O*((*N* + *M*) + *N* * *logN*) exist? [Solution](//codeforces.com/blog/entry/8755#comment-144890) by [CountZero](/profile/CountZero "Expert CountZero")
+
+**Div2 E / Div1 C** Find a solution running in liniar time. [Solution (dynamic programming)](//codeforces.com/blog/entry/8755#comment-144888) by [ivan100sic](/profile/ivan100sic "Candidate Master ivan100sic") . [Solution (inclusion exclusion principle)](//codeforces.com/blog/entry/8748#comment-144745) by [eduardische](/profile/eduardische "Candidate Master eduardische")
+
+**Div1 D** Suppose the 3D version of this problem. You have a 3D matrix and you perform same QUERY/UPDATE operations, but using 6 parameters (a submatrix is defined now all elements a[i][j][k] for which x0 <= i <= x1, y0 <= j <= y1, z0 <= k <= z1). Can you get a solution using *O*(*log*3 * *N*) per query, having constant 8? But for d dimensions, does an *O*(2*d* * (*log**d*)*n*) algorithm per query exist? :) [Solution](//codeforces.com/blog/entry/8755#comment-144896) by [Dwylkz](/profile/Dwylkz "Expert Dwylkz").
+
+**Div1 E** In our algorithm, we pick arbitrary 3 boxes. Can you find some heuristics of picking 3 boxes to reduce number of moves?
diff --git a/editorials/341.md b/editorials/341.md
@@ -0,0 +1,257 @@
+Source: https://codeforces.com/blog/entry/8755
+
+## [340A - The Wall](/contest/340/problem/A "Codeforces Round 198 (Div. 2)")
+
+You are given a range [*A*, *B*]. You're asked to compute fast how many numbers in the range are divisible by both *x* and *y*. I'll present here an *O*(*log*(*max*(*x*, *y*)) solution. We made tests low so other not optimal solutions to pass as well. The solution refers to the original problem, where *x*, *y* ≤ 109.
+
+Firstly, we can simplify the problem. Suppose we can calculate how many numbers are divisible in range [1, *X*] by both *x* and *y*. Can this solve our task? The answer is yes. All numbers in range [1, *B*] divisible by both numbers should be counted, except the numbers lower than *A* (1, 2, ..., A — 1). But, as you can see, numbers lower than A divisible by both numbers are actually numbers from range [1, A — 1]. So the answer of our task is f(B) — f(A — 1), where f(X) is how many numbers from 1, 2, ..., X are divisible by both x and y.
+
+For calculate in *O*(*log*(*max*(*x*, *y*)) the f(X) we need some math. If you don't know about it, please read firstly about least common multiple. Now, what will be the lowest number divisible by both x and y. The answer is least common multiple of x and y. Let's note it by *M*. The sequence of the numbers divisible by both x and y is *M*, 2 * *M*, 3 * *M* and so on. As a proof, suppose a number z is divisible by both x and y, but it is not in the above sequence. If a number is divisible by both x and y, it will be divisible by M also. If a number is divisible by M, it will be in the above sequence. Hence, the only way a number to be divisible by both x and y is to be in sequence *M*, 2 * *M*, 3 * *M*, ...
+
+The f(X) calculation reduces to finding the number of numbers from sequence *M*, 2 * *M*, 3 * *M*, ... lower or equal than X. It's obvious that if a number h * M is greater than X, so will be (h + 1) * M, (h + 2) * M and so on. We actually need to find the greatest integer number h such as *h* * *M* ≤ *X*. The numbers we're looking for will be 1 * *M*, 2 * *M*, ..., *h* * *M* (so their count will be *h*). The number h is actually [X / M], where [number] denotes the integer part of [number]. Take some examples on paper, you'll see why it's true.
+
+The only thing not discussed is how to calculate the number M given 2 number x and y. You can use this formula *M* = *x* * *y* / *gcd*(*x*, *y*). For calculate gcd(x, y) you can use Euclid's algorithm. Its complexity is *O*(*log*(*max*(*x*, *y*)), so this is the running time for the entire algorithm.
+
+Official solution: [4383403](/contest/340/submission/4383403 "Submission 4383403 by fchirica")
+
+## [340B - Maximal Area Quadrilateral](/contest/340/problem/B "Codeforces Round 198 (Div. 2)")
+
+I want to apologize for not estimating the real difficulty of this task. It turns out that it was more complicated than we thought it might be. Let's start explanation.
+
+Before reading this, you need to know what is signed area of a triangle (also called cross product or ccw function). Without it, this explanation will make no sense.
+
+The first thing we note is that a quadrilateral self intersecting won't have maximum area. I'll show you this by an image made by my "talents" in Paint :) As you can see, if a quadrilateral self intersects, it can be transformed into one with greater area.
+
+
+
+Each quadrilateral has 2 diagonals: connecting 1st and 3rd point and connecting 2nd and 4th point. A diagonal divides a plane into 2 subplanes. Suppose diagonal is AB. A point X can be in one of those two subplanes: that making cross product positive and that making cross product negative. A point is in "positive" subplane if ccw(X, A, B) > 0 and in "negative" subplane ccw(X, A, B) < 0. Note that according to the constraints of the task, ccw(X, A, B) will never be 0.
+
+Let's make now the key observation of the task. We have a quadrilateral. Suppose AB is one of diagonals and C and D the other points from quadrilateral different by A and B. If the current quadrilateral could have maximal area, then one of points from C and D needs to be in "positive subplane" of AB and the other one in "negative subplane". What would happen if C and D will be in the same subplane of AB? The quadrilateral will self intersect. If it will self intersect, it won't have maximal area. "A picture is worth a thousand words" — this couldn't fit better in this case :) Note that the quadrilateral from the below image is A-C-B-D-A.
+
+
+
+Out task reduces to fix a diagonal (this taking O(N ^ 2) time) and then choose one point from the positive and the negative subplane of the diagonal. I'll say here how to choose the point from the positive subplane. That from negative subplane can be chosen identically. The diagonal and 3rd point chosen form a triangle. As we want quadrilateral to have maximal area, we need to choose 3rd point such as triangle makes the maximal area. As the positive and negative subplanes are disjoint, the choosing 3rd point from each of them can be made independently. Hence we get O(N ^ 3) complexity. A tricky case is when you choose a diagonal but one of the subplanes is empty. In this case you have to disregard the diagonal and move to the next one.
+
+Official solution: [4383413](/contest/340/submission/4383413 "Submission 4383413 by fchirica")
+
+## [340C - Tourist Problem](/contest/340/problem/C "Codeforces Round 198 (Div. 2)")
+
+Despite this is a math task, the only math formula we'll use is that number of permutations with *n* elements is *n*!. From this one, we can deduce the whole task.
+
+The average formula is sum_of_all_routes / number_of_routes. As each route is a permutation with n elements, number_of_routes is *n*!. Next suppose you have a permutation of a: p1, p2, …, pn. The sum for it will be p1 + |p2 – p1| + … + |pn – pn-1|. The sum of routes will be the sum for each possible permutation.
+
+We can calculate sum_of_all routes in two steps: first time we calculate sums like “p1” and then we calculate sums like “|p2 – p1| + … + |pn – pn-1|” for every existing permutation.
+
+**First step** Each element of *a*1, *a*2, …, *a**n* can appear on the first position on the routes and needs to be added as much as it appears. Suppose I fixed an element X for the first position. I can fill positions 2, 3, .., n – 1 in (n – 1)! ways. Why? It is equivalent to permuting n – 1 elements (all elements except X). So sum_of_all = *a*1 * (n – 1)! + *a*2 * (n – 1)! + … * *a**n* * (n – 1)! = (n – 1)! * (*a*1 + *a*2 + … + *a**n*).
+
+**Second step** For each permutation, for each position j between 1 and n – 1 we need to compute |*p**j* — *p*(*j* + 1)|. Similarly to first step, we observe that only elements from *a* can appear on consecutive positions. We fix 2 indices i and j. We’re interested in how many permutations do *a**i* appear before *a**j*. We fix k such as on a permutation p, *a**i* appears on position k and *a**j* appears on a position k + 1. In how many ways can we fix this? n – 1 ways (1, 2, …, n – 1). What’s left? A sequence of (n – 2) elements which can be permuted independently. So the sum of second step is |*a**i* - *a**j*| * (n – 1) * (n – 2)!, for each i != j. If I note (*a*1 + *a*2 + … + *a**n*) by S1 and |*a**i* - *a**j*| for each i != j by S2, the answer is (N – 1)! * S1 + (N – 1)! * S2 / N!. By a simplification, the answer is (S1 + S2) / N.
+
+The only problem remained is how to calculate S2. Simple iteration won’t enter in time limit. Let’s think different. For each element, I need to make sum of differences between it and all smaller elements in the array a. As well, I need to make sum of all different between bigger elements than it and it. I’ll focus on the first part. I sort increasing array a. Suppose I’m at position *i*. I know that (i – 1) elements are smaller than *a**i*. The difference is simply (i — 1) * *a**i* — sum_of_elements_before_position_i. Sum of elements before position i can be computed when iterating i. Let’s call the obtained sum Sleft. I need to calculate now sum of all differences between an element and bigger elements than it. This sum is equal to Sleft. As a proof, for an element *a**i*, calculating the difference *a**j* — *a**i* when *a**j* > *a**i* is equivalent to calculating differences between *a**j* and a smaller element of it (in this case *a**i*). That’s why Sleft = Sright.
+
+As a conclusion, the answer is (S1 + 2 * Sleft) / N. For make fraction irreducible, you can use Euclid's algorithm. The complexity of the presented algorithm is *O*(*N* * *logN*), necessary due of sorting. Sorting can be implemented by count sort as well, having a complexity of O(maximalValue), but this is not necessary.
+
+Official solution: [4383420](/contest/340/submission/4383420 "Submission 4383420 by fchirica")
+
+## [340D - Bubble Sort Graph](/contest/340/problem/D "Codeforces Round 198 (Div. 2)")
+
+A good way to approach this problem is to notice that you can't build the graph. In worst case, the graph will be built in *O*(*N*2) complexity, which will time out. Also, notice that "maximal independent set" is a NP-Hard task, so even if you can build the graph you can't continue from there. So, the correct route to start is to think of graph's properties instead of building it. After sketching a little on the paper, you should find this property:
+
+**Lemma 1** Suppose we choose 2 indices i and j, such as i < j. We'll have an edge on the graph between vertices *a**i* and *a**j* if and only if *a**i* > *a**j*. We'll call that i and j form an inversion in the permutation.
+
+**Proof** We assume we know the proof that bubble sort does sort correctly an array. To proof lemma 1, we need to show two things.
+
+1. Every inversion will be swapped by bubble sort.
+2. For each i < j when *a**i* < *a**j*, bubble sort will NOT swap this elements.
+
+To proof 1, if bubble sort wouldn't swap an inversion, the sequence wouldn't be sorted. But we know that bubble sort always sorts a sequence, so all inversions will be swapped. Proofing 2 is trivial, just by looking at the code.
+
+So far we've got how the graph G is constructed. Let's apply it in maximal independent set problem.
+
+**Lemma 2** A maximal independent set of graph G is a longest increasing sequence for permutation a.
+
+**Proof**: Suppose we have a set of indices *i*1 < *i*2 < ... *ik* such as *a**i*1, *a**i*2, ..., *a**ik* form an independent set. Then, anyhow we'd choose *d* and *e*, there won't exist an edge between *a**id* and *a**ie*. According to proof 1, this only happens when *a**id* < *a**ie*. Hence, an independent set will be equivalent to an increasing sequence of permutation a. The maximal independent set is simply the maximal increasing sequence of permutation a.
+
+The task reduces to find longest increasing sequence for permutation *a*. This is a classical problem which can be solved in *O*(*N* * *logN*). [Here](//codeforces.com/blog/entry/8761) is an interesting discussion about how to do it.
+
+## [340E - Iahub and Permutations](/contest/340/problem/E "Codeforces Round 198 (Div. 2)")
+
+In this task, author's intended solution is an O(N ^ 2) dp. However, during testing [Gerald](/profile/Gerald "Master Gerald") fount a solution using principle of inclusion and exclusion. We've thought to keep both solutions. We're sorry if you say the problem was well-known, but for both me and the author of the task, it was first time we saw it.
+
+**Dynamic programming solution**
+
+After reading the sequence, we can find which elements are deleted. Suppose we have in a set D all deleted elements. I'll define from now on a "free position" a position which has -1 value, so it needs to be completed with a deleted element.
+
+We observe that some elements from D can appear on all free positions of permutation without creating a fixed point. The other elements from D can appear in all free positions except one, that will create the fixed point. It's intuitive that those two "classes" don't influence in the same way the result, so they need to be treated separated.
+
+So from here we can get the dp state. Let dp(n, k) = in how many ways can I fill (n + k) free positions, such as n elements from D can be placed anywhere in the free position and the other k elements can be placed in all free positions except one, which will create the fixed point. As we'll prove by the recurrences, we are not interested of the values from elements of D. Instead, we'll interested in their property: if they can(not) appear in all free positions.
+
+If k = 0, the problem becomes straight-forward. The answer for dp(n, 0) will be n!, as each permutation of (n + 0) = n numbers is valid, because all numbers can appear on all free positions. We can also calculate dp(n, 1). This means we are not allowed to place an element in a position out of (n + 1) free positions. However, we can place it in the other n positions. From now we get n elements which can be placed anywhere in the n free positions left. Hence, dp(n, 1) = n! * n.
+
+We want to calculate dp(n, k) now, k > 1. Our goal is to reduce the number k, until find something we know how to calculate. That is, when k becomes 0 or 1 problem is solved. Otherwise, we want to reduce the problem to a problem when k becomes 0 or 1. I have two cases. In a first case, I take a number from numbers which can be placed anywhere in order to reduce the numbers which can form fixed points. In the second case, I take a number from those which can form fixed points in order to make the same goal as in the first case. Let's analyze them.
+
+Case 1. Suppose X is the first free position, such as in the set of k numbers there exist one which cannot be placed there (because it will make a fixed point). Obviously, this position exist, otherwise k = 0. Also obviously, this position will need to be completed with a term when having a solution. In this case, I complete position X with one of n numbers. This will make number equal to X from the k numbers set to become a number which can be placed anywhere. So I "loose" one number which can be placed anywhere, but I also "gain" one. As well, I loose one number which can form a fixed point.
+
+Hence dp(n, k) += n * dp(n, k — 1).
+
+Case 2. In this case position X will be completed with one number from the k numbers set. All numbers which can form fixed points can appear there, except number having value equal to X. So there are k — 1 of them. I choose an arbitrary number Y from those k — 1 to place on the position X. This time I "loose" two numbers which could form fixed points: X and Y. As well, I "gain" one number which can be placed anywhere: X.
+
+Hence dp(n, k) += (k — 1) * dp(n + 1, k — 2).
+
+**TL;DR**
+
+dp[N][0]=N!
+
+dp[N][1]=N*dp[N][0]
+
+dp[N][K]=N*dp[N][K-1]+(K-1)*dp[N+1][K-2] for K>=2
+
+This recurrences can be computed by classical dp or by memoization. I'll present [DamianS](/profile/DamianS "Grandmaster DamianS")'s source, which used memoization. As you can see, it's very short and easy to implement. [Link](http://pastie.org/8286348)
+
+**Inclusion and exclusion principle**
+
+I'll present here an alternative to the dynamic programming solution. Let's calculate in *tot* the number of deleted numbers. Also, let's calculate in *fixed* the **maximal number of fixed points a permutation can have**. For calculate *fixed*, let's iterate with an index *i* each permutation position. We can have a fixed point on position *i* if element from position *i* was deleted (*a**i* = -1) and element i does not exist in sequence *a*. With other words, element *i* was deleted and now I want to add it back on position *i* to obtain maximal number of fixed points.
+
+We iterate now an index *i* from *fixed* to 0. Let sol[i] = the number of possible permutations having *exactly* *i* fixed points. Obviously, sol[0] is the answer to our problem. Let's introduce a [combination](https://en.wikipedia.org/wiki/Combination)  representing in how many ways I can choose k objects out of n. I have list of positions which can be transformed into fix points (they are *fixed* positions). I need to choose *i* of them. According to the above definition, I get sol[i] =  . Next, I have to fill *tot* - *i* positions with remained elements. We'll consider for this moment valid each permutation of not used values. So, sol[i] = 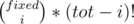 . Where is the problem to this formula?
+
+The problem is that it's possible, when permuting (tot — i) remained elements to be added, one (or more) elements to form more (new) fixed points. But if somehow I can exclude (subtract) the wrong choices from sol[i], sol[i] will be calculated correctly. I iterate another index *j* from i + 1 to *fixed*. For each j, I'll calculate how many permutations I considered in sol[i] having *i* fixed points but actually they have *j*. I'll subtract from sol[i] this value calculated for each j. If I do this, obviously sol[i] will be calculated correctly.
+
+Suppose we fixed a j. We know that exactly sol[j] permutations have j fixed points (as j > i, this value is calculated correctly). Suppose now I fix a permutation having j fixed points. For get the full result, I need to calculate for all sol[j] permutations. Happily, I can multiply result obtained for a single permutation with sol[j] and obtain the result for all permutations having j fixed points. So you have a permutation having j fixed points. The problem reduces to choosing i objects from a total of j. Why? Those i objects chosen are actually the positions considered in sol[i] to be ones having exactly i fixed points. But permutation has j fixed points. Quoting for above, "For each j, I'll calculate how many permutations I considered in sol[i] having *i* fixed points but actually they have *j*" . This is exactly what algorithm does.
+
+To sum up in a "LaTeX" way, 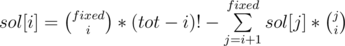
+
+We can compute binomial coefficients using Pascal's triangle. Using inclusion and exclusion principle, we get *O*(*N*2). Please note that there exist an *O*(*N*) solution for this task, using inclusion and exclusion principle, but it's not necessary to get AC. I'll upload [Gerald](/profile/Gerald "Master Gerald")'s source [here](http://pastie.org/8287332).
+
+## [341D - Iahub and Xors](/contest/341/problem/D "Codeforces Round 198 (Div. 1)")
+
+The motivation of the problem is that x ^ x = 0. x ^ x ^ x… ^ x (even times) = 0
+
+**Update per range, query per element**
+
+When dealing with complicated problems, it's sometimes a good idea to try solving easier versions of them. Suppose you can query only one element each time (x0 = x1, y0 = y1).
+
+To update a submatrix (x0, y0, x1, y1), I’ll do following operations. A[x0][y0] ^= val. A[x0][y1 + 1] ^= val. A[x1 + 1][y0] ^= val. A[x1 + 1][y1 + 1] ^= val.
+
+To query about an element (X, Y), that element’s value will be the xor sum of submatrix A(1, 1, X, Y). Let’s take an example. I have a 6x6 matrix and I want to xor all elements from submatrix (2, 2, 3, 4) with a value. The below image should be explanatory how the method works:
+
+
+
+Next, by (1, 1, X, Y) I’ll denote xor sum for this submatrix.
+
+“White” cells are not influenced by (2, 2, 3, 4) matrix, as matrix (1, 1, X, Y) with (X, Y) a white cell will never intersect it. “Red” cells are from the submatrix, the ones that need to be xor-ed. Note that for a red cell, (1, 1, X, Y) will contain the value we need to xor (as it will contain (2, 2)). Next, “blue” cells. For this ones (1, 1, X, Y) will contain the value we xor with, despite they shouldn’t have it. This is why both (2, 5) and (4, 2) will be xor-ed again by that value, to cancel the xor of (2, 2). Now it’s okay, every “blue” cell do not contain the xor value in their (1, 1, X, Y). Finally, the “green” cells. These ones are intersection between the 2 blue rectangles. This means, in their (1, 1, X, Y) the value we xor with appears 3 times (this means it is contained 1 time). For cancel this, we xor (4, 5) with the value. Now for every green cell (1, 1, X, Y) contains 4 equal values, which cancel each other.
+
+You need a data structure do to the following 2 operations:
+
+* Update an element (X, Y) (xor it with a value).
+* Query about xor sum of (1, 1, X, Y).
+
+Both operations can be supported by a Fenwick tree 2D. If you don't know this data structure, learn it and come back to this problem after you do this.
+
+**Coming back to our problem**
+
+Now, instead of finding an element, I want xor sum of a submatrix. You can note that xor sum of (x0, y0, x1, y1) is (1, 1, x1, y1) ^ (1, 1, x0 – 1, y1) ^ (1, 1, x1, y0 – 1) ^ (1, 1, x0 – 1, y0 – 1). This is a classical problem, the answer is (1, 1, x1, y1) from which I exclude what is not in the matrix: (1, 1, x0 – 1, y1) and (1, 1, x1, y0 – 1). Right now I excluded (1, 1, x0 – 1, y0 – 1) 2 times, so I need to add it one more time.
+
+How to get the xor sum of submatrix (1, 1, X, Y)? In brute force approach, I’d take all elements (x, y) with 1 <= x <= X and 1 <= y <= Y and xor their values. Recall the definition of the previous problem, each element (x, y) is the xor sum of A(1, 1, x, y). So the answer is xor sum of all xor sums of A(1, 1, x, y), with 1 <= x <= X and 1 <= y <= Y.
+
+We can rewrite that long xor sum. A number A[x][y] appears in exactly (X – x + 1) * (Y – y + 1) terms of xor sum. If (X – x + 1) * (Y – y + 1) is odd, then the value A[x][y] should be xor-ed to the final result exactly once. If (X — x + 1) * (Y — y + 1) is even, it should be ignored.
+
+Below, you'll find 4 pictures. They are matrixes with X lines and Y columns. Each picture represents a case: (X odd, Y odd) (X even, Y even) (X even Y odd) (X odd Y even). Can you observe a nice pattern? Elements colored represent those for which (X – x + 1) * (Y – y + 1) is odd.
+
+   
+
+Yep, that's right! There are 4 cases, diving the matrix into 4 disjoint areas. When having a query of form (1, 1, X, Y) you only need specific elements sharing same parity with X and Y. This method works in O(4 * logN * logN) for each operation and is the indented solution. We keep 4 Fenwick trees 2D. We made tests such as solutions having complexity greater than O(4 * logN * logN) per operation to fail.
+
+Here is our official solution: [4383473](/contest/341/submission/4383473 "Submission 4383473 by fchirica")
+
+## [341E - Candies Game](/contest/341/problem/E "Codeforces Round 198 (Div. 1)")
+
+**Key observation** Suppose you have 3 boxes containing A, B, C candies (A, B, C all greater than 0). Then, there will be always possible to empty one of boxes using some moves.
+
+**Proof** We can suppose that A <= B <= C. We need some moves such as the minimum from A, B, C will be zero. If we always keep the numbers in order A <= B <= C, it’s enough some moves such as A = 0. I’ll call this notation (A, B, C).
+
+How can we prove that always exist such moves? We can use reductio ad absurdum to prove it. Let’s suppose, starting from (A, B, C) we can go to a state (A2, B2, C2). We suppose A2 (A2 > 0) is minimal from every state we can obtain. Since A2 is minimal number of coins that can be obtained and A2 is not zero, the statement is equivalent with we can’t empty one chest from configuration (A, B, C). Then, we can prove that from (A2, B2, C2) we can go to a state (A3, B3, C3), where A3 < A2. Obviously, this contradicts our assumption that A2 is minimal of every possible states. If A2 would be minimal, then there won’t be any series of moves to empty one chest. But A2 isn’t minimal, hence there always exist some moves to empty one chest.
+
+Our algorithm so far:
+
+void emptyOneBox(int A, int B, int C) {
+
+if A is 0, then exit function.
+
+Make some moves such as to find another state (A2, B2, C2) with A2 < A.
+
+emptyOneBox (A2, B2, C2);
+
+}
+
+The only problem which needs to be proven now is: given a configuration (A, B, C) with A > 0, can we find another one (A2, B2, C2) such as A2 < A? The answer is always yes, below I’ll prove why.
+
+Firstly, let’s imagine we want to constantly move candies into a box. It doesn't matter yet from where come the candies, what matters is candies arrive into the box. The box has initially X candies. After 1 move, it will have 2 * X candies. After 2 moves, it will have 2 * (2 * X) candies = 4 * X candies. Generally, after K moves, the box will contain 2^K * X candies.
+
+We have A < B < C (if 2 numbers are equal, we can make a move and empty 1 box). If we divide B by A, we get from math that B = A * q + r. (obviously, always r < A). What if we can move exactly A * q candies from B to A? Then, our new state would be (r, B2, C2). We have now a number A2 = r, such as A2 < A.
+
+How can we move exactly A * q coins? Let’s write q in base 2. Making that, q will be written as a sum of powers of 2. Suppose lim is the maximum number such as 2 ^ lim <= q. We get every number k from 0 to lim. For each k, I push into the first box (the box containing initially A candies) a certain number of candies. As proven before, I'll need to push (2 ^ k) * A candies. Let's take a look at the k-th bit from binary representation of q. If k-th bit is 1, B will be written as following: B = A * (2 ^ k + 2 ^ (other_power_1) + 2 ^ (other_power_2) + ...) + r. Hence, I'll be able to move A * (2 ^ k) candies from "B box" to "A box". Otherwise, I'll move from "C box" to "A box". It will be always possible to do this move, as C > B and I could do that move from B, too.
+
+The proposed algorithm may look abstract, so let's take an example.
+
+Suppose A = 3, B = 905 and C = 1024. Can we get less than 3 for this state?
+
+B = 3 * 301 + 2. B = 3 * (100101101)2 + 2.
+
+K = 0: we need to move (2^0) * 3 coins into A. 0th bit of q is 1, so we can move from B to A.
+
+A = 6, B = 3 * (100101100)2 + 2 C = 1024
+
+K = 1: we need to move (2 ^ 1) * 3 coins into A. Since 1th bit of q is already 0, we have to move from C.
+
+A = 12, B = 3 * (100101100)2 + 2 C = 1018
+
+K = 2: we need to move (2 ^ 2) * 3 coins into A. 2nd bit of q is 1, so we can move from B.
+
+A = 24, B = 3 * (100101000)2 + 2 C = 1018
+
+K = 3: we need to move (2 ^ 3) * 3 coins into A. 3nd bit of q is 1, so we can move from B.
+
+A = 48, B = 3 * (100100000)2 + 2 C = 1018
+
+K = 4. we need to move (2 ^ 4) * 3 coins into A. 4th bit of q is 0, we need to move from C.
+
+A = 96, B = 3 * (100100000)2 + 2 C = 970
+
+K = 5. we need to move (2 ^ 5) * 3 coins into A. 5th bit of q is 1, so we need to move from B.
+
+A = 192, B = 3 * (100000000)2 + 2 C = 970
+
+K = 6 we need to move (2 ^ 6) * 3 coins into A. We mve them from C.
+
+A = 384 B = 3 * (100000000)2 + 2 C = 778
+
+K = 7 we need to move (2 ^ 7) * 3 coins into A. We move them from C
+
+A = 768 B = 3 * (100000000)2 + 2 C = 394
+
+K=8 Finally, we can move our last 1 bit from B to A.
+
+A = 1536 B = 3 * (000000000)2 + 2 C = 394
+
+A = 1536 B = (3 * 0 + 2) C = 394
+
+In the example, from (3, 905, 1024) we can arrive to (2, 394, 1536). Then, with same logic, we can go from (2, 394, 1536) to (0, X, Y), because 394 = 2 * 197 + 0.
+
+This is how you could write emptyOneBox() procedure. The remained problem is straight-forward: if initially there are zero or one boxes having candies, the answer is "-1". Otherwise, until there are more than 2 boxes having candies, pick 3 boxes arbitrary and apply emptyOneBox().
+
+Here is a source implementing the algorithm. [4383485](/contest/341/submission/4383485 "Submission 4383485 by fchirica")
+
+## BONUS
+
+Instead of a conclusion, I'll post here related problems to the ones used in the round. :) Please note that some of them might be more easier / complicated than level of difficulty used in the round. Feel free to think of them / ask help / discuss them in the comment section :)
+
+**Div2 A** Suppose *x*, *y*, *A*, *B* ≤ 109. Instead of being asked how many bricks are colored with both red and pink in range [*A*, *B*], you're asked how many bricks are colored with at least one color. After you solve this one, solve the same problem, but instead of having 2 persons painting, you have k persons (*k* ≤ 20). [Solution](//codeforces.com/blog/entry/8755#comment-144971) by [Enchom](/profile/Enchom "Candidate Master Enchom")
+
+**Div2 B** Given a very long list of special points, can you find quickly a convex special quadrilateral? Can you find very very quickly? :) Also, can you find maximal area of a special convex quadrilateral in time better than *O*(*N*4)? Solutions for [first problem](//codeforces.com/blog/entry/8755#comment-145790) and [second problem](//codeforces.com/blog/entry/8755#comment-145492) provided by [Xellos](/profile/Xellos "Candidate Master Xellos") and [Enchom](/profile/Enchom "Candidate Master Enchom")
+
+**Div2 D / Div1 B** Suppose the reverse problem. You are given a bubble sort graph having *N* vertices and *M* edges. Find its independent maximal set. Can you achieve *O*(*N*2) to do this? Does a solution in *O*((*N* + *M*) + *N* * *logN*) exist? [Solution](//codeforces.com/blog/entry/8755#comment-144890) by [CountZero](/profile/CountZero "Expert CountZero")
+
+**Div2 E / Div1 C** Find a solution running in liniar time. [Solution (dynamic programming)](//codeforces.com/blog/entry/8755#comment-144888) by [ivan100sic](/profile/ivan100sic "Candidate Master ivan100sic") . [Solution (inclusion exclusion principle)](//codeforces.com/blog/entry/8748#comment-144745) by [eduardische](/profile/eduardische "Candidate Master eduardische")
+
+**Div1 D** Suppose the 3D version of this problem. You have a 3D matrix and you perform same QUERY/UPDATE operations, but using 6 parameters (a submatrix is defined now all elements a[i][j][k] for which x0 <= i <= x1, y0 <= j <= y1, z0 <= k <= z1). Can you get a solution using *O*(*log*3 * *N*) per query, having constant 8? But for d dimensions, does an *O*(2*d* * (*log**d*)*n*) algorithm per query exist? :) [Solution](//codeforces.com/blog/entry/8755#comment-144896) by [Dwylkz](/profile/Dwylkz "Expert Dwylkz").
+
+**Div1 E** In our algorithm, we pick arbitrary 3 boxes. Can you find some heuristics of picking 3 boxes to reduce number of moves?
diff --git a/editorials/342.md b/editorials/342.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/8800
+
+[342A - Xenia and Divisors](/contest/342/problem/A "Codeforces Round 199 (Div. 2)")
+
+In this problem you should guess that exists only three valid groups of three
+
+1) 1, 2, 4
+
+2) 1, 2, 6
+
+3) 1, 3, 6
+
+(You can see that integers 5 and 7 are bad).
+
+So, we will greedy take these groups of three. If some integers will be not used, the answer is -1. In other case, print found answer.
+
+[342B - Xenia and Spies](/contest/342/problem/B "Codeforces Round 199 (Div. 2)")
+
+The problem is solved by greedy algorithm. We will pass the note only in correct direction. Also, if we can pass the note at the current moment of time, we do it. In other case, we will hold it and don't give it to neighbors (we can make this action at any moment of time). Obviously this algorithm is correct. You should only implement it carefully.
+
+[342C - Cupboard and Balloons](/contest/342/problem/C "Codeforces Round 199 (Div. 2)")
+
+In the problem you should carefully get formula. The optimal solution put marbles by two in a row. And then put one marble upon others if it possible. The most difficulties were to deal with this last phase.
+
+In comments to the post were given formulas how to put the last marble (exactly in the middle). And there was a good beautiful illustration, which describes the situation.
+
+[342D - Xenia and Dominoes](/contest/342/problem/D "Codeforces Round 199 (Div. 2)")
+
+In the problem you can count number of correct puzzles or substract number of incorrect puzzles from number of all puzzles. In any case you should count DP, where the state is (*j*, *mask*) — *j* — number of the last full column, *mask* — mask of the last column. This problem is equivalent to the well known problem about domino tiling or the problem about parquet.
+
+To get the solution of the whole problem I did the following. I try to attach one domino to each of 4 directions, then paint all three cells in black and count the number of correct puzzles. But in this case you will count some solutions several number of times. So you need to use inclusion exclusion formula for these 4 directions.
+
+[342E - Xenia and Tree](/contest/342/problem/E "Codeforces Round 199 (Div. 2)")
+
+The problem can be solved in different ways. The most easy idea is sqrt-optimization. Split all queries into *sqrt*(*m*) blocks. Each block we will process separately. Before processing each block, we should calculate minimum distances from every node to the closest red node using bfs. To answer the query we should update this value by shortest distances to red nodes in current block.
+
+The solution becomes simple. Every *sqrt*(*m*) queries we make simple bfs and for every node *v* WE calculate value *d*[*v*] — the shortest distance to some red node from node *v*. Then to answer the query of type 2 you should calculate *min*(*d*[*v*], *dist*(*v*, *u*)), where *u* — every red node, which becomes red in current block of length *sqrt*(*m*).
+
+Distance between two nodes *dist*(*u*, *v*) can be got using preprocessing for lca.
diff --git a/editorials/343.md b/editorials/343.md
@@ -0,0 +1,85 @@
+Source: https://codeforces.com/blog/entry/8860
+
+#### [344A - Magnets](/contest/344/problem/A "Codeforces Round 200 (Div. 2)")
+
+By the definition each block consists of a number of consequent and equally oriented dominoes. That means that in places where adjacent dominoes are not oriented equally, one block ends and another block starts. So, if there are *x* such places, the answer is equal to *x* + 1.
+
+Solution complexity: *O*(*n*). Problem author: [gen](/profile/gen "Candidate Master gen").
+
+**Bonus:** The problem was created a day before the contest and filled in the last part of a physically flavoured DivII complect. :]
+
+#### [344B - Simple Molecules](/contest/344/problem/B "Codeforces Round 200 (Div. 2)")
+
+First solution. First, the sum *a* + *b* + *c* should be even, since each bond adds 2 to the sum. Now let *x*, *y*, *z* be the number of bonds between 1st and 2nd, 2nd and 3rd, 3rd and 1st atoms, accordingly. So we have to solve the system *x* + *z* = *a*, *y* + *x* = *b*, *z* + *y* = *c*. Now observe that the solution to the system is the length of the tangents on the triangle with sides of length *a*, *b*, *c* to its inscribed circle, and are equal to , , . If the problem asked only the possibility of building such a molecule, we could just check if there exists (possibly degenerate) triangle with sides *a*, *b*, *c*.
+
+
+
+Second solution. Bruteforce all *x* values. For a fixed *x* values of *y* and *z* are defined uniquely: *y* = *b* - *x*, *z* = *a* - *x*.
+
+Solution complexity: *O*(1) / *O*(*n*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Bonus:** Can you solve the problem for any vertex number *n*? When and how can such a graph be built?
+
+#### [343A - Rational Resistance](/contest/343/problem/A "Codeforces Round 200 (Div. 1)")
+
+If a fraction  can be obtained with *k* resistors, then it is simple to calculate that we can obtain fractions  and  with *k* + 1 resistors. So adding one resistor means performing one operation backwards in Euclidean algorithm. That means that the answer is equal to the number of steps in standard Euclidean algorithm.
+
+Solution complexity: 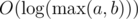. Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Бонус:** At first we thought about the major problem (any two elements can be joined), but had a moment of eureka and got that the given problem unexpectedly naturally can be reduced to GCD. By the way, the result tree — [http://en.wikipedia.org/wiki/Calkin%E2%80%93Wilf_tree](https://en.wikipedia.org/wiki/Calkin%E2%80%93Wilf_tree).
+
+#### [343B - Alternating Current](/contest/343/problem/B "Codeforces Round 200 (Div. 1)")
+
+Let us solve the following problem first: we are given a string of symbols A and B. If the *i*-th symbol is *A*, then at the *i*-th step the upper wire (see figure) is being put over the lower wire. If the *i*-th symbol is *B*, the lower wire is being put over the upper wire at *i*-th step. Observe that if some two symbols *A* and *B* are adjacent, we can untangle this place, throw the symbols out and obtain the string of length two symbols less. So the wires can be untangled iff the number of A's and B's in the string is the same. The given problem can be reduced to the described in a following fashion: in each odd position we change – to B and + to A. In each even position we change — to A and + to B. The reduction is correct, since on each even position the order of — and + are always swapped, and in each odd position their order is the same as in the beginning.
+
+Solution complexity: *O*(*n*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Bonus:** If you are interested by this problem, you can learn about the braid theory [http://en.wikipedia.org/wiki/Braid_theory](https://en.wikipedia.org/wiki/Braid_theory) :] Fun fact: a harder version of this problem was planned already for Round #142, but the error in solution idea was found, and the problem was left to lay for almost a year.
+
+#### [343C - Read Time](/contest/343/problem/C "Codeforces Round 200 (Div. 1)")
+
+Let's search the answer *t* with the binary search. Fix some value of *t*. Look at the first head from the left *h*[*i*] that can read track *p*[0]. If *p*[0] > *h*[*i*], then *h*[*i*] goes to the right *t* seconds and reads all tracks on its way. Otherwise if *p*[0] ≤ *h*[*i*], then the head has two choices:
+
+1. go to the right  seconds, then  to the left and *h*[*i*] - *p*[0] again to the left;
+2. go to the left *h*[*i*] - *p*[0] seconds, then *h*[*i*] - *p*[0] to the right and *t* - 2·(*h*[*i*] - *p*[0]) again to the right.
+
+Obviously, for *h*[*i*] it is more advantageous to visit the track positioned as much as possible to the right. So we choose by 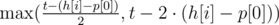. Then we move the pointer onto the first unread track, and repeat the algorithm for *h*[*i* + 1], and so on with each head.
+
+Solution complexity: 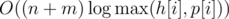. Problem authors: [gen](/profile/gen "Candidate Master gen"), [gorbunov](/profile/gorbunov "Pupil gorbunov").
+
+**Bonus:** The problem is completely real, if the disk has only a single head, if we know, what tracks should be read; then the optimal algorithm chooses between the two choices described above. I and [gorbunov](/profile/gorbunov "Pupil gorbunov") were listening this on a lecture, and created the given problem out of boredom ;]
+
+#### [343D - Water Tree](/contest/343/problem/D "Codeforces Round 200 (Div. 1)")
+
+Let's learn how to color a whole subtree. For that enumerate all vertices in post-order DFS. Then each subtree covers a single continious vertex number segment. For each vertex we store the bounds of such segment for a subtree with a root in this vertex. Then to color a subtree means to color a segment in a segment tree.
+
+Then create a segment tree that has a following property: if a vertex *v* was emptied, and is still empty, then this vertex is colored in the segment tree. In the beginning "empty" all the vertices. That is, color all the vertices in the segment tree. With this tree we can efficiently process the queries:
+
+1. Fill a vertex *v*. Clean the interval for the subtree of *v*. If before that some vertex of a subtree was empty, color the parent of *v*.
+2. Empty a vertex *v*. Color the vertex *v* in the segment tree.
+3. Reply whether a vertex *v* is filled. If in the segment tree at least one vertex is colored, then there is such a descendant of *v* that is empty now, so the vertex *v* is not filled.
+
+[Shtrix](/profile/Shtrix "Expert Shtrix") noted that essentially the same solution can be implemented with only a single set.
+
+Solution complexity: . Problem author: [gen](/profile/gen "Candidate Master gen").
+
+**Bonus:** Some participants could see the similarities with a problem Ball Machine from BOI 2013, but the solutions to the both problems are quite different.
+
+#### [343E - Pumping Stations](/contest/343/problem/E "Codeforces Round 200 (Div. 1)")
+
+In this problem we are asked to find such graph vertex permutation that maximizes the sum of the maximum flows sent between each two consequtive vertices in the permutation.
+
+The problem can be solved with [Gomory-Hu](https://en.wikipedia.org/wiki/Gomory%E2%80%93Hu_tree) tree data structure. For a given weighted graph the tree has the following properties:
+
+1. The vertex set of the tree and the graph is the same.
+2. The maximum flow between vertices *u* and *v* in the tree is equal to the maximum flow in the graph.
+
+Surprisingly, such a tree exists for any weighted graph, and can be built in *O*(*n*·*maxFlow*). It appears that the answer to the problem is equal to the sum of the edge weights in this tree.
+
+We prove this statement by induction on the number of the tree vertices. Pick the edge (*u*, *v*) with the smallest weight in the tree. Consider that in an optimal permutation more than one path between two adjacent verteces in the permutation passes through this edge. Erase all these paths, then each of the *u* and *v* subtrees holds a set of disjoint remaining paths from the permutation. For each set, join all the paths in one chain, obtaining two chains. These chains we join by a path *s* that goes trough the edge (*u*, *v*). Thus we have built a permutation that is not worse than the considered one. For a path *s* the edge (*u*, *v*) is the smallest, so the flow along this path is equal to the weight of this edge. It follows from the induction that in subtrees *u* and *v* the answer is equal to the sum of edges. By adding the weight of edge (*u*, *v*), we get the desired result.
+
+From the last paragraph it is clear how to build such a permutation: take the smallest edge, obtain two chains from the vertex subtrees recursively, and add them together to form a one chain. Since there are not many vertices, we can do this part in *O*(*n*2).
+
+Solution complexity: *O*(*n*·*maxFlow*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [Gerald](/profile/Gerald "Master Gerald").
+
+**Bonus:** Shortly before the contest we decided to make the constraints more loyal, so some solution that find Gomory-Hu tree by finding flow *O*(*n*2) times also passed. We hope that nobody is particularly saddened by this fact. (;
diff --git a/editorials/344.md b/editorials/344.md
@@ -0,0 +1,85 @@
+Source: https://codeforces.com/blog/entry/8860
+
+#### [344A - Magnets](/contest/344/problem/A "Codeforces Round 200 (Div. 2)")
+
+By the definition each block consists of a number of consequent and equally oriented dominoes. That means that in places where adjacent dominoes are not oriented equally, one block ends and another block starts. So, if there are *x* such places, the answer is equal to *x* + 1.
+
+Solution complexity: *O*(*n*). Problem author: [gen](/profile/gen "Candidate Master gen").
+
+**Bonus:** The problem was created a day before the contest and filled in the last part of a physically flavoured DivII complect. :]
+
+#### [344B - Simple Molecules](/contest/344/problem/B "Codeforces Round 200 (Div. 2)")
+
+First solution. First, the sum *a* + *b* + *c* should be even, since each bond adds 2 to the sum. Now let *x*, *y*, *z* be the number of bonds between 1st and 2nd, 2nd and 3rd, 3rd and 1st atoms, accordingly. So we have to solve the system *x* + *z* = *a*, *y* + *x* = *b*, *z* + *y* = *c*. Now observe that the solution to the system is the length of the tangents on the triangle with sides of length *a*, *b*, *c* to its inscribed circle, and are equal to , , . If the problem asked only the possibility of building such a molecule, we could just check if there exists (possibly degenerate) triangle with sides *a*, *b*, *c*.
+
+
+
+Second solution. Bruteforce all *x* values. For a fixed *x* values of *y* and *z* are defined uniquely: *y* = *b* - *x*, *z* = *a* - *x*.
+
+Solution complexity: *O*(1) / *O*(*n*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Bonus:** Can you solve the problem for any vertex number *n*? When and how can such a graph be built?
+
+#### [343A - Rational Resistance](/contest/343/problem/A "Codeforces Round 200 (Div. 1)")
+
+If a fraction  can be obtained with *k* resistors, then it is simple to calculate that we can obtain fractions  and  with *k* + 1 resistors. So adding one resistor means performing one operation backwards in Euclidean algorithm. That means that the answer is equal to the number of steps in standard Euclidean algorithm.
+
+Solution complexity: 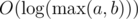. Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Бонус:** At first we thought about the major problem (any two elements can be joined), but had a moment of eureka and got that the given problem unexpectedly naturally can be reduced to GCD. By the way, the result tree — [http://en.wikipedia.org/wiki/Calkin%E2%80%93Wilf_tree](https://en.wikipedia.org/wiki/Calkin%E2%80%93Wilf_tree).
+
+#### [343B - Alternating Current](/contest/343/problem/B "Codeforces Round 200 (Div. 1)")
+
+Let us solve the following problem first: we are given a string of symbols A and B. If the *i*-th symbol is *A*, then at the *i*-th step the upper wire (see figure) is being put over the lower wire. If the *i*-th symbol is *B*, the lower wire is being put over the upper wire at *i*-th step. Observe that if some two symbols *A* and *B* are adjacent, we can untangle this place, throw the symbols out and obtain the string of length two symbols less. So the wires can be untangled iff the number of A's and B's in the string is the same. The given problem can be reduced to the described in a following fashion: in each odd position we change – to B and + to A. In each even position we change — to A and + to B. The reduction is correct, since on each even position the order of — and + are always swapped, and in each odd position their order is the same as in the beginning.
+
+Solution complexity: *O*(*n*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [andreyv](/profile/andreyv "Expert andreyv").
+
+**Bonus:** If you are interested by this problem, you can learn about the braid theory [http://en.wikipedia.org/wiki/Braid_theory](https://en.wikipedia.org/wiki/Braid_theory) :] Fun fact: a harder version of this problem was planned already for Round #142, but the error in solution idea was found, and the problem was left to lay for almost a year.
+
+#### [343C - Read Time](/contest/343/problem/C "Codeforces Round 200 (Div. 1)")
+
+Let's search the answer *t* with the binary search. Fix some value of *t*. Look at the first head from the left *h*[*i*] that can read track *p*[0]. If *p*[0] > *h*[*i*], then *h*[*i*] goes to the right *t* seconds and reads all tracks on its way. Otherwise if *p*[0] ≤ *h*[*i*], then the head has two choices:
+
+1. go to the right  seconds, then  to the left and *h*[*i*] - *p*[0] again to the left;
+2. go to the left *h*[*i*] - *p*[0] seconds, then *h*[*i*] - *p*[0] to the right and *t* - 2·(*h*[*i*] - *p*[0]) again to the right.
+
+Obviously, for *h*[*i*] it is more advantageous to visit the track positioned as much as possible to the right. So we choose by 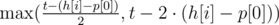. Then we move the pointer onto the first unread track, and repeat the algorithm for *h*[*i* + 1], and so on with each head.
+
+Solution complexity: 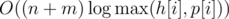. Problem authors: [gen](/profile/gen "Candidate Master gen"), [gorbunov](/profile/gorbunov "Pupil gorbunov").
+
+**Bonus:** The problem is completely real, if the disk has only a single head, if we know, what tracks should be read; then the optimal algorithm chooses between the two choices described above. I and [gorbunov](/profile/gorbunov "Pupil gorbunov") were listening this on a lecture, and created the given problem out of boredom ;]
+
+#### [343D - Water Tree](/contest/343/problem/D "Codeforces Round 200 (Div. 1)")
+
+Let's learn how to color a whole subtree. For that enumerate all vertices in post-order DFS. Then each subtree covers a single continious vertex number segment. For each vertex we store the bounds of such segment for a subtree with a root in this vertex. Then to color a subtree means to color a segment in a segment tree.
+
+Then create a segment tree that has a following property: if a vertex *v* was emptied, and is still empty, then this vertex is colored in the segment tree. In the beginning "empty" all the vertices. That is, color all the vertices in the segment tree. With this tree we can efficiently process the queries:
+
+1. Fill a vertex *v*. Clean the interval for the subtree of *v*. If before that some vertex of a subtree was empty, color the parent of *v*.
+2. Empty a vertex *v*. Color the vertex *v* in the segment tree.
+3. Reply whether a vertex *v* is filled. If in the segment tree at least one vertex is colored, then there is such a descendant of *v* that is empty now, so the vertex *v* is not filled.
+
+[Shtrix](/profile/Shtrix "Expert Shtrix") noted that essentially the same solution can be implemented with only a single set.
+
+Solution complexity: . Problem author: [gen](/profile/gen "Candidate Master gen").
+
+**Bonus:** Some participants could see the similarities with a problem Ball Machine from BOI 2013, but the solutions to the both problems are quite different.
+
+#### [343E - Pumping Stations](/contest/343/problem/E "Codeforces Round 200 (Div. 1)")
+
+In this problem we are asked to find such graph vertex permutation that maximizes the sum of the maximum flows sent between each two consequtive vertices in the permutation.
+
+The problem can be solved with [Gomory-Hu](https://en.wikipedia.org/wiki/Gomory%E2%80%93Hu_tree) tree data structure. For a given weighted graph the tree has the following properties:
+
+1. The vertex set of the tree and the graph is the same.
+2. The maximum flow between vertices *u* and *v* in the tree is equal to the maximum flow in the graph.
+
+Surprisingly, such a tree exists for any weighted graph, and can be built in *O*(*n*·*maxFlow*). It appears that the answer to the problem is equal to the sum of the edge weights in this tree.
+
+We prove this statement by induction on the number of the tree vertices. Pick the edge (*u*, *v*) with the smallest weight in the tree. Consider that in an optimal permutation more than one path between two adjacent verteces in the permutation passes through this edge. Erase all these paths, then each of the *u* and *v* subtrees holds a set of disjoint remaining paths from the permutation. For each set, join all the paths in one chain, obtaining two chains. These chains we join by a path *s* that goes trough the edge (*u*, *v*). Thus we have built a permutation that is not worse than the considered one. For a path *s* the edge (*u*, *v*) is the smallest, so the flow along this path is equal to the weight of this edge. It follows from the induction that in subtrees *u* and *v* the answer is equal to the sum of edges. By adding the weight of edge (*u*, *v*), we get the desired result.
+
+From the last paragraph it is clear how to build such a permutation: take the smallest edge, obtain two chains from the vertex subtrees recursively, and add them together to form a one chain. Since there are not many vertices, we can do this part in *O*(*n*2).
+
+Solution complexity: *O*(*n*·*maxFlow*). Problem authors: [gen](/profile/gen "Candidate Master gen"), [Gerald](/profile/Gerald "Master Gerald").
+
+**Bonus:** Shortly before the contest we decided to make the constraints more loyal, so some solution that find Gomory-Hu tree by finding flow *O*(*n*2) times also passed. We hope that nobody is particularly saddened by this fact. (;
diff --git a/editorials/346.md b/editorials/346.md
@@ -0,0 +1,191 @@
+Source: https://codeforces.com/blog/entry/8903
+
+
+
+# Overview
+
+In DIV 1, there are 4 interesting problems together with a normal one. We think it is reasonable because we can't have a round fullly with intelligence. Problem A, C have weak pretests while others intended to be strong. About more then 200 participants solve A in the early 45mins, then a few of them start from C while most of the other start from B.
+
+Problem B is a rather standard problem, but if you're unfamiliar with the algorithm, it can be very hard. Problem C is a more intersting problem. As the name implies, there was [a similar version](//codeforces.com/problemset/problem/251/C) in the previous round before, but this time it has a brand new constrains.(So here we have a psychology experiment: could different constrains make people thinking in a slightly different way?ww)
+
+The standard solution of problem C is *O*((*b* - *a*) + *nlogn*). The first expected correct solution was written by [zeliboba](/profile/zeliboba "International Master zeliboba"). [http://codeforces.com/contest/346/submission/4512654](//codeforces.com/contest/346/submission/4512654)
+
+After that, some people start to solve problem D. Problem D looks like a hard dp problem on a graph at the first glance, the key point is how to avoid the circle in the transfer equation. It turn out to be elegant after you could found a right order of the evaluation. Problem E is challenging which you need find a way to transform the original question into a smaller scale, and cut off many many corner cases ... And in the very end, you find a way like binary search to get *O*(*logn*) as the time complexity. No one manage to solve problem E during the contest, maybe [Petr](/profile/Petr "International Grandmaster Petr") is the man who closest to it.
+
+The winner comes to [cgy4ever](/profile/cgy4ever "Grandmaster cgy4ever"), because he found the draw-black in his previous C submission during the very beginning even when there is nobody hack him! He resubmit it decisively and get back when finished problem D. After that, he use the same trick which made him failed before to hack others and got a handsomely rewards. The second place went to [rng_58](/profile/rng_58 "International Grandmaster rng_58"), because of the combination of decent speed in A, B, C, D.
+
+Problem B belongs to me, problem C belongs to [CMHJT](/profile/CMHJT "Candidate Master CMHJT") and others belong to [UESTC_Nocturne](/profile/UESTC_Nocturne "International Master UESTC_Nocturne"). The illustrator of problem C is [Chairman Miao(貓主席)](http://www.pixiv.net/member_illust.php?mode=medium&illust_id=38602657).
+
+# Editorial
+
+### [Problem A. Alice and Bob](//codeforces.com/problemset/problem/346/A)
+
+#### Brief description:
+
+Alice and Bob play a game, the rules are as follows: First, they will get a set of *n* distinct numbers. And then they take turns to do the following operations. During each operation, either Alice or Bob can choose two different numbers *x* and *y* from the set, as long as |*x* - *y*| is not in the set, then they add it to the set. The person who can not choose two numbers successfully will lose the game. The question is who will finally win the game if both of them do operations optimally. Remember that Alice always goes first.
+
+#### Analysis:
+
+First, no matter what happend, the number set we get at the very endding will be same all the time. Let's say *d* = *gcd*{*x**i*}. Then the set in the endding will be some things like {*d*, 2*d*, 3*d*, ... *max*{*x**i*}}. So there is always *max*{*x**i*} / *d* — *n* rounds. And what we should do rest is to check the parity of this value.
+
+### [Problem B. Lucky Common Subsequence](//codeforces.com/problemset/problem/346/B)
+
+#### Brief description:
+
+You have been given two strings *s*1, *s*2 and *virus*, and you have to find the longest common subsequence of *s*1 and *s*2 without *virus* as a substring.
+
+#### Analysis:
+
+This is a rather classical problem, let's say if there is no virus, then it is the classical **LCS ** problem. You can solve this by a *O*(*n*2) dynamic programing.
+
+When consider about the virus, we should add 1 more dimension on the state to trace the growth of the virus. It can be done by wheather **Aho-Corasick automation**, or **KMP** when there is only one virus in this case. The overall time complexity is *O*(*n*3).
+
+### [Problem C. Number Transformation II](//codeforces.com/problemset/problem/346/C)
+
+#### Brief description:
+
+You have a number *b*, and want to minus it to *a*, what you can do in each step is weather subtract 1 or *b* mod *x**i* from *b*. And we ask what is the minimum number of steps you need.
+
+#### Analysis:
+
+I bet there is a few people know the greedy method even if he/she have solved the early version before.
+
+[Codeforces #153 Div 1. Problem C. Number Transformation](//codeforces.com/problemset/problem/251/C)
+
+Let dp[k] denotes the minimum number of steps to transform b+k to b. In each step, you could only choose i which makes b+k-(b+k) mod x[i] minimal to calc dp[k]. It works bacause dp[0..k-1] is a monotone increasing function. Proof: - Say dp[k]=dp[k-t]+1.If t==1, then dp[0..k] is monotone increasing obviously.Otherwise dp[k-1]<=dp[k-t]+1=dp[k] (there must exist a x[i] makes b+k-1 also transform to b+k-t,and it is not necessarily the optimal decision of dp[k-1]). So dp[k] is a monotone increasing function, we can greedily calc dp[a-b].
+
+In the first glance, it looks like something which will run in square complexity. But actually is linear. That is because, we could cut exactly max{*x**i*} in each 2 step. It can be proof by induction.
+
+So the remians work is to delete those same *x**i*, and watch out some situation could cause degeneration. Many of us failed in this last step and got **TLE**
+
+### [Problem D. Robot Control](//codeforces.com/problemset/problem/346/D)
+
+Let's dp from t to s.
+
+dp[u] = min(min(dp[v]) + 1 , max(dp[v])) | u->v
+
+Here dp[u] means, the minimum number of orders mzry1992 needs to send in the worst case. The left-hand-side is sending order while the right-hand side is not. At the beginning, we have dp[t] = 1, and dp[s] will be the answer.
+
+We can see there is circular dependence in this equation, in this situation, one standard method is using Bellman-Ford algorithm to evaluate the dp function.
+
+But it is not appropriate for this problem.
+
+(In fact, we add a part of targeted datas in pretest, these datas are enough to block most of our [Bellman-Ford algorithm](https://en.wikipedia.org/wiki/Bellman%E2%80%93Ford_algorithm), although there is still a few participator can get accepted by Bellman-Ford algorithm during the contest.
+
+Check [rares.buhai](/profile/rares.buhai "Candidate Master rares.buhai")'s [solution](//codeforces.com/contest/346/submission/4520171)
+
+dp[u] = min(min(dp[v]) + 1 , max(dp[v])) | u->v
+
+The expected solution is evaluating the dp function as the increased value of dp[u] itself. Further analysis shows, wheather we decided sending order or not in u can be judged as the out-degree of u.
+
+```
+while (!Q.empty()) {
+ u = Q.front(), Q.pop_front()
+ for each edge from v to u
+ --out_degree[v]
+ if (out_degree[v] == 0) {
+ relax dp[v] by dp[u]
+ if success, add v to the front of Q
+ }
+ else{
+ relax dp[v] by dp[u] + 1
+ if success, add v to the back of Q
+ }
+ }
+```
+
+Check [Ra16bit](/profile/Ra16bit "International Master Ra16bit")'s [solution](//codeforces.com/contest/346/submission/4519668) to see how it works.
+
+### [Problem E. Doodle Jump](//codeforces.com/problemset/problem/346/E)
+
+#### Brief description:
+
+You have been give *a*, *p*, *n*, *h* (gcd(*a*, *p*) = 1), For each *ai* mod *p*, (*i*∈[1, n]), check weather the maximum distance in neighborhood after sorting is <= *h*.
+
+#### Analysis:
+
+Take *a* =5, *p* =23 for example ... Divided the numbers in group.
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16 21
+3 8 13 18
+```
+
+We start a new group when the number > P
+
+We found the difference between the elements of the first group is 5, The subsequent is filling some gap between the them ...
+
+After some observation we could found that we should only consider into one gap ...(e.g. [0, 5] or [15, 20] or [20, 25] ... )
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16
+```
+
+That says .. *a* =5, *p* =23 is roughly equal to some things in small scale?
+
+So let's check it in detail. Lemma 1. In any case, the gap after 20 won't better than any gap before it.
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16
+```
+
+For example, in this case, the gap after 20 is: 20, 22 And it has 16 in [15, 17] but no 21.
+
+Is there any chance that [20, 23] is better than [15, 20]?
+
+No, that is because, when there is no 21, then (19+5)%23 = 1, go to next floor. and there is no corresponding gap after 20 ([22, 24]) for this gap ([17, 19])
+
+So we only need to consider [15, 20] ... and we found [15, 20] is roughly equal to [0, 5]
+
+```
+e.g. : 15 20 17 19 16 18
+equal: 0 5 2 4 1 3
+```
+
+we say 'roughly' because we havn't check some boundary case like there is 3 but on 18 ...
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16 21
+3 8 13
+```
+
+If it happend, we should remove the number 3. .. If we can remove the element 5, then we can from a=5, p=23 to a'=2, p'=5 ...(n' = an/p, a' = a-p%a, if there is 3 but no 18, n'=n'-1)
+
+The rest things is to discuss wheather 5 is necessary or not.
+
+Let's we have:
+
+```
+0 2 4
+1 3
+```
+
+If the 2*n'<5, then there is only one floor, the answer is max(2, 5-2*n'). If there is more than one floor, we could conclude that 5 is useless.
+
+Proof: Elemets in 1st floor is:
+
+```
+0 a 2a 3a ...
+```
+
+Let's say the maximum elements in 1st floor is x, then the minimum element in the 2nd floor is b0 = x+a-p, because b0 — a = x-p, so the difference between b0 and a is equal to the difference between x and p. That is, we can consider [b0, a] rather than [x, p], when there is a element insert in [b0, a], there must be some element insert in [x, p] in the same position.
+
+So we have have succeeded to transform our original problem into a small one. Of couse, this problem havn't been solved, we haven't consider the time complexity. Says a' = a — p%a, when p = a+1, then a' = a-1, but we have *a* equal to 10^9, it won't work.
+
+But, let's we have A1, A2, ... An ... and we subtract *d* from all of them, the answer won't be changed. So we can use p%a substitute for a-p%a, this is equivalent to we subtract %p% from all of them ...
+
+So we set a' = min(a-p%a, p%a), so a'<=a/2, therefore, the final time complexity is *O*(*logn*).
+
+You can check [Petr](/profile/Petr "International Grandmaster Petr") ['s solution](//codeforces.com/contest/346/submission/4523388) for detail.
diff --git a/editorials/347.md b/editorials/347.md
@@ -0,0 +1,191 @@
+Source: https://codeforces.com/blog/entry/8903
+
+
+
+# Overview
+
+In DIV 1, there are 4 interesting problems together with a normal one. We think it is reasonable because we can't have a round fullly with intelligence. Problem A, C have weak pretests while others intended to be strong. About more then 200 participants solve A in the early 45mins, then a few of them start from C while most of the other start from B.
+
+Problem B is a rather standard problem, but if you're unfamiliar with the algorithm, it can be very hard. Problem C is a more intersting problem. As the name implies, there was [a similar version](//codeforces.com/problemset/problem/251/C) in the previous round before, but this time it has a brand new constrains.(So here we have a psychology experiment: could different constrains make people thinking in a slightly different way?ww)
+
+The standard solution of problem C is *O*((*b* - *a*) + *nlogn*). The first expected correct solution was written by [zeliboba](/profile/zeliboba "International Master zeliboba"). [http://codeforces.com/contest/346/submission/4512654](//codeforces.com/contest/346/submission/4512654)
+
+After that, some people start to solve problem D. Problem D looks like a hard dp problem on a graph at the first glance, the key point is how to avoid the circle in the transfer equation. It turn out to be elegant after you could found a right order of the evaluation. Problem E is challenging which you need find a way to transform the original question into a smaller scale, and cut off many many corner cases ... And in the very end, you find a way like binary search to get *O*(*logn*) as the time complexity. No one manage to solve problem E during the contest, maybe [Petr](/profile/Petr "International Grandmaster Petr") is the man who closest to it.
+
+The winner comes to [cgy4ever](/profile/cgy4ever "Grandmaster cgy4ever"), because he found the draw-black in his previous C submission during the very beginning even when there is nobody hack him! He resubmit it decisively and get back when finished problem D. After that, he use the same trick which made him failed before to hack others and got a handsomely rewards. The second place went to [rng_58](/profile/rng_58 "International Grandmaster rng_58"), because of the combination of decent speed in A, B, C, D.
+
+Problem B belongs to me, problem C belongs to [CMHJT](/profile/CMHJT "Candidate Master CMHJT") and others belong to [UESTC_Nocturne](/profile/UESTC_Nocturne "International Master UESTC_Nocturne"). The illustrator of problem C is [Chairman Miao(貓主席)](http://www.pixiv.net/member_illust.php?mode=medium&illust_id=38602657).
+
+# Editorial
+
+### [Problem A. Alice and Bob](//codeforces.com/problemset/problem/346/A)
+
+#### Brief description:
+
+Alice and Bob play a game, the rules are as follows: First, they will get a set of *n* distinct numbers. And then they take turns to do the following operations. During each operation, either Alice or Bob can choose two different numbers *x* and *y* from the set, as long as |*x* - *y*| is not in the set, then they add it to the set. The person who can not choose two numbers successfully will lose the game. The question is who will finally win the game if both of them do operations optimally. Remember that Alice always goes first.
+
+#### Analysis:
+
+First, no matter what happend, the number set we get at the very endding will be same all the time. Let's say *d* = *gcd*{*x**i*}. Then the set in the endding will be some things like {*d*, 2*d*, 3*d*, ... *max*{*x**i*}}. So there is always *max*{*x**i*} / *d* — *n* rounds. And what we should do rest is to check the parity of this value.
+
+### [Problem B. Lucky Common Subsequence](//codeforces.com/problemset/problem/346/B)
+
+#### Brief description:
+
+You have been given two strings *s*1, *s*2 and *virus*, and you have to find the longest common subsequence of *s*1 and *s*2 without *virus* as a substring.
+
+#### Analysis:
+
+This is a rather classical problem, let's say if there is no virus, then it is the classical **LCS ** problem. You can solve this by a *O*(*n*2) dynamic programing.
+
+When consider about the virus, we should add 1 more dimension on the state to trace the growth of the virus. It can be done by wheather **Aho-Corasick automation**, or **KMP** when there is only one virus in this case. The overall time complexity is *O*(*n*3).
+
+### [Problem C. Number Transformation II](//codeforces.com/problemset/problem/346/C)
+
+#### Brief description:
+
+You have a number *b*, and want to minus it to *a*, what you can do in each step is weather subtract 1 or *b* mod *x**i* from *b*. And we ask what is the minimum number of steps you need.
+
+#### Analysis:
+
+I bet there is a few people know the greedy method even if he/she have solved the early version before.
+
+[Codeforces #153 Div 1. Problem C. Number Transformation](//codeforces.com/problemset/problem/251/C)
+
+Let dp[k] denotes the minimum number of steps to transform b+k to b. In each step, you could only choose i which makes b+k-(b+k) mod x[i] minimal to calc dp[k]. It works bacause dp[0..k-1] is a monotone increasing function. Proof: - Say dp[k]=dp[k-t]+1.If t==1, then dp[0..k] is monotone increasing obviously.Otherwise dp[k-1]<=dp[k-t]+1=dp[k] (there must exist a x[i] makes b+k-1 also transform to b+k-t,and it is not necessarily the optimal decision of dp[k-1]). So dp[k] is a monotone increasing function, we can greedily calc dp[a-b].
+
+In the first glance, it looks like something which will run in square complexity. But actually is linear. That is because, we could cut exactly max{*x**i*} in each 2 step. It can be proof by induction.
+
+So the remians work is to delete those same *x**i*, and watch out some situation could cause degeneration. Many of us failed in this last step and got **TLE**
+
+### [Problem D. Robot Control](//codeforces.com/problemset/problem/346/D)
+
+Let's dp from t to s.
+
+dp[u] = min(min(dp[v]) + 1 , max(dp[v])) | u->v
+
+Here dp[u] means, the minimum number of orders mzry1992 needs to send in the worst case. The left-hand-side is sending order while the right-hand side is not. At the beginning, we have dp[t] = 1, and dp[s] will be the answer.
+
+We can see there is circular dependence in this equation, in this situation, one standard method is using Bellman-Ford algorithm to evaluate the dp function.
+
+But it is not appropriate for this problem.
+
+(In fact, we add a part of targeted datas in pretest, these datas are enough to block most of our [Bellman-Ford algorithm](https://en.wikipedia.org/wiki/Bellman%E2%80%93Ford_algorithm), although there is still a few participator can get accepted by Bellman-Ford algorithm during the contest.
+
+Check [rares.buhai](/profile/rares.buhai "Candidate Master rares.buhai")'s [solution](//codeforces.com/contest/346/submission/4520171)
+
+dp[u] = min(min(dp[v]) + 1 , max(dp[v])) | u->v
+
+The expected solution is evaluating the dp function as the increased value of dp[u] itself. Further analysis shows, wheather we decided sending order or not in u can be judged as the out-degree of u.
+
+```
+while (!Q.empty()) {
+ u = Q.front(), Q.pop_front()
+ for each edge from v to u
+ --out_degree[v]
+ if (out_degree[v] == 0) {
+ relax dp[v] by dp[u]
+ if success, add v to the front of Q
+ }
+ else{
+ relax dp[v] by dp[u] + 1
+ if success, add v to the back of Q
+ }
+ }
+```
+
+Check [Ra16bit](/profile/Ra16bit "International Master Ra16bit")'s [solution](//codeforces.com/contest/346/submission/4519668) to see how it works.
+
+### [Problem E. Doodle Jump](//codeforces.com/problemset/problem/346/E)
+
+#### Brief description:
+
+You have been give *a*, *p*, *n*, *h* (gcd(*a*, *p*) = 1), For each *ai* mod *p*, (*i*∈[1, n]), check weather the maximum distance in neighborhood after sorting is <= *h*.
+
+#### Analysis:
+
+Take *a* =5, *p* =23 for example ... Divided the numbers in group.
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16 21
+3 8 13 18
+```
+
+We start a new group when the number > P
+
+We found the difference between the elements of the first group is 5, The subsequent is filling some gap between the them ...
+
+After some observation we could found that we should only consider into one gap ...(e.g. [0, 5] or [15, 20] or [20, 25] ... )
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16
+```
+
+That says .. *a* =5, *p* =23 is roughly equal to some things in small scale?
+
+So let's check it in detail. Lemma 1. In any case, the gap after 20 won't better than any gap before it.
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16
+```
+
+For example, in this case, the gap after 20 is: 20, 22 And it has 16 in [15, 17] but no 21.
+
+Is there any chance that [20, 23] is better than [15, 20]?
+
+No, that is because, when there is no 21, then (19+5)%23 = 1, go to next floor. and there is no corresponding gap after 20 ([22, 24]) for this gap ([17, 19])
+
+So we only need to consider [15, 20] ... and we found [15, 20] is roughly equal to [0, 5]
+
+```
+e.g. : 15 20 17 19 16 18
+equal: 0 5 2 4 1 3
+```
+
+we say 'roughly' because we havn't check some boundary case like there is 3 but on 18 ...
+
+```
+0 5 10 15 20
+2 7 12 17 22
+4 9 14 19
+1 6 11 16 21
+3 8 13
+```
+
+If it happend, we should remove the number 3. .. If we can remove the element 5, then we can from a=5, p=23 to a'=2, p'=5 ...(n' = an/p, a' = a-p%a, if there is 3 but no 18, n'=n'-1)
+
+The rest things is to discuss wheather 5 is necessary or not.
+
+Let's we have:
+
+```
+0 2 4
+1 3
+```
+
+If the 2*n'<5, then there is only one floor, the answer is max(2, 5-2*n'). If there is more than one floor, we could conclude that 5 is useless.
+
+Proof: Elemets in 1st floor is:
+
+```
+0 a 2a 3a ...
+```
+
+Let's say the maximum elements in 1st floor is x, then the minimum element in the 2nd floor is b0 = x+a-p, because b0 — a = x-p, so the difference between b0 and a is equal to the difference between x and p. That is, we can consider [b0, a] rather than [x, p], when there is a element insert in [b0, a], there must be some element insert in [x, p] in the same position.
+
+So we have have succeeded to transform our original problem into a small one. Of couse, this problem havn't been solved, we haven't consider the time complexity. Says a' = a — p%a, when p = a+1, then a' = a-1, but we have *a* equal to 10^9, it won't work.
+
+But, let's we have A1, A2, ... An ... and we subtract *d* from all of them, the answer won't be changed. So we can use p%a substitute for a-p%a, this is equivalent to we subtract %p% from all of them ...
+
+So we set a' = min(a-p%a, p%a), so a'<=a/2, therefore, the final time complexity is *O*(*logn*).
+
+You can check [Petr](/profile/Petr "International Grandmaster Petr") ['s solution](//codeforces.com/contest/346/submission/4523388) for detail.
diff --git a/editorials/348.md b/editorials/348.md
@@ -0,0 +1,88 @@
+Source: https://codeforces.com/blog/entry/9031
+
+### [349A - Cinema Line](/contest/349/problem/A "Codeforces Round 202 (Div. 2)")
+
+In the problem you need to decide whether cashier can give a change to all customers if the price of the ticket is 25 rubles and there's 3 kinds of bills: 25, 50 and 100 rubles. There's no money in the ticket office in the beginning.
+
+Let's consider 3 cases.
+
+* Customer has 25 rubles hence he doesn't need a change.
+* Customer has 50 rubles hence we have to give him 25 rubles back.
+* Customer has 100 rubles hence we need to give him 75 rubles back. It can be done in 2 ways. 75=25+50 и 75=25+25+25. Notice that it's always worth to try 25+50 first and then 25+25+25. It's true because bills of 25 rubles can be used both to give change for 50 and 100 rubles and bills of 50 rubles can be used only to give change for 100 rubles so we need to save as much 25 ruble bills as possible.
+
+The solution is to keep track of the number of 25 and 50 ruble bills and act greedily when giving change to 100 rubles — try 25+50 first and then 25+25+25.
+
+### [349B - Color the Fence](/contest/349/problem/B "Codeforces Round 202 (Div. 2)")
+
+In the problem you're asked to write the largest possible number given number of paint that you have and number of paint that you need to write each digit.
+
+Longer number means larger number so it's worth to write the longest possible number. Because of that we choose the largest digit among those that require the least number of paint. Let the number of paint for that digit *d* be equal to *x*, and we have *v* liters of paint total. Then we can write number of the length .
+
+Now we know the length of the number, let it be *len*. Write down temporary result – string of length *len*, consisting of digits *d*. We have supply of *v*–*len*·*x* liters of paint. In order to enhance the answer, we can try to update the number from the beginning and swap each digit with the maximal possible. It's true because numbers of the equal length are compared in the highest digits first. Among digits that are greater than current we choose one that we have enough paint for and then update answer and current number of paint.
+
+If the length of the answer is 0 then you need to output -1.
+
+### [348A - Mafia](/contest/348/problem/A "Codeforces Round 202 (Div. 1)")
+
+In the problem you need to find out how many games you need to play in order to make all people happy. It means that each of them played as many games as he wanted.
+
+Let the answer be *x* games. Notice that *max*(*a*1, *a*2, …, *a**n*) ≤ *x*. Then *i*-th player can be game supervisor in *x*–*a**i* games. If we sum up we get 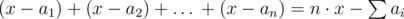 — it's the number of games in which players are ready to be supervisor. This number must be greater or equal to *x* — our answer.
+
+ 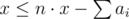
+
+ 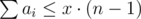
+
+ 
+
+ 
+
+Don't forget about that condition: *max*(*a*1, *a*2, …, *a**n*) ≤ *x*.
+
+### [348B - Apple Tree](/contest/348/problem/B "Codeforces Round 202 (Div. 1)")
+
+In the problem you need to find out minimal number of apples that you need to remove in order to make tree balanced.
+
+Notice, that if we know the value in the root then we know values in all other vertices. The value in the leaf is equal to the value in the root divided to the product of the powers of all vertices on the path between root and leaf.
+
+For every vertex let's calculate *d**i* — minimal number in that vertex (not zero) in order to make tree balanced. For leaves *d**i* = 1, for all other vertices *d**i* is equal to *k*·*lcm*(*d**j*1, *d**j*2, ..., *d**j**k*), where *j*1, *j*2, ..., *j**k* — sons of the vertex *i*. Let's calculate *s**i* — sum in the subtree of the vertex *i*. All that can be done using one depth first search from the root of the tree.
+
+Using second depth first search one can calculate for every vertex maximal number that we can write in it and satisfty all conditions. More precisely, given vertex *i* and *k* of its sons *j*1, *j*2, ..., *j**k*. Then if *m* = *min*(*s**j*1, *s**j*2, ..., *s**j**k*) and  — minimal number, that we can write to the sons of vertex *i*, then it's worth to write numbers  to the sons of vertex *i*. Remains  we add to the answer.
+
+### [348C - Subset Sums](/contest/348/problem/C "Codeforces Round 202 (Div. 1)")
+
+This problem is about data structures.
+
+First step of the solution is to divide sets to heavy and light. Light ones are those that contains less than  elements. All other sets are heavy.
+
+Key observation is that every light set contains less than  elements and number of heavy sets doesn't exceed  because we have upper bound for sum of the sizes of all sets.
+
+In order to effectively answer queries, for every set (both light and heavy) we calculate size of the intersection of this set and each heavy set. It can be done with time and memory . For every heavy set we create boolean array of size *O*(*n*). In *i*-th cell of this array we store how many elements *i* in given set. Then for each element and each heavy set we can check for *O*(1) time whether element is in the set.
+
+Now let's consider 4 possible cases:
+
+* *Add to the light set.* Traverse all numbers in the set and add the value from the query to each of them. Then traverse all heavy sets and add (size of intersection * the value from the query). Time is 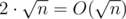.
+* *Add to the heavy set.* Just update the counter for the heavy set. Time is *O*(1).
+* *Answer to the query for the light set.* Traverse all numbers in the set and add values to the answer. Then traverse all heavy sets and add to the answer (answer for this heavy set * size of intersection with the set in the query). Time is 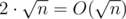.
+* *Answer to the query for the heavy set.* Take already calculated answer, then traverse all heavy sets and add (answer for this heavy set * size of intersection with the set in the query). Time is 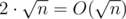.
+
+We have *O*(*n*) queries so total time is .
+
+### [348D - Turtles](/contest/348/problem/D "Codeforces Round 202 (Div. 1)")
+
+In the problem you're asked to find the number of pairs of non-intersecting paths between left upper and right lower corners of the grid. You can use following [lemma](https://en.wikipedia.org/wiki/Lindstr%C3%B6m%E2%80%93Gessel%E2%80%93Viennot_lemma) for that. Thanks to [rng_58](/profile/rng_58 "International Grandmaster rng_58") for the link. More precisely, considering our problem, this lemma states that given sets of initial *A* = {*a*1, *a*2} and final *B* = {*b*1, *b*2} points, the answer is equal to the following determinant:
+
+  where *f*(*x*, *y*) — is equal to the number of paths from point *x* to point *y*. You can calculate this function using dynamic programming.
+
+Finally we need to decide what sets of initial and final points we choose. You can take *A* = {(0, 1), (1, 0)} and *B* = {(*n* - 2, *m* - 1), (*n* - 1, *m* - 2)} in order to make paths non-intersecting even in 2 points.
+
+### [348E - Pilgrims](/contest/348/problem/E "Codeforces Round 202 (Div. 1)")
+
+Let’s build a simple solution at first and then we will try to improve it to solve problem more effectively given the constraints.
+
+For every vertex let’s find the list of the farthest vertices. Let’s find vertices on the intersection of the paths between current vertex and each vertex from the list that don’t contain monasteries. If we remove any of these vertices then every vertex from the list is unreachable from the current monastery. For every vertex from the intersection increment the counter. Then the answer for the problem is the maximum among all counters and the number of such maxima.
+
+Let’s solve the problem more effectively using the same idea. Let’s make the tree with root. For every vertex we will find the list of the farthest vertices only in the subtree. While traversing the tree using depth first search we return the largest depth in the subtree and the number of the vertex where it was reached. Among all of the sons of the current vertex we choose the maximum of depths. If maximum is reached one time then we return the same answer that was returned from the son. If the answer was reached more than one time then we return the number of the current vertex. Essentially, we find LCA of the farthest vertices according to the current vertex. Before quitting the vertex we increment the values on the segment between current vertex and found LCA. One can use Eulerian tour and segment tree for adding on the segment.
+
+Finally, the last stage of solving the problem – to solve it for the case when the farthest vertex is not in the subtree of the current vertex. For solving of that subproblem we use the same idea that was used in the problem of the finding the maximal path in the tree. For every vertex we keep 3 maximums – 3 farthest vertices in the subtree. When we go down to the subtree, we pass 2 remaining maximums too. In that way, when we’re in any vertex, we can decide whether there’s a path not in the subtree (it means, going up) of the same or larger length. If there’re 2 paths of the same length in the subtree and not in the subtree, it means that for the pilgrim from the current monastery there’s always a path no matter what town was destroyed. If one of the quantities is larger then we choose the segment in Eulerian tour and increment the value on the segment. The case where there’s several paths (at least 2) out of the subtree of the same maximal length, is the same with the case in the subtree.
+
+LCA and segment tree can be solved effectively in *O*(*logN*) time per query so the total memory and time is *O*(*NlogN*).
diff --git a/editorials/349.md b/editorials/349.md
@@ -0,0 +1,88 @@
+Source: https://codeforces.com/blog/entry/9031
+
+### [349A - Cinema Line](/contest/349/problem/A "Codeforces Round 202 (Div. 2)")
+
+In the problem you need to decide whether cashier can give a change to all customers if the price of the ticket is 25 rubles and there's 3 kinds of bills: 25, 50 and 100 rubles. There's no money in the ticket office in the beginning.
+
+Let's consider 3 cases.
+
+* Customer has 25 rubles hence he doesn't need a change.
+* Customer has 50 rubles hence we have to give him 25 rubles back.
+* Customer has 100 rubles hence we need to give him 75 rubles back. It can be done in 2 ways. 75=25+50 и 75=25+25+25. Notice that it's always worth to try 25+50 first and then 25+25+25. It's true because bills of 25 rubles can be used both to give change for 50 and 100 rubles and bills of 50 rubles can be used only to give change for 100 rubles so we need to save as much 25 ruble bills as possible.
+
+The solution is to keep track of the number of 25 and 50 ruble bills and act greedily when giving change to 100 rubles — try 25+50 first and then 25+25+25.
+
+### [349B - Color the Fence](/contest/349/problem/B "Codeforces Round 202 (Div. 2)")
+
+In the problem you're asked to write the largest possible number given number of paint that you have and number of paint that you need to write each digit.
+
+Longer number means larger number so it's worth to write the longest possible number. Because of that we choose the largest digit among those that require the least number of paint. Let the number of paint for that digit *d* be equal to *x*, and we have *v* liters of paint total. Then we can write number of the length .
+
+Now we know the length of the number, let it be *len*. Write down temporary result – string of length *len*, consisting of digits *d*. We have supply of *v*–*len*·*x* liters of paint. In order to enhance the answer, we can try to update the number from the beginning and swap each digit with the maximal possible. It's true because numbers of the equal length are compared in the highest digits first. Among digits that are greater than current we choose one that we have enough paint for and then update answer and current number of paint.
+
+If the length of the answer is 0 then you need to output -1.
+
+### [348A - Mafia](/contest/348/problem/A "Codeforces Round 202 (Div. 1)")
+
+In the problem you need to find out how many games you need to play in order to make all people happy. It means that each of them played as many games as he wanted.
+
+Let the answer be *x* games. Notice that *max*(*a*1, *a*2, …, *a**n*) ≤ *x*. Then *i*-th player can be game supervisor in *x*–*a**i* games. If we sum up we get 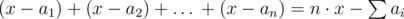 — it's the number of games in which players are ready to be supervisor. This number must be greater or equal to *x* — our answer.
+
+ 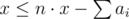
+
+ 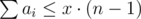
+
+ 
+
+ 
+
+Don't forget about that condition: *max*(*a*1, *a*2, …, *a**n*) ≤ *x*.
+
+### [348B - Apple Tree](/contest/348/problem/B "Codeforces Round 202 (Div. 1)")
+
+In the problem you need to find out minimal number of apples that you need to remove in order to make tree balanced.
+
+Notice, that if we know the value in the root then we know values in all other vertices. The value in the leaf is equal to the value in the root divided to the product of the powers of all vertices on the path between root and leaf.
+
+For every vertex let's calculate *d**i* — minimal number in that vertex (not zero) in order to make tree balanced. For leaves *d**i* = 1, for all other vertices *d**i* is equal to *k*·*lcm*(*d**j*1, *d**j*2, ..., *d**j**k*), where *j*1, *j*2, ..., *j**k* — sons of the vertex *i*. Let's calculate *s**i* — sum in the subtree of the vertex *i*. All that can be done using one depth first search from the root of the tree.
+
+Using second depth first search one can calculate for every vertex maximal number that we can write in it and satisfty all conditions. More precisely, given vertex *i* and *k* of its sons *j*1, *j*2, ..., *j**k*. Then if *m* = *min*(*s**j*1, *s**j*2, ..., *s**j**k*) and  — minimal number, that we can write to the sons of vertex *i*, then it's worth to write numbers  to the sons of vertex *i*. Remains  we add to the answer.
+
+### [348C - Subset Sums](/contest/348/problem/C "Codeforces Round 202 (Div. 1)")
+
+This problem is about data structures.
+
+First step of the solution is to divide sets to heavy and light. Light ones are those that contains less than  elements. All other sets are heavy.
+
+Key observation is that every light set contains less than  elements and number of heavy sets doesn't exceed  because we have upper bound for sum of the sizes of all sets.
+
+In order to effectively answer queries, for every set (both light and heavy) we calculate size of the intersection of this set and each heavy set. It can be done with time and memory . For every heavy set we create boolean array of size *O*(*n*). In *i*-th cell of this array we store how many elements *i* in given set. Then for each element and each heavy set we can check for *O*(1) time whether element is in the set.
+
+Now let's consider 4 possible cases:
+
+* *Add to the light set.* Traverse all numbers in the set and add the value from the query to each of them. Then traverse all heavy sets and add (size of intersection * the value from the query). Time is 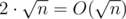.
+* *Add to the heavy set.* Just update the counter for the heavy set. Time is *O*(1).
+* *Answer to the query for the light set.* Traverse all numbers in the set and add values to the answer. Then traverse all heavy sets and add to the answer (answer for this heavy set * size of intersection with the set in the query). Time is 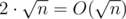.
+* *Answer to the query for the heavy set.* Take already calculated answer, then traverse all heavy sets and add (answer for this heavy set * size of intersection with the set in the query). Time is 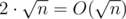.
+
+We have *O*(*n*) queries so total time is .
+
+### [348D - Turtles](/contest/348/problem/D "Codeforces Round 202 (Div. 1)")
+
+In the problem you're asked to find the number of pairs of non-intersecting paths between left upper and right lower corners of the grid. You can use following [lemma](https://en.wikipedia.org/wiki/Lindstr%C3%B6m%E2%80%93Gessel%E2%80%93Viennot_lemma) for that. Thanks to [rng_58](/profile/rng_58 "International Grandmaster rng_58") for the link. More precisely, considering our problem, this lemma states that given sets of initial *A* = {*a*1, *a*2} and final *B* = {*b*1, *b*2} points, the answer is equal to the following determinant:
+
+ 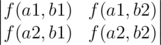 where *f*(*x*, *y*) — is equal to the number of paths from point *x* to point *y*. You can calculate this function using dynamic programming.
+
+Finally we need to decide what sets of initial and final points we choose. You can take *A* = {(0, 1), (1, 0)} and *B* = {(*n* - 2, *m* - 1), (*n* - 1, *m* - 2)} in order to make paths non-intersecting even in 2 points.
+
+### [348E - Pilgrims](/contest/348/problem/E "Codeforces Round 202 (Div. 1)")
+
+Let’s build a simple solution at first and then we will try to improve it to solve problem more effectively given the constraints.
+
+For every vertex let’s find the list of the farthest vertices. Let’s find vertices on the intersection of the paths between current vertex and each vertex from the list that don’t contain monasteries. If we remove any of these vertices then every vertex from the list is unreachable from the current monastery. For every vertex from the intersection increment the counter. Then the answer for the problem is the maximum among all counters and the number of such maxima.
+
+Let’s solve the problem more effectively using the same idea. Let’s make the tree with root. For every vertex we will find the list of the farthest vertices only in the subtree. While traversing the tree using depth first search we return the largest depth in the subtree and the number of the vertex where it was reached. Among all of the sons of the current vertex we choose the maximum of depths. If maximum is reached one time then we return the same answer that was returned from the son. If the answer was reached more than one time then we return the number of the current vertex. Essentially, we find LCA of the farthest vertices according to the current vertex. Before quitting the vertex we increment the values on the segment between current vertex and found LCA. One can use Eulerian tour and segment tree for adding on the segment.
+
+Finally, the last stage of solving the problem – to solve it for the case when the farthest vertex is not in the subtree of the current vertex. For solving of that subproblem we use the same idea that was used in the problem of the finding the maximal path in the tree. For every vertex we keep 3 maximums – 3 farthest vertices in the subtree. When we go down to the subtree, we pass 2 remaining maximums too. In that way, when we’re in any vertex, we can decide whether there’s a path not in the subtree (it means, going up) of the same or larger length. If there’re 2 paths of the same length in the subtree and not in the subtree, it means that for the pilgrim from the current monastery there’s always a path no matter what town was destroyed. If one of the quantities is larger then we choose the segment in Eulerian tour and increment the value on the segment. The case where there’s several paths (at least 2) out of the subtree of the same maximal length, is the same with the case in the subtree.
+
+LCA and segment tree can be solved effectively in *O*(*logN*) time per query so the total memory and time is *O*(*NlogN*).
diff --git a/editorials/350.md b/editorials/350.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/9042
+
+## [350A - TL](/contest/350/problem/A "Codeforces Round 203 (Div. 2)")
+
+Let's *v* = *min*(*a**i*), *p* = *max*(*a**i*), *c* = *min*(*b**i*). So, if *max*(2 * *v*, *p*) < *c*, then answer is *max*(2 * *v*, *p*), else answer is - 1.
+
+Author solution: [4632352](/contest/350/submission/4632352 "Submission 4632352 by gridnevvvit")
+
+## [350B - Resort](/contest/350/problem/B "Codeforces Round 203 (Div. 2)")
+
+Input data represents a graph, by using a array of parents of every vertex. Because every vertex has at most one parent, we can use following solution: we will go up to parent of vertex *v* (*prev*[*v*]) until not found vertex with the outcome degree ≥ 2. It is better to calculate outcome degrees in advance. After all, we will update the answer.
+
+This algorithm works in *O*(*n*).
+
+Author solution: [4632399](/contest/350/submission/4632399 "Submission 4632399 by gridnevvvit")
+
+## [350C - Bombs](/contest/350/problem/C "Codeforces Round 203 (Div. 2)")
+
+First of all, Let's sort all point by increasing of value |*x**i*| + |*y**i*|, all points we will process by using this order. We will process each point greedily, by using maximum six moves. Now we want to come to the point (*x*, *y*). Let's *x* ≠ 0. Then we need to move exactly |*x*| in the *dir* direction (if *x* < 0 the dir is *L*, *x* > 0 — *R*). Similarly we will work with *y*-coordinates of point (*x*, *y*). Now we at the point (*x*, *y*), let's pick a bomb at point (*x*, *y*). After that we should come back to point (0, 0). Why it is correct to sort all point by increasing of [Manhattan distance](https://en.wikipedia.org/wiki/Taxicab_geometry)? If you will look at the path that we have received, you can notice that all points of path have lower Manhattan distance, i.e. we will process this points earlier.
+
+This solution works in 
+
+Authors solution: [4632478](/contest/350/submission/4632478 "Submission 4632478 by gridnevvvit")
+
+## [350D - Looking for Owls](/contest/350/problem/D "Codeforces Round 203 (Div. 2)")
+
+It's possible to solve this problem by using only integer calculations. Normalization of the line *Ax* + *By* + *C* is following operation: we multiply our equation on the value , where *g* = *gcd*(*A*, *gcd*(*B*, *C*)), if *A* < 0 (*orA* = 0*andB* < 0) then *sgn* equals to - 1, else sgn equals to 1.
+
+Now the solution. We will have two maps (map<> in С++, TreeMap(HashMap) in Java) to a set of points (it's possible that some points will have multiply occurrence into the set). In first map we will store right boundaries of the segments, in second — left boundaries (in increasing order).
+
+In advance for every segment we will build a normalized line, and for this normalized line we will put in our maps left and right segments of the segment.
+
+After all, for every fixed line let's sort our sets.
+
+Let's fix two different circles. After that, let's check that distance beetween them is greater then sum their radiuses, also you should check that circles has same radius. We can assume that we builded a line between centers of circles (*x*1, *y*1) and (*x*2, *y*2). Perpendicular to this line will have next coefficients (center of the segment [(*x*1, *y*1), (*x*2, *y*2)] also will belong to the next line) *A* = 2(*x*1 - *x*2), *B* = 2(*y*1 - *y*2), *C* = - ((*x*1 - *x*2) * (*x*1 + *x*2) + (*y*1 - *y*2) * (*y*1 + *y*2)). After that you need to calculate values *cntL*, *cntR* by using binary search on set of points that lie on this line. *cntL* — amount of left boundaries that lie on the right side of point ((*x*1 + *x*2) / 2, (*y*1 + *y*2) / 2), *cntR* -- amount of right boundaries that lie on the left side of the point ((*x*1 + *x*2) / 2, (*y*1 + *y*2) / 2). After that you should add to answer value *cntV* - *cntR* - *cntL*,l where *cntV* — amount of segments, that lie on the nolmalized line.
+
+Total complexity: 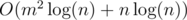.
+
+solution: [4632546](/contest/350/submission/4632546 "Submission 4632546 by gridnevvvit")
+
+## [350E - Wrong Floyd](/contest/350/problem/E "Codeforces Round 203 (Div. 2)")
+
+Let's do the following: construct the graph with the maximum possible number of edges and then remove the excess. First of all, you can notice that if *k* = *n* answer is - 1. Else let's fix some marked vertex, for example *a*1. Let's put in our graph all edges except edges beetween *a*1 and *x*, where *x* — an another marked vertex.
+
+So, why this algorithm is correct? If Valera's algorithm is wrong, then there are a ''bad'' pair of vertexes (i, j). ``Bad'' pair is a pair for that Valera's algorithm works wrong. So, there are not marked vertex *v* on the shortest path from i to j, and *v* ≠ *i*, and *v* ≠ *j*. Without loss of generality, we can assume, that distance beetween *i* and *j* equals to 2, but Valera's algorithm gives greater answer. There are some cases, that depends on the type of vertexes *i*, *j*. But we can look only at the case where (*i*, *j*) are marked vertexes. First, add to the graph all edges beetween not fixed (*i*, *j*) vertexes. Second, add to the graph edges beetween some fixed vertex (*i* or *j*) and some not marked vertex. Third, add to the graph edges beetween *i* and some marked vertex *v*, where *v* ≠ *j*. It's simple to understand, that if we add some another edge, the Valera's algorithm will work correctly. Total amount of edges is 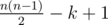.
+
+**BONUS** Simple bonus. For same contrains (*n*, *m*, *k*) can you build a graph, where Valera's code works correctly?
+
+Код: [4632600](/contest/350/submission/4632600 "Submission 4632600 by gridnevvvit")
diff --git a/editorials/351.md b/editorials/351.md
@@ -0,0 +1,91 @@
+Source: https://codeforces.com/blog/entry/9070
+
+### Editorial for Codeforces Round #204
+
+#### [352A - Jeff and Digits](/contest/352/problem/A "Codeforces Round 204 (Div. 2)")
+
+Solution is looking for few cases:
+1. If we do not have zeros, then the answer is -1.
+2. If we have less than 9 fives, then the answer is 0.
+3. Otherwise, the answer is:
+4. 1. The maximum number of fives divisible by 9
+4. 2. All zeros, we have
+
+#### [352B - Jeff and Periods](/contest/352/problem/B "Codeforces Round 204 (Div. 2)")
+
+We will go through the array from left to right. At each step, we will store the arrays:
+1. *next**x* — the last occurrence of the number *x*
+2. *period**x* — period, which occurs *x*
+3. *fail**x* — whether a time when the number of *x* no longer fit
+
+Now, when we get a new number we considering the case when it is the first, second or occurred more than twice.
+All the cases described in any past system testing solution.
+
+#### [351A - Jeff and Rounding](/contest/351/problem/A "Codeforces Round 204 (Div. 1)")
+
+Initially, we should remember the number of integers — *C*. On next step we will round down all numbers and count the sum. Now we can change the sum, rounding up some numbers, with those not matter what kind of, the main thing — how many. Consider a couple what we could get:
+1. (*int*, *int*) (*c*1)
+2. (*int*, *double*) (*c*2)
+3. (*double*, *int*) (*c*3)
+4. (*double*, *double*) (*c*4)
+
+Iterate over the number of pairs of the first type. Then we know the total number of second and third type and number of the fourth type:
+1. *c*2 + *c*3 = *C* - 2*c*1
+2. *c*4 = *N* - (*c*1 + *c*2 + *c*3)
+Check to see if you can get such numbers (enough for us count of integers and real numbers, respectively). We find that we can round up from *c*4 to *c*4 + *c*2 + *c*3 numbers. We will find the best choise.
+
+#### [351B - Jeff and Furik](/contest/351/problem/B "Codeforces Round 204 (Div. 1)")
+
+ote that after each step, the number of inversions in the permutation is changed by **1**. Let us turn to the inversions of the permutation — let them be *I* pcs. It is clear that when we have one inversion, then the answer — 1. Now we will see how to use it further:
+1. it is clear that after a Jeff's step inversions will become lower by 1
+2. it is clear that after a Furik's step inversions will be on 1 lowerwith porbability of 0, 5, and on 1 greater with probability of 0, 5.
+3. we have the formula for an answer *ans**I* = 1 + 1 + *ans**I* - 1 - 1 × 0.5 + *ans**I* - 1 + 1 × 0.5
+4. after transformation we have *ans**I* = 4 + *ans**I* - 2.
+
+#### [351C - Jeff and Brackets](/contest/351/problem/C "Codeforces Round 204 (Div. 1)")
+
+How to solve the problem for small *NM*? Just use the dynamic programming *dp**i*, *j* — minimum cost to build *i* first brackets with the balance *j*. Transfers are simple:
+1. *dp**i*, *j* + *a**i* + 1 -> *dp**i* + 1, *j* + 1
+2. *dp**i*, *j* + *b**i* + 1 -> *dp**i* + 1, *j* - 1
+3. we make transfers only when balance will be non-negative
+4. starting state *dp*0, 0 = 0
+
+In this problem, we can assume that the balance will never exceed 2*N*. The proof is left as homework.
+
+And by using this fact problem can be done by erecting a matrix to the power:
+1. lets *T**i*, *j* — cost of transfer from balance *i* to balance *j*, using *N* brackets
+2. (*T**M*)0, 0 — answer to the problem
+
+#### [351D - Jeff and Removing Periods](/contest/351/problem/D "Codeforces Round 204 (Div. 1)")
+
+After the first request we can sort the numbers and for further moves will be able to remove all occurrences of a certain number. So the answer is the number of different numbers + 1 if there is no number, occurrence of which form an arithmetic progression.
+
+Number of different numbers on a segment — standart problem, can be done *O*(*N*1.5) with offline algorithm.
+
+The problem about finding the right number will be solved in a similar algorithm:
+1. lets sort queries like pairs (*l**i* / 300, *r**i*), we use integer dividing
+2. learn how to move from the interval (*l*, *r*) to intervals (*l* - 1, *r*), (*l* + 1, *r*), (*l*, *r* - 1), (*l*, *r* + 1) with complexcity *O*(1)
+3. by means of such an operation will move from one segment to the next, in the amount of the operation algorithm will works *O*(*N*1.5)
+
+It remains to learn how to make the change on the interval by 1 element. Such a problem can be solved quite simply:
+1. we craete *deque* for all value of numbers in array
+2. depending on changes in the segment will add / remove items to the start / end of the respective *deque*
+3. check whether the resulting *deque* is arithmetic progression. it will be homework.
+
+#### [351E - Jeff and Permutation](/contest/351/problem/E "Codeforces Round 204 (Div. 1)")
+
+We make the zero step, replace the elements on their modules.
+
+The first thing you need to understand the way in which we will build our response. After selecting a few ways to understand the fact that initially you need to determine the sign of the largest numbers.
+
+Consider the case where the current step we have only one maximal element. It is clear that if you put a sign - all the elements on the left of this will form an inversion, while on the right there will be no inversions. If we do not put a sign - it will all be the opposite. We select the best one and cross out the number of the array, it will not affect to some inversion.
+
+Now we should understand how to read the response when the highs more than one. We write the dynamics **dp[i][j]** — how much inversions can you get, when we looked at the first **i** higest values and **j** from them lefted as possitive. Of these dynamics is not difficult to make the transition and get the answer.
+
+And so we have a simple and short algorithm:
+1. Iterates until the array is not empty
+2. Find all the maximal elements
+3. Calculate dynamics and find right signs
+4. Remove elements from an array
+
+#### *For more details view any passed system tests solution.*
diff --git a/editorials/353.md b/editorials/353.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/9145
+
+[353A - Domino](/contest/353/problem/A "Codeforces Round 205 (Div. 2)")
+
+Let's denote the sum of numbers on the upper halves of pieces as *s*1, and the sum on the lower halves — *s*2. If this sums are even, than the answer is obviously 0. Note, that if the numbers on both halves of piece have the same parity, than parity of *s*1 and *s*2 won't change after rotation this piece. If the numbers on halves have different parity, than parities of both *s*1 and *s*2 will change after rotation. Therefore, if *s*1 and *s*2 have different parities, than the answer is - 1. If both *s*1 and *s*2 are odd, than we should check, if there is a piece with numbers of different parities. If so, the answer is 1, otherwise, the answer is - 1.
+
+[353B - Two Heaps](/contest/353/problem/B "Codeforces Round 205 (Div. 2)")
+
+Let's say for shortness, that we put numbers, that are painted on cubes, in piles, instead of cubes themselves.
+
+Note, that the answer is the product of *c*1... *c*2, where *c**i* is the number of different numbers in the *i*-th pile. Let's consider that all numbers are different. In this case the answer is *n*2. Now, let's suppose that we have two equal numbers and all the other are different. Then, if we put them in different piles, the answer will be *n*2, but if we put them in one — *n*·(*n* - 1). Obviously, the first case give greater product.
+
+Thinking in similar manner, you can conclude, that we should do the following. Take numbers, that appear more than once, and put one of them in the first pile, one of them in the second pile and the other put aside. After that, divide the numbers, that appears once, in two equal part and put the first part in the first pile and second part in the second pile. Finally, take the numbers, that we put aside, and separate them in two pile in any kind.
+
+[353C - Find Maximum](/contest/353/problem/C "Codeforces Round 205 (Div. 2)")
+
+Let's see on the highest bit of *m*. If it equals to zero, than for any  there is a zero on the (*n* - 1)-th position, so *a**n* - 1 doesn't affect the answer and we can put it aside and find the answer for smaller number of elements.
+
+If the highest bit of *m* equals to 1, than *a**n* - 1 for some *x* will present in *f*(*x*), but for some will not. Let's consider such *x*, that *a*{*n* - 1} will present in *f*(*x*) with zero coefficient. It is obvious that 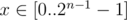. In this case *f*(*x*) will have maximum value when *x* = 2*n* - 1 - 1. Try to update the answer by this value.
+
+Now we should analyze the case, when 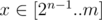, find the maximum value of *f*(*x*) for all such *x* and try to update the answer by this value. Let's note, that in all such *x* there is 1 in (*n* - 1)-th position. Therefore we can find the maximum value of *f*(*y*) for all 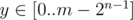 and add *a**n* - 1 to it.
+
+[353D - Queue](/contest/353/problem/D "Codeforces Round 205 (Div. 2)")
+
+Note that if there are some girls in the begining of the line, they will never move. So let's remove them and will consider that the first schoolchildren in the line is a boy. Also note, the relative order of the girls doesn't change. Let's calculate for each girl such moment of time *t**i*, that after it she won't move forever. Note, that for *i*-th girl *t**i* ≥ *t**i* - 1. Let's calculate *t**i* in order from left to right. Let's denote *y**i* is the position in the line where *i*-th girl will stop, ans *x**i* is her current position. Therefore it is needed *x**i* - *y**i* second for girl to reach her finish position. So if *x**i* - *y**i* > *t**i* - 1, then *t**i* = *x**i* - *y**i*. Let's manage the case when *x**i* - *y**i* ≤ *t**i*. The girl with number (*i* - 1) will be on *y**i*-th position by *t**i* - 1-th second, so *t**i* ≥ *t**i* - 1 + 1. Let's consider such moment of time *p*, when *i*-th girl stand right after (*i* - 1)-th, but not on *y**i*-th position. After that, in (*p* + 1)-th moment of time (*i* - 1)-th girl and the boy standing in front of her will swap their positions, but *i*-th girl will save her position. Then since *p* + 2-th second till *t**i* - 1 both girls will change their positions. Finally, at (*t**i* - 1 + 1) - *th* second *i*-th girl will occupy her position. Therefore, *t**i* = *t**i* - 1 + 1 in this case.
+
+[353E - Antichain](/contest/353/problem/E "Codeforces Round 205 (Div. 2)")
+
+Let's divide our graph on chains. Denote chain as the maximal sequence of the edges, which have the same direction. If there are more than 2 edges in each chain, then the answer is the number of such chains.
+
+If there is a chain containing only one edge (*u*, *v*), then brute vertex, which we will take in maximal antichain (also consider the case, when we take none of them). Let's suppose we brute the vertex *v*. After that we put aside this vertex and all vertices, which is comparable with *v*. In received graph we can find the size of the maximal antichain by uning dynamic programming with *O*(*n*) time complexity. Let's show how to do this.
+
+Write all remaining vertices in line and renumerate them from left to right by the numbers from 1 to *k*. After that we are going to calculate *d**i* — the size of the maximal antichain among vertices with numbers *j* ≥ *i*. So if *i* > *k*, then *d**i* = 0. In other case we can skip *i*-th vertex and try to update *d**i* by the value of *d**i* + 1. Also we can try to take *i*-th vertex to the answer. In this case we should skip all vertices, that are reachable from *i*-th, or the vertices, from which we can reach *i*-th, take the answer from the next vertex, add 1 to it and try to update the answer.
diff --git a/editorials/354.md b/editorials/354.md
@@ -0,0 +1,138 @@
+Source: https://codeforces.com/blog/entry/8672
+
+[355A - Vasya and Digital Root](/contest/355/problem/A "Codeforces Round 206 (Div. 2)")
+
+If *d* = 0, the there is the only number with , so, if *k* = 1, the answer is 0, otherwise — *No* *solution*.
+
+If *d* > 0, then one of correct numbers is *d* × 10*k* - 1.
+
+Time complexity: *O*(1) + *O*(*k*) for the output.
+
+[355B - Vasya and Public Transport](/contest/355/problem/B "Codeforces Round 206 (Div. 2)")
+
+If we buy a ticket of the fourth type, we don't have to buy anything else, so, the answer is *min*(*c*4, *answer* *using* *tickets* *of* *first* *three* *types*).
+
+Now, when we don't have ticket of the fourth type, we can solve the task separately for buses and trolleys.
+
+Solving the problem only for buses: if we buy a ticket of the third type, we don't have to buy anything else, so, the answer is *min*(*c*3, *answer* *using* *tickets* *of* *first* *two* *types*).
+
+Without tickets of type three, we can solve the problem separately for each bus. If we buy a ticket of the second type, we will spend *c*2 burles and if we buy *a**i* tickets of the first type, we will spend (*a**i* × *c*1) burles. So, the answer for bus *i* is *min*(*c*2, *a**i* × *c*1).
+
+Now it is not difficult to obtain the following solution:
+
+```
+ function f(x, k) {
+ res = 0;
+ for i = 1 .. k
+ res = res + min(c2, x[i] * c1);
+
+ return min(c3, res);
+ }
+
+ ans = min(c4, f(a, n) + f(b, m));
+```
+
+Time complexity: *O*(*n* + *m*).
+
+[354A - Vasya and Robot](/contest/354/problem/A "Codeforces Round 206 (Div. 1)")
+
+Brute force how many times we will use operation from the left. So, if we use it *k* times, then it's clear, that we will take first *k* items by the left operations and last (*n* - *k*) items by the right operations. So, robot will spend *sumLeft*[*k*]·*l* + *sumRight*[*n* - *k*]·*r* energy plus some penalty for the same operations. To minimize this penalty we should perform the operations in the following order LRLRL ... RLRLLLLL ..., starting from the bigger set. For example, if *k* = 7, *n* - *k* = 4, we should perform operations in this order: LRLRLRLRL **LL**. So, we will have to pay the penalty two times (7 - 4 - 1).
+
+*sumLeft*[*i*] — sum of first *i* weights, *sumRight*[*i*] — sum of last *i* weights.
+
+Solution in pseudocode:
+
+```
+ ans = inf;
+ for i = 0 .. n {
+ curr = firstSum[i] * l + lastSum[n-i] * r;
+ if ( i > n - i ) curr = curr + (2i - n - 1) * Ql;
+ if ( i < n - i ) curr = curr + (n - 2i - 1) * Qr;
+
+ ans = min(ans, curr);
+ }
+```
+
+Time complexity: *O*(*n*).
+
+[354B - Game with Strings](/contest/354/problem/B "Codeforces Round 206 (Div. 1)")
+
+We will say that cell (*r*, *c*) corresponds to a string *s*, if there exist correct path, which ends in the cell (*r*, *c*) and this path corresponds to a string *s*.
+
+Let call a set of cells which corresponds to some string *s* a state. One state can correspond to different strings. We can't brute force all possible strings, because their count —  is too big, but we can brute force all possible states. It's not hard to observe that all cells that corresponds to some string *s* lies on same diagonal, so the total count of states is 21 + 22 + ... + 2*n* - 1 + 2*n* + 2*n* - 1 + ... + 22 + 21 = *O*(2*n*). In implementation we can denote state with diagonal number (from 1 to 2*n* - 1) and bitmask of cells corresponding to this state (2*n*).
+
+From each state we can move to 26 different states (actually less) and all possible moves depends on the state, not on the string. On the image you can see an example of move: from state, which is highlighted in blue by letter *a* we will move to the state, which is highlighted in yellow.
+
+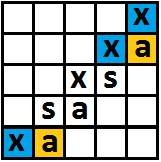
+
+Now, for each state we can calculate a value of (count of letters A - count of letters B) in the string, starting from this state. If at the moment is first players turn (an even diagonal), we have to maximize this value, otherwise — minimize. It can be implemented as recursion with memoization.
+
+The winner can be determined by the value of state, which corresponds to the single cell (1, 1).
+
+Complexity: *O*(2*n* × (*n* + *alpha*)), where *alpha* is the size of alphabet.
+
+[354C - Vasya and Beautiful Arrays](/contest/354/problem/C "Codeforces Round 206 (Div. 1)")
+
+The problem was to find greatest *d*, such that *a**i* ≥ *d*, *a**i* *mod* *d* ≤ *k* holds for each *i*.
+
+Let *m* = *min*(*a**i*), then *d* ≤ *m*. Let consider two cases:
+
+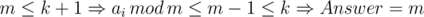
+
+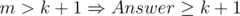. In this case we will brute force answer from *k* + 1 to *m*. We can check, if number *d* is a correct answer in the following way:
+
+We have to check that *a**i* *mod* *d* ≤ *k* for some fixed *d*, which is equals to 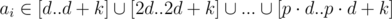, where . Since all these intervals [*x*·*d*..*x*·*d* + *k*] doesn't intersects each with other, we can just check that 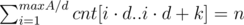, where *cnt*[*l*..*r*] — count of numbers *a**i* in the interval [*l*..*r*].
+
+Time complexity: *O*(*maxA* *log* *maxA*), proof is based on the sum of [harmonic series](https://ru.wikipedia.org/wiki/%D0%93%D0%B0%D1%80%D0%BC%D0%BE%D0%BD%D0%B8%D1%87%D0%B5%D1%81%D0%BA%D0%B8%D0%B9_%D1%80%D1%8F%D0%B4).
+
+[354D - Transferring Pyramid](/contest/354/problem/D "Codeforces Round 206 (Div. 1)")
+
+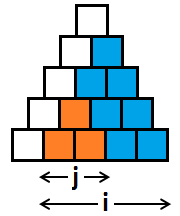
+
+This tasks is solvable with dynamic programming. First of all let consider solution with complexity *O*(*n*3).
+
+Let *dp*[*i*][*j*] be the answer for the highlighted in blue part (minimal cost of transferring all special cells that lies inside this area). Then *dp*[*n*][0] will be the answer for our original problem.
+
+How to recalculate such DP? It's clear that in the leftmost column (inside the blue area) we will choose at most one cell as the top of some subpyramid. If we choose two, then the smallest one will lie fully inside the biggest one (as the orange subpyramid lies inside the blue one). Now, let brute force the cell, which will be the top of subpyramid in this column in time *O*(*n*) and we will obtain the following transition:
+
+To simplify the formulas, let assume that 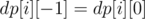.
+
+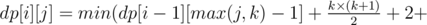 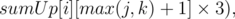 0 ≤ *k* ≤ *i*, where *k* is the height on which we will choose our top cell, or 0, if we don't choose any subpyramid in this column. *sumUp*[*i*][*p*] — count of special cells in the *i*-th column at height starting from *p*, this cells we will have to transfer one by one, using the first type operations.
+
+We can reduce the complexity by one *n*, if we will recalculate out DP in the following way:
+
+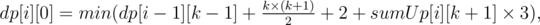 0 ≤ *k* ≤ *i*;
+
+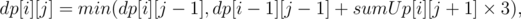 for all *j* > 0.
+
+The proof that this is correct is quite simple and is left to the reader. :)
+
+Also, we can observe that it is not profitably to take some subpyramid with height greater than , because for such subpyramid we will pay > 3*k*, but if we transfer all cells using the first type operations we will pay only 3*k*. So, the second dimension (*j*) in out DP can be reduced to .
+
+Also, to receive AC, you should store only last 2 layers of the DP, otherwise there will be not enough memory.
+
+Time complexity: .
+
+[354E - Lucky Number Representation](/contest/354/problem/E "Codeforces Round 206 (Div. 1)")
+
+Author's solution, much more complicated than suggested by many participants during the competition, easy solution will be described below.
+
+First of all, let write a DP with complexity *O*(*N* * *lucky*_*count*(*N*)), where *lucky*_*count*(*N*) is the count of lucky numbers ≤ *N*, *lucky*_*count*(10*n*) = 3*n*. As we can see, for all sufficiently large *N* solution exists. Really — for every *N* > 523.
+
+Now, we can say that for *N* ≤ 10000 we have a solution, which is found using DP. Let's solve the task for larger values of *N*.
+
+Next and key idea is to separate the task into two parts: *N* = *N*1 + *N*2. Let's choose *N*1 and *N*2 in such way that for them it was easy to find a solution and then merge these two solutions into one. Let *N*1 = *N* *mod* 4000, *N*2 = *N* - *N*1. Here we can have a problem that there is no solution for number *N*1, in this case we can do *N*1 = *N*1 + 4000, *N*2 = *N*2 - 4000.
+
+Now it is guaranteed that solutions exists for both *N*1 and *N*2, moreover, the solution for number *N*1 will contain only numbers of not more than 3 digits ( < 1000). The proof is quite easy: if *N*1 < 4000 — it is obvious; else — if the solution uses some number of the form (4000 + *some*_*lucky*_*number*), we can replace it with just *some*_*lucky*_*number* and receive a correct solution for number (*N*1 - 4000), but is doesn't exist!
+
+So, the solution for number *N*1 we have found using DP, now let's find the solution for *N*2. If it will contains only of numbers of the form (*some*_*lucky*_*number* × 1000), then we will be able to easily merge this solution with solution for *N*1, so, let's find such a solution. Here we will use the fact that *N*2 is divisible by 4. For simplicity, let's divide *N*2 by 1000 and in the end multiply all *Ans*2(*i*) by the same 1000. Let *P* = *N*2 / 4. Now, let's construct the solution. Consider, for example, P = 95: we will walk through digits of this number, last digit — 5, means that we want to put digit 4 at the last decimal position of five answer numbers — ok, put it and in the last, sixth, number leave there digit 0. Go forward, digit 9 — we don't have nine numbers, but we can replace seven fours with four sevens, then to the second position we have to put (9 - 7) fours and 4 sevens, in total — 6 numbers, exactly as much as we have.
+
+Thus, if next digit *d* ≤ 6, we just put to the first *d* answer numbers digit 4 to the next position; if *d* > 6, then we put 4 sevens and (*d* - 7) fours. In all other numbers we just leave digit 0 at this position.
+
+If *Ans*1(*i*) — answer for *N*1, *Ans*2(*i*) — for *N*2, the the answer for *N* will be just *Ans*(*i*) = *Ans*1(*i*) + *Ans*2(*i*).
+
+Time complexity for one number: *O*(*logN*).
+
+During the competition many participants have wrote the following solution:
+
+*dp*[*i*][*j*] — can we put the digit to the last *i* decimal positions of the answer number in such way that we will get correct last *i* digits in the sum and with carry to the next position equals to *j*. Then the solution exist iff *dp*[19][0] = *true*. To restore the answer we just have to remember for each state the previous state. Base — *dp*[0][0] = *true*. Transition — brute force how many fours and sevens we will put to the *i*-th position.
diff --git a/editorials/355.md b/editorials/355.md
@@ -0,0 +1,138 @@
+Source: https://codeforces.com/blog/entry/8672
+
+[355A - Vasya and Digital Root](/contest/355/problem/A "Codeforces Round 206 (Div. 2)")
+
+If *d* = 0, the there is the only number with 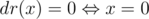, so, if *k* = 1, the answer is 0, otherwise — *No* *solution*.
+
+If *d* > 0, then one of correct numbers is *d* × 10*k* - 1.
+
+Time complexity: *O*(1) + *O*(*k*) for the output.
+
+[355B - Vasya and Public Transport](/contest/355/problem/B "Codeforces Round 206 (Div. 2)")
+
+If we buy a ticket of the fourth type, we don't have to buy anything else, so, the answer is *min*(*c*4, *answer* *using* *tickets* *of* *first* *three* *types*).
+
+Now, when we don't have ticket of the fourth type, we can solve the task separately for buses and trolleys.
+
+Solving the problem only for buses: if we buy a ticket of the third type, we don't have to buy anything else, so, the answer is *min*(*c*3, *answer* *using* *tickets* *of* *first* *two* *types*).
+
+Without tickets of type three, we can solve the problem separately for each bus. If we buy a ticket of the second type, we will spend *c*2 burles and if we buy *a**i* tickets of the first type, we will spend (*a**i* × *c*1) burles. So, the answer for bus *i* is *min*(*c*2, *a**i* × *c*1).
+
+Now it is not difficult to obtain the following solution:
+
+```
+ function f(x, k) {
+ res = 0;
+ for i = 1 .. k
+ res = res + min(c2, x[i] * c1);
+
+ return min(c3, res);
+ }
+
+ ans = min(c4, f(a, n) + f(b, m));
+```
+
+Time complexity: *O*(*n* + *m*).
+
+[354A - Vasya and Robot](/contest/354/problem/A "Codeforces Round 206 (Div. 1)")
+
+Brute force how many times we will use operation from the left. So, if we use it *k* times, then it's clear, that we will take first *k* items by the left operations and last (*n* - *k*) items by the right operations. So, robot will spend *sumLeft*[*k*]·*l* + *sumRight*[*n* - *k*]·*r* energy plus some penalty for the same operations. To minimize this penalty we should perform the operations in the following order LRLRL ... RLRLLLLL ..., starting from the bigger set. For example, if *k* = 7, *n* - *k* = 4, we should perform operations in this order: LRLRLRLRL **LL**. So, we will have to pay the penalty two times (7 - 4 - 1).
+
+*sumLeft*[*i*] — sum of first *i* weights, *sumRight*[*i*] — sum of last *i* weights.
+
+Solution in pseudocode:
+
+```
+ ans = inf;
+ for i = 0 .. n {
+ curr = firstSum[i] * l + lastSum[n-i] * r;
+ if ( i > n - i ) curr = curr + (2i - n - 1) * Ql;
+ if ( i < n - i ) curr = curr + (n - 2i - 1) * Qr;
+
+ ans = min(ans, curr);
+ }
+```
+
+Time complexity: *O*(*n*).
+
+[354B - Game with Strings](/contest/354/problem/B "Codeforces Round 206 (Div. 1)")
+
+We will say that cell (*r*, *c*) corresponds to a string *s*, if there exist correct path, which ends in the cell (*r*, *c*) and this path corresponds to a string *s*.
+
+Let call a set of cells which corresponds to some string *s* a state. One state can correspond to different strings. We can't brute force all possible strings, because their count —  is too big, but we can brute force all possible states. It's not hard to observe that all cells that corresponds to some string *s* lies on same diagonal, so the total count of states is 21 + 22 + ... + 2*n* - 1 + 2*n* + 2*n* - 1 + ... + 22 + 21 = *O*(2*n*). In implementation we can denote state with diagonal number (from 1 to 2*n* - 1) and bitmask of cells corresponding to this state (2*n*).
+
+From each state we can move to 26 different states (actually less) and all possible moves depends on the state, not on the string. On the image you can see an example of move: from state, which is highlighted in blue by letter *a* we will move to the state, which is highlighted in yellow.
+
+
+
+Now, for each state we can calculate a value of (count of letters A - count of letters B) in the string, starting from this state. If at the moment is first players turn (an even diagonal), we have to maximize this value, otherwise — minimize. It can be implemented as recursion with memoization.
+
+The winner can be determined by the value of state, which corresponds to the single cell (1, 1).
+
+Complexity: *O*(2*n* × (*n* + *alpha*)), where *alpha* is the size of alphabet.
+
+[354C - Vasya and Beautiful Arrays](/contest/354/problem/C "Codeforces Round 206 (Div. 1)")
+
+The problem was to find greatest *d*, such that *a**i* ≥ *d*, *a**i* *mod* *d* ≤ *k* holds for each *i*.
+
+Let *m* = *min*(*a**i*), then *d* ≤ *m*. Let consider two cases:
+
+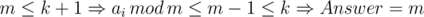
+
+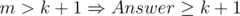. In this case we will brute force answer from *k* + 1 to *m*. We can check, if number *d* is a correct answer in the following way:
+
+We have to check that *a**i* *mod* *d* ≤ *k* for some fixed *d*, which is equals to 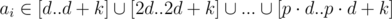, where . Since all these intervals [*x*·*d*..*x*·*d* + *k*] doesn't intersects each with other, we can just check that 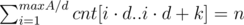, where *cnt*[*l*..*r*] — count of numbers *a**i* in the interval [*l*..*r*].
+
+Time complexity: *O*(*maxA* *log* *maxA*), proof is based on the sum of [harmonic series](https://ru.wikipedia.org/wiki/%D0%93%D0%B0%D1%80%D0%BC%D0%BE%D0%BD%D0%B8%D1%87%D0%B5%D1%81%D0%BA%D0%B8%D0%B9_%D1%80%D1%8F%D0%B4).
+
+[354D - Transferring Pyramid](/contest/354/problem/D "Codeforces Round 206 (Div. 1)")
+
+
+
+This tasks is solvable with dynamic programming. First of all let consider solution with complexity *O*(*n*3).
+
+Let *dp*[*i*][*j*] be the answer for the highlighted in blue part (minimal cost of transferring all special cells that lies inside this area). Then *dp*[*n*][0] will be the answer for our original problem.
+
+How to recalculate such DP? It's clear that in the leftmost column (inside the blue area) we will choose at most one cell as the top of some subpyramid. If we choose two, then the smallest one will lie fully inside the biggest one (as the orange subpyramid lies inside the blue one). Now, let brute force the cell, which will be the top of subpyramid in this column in time *O*(*n*) and we will obtain the following transition:
+
+To simplify the formulas, let assume that 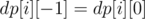.
+
+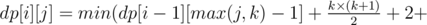 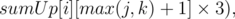 0 ≤ *k* ≤ *i*, where *k* is the height on which we will choose our top cell, or 0, if we don't choose any subpyramid in this column. *sumUp*[*i*][*p*] — count of special cells in the *i*-th column at height starting from *p*, this cells we will have to transfer one by one, using the first type operations.
+
+We can reduce the complexity by one *n*, if we will recalculate out DP in the following way:
+
+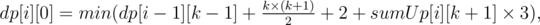 0 ≤ *k* ≤ *i*;
+
+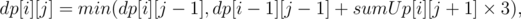 for all *j* > 0.
+
+The proof that this is correct is quite simple and is left to the reader. :)
+
+Also, we can observe that it is not profitably to take some subpyramid with height greater than , because for such subpyramid we will pay > 3*k*, but if we transfer all cells using the first type operations we will pay only 3*k*. So, the second dimension (*j*) in out DP can be reduced to .
+
+Also, to receive AC, you should store only last 2 layers of the DP, otherwise there will be not enough memory.
+
+Time complexity: .
+
+[354E - Lucky Number Representation](/contest/354/problem/E "Codeforces Round 206 (Div. 1)")
+
+Author's solution, much more complicated than suggested by many participants during the competition, easy solution will be described below.
+
+First of all, let write a DP with complexity *O*(*N* * *lucky*_*count*(*N*)), where *lucky*_*count*(*N*) is the count of lucky numbers ≤ *N*, *lucky*_*count*(10*n*) = 3*n*. As we can see, for all sufficiently large *N* solution exists. Really — for every *N* > 523.
+
+Now, we can say that for *N* ≤ 10000 we have a solution, which is found using DP. Let's solve the task for larger values of *N*.
+
+Next and key idea is to separate the task into two parts: *N* = *N*1 + *N*2. Let's choose *N*1 and *N*2 in such way that for them it was easy to find a solution and then merge these two solutions into one. Let *N*1 = *N* *mod* 4000, *N*2 = *N* - *N*1. Here we can have a problem that there is no solution for number *N*1, in this case we can do *N*1 = *N*1 + 4000, *N*2 = *N*2 - 4000.
+
+Now it is guaranteed that solutions exists for both *N*1 and *N*2, moreover, the solution for number *N*1 will contain only numbers of not more than 3 digits ( < 1000). The proof is quite easy: if *N*1 < 4000 — it is obvious; else — if the solution uses some number of the form (4000 + *some*_*lucky*_*number*), we can replace it with just *some*_*lucky*_*number* and receive a correct solution for number (*N*1 - 4000), but is doesn't exist!
+
+So, the solution for number *N*1 we have found using DP, now let's find the solution for *N*2. If it will contains only of numbers of the form (*some*_*lucky*_*number* × 1000), then we will be able to easily merge this solution with solution for *N*1, so, let's find such a solution. Here we will use the fact that *N*2 is divisible by 4. For simplicity, let's divide *N*2 by 1000 and in the end multiply all *Ans*2(*i*) by the same 1000. Let *P* = *N*2 / 4. Now, let's construct the solution. Consider, for example, P = 95: we will walk through digits of this number, last digit — 5, means that we want to put digit 4 at the last decimal position of five answer numbers — ok, put it and in the last, sixth, number leave there digit 0. Go forward, digit 9 — we don't have nine numbers, but we can replace seven fours with four sevens, then to the second position we have to put (9 - 7) fours and 4 sevens, in total — 6 numbers, exactly as much as we have.
+
+Thus, if next digit *d* ≤ 6, we just put to the first *d* answer numbers digit 4 to the next position; if *d* > 6, then we put 4 sevens and (*d* - 7) fours. In all other numbers we just leave digit 0 at this position.
+
+If *Ans*1(*i*) — answer for *N*1, *Ans*2(*i*) — for *N*2, the the answer for *N* will be just *Ans*(*i*) = *Ans*1(*i*) + *Ans*2(*i*).
+
+Time complexity for one number: *O*(*logN*).
+
+During the competition many participants have wrote the following solution:
+
+*dp*[*i*][*j*] — can we put the digit to the last *i* decimal positions of the answer number in such way that we will get correct last *i* digits in the sum and with carry to the next position equals to *j*. Then the solution exist iff *dp*[19][0] = *true*. To restore the answer we just have to remember for each state the previous state. Base — *dp*[0][0] = *true*. Transition — brute force how many fours and sevens we will put to the *i*-th position.
diff --git a/editorials/356.md b/editorials/356.md
@@ -0,0 +1,124 @@
+Source: https://codeforces.com/blog/entry/9210
+
+#### [357A - Group of Students](/contest/357/problem/A "Codeforces Round 207 (Div. 2)")
+
+In this problem you need to iterate over all possible values of passing rate from 1 to 100 and for each value calculate the sizes of two groups.
+
+#### [357B - Flag Day](/contest/357/problem/B "Codeforces Round 207 (Div. 2)")
+
+Let's process the dances in the given order and determine the colors of dancers' clothes. If there are no dancer from some previous dance, we can give the dances different colors arbitrarily. And if there is such dancer, we already know the color of his clothes. So, we arbitrarily distribute the other two colors between the remaning two dancers.
+
+#### [356A - Knight Tournament](/contest/356/problem/A "Codeforces Round 207 (Div. 1)")
+
+Let's the current fight (*l*, *r*, *x*) consists of *K* knights fighting. Then all we have to do is to find all these knights in time *O*(*K*) or *O*(*KlogN*). There are several ways to do that, let's consider some of them.
+
+The first way is to store the numbers of all alive knights in std::set (C++) or TreeSet (Java). Then in C++ we can use lower_bound method to find the first knight in the fight that is alive, and to iterate over this set, each time moving to the next alive knight. In Java we should use subSet method.
+
+```
+ set<int> alive;
+ for (int i = 0; i < n; i++)
+ alive.insert(i);
+
+ for (int i = 0; i < m; i++) {
+ int l, r, x;
+ scanf("%d%d%d", &l, &r, &x);
+ l--, r--, x--;
+ set<int>::iterator it = alive.lower_bound(l);
+ vector<int> toErase;
+ while(it != alive.end()){
+ int cur = *it;
+ if(cur > r)
+ break;
+ if(cur != x){
+ toErase.pb(cur); answer[cur] = x;
+ }
+ it++;
+ }
+
+ for (size_t j = 0; j < toErase.size(); j++)
+ alive.erase(toErase[j]);
+ }
+```
+
+The second way is to define array next with the following meaning:
+
+* if knight *v* is alive, then *next*[*v*] = *v*;
+* if knight *v* is out of tournament, next[v] points to some knight *u* (*next*[*v*] = *u*), such that there are no alive knights between *v* and *u*;
+
+To find the first alive knight starting from the knight *v* we need to follow this links until we find the first knight *w* with *next*[*w*] = *w*. In order not to pass the same links too many times, we will use the trick known as path compression (it is used in Disjoint Set Union). Note that you should handle the case when the current knight is the last knight and is out of tournament.
+
+```
+ int getNext(int v){
+ if(next[v] == v)
+ return v;
+ return next[v] = getNext(next[v]);
+ }
+
+ ...
+
+ int cur = getNext(l);
+ while(cur <= r){
+ if(cur == x){
+ cur = cur + 1;
+ }else{
+ answer[cur] = x;
+ next[cur] = cur + 1;
+ }
+
+ cur = getNext(cur);
+ }
+```
+
+#### [356B - Xenia and Hamming](/contest/356/problem/B "Codeforces Round 207 (Div. 1)")
+
+Let's denote the length of the first string as *lenX*, the length of the second string as *lenY*. Let *L* = *LCM*(*lenX*, *lenY*). It's obvious that *L* is a period of the long strings *a* and *b*, so we can find the distance of its' prefixes of length *L* and multiply the answer by . Let's fix the position *i* in the string *x* and think about all characters from the second string it will be compared with. It it easy to conclude that it will be compared with such *y**j* that *i* ≡ *j* (*mod* *g*), where *g* = *GCD*(*lenX*, *lenY*). For each possible remainder of division by *g* and for each character *c* we can calculate *count*(*r*, *c*) — the number of characters *c* that appear in *y* in such positions *j* that *j* *mod* *g* = *r*. When calculating the Hamming distance, the character *x**i* will be compared with exactly *count*(*i* *mod* *g*, *x**i*) characters from *y* that are equal to it, all other comparisons will add one to the distance.
+
+```
+private void solve() {
+ Scanner in = new Scanner(System.in);
+ long n = in.nextLong(), m = in.nextLong();
+ String x = in.next(), y = in.next();
+ int lenX = x.length(), lenY = y.length();
+ int g = gcd(lenX, lenY);
+ long L = lenX * (long)lenY / g;
+ long answer = L;
+ int[][] count = new int[g][26];
+ for (int j = 0; j < lenY; j++) {
+ count[j % g][y.charAt(j) - 'a']++;
+ }
+ for (int i = 0; i < lenX; i++) {
+ answer -= count[i % g][x.charAt(i) - 'a'];
+ }
+ System.out.println(answer * (n * lenX / L));
+ }
+```
+
+#### [356C - Compartments](/contest/356/problem/C "Codeforces Round 207 (Div. 1)")
+
+In the problem you should come up with some right greedy algorithm. One of correct approaches acts as follows:
+
+1. Firstly, it joins all "twos" and "ones" (to get "threes"). Several "ones" should be moved.
+2. Then you should consider two cases depend on amounts of "ones" and "twos". If initially you have more "ones", you should try to join remaining after the first point "ones" into groups of three. If initially you have more "twos", you should try to join remaining after the first point "twos" into groups of three. You can get two "threes" from three "twos".
+3. After the first point and the second point some "ones" or "twos" can remain. You shouldn't come up with common solution. Else you should just to consider all possible cases.
+
+To solve the problem you should follow your common sense (is it greedy?). Writing naive solution (bfs search) for stress purposes is not so bad for proving correctness of your solution.
+
+#### [356D - Bags and Coins](/contest/356/problem/D "Codeforces Round 207 (Div. 1)")
+
+It's easy to see that bags and their relations "lies directly in" should form directed forest. Each vertex should be given value *c**i* — the number of coins in the corresponding bag. Let's denote the sum of values *c**j* in the subtree of vertex *i* as *f**i*. The following conditions should be met:
+
+* *f**i* = *a**i*
+* then sum of *f**i* of roots equals *s*.
+
+It's clear that one of the bags with largest *a**i* must be the root of some tree. It's quite easy to see that the solution exists if and only if there exists a subset *a**i*1, *a**i*2, ..., *a**ik* such that *a**i*1 + *a**i*2 + ... + *a**ik* = *s* and this subset contains at least one bag with the largest *a**i*. It's obvious that it is necessary condition, the sufficiency is also easy to see: let's suppose we have such subset. Then all bags from the subset, except one of the largest, will be roots of the signle-vertex trees (i.e. *c**i* = *a**i* for them). All bags that are not in the subset we will consequentially put into the largest bag, forming the "russian doll" (this tree will be directed chain).
+
+So, we reduced the task to the well-known subset-sum problem: from the items *a*1, *a*2, ... *a**n* find the subset with the given sum *s*. This problem is NP-Complete, and with these constraints is solved in a following way: let *T*(*i*, *j*) = 1 if it is possible to obtain sum *j* using some of the first *i* items, and *T*(*i*, *j*) = 0 otherwise. Then 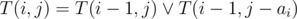. The *i*-th row of this table depends only on the previous row, so we don't have to store the whole table in memory. Also we should use the fact that the values of the table are zeroes and ones, and we can use bit compression and store each row in an array of int's of size . To get the *i*-th row, we should calculate the bitwise OR of the previous row and the previous row shifted to the left by *a**i* positions. That is, we can find out whether it possible to obtain the sum *s* in approximately  operations. To find the actual way to obtain *s*, we need to use the following trick: for every possible sum *j* we will remember the value *first*(*j*) — the number of such item that after considering this item it became possible to obtain *j*. This allows us to restore the solution.
+
+#### [356E - Xenia and String Problem](/contest/356/problem/E "Codeforces Round 207 (Div. 1)")
+
+During the contest most of participants write the solutions that are very similar to the author's one. One of the author's solution uses hashes (but there exist solution without it), you can see short description of the solution below:
+
+1. For each position *i* calculate with hashes the maximal value of *L**i*, such that substring *s*[(*i* - *L**i* + 1)..(*i* + *L**i* - 1)] is Gray string. Also, calculate the maximal value *P**i*, that substring *s*[(*i* - *P**i* + 1)..(*i* + *P**i* - 1)] differs from some Gray string in at most one position. You can see that *P**i* ≥ *L**i*. If *P**i* > *L**i*, also remember position and letter in the position, that differs Gray string and the substring.
+2. You can see, that if we don't need to change letters, then the answer for the problem is , where *f*(*L*) = 12 + 32 + 72 + ... + *L*2. So, calculate an answer without changes.
+3. Next, iterate through all positions and letters in it. What is the new answer for the problem? Look at all Gray strings that occurs in our string and touches our fixed position. After we change this position the string will not be Gray string anymore (so we should subtract the squired length of the string from our answer). Look at all Gray strings that differs in exactly fixed position from some substring of the string. If we change the letter in the position to the fixed letter, all such strings will be added to the answer (and we should add their squired lengths).
+4. Summary, with *P**i* and *L**i* we need to calculate for each position and letter, how the answer differs if we change the letter in the position to the fixed one. For that reason we should use offline update (+=) on the segment. After the values will be calculated we can update our answer with all possible values.
diff --git a/editorials/357.md b/editorials/357.md
@@ -0,0 +1,124 @@
+Source: https://codeforces.com/blog/entry/9210
+
+#### [357A - Group of Students](/contest/357/problem/A "Codeforces Round 207 (Div. 2)")
+
+In this problem you need to iterate over all possible values of passing rate from 1 to 100 and for each value calculate the sizes of two groups.
+
+#### [357B - Flag Day](/contest/357/problem/B "Codeforces Round 207 (Div. 2)")
+
+Let's process the dances in the given order and determine the colors of dancers' clothes. If there are no dancer from some previous dance, we can give the dances different colors arbitrarily. And if there is such dancer, we already know the color of his clothes. So, we arbitrarily distribute the other two colors between the remaning two dancers.
+
+#### [356A - Knight Tournament](/contest/356/problem/A "Codeforces Round 207 (Div. 1)")
+
+Let's the current fight (*l*, *r*, *x*) consists of *K* knights fighting. Then all we have to do is to find all these knights in time *O*(*K*) or *O*(*KlogN*). There are several ways to do that, let's consider some of them.
+
+The first way is to store the numbers of all alive knights in std::set (C++) or TreeSet (Java). Then in C++ we can use lower_bound method to find the first knight in the fight that is alive, and to iterate over this set, each time moving to the next alive knight. In Java we should use subSet method.
+
+```
+ set<int> alive;
+ for (int i = 0; i < n; i++)
+ alive.insert(i);
+
+ for (int i = 0; i < m; i++) {
+ int l, r, x;
+ scanf("%d%d%d", &l, &r, &x);
+ l--, r--, x--;
+ set<int>::iterator it = alive.lower_bound(l);
+ vector<int> toErase;
+ while(it != alive.end()){
+ int cur = *it;
+ if(cur > r)
+ break;
+ if(cur != x){
+ toErase.pb(cur); answer[cur] = x;
+ }
+ it++;
+ }
+
+ for (size_t j = 0; j < toErase.size(); j++)
+ alive.erase(toErase[j]);
+ }
+```
+
+The second way is to define array next with the following meaning:
+
+* if knight *v* is alive, then *next*[*v*] = *v*;
+* if knight *v* is out of tournament, next[v] points to some knight *u* (*next*[*v*] = *u*), such that there are no alive knights between *v* and *u*;
+
+To find the first alive knight starting from the knight *v* we need to follow this links until we find the first knight *w* with *next*[*w*] = *w*. In order not to pass the same links too many times, we will use the trick known as path compression (it is used in Disjoint Set Union). Note that you should handle the case when the current knight is the last knight and is out of tournament.
+
+```
+ int getNext(int v){
+ if(next[v] == v)
+ return v;
+ return next[v] = getNext(next[v]);
+ }
+
+ ...
+
+ int cur = getNext(l);
+ while(cur <= r){
+ if(cur == x){
+ cur = cur + 1;
+ }else{
+ answer[cur] = x;
+ next[cur] = cur + 1;
+ }
+
+ cur = getNext(cur);
+ }
+```
+
+#### [356B - Xenia and Hamming](/contest/356/problem/B "Codeforces Round 207 (Div. 1)")
+
+Let's denote the length of the first string as *lenX*, the length of the second string as *lenY*. Let *L* = *LCM*(*lenX*, *lenY*). It's obvious that *L* is a period of the long strings *a* and *b*, so we can find the distance of its' prefixes of length *L* and multiply the answer by . Let's fix the position *i* in the string *x* and think about all characters from the second string it will be compared with. It it easy to conclude that it will be compared with such *y**j* that *i* ≡ *j* (*mod* *g*), where *g* = *GCD*(*lenX*, *lenY*). For each possible remainder of division by *g* and for each character *c* we can calculate *count*(*r*, *c*) — the number of characters *c* that appear in *y* in such positions *j* that *j* *mod* *g* = *r*. When calculating the Hamming distance, the character *x**i* will be compared with exactly *count*(*i* *mod* *g*, *x**i*) characters from *y* that are equal to it, all other comparisons will add one to the distance.
+
+```
+private void solve() {
+ Scanner in = new Scanner(System.in);
+ long n = in.nextLong(), m = in.nextLong();
+ String x = in.next(), y = in.next();
+ int lenX = x.length(), lenY = y.length();
+ int g = gcd(lenX, lenY);
+ long L = lenX * (long)lenY / g;
+ long answer = L;
+ int[][] count = new int[g][26];
+ for (int j = 0; j < lenY; j++) {
+ count[j % g][y.charAt(j) - 'a']++;
+ }
+ for (int i = 0; i < lenX; i++) {
+ answer -= count[i % g][x.charAt(i) - 'a'];
+ }
+ System.out.println(answer * (n * lenX / L));
+ }
+```
+
+#### [356C - Compartments](/contest/356/problem/C "Codeforces Round 207 (Div. 1)")
+
+In the problem you should come up with some right greedy algorithm. One of correct approaches acts as follows:
+
+1. Firstly, it joins all "twos" and "ones" (to get "threes"). Several "ones" should be moved.
+2. Then you should consider two cases depend on amounts of "ones" and "twos". If initially you have more "ones", you should try to join remaining after the first point "ones" into groups of three. If initially you have more "twos", you should try to join remaining after the first point "twos" into groups of three. You can get two "threes" from three "twos".
+3. After the first point and the second point some "ones" or "twos" can remain. You shouldn't come up with common solution. Else you should just to consider all possible cases.
+
+To solve the problem you should follow your common sense (is it greedy?). Writing naive solution (bfs search) for stress purposes is not so bad for proving correctness of your solution.
+
+#### [356D - Bags and Coins](/contest/356/problem/D "Codeforces Round 207 (Div. 1)")
+
+It's easy to see that bags and their relations "lies directly in" should form directed forest. Each vertex should be given value *c**i* — the number of coins in the corresponding bag. Let's denote the sum of values *c**j* in the subtree of vertex *i* as *f**i*. The following conditions should be met:
+
+* *f**i* = *a**i*
+* then sum of *f**i* of roots equals *s*.
+
+It's clear that one of the bags with largest *a**i* must be the root of some tree. It's quite easy to see that the solution exists if and only if there exists a subset *a**i*1, *a**i*2, ..., *a**ik* such that *a**i*1 + *a**i*2 + ... + *a**ik* = *s* and this subset contains at least one bag with the largest *a**i*. It's obvious that it is necessary condition, the sufficiency is also easy to see: let's suppose we have such subset. Then all bags from the subset, except one of the largest, will be roots of the signle-vertex trees (i.e. *c**i* = *a**i* for them). All bags that are not in the subset we will consequentially put into the largest bag, forming the "russian doll" (this tree will be directed chain).
+
+So, we reduced the task to the well-known subset-sum problem: from the items *a*1, *a*2, ... *a**n* find the subset with the given sum *s*. This problem is NP-Complete, and with these constraints is solved in a following way: let *T*(*i*, *j*) = 1 if it is possible to obtain sum *j* using some of the first *i* items, and *T*(*i*, *j*) = 0 otherwise. Then 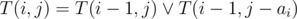. The *i*-th row of this table depends only on the previous row, so we don't have to store the whole table in memory. Also we should use the fact that the values of the table are zeroes and ones, and we can use bit compression and store each row in an array of int's of size . To get the *i*-th row, we should calculate the bitwise OR of the previous row and the previous row shifted to the left by *a**i* positions. That is, we can find out whether it possible to obtain the sum *s* in approximately  operations. To find the actual way to obtain *s*, we need to use the following trick: for every possible sum *j* we will remember the value *first*(*j*) — the number of such item that after considering this item it became possible to obtain *j*. This allows us to restore the solution.
+
+#### [356E - Xenia and String Problem](/contest/356/problem/E "Codeforces Round 207 (Div. 1)")
+
+During the contest most of participants write the solutions that are very similar to the author's one. One of the author's solution uses hashes (but there exist solution without it), you can see short description of the solution below:
+
+1. For each position *i* calculate with hashes the maximal value of *L**i*, such that substring *s*[(*i* - *L**i* + 1)..(*i* + *L**i* - 1)] is Gray string. Also, calculate the maximal value *P**i*, that substring *s*[(*i* - *P**i* + 1)..(*i* + *P**i* - 1)] differs from some Gray string in at most one position. You can see that *P**i* ≥ *L**i*. If *P**i* > *L**i*, also remember position and letter in the position, that differs Gray string and the substring.
+2. You can see, that if we don't need to change letters, then the answer for the problem is , where *f*(*L*) = 12 + 32 + 72 + ... + *L*2. So, calculate an answer without changes.
+3. Next, iterate through all positions and letters in it. What is the new answer for the problem? Look at all Gray strings that occurs in our string and touches our fixed position. After we change this position the string will not be Gray string anymore (so we should subtract the squired length of the string from our answer). Look at all Gray strings that differs in exactly fixed position from some substring of the string. If we change the letter in the position to the fixed letter, all such strings will be added to the answer (and we should add their squired lengths).
+4. Summary, with *P**i* and *L**i* we need to calculate for each position and letter, how the answer differs if we change the letter in the position to the fixed one. For that reason we should use offline update (+=) on the segment. After the values will be calculated we can update our answer with all possible values.
diff --git a/editorials/358.md b/editorials/358.md
@@ -0,0 +1,50 @@
+Source: https://codeforces.com/blog/entry/9334
+
+### [358A - Dima and Continuous Line](/contest/358/problem/A "Codeforces Round 208 (Div. 2)")
+
+Author — [Berezin](/profile/Berezin "Expert Berezin")
+
+If our line has self-intersections, that some pair of semi-circles exists, which intersect each other.
+Let points *x*1 < *x*2 are connected with a semi-circle and points *x*3 < *x*4 are connected with another semi-circle. Then this semis-circles intersect if one of the conditions is true:
+
+1). *x*1 < *x*3 < *x*2 < *x*4
+2). *x*3 < *x*1 < *x*4 < *x*2
+
+Let’s iterate trough all pairs of semi-circles, and check if the semi-circles intersect each other. So, the solution will have complexity *O*(*N*2) what satisfied the constrains.
+
+### [358B - Dima and Text Messages](/contest/358/problem/B "Codeforces Round 208 (Div. 2)")
+
+Author — [Berezin](/profile/Berezin "Expert Berezin")
+
+It’s clear, that adding new random symbols means, that we can simply omit them, they don’t change the structure of the phrase: < 3*word*1 < 3*word*2 < 3... *word**N* < 3. Let’s determine the phrase before inserting random elements: *s* = " < 3" + *word*1 + " < 3" + ... + " < 3" + *wordN* + " < 3". Lets *i* —is an index in *s*, we are waiting for. At the beginning *i* = 0; we will iterate though the sms and when we will meet the symbol which equals to *s**i* we will simply increment *i*.
+
+if at some moment |*s*| ≤ *I* we found all needed symbols and answer is yes, otherwise – no.
+
+### [358C - Dima and Containers](/contest/358/problem/C "Codeforces Round 208 (Div. 2)")
+
+Author — [Berezin](/profile/Berezin "Expert Berezin")
+
+We know all the numbers at the beginning, so, it’s clear, that we want pop three maximums. We can “precalculate “ maximums with finding next zero and iterating through all numbers between two zeroes.
+We should do pops from different containers, so let’s save maximums in the top of the stack, in the beginning of the queue and on the beginning of the dek. (you can do this in some other way) We should determine, where will be stored the 1st, 2nd and 3rd maximum. For example, the first(the biggest one) – in the stack, second – in queue, and the third – in dek. “trash” – other numbers we can save into the end of the dek.
+Also you need to catch cases, when two or less numbers are between zeroes.
+
+### [358D - Dima and Hares](/contest/358/problem/D "Codeforces Round 208 (Div. 2)")
+
+Author — [Sereja](/profile/Sereja "Master Sereja")
+
+Let’s look at the first hare: we chose them befoe second, or after. If it is chosen after the second, than the solution from the 2nd hare to the last doesn’t depend on the first one, otherwise, we will receive the same but before the second hair will be obviously the feed hair. So, we have two dinamics:
+1). *d*0*i* — answer for suffix as a separate task.
+2). *d*1*i* — answer for suffix if the previous hair for this suffix is feed already.
+Movements:
+*d*0*n* = *an*
+*d*1*n* = *bn*
+*d*0*i* = *max*(*ai* + *d*1*i* + 1, *bi* + *d*0*i* + 1)
+*d*1*i* = *max*(*bi* + *d*1*i* + 1, *ci* + *d*0*i* + 1)
+answer is *d*01;
+
+### [358E - Dima and Kicks](/contest/358/problem/E "Codeforces Round 208 (Div. 2)")
+
+Author — [Sereja](/profile/Sereja "Master Sereja")
+
+The first thing to understand is that the answer is the divisor of maximal-length sequence of standing one by one ones. (1111…11)
+Let’s iterate trough this number. Now we should check the table knowing the value of *K*. Let’s find the most left of ones, and choose from them the most top. Let it be (*X*, *Y*). then after each step Dima can appear inly in cells which look like: (*X* + *K* * *a*, *Y* + *K* * *b*). Let such cells are the vertexes of the graph. And sequences of ones – the ribs. We will build the graph. We should check that there are no additional ones in table. We should also check if the graph is connected and has en Euler’s path. The value of K is the next answer under the all conditions. The correct implementation will have the complexity *O*(*N* * *N* * *log*(*N*)). In reality it will be never achieved.
diff --git a/editorials/359.md b/editorials/359.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/9425
+
+**I'm not good in English. So, if you find an mistake in editorial, please, send me a private message.**
+
+## [359A - Table](/contest/359/problem/A "Codeforces Round 209 (Div. 2)")
+
+If there are some good cell, which is located in the first row or in the first column, the answer is two. Similarly, if If there are some good cell, which is located in the last row or in the last column, the answer is two. Otherwise, the answer is four.
+
+Авторское решение: [4968279](/contest/359/submission/4968279 "Submission 4968279 by gridnevvvit")
+
+## [359B - Permutation](/contest/359/problem/B "Codeforces Round 209 (Div. 2)")
+
+The answer is a slightly modified permutation 1, 2, ..., 2*n*. Let's reverse numbers 2*i* - 1 and 2*i* for each 1 ≤ *i* ≤ *k*. It's not hard to understand, that this permutation is good.
+
+Авторское решение: [4968385](/contest/359/submission/4968385 "Submission 4968385 by gridnevvvit")
+
+## [359C - Prime Number](/contest/359/problem/C "Codeforces Round 209 (Div. 2)")
+
+Obviously, the answer is *x**v*. Let *sum* = *a*1 + *a*2 + ... + *a**n*. Also let *s**i* = *sum* - *a**i* (the array of degrees). After that let's find value *v* by the following algorithm: Let's consider a sequence of degrees as decreasing sequence. Now we will perform the following operation until it's possible to perfom it. Take the minimum degree *v* from the array of degrees and calculate the number of elements *cnt*, which have the same degree. If *cnt* multiples of *x*, then replace all *cnt* elements by *cnt* / *x* elements of the form *v* + 1. Since the sequence of degrees is a decreasing sequence, we can simply assign them to the end. If *cnt* is not a multiple of *x*, then we found the required value *v*. Also you need to check, that *v* is not greater then *sum*. Otherwise, *v* will be equals to *sum*.
+
+Авторское решение: [4968346](/contest/359/submission/4968346 "Submission 4968346 by gridnevvvit")
+
+## [359D - Pair of Numbers](/contest/359/problem/D "Codeforces Round 209 (Div. 2)")
+
+Quite simple note: if the pair (*l*, *r*) satisfies the condition 1 from the statements, then *min*(*l*, *r*) = *GCD*(*l*, *r*), where *min*(*l*, *r*) is smallest number *a**i* from the segment (l, r) and *GCD*(*l*, *r*) is a GCD of all numbers from the segment (l, r). Calculate some data structure that will allow us to respond quickly to requests *GCD*(*l*, *r*) and *min*(*l*, *r*). For example, you can use Sparce Table. Solutuions, that uses segment tree, is too slow. So I think, you should use Sparce Table. So, now our task quite simple. Let's use binary search to find greatest value of *r* - *l*:
+
+```
+lf = 0; //left boundary of binary search
+rg = n; //right boundary of binary search
+while (rg - lf > 1) {
+ int mid = (lf + rg) / 2;
+ if (ok(mid)) //ok(mid)
+ lf = mid;
+ else
+ rg = mid;
+}
+```
+
+*ok*(*mid*) is the function, that determines, is there some segment where *min*(*l*, *r*) = *GCD*(*l*, *r*) and *mid* = *r* - *l* (*mid* — is fixed value by binary search). If there is some good segment, you should update boundaries of binary search correctly. After that, it's very simple to restore answer.
+
+[Some information about Sparce Table](http://www.topcoder.com/tc?d1=tutorials&d2=lowestCommonAncestor&module=Static)
+
+Авторское решение: [4968587](/contest/359/submission/4968587 "Submission 4968587 by gridnevvvit")
+
+## [359E - Neatness](/contest/359/problem/E "Codeforces Round 209 (Div. 2)")
+
+You should write recursive function, that will turn on the light in all rooms, where it's possible. Also this function will visit all rooms, which it may visit. Let this function is called paint(x, y), where x, y is the current room. *Paint*(*x*, *y*) will use following idea: Let's look at all neighbors. If there is a light in the current direction (rule 3 from the statement), and the room (*nx*, *ny*) (current neighbor) has not yet visited, we will call our recursive function from (*nx*, *ny*). Also, we will turn on the light in all rooms, were we were. If some room is not visited by *paint*(*x*, *y*) and lights is on in this room, the answer is "NO". Otherwise, the answer is "YES". After that let's calculate value *dist*(*x*, *y*) by using bfs. *dist*(*x*, *y*) — is a minimal possible distance from the start to the current position (*x*, *y*). It's possible to use in our bfs only rooms, where lights is on. After that we will write the same function *repaint*(*x*, *y*). *Repaint*(*x*, *y*) will use following idea: Let's look at all neighbors. If there is a light in the current neighbor (*nx*, *ny*) and *dist*(*nx*, *ny*) > *dist*(*x*, *y*) ((*x*, *y*) — current room), let's call our recursive function from (*nx*, *ny*).After that we will come back to room (*x*, *y*). If there is no such neigbor (*nx*, *ny*), turn off the light in the room (*x*, *y*). Also you should look at my solution for more details.
+
+Авторское решение: [4968657](/contest/359/submission/4968657 "Submission 4968657 by gridnevvvit")
diff --git a/editorials/360.md b/editorials/360.md
@@ -0,0 +1,102 @@
+Source: https://codeforces.com/blog/entry/9529
+
+#### [361A - Levko and Table](/contest/361/problem/A "Codeforces Round 210 (Div. 2)")
+
+Matrix,in which all diagonal elements equal *k* and other elements equal 0, satisfied all conditions.
+
+For example, if n = 4 and k = 7, our matrix will be
+
+7 0 0 0
+
+0 7 0 0
+
+0 0 7 0
+
+0 0 0 7
+
+#### [361B - Levko and Permutation](/contest/361/problem/B "Codeforces Round 210 (Div. 2)")
+
+*gcd*(1, *m*) = 1, so if *n* = *k*, there is no suitable permutation.
+
+It is well known that *gcd*(*m*, *m* - 1) = 1. Lets construct following permutation. It has exactly *k* good elements.
+
+*n* - *k* 1 2 3 ... *n* - *k* - 1 *n* - *k* + 1 *n* - *k* + 2 ... *n*
+
+#### [360A - Levko and Array Recovery](/contest/360/problem/A "Codeforces Round 210 (Div. 1)")
+
+Let's find such value *b*[*i*] that *a*[*i*] ≤ *b*[*i*] for all indeces *i*. Let's simulate all operations and *diff*[*i*] will be the difference between current value of *i*-th element and its initial value. If we have operation of first type, we change values of *diff*[*i*]. If we have operation of second type, we know that *a*[*i*] + *diff*[*i*] ≤ *m*[*i*], so *a*[*i*] ≤ *m*[*i*] - *diff*[*i*]. We will get array *b* when we union all this inequalities.
+
+Let's prove that either *b* satisfied all conditions or there is no such array. It can be two cases, why *b* does not suit:
+
+1.  — it's impossible due to construction of array *b*.
+2.  — *b*[*i*] is a maximal possible value of *a*[*i*], so  can't be bigger.
+
+#### [360B - Levko and Array](/contest/360/problem/B "Codeforces Round 210 (Div. 1)")
+
+Let's solve this problem using binary search. We need to check whether we can achieve an array, when *c*(*a*) will be at most *x*. Lets make dp. *dp*[*i*] means minimal number of elements with indeces less than *i*, which we need to change, but we don't change *i*-th element. Let's iterate next element *j*, which we don't change. Then we know that we can change all elements between *i* and *j*. It is equivalent to such condition
+
+|*a**j* - *a**i*| ≤ (*j* - *i*)·*x*
+
+Difference between neighboring elements can be at most *x*. The maximal possible difference increases by *x* exactly *j* - *i* times between elements *i* and *j*, so this inequality is correct.
+
+#### [360C - Levko and Strings](/contest/360/problem/C "Codeforces Round 210 (Div. 1)")
+
+Let's count amount of such substrings of *t* that are bigger than corresponding substring of *s* and begin at the position *i*.
+
+1. If *t*[*i*] < *s*[*i*], this amount equals 0.
+2. If *t*[*i*] > *s*[*i*], this amount equals *n* - *i*.
+3. If *t*[*i*] = *s*[*i*], then let's find such nearest position *j*, *j* > *i* , that *t*[*j*] ≠ *s*[*j*]. If *t*[*j*] > *s*[*j*], needed amount of substrings will be *n* - *j*. If *t*[*j*] < *s*[*j*], needed amount of substrings will be 0.
+
+We can rephrase this: If *t*[*i*] > *s*[*i*], it will be (1 + *pref*)·(*n* - *i*) new substrings, where *pref* means how many last elements in *s* and *t* is equal.
+
+Let's make dp. *dp*[*i*][*sum*] means that we viewed *i* positions, have *sum* needed substrings and *s*[*i*] ≠ *t*[*i*]. Lets iterate their common prefix *pref*.
+
+If *t*[*i*] < *s*[*i*], *dp*[*i*][*sum*] + = *dp*[*i* - *pref* - 1][*sum*]·(*s*[*i*] - '*a*') — we can count this value using partial sums.
+
+If *t*[*i*] > *s*[*i*], *dp*[*i*][*sum*] + = *dp*[*i* - *pref* - 1][*sum* - (1 + *pref*)·(*n* - *i*)]·('*z*' - *s*[*i*]). Let's iterate *pref*.
+
+Let's note that *sum* - *pref*·(*n* - *i*) ≥ 0, so *pref* ≤ *sum* / (*n* - *i*) and *pref* ≤ *k* / (*n* - *i*). This means that third cycle will make at most *k* / (*n* - *i*) iterations when we find value of *dp*[*i*][*sum*]. Let's count total number of iterations:
+
+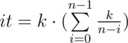 =  < *k*·(*n* + *k*·*log* *k*).
+
+#### [360D - Levko and Sets](/contest/360/problem/D "Codeforces Round 210 (Div. 1)")
+
+*p* is prime, so there exist primitive root *g* modulo *p*(We don't need to find it, but we know that it exists). We can write *a**i* = *g**r**i*. Note, that *i*-th set consists of all numbers , where *c**j* ≥ 0, or we can write it as .
+
+By Fermat's little theorem *a**p* - 1 = 1 *mod* *p* we have that *a**k* *mod* *p* = *a**k* *mod* (*p* - 1) *mod* *p*. So  can be equal to all values *k*·*t* modulo *p* - 1, where *t* = *gcd*(*b*1, *b*2, ... , *b**m*, *p* - 1). Note that *t* doesn't depend on *r**i*, so we can assign *g* = *g**t*. Then all elements of *i*-th set will be *g**r**i*·*k*, where *k* ≥ 0. Now we can replace *b**i* by *q**i*, where *q**i* = *gcd*(*r**i*, *p* - 1), as we do with *b**i* at the beginning. Then all elements of *i*-th set will be *g**q**i*·*k*, where *k* ≥ 0. This means that if we write all values *g*0, *g*1, ..., *g**p* - 2 in a line, *i*-th set will contain every *q**i*-th element.
+
+Now we need to find union of this sets.Let's do it using inclusion-exclusion principle. All our numbers are divisors of *p* - 1. Let's *dp**i* be the coefficient near *i* in inclusion-exclusion principle(*i* is a divisor of *p* - 1) and we can find this values, adding all *q**i* alternatively.
+
+Also we need to find *q**i*. Let's find volume of the i-th set. It is equal to . From the other side it is equal to such minimal number *d**i*, that *a**i**d**i* = 1 *mod* *p* (*d**i* is a cycle). From *a**i**p* - 1 = 1 *mod* *p* we have that *p* - 1 is divisible by *d**i*. So we can find *d**i* as a divisor of *p* - 1. And .
+
+#### [360E - Levko and Game](/contest/360/problem/E "Codeforces Round 210 (Div. 1)")
+
+**Algorithm:**
+
+Firstly we will solve problem if first player can win.
+
+Let's make all roads that we can change equal to *r*[*i*] and do two Dijkstra's algorithms from vertices *s*1 and *s*2. Let's *d*1[*i*] be the distance from *s*1 to *i*, *d*2[*i*] be the distance from *s*2 to *i*. Consider a road, that we can change, from *a* to *b*. If *d*1[*a*] < *d*2[*a*], we will set length of such road equal to *l*[*i*] and do two Dijkstra's algorithms again. We run such process until any road changes its length.
+
+If *d*1[*f*] < *d*2[*f*] after all changes then first player wins.
+
+If we replace condition *d*1[*a*] < *d*2[*a*] by *d*1[*a*] ≤ *d*2[*a*], we can check if Levko can end this game with a draw.
+
+**Proof:**
+
+Let's call "edges" only roads which Levko can change. When we do Dijkstra's algorithm we use all roads, not only edges.
+
+1. Let's prove that if there exist such edges values that first player wins, there exist values of edges such that first player wins and all this values equal either *l*[*i*] or *r*[*i*]. Consider shortest pathes of both players.
+ If only first player goes on edge from *a* to *b*, we can set its value *l*[*i*]. Proof: there must hold *d*1[*a*] < *d*2[*a*] because first player goes on it and wins. This condition holds after change of value of this edge. If second player goes on this edge, he loses because *d*1[*f*] ≤ *d*1[*a*] + *d*(*a*, *b*) + *d*(*b*, *f*) < *d*2[*a*] + *d*(*a*, *b*) + *d*(*b*, *F*) = *d*2[*f*]. If second player doesn't go on this edge, he loses because shortest path of first player became smaller(*d*(*x*, *y*) — shortest path from *x* to *y*).
+ If only second player goes on edge from *a* to *b*, we can set its value *r*[*i*]. Proof: Shortest path of the first player doesn't change and shortest path of second player can only become larger.
+ If no player go on edge, we can set its value *r*[*i*]. Proof: Shortest pathes of both players doesn't change.
+ If both players go on edge from *a* to *b*, we can set its value *l*[*i*]. Proof: Shortest pathes of both players decrease by (initial value of this edge — *l*[*i*]).
+ After every such operation first player wins again and all edges become either *l*[*i*] or *r*[*i*].
+2. Consider result of our algorithm. Let's call edge "good" if its value is equal to *l*[*i*] and "bad" if its value equals *r*[*i*].
+ (a) Let's prove that after performing all operations we will have *d*1[*a*] < *d*2[*a*] for all good edges (*a*, *b*). If we have *d*1[*a*1] < *d*2[*a*1] for edge (*a*1, *b*1) and after changing value of (*a*2, *b*2) this condition doesn't hold. We have *d*1[*a*1] > = *d*2[*a*1], *d*1[*a*2] < *d*2[*a*2]. We change only one edge and shortest path from *s*2 to *f* become shorter so edge (*a*2, *b*2) lies on this path.
+ *d*2[*a*1] = *d*2[*a*2] + *d*(*a*2, *b*2) + *d*(*b*2, *a*1) > *d*1[*a*2] + *d*(*a*2, *b*2) + *d*(*b*2, *a*1) ≥ *d*1[*a*1]. Contradiction. (b) Let's prove that after performing all operations we will have *d*1[*a*] ≥ *d*2[*a*] for all bad edges. We can continue our procces otherwise.
+ (c) Let's prove that if condition *d*1[*a*] < *d*2[*a*] holds for some edge but we doesn't change it on this iteration, this continion holds after this iteration. Proof is same as in (a).
+ (d) Let's prove that if any subset of good edges is equal to *l*[*i*] and *d*1[*a*] < *d*2[*a*], ift also holds when we make all good edges equal *l*[*i*]. Let's simulate all procces and use (c).
+3. Lets prove that for all edges values(not necessary only *l*[*i*] or *r*[*i*]), *d*1[*a*] ≥ *d*2[*a*] for all bad edges (*a*, *b*).
+ Assume that we have such edge. Consider shortest path of first player to its beginning. If there exist bad edges (*a*1, *b*1) on this path, there must holds inequality *d*1[*a*1] < *d*2[*a*1]. Consider first of this bad edges (*a*, *b*). Then shortest path of first player to *a* doesn't consist any bad edge. Consider problem,m which is equivalent to our problem but finish is in vertex *a*. good and bad edges will be same. Let's change all value of edges as we do in item 1. Note? that all bad edges will be equal to *r*[*i*]. So only subset of good edges can be equal to *l*[*i*] and *d*1[*a*1] < *d*2[*a*1]. By (d) we have that we can set all good edges *l*[*i*] and condition *d*1[*a*1] < *d*2[*a*1] will be satisfied. So we have contradiction thst this edge is bad.
+4. This means that if first player goes on any bad edge, he loses. So we can set *r*[*i*] to all this edges. So we can set *l*[*i*] to some subset of good edges. By (d) we have that if we have *d*1[*f*] < *d*2[*f*] for some subset of good edges, this condition will be true if we set all good edges *l*[*i*].
+5. Note that proof will be same if we want to check whether Levko can end a game with a draw.
diff --git a/editorials/361.md b/editorials/361.md
@@ -0,0 +1,102 @@
+Source: https://codeforces.com/blog/entry/9529
+
+#### [361A - Levko and Table](/contest/361/problem/A "Codeforces Round 210 (Div. 2)")
+
+Matrix,in which all diagonal elements equal *k* and other elements equal 0, satisfied all conditions.
+
+For example, if n = 4 and k = 7, our matrix will be
+
+7 0 0 0
+
+0 7 0 0
+
+0 0 7 0
+
+0 0 0 7
+
+#### [361B - Levko and Permutation](/contest/361/problem/B "Codeforces Round 210 (Div. 2)")
+
+*gcd*(1, *m*) = 1, so if *n* = *k*, there is no suitable permutation.
+
+It is well known that *gcd*(*m*, *m* - 1) = 1. Lets construct following permutation. It has exactly *k* good elements.
+
+*n* - *k* 1 2 3 ... *n* - *k* - 1 *n* - *k* + 1 *n* - *k* + 2 ... *n*
+
+#### [360A - Levko and Array Recovery](/contest/360/problem/A "Codeforces Round 210 (Div. 1)")
+
+Let's find such value *b*[*i*] that *a*[*i*] ≤ *b*[*i*] for all indeces *i*. Let's simulate all operations and *diff*[*i*] will be the difference between current value of *i*-th element and its initial value. If we have operation of first type, we change values of *diff*[*i*]. If we have operation of second type, we know that *a*[*i*] + *diff*[*i*] ≤ *m*[*i*], so *a*[*i*] ≤ *m*[*i*] - *diff*[*i*]. We will get array *b* when we union all this inequalities.
+
+Let's prove that either *b* satisfied all conditions or there is no such array. It can be two cases, why *b* does not suit:
+
+1.  — it's impossible due to construction of array *b*.
+2.  — *b*[*i*] is a maximal possible value of *a*[*i*], so  can't be bigger.
+
+#### [360B - Levko and Array](/contest/360/problem/B "Codeforces Round 210 (Div. 1)")
+
+Let's solve this problem using binary search. We need to check whether we can achieve an array, when *c*(*a*) will be at most *x*. Lets make dp. *dp*[*i*] means minimal number of elements with indeces less than *i*, which we need to change, but we don't change *i*-th element. Let's iterate next element *j*, which we don't change. Then we know that we can change all elements between *i* and *j*. It is equivalent to such condition
+
+|*a**j* - *a**i*| ≤ (*j* - *i*)·*x*
+
+Difference between neighboring elements can be at most *x*. The maximal possible difference increases by *x* exactly *j* - *i* times between elements *i* and *j*, so this inequality is correct.
+
+#### [360C - Levko and Strings](/contest/360/problem/C "Codeforces Round 210 (Div. 1)")
+
+Let's count amount of such substrings of *t* that are bigger than corresponding substring of *s* and begin at the position *i*.
+
+1. If *t*[*i*] < *s*[*i*], this amount equals 0.
+2. If *t*[*i*] > *s*[*i*], this amount equals *n* - *i*.
+3. If *t*[*i*] = *s*[*i*], then let's find such nearest position *j*, *j* > *i* , that *t*[*j*] ≠ *s*[*j*]. If *t*[*j*] > *s*[*j*], needed amount of substrings will be *n* - *j*. If *t*[*j*] < *s*[*j*], needed amount of substrings will be 0.
+
+We can rephrase this: If *t*[*i*] > *s*[*i*], it will be (1 + *pref*)·(*n* - *i*) new substrings, where *pref* means how many last elements in *s* and *t* is equal.
+
+Let's make dp. *dp*[*i*][*sum*] means that we viewed *i* positions, have *sum* needed substrings and *s*[*i*] ≠ *t*[*i*]. Lets iterate their common prefix *pref*.
+
+If *t*[*i*] < *s*[*i*], *dp*[*i*][*sum*] + = *dp*[*i* - *pref* - 1][*sum*]·(*s*[*i*] - '*a*') — we can count this value using partial sums.
+
+If *t*[*i*] > *s*[*i*], *dp*[*i*][*sum*] + = *dp*[*i* - *pref* - 1][*sum* - (1 + *pref*)·(*n* - *i*)]·('*z*' - *s*[*i*]). Let's iterate *pref*.
+
+Let's note that *sum* - *pref*·(*n* - *i*) ≥ 0, so *pref* ≤ *sum* / (*n* - *i*) and *pref* ≤ *k* / (*n* - *i*). This means that third cycle will make at most *k* / (*n* - *i*) iterations when we find value of *dp*[*i*][*sum*]. Let's count total number of iterations:
+
+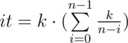 =  < *k*·(*n* + *k*·*log* *k*).
+
+#### [360D - Levko and Sets](/contest/360/problem/D "Codeforces Round 210 (Div. 1)")
+
+*p* is prime, so there exist primitive root *g* modulo *p*(We don't need to find it, but we know that it exists). We can write *a**i* = *g**r**i*. Note, that *i*-th set consists of all numbers , where *c**j* ≥ 0, or we can write it as .
+
+By Fermat's little theorem *a**p* - 1 = 1 *mod* *p* we have that *a**k* *mod* *p* = *a**k* *mod* (*p* - 1) *mod* *p*. So  can be equal to all values *k*·*t* modulo *p* - 1, where *t* = *gcd*(*b*1, *b*2, ... , *b**m*, *p* - 1). Note that *t* doesn't depend on *r**i*, so we can assign *g* = *g**t*. Then all elements of *i*-th set will be *g**r**i*·*k*, where *k* ≥ 0. Now we can replace *b**i* by *q**i*, where *q**i* = *gcd*(*r**i*, *p* - 1), as we do with *b**i* at the beginning. Then all elements of *i*-th set will be *g**q**i*·*k*, where *k* ≥ 0. This means that if we write all values *g*0, *g*1, ..., *g**p* - 2 in a line, *i*-th set will contain every *q**i*-th element.
+
+Now we need to find union of this sets.Let's do it using inclusion-exclusion principle. All our numbers are divisors of *p* - 1. Let's *dp**i* be the coefficient near *i* in inclusion-exclusion principle(*i* is a divisor of *p* - 1) and we can find this values, adding all *q**i* alternatively.
+
+Also we need to find *q**i*. Let's find volume of the i-th set. It is equal to . From the other side it is equal to such minimal number *d**i*, that *a**i**d**i* = 1 *mod* *p* (*d**i* is a cycle). From *a**i**p* - 1 = 1 *mod* *p* we have that *p* - 1 is divisible by *d**i*. So we can find *d**i* as a divisor of *p* - 1. And .
+
+#### [360E - Levko and Game](/contest/360/problem/E "Codeforces Round 210 (Div. 1)")
+
+**Algorithm:**
+
+Firstly we will solve problem if first player can win.
+
+Let's make all roads that we can change equal to *r*[*i*] and do two Dijkstra's algorithms from vertices *s*1 and *s*2. Let's *d*1[*i*] be the distance from *s*1 to *i*, *d*2[*i*] be the distance from *s*2 to *i*. Consider a road, that we can change, from *a* to *b*. If *d*1[*a*] < *d*2[*a*], we will set length of such road equal to *l*[*i*] and do two Dijkstra's algorithms again. We run such process until any road changes its length.
+
+If *d*1[*f*] < *d*2[*f*] after all changes then first player wins.
+
+If we replace condition *d*1[*a*] < *d*2[*a*] by *d*1[*a*] ≤ *d*2[*a*], we can check if Levko can end this game with a draw.
+
+**Proof:**
+
+Let's call "edges" only roads which Levko can change. When we do Dijkstra's algorithm we use all roads, not only edges.
+
+1. Let's prove that if there exist such edges values that first player wins, there exist values of edges such that first player wins and all this values equal either *l*[*i*] or *r*[*i*]. Consider shortest pathes of both players.
+ If only first player goes on edge from *a* to *b*, we can set its value *l*[*i*]. Proof: there must hold *d*1[*a*] < *d*2[*a*] because first player goes on it and wins. This condition holds after change of value of this edge. If second player goes on this edge, he loses because *d*1[*f*] ≤ *d*1[*a*] + *d*(*a*, *b*) + *d*(*b*, *f*) < *d*2[*a*] + *d*(*a*, *b*) + *d*(*b*, *F*) = *d*2[*f*]. If second player doesn't go on this edge, he loses because shortest path of first player became smaller(*d*(*x*, *y*) — shortest path from *x* to *y*).
+ If only second player goes on edge from *a* to *b*, we can set its value *r*[*i*]. Proof: Shortest path of the first player doesn't change and shortest path of second player can only become larger.
+ If no player go on edge, we can set its value *r*[*i*]. Proof: Shortest pathes of both players doesn't change.
+ If both players go on edge from *a* to *b*, we can set its value *l*[*i*]. Proof: Shortest pathes of both players decrease by (initial value of this edge — *l*[*i*]).
+ After every such operation first player wins again and all edges become either *l*[*i*] or *r*[*i*].
+2. Consider result of our algorithm. Let's call edge "good" if its value is equal to *l*[*i*] and "bad" if its value equals *r*[*i*].
+ (a) Let's prove that after performing all operations we will have *d*1[*a*] < *d*2[*a*] for all good edges (*a*, *b*). If we have *d*1[*a*1] < *d*2[*a*1] for edge (*a*1, *b*1) and after changing value of (*a*2, *b*2) this condition doesn't hold. We have *d*1[*a*1] > = *d*2[*a*1], *d*1[*a*2] < *d*2[*a*2]. We change only one edge and shortest path from *s*2 to *f* become shorter so edge (*a*2, *b*2) lies on this path.
+ *d*2[*a*1] = *d*2[*a*2] + *d*(*a*2, *b*2) + *d*(*b*2, *a*1) > *d*1[*a*2] + *d*(*a*2, *b*2) + *d*(*b*2, *a*1) ≥ *d*1[*a*1]. Contradiction. (b) Let's prove that after performing all operations we will have *d*1[*a*] ≥ *d*2[*a*] for all bad edges. We can continue our procces otherwise.
+ (c) Let's prove that if condition *d*1[*a*] < *d*2[*a*] holds for some edge but we doesn't change it on this iteration, this continion holds after this iteration. Proof is same as in (a).
+ (d) Let's prove that if any subset of good edges is equal to *l*[*i*] and *d*1[*a*] < *d*2[*a*], ift also holds when we make all good edges equal *l*[*i*]. Let's simulate all procces and use (c).
+3. Lets prove that for all edges values(not necessary only *l*[*i*] or *r*[*i*]), *d*1[*a*] ≥ *d*2[*a*] for all bad edges (*a*, *b*).
+ Assume that we have such edge. Consider shortest path of first player to its beginning. If there exist bad edges (*a*1, *b*1) on this path, there must holds inequality *d*1[*a*1] < *d*2[*a*1]. Consider first of this bad edges (*a*, *b*). Then shortest path of first player to *a* doesn't consist any bad edge. Consider problem,m which is equivalent to our problem but finish is in vertex *a*. good and bad edges will be same. Let's change all value of edges as we do in item 1. Note? that all bad edges will be equal to *r*[*i*]. So only subset of good edges can be equal to *l*[*i*] and *d*1[*a*1] < *d*2[*a*1]. By (d) we have that we can set all good edges *l*[*i*] and condition *d*1[*a*1] < *d*2[*a*1] will be satisfied. So we have contradiction thst this edge is bad.
+4. This means that if first player goes on any bad edge, he loses. So we can set *r*[*i*] to all this edges. So we can set *l*[*i*] to some subset of good edges. By (d) we have that if we have *d*1[*f*] < *d*2[*f*] for some subset of good edges, this condition will be true if we set all good edges *l*[*i*].
+5. Note that proof will be same if we want to check whether Levko can end a game with a draw.
diff --git a/editorials/362.md b/editorials/362.md
@@ -0,0 +1,25 @@
+Source: https://codeforces.com/blog/entry/9584
+
+[362A - Two Semiknights Meet](/contest/362/problem/A "Codeforces Round 212 (Div. 2)")
+
+Autors have proposed different solutions. One can notice that if semiknights did not have a meeting after first step (it is not necessary they have a meeting in "good" square), they will not meet at all. This fact appears from board size and possible semiknight's moves. As the initial semiknight's squares are considered good for the meeting the semiknights have arrived to the one square and then they move together to one of the initial squares and meeting will count.
+
+[362B - Petya and Staircases](/contest/362/problem/B "Codeforces Round 212 (Div. 2)")
+
+One has to note that the number of dirty stairs ≤ 3000. Petya can reach stair number *n* if the first and the last stairs are not dirty and there are not three or more dirty stairs in a row. So let sort the array of dirty stairs and go through it, checking for three or more consecutive dirty stairs. Also one need to check if the first or the last stair is in this array.
+
+[362C - Insertion Sort](/contest/362/problem/C "Codeforces Round 212 (Div. 2)")
+
+The number of times swap is called equals the number of inversions in the input permutation. It’s easy to see that it is reasonable to swap only such elements *a**i*, *a**j* that *i* < *j* and *a**i* > *a**j* (otherwise the number of inversions will increase). Let *d**i*, *j* be the number of permutation of elements with indices from 0 to *i* inclusive which are strictly less than *j*. Then, after swapping elements with indices *i* and *j*, the number of inversions will be *old* - 2 * (*d**i*, *a**i* + *d**j*, *a**j* - *d**i*, *a**j* - *d**j*, *a**i*) - 1, where old is the number of inversions in the initial permutation. It is sufficient to search all pairs of elements and pick those which help to minimize the number of inversions. The reader may prove the correctness of the formula as a supplementary task.
+
+[362D - Fools and Foolproof Roads](/contest/362/problem/D "Codeforces Round 212 (Div. 2)")
+
+If the given graph contains less than *q* connectivity components, then there’s no solution. Otherwise it’s optimal at first add edges that connect different components and afterwards all remaining edges (they will be connect edges from one component). For the first phase you can use greedy algorithm: each time you select two components, current weight of which is minimal, and connect them with an edge. For example, you can store weights of all components in the current graph in some data structure (like set in С++). For the second phase it’s enough to find any component that contains two or more vertices (because loops are forbidden) and add all remaining edges between some two vertices of this component. If some action cannot be successfully executed (for example, you added all the edges and number of connectivity components if greater than *q*), then there’s no solution.
+
+Asymptotics — *O*(*n* + *m* + *plogn*).
+
+[362E - Petya and Pipes](/contest/362/problem/E "Codeforces Round 212 (Div. 2)")
+
+Construct the following flow network. Water tank 1 is the source, water tank *n* is the sink. Every pipe from water tank *u* to water tank *v* is presented as two arcs — the first one with capacity *c**uv* and cost 0 and the second one with infinite capacity and cost 1. Thus, the answer is the maximum flow with cost not greater than k. It can be found by standard augmenting paths algorithm.
+
+**UPD1.** Tutorial for problems A and B added. **UPD2.** Tutorial for problem C added.
diff --git a/editorials/363.md b/editorials/363.md
@@ -0,0 +1,25 @@
+Source: https://codeforces.com/blog/entry/9537
+
+#### [363A - Soroban](/contest/363/problem/A "Codeforces Round 211 (Div. 2)")
+
+Not so much to say about this problem. You need to extract the digits of the given number (read it as string or repeteadly divide by 10 and take the remainders). Then carefully do the mapping of digits to its' representation.
+
+#### [363B - Fence](/contest/363/problem/B "Codeforces Round 211 (Div. 2)")
+
+Another easy problem. We need to calculate the sum of every consequtive segment of *k* planks. One way to do this is to calculate partial prefix sums: . Then the sum of heights of the planks *i*, *i* + 1, ..., *i* + *k* - 1 is *s**i* + *k* - 1 - *s**i* - 1. The other approach is to calculate the sum of the first *k* planks: *h*1 + *h*2 + ... + *h**k*. By subtracting *h*1 and adding *h**k* + 1 we get sum of *k* planks starting from the second plank. Then, by subtracting *h*2 and adding *h**k* + 2 we get sum of *k* planks starting from the third plank, and so on.
+
+#### [363C - Fixing Typos](/contest/363/problem/C "Codeforces Round 211 (Div. 2)")
+
+The general idea of the solution is the following: while there are three consequtive equal characters, remove any one of them. After that we can only have typos of the second type. So, if we have one couple of equal characters immediately after another couple of equal characters (*xxyy*), we need to decide which character to remove, *x* or *y*? Let's find the leftmost typo of the second type in the string. It is easy to see that we can always remove the character from the second couple.
+
+All these can be done in a single pass. Go through the characters of the given string and build the resulting string *ans*. Let's denote the current character as *ch*. If *ch* is equal to the last two characters of *ans*, skip *ch*. If *ch* is equal to the last character of *ans* and *ans*[*length*(*ans*) - 2] = *ans*[*length*(*ans*) - 3] (assume that *ans* is 1-indexed), skip *ch*. Otherwise, append *ch* to *ans*.
+
+#### [363D - Renting Bikes](/contest/363/problem/D "Codeforces Round 211 (Div. 2)")
+
+Let's do a binary search over the number of boys that can rent a bike. So let's say that we want to check whether it possible for *k* boys to rent bikes. If some *k* boys can rent a bike, then the *k* "richest" boys (with the most amount of personal money) also can do that. It is easy to see that if they can rent bikes, they can rent *k* cheapest bikes (if we first sort the bikes in increasing order of price, it will be just the first *k* bikes).
+
+So, take *k* richest boys and try to match them with *k* cheapest bikes, spending as much common budget as possible. The following algorithm works (try to understand and prove it before asking questions): take the boy with least number of money (of course, among the considered *k* richest) and try to give him the cheapest bike. If the boy has ehough personal money to rent this bike, use his money to do this. Otherwise, use all his money and take some money from the common budget. Continue this process with the second cheapest bike and the second "poorest among the richest" boys. This process can end in two ways: we will either run out of budget and fail to rent *k* bikes, or we will successfully rent these bikes.
+
+#### [363E - Two Circles](/contest/363/problem/E "Codeforces Round 211 (Div. 2)")
+
+Correct solution will be published later.
diff --git a/editorials/5.md b/editorials/5.md
@@ -0,0 +1,98 @@
+Source: https://codeforces.com/blog/entry/213
+
+As there is no tutorial of Codeforces Beta Round #5 in English, I have decided to write this one. Possibly, some ideas will be similar to ones, expressed in Russian tutorial made by SkidanovAlex, but I hope everybody will find some useful in this problem analysis too.
+
+
+### **Problems A and B.**
+
+
+Both are implementation problems. The only difficult, many participants faced with - to read data correctly. It is recommended to use *gets(s)* or *getline(cin, s)* in C++, *readLine()* method of BufferedReader class in Java.
+
+
+### **Problem C.**
+
+
+First of all, for each closing bracket in our string let's define 2 values:
+
+* d[j] = position of corresponding open bracket, or -1 if closing bracket doesn't belong to any regular bracket sequence.
+* c[j] = position of **earliest** opening bracket, such that substring s(c[j], j) (both boundaries are inclusive) is a regular bracket sequence. Let's consider c[j] to be -1 if closing bracket doesn't belong to any regular bracket sequence.
+
+It can be seen, that c[j] defines the beginning position of the longest regular bracket sequence, which will end in position j. So, having c[j] answer for the problem can be easily calculated.
+
+Both d[j] and c[j] can be found with following algorithm, which uses stack.
+
+1. Iterate through the characters of the string.
+2. If current character is opening bracket, put its position into the stack.
+3. If current character is closing bracket, there are 2 subcases:
+
+* Stack is empty - this means that current closing bracket doesn't have corresponding open one. Hence, both d[j] and c[j] are equal to -1.
+* Stack is not empty - we will have position of the corresponding open bracket on the top of the stack - let's put it to d[j] and remove this position from the stack. Now it is obvious, that c[j] is equal at least to d[j]. But probably, there is a better value for c[j]. To find this out, we just need to look at the position d[j] - 1. If there is a closing bracket at this position, and c[d[j] - 1] is not -1, than we have 2 regular bracket sequences s(c[d[j] - 1], d[j] - 1) and s(d[j], j), which can be concatenated into one larger regular bracket sequence. So we put c[j] to be c[d[j] - 1] for this case.
+
+
+
+### **Problem D.**
+
+
+This problem can be solved by careful case handling. Let's construct O(1) solution for it.
+
+First of all, let's define 2 functions:
+
+
+1. *dist*(*speed*, *time*) - calculates the distance will be covered in specified time, if car's current speed is speed. This function will not take car's speed limit into account. Also it assumes, that car is always driven with maximum acceleration *a*. It is obvious that required distance is equal to 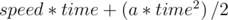.
+2. *travelTime*(*distance*, *speed*) - calculates the time, required to travel specified distance, if car have starting speed equal to speed. This function will also take care about car's speed limit.
+ We will have the following quadratic equation for time *t*: 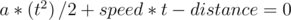. This equation will have exactly 2 different roots. Using Viete's formulas it can be concluded, that one root of the equation is non-positive and other is non-negative. Let's define the larger root of the equation as *tAll*. It will be the answer, if there is no car's speed limit. To take the limit into account let's find the time, required to gain car's max speed. *tMax* = (*v* - *speed*) / *a*. If *tMax* ≥ *tAll*, function should just returns *tAll* as a result. Otherwise result is *tMax* hours to achieve car's maximal speed plus (*distance* - *dist*(*speed*, *tMax*)) / *v* hours to cover remaining distance.
+
+
+Having these functions, solution will be the following:
+
+
+1. If *v* ≤ *w*, answer is *travelTime*(*l*, 0).
+2. Calculate *tw* = *w* / *a* - time, required to gain speed *w*.
+3. Consider *dw* = *dist*(0, *tw*).
+4. If *dw* ≥ *d*, we will pass the point there sign is placed before we gain speed *w*. Answer for this case is *travelTime*(*l*, 0) as well.
+5. Otherwise, we will gain speed *w* before the sign. Let's consider segment of the road [*dw*, *d*]. We need to find out the best strategy to drive it. It is obvious, that we definitely should have speed *w* at the both ends of this segment. Also we know, that acceleration is equal to deceleration. Taking these facts into account we can see, that the speed in the optimal solution will be symmetrical with respect to the middle of the segment [*dw*, *d*]. Hence answer for this case will be *tw* + 2 * *travelTime*(0.5 * (*d* - *dw*), *w*) + *travelTime*(*l* - *d*, *w*).
+
+### **Problem E.**
+
+
+Let's reduce the problem from the circle to the straight line. Perform the following actions to do it:
+
+
+1. Find the hill with the maximal height (if it is not unique, choose any).
+2. Rotate all the sequence in such a way that hill with maximal height goes first.
+3. For convenience, add one more hill with maximum height to the end of the sequence. (It will represent the first hill, which goes after the last in the circle order).
+
+Now we have almost the same problem on the straight line. One exception is that now first hill is doubled.
+
+*General idea of the solution:*
+
+Consider there is a pair of hills, such that these hills are visible from each other. Let's define hill with lower height (if heights are equal - with lower position) as *responsible* for adding this pair to the answer.
+
+From this point of view, hill x will adds to the answer 3 kinds of hills as his pair:
+
+* First hill to the left of the x, which is strictly higher than x. (Let's define its position as l[x])
+* First hill to the right of the x, which is strictly higher than x. (Let's call this hill y and define it's position as r[x]).
+* All hills that are as high as x and are located between x and y. (Let's define this count as c[x]).
+
+Arrays r[x] and c[x] can be calculated by the following piece of code:
+
+c[n] = 0;
+for(int i = n - 1; i >= 0; --i) {
+ r[i] = i + 1;
+ while (r[i] < n && height[i] > height[r[i]]) r[i] = r[r[i]];
+ if (r[i] < n && height[i] == height[r[i]]) {
+ c[i] = c[r[i]] + 1;
+ r[i] = r[r[i]];
+ }
+}
+
+I am not going to prove here, that it works for the O(N) time, but believe it does :)
+
+Pay attention, that r[x] is undefined for hills with maximum height and this algorithm will find r[x] = n for such hills.
+
+Array l[x] can be found in a similar way.
+
+Having l[x], r[x] and c[x], it's not so difficult to calculate the answer. We should just notice, that:
+
+* Each hill will add c[x] pairs to the answer.
+* Each hill, lower than maximal, will also add 2 pairs (x, l[x]) and (x, r[x]) to the answer. The only corner case here is l[x] = 0 and r[x] = n, because (x, 0) and (x, n) is the same pair of hills in the original problem, where hills are circled.
diff --git a/editorials/6.md b/editorials/6.md
@@ -0,0 +1,35 @@
+Source: https://codeforces.com/blog/entry/249
+
+### A. Треугольник
+
+Из трех палочек с длинами *a*, *b*, *c* > 0 можно составить треугольник ненулевой площади тогда и только тогда, когда:
+|*a* - *b*| < *c* < *a* + *b* (+)
+При вырожденном случае в (+) одно из неравенств обращается в равенство. (Для обоснования можно построить окружности радиуса *a* и *b* с центрами в концах отрезка длины *c*, и проверить когда они пересекаются).
+
+Таким образом, можно перебрать все тройки чисел из данных 4-х и проверить (+).
+
+
+### B. Кабинет президента
+
+Достаточно перебрать все клетки, соседние с клетками цвета стола президента, помечая их цвета. То есть после процедуры мы будем знать для каждого цвета, является ли он соседним с данным нам. Ответ на задачу - количество помеченных цветов.
+
+### C. Алиса, Боб и шоколад
+
+Необходимо промоделировать описанную в условии игру. Имеем два указателя на начало и конец массива длин шоколадок, каждый раз смещаясь по первому, второму или обоим (в зависимости от длин шоколадок). Сместившись только по одному указателю, нужно уменьшить длину недоеденной шоколадки.
+Единственная техническая трудность - правильно обработать последнюю шоколадку, можно ошибиться или зациклиться, если участники перейдут к ней одновременно.
+
+### E. Экспозиция
+
+Рассмотрим функцию *f*(*l*, *r*) = max(*hi*) - min(*hj*), *l* ≤ *i*, *j*≤ *r*. (<*максимум на отрезке*> - <*минимум на отрезке*>). Эта функция как раз и отражает разницу между самой высокой и самой низкой книгами на взятом отрезке.
+Если *l* возрастает при фиксированом *r*, то функция убывает, аналогично, по *r* функция растет. К монотонной по *r* функции *f*(*l*0, *r*) можно применить бинарный поиск и найти наибольшее *r*, для которого *f*(*l*0, *r*) ≤ *k*. Подходящая структура данных для поиска минимума (максимума) на отрезке - дерево отрезков.
+Для каждого левого конца можно найти максимально удаленный правый за время O(*n**log2(*n*)). (*n* - левых концов, O(log(*n*)) вычислений *f* с помощью дерева отрезков за O(log(*n*))). Из этого множества отрезков ответом являются те, длина которых максимальна.
+Можно упростить это решение и по написанию кода и по времени "техникой двух указателей". *pl* указывает на начало отрезка, *pr* на конец, причем если *f*(*pl*, *pr*) < *k*, то увеличиваем *pl*, иначе *pr*. Из-за уже указанных свойствах монотонности *f* по *l* и *r*, можно утверждать*,* что [*pl*, *pr*] заметут все искомые отрезки.
+
+Теперь можно увидеть, что мы используем всего три операции:
+<*добавить элемент* *pr*>
+<*удалить* *элемент* *pl*>
+<*взять максимум - минимум на текущем отрезке*>
+
+То есть можно просто кидать/удалять элементы вида (*hi*, *i*) в **set** (структура данных организующая множество, построенная на любом сбалансированном дереве, как правило есть стандартных библиотеках языка). Минимум - левый элемент в дереве, максимум - правый.
+
+Сложность алгоритма с сетом O(*n**log(*n*)). (≤ 2*n* смещений *pl*, *pr*, на каждом шаге обращение к сету за O(log(*n*))).
diff --git a/editorials/8.md b/editorials/8.md
@@ -0,0 +1,34 @@
+Source: https://codeforces.com/blog/entry/4441
+
+Recently, I started solving codeforces problems from the beginning. I just solved [Codeforces Beta Round 8](/contest/8 "Codeforces Beta Round 8"). I couldn't find any tutorial for the round so I decided to write tutorial for the last two problems. The others I solve long time ago in the real contest. Problem E took me quite some time and I couldn't find even a discussion about it, so here are my solutions.
+
+### D. [8D - Two Friends](/contest/8/problem/D "Codeforces Beta Round 8")
+
+The main observation for this problem is the following: If Alan and/or Bob is at some point X and moves following some curve and travels distance d, then the point at which they finish can be ANY point on or inside the circle with center X and radius d. In other words: If you start at some point X and go to some point Y, you can do this on as long curve as we want(only not shorter then the `distance(X, Y)`. Now, for convenience, lets say that `T1` is the longest allowed path for Alan and `T2` is the longest allowed path for Bob. These values are easily calculated:
+
+```
+T1 = distance(cinema, shop) + distance(shop, home) + t1
+T2 = distance(cinema, home) + t2
+```
+
+Now, there are two cases. The first and trivial case is when `distance(cinema, shop) + distance(shop, home) <= T2`. In this case, it is OK for Bob to go to the shop with Alan. If they go to the shop together there is no need for them to ever split. So they go together all the way from the cinema to the shop and then from the shop to their home. In this case the solution is `min(T1, T2)` Why? (Hint: here the observation in the beginning is important).
+
+The second case is when Bob cannot go to the shop with Alan. We'll solve this case with binary search on the distance that they could cover together before splitting. Let's assume that the go to some point `P` together covering some distance `x`. After they split Bob goes home in straight line and Alan first goes to the shop in straight line and then goes home again in straight line. This circumstance forces three condition for the point `P`.
+
+1. Point `P` must be inside a circle with center 'cinema' and radius `x`. This follows directly from the main observation.
+2. `x + distance(P, home) <= T2` — Bob must be able to go home in time. This condition means that `P` must be inside a circle with center `home` and radius `max(0, T2 - x)`.
+3. `x + distance(P, shop) + distance(shop, home) <= T1` — Alan must be able to go home in time. This condition means that `P` must be inside circle with center `shop` and radius `max(0, T1 - x - distance(shop, home)`.
+
+Now we have three circles and if they intersect, then it's possible to choose point `P` in such a way that Alan and Bob will the together the first `x` meters of their journey.
+
+Now, the problem is to check if three circles intersect. I come up with easy solution for this problem. I haven't proven it correct, but it seem to work. I don't know if there is some standard algorithm for this problem. My idea is the following. Let the 3 circles be `C1, C2 and C3`. If `C1 and C2` intersect they do it in one or two point. Now we check is some of these points is inside `C3`. If there is such point, then the 3 circles intersect, but if there is no such point, it doesn't necessarily mean thath the 3 circles doesn't intersect. We should try all permutations of the 3 circles. That is we first check C1 and C2 and the intersected points with C3, then C1 and C3 and the intersected points with C2, and so on.
+
+Here is my solution for reference: [1632676](/contest/8/submission/1632676 "Submission 1632676 by Nedy88")
+
+### E. [8E - Beads](/contest/8/problem/E "Codeforces Beta Round 8")
+
+This is quite an interesting problem for me. We must find the k-th lexicographically smallest number from a subset of the numbers from 0 to 2^N(It is easier to increase K with one and consider the all zeroes and all ones case, too). The numbers which we want to count are those which are smaller or equal to their inverted number(flip zeroes and ones), their reversed number(read the bits of the number from right to left) and their reversed and inverted number.
+
+Let's call a prefix the first half of the numbers, i.e. when only the first N/2 bits are set. Since N <= 50, there are at most 2 ^ 25 such numbers. Also we will only consider numbers with 0 at the first bit. If it is 1, then the inverse number will be smaller, so there are at most 2^24 prefixes. Now if we have some prefix, using dynamic programming we will see in how many ways can we finish it to a real number. The state of the dp is: `(int pos, bool less, bool lessInv)` and `dp[pos][less][lessInv]` is the number of ways to finish the number if we have to choose the pos-th bit now. `less` shows if so far we are less then or equal to the reversed number and `lessInv` shows if so far we are less then or equal to the inverted and reversed number. Using the dp we could easily find the k-th number.
+
+There is one final note. The DP here is run for every possible prefix and the prefixes could be up to 2^24. Every time we clear the DP table before running it. This makes the solution slow even for the 5 seconds time limit. There is one more observation which makes the solution run in time. We iterate the prefixes in order, that is in each step `newprefix = oldprefix + 1`. In this case only the last few bits of the prefix are changed. The other part of the prefix remains the same and there is no need to clear the whole DP table, only the parts that changed due to changing the last few bits. This is left for exercise and my solution using this method is: [1644014](/contest/8/submission/1644014 "Submission 1644014 by Nedy88")
diff --git a/editorials/9.md b/editorials/9.md
@@ -0,0 +1,55 @@
+Source: https://codeforces.com/blog/entry/283
+
+### A. [Die Roll](../../../contest/9/problem/A)
+
+If the maximum of Yakko's and Wakko's points is a, then Dot will win, if she has not less than a points. So the probability of her win is (6 - (a-1)) / 6. Since there are only 6 values for a, you can simply hardcode the answers.
+
+
+### B. [Running Student](../../../contest/9/problem/B)
+
+It is simple to calculate the time *t**i* that the Student will need, if he gets off the bus at the i-th stop: *t**i* = *b**i* + *s**i*, where *b**i* = *x**i* / *v**b* is the time he will drive on the bus, and 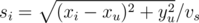 is the time he will need to get from the i-th stop to the University. We need to choose indices with minimal possible *t**i*, and among them - the index with minimal possible *s**i*, that is, with maximal *b**i*, that is (since the coordinates of bus stops are already ordered) with maximal i.
+
+Note that due to precision issues, you should be careful when you compare *t**i*: the condition *t**i* = *t**j* should be written in the form |*t**i* - *t**j*| < ε for some small ε.
+
+
+### C. [Hexadecimal's Numbers](../../../contest/9/problem/C)
+
+Brute force solution, when you try each number from 1 to n, will not fit into the time limit.
+Note, however, that all good numbers have at most 10 digits, and each of the digits is 0 or 1. That is, there are at most 210 binary strings to check. Each of these strings is a number from 1 to 210 - 1 in binary representation. So the algorithm is the following: for each number from 1 to 210 - 1 write its binary representation, read it as if it was decimal representation and compare the result to n.
+
+
+### D. [How many trees?](../../../contest/9/problem/D)
+
+Denote by *t**nh* the number of binary search trees on n nodes with height equal to h. We will derive a recurrent formula for *t**nh*. For the base case note that *t*00 = 1 (empty tree), and *t**i*0 = *t*0*i* = 0 if i>0.
+
+Now take any binary search tree on n nodes with height equal to h. Let m be the number written at its root, 1 ≤ *m* ≤ *n*. The left subtree is a binary search tree on m-1 nodes, and the right subtree is a binary search tree on n-m nodes. The maximal of their heights must be equal to h-1. Consider 2 subcases:
+1. The height of the left subtree is equal to h-1. There are *t**m* - 1, *h* - 1 such trees. The right subtree can have any height from 0 to h-1, so there are  such trees. Since we can choose left and right subtrees independently, we have 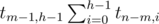 variants in this case.
+2. The height of the left subtree is less than h-1. There are  such trees, and the right subtree must have height exactly h-1, which gives us totally 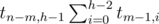 variants.
+So the recurrent formula is the following: 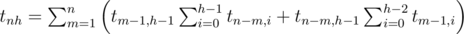.
+
+All the values *t**nh* can be calculated by dynamic programming. The answer, then, is .
+
+
+
+### E. [Interesting graph and Apples](../../../contest/9/problem/E)
+
+The funny ring consists of n vertices and n edges. If there is another edge except for these n, then the vertices it connects belong to more than one cycle. So, an interesting graph is just a funny ring.
+A graph is a funny ring if and only if the following conditions hold:
+A1. The degree of each vertex equals 2.
+A2. The graph is connected.
+ Now let's figure out when a graph is not yet a funny ring, but can be transformed into a funny ring by adding edges. There are obvious necessary conditions:
+B1. m < n.
+B2. There are no cycles.
+B3. The degree of each vertex is not more than 2.
+ Let's add edges so that these conditions were preserved, and the sequence of edges was lexicographically minimal. So, we add an edge (i,j) such that:
+1. The degrees of i and j are less than 2. (Otherwise we would break B3).
+2. i and j belong to different connected components. (Otherwise we would break B2).
+3. The pair (i,j) is lexicographically minimal.
+ Let's see what we have when we can't add edges anymore. Since there are no cycles, each connected component is a tree, and therefore has at least one vertex with degree less than 2. If there are two connected components, then they could be connected by an edge without breaking B1-B3. So the graph is connected, has no cycles, and the degree of each vertex is not more than 2. This means that the obtained graph is just a walk and we can connect its end points to obtain a funny ring.
+
+ To summarize, the algorithm is the following:
+ 1. Check if A1-A2 hold. If yes, output "YES" and 0.
+ 2. Check if B1-B3 hold. If no, output "NO".
+ 3. Output "YES" and n-m.
+ 4. Add edges as described. When the edge (i,j) is added, output "i j".
+ 5. Find the only vertices i and j with degree less than 2 (they can be equal if n=1). Output "i j".
