commit c8e1f7ab498ed689d240ee8728349fdf99c2fb44
parent ef0df92922e53716ec4b4792f1bb63f56552c811
Author: Andrew Laack <andrew@laack.co>
Date:   Mon,  9 Nov 2026 00:58:31 -0600

More editorials

Diffstat:
| A | editorials/120.md | | | 101 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/121.md | | | 31 | +++++++++++++++++++++++++++++++ |
| A | editorials/122.md | | | 31 | +++++++++++++++++++++++++++++++ |
| A | editorials/123.md | | | 43 | +++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/124.md | | | 43 | +++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/126.md | | | 86 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/127.md | | | 86 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/128.md | | | 37 | +++++++++++++++++++++++++++++++++++++ |
| A | editorials/129.md | | | 58 | ++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/130.md | | | 119 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/131.md | | | 70 | ++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/132.md | | | 51 | +++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/133.md | | | 51 | +++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/135.md | | | 99 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/137.md | | | 31 | +++++++++++++++++++++++++++++++ |
| A | editorials/138.md | | | 106 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/139.md | | | 106 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/141.md | | | 27 | +++++++++++++++++++++++++++ |
| A | editorials/142.md | | | 147 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/144.md | | | 33 | +++++++++++++++++++++++++++++++++ |
| A | editorials/145.md | | | 61 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/146.md | | | 61 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/148.md | | | 61 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/149.md | | | 47 | +++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/150.md | | | 83 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/151.md | | | 83 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/152.md | | | 96 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/153.md | | | 90 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/154.md | | | 63 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/155.md | | | 63 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/156.md | | | 128 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/157.md | | | 128 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/79.md | | | 42 | ++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/80.md | | | 39 | +++++++++++++++++++++++++++++++++++++++ |
| A | editorials/82.md | | | 29 | +++++++++++++++++++++++++++++ |
| A | editorials/83.md | | | 23 | +++++++++++++++++++++++ |
| A | editorials/85.md | | | 14 | ++++++++++++++ |
| A | editorials/86.md | | | 86 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/87.md | | | 83 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/88.md | | | 83 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/89.md | | | 119 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/90.md | | | 119 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/91.md | | | 100 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/92.md | | | 100 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/93.md | | | 53 | +++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/94.md | | | 128 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/95.md | | | 51 | +++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/96.md | | | 51 | +++++++++++++++++++++++++++++++++++++++++++++++++++ |
| A | editorials/97.md | | | 18 | ++++++++++++++++++ |
| A | editorials/98.md | | | 97 | +++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++++ |
50 files changed, 3555 insertions(+), 0 deletions(-)
diff --git a/editorials/120.md b/editorials/120.md
@@ -0,0 +1,101 @@
+Source: https://codeforces.com/blog/entry/2892
+
+You can leave your questions, suggestions and more beautiful in comments.
+
+### Problem A. Elevator
+
+
+
+You can either check all four cases or notice, that if we consider front/back equal to 0/1 (b) and decrease a by 1, then a XOR b became the answer (0/1). Time and memory consumption - *O*(1).
+
+
+
+
+
+### Problem B. Quiz League
+
+
+
+Just write one loop: while *k*th question has already been asked, increase *k* by one and if *k* > *n* let *k* = 1. Time and memory consumpiton - *O*(*n*).
+
+
+
+
+
+### Problem C. Winnie-the-Pooh and honey
+
+
+
+One of the possible solutions is direct emulation. Winnie won't do more than 3*n* iterations (because he can use each jar more than three times). You can emulate each iteration in *O*(*n*) (just find maximum in array). Summary time - *O*(*n*2) ≈ 104 operations, memory consumption - *O*(*n*)
+
+There is another shorter solution: let's notice that order of jars doesn't matter. Let's see how much honey from each jar will be eaten by Winnie and how much will be left to Piglet. If *a**i* ≥ 3*k* then Winnie will leave *a**i* - 3*k* kg of honey to Piglet. If *a**i* < 3*k* then he'll leave only  kg. Now solution is one loop. Time and memory consumption is *O*(*n*).
+
+
+
+
+
+### Problem E. Put Knight!
+
+
+
+Petya wins if *n* is odd, Gena wins if *n* is even. It's quite easy to prove - just do symmetrical turns.
+
+
+
+
+
+### Problem F. Spiders
+
+
+
+Answer is sum of all spiders' lengths. Use depth-first-search (started at all vertexes) to calculate length of each spider.
+
+
+
+
+
+### Problem G. Boom
+
+
+
+It's simple realization problem. All you need is two-dimensional arrays and one queue. [Code](http://pastebin.com/wW3j4HHN)
+
+
+
+
+
+### Problem H. Brevity is Soul of Wit
+
+
+
+Notice that there are only 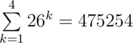 different strings that have length 4 or less. Then notice that each of input strings you can change to 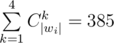 different short words at most (|*w**i*| is length of the *i*th word).
+
+Now let's make bipartite graph. One part is all source words, the second part is all short words and there is edge if and only if we can change word from the first part to the short word from the second part. Now our task is just find perfect matching in this graph. It can be done in *O*(*n*1· *m*) ≈ 200· 200· 385 = 15.4·106 operations which is enough.
+
+
+
+
+
+### Problem I. Luck is in Numbers
+
+
+
+Unfortunately, my solution for this problem is rather big. If someone know beautiful one share it please.
+
+The main idea is very standard: let's fix some prefix of number, which is strictly greater than such prefix of source number. If we can get known what is maximal happiness for suffix of our number then we can solve the problem by just running down values for each number in suffix and checking that we still can reach necessary value of happiness.
+
+Now solution for this subproblem is just to fill suffix with eights and calculate the answer. It's good but takes a lot of time. We need to store old values and recalculate its in *O*(1). There are very simple formulas to do it.
+
+
+
+
+
+### Problem J. Minimum sum
+
+
+
+Firstly you need to notice that you can turn all vectors in such way that all of them have non-negative coordinates and the answer will remain the same.
+
+And now we have the following problem: find two nearest points from the given set. It's standard divide-and-conquer problem, it's described in [Wikipedia](https://en.wikipedia.org/wiki/Closest_pair_of_points_problem).
+
+Also there is simpler solution (added by [diogen](/profile/diogen "Expert diogen")): let's sort all our points by distance from a random point far-far away. It's oblivious that if some points lie near each other, distance to this far point doesn't vary a lot. And now solution is run down for each point *C* points near it in the sorted array. *C* about 200 is enough to got Accepted.
diff --git a/editorials/121.md b/editorials/121.md
@@ -0,0 +1,31 @@
+Source: https://codeforces.com/blog/entry/2956
+
+**1. [Lucky Div (Div2 A)](/contest/122/problem/A "122A - Lucky Division")**
+
+In this problem you just need to loop through the integers *i* from 1 to *n* determine, is *i* lucky, if yes, then try, if *n* mod *i* = 0, then answer is "YES". If there are no such *i*, answer is "NO".
+
+**2. [Lucky Substring (Div2 B)](/contest/122/problem/B "122B - Lucky Substring")**
+
+Notice, that answer is either one digit or -1. So, if there are no 4 and 7 digits, then answer is -1. Else, if there is more or equel number of digits 4, then answer is 4, else answer is 7.
+
+**3. [Lucky Sum (Div1 A + Div2 C)](/contest/121/problem/A "121A - Lucky Sum")**
+
+Let generate all lucky number between 1 and 1010. Consider all segment [1;*L*0], [*L*0 + 1;*L*1], [*L*1 + 1;*L*2] ... Then the result equals to product of intersection of segments [1;*L*0] and [1;*n*] by *L*0 plus size of intersection of [*L*0 + 1;*L*1] and [1;*n*] multiplied by *L*1 and so on.
+
+**4. [Lucky Operation (Div1 B + Div2 D)](/contest/121/problem/B "121B - Lucky Transformation")**
+
+Notice, that if there exits such *i* that *i* mod 2 = 0 and *d**i* = 4 and *d**i* + 1 = 7 and *d**i* - 1 = 4 then after that operation there will be a loop. So, let we simple do all operation from left ro right, and, when we will win our loop, just return a rusult (which variates by *k* mod 2 (*k* is one that leaves after operation from left side).
+
+**5. [Lucky Permuation (Div1 C + Div2 E)](/contest/121/problem/C "121C - Lucky Permutation")**
+
+If *n* ≤ 14 let find out, is *k* more than *n*! or not? If yes, then return -1. Then, notice, that since *k* ≤ 109, then at most 13 elements from right (suffix) will change. So, element from left of this part (prefix) will not change (then we can just find a number of lucky numbers on than range). To find result for the rest of the permutation (suffix) we need to find *k*-th permutation of number from 1 to *t* (*t* is maximun integer, such that *t*! ≤ *k*). After we find that permutation, we can just loop through that permutation and count result.
+
+**6. [Lucky Segments (Div1 D)](/contest/121/problem/D "121D - Lucky Segments")**
+
+Lei calculate arrays *L* and *R*. Let for all lucky *i*, *L*[*i*] = number of operation needed to move every segment, which's right end is to left from *i* to *i*. *R*[*i*] = number of operation needed to move every segment which left end is to right to *i*. How to calculate such array? Just use a sorting. Let arrange array *A* of pairs of integers, first - number, second equals to 0, if that number end of some segment, 1 if that number is lucky. Then, iterate from left to right, counting number of segment end we counted and *s**i*, *s**i* = *s**i* - 1 + (*A**i* - *A**i* - 1) * *c**i*. The same way you can use to *R*. Now, to find the answer we must find (using method of two pointers of binary search) pair of indexes *x* and *y*, such that *i* ≤ *j*, *L**j* + *R**i* ≤ *k*, *Lucky**j* - *Lucky**i* + 1 ≤ min_size_of_input_segment. Also, is this problem you should arrange function *Mul*(*a*, *b*), which return *min*(*a* * *b*, *INF*). Since simple multiplication overflows, then you can use multipling modulo 264 or double or min-long-arithmetic.
+
+**7. [Lucky Array (Div1 E)](/contest/121/problem/E "121E - Lucky Array")**
+
+In this problem you can use many different algorithms, here is one of them. Obviously, number of different lucky number is 30, because *A**i* always is ≤ 10000. Let *D**i* - difference between minimum lucky number which is greater than or equal to *A**i* and *A**i*. Now, we need to have 5 (but you can use less number) of operation on *D*: Subtract(l, r, d) - subtract number *d* from all *A**i* (*l* ≤ *i* ≤ *r*), Minimum(l, r) - minumum number of all *D**i* (*l* ≤ *i* ≤ *r*), Count(l, r) - how many times that minimum occared in that interval, Left(l, r) = leftmost occarence of that minimum, Set(i, d) - assign *d* to *D**i* (*D**i* = *d*). Now, we can do our operations. If our operation is "count", then we need to find minimum number *d* (*d* = Minimum(l, r)), if it is equal to 0, then answer is Count(l, r, 0), otherwise, answer is 0. If out operation is "add", then we need to Subtract(l, r, d), but now some *D**i* might be less than 0. So, while, Minimum(l, r) ≤ 0, let j = Left(l, r), assign *D**j* new value (use Set(j, *D**j*')), which can be calculated with complaxity *O*(1).
+
+Complexity of this algorithm is *O*(*m* * *log*(*n*) + *n* * *log*(*n*) * *C*), where *C* is equal to 30.
diff --git a/editorials/122.md b/editorials/122.md
@@ -0,0 +1,31 @@
+Source: https://codeforces.com/blog/entry/2956
+
+**1. [Lucky Div (Div2 A)](/contest/122/problem/A "122A - Lucky Division")**
+
+In this problem you just need to loop through the integers *i* from 1 to *n* determine, is *i* lucky, if yes, then try, if *n* mod *i* = 0, then answer is "YES". If there are no such *i*, answer is "NO".
+
+**2. [Lucky Substring (Div2 B)](/contest/122/problem/B "122B - Lucky Substring")**
+
+Notice, that answer is either one digit or -1. So, if there are no 4 and 7 digits, then answer is -1. Else, if there is more or equel number of digits 4, then answer is 4, else answer is 7.
+
+**3. [Lucky Sum (Div1 A + Div2 C)](/contest/121/problem/A "121A - Lucky Sum")**
+
+Let generate all lucky number between 1 and 1010. Consider all segment [1;*L*0], [*L*0 + 1;*L*1], [*L*1 + 1;*L*2] ... Then the result equals to product of intersection of segments [1;*L*0] and [1;*n*] by *L*0 plus size of intersection of [*L*0 + 1;*L*1] and [1;*n*] multiplied by *L*1 and so on.
+
+**4. [Lucky Operation (Div1 B + Div2 D)](/contest/121/problem/B "121B - Lucky Transformation")**
+
+Notice, that if there exits such *i* that *i* mod 2 = 0 and *d**i* = 4 and *d**i* + 1 = 7 and *d**i* - 1 = 4 then after that operation there will be a loop. So, let we simple do all operation from left ro right, and, when we will win our loop, just return a rusult (which variates by *k* mod 2 (*k* is one that leaves after operation from left side).
+
+**5. [Lucky Permuation (Div1 C + Div2 E)](/contest/121/problem/C "121C - Lucky Permutation")**
+
+If *n* ≤ 14 let find out, is *k* more than *n*! or not? If yes, then return -1. Then, notice, that since *k* ≤ 109, then at most 13 elements from right (suffix) will change. So, element from left of this part (prefix) will not change (then we can just find a number of lucky numbers on than range). To find result for the rest of the permutation (suffix) we need to find *k*-th permutation of number from 1 to *t* (*t* is maximun integer, such that *t*! ≤ *k*). After we find that permutation, we can just loop through that permutation and count result.
+
+**6. [Lucky Segments (Div1 D)](/contest/121/problem/D "121D - Lucky Segments")**
+
+Lei calculate arrays *L* and *R*. Let for all lucky *i*, *L*[*i*] = number of operation needed to move every segment, which's right end is to left from *i* to *i*. *R*[*i*] = number of operation needed to move every segment which left end is to right to *i*. How to calculate such array? Just use a sorting. Let arrange array *A* of pairs of integers, first - number, second equals to 0, if that number end of some segment, 1 if that number is lucky. Then, iterate from left to right, counting number of segment end we counted and *s**i*, *s**i* = *s**i* - 1 + (*A**i* - *A**i* - 1) * *c**i*. The same way you can use to *R*. Now, to find the answer we must find (using method of two pointers of binary search) pair of indexes *x* and *y*, such that *i* ≤ *j*, *L**j* + *R**i* ≤ *k*, *Lucky**j* - *Lucky**i* + 1 ≤ min_size_of_input_segment. Also, is this problem you should arrange function *Mul*(*a*, *b*), which return *min*(*a* * *b*, *INF*). Since simple multiplication overflows, then you can use multipling modulo 264 or double or min-long-arithmetic.
+
+**7. [Lucky Array (Div1 E)](/contest/121/problem/E "121E - Lucky Array")**
+
+In this problem you can use many different algorithms, here is one of them. Obviously, number of different lucky number is 30, because *A**i* always is ≤ 10000. Let *D**i* - difference between minimum lucky number which is greater than or equal to *A**i* and *A**i*. Now, we need to have 5 (but you can use less number) of operation on *D*: Subtract(l, r, d) - subtract number *d* from all *A**i* (*l* ≤ *i* ≤ *r*), Minimum(l, r) - minumum number of all *D**i* (*l* ≤ *i* ≤ *r*), Count(l, r) - how many times that minimum occared in that interval, Left(l, r) = leftmost occarence of that minimum, Set(i, d) - assign *d* to *D**i* (*D**i* = *d*). Now, we can do our operations. If our operation is "count", then we need to find minimum number *d* (*d* = Minimum(l, r)), if it is equal to 0, then answer is Count(l, r, 0), otherwise, answer is 0. If out operation is "add", then we need to Subtract(l, r, d), but now some *D**i* might be less than 0. So, while, Minimum(l, r) ≤ 0, let j = Left(l, r), assign *D**j* new value (use Set(j, *D**j*')), which can be calculated with complaxity *O*(1).
+
+Complexity of this algorithm is *O*(*m* * *log*(*n*) + *n* * *log*(*n*) * *C*), where *C* is equal to 30.
diff --git a/editorials/123.md b/editorials/123.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/3047
+
+**Div-2. [124A - The number of positions](/contest/124/problem/A "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's iterate through the each item and check whether it is appropriate to the conditions *a* ≤ *i* - 1 and *n* - *i* ≤ *b* (for *i* from 1 to *n*). The first condition can be converted into *a* + 1 ≤ *i*, and the condition *n* - *i* ≤ *b* in *n* - *b* ≤ *i*, then the general condition can be written *max*(*a* + 1, *n* - *b*) ≤ *i* and then our answer can be calculated by the formula *n* - *max*(*a* + 1, *n* - *b*) + 1.
+[The author's solution](/contest/124/submission/835581 "Submission 835581 by aropan")
+
+**Div-2. [124B - Permutations](/contest/124/problem/B "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's try all possible ways to rearrange digits in the numbers and check the difference between maximum and minimum number.
+[The author's solution](/contest/124/submission/835584 "Submission 835584 by aropan")
+
+**Div-1. [123A - Prime Permutation](/contest/123/problem/A "Codeforces Beta Round 92 (Div. 1 Only)")
+Div-2. [124C - Prime Permutation](/contest/124/problem/C "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+All positions except the first and those whose number is a prime greater |*s*| / 2 have to have the same symbol. Remaining positions can have any symbol. Consider positions that should be the same for *p* = 2 is 2,4,6,8 ... Now let's take a position with the number *x* ≤ |*s*| / 2, this position should have the same character as the position of 2 as the symbol *x* must be equal to the character at position 2 * *x*, which is equal to the character at position 2. Now consider the position whose number is more than |*s*| / 2. If this position is not a prime then there is a prime number *p* to divide the number at our positions and *p* ≤ |*s*| / 2. So character at position *p* is equal the character at position 2 and so a symbol at our position is also consistent to the character at position 2. The remaining positions are not combined with any other positions so it does not matter which symbol is situated here.
+Let's find the symbol which occurs the most and try to place the symbol on the position in which the characters have to be equal. If this symbol for all positions is not enough then the answer will be "NO", otherwise arrange the remaining characters by any way at other positions.
+[The author's solution](/contest/123/submission/835585 "Submission 835585 by aropan")
+
+**Div-1. [123B - Squares](/contest/123/problem/B "Codeforces Beta Round 92 (Div. 1 Only)")**
+**Div-2. [124D - Squares](/contest/124/problem/D "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's turn the field on 45*o* transforming cells coordinates (*x*, *y*) in (*x* + *y*, *x* - *y*). Then the cell (*x*, *y*) will be bad if one of the conditions occurs *x* ≡ 0 (*mod* 2*a*) or *y* ≡ 0 (*mod* 2*b*). So good cells will be divided into sectors by vertical and horizontal lines. For each sector, it is possible to determine the coordinates of a pair of numbers, the first number that will rise during the transition to the next right sector, and the second pair number will increase during the transition to the next upper sector. From the sector with coordinates (*x*, *y*) can go to any nearby on the side of the sector, visiting at least one bad cell, ie in (*x* - 1, *y*), (*x* + 1, *y*), (*x*, *y* - 1) and (*x*, *y* + 1). Since the numbers 2*a* and 2*b* have the same parity, then from the sector (*x*, *y*) can also go to the sector on the diagonal, and visiting a bad cell, ie in (*x* - 1, *y* + 1), (*x* + 1, *y* - 1), (*x* - 1, *y* - 1) and (*x* + 1, *y* + 1). Then it turns out that the minimum number of bad cells, which should be visited on the way out of from the sector (*x*1, *y*1) to sector of (*x*2, *y*2) equals *max*(|*x*1 - *x*2|, |*y*1 - *y*2|).
+Let's transform the coordinates of the initial and final cells as described rule above. Then find sectors which contain our cells and calculate answer with formula above.
+[The author's solution](/contest/123/submission/835587 "Submission 835587 by aropan")
+
+**Div-1. [123C - Brackets](/contest/123/problem/C "Codeforces Beta Round 92 (Div. 1 Only)")**
+**Div-2. [124E - Brackets](/contest/124/problem/E "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's reduce the problem to a one-dimensional matrix. Consider a monotonous path (1, 1), (1, 2), ..., (1, *m* - 1), (1, *m*), (2, *m*), ..., (*n* - 1, *m*), (*n*, *m*) which has correct bracket sequence. Now, in this way a cell (1, *m*) can be replaced on (2, *m* - 1) and still be a monotonous way and will form the correct sequence of the bracket. So in the cells of (1, *m*) and (2, *m* - 1) is one type of bracket. Proceeding further (eg to replace (1, *m* - 1) on (2, *m* - 2) or (2, *m*) on (3, *m* - 1)) can be seen that in cells (*i*, *j*) and (*i* - 1, *j* + 1) is one type of bracket. Then we get not two-dimensional array *n* × *m*, a one-dimensional size *n* + *m* - 1. For each position can be determined what her highest priority, ie for cell *i* (1 ≤ *i* ≤ *n* + *m* - 1), the priority will be equal to the minimum value of *p**x*, *y* where 1 ≤ *x* ≤ *n*, 1 ≤ *y* ≤ *m* and *x* + *y* - 1 = *i*.
+Let's iterate through the positions, starting with the highest priority. Let's put in this position the bracket "(" and consider how many ways can complete the remaining brackets to get the correct bracket sequence. If the number of ways of not less than *k*, then leave in this position "(", or reduce the *k* on the number of ways and put in this positions bracket ")". And so let's iterate through all items. In order to calculate the number of ways each time dynamics is calculated on two parameters *f**i*, *j*, where *i* is the number of processed positions, and *j* is the number of opened brackets. If the position of *i* + 1 bracket is not defined yet then you can go to *f**i* + 1, *j* + 1 or *f**i* + 1, *j* - 1, if defined then only *f**i* + 1, *j* + 1 or only *f**i* + 1, *j* - 1, depending on opening or closing bracket respectively.
+[The author's solution](/contest/123/submission/835590 "Submission 835590 by aropan")
+
+**Div-1. [123D - String](/contest/123/problem/D "Codeforces Beta Round 92 (Div. 1 Only)")**
+
+Sort all suffixes of the string (denoted by an array of strings *c**i*). Then the answer to the problem is the amount of 1 ≤ *i* ≤ *j* ≤ |*s*| and 1 ≤ *k*, that the prefixes of length *k* in all *c**i*..*j* are equal. Options when *i* = *j*, and 1 ≤ *k* ≤ |*c**i*| can calculate at once, it is the number of substrings in the string, ie |*s*| * (|*s*| + 1) / 2. Now let's count the LCP (longest common prefix) for adjacent suffixes, ie *a**i* = *LCP*(*c**i*, *c**i* + 1) for 1 ≤ *i* < |*s*|. Then let's count the number of 1 ≤ *i* ≤ *j* < |*s*| and 1 ≤ *k*, that *k* ≤ *min*(*a**i*..*j*). This task is to count the number of rectangles if there is a limit to the height of each column, ie *a**i* the maximum height of the rectangle in the column *i*. Solve by a stack or list.
+[The author's solution](/contest/123/submission/835591 "Submission 835591 by aropan")
+
+**Div-1. [123E - Maze](/contest/123/problem/E "Codeforces Beta Round 92 (Div. 1 Only)")**
+
+Consider what is the expected value for a given entrance and exit vertexes. It is clear that there will be only one path from the entrance to the exit, which in any case will be passed. Also, you can still go in the wrong direction. Consider the case when the chosen vertex from which there is *k* false paths and one right (it is always). Then before going in the right direction it can be 2*k* equiprobable way around false paths. Every false way occurs the 2*k* - 1 ways and to increase the number of moves in 2 × < *amount* *of* *vertexes* *in* *false* *subtree* > ie expectation of a false path to increase by 2 × < *amount* *of* *vertexes* *in* *false* *subtree* > × 2*k* - 1 / 2*k* = < *amount* *of* *vertexes* *in* *false* *subtree* > . Then expectation in vertex is equal to sum of < *amount* *of* *vertexes* *in* *false* *subtrees* > + 1 (a move in the right direction) + expectation of the vertex if to go the right direction. The result is that the expected value equal to the number of edges reachable from the entrance, without passing through the exit.
+Let's run dfs and consider of the vertex as exit vertex. Then, if in some subtree defined entrance, the expected value equal to the size of the subtree. Calculate how much of each subtree is the number of entrance and calculate the number of moves, if the exit is in the current vertex. It is necessary not to forget to count cases where the current vertex is an exit and entrance is higher in the tree traversal.
+[The author's solution](/contest/123/submission/835592 "Submission 835592 by aropan")
diff --git a/editorials/124.md b/editorials/124.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/3047
+
+**Div-2. [124A - The number of positions](/contest/124/problem/A "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's iterate through the each item and check whether it is appropriate to the conditions *a* ≤ *i* - 1 and *n* - *i* ≤ *b* (for *i* from 1 to *n*). The first condition can be converted into *a* + 1 ≤ *i*, and the condition *n* - *i* ≤ *b* in *n* - *b* ≤ *i*, then the general condition can be written *max*(*a* + 1, *n* - *b*) ≤ *i* and then our answer can be calculated by the formula *n* - *max*(*a* + 1, *n* - *b*) + 1.
+[The author's solution](/contest/124/submission/835581 "Submission 835581 by aropan")
+
+**Div-2. [124B - Permutations](/contest/124/problem/B "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's try all possible ways to rearrange digits in the numbers and check the difference between maximum and minimum number.
+[The author's solution](/contest/124/submission/835584 "Submission 835584 by aropan")
+
+**Div-1. [123A - Prime Permutation](/contest/123/problem/A "Codeforces Beta Round 92 (Div. 1 Only)")
+Div-2. [124C - Prime Permutation](/contest/124/problem/C "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+All positions except the first and those whose number is a prime greater |*s*| / 2 have to have the same symbol. Remaining positions can have any symbol. Consider positions that should be the same for *p* = 2 is 2,4,6,8 ... Now let's take a position with the number *x* ≤ |*s*| / 2, this position should have the same character as the position of 2 as the symbol *x* must be equal to the character at position 2 * *x*, which is equal to the character at position 2. Now consider the position whose number is more than |*s*| / 2. If this position is not a prime then there is a prime number *p* to divide the number at our positions and *p* ≤ |*s*| / 2. So character at position *p* is equal the character at position 2 and so a symbol at our position is also consistent to the character at position 2. The remaining positions are not combined with any other positions so it does not matter which symbol is situated here.
+Let's find the symbol which occurs the most and try to place the symbol on the position in which the characters have to be equal. If this symbol for all positions is not enough then the answer will be "NO", otherwise arrange the remaining characters by any way at other positions.
+[The author's solution](/contest/123/submission/835585 "Submission 835585 by aropan")
+
+**Div-1. [123B - Squares](/contest/123/problem/B "Codeforces Beta Round 92 (Div. 1 Only)")**
+**Div-2. [124D - Squares](/contest/124/problem/D "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's turn the field on 45*o* transforming cells coordinates (*x*, *y*) in (*x* + *y*, *x* - *y*). Then the cell (*x*, *y*) will be bad if one of the conditions occurs *x* ≡ 0 (*mod* 2*a*) or *y* ≡ 0 (*mod* 2*b*). So good cells will be divided into sectors by vertical and horizontal lines. For each sector, it is possible to determine the coordinates of a pair of numbers, the first number that will rise during the transition to the next right sector, and the second pair number will increase during the transition to the next upper sector. From the sector with coordinates (*x*, *y*) can go to any nearby on the side of the sector, visiting at least one bad cell, ie in (*x* - 1, *y*), (*x* + 1, *y*), (*x*, *y* - 1) and (*x*, *y* + 1). Since the numbers 2*a* and 2*b* have the same parity, then from the sector (*x*, *y*) can also go to the sector on the diagonal, and visiting a bad cell, ie in (*x* - 1, *y* + 1), (*x* + 1, *y* - 1), (*x* - 1, *y* - 1) and (*x* + 1, *y* + 1). Then it turns out that the minimum number of bad cells, which should be visited on the way out of from the sector (*x*1, *y*1) to sector of (*x*2, *y*2) equals *max*(|*x*1 - *x*2|, |*y*1 - *y*2|).
+Let's transform the coordinates of the initial and final cells as described rule above. Then find sectors which contain our cells and calculate answer with formula above.
+[The author's solution](/contest/123/submission/835587 "Submission 835587 by aropan")
+
+**Div-1. [123C - Brackets](/contest/123/problem/C "Codeforces Beta Round 92 (Div. 1 Only)")**
+**Div-2. [124E - Brackets](/contest/124/problem/E "Codeforces Beta Round 92 (Div. 2 Only)")**
+
+Let's reduce the problem to a one-dimensional matrix. Consider a monotonous path (1, 1), (1, 2), ..., (1, *m* - 1), (1, *m*), (2, *m*), ..., (*n* - 1, *m*), (*n*, *m*) which has correct bracket sequence. Now, in this way a cell (1, *m*) can be replaced on (2, *m* - 1) and still be a monotonous way and will form the correct sequence of the bracket. So in the cells of (1, *m*) and (2, *m* - 1) is one type of bracket. Proceeding further (eg to replace (1, *m* - 1) on (2, *m* - 2) or (2, *m*) on (3, *m* - 1)) can be seen that in cells (*i*, *j*) and (*i* - 1, *j* + 1) is one type of bracket. Then we get not two-dimensional array *n* × *m*, a one-dimensional size *n* + *m* - 1. For each position can be determined what her highest priority, ie for cell *i* (1 ≤ *i* ≤ *n* + *m* - 1), the priority will be equal to the minimum value of *p**x*, *y* where 1 ≤ *x* ≤ *n*, 1 ≤ *y* ≤ *m* and *x* + *y* - 1 = *i*.
+Let's iterate through the positions, starting with the highest priority. Let's put in this position the bracket "(" and consider how many ways can complete the remaining brackets to get the correct bracket sequence. If the number of ways of not less than *k*, then leave in this position "(", or reduce the *k* on the number of ways and put in this positions bracket ")". And so let's iterate through all items. In order to calculate the number of ways each time dynamics is calculated on two parameters *f**i*, *j*, where *i* is the number of processed positions, and *j* is the number of opened brackets. If the position of *i* + 1 bracket is not defined yet then you can go to *f**i* + 1, *j* + 1 or *f**i* + 1, *j* - 1, if defined then only *f**i* + 1, *j* + 1 or only *f**i* + 1, *j* - 1, depending on opening or closing bracket respectively.
+[The author's solution](/contest/123/submission/835590 "Submission 835590 by aropan")
+
+**Div-1. [123D - String](/contest/123/problem/D "Codeforces Beta Round 92 (Div. 1 Only)")**
+
+Sort all suffixes of the string (denoted by an array of strings *c**i*). Then the answer to the problem is the amount of 1 ≤ *i* ≤ *j* ≤ |*s*| and 1 ≤ *k*, that the prefixes of length *k* in all *c**i*..*j* are equal. Options when *i* = *j*, and 1 ≤ *k* ≤ |*c**i*| can calculate at once, it is the number of substrings in the string, ie |*s*| * (|*s*| + 1) / 2. Now let's count the LCP (longest common prefix) for adjacent suffixes, ie *a**i* = *LCP*(*c**i*, *c**i* + 1) for 1 ≤ *i* < |*s*|. Then let's count the number of 1 ≤ *i* ≤ *j* < |*s*| and 1 ≤ *k*, that *k* ≤ *min*(*a**i*..*j*). This task is to count the number of rectangles if there is a limit to the height of each column, ie *a**i* the maximum height of the rectangle in the column *i*. Solve by a stack or list.
+[The author's solution](/contest/123/submission/835591 "Submission 835591 by aropan")
+
+**Div-1. [123E - Maze](/contest/123/problem/E "Codeforces Beta Round 92 (Div. 1 Only)")**
+
+Consider what is the expected value for a given entrance and exit vertexes. It is clear that there will be only one path from the entrance to the exit, which in any case will be passed. Also, you can still go in the wrong direction. Consider the case when the chosen vertex from which there is *k* false paths and one right (it is always). Then before going in the right direction it can be 2*k* equiprobable way around false paths. Every false way occurs the 2*k* - 1 ways and to increase the number of moves in 2 × < *amount* *of* *vertexes* *in* *false* *subtree* > ie expectation of a false path to increase by 2 × < *amount* *of* *vertexes* *in* *false* *subtree* > × 2*k* - 1 / 2*k* = < *amount* *of* *vertexes* *in* *false* *subtree* > . Then expectation in vertex is equal to sum of < *amount* *of* *vertexes* *in* *false* *subtrees* > + 1 (a move in the right direction) + expectation of the vertex if to go the right direction. The result is that the expected value equal to the number of edges reachable from the entrance, without passing through the exit.
+Let's run dfs and consider of the vertex as exit vertex. Then, if in some subtree defined entrance, the expected value equal to the size of the subtree. Calculate how much of each subtree is the number of entrance and calculate the number of moves, if the exit is in the current vertex. It is necessary not to forget to count cases where the current vertex is an exit and entrance is higher in the tree traversal.
+[The author's solution](/contest/123/submission/835592 "Submission 835592 by aropan")
diff --git a/editorials/126.md b/editorials/126.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/3140
+
+**div2 A.** In this problem you should find length of polyline, multiply it by *k* / 50 and output that you will recieve. Length of polyline is sum of lengths of its segments. You can calculate length of every segment using Pythagorean theorem: 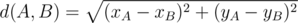.
+
+**div2 B.** Idea of this problem was offered by [RAD](/profile/RAD "Candidate Master RAD"). It was the last problem in the problemset and I had no any easy idea:) I thank him for it.
+
+Here you should calculate an array *cnt*[100]. *i*-th element of it stores number of sticks whose lengths equal *i*. Now you should calculate number of pairs of sticks of equal lengths. This number is 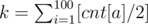, where [*x*] is floor of *x*. For every frame you need 2 if such pairs and you can choose it in any order. Therefore the answer will be *z* = [*k* / 2].
+
+**div2 С. div1 A.** At the first you should consider cases when *t*0 = *t*1, *t*0 = *t*2 and *t*1 = *t*2. Answers will be (*x*1, 0), (0, *x*2) and (*x*1, *x*2). The last 2 of them didn't present in the pretests.
+
+Next, for all 1 ≤ *y*1 ≤ *x*1 you should find minimal *y*2, for that *t*(*y*1, *y*2) ≥ *t*0. You can do it using one of three ways: binary search, two pointers or just calculation by formula [*y*1(*t*0 - *t*1) / (*t*2 - *t*0)], where [*x*] is rounding up of *x*. You should iterate over all cases and choose one optimal of them.
+
+The last tricky case consists in the fact that for all 1 ≤ *y*1 ≤ *x*1 и 1 ≤ *y*2 ≤ *x*2 *t*(*y*1, *y*2) < *t*0. For example, you can see following test
+
+100 110 2 2 109 (it is the 6th pretest).
+
+In this case you should output (0, *x*2).
+
+All calculations should be done in 64-bit integers (8th pretest checks overflow of 32-bit integers) or very carefully in the real numbers.
+
+**div2 D. div1 B.**
+
+Let us calculate a prefix-function for all prefices of string. Prefix-function *p*[*i*] is maximal length of prefix that also is suffix of substring [1...*i*]. More about prefix function you can see in a description of Knuth-Morris-Pratt algorithm (KMP).
+
+The first of possible answers is prefix of length *p*[*n*]. If *p*[*n*] = 0, there is no solution. For checking the first possible answer you should iterate over *p*[*i*]. If at least one of them equal to *p*[*n*] (but not *n*-th, of course) - you found the answer. The second possible answer is prefix of length *p*[*p*[*n*]]. If *p*[*p*[*n*]] = 0, you also have no solution. Otherwise you can be sure that the answer already found. This substring is a prefix and a suffix of our string. Also it is suffix of prefix with length *p*[*n*] that places inside of all string. This solution works in *O*(*n*).
+
+Also this problem can be solved using hashing. You can find hash of every substring in O(1) and compare substrings by comparing thier hashes. Well, let's check for every prefix that it is a suffix of our string and store thier lengths into some array in the increasing order. Then, using binary search over the array, you can find maximal length of prefix that lie inside of string. Check of every prefix you can do in *O*(*n*). So, you have some  solution.
+
+In point of fact, the array of prefix lengths in the previous solution is list { *p*[*n*], *p*[*p*[*n*]], ... }, that written if reversed order. From the first solution you know that the answer is prefix of length either *p*[*n*], or *p*[*p*[*n*]] (if it exists, of course). Therefore some naive solution without binary search can fits in the limits if you will stupidly check all prefices in the order of decrease thier lengths:) This solution works in *O*(*n*).
+
+Also this problem can be solved using *z*-function.
+
+**div2 E. div1 C.** You can see that every command *i*, *j* you should do no more than once. Also order of commands doesn't matter. Actually, sequence of command you can represent as boolean matrix *A* with size *n* × *n*, where *a**ij* = 1 mean that you do the command *i*, *j*, and *a**ij* = 0 mean that you don't do it.
+
+Let us describe one way to construct the matrix.
+
+Let the starting image is boolean matrix *G*. A boolean matrix *B* of size *n* × *n* stores intermediate image that you will recieve during process of doing commands.
+
+For the upper half of matrix *G* without main diagonal you should move line by line from the up to the down. For every line you should move from the right to the left. You can see that for every positions all nonconsidered positions do not affect the current position. So, if you see that values for position *i*, *j* in the matrices *G* and *B* are different, you should do command *i*, *j*: set in the matrix *A* *a**ij* = 1, and change segments (*i*, *i*) - (*i*, *j*) and (*j*, *j*) - (*i*, *j*) in the matrix *B*.
+
+For the lower half of the matrix *G* without main diagonal you should do it absolutely symmetric. At the end you should iterate over main diagonal. Here it should be clear.
+
+Well, for matrix *G* you always can build matrix *A* and do it by exactly one way. It mean that this way requires minimum number of commands. So, you can get answer for problem by following way: you can build the matrix *A* from the matrix *G* and output number of ones in the matrix *A*.
+
+There is only one problem that you should solve. Algorithm that you can see above works in *O*(*n*3), that doesn't fit into time limits. Let's speed up it to *O*(*n*2). Consider in the matrix *B* the upper half without main diagonal. During doing commands all columns of cells that placed below current position will have same values. Values above current position are not matter for us. Therefore instead of the matrix *B* you can use only one array that stores values of columns. It allows you do every command in *O*(1) instead of *O*(*n*). This optimization gives a solution that works in *O*(*n*2).
+
+**div1 D.** Let us represent a number in the Fibonacci code. You can imagine Fibonacci coding by following way: *i*-th bit of number corresponds to the *i*-th Fibonacci number. For example, 16=13+3 will be written as 100100. You can represent into this code any positive integer, for that no two neighbouring 1-bit will be present. It is possible to do it by only one way (let's define this way as canonical). In the problem you should calculate a number of ways to represent some number into Fibonacci code in that two ones can be placed in the neighbour positions.
+
+You can easily get the canonical representation if you generate several of Fibonacci numbers (about 90) and after that try to substract all of them in the decreasing order.
+
+You should store positions of 1-bits of canonical representation into an array *s* in the increasing order. You can decompose any of them into two ones. It looks like that:
+
+1000000001 // starting number;
+0110000001 // there we decompose
+0101100001 // the first "one"
+0101011001 // using all
+0101010111 // possible ways
+
+After some number of such operations you will meet next 1-bit (or the end of number). This 1-bit also can be decomposed, but it can be "shifted" by only one bit.
+
+Let us *dp*1[*i*] is number of ways to represent a number that consists of *i* last 1-bits of our number in the case that the first of 1-bits are NOT decomposed. Also let us *dp*2[*i*] is number of ways to represent a number that consists of *i* last 1-bits of our number in the case that the first of 1-bits are decomposed.
+
+You can easily recaclulate this dp following way
+
+*dp*1[0] = 1, *dp*2[0] = 0
+*dp*1[*i*] = *dp*1[*i* - 1] + *dp*2[*i* - 1]
+*dp*2[*i*] = *dp*1[*i* - 1] * [(*s*[*i*] - *s*[*i* - 1] - 1) / 2] + *dp*2[*i* - 1] * [(*s*[*i*] - *s*[*i* - 1]) / 2]
+where [*x*] is rounding down.
+
+Answer will be *dp*1[*k*] + *dp*2[*k*], where *k* is total number of 1-bits in the canonical representation. So, we have  solution for one test.
+
+**div1 E.** Consider all partitions of 7 × 8 board into dominoes. There is only 12988816 of them (you can get this number using some simple bruteforce algorithm)
+
+Also, consider all "paintings" of 7 × 8 board (i.e. number of cells of every color) and find number of patritions into set of pills of 10 types for every of them. In the worst case you will get 43044 partitions (this number you can get using another bruteforce algo).
+
+In the first part of solution you should iterate over all partitions of board into dominoes and find all sets of pills that you will get. You will have no more than 43044 of them.
+
+In the second part of solution you should try to distribute all available pills for every of sets that you recieved in the first part. You should distribute them in such way that maximal number of colors match.
+
+You should build a graph that composed from 4 parts - source, the first part of 10 nodes, the second part of 10 nodes and sink. There are edges between all pairs of nodes from neighbour parts. From source to the first part you should set capacities of edges equal to numbers of available pills of every type. From the second part to sink you should set capacities of edges equal to numbers of pills in the current partition. From the first part to the second part you should use infty capacities and set costs equal to number of MISmatched colors in the types of pills (it is some numbers in range from 0 to 2). At the end, you should find maximal flow of minimal cost (MCMF) if this graph and save a flow that gets minimal cost.
+
+In the third part of solution you should restore answer from optimal flow.
+
+In the second part of solution you can replace MCMF by usual maxflow. You can see that at the beginning MCMF will fill edges of cost 0. So, you can fill them by hand. After that you can drop all edges of cost 0 and 2 and just find maxflow.
+
+Complexity of solution is difficult, but it is clear that this solution fits into limits. The first jury solution in C++ that was written carelessly works in 1 sec. Some more clever solutions works in 0.4 sec, but you can write something more faster.
diff --git a/editorials/127.md b/editorials/127.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/3140
+
+**div2 A.** In this problem you should find length of polyline, multiply it by *k* / 50 and output that you will recieve. Length of polyline is sum of lengths of its segments. You can calculate length of every segment using Pythagorean theorem: 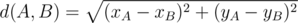.
+
+**div2 B.** Idea of this problem was offered by [RAD](/profile/RAD "Candidate Master RAD"). It was the last problem in the problemset and I had no any easy idea:) I thank him for it.
+
+Here you should calculate an array *cnt*[100]. *i*-th element of it stores number of sticks whose lengths equal *i*. Now you should calculate number of pairs of sticks of equal lengths. This number is 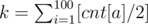, where [*x*] is floor of *x*. For every frame you need 2 if such pairs and you can choose it in any order. Therefore the answer will be *z* = [*k* / 2].
+
+**div2 С. div1 A.** At the first you should consider cases when *t*0 = *t*1, *t*0 = *t*2 and *t*1 = *t*2. Answers will be (*x*1, 0), (0, *x*2) and (*x*1, *x*2). The last 2 of them didn't present in the pretests.
+
+Next, for all 1 ≤ *y*1 ≤ *x*1 you should find minimal *y*2, for that *t*(*y*1, *y*2) ≥ *t*0. You can do it using one of three ways: binary search, two pointers or just calculation by formula [*y*1(*t*0 - *t*1) / (*t*2 - *t*0)], where [*x*] is rounding up of *x*. You should iterate over all cases and choose one optimal of them.
+
+The last tricky case consists in the fact that for all 1 ≤ *y*1 ≤ *x*1 и 1 ≤ *y*2 ≤ *x*2 *t*(*y*1, *y*2) < *t*0. For example, you can see following test
+
+100 110 2 2 109 (it is the 6th pretest).
+
+In this case you should output (0, *x*2).
+
+All calculations should be done in 64-bit integers (8th pretest checks overflow of 32-bit integers) or very carefully in the real numbers.
+
+**div2 D. div1 B.**
+
+Let us calculate a prefix-function for all prefices of string. Prefix-function *p*[*i*] is maximal length of prefix that also is suffix of substring [1...*i*]. More about prefix function you can see in a description of Knuth-Morris-Pratt algorithm (KMP).
+
+The first of possible answers is prefix of length *p*[*n*]. If *p*[*n*] = 0, there is no solution. For checking the first possible answer you should iterate over *p*[*i*]. If at least one of them equal to *p*[*n*] (but not *n*-th, of course) - you found the answer. The second possible answer is prefix of length *p*[*p*[*n*]]. If *p*[*p*[*n*]] = 0, you also have no solution. Otherwise you can be sure that the answer already found. This substring is a prefix and a suffix of our string. Also it is suffix of prefix with length *p*[*n*] that places inside of all string. This solution works in *O*(*n*).
+
+Also this problem can be solved using hashing. You can find hash of every substring in O(1) and compare substrings by comparing thier hashes. Well, let's check for every prefix that it is a suffix of our string and store thier lengths into some array in the increasing order. Then, using binary search over the array, you can find maximal length of prefix that lie inside of string. Check of every prefix you can do in *O*(*n*). So, you have some  solution.
+
+In point of fact, the array of prefix lengths in the previous solution is list { *p*[*n*], *p*[*p*[*n*]], ... }, that written if reversed order. From the first solution you know that the answer is prefix of length either *p*[*n*], or *p*[*p*[*n*]] (if it exists, of course). Therefore some naive solution without binary search can fits in the limits if you will stupidly check all prefices in the order of decrease thier lengths:) This solution works in *O*(*n*).
+
+Also this problem can be solved using *z*-function.
+
+**div2 E. div1 C.** You can see that every command *i*, *j* you should do no more than once. Also order of commands doesn't matter. Actually, sequence of command you can represent as boolean matrix *A* with size *n* × *n*, where *a**ij* = 1 mean that you do the command *i*, *j*, and *a**ij* = 0 mean that you don't do it.
+
+Let us describe one way to construct the matrix.
+
+Let the starting image is boolean matrix *G*. A boolean matrix *B* of size *n* × *n* stores intermediate image that you will recieve during process of doing commands.
+
+For the upper half of matrix *G* without main diagonal you should move line by line from the up to the down. For every line you should move from the right to the left. You can see that for every positions all nonconsidered positions do not affect the current position. So, if you see that values for position *i*, *j* in the matrices *G* and *B* are different, you should do command *i*, *j*: set in the matrix *A* *a**ij* = 1, and change segments (*i*, *i*) - (*i*, *j*) and (*j*, *j*) - (*i*, *j*) in the matrix *B*.
+
+For the lower half of the matrix *G* without main diagonal you should do it absolutely symmetric. At the end you should iterate over main diagonal. Here it should be clear.
+
+Well, for matrix *G* you always can build matrix *A* and do it by exactly one way. It mean that this way requires minimum number of commands. So, you can get answer for problem by following way: you can build the matrix *A* from the matrix *G* and output number of ones in the matrix *A*.
+
+There is only one problem that you should solve. Algorithm that you can see above works in *O*(*n*3), that doesn't fit into time limits. Let's speed up it to *O*(*n*2). Consider in the matrix *B* the upper half without main diagonal. During doing commands all columns of cells that placed below current position will have same values. Values above current position are not matter for us. Therefore instead of the matrix *B* you can use only one array that stores values of columns. It allows you do every command in *O*(1) instead of *O*(*n*). This optimization gives a solution that works in *O*(*n*2).
+
+**div1 D.** Let us represent a number in the Fibonacci code. You can imagine Fibonacci coding by following way: *i*-th bit of number corresponds to the *i*-th Fibonacci number. For example, 16=13+3 will be written as 100100. You can represent into this code any positive integer, for that no two neighbouring 1-bit will be present. It is possible to do it by only one way (let's define this way as canonical). In the problem you should calculate a number of ways to represent some number into Fibonacci code in that two ones can be placed in the neighbour positions.
+
+You can easily get the canonical representation if you generate several of Fibonacci numbers (about 90) and after that try to substract all of them in the decreasing order.
+
+You should store positions of 1-bits of canonical representation into an array *s* in the increasing order. You can decompose any of them into two ones. It looks like that:
+
+1000000001 // starting number;
+0110000001 // there we decompose
+0101100001 // the first "one"
+0101011001 // using all
+0101010111 // possible ways
+
+After some number of such operations you will meet next 1-bit (or the end of number). This 1-bit also can be decomposed, but it can be "shifted" by only one bit.
+
+Let us *dp*1[*i*] is number of ways to represent a number that consists of *i* last 1-bits of our number in the case that the first of 1-bits are NOT decomposed. Also let us *dp*2[*i*] is number of ways to represent a number that consists of *i* last 1-bits of our number in the case that the first of 1-bits are decomposed.
+
+You can easily recaclulate this dp following way
+
+*dp*1[0] = 1, *dp*2[0] = 0
+*dp*1[*i*] = *dp*1[*i* - 1] + *dp*2[*i* - 1]
+*dp*2[*i*] = *dp*1[*i* - 1] * [(*s*[*i*] - *s*[*i* - 1] - 1) / 2] + *dp*2[*i* - 1] * [(*s*[*i*] - *s*[*i* - 1]) / 2]
+where [*x*] is rounding down.
+
+Answer will be *dp*1[*k*] + *dp*2[*k*], where *k* is total number of 1-bits in the canonical representation. So, we have  solution for one test.
+
+**div1 E.** Consider all partitions of 7 × 8 board into dominoes. There is only 12988816 of them (you can get this number using some simple bruteforce algorithm)
+
+Also, consider all "paintings" of 7 × 8 board (i.e. number of cells of every color) and find number of patritions into set of pills of 10 types for every of them. In the worst case you will get 43044 partitions (this number you can get using another bruteforce algo).
+
+In the first part of solution you should iterate over all partitions of board into dominoes and find all sets of pills that you will get. You will have no more than 43044 of them.
+
+In the second part of solution you should try to distribute all available pills for every of sets that you recieved in the first part. You should distribute them in such way that maximal number of colors match.
+
+You should build a graph that composed from 4 parts - source, the first part of 10 nodes, the second part of 10 nodes and sink. There are edges between all pairs of nodes from neighbour parts. From source to the first part you should set capacities of edges equal to numbers of available pills of every type. From the second part to sink you should set capacities of edges equal to numbers of pills in the current partition. From the first part to the second part you should use infty capacities and set costs equal to number of MISmatched colors in the types of pills (it is some numbers in range from 0 to 2). At the end, you should find maximal flow of minimal cost (MCMF) if this graph and save a flow that gets minimal cost.
+
+In the third part of solution you should restore answer from optimal flow.
+
+In the second part of solution you can replace MCMF by usual maxflow. You can see that at the beginning MCMF will fill edges of cost 0. So, you can fill them by hand. After that you can drop all edges of cost 0 and 2 and just find maxflow.
+
+Complexity of solution is difficult, but it is clear that this solution fits into limits. The first jury solution in C++ that was written carelessly works in 1 sec. Some more clever solutions works in 0.4 sec, but you can write something more faster.
diff --git a/editorials/128.md b/editorials/128.md
@@ -0,0 +1,37 @@
+Source: https://codeforces.com/blog/entry/3219
+
+### [DivII A. Печеньки](https://codeforces.com/problemset/problem/129/A)
+
+Самый лёгкий способ решить задачу — сперва посчитать всю сумму чисел, и затем посчитать количество чётных разностей между этой суммой и каждым числом. Однако маленькое наблюдение позволит написать решение немного эффективней: помимо суммы (*sum*) посчитаем также, сколько среди данных чисел есть чётных (*even*) и нечётных (*odd*). Тогда, если сумма нечётна, то ответ — *odd*, иначе — *even*. Время *O*(*n*), память *O*(1).
+
+### [DivII B. Шнурки и шестиклассники](https://codeforces.com/problemset/problem/129/B)
+
+Маленькие ограничения позволяют нам написать решение «в лоб». Будем хранить данный граф в матрице смежности, и симулировать происходящее. Также будем хранить степень каждой вершины отдельно, чтобы быстро находить детей, которые связаны только одним шнурком. Тогда при каждой итерации удаляем все вершины со степенью 1 и все грани, которые соединяются с этими вершинами; продолжаем до тех пор, пока не останется таких вершин. Ответом будет количество произведённых итераций. Время *O*(*n*3), память *O*(*n*2).
+
+### [DivII C / DivI A. Статуи](https://codeforces.com/problemset/problem/128/A)
+
+Произведём симуляцию падения статуй. При каждой итерации будем сдвигать все статуи на одну клетку вниз. Перед каждым ходом (итерацией) будем получать список всех полей, куда Маша может пойти (до того, как статуи передвинутся на одну клетку вниз), используя список тех полей, куда она могла придти с прошлого хода (единственное, из полей с прошлого хода можно использовать только те, в которые после конца прошлого хода не переместилась статуя). Логично, что через 8 любых ходов на доске не останется ни одной статуи. Поэтому, если список доступных Маше полей после 8-ого хода не пуст, то она может добраться до Ани, потому что дальше её ходы ничто не ограничивает. Время *O*(9· 83) = *O*(1), память *O*(82) = *O*(1).
+
+### [DivII D / DivI B. Строка](https://codeforces.com/problemset/problem/128/B)
+
+Вначале ликвидируем случай невозможности — такой строки нет, если *k* больше, чем количество подстрок, т.е. , где *n* — длина строки.
+
+Теперь заметим, что для каждой буквы мы можем быстро оценить, сколько подстрок начинаются именно с этой буквы. Действительно, если буква стоит на позиции *i* (нумеруя с 1), то количеством подстрок, начинающихся с позиции *i*, является *n* - *i* + 1. Тогда количество строк, которые начинаются с конкретной буквы, будет сумма всех таких значений для позиций, в которых стоит эта буква.
+
+Далее, используя найденную информацию, не сложно выяснить, с какой буквы будет начинаться нужная подстрока (потому что в слове при лексикографическом сравнении буквы слева важнее, чем буквы справа). Теперь заметим, что тоже самое рассуждение мы можем применить и для следующей буквы нужного слова, только теперь нужно проверить только такие буквы, которые следуют после первой буквы слова. Таким образом, мы повторяем итерации и для 3-ей, 4-ой, ... букв до тех пор, пока не найдём нужную строку. Чтобы не искать каждый раз нужные позиции, будем хранить их отдельно; при каждой итерации сдвигать их на одну позицию направо и исполнять алгоритм только для них, а после нахождения *i*-того символа убирать те позиции, буквы в которых не равны с найденным символом. Время благодаря *k* ≤ 105 не квадратичное (самому ещё не получилось доказать), память *O*(*n*).
+
+Также задачу можно было решить с помощью [хэшей](https://codeforces.com/blog/entry/3193#comment-64020) или [суффиксного массива](https://codeforces.com/blog/entry/3193#comment-64010).
+
+### [DivII E / DivI C. Игра с прямоугольниками](https://codeforces.com/problemset/problem/128/C)
+
+Рассмотрим все левые и правые границы всех *k* внутренних прямоугольников, вместе их 2*k*. Присвоим им произвольные 2*k* координат между левой и правой стороной данного прямоугольника, это можно сделать  способами. То же самое сделаем и с верхними и нижними границами, это можно сделать  способами. Заметим, что каждая пара таких размещений однозначно определяет одно искомое расположение, и все такие расположения можно определить одной парой размещений. Поэтому ответом является . Так как *n* и *m* не больше 1000, то коэффициенты можно посчитать с помощью треугольника Паскаля (не забывая вычислять по данному модулю). Время *O*(*max*(*n*, *m*)2), память *O*(*max*(*n*, *m*)2).
+
+### [DivI D. Числа](https://codeforces.com/problemset/problem/128/D)
+
+У меня эта задача ассоциировалась с атомами и молекулами. :) Представим, что каждое из чисел имеет две связи, где связь соединяется с другой по заданным правилам. Тогда решение существует тогда и только тогда, когда все связи соединены, и из каждого элемента по связям можно дойти до любого другого элемента; также решения не существует, если присутствуют числа *x*, *x* + 2, но *x* + 1 не присутствует.
+
+Пусть у нас есть числа *a*, *a* + 1, ..., *b*, тогда количество связей у них 2|*a*|, 2|*a* + 1|, ..., 2|*b*|, где |*x*| — количество чисел *x*. Ясно, что 2|*a*| связей от 2|*a* + 1| «съедают» элементы *a*. У *a* + 1 свободными остаются *p* = 2|*a* + 1| - 2|*a*| связей. Аналогично, эти *p* связей соединяются с *a* + 2 элементами и т.д. В конце концов, если у *b* - 1 свободными остаются *q* связей, то должно быть *q* = 2|*b*|, чтобы завершить цепочку. Остаётся только проверить все эти соотношения (учитывая то, что цепочку нельзя завершить раньше, чем не истрачены все связи — то есть, вычисляемый *p* не может быть 0). Время  (т.к. данные числа нужно отсортировать), память *O*(*n*). Для простоты вычислений можно ещё заметить, что 2|*a*| можно заменить на |*a*|, из-за этого ничего не изменится.
+
+### [DivI E. День рождения](https://codeforces.com/problemset/problem/128/E)
+
+См. хороший разбор [здесь](https://codeforces.com/blog/entry/3193#comment-64175).
diff --git a/editorials/129.md b/editorials/129.md
@@ -0,0 +1,58 @@
+Source: https://codeforces.com/blog/entry/3196
+
+Today's contest had some pretty interesting problems; I particularly liked [Problem C](//codeforces.com/contest/128/problem/C) and [Problem D](//codeforces.com/contest/128/problem/D). I'm going to describe my solution to D which I think is quite nice (and results in simple code). I don't doubt that there are even easier solutions to the problem, so please enlighten me if you have one :).
+
+
+
+### Impossibility
+
+Let us denote the sequence by *a*1, ..., *a**n* and assume it has been sorted already. We can note immediately that there are some easy cases we can rule out. If *n* is odd, by a parity argument it is impossible. Moreover, let *m* = *a**n* - *a*1, i.e. the range of the values. If *m* = 0 it is impossible since *n* ≥ 3, and if *m* > *n* / 2 it is impossible since we cannot get from *a*1 to *a**n* and back going around the circle. Now that these cases are out of the way we move on to the actual algorithm.
+
+### Transformation
+
+It's natural to transform the input we're given into a form that's easier to work with, i.e. a histogram. As such, we define *c**i* to be the number of values *a**j* with *a**j* - *a*1 = *i* for *i* = 0, 1, ..., *m*. Now we replace each *a**i* with *a**i* - *a*1 so that they are all in the range [0, *m*].
+
+### Observation
+
+A nice observation we can make about any valid sequence is the following. Consider the positions of any 0 and any *m* in the circle. There are two paths from 0 to *m*. We observe that if any valid sequence exists, then there exists one for which, along each of these paths, the value never decreases twice in a row (that is, we can think of each path as "increasing" with some oscillation). Suppose this does happen in our sequence, i.e. we have something like
+
+0, 1, ..., *i* - 1, *i*, *i* - 1, ..., *j* + 1, *j*, *j* + 1, ..., *m* - 1, *m*
+
+where *j* < *i* - 1 so *i*, *i* - 1, ..., *j* + 1, *j* is the decreasing sequence. Then we note that *j* + 1 appeared somewhere between 0 and *i*, so we can take the values *j*, *j* + 1 and move them directly after the *j* + 1 that was between 0 and *i* (easy to see that the sequence is still valid). Repeating this for whenever we have a decrease of two or more gives us paths that never decreases twice in a row.
+
+### Validation
+
+Now with our transformation and observation, we can come up with the method of checking whether or not the histogram can produce a valid sequence. To do so, first place a 0 on the circle. Then we have *L* = *c*0 - 1 zeros left to place. Note, however, that each zero must be adjacent to a one. So in fact there must be at least *L* + 2 ones to "hide" all of the zeros from the rest of the numbers (one on each side and one for each additional zero). If there are fewer than that many, it is impossible. After placing the remaining zeros and ones arbitrarily (but alternating) on each side of the initial 0, we see that there are *L* = *c*1 - (*L* + 2) ones remaining. By the same argument, we know how many twos there must be (again, *L* + 2). We can continue like this until we get to *m*. If there are *L* remaining values of *m* - 1, we need *c**m* = *L* + 1 to complete the circle (one to be the "end" and one for each additional *m* - 1). If this is true, then it is possible and otherwise it is not.
+
+Note that the above placement strategy works because of the observation we made (we know we can use the small numbers greedily) and the fact that it doesn't matter how many of each number we put in each path as long as they end in the same value.
+
+### Code
+
+```
+
+```
+
+```
+int a[100100], c[100100];
+
+int main() {
+ int n; cin >> n;
+ for (int i = 0; i < n; i++) cin >> a[i];
+ sort(a, a+n);
+ int m = a[n-1]-a[0];
+ if (n % 2 == 1 || m > n/2 || m == 0) { cout << "NO" << endl; return 0; }
+
+ memset(c, 0, sizeof(c));
+ for (int i = 0; i < n; i++) c[a[i]-a[0]]++;
+
+ bool poss = true;
+ int L = c[0]-1;
+ for (int i = 1; i < m; i++) {
+ if (c[i] < L+2) { poss = false; break; }
+ c[i] -= (L+2); L = c[i];
+ }
+ poss = poss && (c[m] == L+1);
+ cout << (poss ? "YES" : "NO") << endl;
+ return 0;
+}
+```
diff --git a/editorials/130.md b/editorials/130.md
@@ -0,0 +1,119 @@
+Source: https://codeforces.com/blog/entry/3226
+
+So here goes an editorial for the round. For me Befunge is one of the languages in which it's much easier to write code than to read it (and debugging code written by someone else is a complete torture; that's why we don't have hacking in ULRs). That's why I'll post just the general idea of the solution and my own codes — the latter just to show that I can code in Befunge too.
+
+### A. Hexagonal numbers
+
+```
+&:2*1-*.@
+```
+
+A "consolation" problem, which requires only to understand the principles of working with stack. Read *n*, duplicate it, multiply the topmost copy by 2 and decrement the result. Now the stack contains two numbers *n* and 2*n* - 1; multiply them and print the result.
+
+### B. Gnikool Ssalg
+
+```
+> ~ : 25*- #v_ $ >:#,_ @
+^ <
+```
+
+Here the easiest solution is to use the main stack property — elements are popped in reverse order compared to the order in which they were pushed. You can break the solution in two loops — in the first one you read input data till the end of line (#10) and keep the characters on the stack, and in the second one you print stack elements as long as it's not empty. To run a loop (as well as to do any conditional branching) one has to use commands `_` and `|`, but remember that they delete from the stack the element they use to make a choice, so if you're going to need it later, duplicate it.
+
+### C. Decimal sum
+
+```
+0 &>: #v_ $. @
+ >1- \ & + \v
+ ^ <
+```
+
+A one-loop problem which requires tracking the current contents of the stack carefully. At the start of each loop iteration the stack contains two elements: the current sum (initialized with zero) and the quantity of numbers you still have to add (initialized by reading input). If the latter is non-zero, the instruction pointer goes into the loop body (second line of the program). There we decrement the counter and swap it with the current sum. After this we read the current number and add it to the sum. Finally we swap the top two elements of the stack again — and we're ready for the next iteration.
+
+It was also possible to use a memory cell to store the loop counter, but I think it's an unnecessary over-complication.
+
+### D. Exponentiation
+
+```
+&30p & &32p 1 \ >:#v_ $. 25*, @
+ >1- \ 30g * 32g % \v
+ ^ <
+```
+
+The task becomes more complicated: this time on each iteration you have to juggle more than two numbers, so the stack alone is not enough — unlike some other stack-based languages, Befunge has no commands which allow access to stack elements buried deeper than top two positions. We'll have to use "memory" — program cells not occupied by useful commands. Commands `p` and `g` are meant for writing self-modifying code, but Befunge has no regular random-access memory, so one has to use whatever it has.
+
+Usage of memory simplifies things: write *a* and *c* into memory, keep *b* on the stack as loop counter, and keep the current value of the power on the stack as well. In the loop body the required values are extracted from memory as needed, so that the stack doesn't get littered.
+
+### E. Tribonacci numbers
+
+```
+031p032p133p & > 31g 32g + 33g + 39*1-% 32g 31p 33g 32p 33p v
+ | :-1 <
+ > 31g . 25*,@
+```
+
+The same principle as in the previous problem, but a bit more memory manipulation; handle with care.
+
+### F. Prime factorization
+
+```
+& 211p > : 1 - #v_ 25*, @ > 11g:. / v
+ > : 11g %!|
+ > 11g 1+ 11p v
+ ^ <
+```
+
+Forget whatever code you write lightning-fast on any regular contest :-) and recall how you solved this a long time ago. The number itself is small enough, so you can check divisors up to *n* instead of *sqrt*(*n*). If you divide the number by the divisor you find, you're fine with not skipping composite divisors — they won't divide the number anyways. Finally, if a divisor is found, you don't have to find its degree immediately — it's enough not to increment it during this iteration, and you'll find it again on the next one. Keep *n* on the stack, store the current divisor in memory and perform actions in each branch carefully, and the problem will be solved.
+
+### G. CAPS LOCK ON
+
+```
+> ~ : 25*- #v_ 25* , @ >48*-v
+ > :: "`"` \"{"\` * | > , v
+ > ^
+^ <
+```
+
+This problem is very similar to CamelCase example from the given article about Befunge. It was even easier — you needn't care about the type of the previous character. The most complicated thing about it might be learning "greater than" operation and applying it to correct values.
+
+### H. Balanced brackets
+
+```
+v > "ON" ,, v
+> ~ : 25*- #v_ $ | > 25*, @
+ > "SEY" ,,, ^
+ > : 58*- #v_ v
+ > \ : 58*- #v_v
+ \ $
+^ < <$<
+```
+
+Originally I intended to give strings which had three types of brackets in them, but by the time I've implemented the check for only one type, I realized that it was a pretty bad idea. Even with one type of brackets you have enough trouble implementing the check. There are two possible ways to solve the problem: store the opening brackets themselves on the stack (with several types of brackets it would be the only option) or store only the quantity of opening brackets which are not closed yet. The answer is "NO" in two cases: if the current bracket is closing and you have no opening brackets on the stack, or if the input data is over and you still have opening brackets left.
+
+### I. Array sorting
+
+```
+v
+> 543** > :#v_ $&> :#v_ 1 > :0g > :#v_ $ 1+: 543** `! #v_ 25*,@
+ ^-1p0\0:< ^-1 p0\+1 g0:&< ^-1\.:\<
+ ^ <
+```
+
+Once again, forget about nice things like Arrays.sort() and recall counting sort. Befunge program is sized 25 x 80, the given numbers can vary between 1 and 60, so we can store the quantity of number i in a cell (0, i), if this part of the program (the first line) has no commands we'll need. The program will have three main loops — initializing memory with zeros, reading input and incrementing values in corresponding memory cells, and convering the resulting values into a sorted array.
+
+### J. Date calculation
+
+```
+56*1+ :10p :30p :50p :70p :80p :52*0p :62*0p 1- :2-20p :40p :60p :90p 92+0p v
+v % *:*45 : & <
+ > > 20g 1+ 20p v
+> ! | > v
+ > : 52*:* % ! |
+ > : 4 % !|
+v << <
+ > . 00g . 25*, @
+> $100p & > : 00g 0g ` ! |
+ > 00g 0g - 00g 1+ 00p v
+ ^ <
+```
+
+This is another problem which is very easy in any high-level language and very ugly in Befunge. First of all we initialize some memory cells with quantities of days in months of a regular non-leap year. Next we read the year index, check whether it's leap and if needed change the number of days in February. Finally, we read the day index and in a loop decrement it by the number of days in the current month while incrementing the index of the current month as many times as possible. Just think how easy this problem would have been if our calendar was organized in a more regular way!
diff --git a/editorials/131.md b/editorials/131.md
@@ -0,0 +1,70 @@
+Source: https://codeforces.com/blog/entry/3256
+
+Hi, these are just some ideas of what I did to solve the problems in #95 (div 2). They're just what I did, better solutions may exist and will be very welcome!
+Also, sorry if I wrote something wrong, English isn't my first language.
+Also, (a b) is a choose b (a!/(b!(a-b)!)).
+ **Problem A**
+
+Just do what the statement asks you to. Check if all letters are uppercase, except for the first one, that you don't need to check. If so, change the case of the entire string. If not, do nothing. Please notice that an one-letter string must have its case changed.
+
+It can be easly done in O(n), where n is the lenght of the string.
+
+**Problem B**
+
+First, let *count(i)* be the numbers of occurrences of the number *i* in the input,
+ for *-10 <= i <= 10*. Remember that there may be negative numbers in the input, so one can use an offset to store these values (use an 21-sized array *C* and store *count(i)* in *C[i+10]*). Except for 0, possible matching are pairs *(i,-i)*, for *1 <= i <= 10*. It's easy to see that there will be exactly *count(i)*count(-i)* valid matching for each i, so just sum them all.
+
+Since 0 "is opposite to itself", but "a client can't form a couple with
+him/herself", the number of valid pairs *(0,0)* will be *(count(0) 2)*. Just sum
+this value to the previous computed sum and print.
+Use 64 bits-types to do the math.
+
+**Problem C**
+
+Since the constraints are small, let's just iterate through all possible numbers *b* of boys in the group and count how many ways we can form the group with *b* boys.
+
+First, consider only the values where *b >= 4*. Given *b*, it's clear that the number of girls in the group must be *g = t - b*. If *g < 1*, don't consider this case. Given the values of *b* and *g*, there are *(n b)*(m g)* ways to form the group, since we can combine the boys independently the girls. Just sum *(n b)*(m g)* for each pair *(b,g)*. Again, use 64 bits-types to do the math.
+
+One could precompute all the values of *(i j)* using the Pascal triangle, but one could also compute it with the traditional formula, if its implementation takes care of possible overflow (30! doesn't fit in 64-bit integer type).
+
+**Problem D**
+
+A graph-related problem. The statement makes you sure that the given graph is connected and contains one (and exactly one) cycle. What you have to do is to compute the distance, in number of edges, from all vertexes to the cycle (print 0 for the vertex that are in the cycle. We will call these vertexes 'in-cycle').
+
+First, let's find the cycle and find the vertexes whose answer is 0. The cycle can be found with a regular Depth-First-Search (DFS), storing the fathers of the vertexes. Notice that, during the search, there will be exactly one back edge, say *(vi, vj)*. When this edge is found, iterate from *vi* to *vj* (using the father array) and label the vertexes as 'in-cycle'.
+
+After that, let's compute the answers for the other vertexes. One could "compact" the graph by merging all the 'in-cycle' vertexes into a single vertex. Then, just do another search starting by this vertex and compute the distances, knowing that the distance of a vertex *vi* is the distance of *father[vi]* plus one.
+
+Also, it's also possible to do as many searchs as the number of 'in-cycle' vertexes if you don't consider others 'in-cycle' vertexes during the search. The running time would still be *O(n + m)*, that, in this problem, is *O(n + n)* = *O(n)*.
+**Problem E**
+
+Let's first consider that the queens can only attack the other pieces standing in the same line - the case with the columns and both diagonals will be analogous.
+
+Let *line[i]* be an array that will store all the queens that are in the *i-th* line on the chessboard. Since it's indexed by the line number, it's only necessary to store the column number of the pieces. So, for example, if we have queens at positions *(4,6), (4,8)* and *(6,5)*, we will have *line[4] = {6,8}* and *line[6] = {5}*.
+
+To check if the queen at position *(i,j)* is attacking someone in its line, you must check if there is some number greater than *j* and/or less than *j* in *line[i]*. To do that, presort *line[i]* and binary search *j* in it. Notice that *j* will always be successful found by the search. Notice also that there will be some number greater than *j* iff the found element is not the last one of *line[i]*. The same applies for the other case: check if *j* is not the first element of *line[i]*. If *j* is not the first nor the last element, the queen is attacking 2 pieces in its line. If *j* is the only element, the queen is attacking no one, and it's attacking 1 piece otherwise.
+
+Do the same thing (compute all *column[i]*, sort them and, for each queen, binary search) to the column, to the "/" diagonal, and to the "\" diagonal. Remember that a piece at position *(i,j)* is at the diagonals *i+j* and *i-j*. Like in problem B, use an offset to handle the negative numbers in the last case. Store the line number in the *column[i]* array. There's no different in witch index (line or column) to use in the diagonals arrays (but, of course, use the same chosen index for everyone).
+
+It seems that the sorting part of the algorithm will run in *O(n*n*logn)* time, since we have *O(n)* lines, columns and diagonals. However, the sum of the sizes of all these arrays will be *m*, the numbers of queens. So the running time will be actually near *O(m*logm)*. Binary searching for every queen will take less than *O(m*logm)*, too.
+
+UPD: [nab](../../../profile/nab "Expert nab") said in the comments that an easier solution can be correctly done in O(m) time. Thank you!
+
+**Problem F**
+
+The main idea is to, for each pair of lines *i1* and *i2*, count the ways you can form the rectangle using a sweep line-like algorithm. The idea is similar to the somewhat classic idea used for the problem that is, given an array of numbers, count how many contiguous sub arrays exists witch sum is equal or greater to some given *k*.
+
+Let's first of all identify all the points where a star can be found, in its "starting" position and "finish" position. These are the S and F position shown below.
+
+ 1
+S1F
+ 1
+
+For each pair of lines *i1* and *i2 (i2 > i1)* we will keep two indices (or pointers) *j1* and *j2* for the columns, with *j2 > j1*. During the algorithm, we will always analyze the rectangle formed by lines *i1,i2* and columns *j1,j2*. Let's start with *j1 = 0* and *j2 = 2* (there won't be any star in the rectangle*i1,i2,0,(0 or 1)* simply because a star won't fit in it). Let's then count the number of stars found in this rectangle. It will be equal to *countfinish(i1+1,i2-1,j2)*, where *countfinish(I1,I2,J)* is the number of "finish"
+positions in the column *J* between the lines *I1* and *I2*. If this number is equal or greater than *k*, this rectangle and all the rectangles *(i1,i2,j1,j)* for *j >= j2* will be valid, so you need to sum *m-j2* to the answer. Then, increment *j1* and recalculate the numbers of stars in the rectangle. It will be equal to the previous number minus *countstart(i1+1,i2-1,j1-1)*, (the definition of *countstart()* is analogous) since it's the number of starts that are "lost" when we move from *j1-1* to *j1*. Check again if the new number is greater or equal than *k* and repeat the process until the number is less than *k*. Notice that *j1* will always be less than *j2*, since a star needs 3 columns to exists.
+
+Then, increment *j2* and, without changing the value of *j1*, repeat the process. Notice that this part of the algorithm will take *O(m)*T* time (where *T* is the time needed to calculate *countstart* and *countfinish*), since both *j2* and *j1* will "walk" in the columns only one time.
+
+A trick can be made to make *T = O(1)*. For each column *j*, precompute an array *countstart[j]*, where *countstart[j][i] = countstart[j][i-1] + (1* if *(i,j)* is a "starting" position, *0* otherwise). To compute *countstart(I1,I2,J)*, just use the formula *countstart[J][I2] - countstart[J][I1-1]*, that gives the value in constant time. Do the same with *countfinish*.
+
+Precomputing countstart and countfinish takes, for each column, *O(n)* time, so all the precomputing can be done in *O(n*m)* time. Since we use an *O(m)*O(1) = O(m)* time for *O(n2)* pairs of lines, the total time used for the algorithm is *O(n*m) + O(n2*m) = O(n2*m)*. A bit high for *n=m=500*, but the time limit for this problem was higher than the usual too (5 seconds instead of 2).
diff --git a/editorials/132.md b/editorials/132.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/3302
+
+### [A. HQ9+](https://codeforces.com/contest/133/problem/A)
+
+The problem described [HQ9+](http://progopedia.com/language/hq9-plus/) programming language and asked whether the given program will print anything. Given the extraordinary simplicity of the language, it was enough to check whether the program contains at least one of the characters H, Q and 9.
+
+### [B. Unary](https://codeforces.com/contest/133/problem/B)
+
+A lovely language [Brainfuck](http://progopedia.com/language/brainfuck/) has dialects for literally every occasion; I guess one could write a whole round about it (not Unknown Language Round, of course, it's too well-known for it), but this time I used it in one problem only.
+
+The solution is quite simple: all you have to do is to follow the described procedure of transforming code from Brainfuck to Unary. If your language has built-in long arithmetics, the solution is straightforward: replace characters of each type with corresponding binary codes, convert the resulting string into a long integer and take it modulo 1000003.
+
+Having no long arithmetics is not a big deal either. The program can be created step by step, adding one character at a time from left to right. On each step the length of the program is multiplied by 16 (the binary code added has length of 4 bits), then the code of the current character is added and the result is taken modulo 1000003, so that the result never gets really large.
+
+### [C. Turing Tape](https://codeforces.com/contest/133/problem/C)
+
+This was another implementation problem, inspired by another great language [INTERCAL](http://progopedia.com/language/intercal/). Technically it was a bit more complicated than the previous one, due to the usage of byte reversal and having to implement not the described procedure but its inverse. For i-th character of input data reverse it and store in *rev*[*i*]; then i-th number of the output can be calculated as (*rev*[*i* - 1] - *rev*[*i*] + 256)%256 (for *i* = 0 *rev*[*i* - 1] = 0).
+
+### [D. Piet](https://codeforces.com/contest/133/problem/D)
+
+As you've already noticed, [Piet](http://progopedia.com/language/piet/) differs from most other esoteric programming languages in the way it interprets the image — the problem offered a very simplified version of it, and still it was quite cruel.
+
+The first step of the solution is finding colored blocks. Given that they are rectangular, this can be done without BFS; once you've found a colored pixel which is not part of any block you've seen before, you just find the maximal contiguous sequence of pixels of the same color in the same line that starts with this pixel, and assume that it's horizontal dimension of its block.
+
+```
+............
+..X----->...
+..|XXXXXX...
+..vXXXXXX...
+............
+```
+
+I found it convenient to index the blocks and store their colors and dimensions at this point, so that this doesn't need to be re-done later. After this I calculated "state transition function" — a function which for each state of instruction pointer defined the next state. The IP has at most 50x50x4x2 states, and they can be indexed with 8*(index of current block) + 2*(direction pointer) + (block chooser). Thus, the transition function can be described with a one-dimensional array (index is current state of IP, and value is the next one), and the simulation of interpretation steps becomes just updating the current state of IP, which is easier than repeating the full procedure described in the statement on each step.
+
+It was also possible to note that at some point there will be a loop in the states of the IP, since the maximal possible number of distinct states is less than the number of steps to be done. But exploiting this wasn't necessary.
+
+### [E. Logo Turtle](https://codeforces.com/contest/133/problem/E)
+
+This was the only problem of the round which featured a non-esoteric language. The solution is dynamic programming, and it could be used in several ways. My solution was to store two three-dimensional arrays: the leftmost and the rightmost position of a turtle after it used I commands from the list, made J changes in these commands and is now facing direction K. The initial condition is that left=right=0 when I = J = 0 and the turtle faces right (the initial direction can be chosen arbitrarily). The rule of moving between states is: if currently executed command is T (either it is the current command of the list and no change is done, or it is a result of a change), the coordinate stays the same and the direction changes; otherwise the direction stays the same and the coordinate changes accordingly to the direction.
+
+It's convenient to do at most one change for each command; in this case after all the arrays are calculated, one has to take the maximal absolute value among all distances which use all commands from the list, all facing directions of the turtle and all quantities of changes which have the same parity as the required quantity (any command can be changed an even number of times without affecting the result).
+
+### [Div1 D. Constants in the language of Shakespeare](https://codeforces.com/contest/132/problem/D)
+
+Two last problems of the round were inspired by [Shakespeare](http://progopedia.com/language/shakespeare/) programming language. The original idea was to make them one problem — "How to print the given sequence using as few adjectives as possible?". But later we came to our senses and split this monster of a problem in two.
+
+The evident greedy solution (break the binary notation into contiguous groups of 1s, if the size of the group is 1, write it as a single power, otherwise write it as a difference of two powers) is wrong. You can see this from test 4 "10110111": the greedy solution will return 5 ( + 27 + 26 - 24 + 23 - 20), while it's possible to find a notation of size 4 ( + 28 - 26 - 24 - 21).
+
+The correct solution is based on the following idea. Let us have a fragment of binary notation which contains bits for powers of 3 between N and M (N < M), inclusive, which has K 0s and L 1s. It can be written as a sum of powers which correspond to positions of 1s, using L powers. Alternatively, it can be written as 2*M* + 1 - 2*N* - ..., where ... are powers which correspond to positions of 0s, using 2 + K powers. It's evident that using second method makes sense only if the fragment starts and ends with 1s (otherwise it can be used for shorter fragment without the leading/trailing 0s, and save at least one power on this) and contains no 00 sequence inside (otherwise you can break the fragment into two in place of these 00 and write these fragments separately with the same or better result).
+
+After you've noted this, you can solve the problem using DP: for each position in binary notation store the sign "write it as sum of powers or as difference of powers", and in second case store the length of the fragment which is written using difference (storing the length of the fragment which is written using sums only is unnecessary, since this can be done for individual bits with the same result as for longer fragments.
diff --git a/editorials/133.md b/editorials/133.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/3302
+
+### [A. HQ9+](https://codeforces.com/contest/133/problem/A)
+
+The problem described [HQ9+](http://progopedia.com/language/hq9-plus/) programming language and asked whether the given program will print anything. Given the extraordinary simplicity of the language, it was enough to check whether the program contains at least one of the characters H, Q and 9.
+
+### [B. Unary](https://codeforces.com/contest/133/problem/B)
+
+A lovely language [Brainfuck](http://progopedia.com/language/brainfuck/) has dialects for literally every occasion; I guess one could write a whole round about it (not Unknown Language Round, of course, it's too well-known for it), but this time I used it in one problem only.
+
+The solution is quite simple: all you have to do is to follow the described procedure of transforming code from Brainfuck to Unary. If your language has built-in long arithmetics, the solution is straightforward: replace characters of each type with corresponding binary codes, convert the resulting string into a long integer and take it modulo 1000003.
+
+Having no long arithmetics is not a big deal either. The program can be created step by step, adding one character at a time from left to right. On each step the length of the program is multiplied by 16 (the binary code added has length of 4 bits), then the code of the current character is added and the result is taken modulo 1000003, so that the result never gets really large.
+
+### [C. Turing Tape](https://codeforces.com/contest/133/problem/C)
+
+This was another implementation problem, inspired by another great language [INTERCAL](http://progopedia.com/language/intercal/). Technically it was a bit more complicated than the previous one, due to the usage of byte reversal and having to implement not the described procedure but its inverse. For i-th character of input data reverse it and store in *rev*[*i*]; then i-th number of the output can be calculated as (*rev*[*i* - 1] - *rev*[*i*] + 256)%256 (for *i* = 0 *rev*[*i* - 1] = 0).
+
+### [D. Piet](https://codeforces.com/contest/133/problem/D)
+
+As you've already noticed, [Piet](http://progopedia.com/language/piet/) differs from most other esoteric programming languages in the way it interprets the image — the problem offered a very simplified version of it, and still it was quite cruel.
+
+The first step of the solution is finding colored blocks. Given that they are rectangular, this can be done without BFS; once you've found a colored pixel which is not part of any block you've seen before, you just find the maximal contiguous sequence of pixels of the same color in the same line that starts with this pixel, and assume that it's horizontal dimension of its block.
+
+```
+............
+..X----->...
+..|XXXXXX...
+..vXXXXXX...
+............
+```
+
+I found it convenient to index the blocks and store their colors and dimensions at this point, so that this doesn't need to be re-done later. After this I calculated "state transition function" — a function which for each state of instruction pointer defined the next state. The IP has at most 50x50x4x2 states, and they can be indexed with 8*(index of current block) + 2*(direction pointer) + (block chooser). Thus, the transition function can be described with a one-dimensional array (index is current state of IP, and value is the next one), and the simulation of interpretation steps becomes just updating the current state of IP, which is easier than repeating the full procedure described in the statement on each step.
+
+It was also possible to note that at some point there will be a loop in the states of the IP, since the maximal possible number of distinct states is less than the number of steps to be done. But exploiting this wasn't necessary.
+
+### [E. Logo Turtle](https://codeforces.com/contest/133/problem/E)
+
+This was the only problem of the round which featured a non-esoteric language. The solution is dynamic programming, and it could be used in several ways. My solution was to store two three-dimensional arrays: the leftmost and the rightmost position of a turtle after it used I commands from the list, made J changes in these commands and is now facing direction K. The initial condition is that left=right=0 when I = J = 0 and the turtle faces right (the initial direction can be chosen arbitrarily). The rule of moving between states is: if currently executed command is T (either it is the current command of the list and no change is done, or it is a result of a change), the coordinate stays the same and the direction changes; otherwise the direction stays the same and the coordinate changes accordingly to the direction.
+
+It's convenient to do at most one change for each command; in this case after all the arrays are calculated, one has to take the maximal absolute value among all distances which use all commands from the list, all facing directions of the turtle and all quantities of changes which have the same parity as the required quantity (any command can be changed an even number of times without affecting the result).
+
+### [Div1 D. Constants in the language of Shakespeare](https://codeforces.com/contest/132/problem/D)
+
+Two last problems of the round were inspired by [Shakespeare](http://progopedia.com/language/shakespeare/) programming language. The original idea was to make them one problem — "How to print the given sequence using as few adjectives as possible?". But later we came to our senses and split this monster of a problem in two.
+
+The evident greedy solution (break the binary notation into contiguous groups of 1s, if the size of the group is 1, write it as a single power, otherwise write it as a difference of two powers) is wrong. You can see this from test 4 "10110111": the greedy solution will return 5 ( + 27 + 26 - 24 + 23 - 20), while it's possible to find a notation of size 4 ( + 28 - 26 - 24 - 21).
+
+The correct solution is based on the following idea. Let us have a fragment of binary notation which contains bits for powers of 3 between N and M (N < M), inclusive, which has K 0s and L 1s. It can be written as a sum of powers which correspond to positions of 1s, using L powers. Alternatively, it can be written as 2*M* + 1 - 2*N* - ..., where ... are powers which correspond to positions of 0s, using 2 + K powers. It's evident that using second method makes sense only if the fragment starts and ends with 1s (otherwise it can be used for shorter fragment without the leading/trailing 0s, and save at least one power on this) and contains no 00 sequence inside (otherwise you can break the fragment into two in place of these 00 and write these fragments separately with the same or better result).
+
+After you've noted this, you can solve the problem using DP: for each position in binary notation store the sign "write it as sum of powers or as difference of powers", and in second case store the length of the fragment which is written using difference (storing the length of the fragment which is written using sums only is unnecessary, since this can be done for individual bits with the same result as for longer fragments.
diff --git a/editorials/135.md b/editorials/135.md
@@ -0,0 +1,99 @@
+Source: https://codeforces.com/blog/entry/3353
+
+Here is the editorial of Codeforces Beta Round #97. If you have any questions or suggestions --- feel free to post them in the comments.
+
+### [136A - Presents](/contest/136/problem/A "Codeforces Beta Round 97 (Div. 2)") (A Div 2)
+
+In this problem one had to read a permutation and output the inverse permutation to it. It can be found with the following algorithm. When reading the *i*-th number, which is equal to *a* one can store *i* into the *a*-th element of the resulting array. The only thing left is to output this array.
+
+The complexity is *O*(*N*).
+
+### [136B - Ternary Logic](/contest/136/problem/B "Codeforces Beta Round 97 (Div. 2)") (B Div 2)
+
+It is easy to see that the answer is always unique. Let's consider an operation which is opposite to *tor*. From each ternary digit of *c* we will subtract a corresponding digit of *a* and take a result modulo 3. We'll obtain a number *b* which has the following property: *a tor b = c*.
+
+The complexity is *O*(*logC* + *logA*).
+
+### [136C - Replacement](/contest/136/problem/C "Codeforces Beta Round 97 (Div. 2)") (C Div 2)
+
+### [135A - Replacement](/contest/135/problem/A "Codeforces Beta Round 97 (Div. 1)") (A Div 1)
+
+If the largest number in our array is equal to 1 then let's replace it with 2, otherwise let's replace it with 1. After that let's sort the array and output it. It is easy to see that the array obtained in that way is the one we are looking for.
+
+The complexity is *O*(*NlogN*).
+
+### [136D - Rectangle and Square](/contest/136/problem/D "Codeforces Beta Round 97 (Div. 2)") (D Div 2)
+
+### [135B - Rectangle and Square](/contest/135/problem/B "Codeforces Beta Round 97 (Div. 1)") (B Div 1)
+
+Let's iterate over all partitions of our set of 8 points into two sets of 4 points. We want to check whether the first set forms a square and the second set forms a rectangle.
+
+To check if 4 points lay at the vertexes of a rectangle one can iterate over all permutations of the last 3 points. Then one need to ensure that every two consecutive sides intersect at a 90 degrees angle. That can be done using the fact that the scalar product of two vectors is equal to 0 iff they intersect at a 90 degrees angle.
+
+To check if 4 points lay at the vertexes of a square one can check whether they lay at the vertexes of a rectangle and ensure that two consecutive sides have equal length.
+
+### [136E - Zero-One](/contest/136/problem/E "Codeforces Beta Round 97 (Div. 2)") (E Div 2)
+
+### [135C - Zero-One](/contest/135/problem/C "Codeforces Beta Round 97 (Div. 1)") (C Div 1)
+
+First, let's solve the problem when there are no spoiled cards. Let *a* be the number of ones and *b* be the number of zeroes. It is easy to see that if *a < b* then the outcome is 00, because the first player can always remove ones until they are over, which will happen before the end of the game regardless of the second player's moves. Similarly, if *a > b + 1* then the outcome is 11.
+
+If *a = b* or *a = b + 1* then the outcome is either 01 or 10. That's because the first player will always remove ones, because otherwise the outcome will be 00 which is worse than any other outcome for him. Similarly, the second player will always remove zeroes. One may notice that the first player can always remove the first card to the left with 1 written on it, because it won't make the outcome worse for him. Similarly, the second player can always remove the first card to the left with 0 written on it. That means that the last card won't be removed by anyone. Thus is the last card is 1 then the outcome is 01, otherwise it is 10.
+
+We've learned how to solve the problem is there are no '?' signs. Now, suppose that the number of ones is *a*, the number of zeroes is *b* and the number of question signs is *c*. To check if the outcome 00 is possible, one can simply replace all question signs with zeroes and use the previous result, i.e. check if *a < b + c*. Similarly, the outcome 11 is possible is *a + c > b + 1*.
+
+Let's show how to check if the outcome 01 is possible. If the last character of the string is 0, then the string is not possible. If the last character is ? then we can replace it with 1, i.e. decrease *c* by 1 and increase *a* by 1. Suppose we want to replace *x* question signs with one and *c - x* question signs with zero. Then the following equality must hold: *x + a = b + c - x + (a + b + c) mod 2*. Thus, *x = (b + c - a + (a + b + c) mod 2) / 2*. If the resulting value of x is non-negative and is not greater than c, then the outcome 01 is possible, otherwise it is not possible.
+
+We can check if the outcome 10 is possible in the similar way.
+
+The complexity is *O*(*N*).
+
+### [135D - Cycle](/contest/135/problem/D "Codeforces Beta Round 97 (Div. 1)") (D Div 1)
+
+One can notice that the only possible variant of a cool cycle which doesn't have zeroes inside it is a 2x2 square of ones. This case should be checked separately. From this point we'll assume that the cool cycle we are looking for contains at least one '0' inside it.
+
+Let's take any zero from the table. If it is adjacent to another zero by a side or a corner then it can't lay inside a cool cycle which doesn't have any other zeroes inside it. Thus, this zero can lay inside a cool cycle only together with all zeroes adjacent to it. Generalizing this fact one can show that the zero can lay inside a cool cycle only together with all zeroes reachable from it. We'll assume that one zero is reachable from another zero if they can be connected with a path which consists only of zeroes and in which every two consecutive cells share either a side or a corner.
+
+Let's find all the connected components of zeroes. Two zeroes are connected if they share either a side or a corner. If the component of zeroes has a cell adjacent to a border of the table, then it can't lay inside any cool cycle and thus it should be ignored. After that for each connected component of zeroes let's find all cells with 1, adjacent to it. By the statement all those cells should be connected. Also, each cell from this set should share a common side with exactly two other cells from the set. Note that if the set of cells with '1' satisfy those restrictions, then it forms a cycle which doesn't contain any other cells with '1' inside it.
+
+The above algorithm has the complexity *O*(*NM*), if implemented carefully.
+
+### [135E - Weak Subsequence](/contest/135/problem/E "Codeforces Beta Round 97 (Div. 1)") (E Div 1)
+
+Let cool substring be the substring which is also a weak subsequence.
+
+The main observation is that the longest cool substring in any string is either its prefix or its suffix. Moreover, if, for example, it is a prefix then it can be found in the following way. Let's start moving from the end of the string towards the beginning and memorize all characters met on our way. We'll stop after some character appear in the second time. The prefix with the end in the position where we stopped is the one we are looking for.
+
+Let's count the number of strings in which the longest cool substring is a suffix. First, we will iterate over the number of characters at the beginning of the string lying before the second appearance of some character. Let this number be *t*. Obviously, *t* is not greater than *k*, because all characters in the prefix of length *t* are distinct. We need to consider the following two cases:
+
+1. If *t* ≤ *w* - 1. The first *t* characters of a resulting string are distinct, then there is a character which was present among the first *t* characters. After it there are *w - 1* more characters. One should also consider that the last *t* characters are distinct, otherwise prefix of length greater than *w* will be also a weak subsequence. Thus, the corresponding summand is equal to .
+
+2. If *t* > *w* - 1. The first *t* characters of a resulting string are distinct, then there is a character which was present among the first *t* characters. The last t characters should be distinct, but at this time the suffix of *t* characters overlaps with the prefix of *t* characters. The corresponding summand is equal to 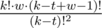.
+
+After adding up everything for all *t* from 1 to *k* we will obtain the number of strings in which the longest cool substring is a suffix of length w.
+
+Similarly, we can find the number of strings in which the longest cool substring is a prefix. The only difference is that we should make sure that the first *t + 1* characters of those strings are distinct in order to avoid a double-counting of the strings in which the first and the last t characters are distinct. Considering this the formulas are:
+
+1. If *t* + 1 ≤ *w* - 1, then the summand is equal to .
+
+2. If *t* + 1 > *w* - 1, then the summand is equal to 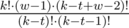.
+
+The only thing left is to add up everything for all *t* from 1 to *k - 1*.
+
+To calculate the above formula quickly one need to precompute factorials for all numbers from 1 to *k* and they inverse modulo 109+7.
+
+The complexity is either *O*(*K*) or *O*(*K*· *log*(*MOD*)), depending on the way of computing inverse values to the factorials.
+
+As a bonus for those who made it to the end of the editorial, I'll describe a simple linear time algorithm of finding inverse values for all integers between 1 and *N* modulo prime number *P (P > N).* I think it will be useful for those who didn't hear about this trick.
+
+Let's consider an obvious equality (% means a remainder of division) and perform a few simple operations with it.
+
+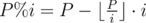
+
+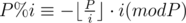
+
+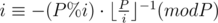
+
+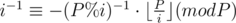
+
+Thus, in order to compute *i*- 1 we only need to know (*P*%*i*)- 1, which is less than *i*. That means we can compute inverse values successively for all integers between 1 and *N* in *O*(*N*) time.
diff --git a/editorials/137.md b/editorials/137.md
@@ -0,0 +1,31 @@
+Source: https://codeforces.com/blog/entry/3318
+
+[A. Postcards and photos](//codeforces.com/contest/137/problem/A)
+
+We will move from the left of string to the right. When we passed the whole string, or in the hands of us have 5 pieces, or current object is different from what we hold in our hands, we remove all the items in the pantry. The answer to the problem is the number of visits to the pantry.
+
+The complexity is O(n).
+
+[B. Permutation](//codeforces.com/contest/137/problem/B)
+
+We can count the number of integers from 1 to n, which occur in sequence at least once. Then the answer is n minus that number.
+
+The complexity is O(n).
+
+[C. History](//codeforces.com/contest/137/problem/C)
+
+Denote a[i], b[i] - ends of the i-th event. Let's sort pairs (a[i], b[i]) by a[i] and iterate over all pairs. Denote rg the maximal b[i] from already processed. If current b[i] < rg than we must increment answer by one. If b[i] > rg than we must assign rg by b[i].
+
+The complexity is O(n logn).
+
+[D. Palindromes](//codeforces.com/contest/137/problem/D)
+
+Let's preprocess array cnt[i][j] - the minimal number of changes tha we must do to make substring from position i to j palindrom. We can easy calc cnt[i][j] with complexity O(n^3). Now we can calculate dynamic programming z[i][j] - minimal number of changes that we can do to split prefix of length i into j palindromes. In begining we must assign z[i][j] = infinity for all (i, j) and assign z[0][0] = 0. If we want to make updates from state (i, j) we must fix the length of j-th palindrom - len. We can update z[i + len][j + 1] by value z[i][j] + cnt[i][i + len - 1]. Answer to the problem is the min(z[n][i]), where n is the length of string and i from range [1, k].
+
+The complexity is O(n^3).
+
+[E. Last Chance](//codeforces.com/contest/137/problem/E)
+
+Let's replace all vowels by -1 and all consonants by +2. Obviously substring from position i to j is good if sum in the substring [i, j] is nonnegative. Denote this sum by sum[i][j]. Obviously sum[i][j] = p[j + 1] - p[i], where p[i] is the sum of first i elements. Now for all i we want to find maximal j such that j >= i and sum[i][j] >= 0. For this let's sort the array of (p[i], i) and build segment tree on this array by i. Let's iterate over all p[i] in nondescending order. Obsiously for fixed i we have that j = max(index[i]), where index[i] is the index of i-th partial sum in nondescending order and i from range [x, n], where x is the position of the first partial sum with value p[i] in sorted array. Than we must update position i by value of negative infinity and update answer by j - i.
+
+The complexity is O(n logn).
diff --git a/editorials/138.md b/editorials/138.md
@@ -0,0 +1,106 @@
+Source: https://codeforces.com/blog/entry/3462
+
+### [139A - Petr and Book](/contest/139/problem/A "Codeforces Beta Round 99 (Div. 2)")
+
+If the total number of pages doesn't exceed the number of pages for Monday, the answer is Monday. Otherwise we can substract the Monday number from total and go on to Tuesday. If Tuesday isn't enough, we subtract and continue to Wednesday, and so on. We are sure that no more than N weeks will pass, as at least one page is read every week. Complexity - O(N).
+
+
+### [139B - Wallpaper](/contest/139/problem/B "Codeforces Beta Round 99 (Div. 2)")
+
+Unluckily, the translated statement was quite tough even tougher to understand than the original statement.
+
+Say we fixed the roll type and the room. The only possible way to cut the roll is to cut it into vertical stripes with length equal to room's height (though it was said we can cut it any way we want, there were some conditions to fulfill, namely there could be no joints other than vertical). So we find the total width of stripes we can cut our roll into as the (length of the roll / height of the room) (rounded down) * (width of the roll). If the roll length is smaller than room height, we obviously can not use this type of rolls (though the statement said there must exist at least one type we can use). The number of rolls is (perimeter of the wall rooms) / (total stripes width) (rounded up).
+
+Then we just try all types for every room and sum the minimal costs. Complexity - O(MN).
+
+### [139C - Literature Lesson](/contest/139/problem/C "Codeforces Beta Round 99 (Div. 2)")
+
+### [138A - Literature Lesson](/contest/138/problem/A "Codeforces Beta Round 99 (Div. 1)")
+
+The hardest part is to check whether two lines rhyme or not.
+
+We have to check the suffixes starting in K-th vowels from the ends for equality. Notice that if a line has less then K vowels, it can NOT be part of any rhyme (even with the identical string).
+
+To check this we can use two pointers running from two ends simultaneously, or use some built-in functions for taking substrings (like s.substr(...) in C++).
+
+Now, let us take three boolean variables: aabb, abab and abba. Each one says if every quatrain we have seen before satisfies the corresponding type of rhyme. To support them, for each new quatrain we must check for rhyming every pair of lines it and change variables if needed.
+
+If at the end of the poem all variables are set to TRUE, then the type is aaaa. If all of them are FALSE's, then the answer is NO. Otherwise exactly on of them is TRUE, and answer is clear.
+
+Complexity - O(S), where S is the sum of all lines' sizes.
+
+### [139D - Digits Permutations](/contest/139/problem/D "Codeforces Beta Round 99 (Div. 2)")
+
+### [138B - Digits Permutations](/contest/138/problem/B "Codeforces Beta Round 99 (Div. 1)")
+
+It turned out to be surprisingly hard, possibly because of lots of cases to think of.
+
+How to determine the number of zeros at the end of the sum of two numbers? First we skip all the positions from the end where both numbers have zeros. If on the next position the sum of digits is not 10, that's it. If it is, we go on while the sum of digits is 9.
+
+Now we take two transitions of digits in N. Let's fix the number of common zeros at the end of both transitions. If, moreover, we fix the digits that sum up to 10 at the next positions, we can find the maximal number of zeros to get with the remaining digits as *min*(*a*0, *b*9) + ... + *min*(*a*9, *b*0), where *a*0, ..., *a*9 are the quantities of every remaining digit in the first transition after taking out the last zeroes and the digit for the 10-sum, and *b*0, ..., *b*9 are the same numbers for second transition (initially these quantities are equal to quantities of digits in N).
+
+So, if we store *a*0, ..., *a*9 and *b*0, ..., *b*9, and then run through the numbers of common zeros at the end and the 10-sum digits, we determine the maximal zeros number (and configuration giving that answer) in O(10 * 10 * N) = O(N) time. Getting the transitions now is easy - we build them from right to left according to the saved answer.
+
+The most common mistake was to think that maximal number of zeros at the end gives the maximal answer. It was disproved by 4-th pretest - 1099. As we can see, the optimal configuration is 1901 + 1099, giving three zeros, which cannot be achieved by placing both zeros at the ends.
+
+### [139E - Mushroom Gnomes - 2](/contest/139/problem/E "Codeforces Beta Round 99 (Div. 2)")
+
+### [138C - Mushroom Gnomes - 2](/contest/138/problem/C "Codeforces Beta Round 99 (Div. 1)")
+
+First of all - the answer is the sum for all mushrooms of the probabilities of not being destroyed multiplied by that mushroom's power. That is a simple property of random variables' means.
+
+So we come to the equivalent statement: we still have mushrooms, but now instead of trees we have a family of segments with probabilities arranged to them. Every segment "exists" with this probability, otherwise it doesn't, and all these events are independent. We want to count the sum of probabilities (with weights) for each mushroom not to lie in any "existing" segment. (Note that we can reformulate the statement this way because any segments containing any fixed point are truly independent: they can't belong to the same tree. Thus the probability to survive for any point in this statement is equal to the probability for this point in the original statement).
+
+Now, how do we count this? There are several ways:
+
+1) "Scanning line". If we go from left to right, we can meet three kinds of events: "the segment *i* started", "the segment *i* finished", "the mushroom *j* found". We can easily support the probability of current point being covered by "existing" segment if we multiply it by segment's probability when we find its beginning and divide by it if we find its end. If we find a mushroom by the way, we can add the known probability to answer (multiplied by its power). To perform the above trick we just sort the array of events by x-coordinate and iterate over it.
+
+This solution is good in theory, but in practice it has a flaw: if the number of segments is large, after multiplying lots of real numbers less then 1 we can exceed the negative explonent of the real type used, and thus get a 0 in a variable instead of desired value. And after any number of divisions it still would be 0, so we couldn't get any sane answer anymore.
+
+This trouble can be resolved in several ways (without changing the solution much):
+
+a) We can have no more than 101 distinct values of probabilities for segments. So, if we store an array for quantities of segments containing current point and having a corresponding probability, we just add and substract 1's from array's elements. When we find a mushroom we find the product of degrees with exponents stored in array, spending ~100 operations.
+
+b) We can store a set of segments containing current point. Every operation with set works in O(log N) time, and iterating over the whole set works in O(N) time. So, upon meeting mushroom we iterate over set and multiply the probabilities for all segments in it.
+The next thing that helps us is that we can drop the answer for current mushroom if it's too small. If we don't store the segments with probability 1, the most number of segments which probabilities' product more than 1e-8 is about 2000 (since 0.99 ^ 2000 < 1e-8). So we can count everything in time.
+
+c) If we use logs of probabilities instead of themselves, we have to add and substract them instead of multiplying and dividing. This way we won't encounter any precision troubles.
+
+2) Segment tree.
+
+Let's sort the mushrooms by their coordinates. Let's also assume we have some set of segments and already counted the desired probabilities. And now we want to add a new segment to the set. What will change? The probabilities of mushrooms lying in this segment (and thus forming a segment in the array) will multiply by segment's probability.
+Now it's clear we can use multiplication segment tree (or simple addition segment tree if we use logs again) to perform the queries for all segments and then sum up the elements in the end.
+
+About the strange score and pretest: we discovered the trouble with precision quite late, and realized that it makes the problem way harder ('cause it's hard to predict during writing and submission phases). What's worse, it won't show itself on the small tests. So we decided to "show up" the test and let the contestants solve this additional problem, for additional score. (However, not all solutions from above list do actually deal with this problem. Unfortunately, we didn't came up with them beforehand.)
+
+### [138D - World of Darkraft](/contest/138/problem/D "Codeforces Beta Round 99 (Div. 1)")
+
+Notice that the game can be separated into two independent: for only even and only odd coordinate sum cells. The player chooses the game he would like to make a move in. Thus, if we find a [Grundy function](https://en.wikipedia.org/wiki/Sprague%E2%80%93Grundy_theorem) for each of this games we can find the whole game result.
+
+Now let's observe only even cells, for instance. We can prove that every diagonally connected piece formed during the game is constructed as the intersection of the field rectangle with some diagonally oriented semi-planes, with exactly one semi-plane for every orientation. Let's enumerate every possible edges of semi-planes, which obviously are some diagonals of the grid. Now we have an enumeration of all possible pieces - by four diagonals being "edges" of this piece.
+
+Now we want to count the Grundy function for some piece. To do this we iterate over all cells in this piece and find XORs of all Grundy functions of pieces formed by making a move in each cell, then find a minimal exclused non-negative number of this set (see the page on the Sprague-Grundy theorem above). All these pieces are smaller than current, so we can use the DP to count the functions. To easily iterate over cells in the piece we can iterate over numbers of two diagonals the cell lies on (going right-and-upwards and right-and-downwards), as we have exactly the bounds on their numbers as the parameters of the piece. For each case of diagonals we also have to check if the piece is inside the field.
+
+So we have counted the Grundy functions for even- and odd-numbered cells separately. If they are equal, the answer is "LOSE", otherwise it's a "WIN" (see the theorem again).
+
+Complexity - *O*((*n* + *m*)4 (number of pieces) *mn* (number of pieces inside one piece and counting MEX)).
+
+### [138E - Hellish Constraints](/contest/138/problem/E "Codeforces Beta Round 99 (Div. 1)")
+
+The most interesting problem. =)
+
+Let's start with the case when we have only one constriction - "*c* *l* *r*". For a string *s* let's count an array *A* with a length equal to *s*'s. *A*[*i*] = 1 if the suffix of *s* starting at position *i* satisfies the condition, and *A*[*i*] = 0 otherwise.
+
+So, we have *s* and already counted *A*. What happens if we write another symbol *c*' at the of *s*? Let *s*' = *s* + *c*', *A*' = *A*(*s*').
+
+If *c*' ≠ *c*, than the part of *A*' corresponding to everything beside the last symbol does not change. The last element is 1 or 0 depending on the condition (it's easy to count).
+
+If *c*' = *c*, some elements of *A* might change. Let's denote the *i*-th occurence of *c* in *s*' counting from the end as *p**i*(*c*) (symbols and occurences are enumerated from 1). If there are less then *i* occurences, *p**i*(*c*) = 0.
+
+It's easy to see that elements from *A*'[*p**l* + 1(*c*) + 1..*p**l*(*c*)] are incremented by 1, and elements from *A*'[*p**r* + 2(*c*) + 1..*p**r* + 1(*c*)] are decremented by 1. It's also clear that as we add the symbols these invervals won't intersect for *l* and *r* separately (that is, every *A*[*i*] will be incremented and decremented not more than one time each).
+
+Now we can have more then one constriction. We count *B*[*i*] as the number of constrictions the suffix starting at *i*-th position satisfies. Clearly, *B*[*i*] is the sum of *A*[*i*]'s for all constrictions. Also, we support the variable *C* - number of *i*-s that satisfy *L* ≤ *B*[*i*] ≤ *R*.
+
+Similarly, we add symbols one after another and change *B*[*i*]. To do that, we must consider all the constrictions concerning new symbols and change the numbers in the intervals mentioned above. Changing the numbers is just iterating over symbols in the mentioned intervals and incrementing/decrementing *B*[*i*]'s (this procedure also lets us to support *C* effectively). As the intervals for each constriction do not intersect, we will not change any *B*[*i*] more than twice for each constriction, so the number of operations concerning any constriction is *O*(*n*), giving total number of operations *O*(*nk*). To get the answer, we just sum up *C*'s states after adding every symbol (as every substring will be a suffix of some prefix exactly one time).
+
+To find borders of every interval used (in which the *B*[*i*]'s are changed) we can enumerate all occurences of every symbols and count the borders easily, knowing how many times every symbol occured. The other way to do that is to keep two pointers for each constriction, showing where last intervals ended. On the next occurence we move these pointers to next occurences of corresponding symbol (however, we need to handle the case when not enough symbols have occured to changed *B*).
diff --git a/editorials/139.md b/editorials/139.md
@@ -0,0 +1,106 @@
+Source: https://codeforces.com/blog/entry/3462
+
+### [139A - Petr and Book](/contest/139/problem/A "Codeforces Beta Round 99 (Div. 2)")
+
+If the total number of pages doesn't exceed the number of pages for Monday, the answer is Monday. Otherwise we can substract the Monday number from total and go on to Tuesday. If Tuesday isn't enough, we subtract and continue to Wednesday, and so on. We are sure that no more than N weeks will pass, as at least one page is read every week. Complexity - O(N).
+
+
+### [139B - Wallpaper](/contest/139/problem/B "Codeforces Beta Round 99 (Div. 2)")
+
+Unluckily, the translated statement was quite tough even tougher to understand than the original statement.
+
+Say we fixed the roll type and the room. The only possible way to cut the roll is to cut it into vertical stripes with length equal to room's height (though it was said we can cut it any way we want, there were some conditions to fulfill, namely there could be no joints other than vertical). So we find the total width of stripes we can cut our roll into as the (length of the roll / height of the room) (rounded down) * (width of the roll). If the roll length is smaller than room height, we obviously can not use this type of rolls (though the statement said there must exist at least one type we can use). The number of rolls is (perimeter of the wall rooms) / (total stripes width) (rounded up).
+
+Then we just try all types for every room and sum the minimal costs. Complexity - O(MN).
+
+### [139C - Literature Lesson](/contest/139/problem/C "Codeforces Beta Round 99 (Div. 2)")
+
+### [138A - Literature Lesson](/contest/138/problem/A "Codeforces Beta Round 99 (Div. 1)")
+
+The hardest part is to check whether two lines rhyme or not.
+
+We have to check the suffixes starting in K-th vowels from the ends for equality. Notice that if a line has less then K vowels, it can NOT be part of any rhyme (even with the identical string).
+
+To check this we can use two pointers running from two ends simultaneously, or use some built-in functions for taking substrings (like s.substr(...) in C++).
+
+Now, let us take three boolean variables: aabb, abab and abba. Each one says if every quatrain we have seen before satisfies the corresponding type of rhyme. To support them, for each new quatrain we must check for rhyming every pair of lines it and change variables if needed.
+
+If at the end of the poem all variables are set to TRUE, then the type is aaaa. If all of them are FALSE's, then the answer is NO. Otherwise exactly on of them is TRUE, and answer is clear.
+
+Complexity - O(S), where S is the sum of all lines' sizes.
+
+### [139D - Digits Permutations](/contest/139/problem/D "Codeforces Beta Round 99 (Div. 2)")
+
+### [138B - Digits Permutations](/contest/138/problem/B "Codeforces Beta Round 99 (Div. 1)")
+
+It turned out to be surprisingly hard, possibly because of lots of cases to think of.
+
+How to determine the number of zeros at the end of the sum of two numbers? First we skip all the positions from the end where both numbers have zeros. If on the next position the sum of digits is not 10, that's it. If it is, we go on while the sum of digits is 9.
+
+Now we take two transitions of digits in N. Let's fix the number of common zeros at the end of both transitions. If, moreover, we fix the digits that sum up to 10 at the next positions, we can find the maximal number of zeros to get with the remaining digits as *min*(*a*0, *b*9) + ... + *min*(*a*9, *b*0), where *a*0, ..., *a*9 are the quantities of every remaining digit in the first transition after taking out the last zeroes and the digit for the 10-sum, and *b*0, ..., *b*9 are the same numbers for second transition (initially these quantities are equal to quantities of digits in N).
+
+So, if we store *a*0, ..., *a*9 and *b*0, ..., *b*9, and then run through the numbers of common zeros at the end and the 10-sum digits, we determine the maximal zeros number (and configuration giving that answer) in O(10 * 10 * N) = O(N) time. Getting the transitions now is easy - we build them from right to left according to the saved answer.
+
+The most common mistake was to think that maximal number of zeros at the end gives the maximal answer. It was disproved by 4-th pretest - 1099. As we can see, the optimal configuration is 1901 + 1099, giving three zeros, which cannot be achieved by placing both zeros at the ends.
+
+### [139E - Mushroom Gnomes - 2](/contest/139/problem/E "Codeforces Beta Round 99 (Div. 2)")
+
+### [138C - Mushroom Gnomes - 2](/contest/138/problem/C "Codeforces Beta Round 99 (Div. 1)")
+
+First of all - the answer is the sum for all mushrooms of the probabilities of not being destroyed multiplied by that mushroom's power. That is a simple property of random variables' means.
+
+So we come to the equivalent statement: we still have mushrooms, but now instead of trees we have a family of segments with probabilities arranged to them. Every segment "exists" with this probability, otherwise it doesn't, and all these events are independent. We want to count the sum of probabilities (with weights) for each mushroom not to lie in any "existing" segment. (Note that we can reformulate the statement this way because any segments containing any fixed point are truly independent: they can't belong to the same tree. Thus the probability to survive for any point in this statement is equal to the probability for this point in the original statement).
+
+Now, how do we count this? There are several ways:
+
+1) "Scanning line". If we go from left to right, we can meet three kinds of events: "the segment *i* started", "the segment *i* finished", "the mushroom *j* found". We can easily support the probability of current point being covered by "existing" segment if we multiply it by segment's probability when we find its beginning and divide by it if we find its end. If we find a mushroom by the way, we can add the known probability to answer (multiplied by its power). To perform the above trick we just sort the array of events by x-coordinate and iterate over it.
+
+This solution is good in theory, but in practice it has a flaw: if the number of segments is large, after multiplying lots of real numbers less then 1 we can exceed the negative explonent of the real type used, and thus get a 0 in a variable instead of desired value. And after any number of divisions it still would be 0, so we couldn't get any sane answer anymore.
+
+This trouble can be resolved in several ways (without changing the solution much):
+
+a) We can have no more than 101 distinct values of probabilities for segments. So, if we store an array for quantities of segments containing current point and having a corresponding probability, we just add and substract 1's from array's elements. When we find a mushroom we find the product of degrees with exponents stored in array, spending ~100 operations.
+
+b) We can store a set of segments containing current point. Every operation with set works in O(log N) time, and iterating over the whole set works in O(N) time. So, upon meeting mushroom we iterate over set and multiply the probabilities for all segments in it.
+The next thing that helps us is that we can drop the answer for current mushroom if it's too small. If we don't store the segments with probability 1, the most number of segments which probabilities' product more than 1e-8 is about 2000 (since 0.99 ^ 2000 < 1e-8). So we can count everything in time.
+
+c) If we use logs of probabilities instead of themselves, we have to add and substract them instead of multiplying and dividing. This way we won't encounter any precision troubles.
+
+2) Segment tree.
+
+Let's sort the mushrooms by their coordinates. Let's also assume we have some set of segments and already counted the desired probabilities. And now we want to add a new segment to the set. What will change? The probabilities of mushrooms lying in this segment (and thus forming a segment in the array) will multiply by segment's probability.
+Now it's clear we can use multiplication segment tree (or simple addition segment tree if we use logs again) to perform the queries for all segments and then sum up the elements in the end.
+
+About the strange score and pretest: we discovered the trouble with precision quite late, and realized that it makes the problem way harder ('cause it's hard to predict during writing and submission phases). What's worse, it won't show itself on the small tests. So we decided to "show up" the test and let the contestants solve this additional problem, for additional score. (However, not all solutions from above list do actually deal with this problem. Unfortunately, we didn't came up with them beforehand.)
+
+### [138D - World of Darkraft](/contest/138/problem/D "Codeforces Beta Round 99 (Div. 1)")
+
+Notice that the game can be separated into two independent: for only even and only odd coordinate sum cells. The player chooses the game he would like to make a move in. Thus, if we find a [Grundy function](https://en.wikipedia.org/wiki/Sprague%E2%80%93Grundy_theorem) for each of this games we can find the whole game result.
+
+Now let's observe only even cells, for instance. We can prove that every diagonally connected piece formed during the game is constructed as the intersection of the field rectangle with some diagonally oriented semi-planes, with exactly one semi-plane for every orientation. Let's enumerate every possible edges of semi-planes, which obviously are some diagonals of the grid. Now we have an enumeration of all possible pieces - by four diagonals being "edges" of this piece.
+
+Now we want to count the Grundy function for some piece. To do this we iterate over all cells in this piece and find XORs of all Grundy functions of pieces formed by making a move in each cell, then find a minimal exclused non-negative number of this set (see the page on the Sprague-Grundy theorem above). All these pieces are smaller than current, so we can use the DP to count the functions. To easily iterate over cells in the piece we can iterate over numbers of two diagonals the cell lies on (going right-and-upwards and right-and-downwards), as we have exactly the bounds on their numbers as the parameters of the piece. For each case of diagonals we also have to check if the piece is inside the field.
+
+So we have counted the Grundy functions for even- and odd-numbered cells separately. If they are equal, the answer is "LOSE", otherwise it's a "WIN" (see the theorem again).
+
+Complexity - *O*((*n* + *m*)4 (number of pieces) *mn* (number of pieces inside one piece and counting MEX)).
+
+### [138E - Hellish Constraints](/contest/138/problem/E "Codeforces Beta Round 99 (Div. 1)")
+
+The most interesting problem. =)
+
+Let's start with the case when we have only one constriction - "*c* *l* *r*". For a string *s* let's count an array *A* with a length equal to *s*'s. *A*[*i*] = 1 if the suffix of *s* starting at position *i* satisfies the condition, and *A*[*i*] = 0 otherwise.
+
+So, we have *s* and already counted *A*. What happens if we write another symbol *c*' at the of *s*? Let *s*' = *s* + *c*', *A*' = *A*(*s*').
+
+If *c*' ≠ *c*, than the part of *A*' corresponding to everything beside the last symbol does not change. The last element is 1 or 0 depending on the condition (it's easy to count).
+
+If *c*' = *c*, some elements of *A* might change. Let's denote the *i*-th occurence of *c* in *s*' counting from the end as *p**i*(*c*) (symbols and occurences are enumerated from 1). If there are less then *i* occurences, *p**i*(*c*) = 0.
+
+It's easy to see that elements from *A*'[*p**l* + 1(*c*) + 1..*p**l*(*c*)] are incremented by 1, and elements from *A*'[*p**r* + 2(*c*) + 1..*p**r* + 1(*c*)] are decremented by 1. It's also clear that as we add the symbols these invervals won't intersect for *l* and *r* separately (that is, every *A*[*i*] will be incremented and decremented not more than one time each).
+
+Now we can have more then one constriction. We count *B*[*i*] as the number of constrictions the suffix starting at *i*-th position satisfies. Clearly, *B*[*i*] is the sum of *A*[*i*]'s for all constrictions. Also, we support the variable *C* - number of *i*-s that satisfy *L* ≤ *B*[*i*] ≤ *R*.
+
+Similarly, we add symbols one after another and change *B*[*i*]. To do that, we must consider all the constrictions concerning new symbols and change the numbers in the intervals mentioned above. Changing the numbers is just iterating over symbols in the mentioned intervals and incrementing/decrementing *B*[*i*]'s (this procedure also lets us to support *C* effectively). As the intervals for each constriction do not intersect, we will not change any *B*[*i*] more than twice for each constriction, so the number of operations concerning any constriction is *O*(*n*), giving total number of operations *O*(*nk*). To get the answer, we just sum up *C*'s states after adding every symbol (as every substring will be a suffix of some prefix exactly one time).
+
+To find borders of every interval used (in which the *B*[*i*]'s are changed) we can enumerate all occurences of every symbols and count the borders easily, knowing how many times every symbol occured. The other way to do that is to keep two pointers for each constriction, showing where last intervals ended. On the next occurence we move these pointers to next occurences of corresponding symbol (however, we need to handle the case when not enough symbols have occured to changed *B*).
diff --git a/editorials/141.md b/editorials/141.md
@@ -0,0 +1,27 @@
+Source: https://codeforces.com/blog/entry/3571
+
+[141A - Amusing Joke](/contest/141/problem/A "Codeforces Round 101 (Div. 2)")
+
+It was enough for solving this problem to calculate for each letter: *a**c* - amount of occurrences of letter *c* in first and second strings in input, *b**c* - amount of occurrences of letter *c* in third string in input. If  the answer is "YES" else "NO".
+
+[141B - Hopscotch](/contest/141/problem/B "Codeforces Round 101 (Div. 2)")
+
+Let's bust the "level" 0 ≤ *i* ≤ 106, in which assumedly the stone could hit. Let’s find the minimal number of square on this level. Then we can understand, how many squares there are on this level: one or two. Then we check with one or two ifs (if on this level two squares) if the stone is in corresponding square or not. If the stone is inside then output the answer. If we didn't find any square, where the stone is, output "-1".
+
+[141C - Queue](/contest/141/problem/C "Codeforces Round 101 (Div. 2)")
+
+Let's sort the pairs (*name**i*, *a**i*) by ascending of *a**i*. If there is an index i: 0 ≤ *i* < *n* that *a**i* > *i*, then answer is "-1". Otherwise the answer exists. We will iterate through the array of sorted pairs from left to right with supporting of vector of results *res*. Let on the current iteration *a**i* = *n* - *i*, then we must transfer the current man in the position *a**i*. It can be done in C++ with one line: res.insert(res.begin() + a[i], man);
+
+[141D - Take-off Ramps](/contest/141/problem/D "Codeforces Round 101 (Div. 2)")
+
+Let's generate the weighted directed graph of all ramps. The graphs' vertexes are the important points on the line *Ox*, there are points: 0, *L*, *x**i* - *p**i*, *x**i* + *d**i*. The graphs' edges are the possible ramp jumps: transfer from point *x**i* - *p**i* to point *x**i* + *d**i* or transfer from vertex in neighboring vertexes (neighboring means that we get the next and previous important points on the line). The weights of these edges are correspondingly *p**i* + *t**i* and *x**v* + 1 - *x**v*, *x**v* - *x**v* - 1. We must note that in the transfers we can't get in the negative part of *Ox*, and we must delete this transfers.
+
+Then we must find and output the shortest path in this graph from vertex 0 to *L*. This can be done, for example, with Dijkstra's algorithm for the sparse graphs.
+
+[141E - Clearing Up](/contest/141/problem/E "Codeforces Round 101 (Div. 2)")
+
+In this problem we must find the minimum spanning tree, in which the half of edges are marked with letter 'S'.
+
+There are *n* - 1 edges in this tree, because of it if *n* is even then the answer is "-1".
+
+Let's delete from the given graph all S-edges. And there are *cnt* components in obtained graph. For making this graph be connected we must add *cnt* - 1 edges or more, that's why if *cnt* - 1 > (*n* - 1) / 2 the answer is "-1". Then we find *cnt* - 1 S-edges, that we must add to the graph, so that it become connected. If *cnt* - 1 < (*n* - 1) / 2 then we will try to add in this set of edges another S-edges, so that the S-edges don't make circle. We must do all of this analogically to Kruskal's algorithm of finding a minimum spanning tree. If we could get a set of S-edges of (*n* - 1) / 2 elements, that there are exactly *cnt* - 1 edges and no S-circles, then the answer exists, Then we must add to this set (*n* - 1) / 2 M-edges, that forms with our set of edges the minimum spanning tree, it must be done analogically with Kruskal's algorithm.
diff --git a/editorials/142.md b/editorials/142.md
@@ -0,0 +1,147 @@
+Source: https://codeforces.com/blog/entry/3651
+
+*This is initial version only. TeX-style and Russian version will appear soon.*
+
+**Problem A (div. 2) - Help Vasilisa the Wise 2**
+
+There are many ways of solving this easiest problem of the contest. I list them in the order of increasing realization difficulty:
+
+1. If you use C++. Take permutation (1, 2, ..., 9). Suppose elements 1-4 are numbers we're looking for. Use next_permutation() to generate all possible combinations of numbers and just check that all conditions are met.
+
+2. Pure brute-force - just 4 nested for() cycles for each unknown number. Here one should not forget to check that all numbers are pairwise different. This takes additional 6 comparisons.
+
+3. One may note that, given the first number in the left upper cell, one may restore rest of the numbers in O(1). So, just check 9 numbers in the first cell (let it be x), restore other numbers from the given conditions:
+
+(x, a)
+
+(b, c)
+
+a = r1-x, b = c1-x, c = r2-b = r2-c1+x
+
+and check that they all lie in [0..9] and rest of the conditions are met.
+
+4. O(1) solution - one may derive it from the previous approach: since x+c = d1 => 2*x + r1 - c1 = d1 => x = (d1+c1-r1)/2
+
+So, you find x, check that it is in [0..9], restore all other numbers as in the previous approach and check that all conditions are met.
+
+**Problem B (div. 2) - Help Kingdom of Far Far Away 2**
+
+This was purely technical problem. String type is the best way to store the number. The main steps to get this problem is just to follow problem statement on how a number in the financial format is stored:
+
+1. Divide the number in the input into integer and fractional parts looking for position of the decimal point in the input number (if input number doesn't have decimal point - assume fractional part is empty string)
+
+2. Insert commas into integer part. This is done with one for() / while() cycle
+
+3. Truncate/add zeroes to length 2 in the fractional part
+
+4. Form the answer [integer part].[fractional part]. If initial number had minus in the beginning - add brackets to both sides of the answer.
+
+**Problem A (div. 1) / C (div. 2) - Help Farmer**
+
+Due to quite low constraint this problem is easily solvable by brute-force. Without loss of generality assume that A <= B <= C. Then it is clear that A cannot exceed , and, given A, B cannot exceed . Then all solution is just two cycles:
+
+for (long long a = 1; a*a*a <= n; ++a) if (n%a == 0){
+
+for (long long b = a; b*b <= n/a; ++b) if ((n/a)%b == 0){
+
+long long c = n/a/b;
+
+...
+
+}
+
+}
+
+Since we assumed A <= B <= C, now it is not clear which parameter (A, B or C) is the height of haystack, so inside the cycle one should consider all three possibilities. For any N <= 10^9 the code inside the second loop runs no more than 25000 times, so this solution fits timelimit even for N <= 10^11 and maybe larger. Why it's so quick? It's because of the fact that number of divisors of arbitrary number N does not exceed about . That's why all similar solutions and maybe some other streetmagic that has anything common with divisors of N, should get AC.
+
+**Problem B (div. 1) / D (div. 2) - Help General**
+
+This problem was not on derivation of the general formula m*n - (m*n)/2 (only this would be too simple for the second/fourth problem, isn't it?) but rather on accurate investigation of several cases. Unfortunately, many participants were very eager to submit the formula above, that's why there were so many hacks. I would say: this is not jury fault - pretests were made very weak intentionally, partially - to give you some space for hacks; but jury didn't presume there would be so many hacks. This is your fault of submitting unproven solutions. This is large risk given Codeforces rules, and this time risk-lovers were not lucky =)
+
+Ok, let's come to the solution. Without loss of generality let's assume m <= n. Then we have the following cases:
+
+1. m = 1 x n fields. It is obvious that here the answer is n.
+
+2. m = 2 x n >= 2 fields. Here the correct formula is 2*[2*(n/4) + min(n%4, 2)]. Why so? To see this draw the board for arbitrary n and draw all possible knight moves on it. In general, you'll see four not overlapping chains. Since you cannot place soldiers in the neighboring cells of any chain, then for a chain of length L the answer doesn't exceed (L - L/2). On the other hand, it is clear that the answer (L - L/2) is always possible since soldiers on different chains never hurt each other. If you consider fields with different remainders n%4, the formula above becomes clear.
+
+3. m >= 3 x n >= 3 fields, except the cases 3 x 3, 3 x 5, 3 x 6 and 4 x 4. Here one may use general formula m*n - (m*n)/2. Why so? It is known (or becomes known with google) that for all such fields knight tours exists. Any knight tour is just a chain of lenght m*n, so by the logic above one cannot place more than m*n - (m*n)/2 soldiers on it. On the other hand, if one makes chessboard coloring of the field, it is clear that the answer above is always achievable if one chooses cells of one color as places for soldiers. So, formula above is proved.
+
+4. Cases 3 x 3, 3 x 5, 3 x 6 and 4 x 4. Here we can't use the logic above to prove that the above formula is also right here. The easiest way is to verify it using brute-force or pen and paper. This concludes the solution.
+
+**Problem C (div. 1) / E (div. 2) - Help Caretaker**
+
+This is technical problem, one may use several approaches to solve it. Additional complexity is to restore the answer after you got it.
+
+1. Dynamic programming "on the broken profile" - I'll not explain the approach here in detail, you can find explanation of it on the Internet or even on Codeforces. Worth to point out, care should be taken of your code memory usage.
+
+2. Search with memorization - one jury solution uses logic like DP with usual (not broken) profile: move by rows (or by columns), try all possible T placements such that upper cell of T's is in the given row and run the same search procedure for the next raw, passing the state of the two last filled rows of the board to it. For the given board state save the answer recursive function returned (max number of T's one may place on the not-yet-filled part of the board) and use it in the future as the answer for the given state. This requires only O(n*2^(2^m)) of memory and works about 2 sec. on maxtest 9 x 9.
+
+3. Branch and bound. Another jury solution recursively tries all possible tilings of the board with T's. If on some step it occured that number of T's on the board plus number of T's one can theoretically place on the remaining part of the board doesn't exceed existing best answer - trim this node. Such solution is the easiest to code and it works only 0.5 sec. on maxtest, however it is not obvious from the very beginning.
+
+4. Precalc - not to write a lot of code (applying DP or search with memorization) and not to deal with possible time/memory limits, some participants did the right thing: using the third approach, just precalculated answers for large (or for all possible) inputs.
+
+**Problem D (div. 1) - Help Donkey and Shrek 2**
+
+Solving this problem involves two basic steps: firstly, to recognize that we have nothing else than generalised version of Nim and secondly, to solve it.
+
+The first part is not difficult: assuming we don't have rows with soldiers of only one color (in which case the game usually becomes trivial, since one or both players may play infinitely long), let the number of cells between two soldiers in every non-empty line be the size of the corresponding piles in nim. Then attack according to the rules of the given game is the move in the corresponding nim that allows you to take as much as you like stones from at most k piles (but at least 1 stone should be taken). Such generalized nim is called Moore's nim-k, and we should solve it to find the winner in the initial game. As any source you may google (except Russian Wikipedia) shows, solution to the Moore's nim-k is the following:
+
+Let's write binary expansions of pile sizes, and for any position check that sum of digits on the given position in all expansions is divisible by k+1. If this holds for all positions - then the winner is the second player, otherwise - the first player. Proof of the fact may be found here: http://www.stat.berkeley.edu/~peres/yuvalweb/gath9.pdf
+
+Let's consider the following case for k = 2:
+
+R-G--
+
+R--G-
+
+R---G
+
+R---G
+
+Corresponding 4-piles nim-2 for this test is (1, 2, 3, 3). After writing binary expansions of piles sizes we get
+
+01
+
+10
+
+11
+
+11
+
+Sums of digits in both positions (3) are divisible by k+1=3, so here Second wins.
+
+But this is still not full solution to the initial game, because we forget about retreat possibility. But it is simple here: only player losing the game in which only attacks allowed may want to retreat (winner just plays corresponding nim by attacking). But if loser retreats, winner just restores initial position attacking in the corresponding rows. And since loser cannot retreat infinitely, he cannot improve his win chances with retreat moves. That's it.
+
+And finally, don't forget about tests like:
+
+2 2 2
+
+GG
+
+RR
+
+Answer: Second
+
+All such tricky cases were in pretests.
+
+**Problem E (div. 1) - Help Greg the Dwarf 2**
+
+This problem was "just" about finding the shortest path on a cone. Unfortunately, even though jury lowered precision requirements to 10^-6 and included all possible general cases in pretests, nobody tried it =(
+
+For solution, let's consider all possible cases of two points on the cone surface (including its basement):
+
+1. Both points on the basement. Here it is clear that Euclidean distance between points is the answer to our problem.
+
+2. Both points on the lateral surface. One may think that optimal path is also always lies on the lateral surface. In this case it is easy to find length of an optimal path from geometric considerations (by considering loft of the lateral surface). But 10-th pretest disproves that it is always optimal:
+
+100 100
+
+99 0 1
+
+-99 0 1
+
+Answer: 202.828427124746210
+
+So, optimal path may go through the basement. In this case it has two points that lie at the same time on the basement and on the lateral surface (let's call them A' and B'), so length of the path through this points is easy to find by adding length of the three different segments - AA', A'B' and B'B. So the problem is reduced to finding optimal positions of A' and B'? Let's assume that polar angle of the first point in XOY plane is a1 (0 <= a1 < 2*PI) and polar angle of the second point is a2 (0 <= a2 < 2*PI). Length of the shortest path between A and B passing through the points A' and B' (AA' + A'B' + B'B) is some function of two arguments that we want to minimize - f (a1, a2). One may minimize it using, for example, grid or any other suitable numerical approach.
+
+3. One point on the basement and another point on the lateral surface. This case is similar to the previous one - optimal path passes some point C' on the "brink" whose optimal polar angle we are to find. In this case we optimize function of one argument g(polar angle(C')) = AC' + C'B.
diff --git a/editorials/144.md b/editorials/144.md
@@ -0,0 +1,33 @@
+Source: https://codeforces.com/blog/entry/3693
+
+Problem A
+
+It's clear that the leftmost soldier with the maximum height should be the first and the rightmost soldier with the minimum height should be the last. Thus we will minimize the number of swaps. And the answer is number of leftmost soldier with the maximum height - 1 + *n* - number of rightmost soldier with the minimum height. And if the leftmost soldier with the maximum height is more right then the rightmost soldier with the minimum height we should subtract one from the answer.
+
+Problem B
+
+Let's try to check all integer points of the table perimeter and add to the answer such of them that don't cover by circles of radiators. Let *x**a* < *x**b* and *y**a* < *y**b*, and if it's not true then swap *x**a* and *x**b*, *y**a* and *y**b*. So generals sit in the next integer points: (*x**a*, *y*), (*x**b*, *y*), (*x*, *y**a*), (*x*, *y**b*), where *x**a* ≤ *x* ≤ *x**b* и *y**a* ≤ *y* ≤ *y**b*. We should be attentive when we count the generals who sits in points: (*x**a*, *y**a*), (*x**a*, *y**b*), (*x**b*, *y**a*), (*x**b*, *y**b*), that don't count them twice.
+
+Problem C
+
+Let's count number of each letter in the second string and save it, for example, in array *a*[1..26]. For the first strings' prefix of length *n*, where *n* is the length of second string, (it's the first substring) we count number of each letter in array *b*[1..26]. We don't count characters ``\texttt{?}''. If there are *b*[*i*] ≤ *a*[*i*] for all *i*, then it's good substring. Then go to the second substring: subtract from the array *b* the first character: *b*[*s*[1] - '*a*' + 1] – and add *n* + 1 character: *b*[*s*[*n* + 1] - '*a*' + 1] + + . If some of these characters is ``\texttt{?}'' then we shouldn't do for it the subtraction or addition. Then repeat the showed check and go to the next substring. Let's repeat this procedure for all substrings of length *n*.
+
+Problem D
+
+*d*[*i*] --- the minimum distance from vertex *s* to vertex *i*, that counted by algorithm of Dijkstra. "et's count the number of points on each edge of the graph that are on the distance *l* form the vertex *s* (and *l* --- the minimum distance from these points to *s*).
+
+For edge (u, v):
+
+if *d*[*u*] < *l* and *l* - *d*[*u*] < *w*(*u*, *v*) and *w*(*u*, *v*) - (*l* - *d*[*u*]) + *d*[*v*] > *l* then add to the answer the point on this edge, the distance of which to the vertex *u* is *l* - *d*[*u*];
+
+if *d*[*v*] < *l* and *l* - *d*[*v*] < *w*(*u*, *v*) and *w*(*u*, *v*) - (*l* - *d*[*v*]) + *d*[*u*] > *l* then add to the answer the point on this edge, the distance of which to the vertex *v* is *l* - *d*[*v*];
+
+if *d*[*v*] < *l* and *d*[*u*] < *l* and *d*[*u*] + *d*[*v*] + *w*(*u*, *v*) = 2 * *l* then add to the answer the point on this edge, the distance of which to the vertex *v* is *l* - *d*[*v*] and to the vertex *u* is *l* - *d*[*u*].
+
+And if *d*[*i*] = *l*, then let's add to the answer this point.
+
+Problem E
+
+It's clear that the nearest squares of the secondary diagonal to some sportsman form the "segment" of the squares of the secondary diagonal. Let's write these segments for each sportsman.
+
+Let's consider sportsmen so that we should compare to each sportsman excactly one square of the secondary diagonal from his "segment" and to each square of the secondary diagonal no more then one sportsman. It's clear that sportsmen can reach theirs squares without occupying the same square simultaneously with another sportsman. We should maximize the number of choosen sportsmen. And solution of this reformulated problem is greedy.
diff --git a/editorials/145.md b/editorials/145.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/3746
+
+**DIV2-A Lucky Ticket:**
+
+In this problem everything is obvious: if all digits are lucky and sum of the digits of the first half equals to the sum of the digits of the second half, then answer is YES, in other case - NO. All this can be checked by single loop through all the digits.
+
+**DIV2-B Lucky Mask:**
+
+You can see that, in worst case, the answer will be equal to 177777. It can't be greater. So, only thing you need is to write some function *F*(*x*) which will return mask of the *x*. After that you need to write such kind of code:
+
+*x* = *a* + 1;
+
+while (*F*(*x*) is not equal to *b*)
+
+increase *x*;
+
+and *x* will contain the answer.
+
+**DIV2-C DIV1-A Lucky Transformation:**
+
+You need to find two numbers: *c*47 (number of such positions *i*, that *a**i* = 4 and *b**i* = 7) and *c*74 (number of such positions that *a**i* = 7 and *b**i* = 4). After that the result will be *max*(*c*47, *c*74) (because you need to obtain *min*(*c*47, *c*74) swaps, the rest *max*(*c*47, *c*74) - *min*(*c*47, *c*74) are editings of digits).
+
+**DIV2-D DIV1-B Lucky Number 2:**
+
+Let we have some string result *s*. Let then delete all repititions, i. e. while we have some pair adjacent equal digits, we delete one of them. Let call formed string a root. In root there will be no adjacent equal digits, so |*cnt*(47) - *cnt*(74)| ≤ 1. So, if |*a*3 - *a*4| > 1, then answer is "-1". Now, if we would know the root, that will be used in our result, we can create result.
+
+You can see, that if *a*3 = *a*4, then root must be 47474747...474 or 747474...747. If *a*3 < *a*4, then root is 74747474....74. If *a*3 > *a*4, then root is 474747...47. Length of the root must be such that it fulfill *a*3 and *a*4.
+
+Now, when you have a root, you can build result. You just need to find first occurrence of 4 in root and insert the rest of 4 from *a*1 right next to that digit. To add the rest of 7, you need to find last occurrence of 7 in root.
+
+The answer does not exits if, after constructing the root, you have used more 4 than *a*1 or more 7 than *a*2.
+
+**DIV2-E DIV1-C Lucky Different:**
+
+As you probably know, the number of lucky numbers in range [1;109] is 1022. We use this fact to solve problem. Let *C*[*i*] - number of occurrences of *i*-th lucky number in array *a*. Now we schould calculate DP with parameters DP[pos][cnt] - what is the number of subsequences that we use lucky numbers up to *pos*-th and our subsequence contains exactly *cnt* lucky number. If we are on state DP[pos][cnt] we can do two things: do not use *pos*-th lucky number (and do DP[pos+1][cnt] += DP[pos][cnt]) or use *pos*-th lucky (and do DP[pos+1][cnt+1] += DP[pos][cnt]*C[pos], because you have C[pos] of *pos*-th lucky number).
+
+Now we need to find total result. To do that we iterate through the number of lucky numbers in our subsequence *i*. Then you need to multiple that number by *C*(*count**unlucky*, *k* - *i*) (bin. coefficient), where *count**unlucky* - number of unlucky numbers of sequence. Sum for all such *i* will be the total result.
+
+**DIV1-D Lucky Pair:**
+
+The main point of this problem is that number of lucky numbers in array is ≤ 1000. Imagine that there is array of 1000 number in range [1;1000] each, and you want to find number of such pairs that there is no equal number in both segments. How to solve this problem? Let we have fixed left point of right segment, let it be *i*. The you should iterate through all *j* (*i* ≤ *j*) - right point of right segment. If you have some fixed right segment [*i*;*j*], then there is some set *S* of numbers that are in that right segment. So, segment [0;*i* - 1] will be divided in some subsegments that don't contain any number from *S*. For example, let *S* = {1, 2, 3} and segment [0;*i* - 1] is [2, 4, 2, 3, 6, 5, 7, 1], then there will be such subsegments (0-based numeration): [1;1], [4;6]. Of course, any subsegment of that subsegments will be good too: they dont contain any number from *S*, too. So, you can keep in *set* (or some structure like *set*) all good subsegments and keep number of all good subsegments in [0;*i* - 1]. When you iterate *j* from *i* to *n* - 1, you will add some numbers to *S*. When you add some number in *S*, you should add all occurrences of that number in subarray [0;*i*]. Notice, that when some number is already in *S*, you don't need to look at that numbers. So, for fixed *i* you should do *O*(*n* * *logn*) operations - any number from *a*[0;*i* - 1] will be added at most once to *set*.
+
+Now, we have not only lucky numbers. So, the problem is the same, but between number there are some "bad" numbers - in this case this are unlucky numbers. But, you can notice, that if we will fix only such *i* that *a*[*i*] is lucky and iterate *j* only such that *a*[*j*] is lucky then you can calculate result in the same way that in simpler problem. But that method allow you to only count such pairs that right one contains some lucky number. So you also need to count other ones. To do so you can fix some *i* - left point of right segment, such that *a*[*i*] is unlucky. Let *F*(*i*) equals to minimum such *j* (*j* > *i*) that *a*[*i*] is lucky. Then there are *F*(*i*) - *i* ways to expand right segment. All such right segments doesn't contain any lucky number. So any left segment will be good. And there are *i* * (*i* + 1) / 2 of such left segments (0-based).
+
+**DIV1-E Lucky Switch:**
+
+(with help of [sjtu_pigoneand](/profile/sjtu_pigoneand "Master sjtu_pigoneand"))
+
+To solve this problem you need to handle segment tree with following information:
+
+n4: number of 4-digits in node range.
+
+n7: number of 7-digits in node range.
+
+n47: maximum non-decreasing subsequence in range.
+
+n74: maximum non-increasing subsequence in range.
+
+When we reverse digits in some node we just swap(n4, n7), swap(n47, n74). When we update node we keep n4(father) = n4(left_son) + n4(right_son), n47(father) = max(n47(left_son) + n7(right_son), n4(left_son) + n47(right_son), n4(left_son) + n7(right_son)). Then for each *count* query result is *n*47.
+
+Read [this](https://codeforces.com/blog/entry/3327) tutorial about segment trees.
diff --git a/editorials/146.md b/editorials/146.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/3746
+
+**DIV2-A Lucky Ticket:**
+
+In this problem everything is obvious: if all digits are lucky and sum of the digits of the first half equals to the sum of the digits of the second half, then answer is YES, in other case - NO. All this can be checked by single loop through all the digits.
+
+**DIV2-B Lucky Mask:**
+
+You can see that, in worst case, the answer will be equal to 177777. It can't be greater. So, only thing you need is to write some function *F*(*x*) which will return mask of the *x*. After that you need to write such kind of code:
+
+*x* = *a* + 1;
+
+while (*F*(*x*) is not equal to *b*)
+
+increase *x*;
+
+and *x* will contain the answer.
+
+**DIV2-C DIV1-A Lucky Transformation:**
+
+You need to find two numbers: *c*47 (number of such positions *i*, that *a**i* = 4 and *b**i* = 7) and *c*74 (number of such positions that *a**i* = 7 and *b**i* = 4). After that the result will be *max*(*c*47, *c*74) (because you need to obtain *min*(*c*47, *c*74) swaps, the rest *max*(*c*47, *c*74) - *min*(*c*47, *c*74) are editings of digits).
+
+**DIV2-D DIV1-B Lucky Number 2:**
+
+Let we have some string result *s*. Let then delete all repititions, i. e. while we have some pair adjacent equal digits, we delete one of them. Let call formed string a root. In root there will be no adjacent equal digits, so |*cnt*(47) - *cnt*(74)| ≤ 1. So, if |*a*3 - *a*4| > 1, then answer is "-1". Now, if we would know the root, that will be used in our result, we can create result.
+
+You can see, that if *a*3 = *a*4, then root must be 47474747...474 or 747474...747. If *a*3 < *a*4, then root is 74747474....74. If *a*3 > *a*4, then root is 474747...47. Length of the root must be such that it fulfill *a*3 and *a*4.
+
+Now, when you have a root, you can build result. You just need to find first occurrence of 4 in root and insert the rest of 4 from *a*1 right next to that digit. To add the rest of 7, you need to find last occurrence of 7 in root.
+
+The answer does not exits if, after constructing the root, you have used more 4 than *a*1 or more 7 than *a*2.
+
+**DIV2-E DIV1-C Lucky Different:**
+
+As you probably know, the number of lucky numbers in range [1;109] is 1022. We use this fact to solve problem. Let *C*[*i*] - number of occurrences of *i*-th lucky number in array *a*. Now we schould calculate DP with parameters DP[pos][cnt] - what is the number of subsequences that we use lucky numbers up to *pos*-th and our subsequence contains exactly *cnt* lucky number. If we are on state DP[pos][cnt] we can do two things: do not use *pos*-th lucky number (and do DP[pos+1][cnt] += DP[pos][cnt]) or use *pos*-th lucky (and do DP[pos+1][cnt+1] += DP[pos][cnt]*C[pos], because you have C[pos] of *pos*-th lucky number).
+
+Now we need to find total result. To do that we iterate through the number of lucky numbers in our subsequence *i*. Then you need to multiple that number by *C*(*count**unlucky*, *k* - *i*) (bin. coefficient), where *count**unlucky* - number of unlucky numbers of sequence. Sum for all such *i* will be the total result.
+
+**DIV1-D Lucky Pair:**
+
+The main point of this problem is that number of lucky numbers in array is ≤ 1000. Imagine that there is array of 1000 number in range [1;1000] each, and you want to find number of such pairs that there is no equal number in both segments. How to solve this problem? Let we have fixed left point of right segment, let it be *i*. The you should iterate through all *j* (*i* ≤ *j*) - right point of right segment. If you have some fixed right segment [*i*;*j*], then there is some set *S* of numbers that are in that right segment. So, segment [0;*i* - 1] will be divided in some subsegments that don't contain any number from *S*. For example, let *S* = {1, 2, 3} and segment [0;*i* - 1] is [2, 4, 2, 3, 6, 5, 7, 1], then there will be such subsegments (0-based numeration): [1;1], [4;6]. Of course, any subsegment of that subsegments will be good too: they dont contain any number from *S*, too. So, you can keep in *set* (or some structure like *set*) all good subsegments and keep number of all good subsegments in [0;*i* - 1]. When you iterate *j* from *i* to *n* - 1, you will add some numbers to *S*. When you add some number in *S*, you should add all occurrences of that number in subarray [0;*i*]. Notice, that when some number is already in *S*, you don't need to look at that numbers. So, for fixed *i* you should do *O*(*n* * *logn*) operations - any number from *a*[0;*i* - 1] will be added at most once to *set*.
+
+Now, we have not only lucky numbers. So, the problem is the same, but between number there are some "bad" numbers - in this case this are unlucky numbers. But, you can notice, that if we will fix only such *i* that *a*[*i*] is lucky and iterate *j* only such that *a*[*j*] is lucky then you can calculate result in the same way that in simpler problem. But that method allow you to only count such pairs that right one contains some lucky number. So you also need to count other ones. To do so you can fix some *i* - left point of right segment, such that *a*[*i*] is unlucky. Let *F*(*i*) equals to minimum such *j* (*j* > *i*) that *a*[*i*] is lucky. Then there are *F*(*i*) - *i* ways to expand right segment. All such right segments doesn't contain any lucky number. So any left segment will be good. And there are *i* * (*i* + 1) / 2 of such left segments (0-based).
+
+**DIV1-E Lucky Switch:**
+
+(with help of [sjtu_pigoneand](/profile/sjtu_pigoneand "Master sjtu_pigoneand"))
+
+To solve this problem you need to handle segment tree with following information:
+
+n4: number of 4-digits in node range.
+
+n7: number of 7-digits in node range.
+
+n47: maximum non-decreasing subsequence in range.
+
+n74: maximum non-increasing subsequence in range.
+
+When we reverse digits in some node we just swap(n4, n7), swap(n47, n74). When we update node we keep n4(father) = n4(left_son) + n4(right_son), n47(father) = max(n47(left_son) + n7(right_son), n4(left_son) + n47(right_son), n4(left_son) + n7(right_son)). Then for each *count* query result is *n*47.
+
+Read [this](https://codeforces.com/blog/entry/3327) tutorial about segment trees.
diff --git a/editorials/148.md b/editorials/148.md
@@ -0,0 +1,61 @@
+Source: https://codeforces.com/blog/entry/3819
+
+So, here goes the editorial. I'll tell you right away that nobody guessed [MikeMirzayanov](/profile/MikeMirzayanov "Headquarters, MikeMirzayanov")'s problem (nice disguise, er?) — it was problem C about the picky princess. Actually, this was the first problem of the round, the rest of problems I invented to keep up the lovely topic.
+
+[148A - Insomnia cure](/contest/148/problem/A "Codeforces Round 105 (Div. 2)")
+
+The number of dragons D can be quite small, so the problem can be solved in a straightforward way, by iterating over dragons 1 through D and checking each dragon individually. Time complexity of such solution is O(D). There exists a smarter solution with O(1) complexity, based on inclusion-exclusion principle. You'll have to count the numbers of dragons which satisfy at least one, two, three or four of the damage conditions *N**i*, i.e., dragons who have index divisible by LCM of the corresponding sets of numbers. Remember that the number of numbers between 1 and D which are divisible by T equals *D* / *T*. Finally, the number of dragons that get damaged equals *N*1 - *N*2 + *N*3 - *N*4. You'd have to use this method if the total number of dragons was too large for iterating over it.
+
+[148B - Escape](/contest/148/problem/B "Codeforces Round 105 (Div. 2)")
+
+In this problem it was enough to simulate the sequence of events that happen on the line between the cave and the castle. My solution focused on two types of evens — "the dragon is in the cave and sets off after the princess" and "the dragon and the princess are at the same coordinate"; in this case it's enough to keep track of time and princess' coordinate, no need to store dragon's one. The first type of event happens for the first time at time T, when the princess' coordinate is *T* * *V**p*. If at this time she has already reached the castle, no bijous are needed. Otherwise we can start iterating. The time between events of first and second type equals the princess' coordinate at the moment of first event, divided by *V**d* - *V**p*. Adjust the princess' coordinate by the distance she will cover during this time and check whether she reached the castle again. If she didn't, she'll need a bijou — increment the number of bijous required. The second part of the loop processes the return of the dragon, i.e., the transition from second type of event to the first one. The time between the events equals princess' new coordinate, divided by the dragon's speed, plus the time of straightening things out in the treasury. Adjust princess' coordinate again and return to the start of the loop (you don't need to check whether the princess reached the castle at this stage, since it doesn't affect the return value).
+
+The complexity of the algorithm can be estimated practically: the number of loop iterations will be maximized when dragon's speed and distance to the castle are maximum, and the rest of parameters are minimum. This results in about 150 bijous and the same number of iterations.
+
+You'll also need to check for the case *V**p* ≥ *V**d* separately — the dragon can be old and fat and lazy, and he might never catch up with the princess.
+
+[148D - Bag of mice](/contest/148/problem/D "Codeforces Round 105 (Div. 2)")
+
+Initially this problem was a boring homework one about drawing balls out of the bag. But seriously, do you think a dragon would have something so mundane as a bag of balls in his cave? And he definitely could find some use for a bag of mice — for example, using them to scare the princess or as a snack.
+
+If mice were balls and never jumped out of the bag, the problem would be doable in a single loop. Suppose that at some step we have W white and B black mice left in the bag, and the probability to get into this state is P (initially W and B are input values, and P = 1). The absolute probability to get a white mouse at this step is *P* * *W* / (*B* + *W*) (the probability of getting to this state, multiplied by the conditional probability of getting white mouse). If it's princess' turn to draw, this probability adds to her winning probability, otherwise her winning probability doesn't change. To move to the next iteration, we need the game to continue, i.e., a black mouse to be drawn on this iteration. This means that the number of black mice decreases by 1, and the probability of getting to the next iteration is multiplied by *B* / (*B* + *W*). Once we've iterated until we're out of black mice, we have the answer.
+
+Unfortunately, the mice in the bag behave not as calmly as the balls. This adds uncertainty — we don't know for sure what state we will get to after the dragon's draw. We'll need a recursive solution to handle this (or dynamic programming — whichever one prefers). When we solve a case for (W, B), the princess' and the dragon's draws are processed in a same way, but to process the mouse jumping out of the bag, we'll need to combine the results of solving subproblems (W, B — 3) and (W — 1, B — 2). The recursive function of the reference solution is:
+
+```
+map<pair<int, int>, double> memo;
+
+double p_win_1_rec(int W, int B) {
+ if (W <= 0) return 0;
+ if (B <= 0) return 1;
+ pair<int, int> args = make_pair(W, B);
+ if (memo.find(args) != memo.end()) {
+ return memo[args];
+ }
+ // we know that currently it's player 1's turn
+ // probability of winning from this draw
+ double ret = W * 1.0 / (W + B), cont_prob = B * 1.0 / (W + B);
+ B--;
+ // probability of continuing after player 2's turn
+ cont_prob *= B * 1.0 / (W + B);
+ B--;
+ // and now we have a choice: the mouse that jumps is either black or white
+ if (cont_prob > 1e-13) {
+ double p_black = p_win_1_rec(W, B - 1) * (B * 1.0 / (W + B));
+ double p_white = p_win_1_rec(W - 1, B) * (W * 1.0 / (W + B));
+ ret += cont_prob * (p_black + p_white);
+ }
+ memo[args] = ret;
+ return ret;
+}
+```
+
+The time complexity of recursion with memoization is O(W*B), i.e., the number of different values the input can take. Note that in this implementation access to the map adds log(W*B) complexity, but you can avoid this by storing the values in an 2-dimensional array.
+
+[148E - Porcelain](/contest/148/problem/E "Codeforces Round 105 (Div. 2)")
+
+This problem involved dynamic programming with precalculation.
+
+The first part of the solution was to precalculate the maximal cost of i items taken from the shelf (i ranging from 1 to the number of items on the shelf) for each shelf. Note that this can't be done greedily: this can be seen on the shelf 6: 5 1 10 1 1 5.
+
+The second part is a standard dynamic programming, which calculates the maximal cost of items taken for index of last shelf used and total number of items taken. To advance to the next shelf, one has to try all possible numbers of items taken from it and increase the total cost of items taken by corresponding precalculated values.
diff --git a/editorials/149.md b/editorials/149.md
@@ -0,0 +1,47 @@
+Source: https://codeforces.com/blog/entry/3864
+
+## [149A - Business trip](/contest/149/problem/A "Codeforces Round 106 (Div. 2)")
+
+First, it is clear that if the sum of all numbers *a**i* is less than *k*, then Peter in any case will not be able to grow a flower to the desired height, and you should output <<-1>>.
+
+Secondly, it is easy to see that if we want to choose a one month of two, in which we watered the flower, it is better to choose one where the number of *a**i* is more. Thus, the solution is very simple: let's take months in descending order of numbers *a**i* and in these months water flowers. As soon as the sum of the accumulated *a**i* becomes greater than or equal to *k* — should stop the process, the answer is found.
+
+## [149B - Martian Clock](/contest/149/problem/B "Codeforces Round 106 (Div. 2)")
+
+In this task required only the ability to work with different numeral systems. Let's try to go through numeral bases, each base to check whether it is permissible, as well as convert hours and minutes to the decimal system and compared with 24 and 60, respectively.
+
+What is maximal base, that we need to check? In fact, it is enough to 60, because 60 — upper limit on the allowable number. It follows from the fact that if the number in an unknown number system consists of one digit, then its value in decimal not ever change, otherwise its value is not less than the base.
+
+It is also worth to consider the case with the response <<-1>>, for this example, you can check a big base, such as 100, and even if the time for him correct, then for all large, it is also correct and the answer is <<-1>>.
+
+## [149C - Division into Teams](/contest/149/problem/C "Codeforces Round 106 (Div. 2)")
+
+Sort all the boys on playing skill. Then, if we send in the first team all the boys standing in a sorted array for odd places, and the second — even standing on the ground, then all requirements for division executed.
+
+The first two requirements are obviously satisfied.
+
+To prove the third we consider the geometric representation: Let each child designated point on the X axis with a value equal his playing skill. Connect the points with segments numbered 1 and 2, 3 and 4, and so on. If *n* is odd, then join the last point with the nearest the previous one.
+
+Obviously, all these segments don't intersect in pairs, except at the points, and their total length is equal to the difference amounts to play boys' skills contained into the first team and second team. It is also clear that all of these segments completely contained in the interval [0, *max*(*a**i*)], as well as the pairs are a length of zero crossing, the third requirement is satisfied, which we proved.
+
+## [149D - Coloring Brackets](/contest/149/problem/D "Codeforces Round 106 (Div. 2)")
+
+We introduce the notation of colors: 0 — black, 1 — red, 2 — blue. Note that a single pair of brackets has 4 different coloring: 0-1, 1-0, 0-2, 2-0.
+
+Consider the dynamic programming, where the state is (*l*, *r*, *c**l*, *c**r*), where the pair (*l*, *r*) defines a pair of brackets, and *c**l* and *c**r* denote a fixed color for them. The value of the dynamic is a number of ways to paint all the parenthesis brackets inside the interval (*l*, *r*) in compliance with all conditions.
+
+We write down all the pairs of brackets that are directly placed into a pair of (*l*, *r*), let *k* of their pieces. Moreover, we consider only the first level of nesting, it is directly attached.
+
+In order to calculate the value of the dynamics for the state, within this state shall calculate the another dynamic, where the state is a pair (*i*, *c*) which means the number of correct colorings of the first *i* directly nested parentheses, and all inside them, if the latter closing bracket has a color *c*. Calcing the values of this dynamic is very simple, let's try to paint a (*i* + 1)-th parenthesis in one of four variants, but you should keep in mind possible conflicts. In such dynamics the initial state is a pair (0, *c**l*), and the final result is sum over the states of the form (*k*, *c*), where *c* must not conflict with the *c**r*.
+
+The answer to the whole problem may be calced as the internal dynamic. Time of solution — *O*(*n*2) by a factor of about 12.
+
+## [149E - Martian Strings](/contest/149/problem/E "Codeforces Round 106 (Div. 2)")
+
+We will solve the problem separately for each *m* strings. Thus, suppose we have a string *p*, its length is *l*, and we need to check whether the Martian be seen.
+
+We introduce additional arrays: let *pref*[*i*] is minimal position in the *s* of the begin of occurrence *p* with length exactly *i*, and let *suff*[*j*] is the maximum position in the *s* of the end of occurrence *p* with length exactly *j*
+
+It is easy to understand that a Martian could see the *p*, if there exists an *i*, that *suff*[*l* - *i*] ≥ *pref*[*i*] + *l* - 1.
+
+How to calculate the arrays? For *pref* array is sufficient to find Z-function p#s, but for an array of *suff* — Z-function r(p)#r(s), where *r*(*t*) means the reversed string *t*. Using an array of Z-functions calcing of arrays *suff* and *pref* is trivial.
diff --git a/editorials/150.md b/editorials/150.md
@@ -0,0 +1,83 @@
+Source: https://codeforces.com/blog/entry/3905
+
+### [150E - Freezing with Style](/contest/150/problem/E "Codeforces Round 107 (Div. 1)")
+
+1. If there exists a path with the median ≥ *k*, for some *k*, then there exists a path with the median ≥ *q*, for each *q* ≤ *k*. That means we can use binary search to calculate the answer. So now the task is: is there any path with the median greater or equal to *Mid* ?
+2. We will calc the edge as + 1 if it's wight ≥ *Mid*, or as - 1 in other case. Now we only need to check if there exists a path with legal length and the sum greater than or equal to zero.
+3. Let's denote some node *V* as a root.
+4. All paths can be divided into two types: that contains *v*, and that do not. Now we are to process all first-type paths and run the algorithm on all subtrees. That is so-called divide-and-conquer strategy.
+5. We can trivially show that it is always possible to choose such vertex *v* that all it's subtrees will have size less than or equal to the size of the whole tree. That means that each node will be proccessed in *LogN* trees max.
+6. So, if we solve the task for one level of recursion in *O*(*F*(*N*)), we'll solve it in time *O*(*F*(*N*) * *log*2(*N*)) on the whole.
+7. First, lets get *O*(*N* * *Log*(*N*)). For each node we shall calc it's deepness, cost of the path to the root ans the first edge (the number of the root's subtree). It will be better now to use 2 and 0 as the edges costs, instead of -1 and 1. Now we shall process root's subtrees one by one. For each node we want to know if there exists a node *u* in any other subtree such that the
+
+ Unable to parse markup [type=CF_TEX]
+
+ and *cost*[*v*] - *deep*[*v*] + *cost*[*u*] - *deep*[*u*] ≥ 0. To do that we need to know the maximum of the function (*cost*[*u*] - *deep*[*u*]) with the deep values between max(0, *L* - *deep*[*v*]) and *R* - *deep*[*v*] inclusive. To achieve *O*(*N* * *log*(*N*)) you need only to use segment tree.
+8. To achieve an AC contestants were to write all code optimally, or to think of one more idea. It is possible to have *O*(*N*) on one level of recursion and *O*(*N* * *log*2(*N*)) in total if you sort roots subtrees in non-decreasing order and use any structure that can answer getmax query on all segments of length (*R* - *L* + 1) and all prefixes and suffixes.
+
+Best of luck to you in upsolving this problem!
+
+### [150D - Mission Impassable](/contest/150/problem/D "Codeforces Round 107 (Div. 1)")
+
+In this problem you have to use dynamic programming. For our convenience we will calulate three type of values:
+
+*Best*[*l*][*r*] — best result player can achieve on the segment [*l*, *r*].
+
+*Full*[*l*][*r*] — best result player can achieve on the segment from [*l*, *r*] if he fully destroys it.
+
+*T*[*l*][*r*][*Len*] — best result player can achieve on the segment from [*l*, *r*] and remain the palindrome of length *len* and only it.
+
+Now solution:
+
+1. *Full*[*l*][*r*]. Let's look which move will be the last. This will be removing the palindrome of length *len* and *c*[*len*] ≥ 0. What is the best result we can achieve? *c*[*len*] + *T*[*l*][*r*][*len*].
+2. *Best*[*l*][*r*]. Either we will destroy all subtring from *l* to *r*, either there exists a letter which we did not touch. That means that all our moves lies fully to the left or fully to the rigth to that position. So *Best*[*l*][*r*] = *Full*[*l*][*r*] or *Best*[*l*][*r*] = *Best*[*l*][*m*] + *Best*[*m* + 1][*r*] for some *m*, *l* ≤ *m* < *r*.
+3. *T*[*l*][*r*][*len*]. *len* = 0, *len* = 1 — two special cases, which is easy to solve without any dynamic. In other case, let's take a look on the left-most position. It either will lie in the result string or not. If not, then let's find the first position which does. Denote it as *m* (*l* < *m* ≤ *r*). Everything what lies to the left need to be fully deleted. So the answer is *Full*[*l*][*m* - 1] + *T*[*m*][*r*][*len*] (for *l* < *m* ≤ *r*). Similarly, for the right-most letters. If it does not lies in the result string we remove everything to the right and our result is *T*[*l*][*m*][*len*] + *Full*[*m* + 1][*r*] (for *l* ≤ *m* < *r*). The last option: both left-most and rigth-most letters lies in the result string. It is possible only if *s*[*l*] = *s*[*r*]. So our result is *T*[*l* + 1][*r* - 1][*len* - 2] (only if *s*[*l*] = = *s*[*r*]).
+
+### [150C - Smart Cheater](/contest/150/problem/C "Codeforces Round 107 (Div. 1)")
+
+1. First lets use the linearity of expected value and solve task independently for each passanger.
+2. For each path segment (route between neighboring stations) we calculate expected value of profit in case we do not sell a ticket for this segment. In case we sell it the expectation of profit is 0.
+3. Now we only need to find the subsegment of segment [a, b] of maximal sum for each passanger.
+4. That's easy to do by the segment tree, we only need to calc four values for each node:
+
+best — the maximal sum of elements on some subsegment
+
+max_left — the maximal sum on prefix
+
+max_right — the maximal sum on suffix
+
+sum — the sum of all elements
+
+### [150B - Quantity of Strings](/contest/150/problem/B "Codeforces Round 107 (Div. 1)")
+
+We can offer you two solitions:
+
+1. You can build a graph with positions in sting as a nodes and equality in any substring of length *k* as edges. Lets denote *e* the number of components in the graph. The answer is *m**e*.
+2. Analyze four cases:
+
+ * *k* = 1 or *к* > *n*, the answer is *m**n*.
+ * *k* = *n*, the answer is *m*(*n* + 1) / 2.
+ * *k* mod 2 = 1, any string like abababab... is ok, so the answer is *m*2.
+ * *k* mod 2 = 0, all symbols coincide and the answer is *m*.
+
+### [150A - Win or Freeze](/contest/150/problem/A "Codeforces Round 107 (Div. 1)")
+
+* if *Q* is prime or *Q* = 1 than it's victory.
+* We loose if: *Q* = *p* * *q* or *Q* = *p*2, where *p* and *q* are prime.
+* It is quite obvious that it is always possible to move in bad position in any other case. That means all other numbers grants us the victory.
+
+We only have to check if *Q* has a divisor of the loose type. We can easily do it in *O*(*sqrt*(*Q*)) time.
+
+### [151B - Phone Numbers](/contest/151/problem/B "Codeforces Round 107 (Div. 2)")
+
+In this task you were to implement the described selection of the maximum elements.
+
+### [151A - Soft Drinking](/contest/151/problem/A "Codeforces Round 107 (Div. 2)")
+
+Soda will be enough for *gas* = (*K* * *L*) / (*N* * *l*) toasts.
+
+Limes will last for *laim* = (*C* * *D*) / *N* toasts.
+
+Salt is enough for *sol* = *P* / (*p* * *N*) toasts.
+
+Total result: *res* = *min*(*gas*, *laim*, *sol*).
diff --git a/editorials/151.md b/editorials/151.md
@@ -0,0 +1,83 @@
+Source: https://codeforces.com/blog/entry/3905
+
+### [150E - Freezing with Style](/contest/150/problem/E "Codeforces Round 107 (Div. 1)")
+
+1. If there exists a path with the median ≥ *k*, for some *k*, then there exists a path with the median ≥ *q*, for each *q* ≤ *k*. That means we can use binary search to calculate the answer. So now the task is: is there any path with the median greater or equal to *Mid* ?
+2. We will calc the edge as + 1 if it's wight ≥ *Mid*, or as - 1 in other case. Now we only need to check if there exists a path with legal length and the sum greater than or equal to zero.
+3. Let's denote some node *V* as a root.
+4. All paths can be divided into two types: that contains *v*, and that do not. Now we are to process all first-type paths and run the algorithm on all subtrees. That is so-called divide-and-conquer strategy.
+5. We can trivially show that it is always possible to choose such vertex *v* that all it's subtrees will have size less than or equal to the size of the whole tree. That means that each node will be proccessed in *LogN* trees max.
+6. So, if we solve the task for one level of recursion in *O*(*F*(*N*)), we'll solve it in time *O*(*F*(*N*) * *log*2(*N*)) on the whole.
+7. First, lets get *O*(*N* * *Log*(*N*)). For each node we shall calc it's deepness, cost of the path to the root ans the first edge (the number of the root's subtree). It will be better now to use 2 and 0 as the edges costs, instead of -1 and 1. Now we shall process root's subtrees one by one. For each node we want to know if there exists a node *u* in any other subtree such that the
+
+ Unable to parse markup [type=CF_TEX]
+
+ and *cost*[*v*] - *deep*[*v*] + *cost*[*u*] - *deep*[*u*] ≥ 0. To do that we need to know the maximum of the function (*cost*[*u*] - *deep*[*u*]) with the deep values between max(0, *L* - *deep*[*v*]) and *R* - *deep*[*v*] inclusive. To achieve *O*(*N* * *log*(*N*)) you need only to use segment tree.
+8. To achieve an AC contestants were to write all code optimally, or to think of one more idea. It is possible to have *O*(*N*) on one level of recursion and *O*(*N* * *log*2(*N*)) in total if you sort roots subtrees in non-decreasing order and use any structure that can answer getmax query on all segments of length (*R* - *L* + 1) and all prefixes and suffixes.
+
+Best of luck to you in upsolving this problem!
+
+### [150D - Mission Impassable](/contest/150/problem/D "Codeforces Round 107 (Div. 1)")
+
+In this problem you have to use dynamic programming. For our convenience we will calulate three type of values:
+
+*Best*[*l*][*r*] — best result player can achieve on the segment [*l*, *r*].
+
+*Full*[*l*][*r*] — best result player can achieve on the segment from [*l*, *r*] if he fully destroys it.
+
+*T*[*l*][*r*][*Len*] — best result player can achieve on the segment from [*l*, *r*] and remain the palindrome of length *len* and only it.
+
+Now solution:
+
+1. *Full*[*l*][*r*]. Let's look which move will be the last. This will be removing the palindrome of length *len* and *c*[*len*] ≥ 0. What is the best result we can achieve? *c*[*len*] + *T*[*l*][*r*][*len*].
+2. *Best*[*l*][*r*]. Either we will destroy all subtring from *l* to *r*, either there exists a letter which we did not touch. That means that all our moves lies fully to the left or fully to the rigth to that position. So *Best*[*l*][*r*] = *Full*[*l*][*r*] or *Best*[*l*][*r*] = *Best*[*l*][*m*] + *Best*[*m* + 1][*r*] for some *m*, *l* ≤ *m* < *r*.
+3. *T*[*l*][*r*][*len*]. *len* = 0, *len* = 1 — two special cases, which is easy to solve without any dynamic. In other case, let's take a look on the left-most position. It either will lie in the result string or not. If not, then let's find the first position which does. Denote it as *m* (*l* < *m* ≤ *r*). Everything what lies to the left need to be fully deleted. So the answer is *Full*[*l*][*m* - 1] + *T*[*m*][*r*][*len*] (for *l* < *m* ≤ *r*). Similarly, for the right-most letters. If it does not lies in the result string we remove everything to the right and our result is *T*[*l*][*m*][*len*] + *Full*[*m* + 1][*r*] (for *l* ≤ *m* < *r*). The last option: both left-most and rigth-most letters lies in the result string. It is possible only if *s*[*l*] = *s*[*r*]. So our result is *T*[*l* + 1][*r* - 1][*len* - 2] (only if *s*[*l*] = = *s*[*r*]).
+
+### [150C - Smart Cheater](/contest/150/problem/C "Codeforces Round 107 (Div. 1)")
+
+1. First lets use the linearity of expected value and solve task independently for each passanger.
+2. For each path segment (route between neighboring stations) we calculate expected value of profit in case we do not sell a ticket for this segment. In case we sell it the expectation of profit is 0.
+3. Now we only need to find the subsegment of segment [a, b] of maximal sum for each passanger.
+4. That's easy to do by the segment tree, we only need to calc four values for each node:
+
+best — the maximal sum of elements on some subsegment
+
+max_left — the maximal sum on prefix
+
+max_right — the maximal sum on suffix
+
+sum — the sum of all elements
+
+### [150B - Quantity of Strings](/contest/150/problem/B "Codeforces Round 107 (Div. 1)")
+
+We can offer you two solitions:
+
+1. You can build a graph with positions in sting as a nodes and equality in any substring of length *k* as edges. Lets denote *e* the number of components in the graph. The answer is *m**e*.
+2. Analyze four cases:
+
+ * *k* = 1 or *к* > *n*, the answer is *m**n*.
+ * *k* = *n*, the answer is *m*(*n* + 1) / 2.
+ * *k* mod 2 = 1, any string like abababab... is ok, so the answer is *m*2.
+ * *k* mod 2 = 0, all symbols coincide and the answer is *m*.
+
+### [150A - Win or Freeze](/contest/150/problem/A "Codeforces Round 107 (Div. 1)")
+
+* if *Q* is prime or *Q* = 1 than it's victory.
+* We loose if: *Q* = *p* * *q* or *Q* = *p*2, where *p* and *q* are prime.
+* It is quite obvious that it is always possible to move in bad position in any other case. That means all other numbers grants us the victory.
+
+We only have to check if *Q* has a divisor of the loose type. We can easily do it in *O*(*sqrt*(*Q*)) time.
+
+### [151B - Phone Numbers](/contest/151/problem/B "Codeforces Round 107 (Div. 2)")
+
+In this task you were to implement the described selection of the maximum elements.
+
+### [151A - Soft Drinking](/contest/151/problem/A "Codeforces Round 107 (Div. 2)")
+
+Soda will be enough for *gas* = (*K* * *L*) / (*N* * *l*) toasts.
+
+Limes will last for *laim* = (*C* * *D*) / *N* toasts.
+
+Salt is enough for *sol* = *P* / (*p* * *N*) toasts.
+
+Total result: *res* = *min*(*gas*, *laim*, *sol*).
diff --git a/editorials/152.md b/editorials/152.md
@@ -0,0 +1,96 @@
+Source: https://codeforces.com/blog/entry/3926
+
+#### [152A - Marks](/contest/152/problem/A "Codeforces Round 108 (Div. 2)")
+
+In this problem you should do exactly what is written in the statement. Here is rough code of solution:
+
+```
+for (int i = 0; i < n; ++i){
+ bool wasBest = false;
+ for(int j = 0; j < m; ++j){
+ bool isBest = true;
+ for(int k = 0; k < n; ++k)
+ if(a[k][j] > a[i][j])
+ isBest = false;
+ if(isBest)
+ wasBest = true;
+ }
+ if(wasBest)
+ ans++;
+}
+```
+
+#### [152B - Steps](/contest/152/problem/B "Codeforces Round 108 (Div. 2)")
+
+Let's find a formula for the position (*x*, *y*) and vector (*dx*, *dy*), how many steps to stop the boy can do. You should use "almost" binary search, for example, see the code written by [RAD](/profile/RAD "Candidate Master RAD").
+
+```
+for (long long cof = 1100000000; cof; cof /= 2)
+ while (onField(xc + cof * dx, yc + cof * dy)) {
+ xc = xc + cof * dx;
+ yc = yc + cof * dy;
+ ans += cof;
+ }
+```
+
+#### [152C - Pocket Book](/contest/152/problem/C "Codeforces Round 108 (Div. 2)")
+
+In this task, it was necessary to understand that in position 1 Vasya can get any name of a special form. More exactly, it's the name of form *s* = *s*1 *s*2 *s*3 *s*4 ... *s**m*, where *s*1 — the first letter of any of the names, *s*2 — the second letter of any of the names, ... *s**m* — *m*-th letter of any of the names. Then the answer to the problem is the product of *cnt**i* (1 ≤ *i* ≤ *m*), where *cnt**i* is a number of different letters in the names placed in position *i*.
+
+#### [152D - Frames](/contest/152/problem/D "Codeforces Round 108 (Div. 2)")
+
+It was necessary to understand if there are two borders or not.
+
+Let's distinguish those *x* — and *y*-coordinates, in which there are at least 3 consecutive symbols '#', becouse the length of each border is no less then 3. It is clear that the coordinates of the corners of borders should be chosen only from those selected *x* and *y*. In general, the various selected *x* no more then 4 and various selected *y* no more then 4.
+
+Except that case when the height or width of the first border is 3, and length of the second side of this border is more than 3, and one side of the second border fills a part of the inside first at least.
+
+For example:
+
+```
+#######
+#######
+#######
+#.....#
+#######
+```
+
+The first border:
+
+```
+#######
+#.....#
+#######
+.......
+.......
+```
+
+The second border:
+
+```
+.......
+#######
+#.....#
+#.....#
+#######
+```
+
+There are 7 different *y*-coordinates in the example.
+
+Carefully processed these cases separately, it is quite simple. (Let's choose 4 *y*-coordinates: minimum, maximum, second minimum and second maximum).
+
+Otherwise, if the amount selected *x* — and *y*-coordinates no more then 4, then let's choose opposite corners of the first and second borders and verify that the selected borders — the correct borders and there are no other characters '#'. Checking is carried out at *O*(*n* + *m*) or *O*(1) (using partial sums).
+
+#### [152E - Garden](/contest/152/problem/E "Codeforces Round 108 (Div. 2)")
+
+The solution of this problem is based on dynamic programming. *dp*[*mask*][*v*] — the value of the minimum correct concrete cover, if we consider as important elements only elements of the mask *mask*, and there are additionally covered the vertex *v* = (*i*, *j*) of the field.
+
+There are two types of transfers.
+
+First of all we can, as if to cut coverage on the vertex *v*. Then you need to go through subpattern of vertex *submask*, which will go to the left coverage and make an optimizing transfer. Update *dp*[*mask*][*v*] with the value *dp*[*submask*][*v*] + *dp*[*mask* ^ *submask*][*v*] - *cost*(*v*).
+
+Second, perhaps in the vertex *v* in the optimal coverage mask *mask*, which covers the vertex *v*, you can not make the cut separating the set of vertices. In this case, this vertex forms something a kind of <>. And there a vertex *u* exists, on which we can make the cut, with the whole shortest path from a vertex *u* to *v* belongs to the optimal coverage. Let's precalculate the shortest paths between all pairs of cells. Now to make this transition, we should count the value of dynamics *dp*[*mask*][*v*] for all vertices *v* only on the basis of the first transition. Now you can make the second transition. For all *u*, *dp*[*mask*][*v*], update the value of *dp*[*mask*][*u*] + *dist*(*v*, *u*) - *cost*(*u*).
+
+Let's process separately state in which exactly one bit in the mask, and the vertex which corresponding to this bit is equal to *v*. In this case the answer is equal to *cost*(*v*), of course.
+
+Thus, each solution is obtained for the *O*(*min*(3*k*·*n*·*m*, 2*k*·(*n*·*m*)2)).
diff --git a/editorials/153.md b/editorials/153.md
@@ -0,0 +1,90 @@
+Source: https://codeforces.com/blog/entry/3948
+
+Here goes a review of the problems. I tried to set them so that each of them shows a certain aspect of the language — a commonly used verb or a specific feature. Once it was recognized and found, the solution should become evident.
+
+#### [153A - A + B](/contest/153/problem/A "Surprise Language Round 5")
+
+Let me note right away that the sample code provided in the blog post does work both in Custom test and in ideone (as well as locally), as long as the numbers are written one per line and (attention!) each of them, including the last one, is followed by the end-of-line character. The last '\n' is not shown in the tests, but it is there, and COBOL minds it. All test cases at Codeforces are generated with this in mind, so there should be no problems like this when the code is submitted.
+
+The most evident COBOL feature is storing numbers in decimal notation, with width set by the programmer. In this case we focused on the fact that by default the number is printed in a fixed-width way, padded with leading zeros if needed. These zeros where what you needed to get rid of. The reference solution transformed the sum of numbers into a string with leading zeros and removed the zeros. To do this, the zeros had to be counted — most likely using the verb INSPECT ... TALLYING which calculates the characters of the string which correspond to the given condition and adds their number to the given variable. The sample A+B code needed only a couple more lines:
+
+```
+ 01 ZEROSCOUNT PIC 99.
+ 01 SUMSTRING PIC X(10).
+
+ MOVE SUM TO SUMSTRING
+ MOVE 1 TO ZEROSCOUNT
+ INSPECT SUMSTRING TALLYING ZEROSCOUNT FOR LEADING "0"
+ DISPLAY SUMSTRING(ZEROSCOUNT:11 - ZEROSCOUNT)
+```
+
+In COBOL string characters and array elements are indexed starting with 1, so the initial value of ZEROSCOUNT must be set to 1.
+
+This problem could be done much easier: declare a variable C of type z(10)9, move the sum into it and just DISPLAY it — this format pads the number to the required width with spaces instead of zeros, and Codeforces checker ignored spaces.
+
+#### [153B - Binary notation](/contest/153/problem/B "Surprise Language Round 5")
+
+The next problem combines two important elements of the language — the verb PERFORM UNTIL, used for loops organization, and string concatenation verb STRING. The condition of loop end is simply N EQUAL 0. STRING arguments are complemented by DELIMITED BY clause which defines the part of the string used in concatenation. Two main modes are DELIMITED BY SIZE (all variable regardless of how much it is filled) and DELIMITED BY SPACE (part of the variable until the first space or the end of the filled part). The current binary digit can be stored in a variable of size 1 and use it as DELIMITED BY SIZE, while the current binary notation should better be DELIMITED BY SPACE (though this would be more important if the digit was appended to the end of the notation, not the other way round).
+
+The main loop of the program is (yes, you could write the code not in uppercase :-)):
+
+```
+ perform until n equal 0
+ divide n by 2 giving n remainder digit
+ move digit to binary_digit
+ string binary_digit delimited by size
+ binary_number delimited by space
+ into str
+ move str to binary_number
+ end-perform.
+```
+
+#### [153C - Caesar Cipher](/contest/153/problem/C "Surprise Language Round 5")
+
+This problem allowed two main approaches. The first one is more typical for programming contests — iterate through the string and process each character separately. The reference solution used the second one, based on yet another COBOL verb INSPECT ... CONVERTING. It allows to iterate through the string replacing the characters which belong to the first argument with corresponding characters from the second one. Encoding with a fixed key would become a one-liner, for example, for ROT-13
+
+```
+inspect cipher
+ converting 'ABCDEFGHIJKLMNOPQRSTUVWXYZ'
+ to 'NOPQRSTUVWXYZABCDEFGHIJKLM'
+```
+
+but this would be boring, wouldn't it? So you had to construct the second argument beforehand — either char-by-char or by cutting the alphabet string in one place and swapping the parts.
+
+#### [153D - Date Change](/contest/153/problem/D "Surprise Language Round 5")
+
+Of course this problem can be solved by hand — split the date into day, month and year and add/subtract one day per iteration for the required number of times. But COBOL has its special functions for this very case — INTEGER-OF-DATE (convert date from YYYYMMDD format to the number of days elapsed since December 31st, 1600) and its inverse DATE-OF-INTEGER. All you have to do is to convert the input data to YYYYMMDD format, convert it to integer, add shift to it and repeat the process in the opposite direction.
+
+#### [153E - Euclidean Distance](/contest/153/problem/E "Surprise Language Round 5")
+
+The last problem of the round required working with arrays, called tables in COBOL. The hardest thing about them is figuring out the declaration format. My data structure looked like this:
+
+```
+ 01 n pic 99.
+ 01 points.
+ 02 occurs 2 to 50 times depending on n.
+ 03 x pic S999.
+ 03 y pic S999.
+```
+
+S character in integer declaration means that is can take negative values — otherwise the minus sign is just dropped. DEPENDING ON N means that the array is automatically resized to contain exactly N elements. Referencing array elements is very simple — x(i) и y(i).
+
+The double loop can be organized in several ways, the easiest of them is using an inner loop:
+
+```
+ perform varying i from 1 by 1 until i > n
+ perform varying j from i by 1 until j > n
+ compute dx = x(i) - x(j)
+ compute dy = y(i) - y(j)
+ compute d = dx * dx + dy * dy
+ if d > maxd
+ move d to maxd
+ end-perform
+ end-perform.
+```
+
+Finally, the last language element used is the call of the library function SQRT:
+
+```
+ display function sqrt(maxd)
+```
diff --git a/editorials/154.md b/editorials/154.md
@@ -0,0 +1,63 @@
+Source: https://codeforces.com/blog/entry/3969
+
+[155A - I_love_\%username\%](/contest/155/problem/A "Codeforces Round 109 (Div. 2)")
+
+You should do what is written: go through the sequence and count the elements which are greater or less than all of its predecessors. We don't even have to store the whole sequence, just the current minimum and maximum. Complexity — O(N), but squared still works fine.
+
+[155B - Combination](/contest/155/problem/B "Codeforces Round 109 (Div. 2)")
+
+Clearly, we can play the cards with *b**i* > 0 first as each of them gives at least one extra move. After that, the number of extra moves left doesn't depend on the order of playing. The left cards all have *b**i* = 0, so we play those of them which have larger *a**i*. Simpler version of this solution: sort all the cards by decrease of *b**i*, if equal — by decrease of *a**i*, and then go through the sorted array from beginning to end, simulate the counter and sum up the points. Remember not to fall over the edge of array if the sum of *b**i*'s is larger than the number of cards. Complexity — O(n log n) (or O(n^2), if using bubblesort, which is still accepted).
+
+[155C - Hometask](/contest/155/problem/C "Codeforces Round 109 (Div. 2)")
+
+[154A - Hometask](/contest/154/problem/A "Codeforces Round 109 (Div. 1)")
+
+Constriction saying that no letter occurs in more than one forbidden pair lets us to use the greedy solution. Without the constriction the problem is quite hard.
+
+Let's look at all occurences of letters from some pair. They form several continuous substrings divided by some other letters. We can note that in optimal solution the substrings cannot merge, 'cause we can leave at least one letter in each of such parts. So, for each of these substrings problem is solved independently. To resolve conflicts within a substring, one has to remove all letters of some kind, 'cause while there are letters of both kinds there will be conflicts. Clearly, from each continuous substring of forbidden letters we remove all letters of the kind which number is less than another.
+
+The answer can be counted in O(kN) with k runs through the string.
+
+[155D - Colliders](/contest/155/problem/D "Codeforces Round 109 (Div. 2)")
+
+[154B - Colliders](/contest/154/problem/B "Codeforces Round 109 (Div. 1)")
+
+The clueless solution ''store all the enabled numbers and compare each new number with each of them'' works too slow, as we can add all the prime numbers below *n*, number of which is O(n / log n).
+
+We can note that for each number k > 1 at any time no more than one collider is turned on which number is divided by k. Let us store an array which has in k-th element the number of turned-on collider which is divided by k, on 0 if there is no such at the moment. To enable the collider with number q we can look over q's divisors and check whether all the array's elements with these numbers have 0's. If some of them has a positive integer, that's the number of collider we conflict with — we can just print it and go on. Otherwise, we have to put q into all the overlooked elements.
+
+This works in O(M sqrt(N) + N). There's faster solution as we can store all of the above only for prime divisors. Total size of the prime divisors list for number from 1 to N is O(N log log N). Thus we have a solution with complexity O(N log log N + M log N), as the number of prime divisors of k doesn't exceed log k (exact upper bound — log k / log log k * (1 + o(1)).
+
+[155E - Double Profiles](/contest/155/problem/E "Codeforces Round 109 (Div. 2)")
+
+[154C - Double Profiles](/contest/154/problem/C "Codeforces Round 109 (Div. 1)")
+
+We want to count the number of pairs of vertices in a undirected graph which neighbours' sets are equal up to these vertices. To count the pairs which sets of neighbours are equal we can hash these sets (for instance, count the polynomial hash of adjacency matrix row) and sort the hashes. Than we have to add the pairs of doubles which have an edge between them.
+
+We can note that there are no more such pairs than there are edges in the graph. So we can iterate through edges and check hashes for equivalence considering the presence of the edge (in case of polynomial hash we just add some degrees to them and then compare them). Other solution was to count another version of the previous hash, now adding a loop to each vertex, and to count the number of pairs just like in the previous case.
+
+Moreover, we could try and sort the whole lists of adjacencies (which previuosly should be sorted too). As their total size is 2M, this works fine too, but needs an accurate realization. Hash solution complexity — O(N log N + M).
+
+[154D - Flatland Fencing](/contest/154/problem/D "Codeforces Round 109 (Div. 1)")
+
+As the moves choices are symmetrical for both players, if one player can reach another in one move from some disposition, the other player also can reach the first. So, if we are allowed to stand in one place (i.e. a <= 0 <= b), we can just stand still and wait for another player to come. If she wants to win, she will have to step within our reach before that so that we can get her. So, if the first player doesn't reach the second initially, there is a draw as no one can ensure her victory. Thus we finished the case a <= 0 <= b: either the first player wins in one move, or there is a draw.
+
+Now, let a and b have the same sign. Denote d = x2 — x1. If a <= b < 0, we can go to the situation with (d, a, b) = (-d, -b, -a), which is similar to the initial. So later on 0 < a.
+
+So we have the following game: there are integers d and 0 < a <= b. In one move each player can substract an arbitrary integer number from segment [a; b] from d. The player who gets d = 0 after her move wins. If at some point d < 0, a draw is proclaimed (as no one can win anymore).
+
+The interesting case is d > 0. Note that if d mod (a + b) = 0, the second player can use the symmetrical strategy: for every first player's move x of she can make a move a + b — x, and support the condition d mod (a + b) = 0. As d decreases, the second player eventually moves to 0 and wins. So, if d mod (a + b) = 0, the second player wins. Thus, if d mod (a + b) is in [a; b], the first player wins, as he can reduce the game to the previous case by letting the second player move in the losing situation.
+
+What about all the other situations? Turns out all the other position are draws. We prove that by induction: let d = k(a + b) + l, where l in [0; a + b). Case l = 0, as we just proved, is losing, cases l in [a; b] are winning. If l is in [1; a — 1], we cannot move to losing position (we use the induction assumption for lesser k), but after the move a, we move to the draw position (if k = 0, we move to the negative number, otherwise we get into [(k — 1)(a + b) + b + 1; k(a + b) — 1] segment, every position from which is a draw by assumption). Similarily for l = [b + 1; a + b — 1], move to a draw — b.
+
+[154E - Martian Colony](/contest/154/problem/E "Codeforces Round 109 (Div. 1)")
+
+We have to find the area of intersection of all circles containing the given set of points (it's clear that the intersection has the least area, and we have an unlimited number of circles). First, what shape does such an intersection have? Its border contains some circle arcs of radius R meeting at some points of convex hull. If we determine which points are present in the border, we can count the total area as the sum of polygon area and several circle segments.
+
+So, how to determine those points? It's clear that if there is a circle of radius R containing all the points and having some of them on its border, then this particular point is present in the border of the intersection. If we fix the circle and move it in some direction, it eventually will run into some point — so we can find at least one point. Then we can perform something similar to ''present wrapping'' — go around the convex hull and support the set of the border points while controlling the relative position of the arcs. While this solution is fast, it is very hard to write and it was not assumed that it should be written during the contest.
+
+There is much simpler solution based on quite different idea. We build the convex hull of the set so that no three points lie on the same line. Let us take the very large R so that every point of convex hull is present in the intersection border. As we gradually decrease R, some points will start to disappear from the border. How to determine which point falls out first? For point u in the convex hull denote its left and right neighbours l(u) and r(u). It's clear, that the first point to disappear will be such point u which has the largest radius of circle going through u, l(u) and r(u) (when R becomes equal to this radius, two arcs will merge into one in point u, while all the other will have joints in them; we will call this radius critical for u). Then we remove u from convex hull and do not take it into account. We repeat while the largest critical radius is larger than R. The rest points will be exactly the points forming the border.
+
+How to do this fast? Note that when we remove some point from the set the critical radii will change only for its two neighbours. Let us store a priority queue containing critical radii along with point numbers. On every iteration we extract the largest critical radius, remove the corresponding point from the set, and refresh the information about the neighbours in the queue. We repeat while the largest radius is greater than R. As we just simulate the process of R decreasing, everything works correctly. The complexity of this procedure is O(n log n), as we have no more than n iterations and on every iteration we perform the constant number of operations with the queue of size at most n.
+
+There is an unclear case, when the border contains only two points. Then on the last phase we have three points in the set and the algorithm doesn't have a clue which one to remove as they have equal critical radii. But we know that the triangle with vertices in these points is obtuse-angled, as we cannot shrink the circumcircle of an acute-angle triangle, as that would contradict with the circle existence condition. So we have to remove the point with the obtuse angle.
diff --git a/editorials/155.md b/editorials/155.md
@@ -0,0 +1,63 @@
+Source: https://codeforces.com/blog/entry/3969
+
+[155A - I_love_\%username\%](/contest/155/problem/A "Codeforces Round 109 (Div. 2)")
+
+You should do what is written: go through the sequence and count the elements which are greater or less than all of its predecessors. We don't even have to store the whole sequence, just the current minimum and maximum. Complexity — O(N), but squared still works fine.
+
+[155B - Combination](/contest/155/problem/B "Codeforces Round 109 (Div. 2)")
+
+Clearly, we can play the cards with *b**i* > 0 first as each of them gives at least one extra move. After that, the number of extra moves left doesn't depend on the order of playing. The left cards all have *b**i* = 0, so we play those of them which have larger *a**i*. Simpler version of this solution: sort all the cards by decrease of *b**i*, if equal — by decrease of *a**i*, and then go through the sorted array from beginning to end, simulate the counter and sum up the points. Remember not to fall over the edge of array if the sum of *b**i*'s is larger than the number of cards. Complexity — O(n log n) (or O(n^2), if using bubblesort, which is still accepted).
+
+[155C - Hometask](/contest/155/problem/C "Codeforces Round 109 (Div. 2)")
+
+[154A - Hometask](/contest/154/problem/A "Codeforces Round 109 (Div. 1)")
+
+Constriction saying that no letter occurs in more than one forbidden pair lets us to use the greedy solution. Without the constriction the problem is quite hard.
+
+Let's look at all occurences of letters from some pair. They form several continuous substrings divided by some other letters. We can note that in optimal solution the substrings cannot merge, 'cause we can leave at least one letter in each of such parts. So, for each of these substrings problem is solved independently. To resolve conflicts within a substring, one has to remove all letters of some kind, 'cause while there are letters of both kinds there will be conflicts. Clearly, from each continuous substring of forbidden letters we remove all letters of the kind which number is less than another.
+
+The answer can be counted in O(kN) with k runs through the string.
+
+[155D - Colliders](/contest/155/problem/D "Codeforces Round 109 (Div. 2)")
+
+[154B - Colliders](/contest/154/problem/B "Codeforces Round 109 (Div. 1)")
+
+The clueless solution ''store all the enabled numbers and compare each new number with each of them'' works too slow, as we can add all the prime numbers below *n*, number of which is O(n / log n).
+
+We can note that for each number k > 1 at any time no more than one collider is turned on which number is divided by k. Let us store an array which has in k-th element the number of turned-on collider which is divided by k, on 0 if there is no such at the moment. To enable the collider with number q we can look over q's divisors and check whether all the array's elements with these numbers have 0's. If some of them has a positive integer, that's the number of collider we conflict with — we can just print it and go on. Otherwise, we have to put q into all the overlooked elements.
+
+This works in O(M sqrt(N) + N). There's faster solution as we can store all of the above only for prime divisors. Total size of the prime divisors list for number from 1 to N is O(N log log N). Thus we have a solution with complexity O(N log log N + M log N), as the number of prime divisors of k doesn't exceed log k (exact upper bound — log k / log log k * (1 + o(1)).
+
+[155E - Double Profiles](/contest/155/problem/E "Codeforces Round 109 (Div. 2)")
+
+[154C - Double Profiles](/contest/154/problem/C "Codeforces Round 109 (Div. 1)")
+
+We want to count the number of pairs of vertices in a undirected graph which neighbours' sets are equal up to these vertices. To count the pairs which sets of neighbours are equal we can hash these sets (for instance, count the polynomial hash of adjacency matrix row) and sort the hashes. Than we have to add the pairs of doubles which have an edge between them.
+
+We can note that there are no more such pairs than there are edges in the graph. So we can iterate through edges and check hashes for equivalence considering the presence of the edge (in case of polynomial hash we just add some degrees to them and then compare them). Other solution was to count another version of the previous hash, now adding a loop to each vertex, and to count the number of pairs just like in the previous case.
+
+Moreover, we could try and sort the whole lists of adjacencies (which previuosly should be sorted too). As their total size is 2M, this works fine too, but needs an accurate realization. Hash solution complexity — O(N log N + M).
+
+[154D - Flatland Fencing](/contest/154/problem/D "Codeforces Round 109 (Div. 1)")
+
+As the moves choices are symmetrical for both players, if one player can reach another in one move from some disposition, the other player also can reach the first. So, if we are allowed to stand in one place (i.e. a <= 0 <= b), we can just stand still and wait for another player to come. If she wants to win, she will have to step within our reach before that so that we can get her. So, if the first player doesn't reach the second initially, there is a draw as no one can ensure her victory. Thus we finished the case a <= 0 <= b: either the first player wins in one move, or there is a draw.
+
+Now, let a and b have the same sign. Denote d = x2 — x1. If a <= b < 0, we can go to the situation with (d, a, b) = (-d, -b, -a), which is similar to the initial. So later on 0 < a.
+
+So we have the following game: there are integers d and 0 < a <= b. In one move each player can substract an arbitrary integer number from segment [a; b] from d. The player who gets d = 0 after her move wins. If at some point d < 0, a draw is proclaimed (as no one can win anymore).
+
+The interesting case is d > 0. Note that if d mod (a + b) = 0, the second player can use the symmetrical strategy: for every first player's move x of she can make a move a + b — x, and support the condition d mod (a + b) = 0. As d decreases, the second player eventually moves to 0 and wins. So, if d mod (a + b) = 0, the second player wins. Thus, if d mod (a + b) is in [a; b], the first player wins, as he can reduce the game to the previous case by letting the second player move in the losing situation.
+
+What about all the other situations? Turns out all the other position are draws. We prove that by induction: let d = k(a + b) + l, where l in [0; a + b). Case l = 0, as we just proved, is losing, cases l in [a; b] are winning. If l is in [1; a — 1], we cannot move to losing position (we use the induction assumption for lesser k), but after the move a, we move to the draw position (if k = 0, we move to the negative number, otherwise we get into [(k — 1)(a + b) + b + 1; k(a + b) — 1] segment, every position from which is a draw by assumption). Similarily for l = [b + 1; a + b — 1], move to a draw — b.
+
+[154E - Martian Colony](/contest/154/problem/E "Codeforces Round 109 (Div. 1)")
+
+We have to find the area of intersection of all circles containing the given set of points (it's clear that the intersection has the least area, and we have an unlimited number of circles). First, what shape does such an intersection have? Its border contains some circle arcs of radius R meeting at some points of convex hull. If we determine which points are present in the border, we can count the total area as the sum of polygon area and several circle segments.
+
+So, how to determine those points? It's clear that if there is a circle of radius R containing all the points and having some of them on its border, then this particular point is present in the border of the intersection. If we fix the circle and move it in some direction, it eventually will run into some point — so we can find at least one point. Then we can perform something similar to ''present wrapping'' — go around the convex hull and support the set of the border points while controlling the relative position of the arcs. While this solution is fast, it is very hard to write and it was not assumed that it should be written during the contest.
+
+There is much simpler solution based on quite different idea. We build the convex hull of the set so that no three points lie on the same line. Let us take the very large R so that every point of convex hull is present in the intersection border. As we gradually decrease R, some points will start to disappear from the border. How to determine which point falls out first? For point u in the convex hull denote its left and right neighbours l(u) and r(u). It's clear, that the first point to disappear will be such point u which has the largest radius of circle going through u, l(u) and r(u) (when R becomes equal to this radius, two arcs will merge into one in point u, while all the other will have joints in them; we will call this radius critical for u). Then we remove u from convex hull and do not take it into account. We repeat while the largest critical radius is larger than R. The rest points will be exactly the points forming the border.
+
+How to do this fast? Note that when we remove some point from the set the critical radii will change only for its two neighbours. Let us store a priority queue containing critical radii along with point numbers. On every iteration we extract the largest critical radius, remove the corresponding point from the set, and refresh the information about the neighbours in the queue. We repeat while the largest radius is greater than R. As we just simulate the process of R decreasing, everything works correctly. The complexity of this procedure is O(n log n), as we have no more than n iterations and on every iteration we perform the constant number of operations with the queue of size at most n.
+
+There is an unclear case, when the border contains only two points. Then on the last phase we have three points in the set and the algorithm doesn't have a clue which one to remove as they have equal critical radii. But we know that the triangle with vertices in these points is obtuse-angled, as we cannot shrink the circumcircle of an acute-angle triangle, as that would contradict with the circle existence condition. So we have to remove the point with the obtuse angle.
diff --git a/editorials/156.md b/editorials/156.md
@@ -0,0 +1,128 @@
+Source: https://codeforces.com/blog/entry/4005
+
+## A (Div2) Результат игры
+
+В этой игре можно было просто сделать, то, что просят в условии.А именно, завести счётчик, перебрать все клетки поля, и для каждой клетки найти сумму чисел в клетках, стоящих с ней на одной горизонтали, сумму чисел в клетках, стоящих с ней на одной вертикали, и сравнить эти суммы. Если сумма по вертикали больше, увеличить счётчик на один. После того, как перебраны все клетки, вывести счётчик. Максимальная сумма может быть 2 × 30 × 100 = 6 000, поэтому для её достаточно типа *int*.
+
+## B (Div2) След
+
+Извиняюсь за кривой
+
+Давайте для начала отсортируем радиусы окружностей по убыванию. Пусть у нас теперь радиус первой окружности — *r*1, второй окружности — *r*2, ..., последней окружности — *r**n*, где *r*1 > *r*2 > ... > *r**n*. Внешняя область — так, которая снаружи первой окружности — покрашена в синий цвет, значит, область между первой и второй окружностью покрашена в красный. Далее, область между второй и третьей окружностью покрашена в синий цвет, между третьей и четвёртой — в красный, между четвёртой и пятой — в синий, и так далее.
+
+Первая область, закрашенная в красный цвет (область между первой и второй окружностями) — это вся область внутри первой окружности, из которой выкинули внутреннюю область второй окружности. Значит, площадь это области равна π × (*r*12 - *r*22). Аналогично, площадь второй красной области (между третьей и четвёртой окружностями) равна π × (*r*32 - *r*42). И так далее. Значит, суммарная их площадь равна π × (*r*12 - *r*22 + *r*32 - *r*42 + *r*52 - *r*62 + ...). Значит, чтобы посчитать ответ можно, например, сложить квадраты радиусов окружностей с нечётным номером, вычесть из полученной суммы квадраты радиусов всех окружностей с чётными номерами, и полученную величину умножить на \pi.
+
+Может возникнуть небольшое затруднение с последней окружностью. Если число окружностей нечётно, то последняя область — не кольцо между двумя окружностями, а круг. Но это, на самом деле, ничего не меняет: тогда последняя окружность имеет нечётный номер, и квадрат её радиуса надо тоже прибавить к сумме.
+
+## A (Div1) — C (Div2) Сообщение
+
+Для начала, добавим к строке *s* с обоих концов по 2000 фиктивному символу — например, <<#>>. Заметим, что это не повлияло на ответ. Действительно, пусть мы взяли подстроку *t*, частично или полностью состоящую из <<#>>. Тогда все символы <<#>> надо было бы заменить. Но если бы их просто не было, то нужные символы надо было бы добавить.
+
+Рассмотрим оптимальную подстроку *t*, и последовательность действий, которую надо с ней сделать, чтобы превратить её в строку *u*. Рассмотрим первое добавление или удаление символа с одного из концов.
+
+Заметим, что это не удаление. Ведь если мы выбрали подстроку *t* и удалили из неё, к примеру, последний символ, то его не надо было бы и брать, потому что для строки *t* без последнего символа надо на одно действие меньше, чем для всей строки *t*.
+
+А теперь заметим, что это и не добавление. Действительно, пусть мы рассмотрели строку *t*, некоторое время меняли в ней символы на другие, и наконец, добавили один, скажем, в начале. Тогда - Если слева от строки есть символ (то есть, строка там ещё не кончается), то можно было его взять сразу (то есть, рассмотреть не *t*, а *t* с ещё одним символом слева). Вместо того, чтобы добавлять символ, можно заменить существующий — это тоже занимает одной действие. - Если слева от строки нету символа (то есть, первый символ *t* является первым символом строки *s*), тогда в *t* есть как минимум 2000 <<#>>. Значит, либо ответ для такой строки как минимум 2000, потому что каждую решётку надо удалить или заменить; либо никаких символов, кроме решёток, в строке *t* нет, и тогда надо сделать как минимум |*u*| действий, потому что каждый символ *u* надо добавить (или сделать из другого символа). Но чтобы получить всего |*u*| действий, достаточно взять любую подстроку длины |*u*|.
+
+Таким образом, существует оптимальная подстрока *t*, из которой получается *u* без добавлений и удалений. Это ключевой момент решения! Ведь это означает, что длина такой строки равна длине *u*. Значит, достаточно перебрать подстроки строки *s* длины |*u*|. Всего таких подстрок *O*(|*s*|), и для каждой подстроки легко за время *O*(|*u*|) посчитать необходимое количество изменений — это просто количество символов, которые надо заменить.
+
+Таким образом, получается очень простое в написании решение за время *O*(|*s*| × |*u*|).
+
+## B (Div1) — D (Div2) Подозреваемые
+
+Будем называть людей, которые сказали <<Убийство совершил подозреваемый номер *a**i*>> *обвиняющими*, а людей, которые сказали <<Подозреваемый номер *a**i* не совершал убийства>> — *оправдывающими*. Рассмотрим подозреваемого номер *k*. Предположим, что он совершил убийство и посчитаем, сколько тогда человек сказали правду. Люди, которые сказали правду — это люди, которые обвиняли *его*, и люди, которые оправдывали *не его*. Таким образом, их количество — это количество людей, которые обвинили его, плюс количество людей, которые оправдали *кого-либо*, и минус количество людей, которые оправдали *его*. Таким образом, нам надо знать - количество людей, которые кого-либо обвиняют (это легко посчитать за *O*(*n*)) - для каждого подозреваемого количество людей которые его обвиняют - для каждого подозреваемого количество людей которые его оправдывают Последние две величины легко посчитать за время *O*(*n*) для всех подозреваемых. Действительно, пусть *i*-того человека обвиняют *x**i* людей и оправдывают *y**i* людей. Тогда надо просто для каждого человека номер *i*, если он оправдывающий, то увеличить *y**a**i*, а если обвиняет — увеличить *x**a**i*.
+
+После этих действий можно за *O*(1) посчитать для каждого подозреваемого число людей, которые говорят правду в том случае, если он преступник, и если это количество равно *m*, то данный человек может быть преступником. А после того, как мы нашли список возможных преступников, то не составляет труда для каждого человека определить, может ли он говорить правду и может ли он врать.
+
+## С (Div1) — E (Div2) Шифр
+
+Давайте в словах записывать вместо букв цифры: вместо <> — 0, вместо <**> — 1, и так далее. Тогда разрешенные операции такие: рассмотреть два соседних числа, и одно из них увеличить на один, а другое — уменьшить на один. Для начала докажем ключевое утверждение задачи: *два слова имеют одинаковый смысл тогда и только тогда, когда у них одинаковая длина и одинакова сумма букв*.**
+
+Я мог бы привести полное и строгое доказательство этого факта, но оно будет длинным и немного занудным и, думается мне, его вряд ли кто-нибудь будет читать. Лучше я просто опишу две переформулировки задачи, в которых этого утверждение становится более очевидным.
+
+**1.** Переформулировка первая. Представим себе, что у нас вместо каждого числа — стопка монет, от 0 до 25 штук. Тогда разрешенные действия — это переложить одну монету из какой-то стопки в соседнюю так, чтобы во всех стопках оставалось от 0 до 25 монет.
+
+**2.** Переформулировка вторая. Рассмотрим последовательность *s**i* (*i* = 0, ..., *n*), такую, что *s**i* равно сумме первых *i* чисел в слове. Последовательность неубывает и разность между соседними элементами последовательности не превосходит 25. Тогда разрешенная операция — это изменить одно из чисел на один в любую сторону, так, чтобы разность между любыми двумя соседними числами по-прежнему не превосходила 25, и последовательность по-прежнему неубывала.
+
+Таким образом, нам надо посчитать, сколько слов такой же длинны имеют такую же сумму букв. Это легко сделать сразу для всех слов длины не больше 100. Посчитаем с помощью динамики такую величину *x*[*l*][*s*] : количество слов длины *l* с суммой букв *s*. - База динамики: *l* = 0. Есть ровно одно слово (пустое, оно же единственное слово длины 0) с суммой букв 0, и по 0 слов с любой другой суммой букв. - Переход динамики: очень простой. Чтобы узнать, сколько слов длины *l* имеют сумму *s*, надо перебрать, какая может быть последняя буква у этого слова: *x*[*l*][*s*] = *x*[*l* - 1][*s*] + *x*[*l* - 1][*s* - 1] + ... + *x*[*l* - 1][*s* - 25]. Конечно, надо не забыть считать эту величину по модулю 109 + 7.
+
+После того, как мы посчитали эту величину для всех 0 ≤ *l* ≤ 100, 0 ≤ *s* ≤ 2500 за *O*(1002 × 25) памяти и *O*(1002 × 252) времени, надо просто для каждого слова найти его длину сумму букв и вывести ответ (не забыв вычесть 1).
+
+## D (Div1) Улики
+
+### Как придумать формулу
+
+Простите все, кому это непривычно, но поскольку интерпретатор ТеХа на Codeforces в данный момент несколько кривоват, вместо традиционных нижних индексов будут нетрадиционные верхние. Это не степени, о степенях я буду оповещать отдельно.
+
+Говоря математическим языком, в задаче надо посчитать количество способов дополнить граф до связного минимальным количеством ребер. Понятно, что сам граф не имеет значения — важны только компоненты связности. Более того, сами компоненты связности не важны, важны только их размеры.
+
+Итак, пусть у нас есть *k* компонент связности размера *s*1, *s*2, ..., *s**k*.Посмотрим, чем равна искомая величина для маленьких *k*.
+
+Пусть *k* = 1. Тогда граф уже связный, есть 1 способ добавить ноль ребер.
+
+Пусть *k* = 2. Тогда в графе две компоненты связности и надо добавить одно ребро между ними. Существует *s*1 способ выбрать вершину из первой компоненты, *s*2 способов — из второй, всего *s*1*s*2 способов.
+
+Пусть *k* = 3. Тогда в графе три компоненты связности, и надо провести два ребра, которые будут соединять различные пары компонент связности. Общее количество способов будет равно *s*1*s*2 × *s*1*s*3 + *s*1*s*2 × *s*2*s*3 + *s*1*s*3 × *s*2*s*3 = *s*1*s*2*s*3 × (*s*1 + *s*2 + *s*3) = *s*1*s*2*s*3 × *n*.
+
+Участники с самой богатой фантазией могли уже сейчас догадаться до правильной формулы. Но лучше посмотрим на следующее значение *k*:
+
+Пусть *k* = 4. Тогда в графе 4 компоненты связности размера *s*1, *s*2, *s*3, *s*4. Надо провести три ребра. Немного подумав, можно понять, что эти рёбра либо будут соединять одну из компонент связности с остальными тремя, либо первую со второй, вторую — с третьей, а третью — с четвёртой (разумеется, компоненты могут следовать в любом порядке).
+
+Количество способов первого типа: (*s*1)3 × *s*2*s*3*s*4 + (*s*2)3 × *s*1*s*3*s*4 + (*s*3)3 × *s*1*s*2*s*4 + (*s*4)3 × *s*1*s*2*s*3 = ((*s*1)2 + (*s*2)2 + (*s*3)2 + (*s*4)2) × (*s*1*s*2*s*3*s*4).
+
+Количество способов второго типа: есть две компоненты связности, из которых выходит по два ребра. Пусть это первая и вторая. Тогда одно ребро проведено между ними, и ещё одно — из них в другие компоненты связности. Эти два ребра могут быть проведены двумя способами: от первой к третьей, а от второй к четвёртой, или наоборот. Значит, количество таких способов равно 2 × (*s*1)2 × (*s*2)2 × *s*3 × *s*4 = 2*s*1*s*2 × (*s*1*s*2*s*3*s*4). И Таких слагаемых 6 штук. Просуммировав их всех и прибавив к ним способы первого типа, можно вынести множитель (*s*1*s*2*s*3*s*4) за скобки, и останется аккурат формула квадрата суммы 4-х слагаемых. Значит, общее количество способов будет равно (*s*1*s*2*s*3*s*4) × *n*2.
+
+На этом месте можно было уже легко догадаться до формулы (*s*1*s*2... *s**k*) × *n**k* - 2, тем более, что в первом случае получается как раз 1 = (*s*1) × *n*- 1.
+
+### Как доказать формулу
+
+Осталось только эту формулу доказать (хотя, конечно, для того, чтобы сдать задачу, доказательства не требовалось =))
+
+Итак, пусть есть некий набор из *k* - 1 ребра, который дополняет граф до связного. Построим по нему **две последовательности чисел**: (x^1, x^2, ..., x^{k-2}) и (a^1,a^2,...,a^k). При это каждое *x* может быть любым числом от 1 до *n*, а *a**i* может быть любым числом от 1 до *s**i*. Легко понять что таких **пар последовательностей** аккурат столько же, сколько (якобы!) способов дополнить наш граф до связного.
+
+Пара последовательностей же строится следующим образом.
+
+Для начала заметим, что этот набор из *k* - 1 ребра как бы образует дерево, в вершинах которого — компоненты связности.
+
+1. Рассмотрим минимальную по номеру компоненту связности, из которой выходит только одно дополняющее ребро. Пусть это компонента номер *i* и ребро соединяет вершину номер *t* в компоненте номер *i* и вершину номер *b* в другой компоненте. Тогда *x*1 = *b*, а *a**i* равно (внимание!) номеру вершины *t* среди вершин компоненты *i*, то есть, числу от 1 до *s**i*.
+2. Одна из компонент связности теперь отвалилась от графа. Остальные *k* - 2 ребер дополняют оставшиеся *k* - 2 компоненты до связного графа. Повторим ту же процедуру еще *k* - 1 раз.
+3. Осталось одно ребро. Оно соединяет две компоненты связности *u* и *v*, которые ещё не упомянуты во второй последовательности. Первая же последовательность заполнена — в ней как раз *k* - 2 элемента. Осталось во вторую последовательность на места номер *u* и *v* записать номера концов оставшегося ребра среди вершин компонент номер *u* и *v* соответственно.
+
+Итого, для каждого способа дополнить граф до связного существует такая пара последовательностей. Заметим, что если компонента *i* была <<висячей>>, то есть, соединялась только с одной другой компонентой, то её вершины не упоминаются в первой последовательности. А если не была висячей — то упоминаются, потому что все рёбра, которые выходят из этой компоненты, надо выкинуть. Каждое ребро, которое мы выкидываем, упирается одним концов в висячую компоненту. И когда было выкинуто первое ребро, выходящее из компоненты *i*, компонента *i* не была висячей. Значит, при выкидывании этого ребра в первую последовательность была записана вершина из компоненты *i*.
+
+Более того, как следует из рассуждений выше, в любой момент в процессе записи первой последовательности, если выясняется, что в ней больше не будет упомянуты вершины из компоненты *i*, то это означает, что компонента *i* либо уже выкинута, либо в данный момент висячая.
+
+Значит, в начальный момент, и каждый момент в процессе построения первой последовательности, по оставшемуся куску последовательности можно судить, какие вершины в данный момент висячие.
+
+Итак, пусть у нас есть какой-то, неизвестный способ дополнить граф до связного и мы построили по нему две последовательности (*x*1, *x*2, ..., *x**k* - 2) и (*a*1, *a*2, ..., *a**k*). Восстановим по ним дополнение графа до связного.
+
+1. Рассмотрим *x*1. Это число говорит нам, что сначала было выкинуто ребро одним концом в *x*1, а другим — в наименьшей по номеру висячей компоненте связности. Мы можем её определить, так как знаем текущий список висячих компонент. Пусть это компонента *i*. Тогда в *a**i* записан номер вершины в компоненте *i*, которая соединена с *x*1. Итак, одно ребро восстановили. Выкидываем компоненту номер *i*.
+2. Делаем эту операцию ещё *k* - 1 раз. Выкинуты *k* - 2 компоненты и восстановлены *k* - 2 ребра. Осталось два неиспользованных элемента второй последовательности, которые определяют вершины в двух оставшихся компонентах. Эти вершины и надо соединить *k* - 1-ым ребром.
+
+Итого, по каждой паре последовательностей восстанавливается дополнение до связного графа, из которого эта пара последовательностей была получена. Значит, количество способов дополнить граф до связного равно количеству пар последовательностей, которое и равно (*s*1*s*2... *s**k*) × *n**k* - 2.
+
+## E (Div1) Оладьи миссис Хадсон
+
+Для начала заметим, что легко придумать очень простое решение этой задачи. Можно просто хранить остаток от деления каждой из цен на каждое из 25 простых чисел от 2 до 97. Тогда каждый запрос будет выполняться за *O*(25 × 10000). И всего решение будет работать за *O*(25 × 10000 × 30000) = *O*(7, 5 × 10⁹) взятий по модулю. К сожалению, это не укладывается в ограничение по времени =)
+
+Первая идея авторского решения: если результаты наших действий класть с мап и доставать оттуда при необходимости, это сильно ускорит работу программы. Но мапить надо с умом! Во-первых, надо класть в мап остатки от произведения цен баночек, подходящих под шаблон, по модулю простых чисел. Во-вторых, все шаблоны, под которые подходят все номера, надо считать идеинтичными, независимо от основания системы исчисления.
+
+Нет смысла приводить здесь нудные вычисления, показывающие, что это действительно дает прирост производительности — гораздо проще написать программу, которая это подсчитает. Получается порядка 3 × 10⁷ чисел, остатки которых надо перемножить, вместо 10 000 × 30 000 = 3 × 10⁸.
+
+Однако всё же 3 × 107 × 25 = 7, 5 × 10⁸ взятий по модулю. Понятно, что это всё равно не уложится в 5 секунд.
+
+Вторая идея авторского решения.
+
+Рассмотрим 4 модуля:
+
+1224469897 = 7 × 17 × 37 × 47 × 61 × 97
+
+1503325967 = 11 × 13 × 41 × 43 × 67 × 89
+
+1336143462 = 2 × 3 × 23 × 31 × 53 × 71 × 83
+
+937397015 = 5 × 19 × 29 × 59 × 73 × 79
+
+Квадрат всех этих 4 чисел влезает в знаковый 64-битный тип данных и их произведение делится на все простые числа до 100. Для каждой из 10 000 цен чисел будем хранить остаток этой цены по каждому из четырех модулей. Легко посчитать остаток произведения и прибавить к нему константу. По четырём остаткам легко определить, какой будет минимальный делитель — перебрать 25 вариантов.
+
+Итого, такая оптимизация дает асимптотику *O*(4 × (3 × 107)) = *O*(1, 2 × 10⁸).
diff --git a/editorials/157.md b/editorials/157.md
@@ -0,0 +1,128 @@
+Source: https://codeforces.com/blog/entry/4005
+
+## A (Div2) Результат игры
+
+В этой игре можно было просто сделать, то, что просят в условии.А именно, завести счётчик, перебрать все клетки поля, и для каждой клетки найти сумму чисел в клетках, стоящих с ней на одной горизонтали, сумму чисел в клетках, стоящих с ней на одной вертикали, и сравнить эти суммы. Если сумма по вертикали больше, увеличить счётчик на один. После того, как перебраны все клетки, вывести счётчик. Максимальная сумма может быть 2 × 30 × 100 = 6 000, поэтому для её достаточно типа *int*.
+
+## B (Div2) След
+
+Извиняюсь за кривой
+
+Давайте для начала отсортируем радиусы окружностей по убыванию. Пусть у нас теперь радиус первой окружности — *r*1, второй окружности — *r*2, ..., последней окружности — *r**n*, где *r*1 > *r*2 > ... > *r**n*. Внешняя область — так, которая снаружи первой окружности — покрашена в синий цвет, значит, область между первой и второй окружностью покрашена в красный. Далее, область между второй и третьей окружностью покрашена в синий цвет, между третьей и четвёртой — в красный, между четвёртой и пятой — в синий, и так далее.
+
+Первая область, закрашенная в красный цвет (область между первой и второй окружностями) — это вся область внутри первой окружности, из которой выкинули внутреннюю область второй окружности. Значит, площадь это области равна π × (*r*12 - *r*22). Аналогично, площадь второй красной области (между третьей и четвёртой окружностями) равна π × (*r*32 - *r*42). И так далее. Значит, суммарная их площадь равна π × (*r*12 - *r*22 + *r*32 - *r*42 + *r*52 - *r*62 + ...). Значит, чтобы посчитать ответ можно, например, сложить квадраты радиусов окружностей с нечётным номером, вычесть из полученной суммы квадраты радиусов всех окружностей с чётными номерами, и полученную величину умножить на \pi.
+
+Может возникнуть небольшое затруднение с последней окружностью. Если число окружностей нечётно, то последняя область — не кольцо между двумя окружностями, а круг. Но это, на самом деле, ничего не меняет: тогда последняя окружность имеет нечётный номер, и квадрат её радиуса надо тоже прибавить к сумме.
+
+## A (Div1) — C (Div2) Сообщение
+
+Для начала, добавим к строке *s* с обоих концов по 2000 фиктивному символу — например, <<#>>. Заметим, что это не повлияло на ответ. Действительно, пусть мы взяли подстроку *t*, частично или полностью состоящую из <<#>>. Тогда все символы <<#>> надо было бы заменить. Но если бы их просто не было, то нужные символы надо было бы добавить.
+
+Рассмотрим оптимальную подстроку *t*, и последовательность действий, которую надо с ней сделать, чтобы превратить её в строку *u*. Рассмотрим первое добавление или удаление символа с одного из концов.
+
+Заметим, что это не удаление. Ведь если мы выбрали подстроку *t* и удалили из неё, к примеру, последний символ, то его не надо было бы и брать, потому что для строки *t* без последнего символа надо на одно действие меньше, чем для всей строки *t*.
+
+А теперь заметим, что это и не добавление. Действительно, пусть мы рассмотрели строку *t*, некоторое время меняли в ней символы на другие, и наконец, добавили один, скажем, в начале. Тогда - Если слева от строки есть символ (то есть, строка там ещё не кончается), то можно было его взять сразу (то есть, рассмотреть не *t*, а *t* с ещё одним символом слева). Вместо того, чтобы добавлять символ, можно заменить существующий — это тоже занимает одной действие. - Если слева от строки нету символа (то есть, первый символ *t* является первым символом строки *s*), тогда в *t* есть как минимум 2000 <<#>>. Значит, либо ответ для такой строки как минимум 2000, потому что каждую решётку надо удалить или заменить; либо никаких символов, кроме решёток, в строке *t* нет, и тогда надо сделать как минимум |*u*| действий, потому что каждый символ *u* надо добавить (или сделать из другого символа). Но чтобы получить всего |*u*| действий, достаточно взять любую подстроку длины |*u*|.
+
+Таким образом, существует оптимальная подстрока *t*, из которой получается *u* без добавлений и удалений. Это ключевой момент решения! Ведь это означает, что длина такой строки равна длине *u*. Значит, достаточно перебрать подстроки строки *s* длины |*u*|. Всего таких подстрок *O*(|*s*|), и для каждой подстроки легко за время *O*(|*u*|) посчитать необходимое количество изменений — это просто количество символов, которые надо заменить.
+
+Таким образом, получается очень простое в написании решение за время *O*(|*s*| × |*u*|).
+
+## B (Div1) — D (Div2) Подозреваемые
+
+Будем называть людей, которые сказали <<Убийство совершил подозреваемый номер *a**i*>> *обвиняющими*, а людей, которые сказали <<Подозреваемый номер *a**i* не совершал убийства>> — *оправдывающими*. Рассмотрим подозреваемого номер *k*. Предположим, что он совершил убийство и посчитаем, сколько тогда человек сказали правду. Люди, которые сказали правду — это люди, которые обвиняли *его*, и люди, которые оправдывали *не его*. Таким образом, их количество — это количество людей, которые обвинили его, плюс количество людей, которые оправдали *кого-либо*, и минус количество людей, которые оправдали *его*. Таким образом, нам надо знать - количество людей, которые кого-либо обвиняют (это легко посчитать за *O*(*n*)) - для каждого подозреваемого количество людей которые его обвиняют - для каждого подозреваемого количество людей которые его оправдывают Последние две величины легко посчитать за время *O*(*n*) для всех подозреваемых. Действительно, пусть *i*-того человека обвиняют *x**i* людей и оправдывают *y**i* людей. Тогда надо просто для каждого человека номер *i*, если он оправдывающий, то увеличить *y**a**i*, а если обвиняет — увеличить *x**a**i*.
+
+После этих действий можно за *O*(1) посчитать для каждого подозреваемого число людей, которые говорят правду в том случае, если он преступник, и если это количество равно *m*, то данный человек может быть преступником. А после того, как мы нашли список возможных преступников, то не составляет труда для каждого человека определить, может ли он говорить правду и может ли он врать.
+
+## С (Div1) — E (Div2) Шифр
+
+Давайте в словах записывать вместо букв цифры: вместо <> — 0, вместо <**> — 1, и так далее. Тогда разрешенные операции такие: рассмотреть два соседних числа, и одно из них увеличить на один, а другое — уменьшить на один. Для начала докажем ключевое утверждение задачи: *два слова имеют одинаковый смысл тогда и только тогда, когда у них одинаковая длина и одинакова сумма букв*.**
+
+Я мог бы привести полное и строгое доказательство этого факта, но оно будет длинным и немного занудным и, думается мне, его вряд ли кто-нибудь будет читать. Лучше я просто опишу две переформулировки задачи, в которых этого утверждение становится более очевидным.
+
+**1.** Переформулировка первая. Представим себе, что у нас вместо каждого числа — стопка монет, от 0 до 25 штук. Тогда разрешенные действия — это переложить одну монету из какой-то стопки в соседнюю так, чтобы во всех стопках оставалось от 0 до 25 монет.
+
+**2.** Переформулировка вторая. Рассмотрим последовательность *s**i* (*i* = 0, ..., *n*), такую, что *s**i* равно сумме первых *i* чисел в слове. Последовательность неубывает и разность между соседними элементами последовательности не превосходит 25. Тогда разрешенная операция — это изменить одно из чисел на один в любую сторону, так, чтобы разность между любыми двумя соседними числами по-прежнему не превосходила 25, и последовательность по-прежнему неубывала.
+
+Таким образом, нам надо посчитать, сколько слов такой же длинны имеют такую же сумму букв. Это легко сделать сразу для всех слов длины не больше 100. Посчитаем с помощью динамики такую величину *x*[*l*][*s*] : количество слов длины *l* с суммой букв *s*. - База динамики: *l* = 0. Есть ровно одно слово (пустое, оно же единственное слово длины 0) с суммой букв 0, и по 0 слов с любой другой суммой букв. - Переход динамики: очень простой. Чтобы узнать, сколько слов длины *l* имеют сумму *s*, надо перебрать, какая может быть последняя буква у этого слова: *x*[*l*][*s*] = *x*[*l* - 1][*s*] + *x*[*l* - 1][*s* - 1] + ... + *x*[*l* - 1][*s* - 25]. Конечно, надо не забыть считать эту величину по модулю 109 + 7.
+
+После того, как мы посчитали эту величину для всех 0 ≤ *l* ≤ 100, 0 ≤ *s* ≤ 2500 за *O*(1002 × 25) памяти и *O*(1002 × 252) времени, надо просто для каждого слова найти его длину сумму букв и вывести ответ (не забыв вычесть 1).
+
+## D (Div1) Улики
+
+### Как придумать формулу
+
+Простите все, кому это непривычно, но поскольку интерпретатор ТеХа на Codeforces в данный момент несколько кривоват, вместо традиционных нижних индексов будут нетрадиционные верхние. Это не степени, о степенях я буду оповещать отдельно.
+
+Говоря математическим языком, в задаче надо посчитать количество способов дополнить граф до связного минимальным количеством ребер. Понятно, что сам граф не имеет значения — важны только компоненты связности. Более того, сами компоненты связности не важны, важны только их размеры.
+
+Итак, пусть у нас есть *k* компонент связности размера *s*1, *s*2, ..., *s**k*.Посмотрим, чем равна искомая величина для маленьких *k*.
+
+Пусть *k* = 1. Тогда граф уже связный, есть 1 способ добавить ноль ребер.
+
+Пусть *k* = 2. Тогда в графе две компоненты связности и надо добавить одно ребро между ними. Существует *s*1 способ выбрать вершину из первой компоненты, *s*2 способов — из второй, всего *s*1*s*2 способов.
+
+Пусть *k* = 3. Тогда в графе три компоненты связности, и надо провести два ребра, которые будут соединять различные пары компонент связности. Общее количество способов будет равно *s*1*s*2 × *s*1*s*3 + *s*1*s*2 × *s*2*s*3 + *s*1*s*3 × *s*2*s*3 = *s*1*s*2*s*3 × (*s*1 + *s*2 + *s*3) = *s*1*s*2*s*3 × *n*.
+
+Участники с самой богатой фантазией могли уже сейчас догадаться до правильной формулы. Но лучше посмотрим на следующее значение *k*:
+
+Пусть *k* = 4. Тогда в графе 4 компоненты связности размера *s*1, *s*2, *s*3, *s*4. Надо провести три ребра. Немного подумав, можно понять, что эти рёбра либо будут соединять одну из компонент связности с остальными тремя, либо первую со второй, вторую — с третьей, а третью — с четвёртой (разумеется, компоненты могут следовать в любом порядке).
+
+Количество способов первого типа: (*s*1)3 × *s*2*s*3*s*4 + (*s*2)3 × *s*1*s*3*s*4 + (*s*3)3 × *s*1*s*2*s*4 + (*s*4)3 × *s*1*s*2*s*3 = ((*s*1)2 + (*s*2)2 + (*s*3)2 + (*s*4)2) × (*s*1*s*2*s*3*s*4).
+
+Количество способов второго типа: есть две компоненты связности, из которых выходит по два ребра. Пусть это первая и вторая. Тогда одно ребро проведено между ними, и ещё одно — из них в другие компоненты связности. Эти два ребра могут быть проведены двумя способами: от первой к третьей, а от второй к четвёртой, или наоборот. Значит, количество таких способов равно 2 × (*s*1)2 × (*s*2)2 × *s*3 × *s*4 = 2*s*1*s*2 × (*s*1*s*2*s*3*s*4). И Таких слагаемых 6 штук. Просуммировав их всех и прибавив к ним способы первого типа, можно вынести множитель (*s*1*s*2*s*3*s*4) за скобки, и останется аккурат формула квадрата суммы 4-х слагаемых. Значит, общее количество способов будет равно (*s*1*s*2*s*3*s*4) × *n*2.
+
+На этом месте можно было уже легко догадаться до формулы (*s*1*s*2... *s**k*) × *n**k* - 2, тем более, что в первом случае получается как раз 1 = (*s*1) × *n*- 1.
+
+### Как доказать формулу
+
+Осталось только эту формулу доказать (хотя, конечно, для того, чтобы сдать задачу, доказательства не требовалось =))
+
+Итак, пусть есть некий набор из *k* - 1 ребра, который дополняет граф до связного. Построим по нему **две последовательности чисел**: (x^1, x^2, ..., x^{k-2}) и (a^1,a^2,...,a^k). При это каждое *x* может быть любым числом от 1 до *n*, а *a**i* может быть любым числом от 1 до *s**i*. Легко понять что таких **пар последовательностей** аккурат столько же, сколько (якобы!) способов дополнить наш граф до связного.
+
+Пара последовательностей же строится следующим образом.
+
+Для начала заметим, что этот набор из *k* - 1 ребра как бы образует дерево, в вершинах которого — компоненты связности.
+
+1. Рассмотрим минимальную по номеру компоненту связности, из которой выходит только одно дополняющее ребро. Пусть это компонента номер *i* и ребро соединяет вершину номер *t* в компоненте номер *i* и вершину номер *b* в другой компоненте. Тогда *x*1 = *b*, а *a**i* равно (внимание!) номеру вершины *t* среди вершин компоненты *i*, то есть, числу от 1 до *s**i*.
+2. Одна из компонент связности теперь отвалилась от графа. Остальные *k* - 2 ребер дополняют оставшиеся *k* - 2 компоненты до связного графа. Повторим ту же процедуру еще *k* - 1 раз.
+3. Осталось одно ребро. Оно соединяет две компоненты связности *u* и *v*, которые ещё не упомянуты во второй последовательности. Первая же последовательность заполнена — в ней как раз *k* - 2 элемента. Осталось во вторую последовательность на места номер *u* и *v* записать номера концов оставшегося ребра среди вершин компонент номер *u* и *v* соответственно.
+
+Итого, для каждого способа дополнить граф до связного существует такая пара последовательностей. Заметим, что если компонента *i* была <<висячей>>, то есть, соединялась только с одной другой компонентой, то её вершины не упоминаются в первой последовательности. А если не была висячей — то упоминаются, потому что все рёбра, которые выходят из этой компоненты, надо выкинуть. Каждое ребро, которое мы выкидываем, упирается одним концов в висячую компоненту. И когда было выкинуто первое ребро, выходящее из компоненты *i*, компонента *i* не была висячей. Значит, при выкидывании этого ребра в первую последовательность была записана вершина из компоненты *i*.
+
+Более того, как следует из рассуждений выше, в любой момент в процессе записи первой последовательности, если выясняется, что в ней больше не будет упомянуты вершины из компоненты *i*, то это означает, что компонента *i* либо уже выкинута, либо в данный момент висячая.
+
+Значит, в начальный момент, и каждый момент в процессе построения первой последовательности, по оставшемуся куску последовательности можно судить, какие вершины в данный момент висячие.
+
+Итак, пусть у нас есть какой-то, неизвестный способ дополнить граф до связного и мы построили по нему две последовательности (*x*1, *x*2, ..., *x**k* - 2) и (*a*1, *a*2, ..., *a**k*). Восстановим по ним дополнение графа до связного.
+
+1. Рассмотрим *x*1. Это число говорит нам, что сначала было выкинуто ребро одним концом в *x*1, а другим — в наименьшей по номеру висячей компоненте связности. Мы можем её определить, так как знаем текущий список висячих компонент. Пусть это компонента *i*. Тогда в *a**i* записан номер вершины в компоненте *i*, которая соединена с *x*1. Итак, одно ребро восстановили. Выкидываем компоненту номер *i*.
+2. Делаем эту операцию ещё *k* - 1 раз. Выкинуты *k* - 2 компоненты и восстановлены *k* - 2 ребра. Осталось два неиспользованных элемента второй последовательности, которые определяют вершины в двух оставшихся компонентах. Эти вершины и надо соединить *k* - 1-ым ребром.
+
+Итого, по каждой паре последовательностей восстанавливается дополнение до связного графа, из которого эта пара последовательностей была получена. Значит, количество способов дополнить граф до связного равно количеству пар последовательностей, которое и равно (*s*1*s*2... *s**k*) × *n**k* - 2.
+
+## E (Div1) Оладьи миссис Хадсон
+
+Для начала заметим, что легко придумать очень простое решение этой задачи. Можно просто хранить остаток от деления каждой из цен на каждое из 25 простых чисел от 2 до 97. Тогда каждый запрос будет выполняться за *O*(25 × 10000). И всего решение будет работать за *O*(25 × 10000 × 30000) = *O*(7, 5 × 10⁹) взятий по модулю. К сожалению, это не укладывается в ограничение по времени =)
+
+Первая идея авторского решения: если результаты наших действий класть с мап и доставать оттуда при необходимости, это сильно ускорит работу программы. Но мапить надо с умом! Во-первых, надо класть в мап остатки от произведения цен баночек, подходящих под шаблон, по модулю простых чисел. Во-вторых, все шаблоны, под которые подходят все номера, надо считать идеинтичными, независимо от основания системы исчисления.
+
+Нет смысла приводить здесь нудные вычисления, показывающие, что это действительно дает прирост производительности — гораздо проще написать программу, которая это подсчитает. Получается порядка 3 × 10⁷ чисел, остатки которых надо перемножить, вместо 10 000 × 30 000 = 3 × 10⁸.
+
+Однако всё же 3 × 107 × 25 = 7, 5 × 10⁸ взятий по модулю. Понятно, что это всё равно не уложится в 5 секунд.
+
+Вторая идея авторского решения.
+
+Рассмотрим 4 модуля:
+
+1224469897 = 7 × 17 × 37 × 47 × 61 × 97
+
+1503325967 = 11 × 13 × 41 × 43 × 67 × 89
+
+1336143462 = 2 × 3 × 23 × 31 × 53 × 71 × 83
+
+937397015 = 5 × 19 × 29 × 59 × 73 × 79
+
+Квадрат всех этих 4 чисел влезает в знаковый 64-битный тип данных и их произведение делится на все простые числа до 100. Для каждой из 10 000 цен чисел будем хранить остаток этой цены по каждому из четырех модулей. Легко посчитать остаток произведения и прибавить к нему константу. По четырём остаткам легко определить, какой будет минимальный делитель — перебрать 25 вариантов.
+
+Итого, такая оптимизация дает асимптотику *O*(4 × (3 × 107)) = *O*(1, 2 × 10⁸).
diff --git a/editorials/79.md b/editorials/79.md
@@ -0,0 +1,42 @@
+Source: https://codeforces.com/blog/entry/1848
+
+## Задача A. Игра в автобусе (автор - [rng_58](//www.codeforces.com/profile/rng_58 "Colonel rng_58"))
+
+В этой задаче прекрасно работает симуляция "в лоб" - нам прямым текстом сказано, как ходят игроки. Лиса Кейл играет по следующей стратегии: если есть хотя бы две монеты по 100 йен и две монеты по 10 йен, она берёт их. Иначе, если есть хотя бы одна монета по 100 йен и 12 монет по 10 - она забирает их. В противном случае она берет 22 монеты по 10 йен. Если ей это не удаётся - выигрывает Ханако. Кролик поступает точно также, но в обратном порядке. Сложность решения - *O(x+y)*.
+
+
+## Задача B. Разноцветное поле (автор - [ir5](//www.codeforces.com/profile/ir5 "Colonel ir5"))
+
+Решение, использующее массив *NxM* получает TL/ML, и, разумеется, мы не можем решать задачу "в лоб". Так как и запросов, и безжизненных клеток не более 1000, нам достаточно научиться отвечать на каждый запрос за время *O(K)*.
+Пусть *(a, b)* - клетка из очередного запроса. Является ли она безжизненной, или нет - решит один цикл *for* по входным данным.
+Итак, мы знаем, что на этой клетке что-то растёт. Пусть *I* - суммарное число клеток перед *(a, b)*, а *J* - количество безжизненных клеток перед *(a, b)*. Тогда ответ определяется значением *(I-J) mod 3* (где *0* => "*Carrots*", *1* => "*Kiwis*", *2* => "*Grapes*"). Путем несложной математики можно понять, что I=(a-1)M+(b-1) (первое слагаемое - это количество клеток в предыдущих строках, а второе - количество предыдущих клеток в текущей строке), а величину *J* можно опять же подсчитать циклом *for* за *O(K)*.
+Получаем решение за *O(TK)*, где *T* - количество запросов.
+
+
+## Задача C. Скучные строки (автор - [ir5](//www.codeforces.com/profile/ir5 "Colonel ir5"))
+
+Мы можем представить каждую подстроку в *s*, совпадающую с какой-либо скучной строкой, как "запрещённый отрезок". Таких кандидатов в плохие отрезки для каждой из *b**i* порядка *O(n)*, поэтому мы можем подсчитать их все за *O*(|*s*|· *n*· |*b**i*|) (да, тут не требуется никаких специальных алгоритмов, например, КМП).
+Теперь мы можем переписать задачу по-другому: дано не более 106 запрещенных отрезков, найти отрезок, который не содержит полностью ни один из запрещённых.
+
+Давайте подсчитаем величину *right[i]* - минимальная правая граница среди запрещенных интервалов с левой границей в *i*. Если таких интервалов нет, положим *right[i]=|s|*.
+
+Теперь давайте переберём начало ответа, начиная с *|s|* и до *0*. Вначале ответ - пустая строка. Пусть ответ для предыдщего начала - подстрока с *i+1* до *j*. Тогда, если *right[i]>j*, то мы можем спокойно приписать один символ слева и ответ увеличивается на 1 - подстрока с *i* до *j*. Если же *right[i]<=j,* то ответ не может быть дальше, чем до *right[i]-1*, в противном случае мы полностью покроем "плохой отрезок". Таким образом, мы пробежимся по всем возможным началам ответов за *O(|s|)*.
+
+Итого время работы - *O*(|*s*|· *n*· |*b**i*|).
+
+
+## Задача D. Кодовый замок (автор - [rng_58](//www.codeforces.com/profile/rng_58 "Colonel rng_58"))
+
+Давайте слегка переформулируем состояние замка: определим массив *b**i* следующим образом: *b**i* = 0, если панели *i* и *i* + 1 находятся в одинаковом состоянии и *b**i* = 1 в противном случае. Положим, что панели 0 и *n* + 1 выключены (OFF). Если Кейл изменяет состояние панелей на отрезке с *x* до *x+a-1* (включительно), то в массиве *b* изменяются значения *b**x* и *b**x* + *a*:
+
+**Задача D'**.
+У Вас есть массив *b**i*. Не более 20 (*=2k*) элементов - единички. За каждый ход Вы можете изменить значения в *b**x* и *b**x* + *a*, где *a* - элемент *a**i* и 0 ≤ *x* ≤ *n* - *a*. Определите минимальное количество ходов, требуемое для обнуления массива (мы просто "перевернули" порядок действий).
+
+Понятно, что порядок ходов не важен. Также понятно, что если массив еще не обнулён, то есть такой индекс *x*, что *b**x* = 1, и нам придётся походить, задев этот индекс, хотя бы один раз. Давайте следаем этот ход первым. Далее применим аналогичное рассуждение и получим, что на каждом ходу хотя бы одно из двух чисел *b**x* и *b**x* + *a* - единица.
+
+**Задача D''.**
+Теперь давайте построим граф с вершинами от *0* до *n+1*. Ребро между двумя вершинами *v*1 и *v*2 будет в том, и только том случае, если |*v*1 - *v*2| - элемент массива *a**i* (то есть, мы можем сделать ход *b**v*1 и *b**v*2. Также изначально есть не более 20 фишек (стоят в позициях изначальных единиц в массиве *b**i*). За один ход мы можем подвинуть фишку по какому-либо ребру. Если две фишки оказываются в одной вершине, они исчезают. Определить минимальное количество ходов, необходимое для избавления от всех фишек.
+
+Для начала предподсчитаем попарные расстояния между всеми фишками. Это можно сделать, 20 раз запустив BFS. А далее имеем динамику по подмножествам: *d[S]* (где *S* - подмножество фишек) - минимальное количество шагов, чтобы убрать все фишки из *S*. Если *S* пусто, *d[S=0]*=0. Если **S* = {*s*0, *s*1, ..., *s**m* - 1}* непусто, то мы выбирае фишки, которая исчезнет вместе с нулевой, и делаем переход: *d*[*S*] = *min*(*d*[*S*\{*s*0, *s**i*}] + *dist*(*s*0, *s**i*)), где 1 ≤ *i* ≤ *m* - 1.
+
+Итоговая сложность решения - *O*(*knl* + *k*· 22*k*).
diff --git a/editorials/80.md b/editorials/80.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/1769
+
+My solution for this task.
+
+We need discriminant to be above zero, so we have:
+
+p - 4q >= 0
+
+p >= 4q
+
+What is probability? It's relation of needed events to all. In this case needed events are all pairs (p,q) where p >= 4q
+
+All events are all possible pairs (p,q)
+
+How we can count them?
+
+All possible pairs is Cartasian product. We can draw it like rectangle.
+
+Its area - number of all possible pairs.
+
+Also we need to find area of polygon, where p >= 4q.
+
+For this let's draw line y=4x and needed set of points is above this line.
+
+Our answer is relation between this area and area of whole rectangle.
+
+I think finding areas isn't problem.
+
+There is one case that I draw on second image, when 4b < a
+
+There are 2 cases - when a=0 and b=0
+
+When a=0 we have only left part of image, so answer is 0.5
+
+When b=0 we have vertical line, so answer is 1.0
+
+Sorry for some mistakes in English.
+
+
diff --git a/editorials/82.md b/editorials/82.md
@@ -0,0 +1,29 @@
+Source: https://codeforces.com/blog/entry/1889
+
+## Task A. Double Cola
+
+Let's designate characters on the first letter of the name. The queue looks like: SH-L-P-R-G, through 5 cans: SH-SH-L-L-P-P-R-R-G-G, through 10 cans: SH-SH-SH-SH-L-L-L-L-P-P-P-P-R-R-R-R-G-G-G-G.
+
+The regularity is clear, and the solution is very simple: we will be iterated on *p* - we will find such minimum *p* that 5· 2*p* > *n* (thus if this number is less or equally we will subtract it from *n*) then we know that at first 2*p* Sheldon's stand, then 2*p* Leonard's and so on. And now we can easily answer who took a can number *n* (namely there was a person with number *n* / 2*p* in sequence SH-L-P-R-G (in 0-indexation).
+
+## Task B. Sets
+
+For the solution the following important fact is required to us: we will admit elements *v* and *u* are in one set then in any of *n*· (*n* - 1) / 2 of sequences from the input data where meets *v* *u* necessarily meets. And also if *v* and *u* are in different sets there is such sequence in which is *v*, but isn't present *u*. Then it is possible to enter the equivalence relation for all elements of all sets - two elements are equivalent, if there is no sequence where one element meets, and another isn't present. Classes of equivalence also are required sets.
+
+It was possible to consider the answer as following algorithm: we will write out for each number the list of numbers of sequences where there is this number, and will unite two numbers if these lists are equal. This algorithm can be realized for *O*(*n*2 * *log*(*n*)) however the solution for *O*(*n*3) passes all tests with time large supply too.
+
+The special case is a test with *n* = 2. This test was used for a considerable quantity of hacks.
+
+## Task C. General Mobilization
+
+At first we will estimate from above the maximum time to which all divisions will reach capital - obviously it is required no more *n* days for this purpose. Therefore restrictions quite allowed model movements of divisions. The key moment of the solution - we will always consider divisions in priority order. Then in every day we will consider the list of those divisions who hasn't reached yet capital, and we will put in priority order on the necessary train. If the train is already filled, the division remains in a current city, differently we will change its position, and in day when the division will reach capital we will write down the answer. Total: in total days which it is necessary model, no more *n*, and every day we move no more *n* divisions. So our solution has asymptotic form no more *O*(*n*2).
+
+The solutions using various structures of the data (sets, turns with priorities etc.) work for *O*(*n*2· *log*(*n*)) and it didn't always keep within in TL.
+
+## Task D. Two out of Three
+
+The problem dares the dynamic programming. We will consider a state (*i*, *j*) meaning that in the current turn there is a person number *i* and also all people from *j* to *n* inclusive. Any turn achievable of the initial can be presented by corresponding condition. The quantity of conditions is *O*(*n*2), the quantity of transitions is only 3, that is *O*(1). So the total asymptotic form is *O*(*n*2).
+
+## Task E. Corridor
+
+This problem has some solutions based on the various methods of the search of the area of the association of the figures on a plane. One of such methods is the method of vertical decomposition (more in detail you can esteem in various articles) and also it was possible to notice that among figures there are no three having non-zero crossing and consequently was to learn to find a total area of two figures enough. For this purpose also it was possible to use the various methods, for example, the author's solution is based on algorithm of cutting off of a convex polygon by a semiplane. Authors supposed the solution for *O*(*n*2).
diff --git a/editorials/83.md b/editorials/83.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/1976
+
+# Задача А (Div-2). Игрушечные армии
+
+Утверждение первое: пусть пусть первым ходом было убито *x* солдат, а вторым *y*, тогда третьим ходом количество убитых будет равно *min*(*n* - *x*, *n* - *y*) = *n* - *max*(*x*, *y*). Значит, общее количество убитых будет равно *x* + *y* + *n* - *max*(*x*, *y*) = *n* + *min*(*x*, *y*), и именно эту величину нам нужно максимизировать. Рассмотрим ограничения на эти переменные: 0 ≤ *x* ≤ *n*, 0 ≤ *y* ≤ *n* - *x*. Значит, нам нужно найти максимум функции *f*(*x*, *y*) = *n* + *min*(*x*, *y*) в этой области. Понятно, что если мы скажем, что *y* = *n* - *x* (то есть для *y* примем крайнее положение), то ответ не уменьшится, а значит, можем свести нашу функцию к *f*(*x*) = *n* + *min*(*x*, *n* - *x*) на отрезке [0, *n*]. Очевидно, максимум этой функции равен 3· *n* / 2 в точке *x* = *n* / 2.
+
+**Ответ: 3· *n* / 2.**
+
+# **Задача E (Div-1). Две последовательности**
+
+Для начала, попробуем нашу задачу решить, не задумываясь об асимптотике. Рассмотрим динамическое программирование, где состояние - это пара (*i*, *j*) (а значение - это минимальная суммарная длина двух последовательностей), которое означает, что первая последовательность у нас заканчивается строкой *i*, а вторая - строкой *j*. Переходы тогда выглядят следующим образом: мы должны взять элемент с номером *v* = *max*(*i*, *j*) + 1 и добавить в одну из последовательностей, таким образом перейти в новые состояния (*i*, *v*) и (*v*, *j*), пересчитав нужным образом значение.
+
+Выпишем более формально, но теперь использовав динамическое программирование "назад", считая, что *i* > *j*:
+
+```
+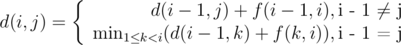
+```
+
+Теперь придумаем окончательное решение. В силу постановки нашей задачи, можно задачу свести к другой динамике - *D*(*i*, *s*), где состояние означает, что одна из последовательностей заканчивается на строку номер *i*, а вторая - на саму строку *s*, причем, заметим, что под строкой *s* будем подразумевать не только строки из входных данных, но и **все их суффиксы длиной от 0 до *l***. Вспомним, что строки у нас бинарные длиной не более 20 символов, а это значит, что строки можно закодировать двоичными числами, в этом случае строка кодируется парой - длиной и самим числом (это строка, если ее интерпретировать как двоичную запись; эта тонкость нужна, т.к. в строках, возможно, присутствуют лидирующие нули, в этом случае разные строки будут переводится в одно и то же число), причем, общее количество пар будет не более 221.
+
+Будем итерироваться по *i* и поддерживать наш массив со значениями динамики (одномерный, размером 2*l*). При переходе, нам нужно обновить его в соответствии с формулами выше: по первой нам нужно ко всем элементам массива прибавить величину f(i - 1, i) - это можно сделать, поддерживая дополнительную переменную *balance* и прибавлять к ней (таким образом, реальное значение элемента *i* будет равно *balance* + *d*[*i*], хотя в самом массиве значение хранится будет *d*[*i*]). А второе обновление еще проще, мы должны перебрать какой длины у нас будет наложение строки на последовательность, взять соотвествующее значение в массиве, и по всем таким перебираемым величинам взять минимум и записать его в соответствующее место в массиве.
+
+Реализовать этот алгоритм можно за асимптотику *O*(*n* * *l*) с требуемой памятью *O*(*n* + 2*l*).
diff --git a/editorials/85.md b/editorials/85.md
@@ -0,0 +1,14 @@
+Source: https://codeforces.com/blog/entry/2020
+
+В задаче нужно было разделить множество точек (мощностью ***n***) на плоскости на два множества так, что бы в каждом множестве расстояние между парой самых удаленных точек было ***d***, которое нужно минимизировать. А затем, уже при найденном минимальном ***d***, посчитать количество способов разбиения с сохранением вышеописанного инварианта.
+
+Для начала научимся решать задачу за более медленную асимптотику. Зафиксируем бинарным поиском искомое расстояние ***d*** и рассмотрим граф из ***n*** вершин (вершины соответствуют точкам), в котором есть ребро между вершинами ***i*** и ***j***, если **|*x**i* - *x**j*| + |*y**i* - *y**j*| > *d***. Тогда понятно, что если полученный граф будет двудольным, то исходное множество можно разбить на две части так, что расстояние между парой самых удаленных точек в каждой части будет не больше ***d***. Пусть мы определили минимальное значение ***d***, при котором вышеописанный граф будет оставаться двудольным, тогда подсчет количества разбиений сводится, как несложно видеть, к подсчету количества раскрасок двудольного графа в два цвета. Время работы данного решения составляет ***O*(*n*2*log*(*n*))**.
+
+Попробуем ускорить данный алгоритм следующим образом. Предположим, что мы отсортировали все попарные расстояния между точками в порядке уменьшения. Данную операцию можно сделать за линейное время от количества пар, т.е. за время ***O*(*n*2)**, используя сортировку подсчетом. Теперь для каждой пары точек **(*i*, *j*)** (в отсортированном порядке) будем добавлять ребро в граф между вершинами ***i*** и ***j***, до тех пор пока он будет оставаться двудольным. Расстояние между парой точек, на которой мы остановились и будет оптимальным значением ***d***. Остался лишь одни неясный момент, как быстро (за ***O*(1)**) проверять остается ли граф двудольным после добавления очередного ребра? Это можно делать используя [CНМ](https://ru.wikipedia.org/wiki/%D0%A1%D0%B8%D1%81%D1%82%D0%B5%D0%BC%D0%B0_%D0%BD%D0%B5%D0%BF%D0%B5%D1%80%D0%B5%D1%81%D0%B5%D0%BA%D0%B0%D1%8E%D1%89%D0%B8%D1%85%D1%81%D1%8F_%D0%BC%D0%BD%D0%BE%D0%B6%D0%B5%D1%81%D1%82%D0%B2). Как известно в двудольном графе нет циклов нечетной длины, а поэтому, нам достаточно модифицировать СНМ так, что бы она не учитывала циклы четной длины, а реагировала лишь на нечетные. Для этого для каждой вершины заведем пометку, которая будет указывать на четность длины пути от вершины до корня ее дерева, которую несложно пересчитывать после изменения СНМ. Реализовав такую структуру данных, мы получим быстрый способ ответа на интересующий нас вопрос. Итого, сложность вышеописанного решения ***O*(*n*2)**.
+
+На самом деле, при использовании манхетенской метрики, данную задачу можно решать за линейное время, т.е. ***O*(*n*)**. Преобразуем систему координат следующим образом:
+***x*’ = *x* - *y*
+*y*’ = *x* + *y***
+Тогда задачу можно свести к покрытию всех точек двумя квадратами одинакового размера (возможно пересекающимися) со сторонами параллельными осям новой системы координат. Ответом на задачу будет наименьшая длина стороны квадратов, которыми можно покрыть все точки, а количество способов разбиения равно **2*k* + 1**, где ***k*** - число точек, которые принадлежат сразу двум квадратам.
+
+Отличную реализацию данного алгоритма можно увидеть в решении участника [Sammarize](//codeforces.com/profile/Sammarize) во время раунда.
diff --git a/editorials/86.md b/editorials/86.md
@@ -0,0 +1,86 @@
+Source: https://codeforces.com/blog/entry/2028
+
+**A. Mirror-number.**
+ First note that if the interval contains a number with *a* digits and a number with *b* digits (where *a* > *b*) then there is no need to consider the number with *b* digits (as the weight of 10*k* is greater then the weights of the numbers less than 10*k*).
+ If we consider only numbers with fixed number of digits (*s* + 1), then the sum of *a* and its reflection is constant. Thus, as product grows as multipliers with fixed sum get closer, the picture is the following: the weight grows from 10*s* to 5· 10*s* - 1, then it stays the same for 5· 10*s* and then it goes down, and reaches its minimum (zero) value at 10*s* + 1 - 1.
+ This is the proof, and the solution is: the maximum weight is reached at either *l*, *r* or 5· 10*s* (we may check all the *s* such that 5· 10*s* belongs to the interval, for example).
+
+**B. Tetris revisited**
+
+It's easy to see that the field may be filled with such figures if and only if there is no isolated cell.
+
+There are many different ways to do that, we will show some of them.
+
+1. Domino filling.
+
+We construct greedy matching on the cells of our field combining them in domino-like figures (rectangles 1 × 2).
+
+Passing through the array that represents our field (from left to right, from top to bottom) we combine the still free horizontal pairs of connected cells into the horizontal dominoes. Then we do the same thing with the still free vertical pairs. Naturally, some cells may be still free. But such cells should be adjoined with some of the dominoes (if they were not isolated). We may attach each of these cells to any of the adjoint dominoes. All resulting figures will contain no more than 5 cells, because the cells still empty after matching can not be neighbour cells and can not be adjacent to the left side of dominoes (by the virtue of the order of our matching).
+
+The last thing that has to be done is the coloring of the figures in accordance with the output format. For example, we may color them like that: color all the cells in the plane in 9 colors (i, j) -> (i % 3) * 3 + j % 3. Then paint each domino in the color of its black cell (according to chess coloring). Each figure will have the color of the domino it grows from.
+
+2. Greedy.
+
+We pass through the array representing the field, again in the same order. Figure for any still free cell may be constructed greedily, but we have to be accurate in order to avoid appearance of new isolated cells. So we just add all the cells that do become isolated when we fill the current figure. Acting in such a fashion we will eventually get the covering by the figures of no more than 5 cells (and at least two, of course).
+
+It is possible to color the figure immediately after its formation. We only need to check the colors of all already colored adjacent figures and to take any color, different from all of them. It is not hard to see that 10 colors are enough.
+
+**C. Genetic engineering.**
+
+Suppose we've built a string *wp* of length *k* < *n* and want to know how many ways there exist to complement *wp* to the suitable string of length *n*.
+ What parameters do we need to know in order to build it further?
+ First of all, we need to know the index *wp* is covered up to (we denote it by *ci* and call it covering index). Also we want to have some information about what the string ends with.
+ Here comes rather standard idea: let's find all the prefixes *ALL**P* of the {*s**i*} and add to our state the largest prefix  such that *wp* ends with *p**k* (as an alternative, you may consider a vertex in a trie constructed with the collection's strings).
+ Now I'll try to convince you that it's enough to set the things going. First of all, when we add a symbol *c* to *wp* we can easily get *p**k* + 1 and it will be equal to the largest string in *ALL**P* such that the string *p**k* + *c* ends with (we can precalculate all the transitions in advance). So the only thing we want to know how to calculate (in order to use dynamic programming approach) is the new covering index. But we notice that it can be changed only by some string from the collection that *w**p* + *c* ends with. Now we observe that it is sufficient to check only the largest from all such strings (denote it *fs*), and that it necessarily contains in *p**k* + 1 (so it also can we easily precalculated for all strings in *ALL**P*). We observe further that the new covering index depends only on the length of *fs*: it either equals the old one if *fs* doesn't cover the symbol *ci* + 1, or equals to (*k* + 1) if the *fs* covers that symbol.
+
+ After calculating all the quantities d[k][k - cov.index][max. prefix] the required number of strings equals the sum of d[n][0][mp] for all *mp*.
+
+**D. Powerful array.**
+Let's solve the problem offline in O(n sqrt(t)) time and O(n) memory. For the simplicity of the reasoning let t = n.
+
+Assume we know the answer to the problem for some interval and want to find it to another one. Let us move the left end of the first one towards the left end of the second, similarly dealing with the right ends. By moving the end by one and for every value in the array maintaining the number of its appearances in the current interval, we will be able to calculate the answer and maintain the numbers of appearances at the same time in O(1). From now on we call the procedure of movement by 1 a step.
+
+Going through the queries in such a fashion, evidently, will cost us O(n^2) steps.
+Let p = sqrt(n). Divide the array into p equal parts Q_1, ..., Q_p. Now consider the queries of the form (Q_i, Q_j) for all i and j (there will be approx. n such queries). Clearly, there doesn't exist an order in which we can go through the queries in o(n sqrt(n)) time as the transition from any interval to the other one is done in no less than sqrt(n) steps.
+
+Nevertheless, there exists a traversal order that guarantees O(n sqrt(n)) steps in the worst case.
+Let's sort the query intervals according to the following rule: first come the intervals with the left ends in Q_1, then the intervals with the left ends in Q_2, and so on. And if the left ends of the two queries belong to the same part, then the interval with the more left right end is assumed to be smaller.
+
+In order to prove the stated asymptotic behavior we will follow the steps of the left and the right ends independently. We note that the left ends that belong to the same Q_i make <= n / p steps, and transition to Q_{i+1} costs no more than 2 * n / p steps. Therefore the left ends make <= n/p * n + 2*n steps (the second summand is O(n), and it's negligible).
+The right ends in the common group move only to the right, and this proves <= n * p steps (during the whole process) estimate. We will estimate the transition to the next Q_i at no more than n steps, so overall we get <= 2 * n * p steps.
+Thus, the total number of steps is no more than (n / p * n + 2 * n * p). Now we choose p = sqrt(n) which proves the statement.
+
+Solution: let us sort the queries by this rule, then make transitions from a query to the next one according to the obtained order.
+
+Note 1. There is nothing special (except for nonadditivity) with the function in the statement.
+
+Note 2. In the case of distinct n and t we can similarly prove the nice estimate 2 * n * sqrt(t), mostly nice because of its exactness (if you follow the proof carefully, you will easily construct the maximal test).
+
+**E. Long sequence.**
+Firstly let's note that there are only 49 different possible inputs.
+So any solution that works finite time at all tests (even if does not pass timelimit) is enough, because we can memorize all the answers. It is not necessary, of course, but may help with slow solutions.
+
+Then, let's answer a more particular question. Assume that *c*1, *c*2, ..., *c**k* and *a*0, *a*1, ..., *a**k* - 1 are already given and we need to check whether the sequence {*a**i*} generated by them is long or not. We know that if it is periodic, then it is possible to find any non-zero k-tuple among k-tuples *a**s*, *a**s* + 1, ..., *a**s* + *k* - 1. So initial k-tuple has no real matter if only it is not zero. Thus the property of sequence "to be long" depends only on coefficients *c**i*, and we may choose any convenient *a*0, *a*1, ..., *a**k* - 1. We will now think that *a*0, *a*1, ..., *a**k* - 2 are zeros and *a**k* - 1 = 1.
+
+Consider the transition matrix *A* of our sequence: for *i* < *k* the *i*-th row of *A* is equal to (0, 0, ... 0, 1, 0, ..., 0) with 1 at (*i* + 1)-th position and last row of *A* is equal to (*c**k*, *c**k* - 1, ..., *c*2, *c*1).
+
+Denote by *x**s* vector (*a**s*, *a**s* + 1, ..., *a**s* + *k* - 1)*T*.
+Then for any integer *s* we have: *A*· *x**s* = *x**s* + 1.
+Last is just a reformulation of the recurrent formula:
+
+*a**n* = *c*1 * *a**n* - 1 + *c*2 * *a**n* - 2 + ... + *c**k* * *a**n* - *k*.
+
+Then by obvious induction we have: *A**p*· *x**s* = *x**s* + *p* for any *p* ≥ 0. Hence *p* is a period iff for any vector *x* that appears in our sequence: *A**p*· *x* = *x*. If the sequence is not long then it is not self-evident still that *A**p* is an identity matrix, because *x* does not take all possible values. But we have chosen *x*0 = (0, 0, ..., 0, 1) before, so it is obvious that vectors *x*0, *x*1, *x*2, ..., *x**k* - 1 form a basis. Hence if *A**p*· *x**i* = *x**i* for any *i* then *A**p* is the identity matrix.
+
+So we just need to do the following:
+
+1) Construct the matrix *A* from the coefficients *c**i*.
+
+2) Check that *A*2*k* - 1 is the identity matrix. (If not, then 2*k* - 1 is not a period.)
+If 2*k* - 1 is a period, then we have to check that it is minimal. Minimal period divides any period so we only need to check the divisors of 2*k* - 1.
+
+3) Generate all maximal divisors of 2*k* - 1 and check that they are not periods (using *A* again).
+
+(By maximal divisor of n we mean divisors of the type n/q where q is a prime number.)
+
+Last thing we need to notice that such a sequence always exists. Moreover, amount of appropriate sets of *c**i* is pretty large. One may prove that there are  such sets (because they correspond to the coefficients of the irreducible factors of the cyclotomic polynomial over ). So we can just take them at random and check.
diff --git a/editorials/87.md b/editorials/87.md
@@ -0,0 +1,83 @@
+Source: https://codeforces.com/blog/entry/2121
+
+Problem DIV1-A, Div2-C. Trains.
+This problem can be approached from two sides - from a programmer's perspective and a mathematician's one. We consider both approaches.
+
+First, let's write some general propositions. Let's put on a straight line all the moments of time when the trains arrive. We will refer the interval between two successive points to the girl, to who the train that matches the right end of the segment is going. Also note that the entire picture is periodic with the period equal to lcm(a, b). Vasya will obviously more often visit the girl, whose total length of the segments is larger.
+
+The programming approach is about modeling the process. If we need to compare the lengths of two sets of intervals, then let's count them. We can do it using two pointers. Let's see what train comes next, add time before the arrival of the train to one of the answers, move the pointer and the current time. We should stop either when two last trains arrive simultaneously or when arrive a+b trains. The solution has asymptotic *O*(*a* + *b*), that fits the time limit. Don't forget that lcm(a,b) ~ 10^12, i.e., we need the 64-bit data type.
+
+The mathematical approach provides us with a more elegant and shorter solution, however, it takes more thinking. It seems obvious that Vasya will more often go to the girl, to who trains go more often. This fact is almost true. Let's try to prove it. Let's divide a and b by their gcd - from this, obviously, nothing will change. To make it clearer, let *a* ≤ *b*. Let's calculate the total length of segments corresponding to the second girl. For this, we need to take a few facts into consideration.
+1) All of them do not exceed a
+2) All a segments are different (due to coprimeness of a and b).
+3) They all are at least 1.
+But such a set of intervals is unique - it’s set of numbers {1, 2, … , a} and its length equals 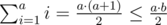. Besides, the equality is fulfilled when the following condition is met: *b* - *a* = 1.
+Hence the following is true. The answer is Equal, when |*a* - *b*| = 1, otherwise Vasya goes more often to the girl to which the trains go more often. The key is not to forget to divide a and b by their gcd.
+
+Problem Div1-B, Div2-D. Vasya and Types.
+In this task, it was necessary to do exactly what is written in the problem's statement, for practically any complexity.
+You are suggested to do the following. For each data type we shall store two values - its name and the number of asterisks when it is brought to void. Then the typeof request is processed by consecutively looking at each element of an array of definitions, in which we find the desired name of the type and the number of asterisks in it.
+The type errtype is convenient to store as void, to which we added - *inf* asterisks.
+Thus, fulfilling a typedef request, we find the number of asterisks in the type A, add to it a number of asterisks and subtract the number of ampersands. Do not forget to replace any negative number of asterisks by - *inf*, and create a new definition of type B, removing the old one.
+
+Problem Div1-C, Div2-E. Interesting Game.
+In this task you should analyze the game. However, due to the fact that with every move the game is divided into several independent ones, the analysis can be performed using the Grundy's function (you can read about it [here](https://en.wikipedia.org/wiki/Sprague%E2%80%93Grundy_theorem), or [here](http://www.yucs.org/%7Egnivasch/cgames/spraguegrundy/index.html)). Now all we have to do is to construct edges for each position. We can build the edges separately for each vertex by solving  simple linear equations for each number of piles after splitting. We can construct all the divisions in advance, simply taking one by one the smallest pile and the number or piles and terminating when the sum exceeds *n*. The second way is better because it works for the *O*(*m* + *n*), where m stands for the number of edges, and the first one works for , which is larger.
+
+We should evaluate m in the maximal test. The edges are no more than 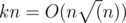. However, in practice they are much less - about 520 thousand. Which is why there's enough time to build the edges within the time limit of *O*(*nk*).
+
+You can try to find a Grundy's function by the definition if we xor all the required values for each position. But this may not work: it has too many long partitions (solutions with lazy countings or other ideas was working, though).
+Let's learn how to quickly count a Grundy's xor function for a long partition. Let's use a standard method for counting functions on the interval - *xor*[*l*, *r*] = *xor*[0, *r*]\^*xor*[0, *l* - 1]. In the course of the algorithm we will keep a xor on a prefix of *xor*[*i*] up to *i*. Then the xor on the interval can also be calculated as O(1). The solution was strictly successful due to the number of edges, which is not very large.
+Problem Div1-D. Beautiful Road.
+In this task we should count for each edge the number of ways on which it is maximal. Since for one edge alone it does not seem possible to find the answer faster than in the linear time, the solution will compute answer for all the edges at once.
+We shall solve the problem first for the two extreme cases, then, combining these two we will obtain a complete solution.
+
+The first case is when the weights of all edges are identical. In this case we can solve the problem via DFS. For each edge, we just need to count the number of paths that this edge lies on it. This number is the product of the number of vertexes on different sides of the edge. If we count the number of vertexes on one side from it, while knowing the total number of vertexes in the tree, it is easy to find the number of vertexes on the other side of it, and hence the required number of ways on which it lies.
+
+The second case - when the weights of all edges are distinct. Sort the edges in the order of the weight's increasing. Initially we take a graph with no edges. We add an edge in the order of increasing of weight. For each edge we join the connected components it connects. Then the answer for each new added edge is the product of the size of components that it has connected.
+
+Now we must combine these two cases. We will add the edges in the ascending order, but not one by one, but in the groups of the equal weight. We should understand what the answer is for each of the added edges. After adding our edges some number of connected components was formed - for each edge, we calculate the same product of the number of vertexes on different sides inside his newly formed connected component.
+
+To find this number of edges on the different sides, we should realize that it is only enough to know the sizes of the old connected components and connections between them - how they were arranged is not important to us. We use a [DSU](https://en.wikipedia.org/wiki/Disjoint-set_data_structure): adding an edge to our forest, we combine the old connected components by these edges. Note that prior to the merging of the components we must calculate an answer for our edges - and it is possible to make via a DFS on our compressed forest as in the first case, only instead of the number of vertexes on different sides of the edge we take the sum of the sizes of the connected components on different sides of the edge.
+
+How to do it neatly:
+
+* It’s good idea to dynamically create compressed graph at each step: it will have O(E’) vertexes and edges, where E' - the number of added edges of the source tree.
+* Do not create unnecessary vertexes in the new created compressed column: after all, the DFS works for O(V + E), rather than O(E), so the unused connected components we do not include in the circuit.
+* We should use the 64-bit data type. To store the response of the order of (105)2 it will fit more than the 32-bit one.
+* We should not merge the adjacency lists explicitly when connecting components. It is too long.
+* You can do everything instead of arrays on vectors / maps / heap, so the total time of nulling of the marks for an array of DFS occupied O(V). Or, instead of nulling of the array overlays we keep instead of a Boolean flag the iteration number. In general, it is better not to null extra arrays. After all, algorithm can make V iterations.
+* Be careful, solutions with map works at TL's maximum, so it should be written very carefully; you should better use the vectors + list of involved nodes. The author's solution with the map fits in the TL with only half a second to spare. While using a vector has a four-time stock of time to spare.
+
+
+
+Problem Div1-E. Mogohu Ree Idol.
+
+In this task we had to verify that the point is the centroid of the triangle formed by points of the given three polygons. Lets reformulate the problem. We should verify the existence of three points A, B, C, such that A belongs to the first polygon, B - to the second one, C - to the third one, and 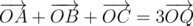. Logically, you should understand what set of points determines this 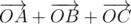, you should understand how to build it and test a point on whether it belongs to the set or not. This set is called Minkowski sum. We will need only one of its properties: the sum of two convex polygons is a convex polygon whose sides coincide as vectors, with the sides of the original polygons. We will prove this later.
+
+How do we use it now? The first thing that this property gives us is an algorithm to test for belonging. Once the sum is built you can test whether or not a point belongs to the sum using a standard algorithm of testing a point being inside of a convex polygon in logarithmic time. Also the constructing algorithm is immediately obtained. We just need to add the coordinates of the lowest (the leftmost of them) points of all three polygons. As a result, we get a point, which is the lower left for the sum polygon. The sides are now represented as a sorted by the polar angles list of parties of the original polygons (instead of sorting we may merge sorted arrays).
+
+Proof.
+
+We shall prove the correctness of the algorithm for two polygons, for three polygons the proof is just the same. Let the first polygon be represented by A and the second one - by B. Denote the sum as M.
+
+We will prove that M is a convex set.
+
+Choose some 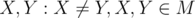. By definition, 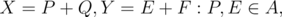 Q, (here and below the point is identified with its radius vector).
+
+Let’s take some point . We shall prove that .
+
+As G lies on the [AB], 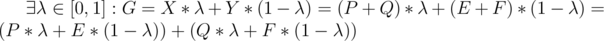.
+
+Note that the first bracket is obviously some point lying on the segment [PE]. That means the point lying inside the polygon A, since A is convex. Similarly, the second bracket is inside B. Hence, their sum, i.e., G, lies in the Minkowski sum. This means that the Minkowski sum is a convex set.
+
+Let us consider some side XY of the first polygon. Let's rotate the plane so that the side XY was horizontal and that the polygon lied above the XY line.
+
+Consider the lowest horizontal line intersecting B. Let it cross B along the segment of PR, where point P does not lie further to the right of the R (it is clear that PR can turn out to be a degenerate segment from one vertex or the segment between two consquent verteces). Let's call PR the lowest segment of the polygon. Then we construct in the similar way the lowest segment UV of polygon M.
+
+Let's prove that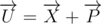 - if not, let 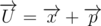 . It is clear that x and p are the lowest points of the polygons A and B - otherwise one of them can be moved to a small vector d, which lies in the lower half-plane, so that the point remained within its polygon. In this case U will move the same way to d, which contradicts the fact that U is one of the lowest points of the polygon.
+
+Thus, x and p are the lowest points of their polygons. Similarly, x and p are the leftmost points on the lowest segments of their polygons - otherwise we shift x or p to vector d that is directed to the left. It is also a contradiction - the U point stops to be the leftmost lower point.
+
+Hence, U = X + P. Similarly, V = Y + Q. Hence, 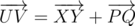.
+
+Thus, the sequence of sides M as vectors in the, for instance, counterclockwise order, is nothing other than the union of sides of *A* and *B* as vectors in the counterclockwise order, that immediately proves the correctness of the algorithm.
diff --git a/editorials/88.md b/editorials/88.md
@@ -0,0 +1,83 @@
+Source: https://codeforces.com/blog/entry/2121
+
+Problem DIV1-A, Div2-C. Trains.
+This problem can be approached from two sides - from a programmer's perspective and a mathematician's one. We consider both approaches.
+
+First, let's write some general propositions. Let's put on a straight line all the moments of time when the trains arrive. We will refer the interval between two successive points to the girl, to who the train that matches the right end of the segment is going. Also note that the entire picture is periodic with the period equal to lcm(a, b). Vasya will obviously more often visit the girl, whose total length of the segments is larger.
+
+The programming approach is about modeling the process. If we need to compare the lengths of two sets of intervals, then let's count them. We can do it using two pointers. Let's see what train comes next, add time before the arrival of the train to one of the answers, move the pointer and the current time. We should stop either when two last trains arrive simultaneously or when arrive a+b trains. The solution has asymptotic *O*(*a* + *b*), that fits the time limit. Don't forget that lcm(a,b) ~ 10^12, i.e., we need the 64-bit data type.
+
+The mathematical approach provides us with a more elegant and shorter solution, however, it takes more thinking. It seems obvious that Vasya will more often go to the girl, to who trains go more often. This fact is almost true. Let's try to prove it. Let's divide a and b by their gcd - from this, obviously, nothing will change. To make it clearer, let *a* ≤ *b*. Let's calculate the total length of segments corresponding to the second girl. For this, we need to take a few facts into consideration.
+1) All of them do not exceed a
+2) All a segments are different (due to coprimeness of a and b).
+3) They all are at least 1.
+But such a set of intervals is unique - it’s set of numbers {1, 2, … , a} and its length equals 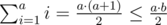. Besides, the equality is fulfilled when the following condition is met: *b* - *a* = 1.
+Hence the following is true. The answer is Equal, when |*a* - *b*| = 1, otherwise Vasya goes more often to the girl to which the trains go more often. The key is not to forget to divide a and b by their gcd.
+
+Problem Div1-B, Div2-D. Vasya and Types.
+In this task, it was necessary to do exactly what is written in the problem's statement, for practically any complexity.
+You are suggested to do the following. For each data type we shall store two values - its name and the number of asterisks when it is brought to void. Then the typeof request is processed by consecutively looking at each element of an array of definitions, in which we find the desired name of the type and the number of asterisks in it.
+The type errtype is convenient to store as void, to which we added - *inf* asterisks.
+Thus, fulfilling a typedef request, we find the number of asterisks in the type A, add to it a number of asterisks and subtract the number of ampersands. Do not forget to replace any negative number of asterisks by - *inf*, and create a new definition of type B, removing the old one.
+
+Problem Div1-C, Div2-E. Interesting Game.
+In this task you should analyze the game. However, due to the fact that with every move the game is divided into several independent ones, the analysis can be performed using the Grundy's function (you can read about it [here](https://en.wikipedia.org/wiki/Sprague%E2%80%93Grundy_theorem), or [here](http://www.yucs.org/%7Egnivasch/cgames/spraguegrundy/index.html)). Now all we have to do is to construct edges for each position. We can build the edges separately for each vertex by solving  simple linear equations for each number of piles after splitting. We can construct all the divisions in advance, simply taking one by one the smallest pile and the number or piles and terminating when the sum exceeds *n*. The second way is better because it works for the *O*(*m* + *n*), where m stands for the number of edges, and the first one works for , which is larger.
+
+We should evaluate m in the maximal test. The edges are no more than 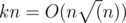. However, in practice they are much less - about 520 thousand. Which is why there's enough time to build the edges within the time limit of *O*(*nk*).
+
+You can try to find a Grundy's function by the definition if we xor all the required values for each position. But this may not work: it has too many long partitions (solutions with lazy countings or other ideas was working, though).
+Let's learn how to quickly count a Grundy's xor function for a long partition. Let's use a standard method for counting functions on the interval - *xor*[*l*, *r*] = *xor*[0, *r*]\^*xor*[0, *l* - 1]. In the course of the algorithm we will keep a xor on a prefix of *xor*[*i*] up to *i*. Then the xor on the interval can also be calculated as O(1). The solution was strictly successful due to the number of edges, which is not very large.
+Problem Div1-D. Beautiful Road.
+In this task we should count for each edge the number of ways on which it is maximal. Since for one edge alone it does not seem possible to find the answer faster than in the linear time, the solution will compute answer for all the edges at once.
+We shall solve the problem first for the two extreme cases, then, combining these two we will obtain a complete solution.
+
+The first case is when the weights of all edges are identical. In this case we can solve the problem via DFS. For each edge, we just need to count the number of paths that this edge lies on it. This number is the product of the number of vertexes on different sides of the edge. If we count the number of vertexes on one side from it, while knowing the total number of vertexes in the tree, it is easy to find the number of vertexes on the other side of it, and hence the required number of ways on which it lies.
+
+The second case - when the weights of all edges are distinct. Sort the edges in the order of the weight's increasing. Initially we take a graph with no edges. We add an edge in the order of increasing of weight. For each edge we join the connected components it connects. Then the answer for each new added edge is the product of the size of components that it has connected.
+
+Now we must combine these two cases. We will add the edges in the ascending order, but not one by one, but in the groups of the equal weight. We should understand what the answer is for each of the added edges. After adding our edges some number of connected components was formed - for each edge, we calculate the same product of the number of vertexes on different sides inside his newly formed connected component.
+
+To find this number of edges on the different sides, we should realize that it is only enough to know the sizes of the old connected components and connections between them - how they were arranged is not important to us. We use a [DSU](https://en.wikipedia.org/wiki/Disjoint-set_data_structure): adding an edge to our forest, we combine the old connected components by these edges. Note that prior to the merging of the components we must calculate an answer for our edges - and it is possible to make via a DFS on our compressed forest as in the first case, only instead of the number of vertexes on different sides of the edge we take the sum of the sizes of the connected components on different sides of the edge.
+
+How to do it neatly:
+
+* It’s good idea to dynamically create compressed graph at each step: it will have O(E’) vertexes and edges, where E' - the number of added edges of the source tree.
+* Do not create unnecessary vertexes in the new created compressed column: after all, the DFS works for O(V + E), rather than O(E), so the unused connected components we do not include in the circuit.
+* We should use the 64-bit data type. To store the response of the order of (105)2 it will fit more than the 32-bit one.
+* We should not merge the adjacency lists explicitly when connecting components. It is too long.
+* You can do everything instead of arrays on vectors / maps / heap, so the total time of nulling of the marks for an array of DFS occupied O(V). Or, instead of nulling of the array overlays we keep instead of a Boolean flag the iteration number. In general, it is better not to null extra arrays. After all, algorithm can make V iterations.
+* Be careful, solutions with map works at TL's maximum, so it should be written very carefully; you should better use the vectors + list of involved nodes. The author's solution with the map fits in the TL with only half a second to spare. While using a vector has a four-time stock of time to spare.
+
+
+
+Problem Div1-E. Mogohu Ree Idol.
+
+In this task we had to verify that the point is the centroid of the triangle formed by points of the given three polygons. Lets reformulate the problem. We should verify the existence of three points A, B, C, such that A belongs to the first polygon, B - to the second one, C - to the third one, and 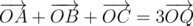. Logically, you should understand what set of points determines this 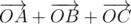, you should understand how to build it and test a point on whether it belongs to the set or not. This set is called Minkowski sum. We will need only one of its properties: the sum of two convex polygons is a convex polygon whose sides coincide as vectors, with the sides of the original polygons. We will prove this later.
+
+How do we use it now? The first thing that this property gives us is an algorithm to test for belonging. Once the sum is built you can test whether or not a point belongs to the sum using a standard algorithm of testing a point being inside of a convex polygon in logarithmic time. Also the constructing algorithm is immediately obtained. We just need to add the coordinates of the lowest (the leftmost of them) points of all three polygons. As a result, we get a point, which is the lower left for the sum polygon. The sides are now represented as a sorted by the polar angles list of parties of the original polygons (instead of sorting we may merge sorted arrays).
+
+Proof.
+
+We shall prove the correctness of the algorithm for two polygons, for three polygons the proof is just the same. Let the first polygon be represented by A and the second one - by B. Denote the sum as M.
+
+We will prove that M is a convex set.
+
+Choose some 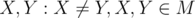. By definition, 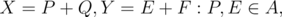 Q, (here and below the point is identified with its radius vector).
+
+Let’s take some point . We shall prove that .
+
+As G lies on the [AB], 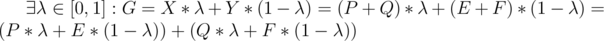.
+
+Note that the first bracket is obviously some point lying on the segment [PE]. That means the point lying inside the polygon A, since A is convex. Similarly, the second bracket is inside B. Hence, their sum, i.e., G, lies in the Minkowski sum. This means that the Minkowski sum is a convex set.
+
+Let us consider some side XY of the first polygon. Let's rotate the plane so that the side XY was horizontal and that the polygon lied above the XY line.
+
+Consider the lowest horizontal line intersecting B. Let it cross B along the segment of PR, where point P does not lie further to the right of the R (it is clear that PR can turn out to be a degenerate segment from one vertex or the segment between two consquent verteces). Let's call PR the lowest segment of the polygon. Then we construct in the similar way the lowest segment UV of polygon M.
+
+Let's prove that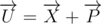 - if not, let 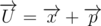 . It is clear that x and p are the lowest points of the polygons A and B - otherwise one of them can be moved to a small vector d, which lies in the lower half-plane, so that the point remained within its polygon. In this case U will move the same way to d, which contradicts the fact that U is one of the lowest points of the polygon.
+
+Thus, x and p are the lowest points of their polygons. Similarly, x and p are the leftmost points on the lowest segments of their polygons - otherwise we shift x or p to vector d that is directed to the left. It is also a contradiction - the U point stops to be the leftmost lower point.
+
+Hence, U = X + P. Similarly, V = Y + Q. Hence, 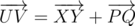.
+
+Thus, the sequence of sides M as vectors in the, for instance, counterclockwise order, is nothing other than the union of sides of *A* and *B* as vectors in the counterclockwise order, that immediately proves the correctness of the algorithm.
diff --git a/editorials/89.md b/editorials/89.md
@@ -0,0 +1,119 @@
+Source: https://codeforces.com/blog/entry/2162
+
+**A div2**. In this problem you can simulate the process. You can consider all minutes and in dependence by a color of a current cablecar decrease size of corresponding group of students *G* by *min*(|*G*|, 2), where |*G*| is size of the group. After that you should determine the first minute *t* in that all three groups of students will be empty. So *t* + 30 is an answer. This solution works in *O*(*r* + *g* + *b*).
+
+Also there is *O*(1) solution. It is following formula: *ans* = *max*(3[(*R* + 1) / 2] + 27, 3[(*G* + 1) / 2] + 28, 3[(*B* + 1) / 2] + 29) where [*x*] is rounding down.
+
+**B div2**. It this problem you should write exactly that is written in statement. For every letter you should see a row and a column of the letter. If equal letter was found, current letter sould not be output. You can combine scanning rows and columns and output an answer, for example, this way:
+
+FOR(a,1,n) FOR(b,1,m)
+{
+ bool should_out=true;
+ FOR(c,1,n) if (c!=a) if (T[a][b]==T[c][b]) should_out=false;
+ FOR(c,1,m) if (c!=b) if (T[a][b]==T[a][c]) should_out=false;
+ if (should_out) printf("%c", T[a][b]);
+}
+
+This solution works in *O*(*mn*(*n* + *m*)).
+
+Also here an *O*(*nm*)-solution exitsts. In every row and column you can calculate a number of every letter of an alphabet. After that check for output can be done in *O*(1). You just should check that numbers of entries of considered letter into corresponding row and column equal exactly 1.
+
+**C div2 и A div1**. Determine a form of all arrangements of diamonds that set of all sums of pairs adjacent cells is invariably. If you remove from the first cell exactly *c* diamonds, you should add exactly *c* diamonds into the second cell, remove *c* diamonds from the third cell and so on. In other words, all valid arrangements can be produced by adding *c* diamonds into every even cell and removing *c* diamonds from every odd cell, where *c* is some integer. *c* lies in range from 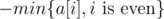 to 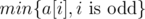 because otherwise number of diamonds in some cell will be less than zero. There is no more valid arrangements.
+
+Now consider a number of all diamonds in cells as a function of *c*. If *n* is even, the sum always is constant. So there is impossible of theft diamonds and answer is 0. For odd *n* for every *c* there is *c* extra diamonds. So, Joe can theft no more than 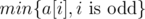 diamonds.
+
+It is easy for undarstanding that for increasing (or decreasing) *c* by some constant *x* Joe should do *x*(*n* + 1) / 2 moves, but he cannot done it by lass count of moves. In one minute Joe can change *c* no more than on [*m* / ((*n* + 1) / 2)]. Common number of diamonds thet Joe can theft for all time is *k*[*m* / ((*n* + 1) / 2)], but you should take into account a limits for changing of *c*.
+
+At the end common solution is following: If *n* is even, answer is 0, otherwise answer is 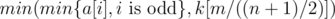.
+
+Be careful fith overflow of 32bit integers. Here you should use an 64bit integers.
+ **D div2 и B div1**. Here you can build some miltigraph in which nodes are widgets and edges are relationship of pack()-method. This graph is acyclic. Next, you should do topological sort of nodes. Sizes of widgets should be calculated in the obtained order. At the last, you should sort all nodes by thier names and output an answer.
+
+About implementation.
+
+Parsing of instructions is very easy if you swap charachers '.', ',', '(', ')' by spaces. Now you can just split instructions into strings using spaces as separators.
+
+Multigraph can be saved into matrix. Cell M[i][j] contains integer number that means number of edges from node i to node j. Topological sort can be done by any stupid method. For example, you can choose *k* times node that has no outgoing edges to unselected nodes, where *k* is numder of nodes. Every check can be done in *O*(*k*2).
+
+You should recalculate sizes of widgets using 64-bit integets (a tip was is statement). In a test like
+
+100
+Widget w(100,100)
+HBox box
+box.pack(w)
+box.set_border(100)
+HBox a
+a.pack(box)
+a.pack(box)
+HBox b
+b.pack(a)
+b.pack(a)
+HBox c
+c.pack(b)
+c.pack(b)
+...
+
+width of widgets grows exponentially. In jurys' tests maximum length of a side of widgets was 103079215104000. You can get that length by packing 4 widgets everu time instead of 2 widgets.
+
+**E div2 и C div1**. This problem can be solved by simulation. You can just iterate over all chips and for every of them calculate number of points. But srupid simulate can give *O*(*k*3) time solution, where *k* is total number of chips. It doesn't fit into time limits. For example, try test like
+
+1 5000
+RRRR...[2500 times]LLLL...[2500 times]
+
+You can simulate process in  time by using some data structures like std::set, but it doesn't fit into limits too.
+
+Similating in *O*(*k*2) time is given by following data structure.
+
+For every chip you can save links to chips that is placed up, doun, left and right from the considered chip. Net of links can be built in O(*nm*). Now, when you simulate process, you can remove chips this way:
+
+Chip->L->R = Chip->R
+Chip->R->L = Chip->L
+Chip->U->D = Chip->D
+Chip->D->U = Chip->U
+
+So, jump from some chip to the next chip in a move can be done in *O*(1). Now you can simulate every move in *O*(*k*).
+
+Remove operation is reversible because every removed chip stores links to all of its neighbours. Therefore you can save links to all removed chips in current move and after restore net of links using following operetions for all removed chips in reversed order
+
+Chip->L->R = Chip
+Chip->R->L = Chip
+Chip->U->D = Chip
+Chip->D->U = Chip
+
+Also you can just build net of links anew for every move.
+
+**D div1**. Initially lets pump all mines on radius of Death Star and squeeze Death Star into point. Now you should determine an intersection of a ray with obtained figures.
+
+Mine's body with radius *r* is pumped into ball with radius *r* + *R*. Every mine's spike is pumped into union of two balls with radius *R* and cylinder. One of these balls lies inside of pumped mine's body, therefore you can don't consider it. Let length of spike is *r*0. Then cylinder will have heigth *r*0 and radius *R*. A distance between center of one base of the cylinder and edge of another one equals . Following unequation proves that this distance always less than radius of pumped mine's body and cylinder lies inside of the pumped mine's body:
+
+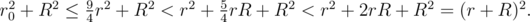
+
+So, you can don't consider the cylinders too. For every spike you should store only ball of radius *R* with center in a peak of the spike.
+
+Now we have set of balls, we are needed to determine a time in that some point collides with every of those balls. Lets write an equation:
+
+|*A* + *vt* - *O*| = *R*,
+
+where *A* is start position of point, *v* is vector of its velocity, *O* is center of ball, *R* is its radius. Lets rewrite equation in scalar variables:
+
+(*A**x* + *v**x**t* - *O**x*)2 + (*A**y* + *v**y**t* - *O**y*)2 + (*A**z* + *v**z**t* - *O**z*)2 = *R*2.
+
+When you expand brackets, you receive some quadratic equation from variable *t*:
+
+*At*2 + *Bt* + *C* = 0.
+
+You should solve it and choose minimal root (minimal root is time of the first collision of point with the ball, maximal one is time of the second collision). Check than root more than 0.
+
+Now you should determine all times and choose minimum of them. If there are no collisions, answer is -1.
+
+All checking should be done in integer 64bit numbers for absolutely precision.
+
+**E div1**. Solomon can just create some segments of ice cubes and cut its. Consider a segment with rightmost begin. You can assume that it ends in position of the last demon (you always can cut end of a segment that ends on last demon and add it to current segment). For cutting the last segment you should build "ice bridge" to it. When you are building this bridge, you should create and cut all others segments.
+
+Now iterate over all start positions of the last segment. For every of them you should decrease powers of demons that is covered by this segment and calculate minimal number of moves for destroy all demons (do not forgen about the last segment!).
+
+You can see that for every fallen ice cube you need exactly 3 operations --- go left, create cube, go right. For cutting a segment you need exactly 2 operations --- create cube and destroy one. Therefore all demons should be covered by minimal number of segments that no cube falls on an empty position. It can be done by greedy algorithm.
+
+Total number of operations for every start position of the last segment can be calculated in *O*(*n*). Total number of checks is *O*(*n*), so we have an *O*(*n*2) solution.
+
+After all, answer can be built very easy.
diff --git a/editorials/90.md b/editorials/90.md
@@ -0,0 +1,119 @@
+Source: https://codeforces.com/blog/entry/2162
+
+**A div2**. In this problem you can simulate the process. You can consider all minutes and in dependence by a color of a current cablecar decrease size of corresponding group of students *G* by *min*(|*G*|, 2), where |*G*| is size of the group. After that you should determine the first minute *t* in that all three groups of students will be empty. So *t* + 30 is an answer. This solution works in *O*(*r* + *g* + *b*).
+
+Also there is *O*(1) solution. It is following formula: *ans* = *max*(3[(*R* + 1) / 2] + 27, 3[(*G* + 1) / 2] + 28, 3[(*B* + 1) / 2] + 29) where [*x*] is rounding down.
+
+**B div2**. It this problem you should write exactly that is written in statement. For every letter you should see a row and a column of the letter. If equal letter was found, current letter sould not be output. You can combine scanning rows and columns and output an answer, for example, this way:
+
+FOR(a,1,n) FOR(b,1,m)
+{
+ bool should_out=true;
+ FOR(c,1,n) if (c!=a) if (T[a][b]==T[c][b]) should_out=false;
+ FOR(c,1,m) if (c!=b) if (T[a][b]==T[a][c]) should_out=false;
+ if (should_out) printf("%c", T[a][b]);
+}
+
+This solution works in *O*(*mn*(*n* + *m*)).
+
+Also here an *O*(*nm*)-solution exitsts. In every row and column you can calculate a number of every letter of an alphabet. After that check for output can be done in *O*(1). You just should check that numbers of entries of considered letter into corresponding row and column equal exactly 1.
+
+**C div2 и A div1**. Determine a form of all arrangements of diamonds that set of all sums of pairs adjacent cells is invariably. If you remove from the first cell exactly *c* diamonds, you should add exactly *c* diamonds into the second cell, remove *c* diamonds from the third cell and so on. In other words, all valid arrangements can be produced by adding *c* diamonds into every even cell and removing *c* diamonds from every odd cell, where *c* is some integer. *c* lies in range from 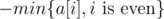 to 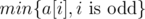 because otherwise number of diamonds in some cell will be less than zero. There is no more valid arrangements.
+
+Now consider a number of all diamonds in cells as a function of *c*. If *n* is even, the sum always is constant. So there is impossible of theft diamonds and answer is 0. For odd *n* for every *c* there is *c* extra diamonds. So, Joe can theft no more than 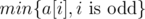 diamonds.
+
+It is easy for undarstanding that for increasing (or decreasing) *c* by some constant *x* Joe should do *x*(*n* + 1) / 2 moves, but he cannot done it by lass count of moves. In one minute Joe can change *c* no more than on [*m* / ((*n* + 1) / 2)]. Common number of diamonds thet Joe can theft for all time is *k*[*m* / ((*n* + 1) / 2)], but you should take into account a limits for changing of *c*.
+
+At the end common solution is following: If *n* is even, answer is 0, otherwise answer is 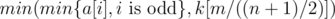.
+
+Be careful fith overflow of 32bit integers. Here you should use an 64bit integers.
+ **D div2 и B div1**. Here you can build some miltigraph in which nodes are widgets and edges are relationship of pack()-method. This graph is acyclic. Next, you should do topological sort of nodes. Sizes of widgets should be calculated in the obtained order. At the last, you should sort all nodes by thier names and output an answer.
+
+About implementation.
+
+Parsing of instructions is very easy if you swap charachers '.', ',', '(', ')' by spaces. Now you can just split instructions into strings using spaces as separators.
+
+Multigraph can be saved into matrix. Cell M[i][j] contains integer number that means number of edges from node i to node j. Topological sort can be done by any stupid method. For example, you can choose *k* times node that has no outgoing edges to unselected nodes, where *k* is numder of nodes. Every check can be done in *O*(*k*2).
+
+You should recalculate sizes of widgets using 64-bit integets (a tip was is statement). In a test like
+
+100
+Widget w(100,100)
+HBox box
+box.pack(w)
+box.set_border(100)
+HBox a
+a.pack(box)
+a.pack(box)
+HBox b
+b.pack(a)
+b.pack(a)
+HBox c
+c.pack(b)
+c.pack(b)
+...
+
+width of widgets grows exponentially. In jurys' tests maximum length of a side of widgets was 103079215104000. You can get that length by packing 4 widgets everu time instead of 2 widgets.
+
+**E div2 и C div1**. This problem can be solved by simulation. You can just iterate over all chips and for every of them calculate number of points. But srupid simulate can give *O*(*k*3) time solution, where *k* is total number of chips. It doesn't fit into time limits. For example, try test like
+
+1 5000
+RRRR...[2500 times]LLLL...[2500 times]
+
+You can simulate process in  time by using some data structures like std::set, but it doesn't fit into limits too.
+
+Similating in *O*(*k*2) time is given by following data structure.
+
+For every chip you can save links to chips that is placed up, doun, left and right from the considered chip. Net of links can be built in O(*nm*). Now, when you simulate process, you can remove chips this way:
+
+Chip->L->R = Chip->R
+Chip->R->L = Chip->L
+Chip->U->D = Chip->D
+Chip->D->U = Chip->U
+
+So, jump from some chip to the next chip in a move can be done in *O*(1). Now you can simulate every move in *O*(*k*).
+
+Remove operation is reversible because every removed chip stores links to all of its neighbours. Therefore you can save links to all removed chips in current move and after restore net of links using following operetions for all removed chips in reversed order
+
+Chip->L->R = Chip
+Chip->R->L = Chip
+Chip->U->D = Chip
+Chip->D->U = Chip
+
+Also you can just build net of links anew for every move.
+
+**D div1**. Initially lets pump all mines on radius of Death Star and squeeze Death Star into point. Now you should determine an intersection of a ray with obtained figures.
+
+Mine's body with radius *r* is pumped into ball with radius *r* + *R*. Every mine's spike is pumped into union of two balls with radius *R* and cylinder. One of these balls lies inside of pumped mine's body, therefore you can don't consider it. Let length of spike is *r*0. Then cylinder will have heigth *r*0 and radius *R*. A distance between center of one base of the cylinder and edge of another one equals . Following unequation proves that this distance always less than radius of pumped mine's body and cylinder lies inside of the pumped mine's body:
+
+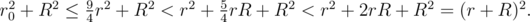
+
+So, you can don't consider the cylinders too. For every spike you should store only ball of radius *R* with center in a peak of the spike.
+
+Now we have set of balls, we are needed to determine a time in that some point collides with every of those balls. Lets write an equation:
+
+|*A* + *vt* - *O*| = *R*,
+
+where *A* is start position of point, *v* is vector of its velocity, *O* is center of ball, *R* is its radius. Lets rewrite equation in scalar variables:
+
+(*A**x* + *v**x**t* - *O**x*)2 + (*A**y* + *v**y**t* - *O**y*)2 + (*A**z* + *v**z**t* - *O**z*)2 = *R*2.
+
+When you expand brackets, you receive some quadratic equation from variable *t*:
+
+*At*2 + *Bt* + *C* = 0.
+
+You should solve it and choose minimal root (minimal root is time of the first collision of point with the ball, maximal one is time of the second collision). Check than root more than 0.
+
+Now you should determine all times and choose minimum of them. If there are no collisions, answer is -1.
+
+All checking should be done in integer 64bit numbers for absolutely precision.
+
+**E div1**. Solomon can just create some segments of ice cubes and cut its. Consider a segment with rightmost begin. You can assume that it ends in position of the last demon (you always can cut end of a segment that ends on last demon and add it to current segment). For cutting the last segment you should build "ice bridge" to it. When you are building this bridge, you should create and cut all others segments.
+
+Now iterate over all start positions of the last segment. For every of them you should decrease powers of demons that is covered by this segment and calculate minimal number of moves for destroy all demons (do not forgen about the last segment!).
+
+You can see that for every fallen ice cube you need exactly 3 operations --- go left, create cube, go right. For cutting a segment you need exactly 2 operations --- create cube and destroy one. Therefore all demons should be covered by minimal number of segments that no cube falls on an empty position. It can be done by greedy algorithm.
+
+Total number of operations for every start position of the last segment can be calculated in *O*(*n*). Total number of checks is *O*(*n*), so we have an *O*(*n*2) solution.
+
+After all, answer can be built very easy.
diff --git a/editorials/91.md b/editorials/91.md
@@ -0,0 +1,100 @@
+Source: https://codeforces.com/blog/entry/2182
+
+**Problems A(div2), B(div2)**
+
+In these problems you should only realize what was written is the statement. In problem *B* wasn't recommended to use BigInteger in Java because of slow speed.
+
+**Problem C(div2), A(div1)**
+
+In this problem letters from *s*1 should be taken greedily: take the left letter from the right of the last used letter, if there is no necessary letter from the right of the right used letter the the search should be started from the beginning of string *s*1 and the answer should be increased by one. But the brute solution get *TL* and have complexity *O*(*Ans* * |*s*1|).
+
+This solution can be optimized using the following way. For every position in *s*1 let's precalculate positions of the closest letters from the right of it from the alphabet. It can be done by moving from the right to the left ins *s*1 and remembering the last position of every type of symbol. This solution have complexity *O*(|*s*1| * *K* + |*s*2|), where *K* is a size of alphabet.
+
+**Problem D(div2), B(div1)**
+
+There were a lot of different solutions but I will tell you the author solution. Let's precalculate [*i*, *n*]. It can be done with the time equal to *O*(*n*) moving from the right to the left. Define [*i*, *n*] as *Min**i*. Obviously, that *Min**i* < = *Min**i* + 1. Now for every position *i* using binary search let's find j (*j* > *i*), that *Min**j* < *a**i* and *Min**j* + 1 > = *a*{*i*}. For such *j* there are no walruses who have age younger then walrus *i*. It's obviously because *Min**j* is the minimum on [*j*, *n*]. If there is no such *j* then print - 1 else print *j* - *i* - 1.
+
+**Problem E(div2), C(div1)**
+
+We will count the number of ski bases including the base consisted of empty subset of edges (before printing just subtract one). In the beginning the number of bases is equal to 1. If we connect vertexes in the same connected components then the result should be multiplied by 2 else do nothing. You should use DJS data structure to know information about connected components where vertexes are and to unite them.
+
+Why is it correct?
+To prove it we will use the matrix of incidence *I*, rows in it will be edges and columns will be vertexes. Let's define *xor* of two rows. *Xor* of two rows *a* и *b* will be row *c* such that *c**i* = *a**i* xor *b**i*. Notice if *xor* of some subset of rows is equal to a zero row then this subset form the ski base. It's correct because, the degree of contiguity of every vertex is even, so we can form an Euler cycle in every connected component. The answer is 2(*m* - *rank*(*I*)).
+
+Why it is correct? Let's write the number of edge from the right of each row which suit this row. While finding the matrix rank using gauss method with *xor* operation, we will *xor* the subsets from the right of the strings. In the end the subsets of edges written from the right of the zero rows will form the basis of the linear space. Thats why we can take any subset of vectors from basis and make up a new ski base. The number of these subsets is equal to 2*k* = 2(*m* - *rank*(*I*)), where k is the number of zero rows.
+
+The last thing we should notice that the adding row is liner depended if and only if there is exist a way between the vertexes *a* and *b* (*a* and *b* are the ends of the adding edge).
+
+**Задача D(div1)**
+
+Let's find all cycles in substitution:
+1 2 3 4 5 ...
+*a*1 *a*2 *a*3 *a*4 *a*5 ...
+For example, in sequence *a* = {2, 1, 4, 5, 3} exist two cycles with length 2 and 3 on positions 1 2 and 3 4 5 respectively. If the length of the cycle is more than 5, then we can take 5 consecutive elements and make a new order in such way that 4 elements will take their places where they should be in sorted array. In common: if we take *p* elements in a cycle of length more than *p*, the we can make a new order in such way that *p* - 1 elements will take their places where they should be in sorted array. If the cycle length is *p* we can sort all the elements taking *p* elements from it. Next in the analysis I will define length of a cycle as a real length of a cycle - 1 (now I can say that if we take *p* consecutive elements then *p* - 1 will take the right places).
+We also can take some elements in one and some elements in other cycles. We can make up division numbers from 2 to 5 into a sum to see how we can use them: 5, 4, 3, 2, 2 + 3, 2 + 2. We can take, for example, three elements in one cycle and two in other, their sizes were reduced by 2 and 1.
+The task now is to get all cycle lengths equal to zero. Let's to suppose that an optimal solution have four operations which decrease the same cycle length by one. We will work with operations of 5 elements and which are not process the same cycle except one, because it's more stronger condition.
+Such operation can be shown as a table where rows are operations, columns are cycles and cells of table are the values on which cycles will be reduced.
+a b c d e
+1 2
+1 2
+1 2
+1 2
+Replace operations this way:
+a b c d e
+4
+ 2 1
+ 1 2
+ 2
+The number of operations was not increased, but now we can see that if there is an optimal solution where one cycle reduced by one four times then there is an optimal solution where no cycles reduced by one four times. Look at some other replacements:
+a b c
+2 1
+2 1
+Replace by:
+a b c
+4
+ 1 1
+
+and
+
+a b c d
+2 1
+1 2
+1 2
+Replace by:
+a b c d
+4
+ 1 2
+ 2
+Now we can see that there is an optimal solution where no operation reducing one cycle in ways:1 + 1 + 1 + 1, 2 + 2, 1 + 1 + 2. That's why we can reduce any cycle by 4 while it's size is > = 4. Let's use zhe same method to prove that cycles of size 3 reduced by 3 in some optimal solution.
+
+a b c
+2 1
+1 2
+Replace by:
+a b c d
+3
+ 1 2
+
+and
+
+a b c d
+1 2
+1 2
+1 2
+Replace by:
+a b c d
+3
+ 2 1
+ 1 2
+
+Now we have cycles only with size 1 or 2. Let's brute the number of operations to process like {2, 2} - > {0, 1} (one cycle will be reduced from 2 to 1 and the other will be reduced from 2 to 0). Fix some such number and make these operations. Now we should process the maximum available operations like {2, 1} - > {0, 0}. After it we will have no cycles or some cycles of size 1 or some cycles of size 2. In the second case we should do the maximum of available operations like {1, 1} - > {0, 0} and if one cycle lasts we should do {1} - > {0}. In the third case we should to do operations like {2} - > {0}. Using such way we can find the optimal set of operations. We shouldn't divide cycle into a parts because it makes the number of operation bigger or the same. Stress test shows the uniting cycles will not improve the answer.
+
+**Problem E(div1)**
+
+We are given the array where the value in each cell is described by the formula depends on T *val**i* = *a**i* + *b**i* * *T* (in geometry mean it is a line equation). Lt's divide the array in blocks of size *d* ~ *sqrt*(*n*): [0;*d*), [*d*, *d* * 2), [*d* * 2, *d* * 3), ..., [*d* * *k*, *n*). Now let's precalculate for each block time moments when the leader of the block changes. So as we have line equation we can perform an intersection of half planes. On *Oy* axis values of the cells are marked and the time moments marked on *Ox* axis. we are interested on *x* coordinate of points of intersections and number of leader after time *x*. So now we know time moment of leader changing for every block. For each block it takes *O*(*d* * *log*(*d*)) time. The number of blocks (*k*) is about *n* / *d* ~ *n* / *sqrt*(*n*) ~ *sqrt*(*n*) so all the process will take *O*(*n* * *log*(*n*)) time.
+
+Let's sort all queries by increasing *t**i*. Now we should to perform queries one by one. Brute all blocks which lay into the query interval. For each such block we will keep up the leader for current time. For this let's process all the time moment of leader changing until *t**i* inclusively and relax leader on the current block. The time moments which ware processed should be erased, they are not keep any useful information ,because all queries sorted by *t**i*. Let's process all cells which were not covered by the processed blocks but covered by the query and relax the leader for the query.
+
+The number of erasing time moments of leader changing is not mere then n and every query need *O*(*sqrt*(*n*)) time to calculate answer without erasing time moments. So the complexity of algorithm is *O*(*n* * *log*(*n*) + *m* * *sqrt*(*n*)).
+
+Interval tree also can be used to solve this problem. Such solution has complexity *O*(*n* * *log*(*n*)), but *O*(*n* * *log*(*n*)) memory.
diff --git a/editorials/92.md b/editorials/92.md
@@ -0,0 +1,100 @@
+Source: https://codeforces.com/blog/entry/2182
+
+**Problems A(div2), B(div2)**
+
+In these problems you should only realize what was written is the statement. In problem *B* wasn't recommended to use BigInteger in Java because of slow speed.
+
+**Problem C(div2), A(div1)**
+
+In this problem letters from *s*1 should be taken greedily: take the left letter from the right of the last used letter, if there is no necessary letter from the right of the right used letter the the search should be started from the beginning of string *s*1 and the answer should be increased by one. But the brute solution get *TL* and have complexity *O*(*Ans* * |*s*1|).
+
+This solution can be optimized using the following way. For every position in *s*1 let's precalculate positions of the closest letters from the right of it from the alphabet. It can be done by moving from the right to the left ins *s*1 and remembering the last position of every type of symbol. This solution have complexity *O*(|*s*1| * *K* + |*s*2|), where *K* is a size of alphabet.
+
+**Problem D(div2), B(div1)**
+
+There were a lot of different solutions but I will tell you the author solution. Let's precalculate [*i*, *n*]. It can be done with the time equal to *O*(*n*) moving from the right to the left. Define [*i*, *n*] as *Min**i*. Obviously, that *Min**i* < = *Min**i* + 1. Now for every position *i* using binary search let's find j (*j* > *i*), that *Min**j* < *a**i* and *Min**j* + 1 > = *a*{*i*}. For such *j* there are no walruses who have age younger then walrus *i*. It's obviously because *Min**j* is the minimum on [*j*, *n*]. If there is no such *j* then print - 1 else print *j* - *i* - 1.
+
+**Problem E(div2), C(div1)**
+
+We will count the number of ski bases including the base consisted of empty subset of edges (before printing just subtract one). In the beginning the number of bases is equal to 1. If we connect vertexes in the same connected components then the result should be multiplied by 2 else do nothing. You should use DJS data structure to know information about connected components where vertexes are and to unite them.
+
+Why is it correct?
+To prove it we will use the matrix of incidence *I*, rows in it will be edges and columns will be vertexes. Let's define *xor* of two rows. *Xor* of two rows *a* и *b* will be row *c* such that *c**i* = *a**i* xor *b**i*. Notice if *xor* of some subset of rows is equal to a zero row then this subset form the ski base. It's correct because, the degree of contiguity of every vertex is even, so we can form an Euler cycle in every connected component. The answer is 2(*m* - *rank*(*I*)).
+
+Why it is correct? Let's write the number of edge from the right of each row which suit this row. While finding the matrix rank using gauss method with *xor* operation, we will *xor* the subsets from the right of the strings. In the end the subsets of edges written from the right of the zero rows will form the basis of the linear space. Thats why we can take any subset of vectors from basis and make up a new ski base. The number of these subsets is equal to 2*k* = 2(*m* - *rank*(*I*)), where k is the number of zero rows.
+
+The last thing we should notice that the adding row is liner depended if and only if there is exist a way between the vertexes *a* and *b* (*a* and *b* are the ends of the adding edge).
+
+**Задача D(div1)**
+
+Let's find all cycles in substitution:
+1 2 3 4 5 ...
+*a*1 *a*2 *a*3 *a*4 *a*5 ...
+For example, in sequence *a* = {2, 1, 4, 5, 3} exist two cycles with length 2 and 3 on positions 1 2 and 3 4 5 respectively. If the length of the cycle is more than 5, then we can take 5 consecutive elements and make a new order in such way that 4 elements will take their places where they should be in sorted array. In common: if we take *p* elements in a cycle of length more than *p*, the we can make a new order in such way that *p* - 1 elements will take their places where they should be in sorted array. If the cycle length is *p* we can sort all the elements taking *p* elements from it. Next in the analysis I will define length of a cycle as a real length of a cycle - 1 (now I can say that if we take *p* consecutive elements then *p* - 1 will take the right places).
+We also can take some elements in one and some elements in other cycles. We can make up division numbers from 2 to 5 into a sum to see how we can use them: 5, 4, 3, 2, 2 + 3, 2 + 2. We can take, for example, three elements in one cycle and two in other, their sizes were reduced by 2 and 1.
+The task now is to get all cycle lengths equal to zero. Let's to suppose that an optimal solution have four operations which decrease the same cycle length by one. We will work with operations of 5 elements and which are not process the same cycle except one, because it's more stronger condition.
+Such operation can be shown as a table where rows are operations, columns are cycles and cells of table are the values on which cycles will be reduced.
+a b c d e
+1 2
+1 2
+1 2
+1 2
+Replace operations this way:
+a b c d e
+4
+ 2 1
+ 1 2
+ 2
+The number of operations was not increased, but now we can see that if there is an optimal solution where one cycle reduced by one four times then there is an optimal solution where no cycles reduced by one four times. Look at some other replacements:
+a b c
+2 1
+2 1
+Replace by:
+a b c
+4
+ 1 1
+
+and
+
+a b c d
+2 1
+1 2
+1 2
+Replace by:
+a b c d
+4
+ 1 2
+ 2
+Now we can see that there is an optimal solution where no operation reducing one cycle in ways:1 + 1 + 1 + 1, 2 + 2, 1 + 1 + 2. That's why we can reduce any cycle by 4 while it's size is > = 4. Let's use zhe same method to prove that cycles of size 3 reduced by 3 in some optimal solution.
+
+a b c
+2 1
+1 2
+Replace by:
+a b c d
+3
+ 1 2
+
+and
+
+a b c d
+1 2
+1 2
+1 2
+Replace by:
+a b c d
+3
+ 2 1
+ 1 2
+
+Now we have cycles only with size 1 or 2. Let's brute the number of operations to process like {2, 2} - > {0, 1} (one cycle will be reduced from 2 to 1 and the other will be reduced from 2 to 0). Fix some such number and make these operations. Now we should process the maximum available operations like {2, 1} - > {0, 0}. After it we will have no cycles or some cycles of size 1 or some cycles of size 2. In the second case we should do the maximum of available operations like {1, 1} - > {0, 0} and if one cycle lasts we should do {1} - > {0}. In the third case we should to do operations like {2} - > {0}. Using such way we can find the optimal set of operations. We shouldn't divide cycle into a parts because it makes the number of operation bigger or the same. Stress test shows the uniting cycles will not improve the answer.
+
+**Problem E(div1)**
+
+We are given the array where the value in each cell is described by the formula depends on T *val**i* = *a**i* + *b**i* * *T* (in geometry mean it is a line equation). Lt's divide the array in blocks of size *d* ~ *sqrt*(*n*): [0;*d*), [*d*, *d* * 2), [*d* * 2, *d* * 3), ..., [*d* * *k*, *n*). Now let's precalculate for each block time moments when the leader of the block changes. So as we have line equation we can perform an intersection of half planes. On *Oy* axis values of the cells are marked and the time moments marked on *Ox* axis. we are interested on *x* coordinate of points of intersections and number of leader after time *x*. So now we know time moment of leader changing for every block. For each block it takes *O*(*d* * *log*(*d*)) time. The number of blocks (*k*) is about *n* / *d* ~ *n* / *sqrt*(*n*) ~ *sqrt*(*n*) so all the process will take *O*(*n* * *log*(*n*)) time.
+
+Let's sort all queries by increasing *t**i*. Now we should to perform queries one by one. Brute all blocks which lay into the query interval. For each such block we will keep up the leader for current time. For this let's process all the time moment of leader changing until *t**i* inclusively and relax leader on the current block. The time moments which ware processed should be erased, they are not keep any useful information ,because all queries sorted by *t**i*. Let's process all cells which were not covered by the processed blocks but covered by the query and relax the leader for the query.
+
+The number of erasing time moments of leader changing is not mere then n and every query need *O*(*sqrt*(*n*)) time to calculate answer without erasing time moments. So the complexity of algorithm is *O*(*n* * *log*(*n*) + *m* * *sqrt*(*n*)).
+
+Interval tree also can be used to solve this problem. Such solution has complexity *O*(*n* * *log*(*n*)), but *O*(*n* * *log*(*n*)) memory.
diff --git a/editorials/93.md b/editorials/93.md
@@ -0,0 +1,53 @@
+Source: https://codeforces.com/blog/entry/2216
+
+Это решение этой задачи было придумано однажды ночью при разработке совершенно другого контеста :)
+
+Пусть  - ответ задачи.
+
+Тогда верен факт (например, можно доказать его из формулы включений-исключений)
+
+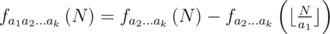
+
+Простой расчет по этой формуле занимает много времени. Можно заметить или знать, что на самом деле аргумент функции достаточно быстро становится маленьким числом, особенно если начальный набор чисел упорядочить по убыванию. Решение с сохранением для маленьких значений аргумента (при должной оптимизации) давало время порядка 1с на худшем тесте и являлось, видимо, неизбежным.
+
+Понятно, что такое решение у меня было, и очень хотелось увеличить ограничение по N раз в 20, чтобы его отсечь, однако не хотелось делать участникам, пишущим на Java, совсем-совсем плохо.
+
+Представим, что мы честно, на листочке, хотим провести расчет по вышеуказанной формуле, например:
+
+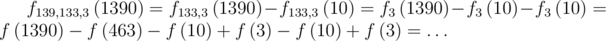
+
+Стоп! Так считала наша программа, а не мы. Мы считали вот так:
+
+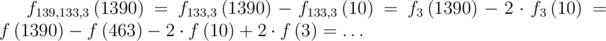
+
+Это толкает нас к следующей идее: будем представлять наше состояние на шаге *j* двумя массивами *X**j* и *Y**j*, имея ввиду
+
+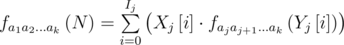
+
+Причем на последнем шаге *j* = *k* будем иметь
+
+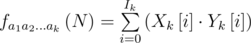
+
+А переход от шага *j* к шагу *j* + 1 выполняется по самой первой формуле с последующим слиянием отсчетов с одинаковым *Y* (массивы в любой момент поддерживаются сортированными, фактически производится слияние прошлого с обновлением и т.д.)
+
+Сложность этого решения, будет, очевидно, 
+
+Утверждение.
+
+
+
+Доказательство.
+
+Любое число, попадающее в массив *Y*, имеет вид  для некоторого натурального *a*. Заметим, что
+
+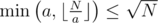
+
+А число вида  задается однозначно либо  (самим собой), либо *a*, из чего очевидным образом следует доказываемое утверждение.
+
+Таким образом, сложность этого решения 
+
+Казалось бы, много (операции деления, все же), но при сортировке по убыванию входных данных наша оценка существенно завышена для первых итераций.
+
+Решение, написанное с оптимизацией хранения для маленьких отсчетов Y (можно посмотреть мои посылки) на сервере CF выполняется порядка 300мс на худшем тесте и укладывается в 2 секунды для *N* = 1015, *k* = 100 (т.е. решает задачу при ограничении на *N* два порядка больше)
+
+Вопросы, предложения, пожелания?
diff --git a/editorials/94.md b/editorials/94.md
@@ -0,0 +1,128 @@
+Source: https://codeforces.com/blog/entry/2208
+
+At first I tell about the contest at all.
+
+My problems in the contest were A-div2, B-div2, C-div2/A-div1, E-div2/C-div1, D-div1. I wanted to make only div.2 round, but then we decided to give you seven problems at both divisions. [MikeMirzayanov](../../../profile/MikeMirzayanov "Штаб, MikeMirzayanov") prepared the problem about milk pouring and [anonymous](../../../profile/anonymous "Майор anonymous") gave E-div1 problem. Also [RAD](../../../profile/RAD "Штаб, RAD") gave some advices to complicate problems Azembler and Flags a bit.
+
+And now let's start analysis.
+
+
+**Problem A (div.2) - Restoring Password**
+
+Password was very easy to restore. You should just iterate over groups of 10 characters in the first string and over all codes. Then, if some number's code is equal to the group - print that number.
+
+Here's the example: <http://pastebin.com/hMV0NcjN>
+
+**Problem B (div.2) - Friends**
+
+Let's construct the graph where vertices correspond to the people and edges correspond to the relationships. Then paint each edge in this way: edge will be red if the men connected by it are friends and black otherwise. Now let's think what is "three pairwise acquainted people" and "three pairwise unacquainted people". We see that they are cycles of only red and only black vertices correspondingly, and the length of these cycles is 3.
+
+Now we know the solution: write 3 "for" cycles, one cycle for one vertex, and check if the edges between these vertices are only red or only black.
+
+Here's the solution: <http://pastebin.com/gswaxGmM>
+
+Another way to solve it is to notice the answer is FAIL if and only if graph has exactly 5 edges and they all together form a cycle with a length 5. It's very funny solution, I think. Here's the code: <http://pastebin.com/09T0ixrJ>
+
+**Problem A (div.1) / C (div.2) - Frames**
+
+The problem is easy, but there were many tricky cases - and contestants show it successful :) I added almost all these cases to the pretests because I didn't want to arrange [Beta Round 60](https://codeforces.com/contest/65/standings).
+
+So let's solve the problem. At first notice that the answer is not greater than 3 because we always can do three selections (maybe, some of them are empty): with first selection we select end of the first row, with second one - begin of the last row, and with last one - all remaining folders (they form the rectangle).
+
+The best way is to find all cases with answer 1 and 2. Try to do it.
+
+If the answer is 1, we can select all folders from *a* to *b* with one selection. There must be nothing hard to detect these cases:
+
+* first and last folders are in the same row (21 5 7 9);
+* first folder is in the first column, and the last folder - in the last column (21 5 1 15), сase *m* = 1 is included here;
+* first folder is in the first column, and the last folder is *n* (21 5 6 21). Case when we must select all folders is included here. I was very surprised when I saw that many contestants forgot about it.
+
+And these are the cases with answer 2:
+
+* first and last folders are in the adjacent rows (21 5 8 14);
+* first folder is in the first column (21 5 6 13);
+* last folder is in the last column (21 5 4 15);
+* last folder is *n* (21 5 4 21);
+* and another tricky case: if the column where first folder is located is just at right from the column where the last column is located (21 5 3 12).
+
+If no one of these conditions is true, answer is 3.
+
+Here's the solution: <http://pastebin.com/8QRytzzF>
+
+
+
+**Problem B (div.1) / D (div.2) - End of Exams**
+
+Greedy algorithm solves this problem. We should consecutively try to pour milk from each bottle into each available cup and in maximal possible amount.
+
+Also we always need to know, how much milk is in each bottle and each cup, for each cup - bottles from which we have poured milk, and for each bottle - cups into which we have poured milk.
+
+Writing it is not hard. But where is one special moment - if we compare real numbers, we must use EPS, or we can get WA on test 12 (50 1000 49). Some programs write NO on this test while answer is YES, because of wrong comparing of real numbers.
+
+It must be said that answer can be calculated in integers: just set the volume of milk in each bottle *mn*. And only when we will print the answer, we divide each volume by *mn* and multiply by *w*. All three jury solutions didn't think up this :)
+
+Here's the solution: <http://pastebin.com/HG5Nrxne> (be careful, it's not as beautiful as previous ones)
+
+
+
+**Problem C (div.1) / E (div.2) - Azembler**
+
+I don't know why so few coders have solved it. Small limitations for *n* and big time limit - 5 seconds - hint that it's backtracking. Also, no need to be a soothsayer to understand that maximal answer is about 5.
+
+Solving it is clear. You should keep all current registers at the vector and call some function that goes over all current registers and calculate new values, then calls itself recursively. In that process we can also save the program itself.
+
+To avoid TLE you should not make recursive calls if the deep of recursion is larger than current answer, should not go to the states where you get a number larger than *n* or less than current biggest number. And if you reach exactly *n*, you should update answer and copy the program to the safe place.
+
+There are some hacks to speed up this approach: for example, iterate over numbers in descending order (it works faster), but 5 seconds is such TLE that you can solve it any way. Or you can launch backtracking for the specific answer (increasing it) while the program won't be found (I don't know how this method is named in English). Also, some contestants have solved it using BFS.
+
+Here are two solutions: standard backtracking (<http://pastebin.com/Z6ZF36st>) and backtracking for the specific answer (<http://pastebin.com/viiYF9CB>).
+
+
+
+**Problem D (div.1) - Flags**
+
+I think my solution is not optimal, it's too long. Many solutions submitted during the contest are shorter. But I tell you about my solution.
+
+At first I solve the problem for the number of stripes equals *N* (or *L* = *R*).
+
+Let  is the number of flags with exactly *N* stripes where symmetrical flags are not identical. Try to get the answer using this designation.
+
+At first sight it seems that answer is . But it's not true for the palindromes. For example, for non-palindromes WBWB and BWBW we should count only one of them, but for the palindromes, such as WBW, it leads to mistake, because each palindrome is symmetrical to itself.
+
+So for the flags with even number of stripes formula 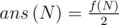 is correct, because there are not palindromes among them. And if *N* is odd, the correct formula is 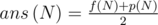, where  is the number of palindromes with *N* stripes. Each palindrome is definited by its first  stripes, and we can write that 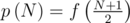.
+
+Now we can give an answer if we know how to calculate number of flags where symmetrical flags are not equal. Notice that if we know two last stripes of the flag, we can definitely say if we can add another stripe to its end.
+
+Let's use dynamic programming. As a state we can take a vector  with a length 8 where each its component keeps a number of flags with *N* stripes and definite two last colors (exactly 8 options). And 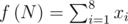 is total number of flags with *N* stripes.
+
+As start state we can take vector  which consists of ones (because there are 8 flags with a length 2, one flag for one possible combination of two colors). And how to calculate ?
+
+It turns out that there is some matrix *A* that 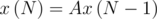. Its elements can be found even using pen and paper: for example, let's we have a combination of two last stripes WB. Then it's possible to add white or yellow stripe to the end, and the last stripes will be BW and BY correspondingly. It means that we can write 1 to the matrix where the row are BW or BY and the column is WB.
+
+We're about the finish. It's obvious that 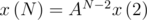. Power of matrix can be calculated with a logarithmic time - that's because our problem is solved. And don't forget if *N* = 1 then answer is 4 and there's no need to do these calculations.
+
+But it was only problem where *L* = *R*. Let's find a solution for the segment .
+
+I know two ways to do it. First way is to add a new component to the vector and new row and column to the matrix. This new component should keep the total number on the segment  (if *L* = 1, we can write "if" somewhere at the beginning of the program). And the matrix *A* should be changed a bit: try to do it by yourself.
+
+I like the second way. As we did it earlier, we will find a number of flags where symmetrical ones are different, but on the segment . It is equal to 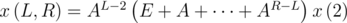. Let's learn how to calculate the sum *E* + *A* + ... + *A**N* quickly.
+
+Let *b* is such maximal power of 2 that 2*b* - 1 ≤ *N*. We can write 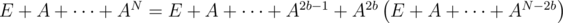.
+
+And apply some math magic to the first part of the previous formula: 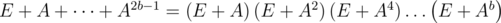. And the expression in the brackets at the second part of that formula is... I think you've already understood it :)
+
+We forgot about the palindromes, but it's very easy to calculate their number. Let's suppose that *L* and *R* are odd (if they are even, we can add one to *L* and substract one from *R*). Then 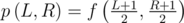.
+
+That's all. Don't forget to apply "mod" operation after each operation and examine border cases carefully. And here's the solution: <http://pastebin.com/wHu1tPgd> (yes, "matrix" and "vector" type definitions are strange - I've totally forgotten how to write in Pascal)
+
+
+**Problem E (div.1) - Lostborn**
+
+This problem can be solved using inclusion-exclusion principle. If  is the answer, then the following formula works: 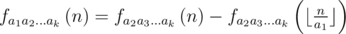. But if you write only this recursive function, you get TLE. Many contestants got TLE and were hacked because they didn't run maximal test on their computers.
+
+And the others who sensed that something was wrong memorized the answers for small *n* and all *a**i*. For example, you can see solution by [rng_58](../../../profile/rng_58 "Полковник rng_58") who won the contest, or this solution: <http://pastebin.com/4kcfJdAi>.
+
+[anonymous](../../../profile/anonymous "Майор anonymous"), the author of this problem, wrote his thoughts about it there: [http://codeforces.com/blog/entry/2216](../2216) (but now there's only russian version). His solution works even if *n* = 1015 and it can be viewed here: [http://codeforces.com/problemset/status/93/E?order=BY_CONSUMED_TIME_ASC](https://codeforces.com/problemset/status/93/E?order=BY_CONSUMED_TIME_ASC). It seems that any solution submitted during the contest would get TLE if *n* = 1015.
+
+
+Sorry for my English :)
diff --git a/editorials/95.md b/editorials/95.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/2257
+
+**Div.2 – A Football**
+
+In this problem you must find longest substring consisting of equal characters and compare it with 7.
+
+**Div.2 – B Lucky Numbers - 2**
+
+If the length of input number |N| is odd, then, obviously, resulting number will have length |N|+1 and will be like this: 4444…7777, at first (|N|+1)/2 digits 4, then the same number of 7’s. If the number has even length, then, probably, resulting number will have size |N|, or |N|+2. So, length of the resulting number will have not more than 10 digits. So, we can recursive generate lucky numbers with size <= 10, take the smallest super lucky number which is greater than or equal to N.
+
+**Div.1 – A, Div. 2 – C – Hockey**
+
+Let B[i] = true, if character in position i is in some substring of W which is in dictionary. For each B[i] = true, do next:
+
+· If S[i] = letter and letter = ‘a’, then S[i] = ‘b’,
+
+· If S[i] = letter and letter != ‘a’ then S[i] = ‘a’;
+
+· If S[i] != letter, then S[i] = letter.
+
+**Div.1 - B. – Lucky Number**
+
+Read Div.2 – B
+
+Notice, that answer will looks like this: to some position result will be equal with input string (that part must be lucky), next digit well be greater, the rest of digits are not important. That guarantees us that result will be greater than or equal to N. As rightest this position will be as number will be lesser. Some of the positions may not be ok to us. Let chosen position is i. Left part must be lucky. If S[i] < ‘4’, we can assign S[i] = ‘4’, then fill minimally right part. If S[i] < ‘7’, we can assign ‘7’ to it, like in prevision case. Call position i ok, if absolute different between number of ‘4’ and ‘7’ in part from 0 to i, inclusive is not more than n-i-1. If we chose some rightmost position, which is ok, now we must fill right part. How to do it? If we can assign to some position (we will fill them from left to right) ‘4’ and this position is still ok, then we place ‘4’, else we assign ‘7’. If there is no ok positions at all, resulting number will looks like this: 4444…7777, when number of digits 4 = number of digits 7 = (|N|+2)/2.
+
+**Div.1 - C, Div.2 - D – Volleyball**
+
+At first in this simple problem you need to find shortest path between all pair of junctions. That can’t be done using O(N^3) algorithms, so you must use Dijkstra algorithm to find this in O(N*N*logN) time. Next part of this problem is to create new matrix, G[i][j] = C[i], if D[i][j] <= R[i], else G[i][j] = INF. Here D[i][j] – length of shortest path between I and j. So, result is shortest path between X and Y using matrix G. That can be done using simple Dijkstra algorithm.
+
+**Div.1 – D, Div.2 – E. Horse Races**
+
+Traditionally I remain that answer is Result(0..R) – Result(0..L-1).
+
+Let we have array DP[x][y][z] – number of x-digits number if last lucky digit was on position y, bool z (0 or 1) – was the pair of lucky digits with less than or equal distance then K (call it lucky pair)? Now, let S – string which represent number N. Let F(x, y, z) – result for substring of first x digits, y – position of last lucky digit, z – (0 or 1) – was the lucky pair before? Try to assign some digits on position x. If this digit is less than S[i], then add to result for F(x, y, z) DP[n-x-1][yy][zz] (yy – updated position of last lucky digit, zz – updated bool for lucky pairs). If this digit is equal to S[i], add F(x+1, yy, zz). DP can be calculated simply. Let from state (x, y, z) we place some digit d on position x. Then, we can go to state (x+1, yy, zz). Again, yy and zz – updated parameters.
+
+Complexity – O(T * |N}).
+
+**Div.1 – E – Lucky Country.**
+
+Let A[i] - sorted array of sizes of different connection components, C[i] – number of connection components of size A[i]. Sum for all C[i]*A[i] is equal to N. Size of A will be O(sqrt(N)).
+
+**Solution** **#****4** (by RAD)
+
+Coming soon…
+
+**Solution** **#7**
+
+Let all C[i] = (2^k)-1, i. e. C[i] = 1 + 2 + 4 + 8 + … + 2^(k-1). Obviously, that if chose some subset of this powers we can get any number from 0 to C[i], inclusive. So, the problem now is next: For each A[i] is log(C[i]) things (cost of this thing is size of subset that create it), each can be used at most once. This is standard “Knapsack” problem (read [this](https://en.wikipedia.org/wiki/Knapsack_problem)). Complexity of this algorithm is O(N * S), when S is the sum for all log(C[i]). If C[i] is not power of 2, then we must find maximal k, which (2^k)-1 <= C[i] and add C[i]-((2^k)-1) to set.
+
+**Sorry for my poor English! If you do not understand something – write in comments, please.**
diff --git a/editorials/96.md b/editorials/96.md
@@ -0,0 +1,51 @@
+Source: https://codeforces.com/blog/entry/2257
+
+**Div.2 – A Football**
+
+In this problem you must find longest substring consisting of equal characters and compare it with 7.
+
+**Div.2 – B Lucky Numbers - 2**
+
+If the length of input number |N| is odd, then, obviously, resulting number will have length |N|+1 and will be like this: 4444…7777, at first (|N|+1)/2 digits 4, then the same number of 7’s. If the number has even length, then, probably, resulting number will have size |N|, or |N|+2. So, length of the resulting number will have not more than 10 digits. So, we can recursive generate lucky numbers with size <= 10, take the smallest super lucky number which is greater than or equal to N.
+
+**Div.1 – A, Div. 2 – C – Hockey**
+
+Let B[i] = true, if character in position i is in some substring of W which is in dictionary. For each B[i] = true, do next:
+
+· If S[i] = letter and letter = ‘a’, then S[i] = ‘b’,
+
+· If S[i] = letter and letter != ‘a’ then S[i] = ‘a’;
+
+· If S[i] != letter, then S[i] = letter.
+
+**Div.1 - B. – Lucky Number**
+
+Read Div.2 – B
+
+Notice, that answer will looks like this: to some position result will be equal with input string (that part must be lucky), next digit well be greater, the rest of digits are not important. That guarantees us that result will be greater than or equal to N. As rightest this position will be as number will be lesser. Some of the positions may not be ok to us. Let chosen position is i. Left part must be lucky. If S[i] < ‘4’, we can assign S[i] = ‘4’, then fill minimally right part. If S[i] < ‘7’, we can assign ‘7’ to it, like in prevision case. Call position i ok, if absolute different between number of ‘4’ and ‘7’ in part from 0 to i, inclusive is not more than n-i-1. If we chose some rightmost position, which is ok, now we must fill right part. How to do it? If we can assign to some position (we will fill them from left to right) ‘4’ and this position is still ok, then we place ‘4’, else we assign ‘7’. If there is no ok positions at all, resulting number will looks like this: 4444…7777, when number of digits 4 = number of digits 7 = (|N|+2)/2.
+
+**Div.1 - C, Div.2 - D – Volleyball**
+
+At first in this simple problem you need to find shortest path between all pair of junctions. That can’t be done using O(N^3) algorithms, so you must use Dijkstra algorithm to find this in O(N*N*logN) time. Next part of this problem is to create new matrix, G[i][j] = C[i], if D[i][j] <= R[i], else G[i][j] = INF. Here D[i][j] – length of shortest path between I and j. So, result is shortest path between X and Y using matrix G. That can be done using simple Dijkstra algorithm.
+
+**Div.1 – D, Div.2 – E. Horse Races**
+
+Traditionally I remain that answer is Result(0..R) – Result(0..L-1).
+
+Let we have array DP[x][y][z] – number of x-digits number if last lucky digit was on position y, bool z (0 or 1) – was the pair of lucky digits with less than or equal distance then K (call it lucky pair)? Now, let S – string which represent number N. Let F(x, y, z) – result for substring of first x digits, y – position of last lucky digit, z – (0 or 1) – was the lucky pair before? Try to assign some digits on position x. If this digit is less than S[i], then add to result for F(x, y, z) DP[n-x-1][yy][zz] (yy – updated position of last lucky digit, zz – updated bool for lucky pairs). If this digit is equal to S[i], add F(x+1, yy, zz). DP can be calculated simply. Let from state (x, y, z) we place some digit d on position x. Then, we can go to state (x+1, yy, zz). Again, yy and zz – updated parameters.
+
+Complexity – O(T * |N}).
+
+**Div.1 – E – Lucky Country.**
+
+Let A[i] - sorted array of sizes of different connection components, C[i] – number of connection components of size A[i]. Sum for all C[i]*A[i] is equal to N. Size of A will be O(sqrt(N)).
+
+**Solution** **#****4** (by RAD)
+
+Coming soon…
+
+**Solution** **#7**
+
+Let all C[i] = (2^k)-1, i. e. C[i] = 1 + 2 + 4 + 8 + … + 2^(k-1). Obviously, that if chose some subset of this powers we can get any number from 0 to C[i], inclusive. So, the problem now is next: For each A[i] is log(C[i]) things (cost of this thing is size of subset that create it), each can be used at most once. This is standard “Knapsack” problem (read [this](https://en.wikipedia.org/wiki/Knapsack_problem)). Complexity of this algorithm is O(N * S), when S is the sum for all log(C[i]). If C[i] is not power of 2, then we must find maximal k, which (2^k)-1 <= C[i] and add C[i]-((2^k)-1) to set.
+
+**Sorry for my poor English! If you do not understand something – write in comments, please.**
diff --git a/editorials/97.md b/editorials/97.md
@@ -0,0 +1,18 @@
+Source: https://codeforces.com/blog/entry/2293
+
+Так как остальные задачи я не то что не пытался решить, а даже не читал, публикую те решения, которые узнал
+
+### Задача A. Домино
+
+Для начала поймём, что на квадраты 2x2 всё поле разбивается однозначно и это можно сделать жадным алгоритмом. Теперь у нас есть 14 квадратов. Далее можно сделать необязательное преобразование, от которого лично мне стало жить проще: построим граф на 14 вершинах, ребро между вершинами будет тогда и только тогда, когда у соответствующих квадратов есть общая доминошка. В принципе, это даже какой-то оптимайз по времени, но не суть важно.
+Теперь задача такова: есть граф на 14 вершинах, надо раскрасить их в цвета от 0 до 6 так, чтобы все рёбра были разными (два ребра одинаковы, если цвета концов совпадают). Утверждается, что решение - перебор. Перебираем цвет первой, второй, третьей, ..., 14й вершины, на каждом шаге проверяем, что у нас не появилось ребро той же расцветки, что уже было (естесственно, делаем это массивом bool'ов). После чего останется вывести ответ и какую-нибудь раскраску.
+Однако это решение может не зайти по времени. Остался один мощный оптимайз. Заметим, что, по сути, разницы между цветами нет. Значит, цвета в раскраске можно переставлять как угодно. Теперь научимся считать количество ответов с точностью до перестановок цветов, а в конце домножим его на 7!=5040. Это просто: достаточно ввести условие, что цвет очередной вершины либо встречался раньше, либо идет сразу после максимального использованного цвета. Например, после цветов 0 1 2 1 0 2 могут идти только цвета 0..3.
+Чтобы уверовать в то, что это решение зайдёт, можно грубо оценить количество ответов. Каждая вершина раскрашена в один из семи цветов, каждый цвет встречается ровно два раза, плюс мы не учитываем различные перестановки. Итого получается 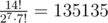, что, очевидно даже при отсечении на последнем шаге рекурсии, влезает в TL.
+
+
+### **Задача B. Надмножество**
+
+Задача была немножко (или множко?) идейной. Одним из возможных решений является разделить множество точек пополам веритикальной прямой (если не получается ровно, та так, чтобы разница была минимальна), решить задачу рекурсивно для двух половин, и добавить на разделяющую прямую точки со всеми встречающимися в ответах для половин y'ами.
+Докажем корректность. Если точки лежат в одной половине, всё мы верим, что верно решили подзадачу. Если же они лежат в разных половинах, то их bounding box пересекает нашу прямую, и в точках пересечения выделенные точки есть (посльку их y'и встречались слева и справа).
+
+Прошу сообщество рассказать остальные задачи в комментариях
diff --git a/editorials/98.md b/editorials/98.md
@@ -0,0 +1,97 @@
+Source: https://codeforces.com/blog/entry/2323
+
+Hi there!
+
+Here is editorial for the round #78.
+
+Russian editorial will be published a bit later - I supposed that there are more people who can understand English (or who can do English -> Russian web page translation) than vice versa.
+
+Again, I'm very sorry for the situation with problem B (div. 1) / D (div. 2). Also, I'm sorry that I underestimated difficulty of the problems. At least, I hope the problems appeared interesting for many contestants.
+
+**Problem A (div. 2) - Help Far Away Kingdom**
+
+Here the problem was to round a number up according to the usual mathematical rules with the exception that if the last digit of integer part is equal to 9, you should output "GOTO Vasilisa.". One may notice that to check whether number's fractional part is not less than 0.5 only one digit just after the decimal point should be analysed. If it is '5' or greater - add one to the last digit of the integer part, and the problem is solved. Probably, the simplest way to deal with the input data was using of the string variables.
+
+**Problem B (div. 2) - Help Chef Gerasim**
+
+The problem was to accurately check what is required in the problem statement. First of all, check whether all volumes in the input are equal. In this case output "Exemplary pages.". Otherwise find two cups with largest and smallest volumes. Suppose their numbers are a and b, and their volumes are v[a] and v[b]. Now suppose that before pouring their volumes were equal to V. Then they contained 2V units of juice before (and after) pouring. So, you need to check whether (v[a] + v[b]) is divisible by 2. If this is not so - output "Unrecoverable confihuration.". Otherwise assign to the cups presumable old volume v[a] = v[b] = (v[a] + v[b])/2. Now if only one pouring have been made, volumes of juice in all cups should be equal, and you print corresponding message "... ml. from ... to ...". If volumes are not equal, print "Unrecoverable configuration" instead.
+
+**Problem A (div. 1) / C (div. 2) - Help Victoria the Wise**
+
+In this problem you were required to find the number of sufficiently different colorings of a cube faces with predefined six colors. The most trivial solution is to introduce some ordering of the cube faces (say, 0 - front, 1 - back, 2 - up, 3 - down, 4 - left, 5 - right), then consider 720 = 6! arrangements of colors over these 6 faces. Each arrangement is some permutation of characters from the input. For each arrangement we find all its 24 rotations - and get 24 strings. Lexicographically smallest string will be representative of this coloring. The answer is the number of different representatives.
+
+**Problem B (div. 1) / D (div. 2) - Help King**
+
+Unfortunately, initial author's solution for this problem appeared wrong. However, the optimality of the below algo was proved by Knuth and Yao in 1976. *Limitation for n in the problem now changed to 10000.*
+
+The process of tossing a coin and making decisions regarding which alternative to choose may be naturally described as drawing some (possibly infinite) binary tree. Each toss "draws" two new branches from every free node of the tree (initially the tree consists of one free node). Whenever the number of free nodes becomes >= n, you turn n free nodes into leaves (onle leaf for each alternative), and proceed with the other free nodes in a similar way. For example, for n == 3 we get the following infitite tree:
+
+o
+
+/ \
+
+o o
+
+/ \ / \
+
+1 2 3 o
+
+/ \
+
+... ...
+
+Now we should evaluate expected length of a random path in this infinite tree now. One may notice that the tree is recursive: since the number of free nodes at every level is strictly less than n, the situation will repeat after maximum of n steps. Once one notices this, it is not so hard to derive formulas for the answer. Since numbers in the answer could be of the order 2^n, one needs to write "long arithmetics", or use Java.BigInteger.
+
+**Problem C (div. 1) / E (div. 2) - Help Greg the Dwarf**
+
+For this problem I assumed numerical solution. But there are several cases to consider. Below without loss of generality we assume a <= b.
+
+1. l <= a <= b. In this case the answer is restricted by the length of the coffin, so the answer is l and it is clear that the coffin l x l can be brought through the corridor (a, b) - let's denote corridor's sizes in this way.
+
+2. a < l <= b. In this case the answer is a, and it is clear that no larger number can be an answer. Indeed, otherwise the coffin (w > a) x (l > a) is impossible to drag through the corridor (a, b).
+
+3. a <= b < l. This is the most general case, where we should rotate the coffin inside the corridor where it has a kink. To maximise the width of the coffin, we want to move it in such a way that one corner of the coffin touches one outer wall of the corridor (suppose bottommost on the picture), and another corner adjacent to the same long side of the coffin touches another outer wall of the corridor (leftmost on the picture). Let's introduce coordinate system in such a way that bottommost wall be OX axis, and leftmost wall - OY axis. Suppose that during the "rotation" process one corner of the coffin is at the point (x,0) (0 <= x <= l), then another corner should be at the point (0,sqrt(l*l-x*x)). And the answer we search for is min {distance from the segment (x,0) - (0,sqrt(l*l-x*x)) to the point (a,b) }, where you take min{} over all 0 <= x <= l. Let this distance at point x be f(x). Since f(x*) is minimal in some point x* and increases everywere to the left and to the right from x*, one may use ternary search to find its minimum.
+
+Exact solution for this problem is also possible: you can reduce the problem to minimizing the dot product of the vectors (a-x,b) and (-x,sqrt(l*l-x*x)) over x. But this leads to the neccessity to find the roots of the fourth-degree polynomial, which is not the best idea during the contest.
+
+**Problem D (div. 1) - Help Monks**
+
+This problem was about famous puzzle "Hanoi towers", but diameters of some discs might be equal. How to solve that? A good thing to do is to write BFS solution to check optimality of your ideas for small inputs (by the way, BSF works quickly for almost all towers that have up to 10 discs) and then try to create an algo which solves the puzzle in an optimal way.
+
+Let C (x1, x2, ..., xn) be a solution (under "solution" here we mean optimal number of moves - the moves itself is easy to get with one recursive procedure; also "solution" is the number of moves to move group of discs from one peg to any other (and not some particular) ) to the puzzle when we have a puzzle with x1 equal largest discs, x2 equal second largest discs and so on. And let U (x1, x2, ..., xn) be a solution to the puzzle when you are allowed not to save the order of the discs (you should still follow the restriction of the initial puzzle not to put larger discs onto the smaller ones, but at the end discs of the same diameter may be in any order).
+
+Then one of the optimal solutions to the problem is the following:
+
+C (x1, x2, ..., xn) = U (x1, x2, ..., xn) if x1 = 1 (*)
+
+C (x1, x2, ..., xn) = 2*x1 - 1 if n = 1 (**)
+
+C (x1, x2, ..., xn) = U (x2, ..., xn) + x1 + U (x2, ..., xn) + x1 + C (x2, ..., xn). (***)
+
+U (x1, x2, ..., xn) = U (x2, ..., xn) + x1 + U (x2, ..., xn) (****)
+
+Why so? One can notice that U() is "almost" solution for our problem: it "flips" order of the bottommost group of equal discs, the order of the rest of the discs remains the same! (try to understand why)
+
+That's why (*) is correct.
+
+The (**) is quite obvious.
+
+The (***) does the following: move (x2, ..., xn) from peg 1 to peg 2 without saving the order. Then move x1 equal discs from peg 1 to peg 3, then move (x2, ..., xn) from peg 2 to peg 1 without saving the order (but it occurs that after we apply U() to the same group of discs twice, the order restored!), then move x1 equal discs from peg 3 to peg 2, and then use C() to move (x2, ..., xn) from peg 1 to peg 2 (here we use C() since we should preserve the order). So, (***) is correct.
+
+And (****) is quite straightforward expression for U(): move all discs but the largest group with the same algo, then move largest discs (that's why if x1 > 1, the group of discs "flips"), and then move all discs but the largest group onto the same peg with x1.
+
+**Problem E (div. 1) - Help Shrek and Donkey**
+
+This problem was about optimally playing this simple-at-first-glance game. The key thing to recognize in the statement was that it is not always optimal to name card which you don't have. Sometimes it is optimal to confuse the opponent by naming card which you have on hand. In this case... yes, he may think that the card you named is card on the table and lose during the next turn. Now the problem is to understand when to use the strategy of reduction of opponent's cards, when to bluff in the abovementioned sense and when to try to determine which card is on the table. But instead of "when" the right question is "how frequently" since we have nothing else but usual constant-sum matrix game, and optimal strategy is the mixture of these three. Let's construct a matrix first. Player 1 has three pure strategies: "playing" (when he plays the game and really tries to determine opponent's cards and card on the table), "guessing" (when he guesses which card is lying on the table) and "bluffing" (when he tries to confuse his opponent to force him to lose by naming card in his own hand). In turn, if the first player used "bluffing" strategy, or during the "playing" strategy named card on the table, his opponent has two strategies: "check" (i.e. to believe the first player that he doesn't own the card he named and guess it as the card on the table) and "move on" (i.e. to decide that it was a "bluffing" strategy and the game should be continued, but with notice that the first player has named card on hands). Let's denote P(m,n) probability to win the game when the first player has m cards and the second player has n cards. Then P(m,n) is the value of the matrix game with the following matrix (rows - strategies of the first player, two numbers in the rows - probabilities to win when the second player uses strategies "check" and "move on" correspondingly:
+
+"check" "move on"
+
+"playing" n/(n+1)*(1-P(n-1,m)) 1/(n+1) + n/(n+1)*(1-P(n-1,m))
+
+"guessing" 1/(n+1) 1/(n+1)
+
+"bluffing" 1 1-P(n,m-1)
+
+How to get these numbers in the matrix? Consider the first row: "playing" strategy of the first player, "check" strategy of the second. First just names one of the n+1 cards. With probability 1/(n+1) he names card on the table, seconds checks it and wins (so, probability to with for the first is 0), with probability n/(n+1) the first names one of the cards on hands of the second player, so the game continues, second wins with prob. P(n-1,m) in this case. Then the overall probability for the first to win with such combination of pure strategies is n/(n+1)*(1-P(n-1,m)). In the same manner we fill other cells of the matrix. Finally we solve the game (this can be done straightforwardly, or with one formula if one notices that the "guessing" strategy is suboptimal everywhere when m>=1 and n>=1 and that the game doesn't have saddle points) and get answer to the problem - P(m,n).
+
+And the last thing to note: when m==0 it is clear that during his move the second wins, so the first should guess, and P(0,n) = 1/(n+1). When n==0 P(m,0)==1 sinse we just do one rightguessing.
