commit 820b09682f8066a0e51dfcd83b96f5181103e01c
parent c8e1f7ab498ed689d240ee8728349fdf99c2fb44
Author: Andrew Laack <andrew@laack.co>
Date:   Mon,  9 Nov 2026 01:04:58 -0600

More editorials

Diffstat:
34 files changed, 1612 insertions(+), 0 deletions(-)
diff --git a/editorials/34.md b/editorials/34.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/748
+
+Привет, мир! Это мой первый разбор, просьба сильно не пинать. =)
+
+A. Разведка 2
+
+Нахождение минимума в массиве, с одим дополнительным сравнением первого и последнего элементов.
+
+B. Распродажа
+
+Отрицательные элементы складываем в массив, сортируем, находим сумму m наибольших по модулю.
+
+C. Список
+
+Решается массивом булей, единственная заковыка - с выводом, но вполне преодолима.
+
+D. Карта дорог
+
+Создаем динамическую матрицу смежности, например, массивом стеков, заполняем. Потом волновым алгоритмом из r2, пробегаясь по каждой вершине один раз, пролучаем результирующий массив.
+
+E. Столкновения
+
+Заведем переменную времени ct, которая вначале равна 0.
+
+Начинаем моделировать:
+
+Пусть dt равен t - ct, просматриваем все пары шариков, по формуле
+
+x1 + v1* dt = x2 + v2 * dt
+
+dt = (x1 - x2) / (v2 - v1)
+
+находим минимальную dt - промежуток времени, через который какие-нибудь шарики столкнуться, или время моделирования закончится.
+
+Сдвигаем шарики на этот промежуток времени, снова просматриваем все пары, если координаты двух совпадают, меняем их скорости по формуле из условия.
+
+Повторять, пока ct не сравняется с t.
+
+Особое внимание стоит уделить точности, наверное на этом и подловили RAVEman'а с ACRush'ем. =)
+
+В принятом решении я использовал double и точность сравнений 10-10.
+
+Удачи в контестах!
diff --git a/editorials/36.md b/editorials/36.md
@@ -0,0 +1,15 @@
+Source: https://codeforces.com/blog/entry/773
+
+The problem is to divide edges of a graph into two groups forming two paths in the graph. Clearly, each path is contained in one connected component. So if the given graph has more than two connected components, the problem has no solution. The same we can say if the graph has more than four vertices of an odd degree. Indeed, each vertex in a path (even if the path contains some vertices more than once) have an even degree, exept the first vertex and the last vertex. So the union of two paths can contain no more than four odd vertices.
+
+Now consider the cases:
+
+1. One connected component, no vertices of an odd degree. So we have an euler cycle, which can be divided into two paths.
+
+2. One connected component, two odd vertices. The same with an euler path instead of euler cycle. There is a tricky case of a graph with only one edge, which cannot be divided into two nonempty paths.
+
+3. One connected component, four odd vertices. The most interesting case. Connect two vertices of an odd degree by a dummy edge. You will get a graph with an euler path. Find the euler path and delete the dummy edge - you will get two paths.
+
+4. Two connetced components, each having zero or two odd vertices. Two euler paths/cycles.
+
+5. Two connected components, four odd vertices in one and no odd vertices in another. No solution.
diff --git a/editorials/37.md b/editorials/37.md
@@ -0,0 +1,30 @@
+Source: https://codeforces.com/blog/entry/798
+
+**A. Towers**
+ The total number of towers is equal to number of different numbers in this set. To get the maximum height of the tower, it was possible to calculate for each length the number of bars with this length, and from these numbers is to choose the maximum.
+
+ **B. Computer Game**
+ Constraints in the problem allows us to solve it this way: we keep the current number of health from the boss, and current summary damage from used scrolls per second. At the next step, we choose which scrolls we can use in the current second. Of all these, we find the scroll, which causes the most damage, and apply it. If at some point we could not use any of the scrolls, and the current damage in one second does not exceed regeneration, we deduce that there are no answers. Otherwise, continue to iterate the algorithm until the number hit points will be nonnegative.
+
+ **C. Old Berland Language**
+One of the easiest to understand solutions of this problem is as follows: sort the words in ascending order of length, while remembering their positions in the source list. We will consistently build our set, starting with the short strings: strings of length one can only be strings "0" and "1". If the number of words of length one in a set are more than two, hence there are no answers. Add the desired number of strings of length one to answer, and remove it from the current list. Then look at the string of length two: each of the remaining strings of length one can be extended in two ways (having added to each of these symbols 0 and 1). Add the desired number of strings of length two in our answer, and then increase the length of the remaining strings by one. Continue this process, until we get all words from the input set. You can see that if at some moment the number of allowable words exceeded the number of remaining, the extra words can be ignored and solution takes O (N * the maximum length of input set) time.
+
+**D. Lesson Timetable**
+
+This problem is solved by dynamic programming:
+
+state of dynamics will be a pair of numbers - the number of current room and number of groups which have first lesson in the room with a number not exceeding the current and for which the second room is not defined yet. For each state check all possible number of groups for which the second lesson will be held in the current classroom. When you add an answer from the new state, it must be multiplied by the corresponding binomial coefficients (the number of ways to select groups which have the first lesson in next room - *X**i* + 1, and the number of ways to select groups which have the second lesson in the current classroom).
+
+**E. Trial for Chief**
+
+First, we construct the following graph: each cell we associate a vertex of the same color as the cell itself. Between neighboring cells hold an edge of weight 0, if the cells share the same color and weight of 1, if different. Now, for each cell count the shortest distance from it to the most distant black cell (denoted by *D*). It is easy to see that we can construct a sequence of *D* + 1 repainting leads to the desired coloring:
+
+
+* The first step of color all the cells at a distance less than or equal to *D* in black color
+
+* At the second step color all the cells at a distance less than or equal to *D* - 1 in white
+
+* Etc.
+
+
+Of all the cells, choose the one for which this distance is minimal, and this distance increased by one will be the answer to the problem.
diff --git a/editorials/38.md b/editorials/38.md
@@ -0,0 +1,8 @@
+Source: https://codeforces.com/blog/entry/812
+
+# Задача C. "Жалюзи"
+
+Нетрудно понять, что для некоторой фиксированной длины полос жалюзи *x*, максимальное количество полос, которые можно получить, равно:
+
+
+тогда переберем это значение *x* ≥ *l*, и найдем максимум выражения *x*· *f*(*x*). Это число и надо вывести.
diff --git a/editorials/39.md b/editorials/39.md
@@ -0,0 +1,67 @@
+Source: https://codeforces.com/blog/entry/786
+
+**Problem A**
+
+To get the maximal possible result you have just to sort summands in non-decreasing order by coefficients (counting coefficients with preceeding signs + and -). You should not pay attention to 'a++' or '++a'! The question is: why is it true?
+
+First, consider an expression with only 'a++'. Then our assertion is obvious: it is better to multiply 'a' by small coefficients when it has small value, and by large coefficients, when it becomes larger. The same also takes place in case of negative coefficients or a-value. Of course, it is not a rigorous proof. I hope you will think on it if you haven't get it yet.
+
+Second, consider the expression *k* * *a* + + + *k* * + + *a*, where *k* is some coefficient equal for both summands. Let initial value of 'a' equals to *a*0. Calculating the value of the expression both ways, we obtain: *k* * *a*0 + *k* * (*a*0 + 2) = *k* * (*a*0 + 1) + *k* * (*a*0 + 1). So in this case the order is immaterial.
+
+Third, let us have the expression *k* * *a* + + + *l* * + + *a*, where *k* and *l* are two distinct coefficients. This expression can have two different values: *k* * *a*0 + *l* * (*a*0 + 2) and *k* * (*a*0 + 1) + *l* * (*a*0 + 1). The first value is greater than the second one if and only if *k* < *l*. We can deal with the expression k*++a+l*a++ analogously.
+
+Thus if we have two succesive summands with the same coefficient, we may swap or not to swap them. If we have two succesive summands with distinct coefficients, we must put the summand with a smaller coeficient first. Applying these considerations while it is necessary, we get a sequence of summands sorted by coefficients.
+
+**Porblem B**
+
+For this problem, the greedy solution is acceptable. Process given numbers consequently until 1 is found. Then continue to process searching for 2, then for 3, etc.
+
+**Problem C**
+
+The authors solution takes *O*(*n*2) time and *O*(*n*2) memory. Solutions with  time and *O*(*n*) memory are also acceptable.
+
+Let us reformulate the problem. Given a set of segments on a line, and the task is to find the largest subset such that segments in it don't intersect ``partially''. Two segments [*a*, *b*] and [*c*, *d*] intersect partially, if, for instance, *a* < *c* < *b* < *d*.
+
+Take all the ends of the given segments, sort them, and compute the dynamics: *d**l*, *r* is the largest possible size of such subset that segments in don't intersect partially and located between the *l*-th end and the *r* end (in sorted order), inclusively. We want to compute *d**l*, *r* having already computed *d**i*, *j* for all *l* ≤ *i* ≤ *j* ≤ *r*, but [*i*, *j*] ≠ [*l*, *r*]. First put *d**l*, *r* = *d**l* + 1, *r* if we don't take segments with the left end in *l*. Now process the segments with the left end in *l*. If the segment [*l*, *r*] exists, we undoubtedly take it to our set. If we take another segment, say, [*l*, *i*], where *i* < *r*, look at segments [*l*, *i*] and [*i*, *r*] (we have answers for them already computed) and try to update *d**l*, *r*. The asymptotics is *O*(*n*2), because the total number of left ends is *O*(*n*). Then you have to output the certificate, i.e. the optimal set itself. It can be done in the standard way.
+
+**Problem D**
+
+The flies can NOT see each other iff they are in opposite vertices. You may use multiple ways to check this. For instance, you can check the Manhattan distance |*x*1 - *x*2| + |*y*1 - *y*2| + |*z*1 - *z*2| = 3 or the Euclidian distance 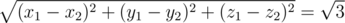. You can check if all three coorditanes are distinct (x1 != x2) && (y1 != y2) && (z1 != z2), or just (x1^x2)+(y1^y2)+(z1^z2) == 3!
+
+**Problem E**
+
+The number of ways to put *b* items into *a* boxes is, of course, *a**b*. So we have an acyclic game for two players with positions (*a*, *b*) for which *a**b* < *n*. Unfortunatly, there exists an infinite number of such positions: *a* = 1, *b* is any. But in this case, if 2*b* ≥ *n*, it is a draw position, because the only way for both players (not leading to lose) is to increase *b* infinitely.
+
+Another special case is a position with *b* = 1 and rather large *a*. Namely, if , there is also only one move from this position - to increase *a*. If *a* = *n* - 1 the position is losing, if *a* = *n* - 2 it is winning, for *a* = *n* - 3 it is losing again and so on.
+
+Thus we have two kinds of positions to deal with them specially. The number of other positions is not very large, and you can compute the standard dynamics for acyclic games for them.
+
+**Problem F**
+
+The simple modelling of frog's jumps works too long, because *n* can be 109. The right solution is to count for each frog a number of smashed mosquitoes by checking divisibility of numbers of hills with mosquitoes by *d**i*.
+
+**Problem G**
+
+What can I say about problem G? You should parse a given function and calculate its value for all values of *n*. Of course, it is impossible to do it just implementing the recursion, because this can work too long (see example with Fibonacci sequence). So you should use dynamic programming.
+
+**Problem H**
+
+You have to calculate all products *i* * *j*, and output them in the system of notations with radix *k*.
+
+**Problem I**
+
+Consider only the part of the graph reachable from 1. The task is to find the largest number *t*, such that a chosen set of vertices is reachable only at moments divisible by *t*. Suppose we have built such a set *S*0. Look at sets *S*1, *S*2, ..., *S**t* - 1 of all vertices reachable at moments having remainders 1, 2, ..., *t* - 1 modulo *t*, respectively. One can easily check that these sets are disjoint, and their union coinside with the set of all reacheble vertices. Clearly, that the edge from *u* to *v* can exist only when *u* and *v* belong to consequetive sets, i.e. , , *k* + 1 is taken modulo *t*.
+
+For each vertex *v*, find a distance *d**v* from 1 to *v* (if there is multiple paths, choose any, for example, by dfs). If the edge exists from *u* to *v*, it must be 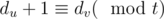. By analyzing all the edges, we come to the conclusion that the optimal value of *t* equals to the greatest common divisor of the numbers |*d**u* + 1 - *d**v*|. To find the set *S*0 is not very difficult now.
+
+**Problem J**
+
+The simplest solution is to find two numbers *l* and *r* - the length of the longest common prefix and the length of the longest common suffix of two strings, respectively. If *l* + 1 < *n* - *r* then there is no solution. Here *n* is the length of the first string. Otherwise we should output positions from *max*(*n* - *r*, 1) to *min*(*l* + 1, *n*).
+
+Problem K
+
+Problem K has a great number of different solutions, so I'm surprised that there was a lack of them during the contest. Solutions with time *O*(*k*4) and even some *O*(*k*5) solutions with optimization were acceptable, but [KADR](https://codeforces.com/profile/KADR "Lieutenant colonel KADR") describes even better solution in *O*(*k*3) ([http://codeforces.com/blog/entry/793](https://codeforces.com/blog/entry/793)).
+
+Here are some jury ideas of this problem. First, let us compress the coordinates. Choose a labeled point in each object and compute by the standard dynamics the number of such labels in each rectangle. It takes *O*(*k*4) to process all possible rectangles. The problem arises that a rectangle may contain a valid number of objects, but contain some objects not completely. To prevent this, we can check the borders. They are segments parallel to the coordinate axes, and their number is *O*(*k*3). So we can precalc for them if they are valid or not comparing them with each object. Then we have to come back to uncompressed coordinates.
+
+The following solution is *O*(*k*5), and it uses the limitation on the number of objects (3) inside the rectangle. Process all the triples of objects (the same, of course, with pairs and single objects). Fix a triple, and change it by a single big object. Then move from the resulting object up (and then down), and check if a row above (or below) can be included in a striked rectangle. For each row we find a longest segment [l, r], which contains the current big object and doesn't contain others. Using this information, one can easily calculate the total number of rectangles that contain the current triple.
diff --git a/editorials/40.md b/editorials/40.md
@@ -0,0 +1,23 @@
+Source: https://codeforces.com/blog/entry/835
+
+**Задача A. Определите цвет
+
+Здесь все понятно. Достаточно рассмотреть несколько случаев. Первый — когда расстояние от **точки до начала координат — целое число, тогда ответ black. В противном случае, пусть *d*****- это расстояние от нашей точки до начала координат. Тогда будем работать с [*d*]. Теперь****осталось два случая: 1) если наша точка лежит в 1-ой, или 3-ей четверти; 2) точка лежит во****2-ой, либо 4-ой четверти. В случае 1) имеем, если [*d*] нечетно, то ответ white, иначе****black; в случае 2) если [*d*] четно, то ответ white, иначе black. Подразумевается, что****[*d*] — целая часть *d*.**
+
+Задача B. Перекрашивания
+
+Первое, что надо заметить, так это то, что на i-ом шаге все перекрашенные клетки будут **лежать в прямоугольнике с вершинами в клетках (i,i), (n-i,m-i) (если считать, что (1,1) -****левая верхняя клетка, а (n,m) — правая нижняя). Тогда отсюда уже следует решение: нужно****подсчитать количество клеток такого типа, что минимальное расстояние до стороны в точности****равняется x. То есть для клетки (a,b) должно выполняться*****min*(*min*(*a*, *b*), *min*(*n* - *a* + 1, *m* - *b* + 1)) = *x*.****
+
+**Задача C. Берляндская площадь**
+
+Идейно эта задача не очень сложная, но было много хитрых случаев. Авторское решение предполагало следующую идею. Сначала заметим, что наше множество окружностей на плоскости может быть несвязным. Тут есть два случая, когда есть хотя бы одна точка пересечения окружностей и когда нет ни одной. Если их нет, то ответ N+M+1. Иначе, если есть хотя бы одна точка пересечения, то мы можем удалить некоторые окружности таким образом, чтобы оставшаяся фигура из окружностей была связной. Тогда для этой фигуры можно применить [формулу Эйлера](https://ru.wikipedia.org/wiki/Планарный_граф). Таким образом, нам здесь нужно посчитать количество точек пересечения и количество дуг-ребер. Нетрудно видеть, что каждая точка пересечения добавляет две дуги. Таким образом, мы можем найти количество частей, на которые разделилась плоскость без удаленных окружностей. Теперь достаточно заметить, что каждая удаленная окружность добавляет ровно 1 к ответу. Весь вопрос в том, чтобы посчитать, сколько точек пересечения. Это можно сделать за O(N+M), если считать для каждой окружности, точки пересечения, которые принадлежат ей. Для этого достаточно заметить, что все окружности, с которыми наша окружность пересекается будут иметь радиусы l, l+1, ..., r. Также, с некоторыми из этих окружностей наша окружность будет иметь не две точки пересечения а одну. Это необходимо учесть в решении. После этого остается лишь аккуратно реализовать эту идею.
+
+**Задача D. Интересная последовательность**
+
+Здесь нужно было погенерировать разные последовательности, которые могут получаться и внимательно смотреть на полученные значения. Основное наблюдение, это то, что каждое из чисел, которые встречаются в последовательности имеет вид 12*k* + 12*m*, при этом это число может встречаться лишь на позиции (*k* + *m* + 1). Теперь, когда известен общий вид, можно по методу математической индукции доказать, что на *x*-ой позиции могут встречаться все числа вида 12*k* + 12*m*, такие что, *k* + *m* + 1 = *x*. После этого можно было реализовать простое в написании решение за *O*(*N*3), где *N* — длина входного числа. Для этого перебираем все x от 1 до 600 и проверяем, существуют ли такие *k* и *m*, что *k* + *m* + 1 = *x* и 12*k* + 12*m* = *A*. Но также есть и решение со сложностью *O*(*N*2).
+
+**Задача E. Таблица из чисел**
+
+Первое, что должно было броситься в глаза, это то, что клеток, изначально не пустых — совсем мало. Из ограничений следует, что всегда есть пустая строка либо пустой столбец. Без ограничений общности можем считать, что у нас есть пустая строка и она последняя. Тогда выберем какой-либо столбец (к примеру, последний) и зафиксируем его одновременно с пустой строкой. Тогда по оставшейся таблице размера (*n* - 1) × (*m* - 1) клетки в последнем столбце и в последней строке заполняются однозначно. Но есть одно замечание, в последнем столбце уже стоят какие-то числа. Тогда нам надо для каждой строки, кроме последней подсчитать, сколько существует вариантов этой строки, таких, что произведение чисел в этой строке равно -1. В авторском решении, эта часть считалась при помощи динамического программирования. После этого нужно перемножить полученные ответы для каждой строки. Тогда ответ на задачу — это полученное произведение, либо 0 — если сумма *n* + *m* нечетна.
+
+Разбор задач был подготовлен мной и [sdya](https://codeforces.com/profile/sdya "Colonel sdya").
diff --git a/editorials/41.md b/editorials/41.md
@@ -0,0 +1,37 @@
+Source: https://codeforces.com/blog/entry/1620
+
+I wrote this post to help my friend , Iman Movahhedi , complete [this one](//www.codeforces.com/blog/entry/1492).
+
+Round #40 was my first contest here in Codeforces and I feel I fell in love with CF just after that.
+
+---
+
+**A-Translation:** ([C# code](http://pastebin.com/YmxXqAAS))
+
+Many languages have built-in reverse() function for strings. we can reverse one of the strings and check if it's equal to the other one , or we can check it manually. I prefer the second.
+
+---
+
+**B-Martian Dollar:**([C# code](http://pastebin.com/EP3KPzUf))
+
+Since number of days is very small (2 × 10³) we can just iterate over all possibilities of buy-day and sell-day. This will take θ (*n*2) time which is OK.
+
+---
+
+**C-Email Address:** ([C++ code](http://pastebin.com/mfbkckEU))
+
+The first letter of the input string can not be part of an "at" or a "dot" so we start from the second character. Greedily put "." wherever you reached "dot" and put "@" the first time you reached "at". This will take θ(*n*) time , where *n* is the length of input.
+
+---
+
+**D-Pawn:**
+
+For each cell of the table store *k* + 1 values. Where *i*th value is the maximum number of peas the pawn can take while he is at that cell and this number mod *k* + 1 is *i*.
+
+This makes a *O*(*n*2 × *m* × *k*) dynamic programming which fits perfectly in the time.
+
+---
+
+**E-3-cycles:** ([C++ code](http://pastebin.com/Z90p9BAm))
+
+The road map with most edges is a complete bipartite graph with equal number of vertices on each side. (Prove it by yourself :D ). We can make such a graph by putting the first  vertices on one side and the other  on the other side.For sure , number of edges is .
diff --git a/editorials/42.md b/editorials/42.md
@@ -0,0 +1,14 @@
+Source: https://codeforces.com/blog/entry/884
+
+**А. Guilty — to the kitchen!**Let us reformulate the statement: we need to find the maximum possible value of x (mentioned in the statement) so that the amount of each ingredient will be enough. Clearly, such x equals min(b_i / a_i). Now it suffices to take minimum of the two values: soup volume we gained and the volume of the pan.
+ **В. Game of chess unfinished.**
+In this problem you are to check exactly what the statement says: if the king's position and all the positions reachable by him in one turn are "beaten", — that's a mate. Thus, we have to determine "beaten" positions correctly. Let us remove the black king from the chessboard, leave the positions of the rooks "unbeaten" (not to forget about possible taking of the rook by the black king), mark positions reachable by rooks "beaten" and then mark positions reachable by white king as "beaten".
+
+**С. Safe cracking.**
+The answer in this problem is always affirmative, which means it is always possible to make all the numbers equal to one. Greedy approach (here we somehow make two adjacent numbers even and then divide them by two) leads the sum of numbers to become less or equal to six in logarithmic (and certainly less than 1000) number of operations. There are several ways do deal with extremal cases: for instance, many of the participants coped with this by the analysis of all of the cases left. The greedy approach only is not sufficient: the crucial test for hacks was (1 1 1 2).
+
+**D. Strange town.**Let us associate some numbers a_i with the vertices of the graph. If, for each edge, we assign it the sum of its endpoints' numbers, then the sum of prices along arbitrary hamiltonian cycle will be equal to the doubled sum of a_i. Therefore, it suffices us to devise such numbers a_i so that their pairwise sums will be distinct (as the edge prices should be distinct). As all of the edge prices are bounded above by 1000, we have to think of an efficient strategy to obtain such a_i. Let's choose them in greedy way, so that newly added a_i should not be equal to (a_p + a_q - a_k) for each triple of already chosen a_p, a_q, a_k. It is clear that a_n = O(n^3) as there are O(n^3) "blocking" triples (p, q, k).
+Another idea lies in that equality AB+CD=AC+BD should hold for every quadruple of distinct vertices A, B, C, D (summands stay for edge prices), because a hamiltonial cycle with edges AB and CD can be easily rearranged in the cycle with edges AC and BD and the sums of these cycles should be equal.
+You may think of how this idea was used by jury to check your solutions in exact and fast way.
+
+The solution of the problem E will appear soon.
diff --git a/editorials/43.md b/editorials/43.md
@@ -0,0 +1,37 @@
+Source: https://codeforces.com/blog/entry/902
+
+# [А. Футбол.](//codeforces.com/contest/43/problem/A)
+
+Эту задачу можно решить, не расходуя лишнюю память, а заведя лишь две строки для хранения названий первой и (возможно) второй команд и две целочисленные переменные для хранения количества голов, забитых первой и второй командами. Считываем название первой команды, запоминаем в первой строке и идем циклом до n - 1. На каждом шаге если считанная строка совпадает с уже имеющейся (первой строкой - она всегда есть, так как мы ее заранее (до цикла) считали), то увеличиваем счет этой команды, иначе запоминаем название второй команды и увеличиваем ее счет. В конце делаем целочисленное сравнение и выводим одну из строк.
+
+Заметим, что даже если вторая строка останется неинициализированной, ничего плохого не произойдет, так как мы к ней никогда не общаемся, кроме случая, когда победила вторая команда (значит, у нее ненулевое количество голов и строку мы все-таки инициализировали).
+
+# [B. Письмо.](//codeforces.com/contest/43/problem/B)
+
+#
+
+Известно, что символы из таблицы ASCII, к которым относятся все (строчные и заглавные) латинские буквы и пробел, имеют коды от 0 до 127. Значит, достаточно завести два массива на 128 символов (можно узнать требуемую память точнее, но char занимает 1 (или 2 байта в Java), поэтому это непринципиально), инициализированных нулями, и заполнить каждый из них следующим образом: идем циклом по строке, получаем код текущего символа строки, элемент массива с таким индексом (кодом символа) увеличиваем на единицу. Таким образом получим два массива - один для первой строки и один для второй. Чтобы составить вторую строку, нужно, чтобы выполнялось условие b[i] <= a[i] для всех i от 0 до 127, кроме (char)i == ' '. Пробелы вырезать ненужно, поэтому для них неравенство может не выполняться.
+
+# [С. Счастливые билеты.](//codeforces.com/contest/43/problem/C)
+
+#
+
+Признак делимости на три говорит нам, что натуральное число делится на три тогда и только тогда, когда сумма его цифр делится на 3. Для каждого кусочка билетика мы можем посчитать остатки от деления этого числа на 3 - 0, 1 или 2. Обозначим количество билетов первого типа - a, второго типа - b, третьего - с. Счастливые билетики можно составить двумя способами: либо соединить кусочки с остатками от деления 0 и 0, либо - 1 и 2. Тогда сумма чисел на получившемся билетике будет 3, что и требуется. Ответом будет число a / 2 + min(b, c). Оставшиеся a % 2 + max(a, b) - min(a, b) билетиков придется выкинуть, так как для них нет соответствующей пары.
+
+# [D. Путешествие](//codeforces.com/contest/43/problem/D)
+
+Сперва заметим, что в оптимальном решении может быть не более одного телепорта. Таблицу n * m можно обойти несколькими способами, перемещаясь только по соседним клеткам - например, змейкой или спиралью. Далее, из последней клетки, в которую мы пришли при обходе таблицы, можно телепортироваться в первую.
+
+В этой задаче нужно было рассмотреть 4 случая:
+
+1. n * m = 2 - тогда ответ легко выписать вручную
+
+2. n = 1, m > 2; n > 2, m = 1 - идем по полоске до конца, а из последней клетки ((1, m) или (n, 1)) телепортируемся в первую
+
+3. оба n и m нечетные (ни одно из чисел не равно 1) - тогда нужна одна телепортация: обходим доску одним из предложенных способов: змейкой (вверх-вниз или вправо-влево) или по спирали - а из последней клетки телепортируемся
+
+4. хотя бы одно из чисел четное, а другое не равно единице - тогда идем вдоль четной стороны до края таблицы, а оставшуюся часть обходим змейкой + делаем один завершающий ход.
+
+Для пояснения пункта 4, рассмотрим пример.
+
+Пусть n - четное, m - нечетное (не равное 1). Тогда идем вдоль края таблицы из клетки (1, 1) в клетку (n, 1). Дальше возвращаемся в клетку (1, 2) следующим образом: если текущая строка i четная - идем вправо от 2 до m, иначе идем влево от m до 2. Заметим, что последней строкой, которую мы так пройдем, будет первая (по номеру), то есть мы действительно закончим в клетке (1, 2). Осталось сделать только заключительный ход в (1, 1).
diff --git a/editorials/44.md b/editorials/44.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/833
+
+**Problem A**
+
+One of possible ways of solving the problem is to compare every leave with all taken before. If it matches one of them, than do not take it. Since the order of leaves is immaterial, you can just sort all the leaves (for example, as pairs of strings) and delete unique leaves.
+
+**Problem B**
+
+The problem is to find a number of triples (x, y, z), such that 0 <= x <= a, 0 <= y <= b, 0 <= z <= c and 0.5 * x + y + 2 * z = n. Trying all triples gets TL, but you can try all possible values of x and y, satisfying 0 <= x <= a, 0 <= y <= b. When x and y are fixed, z can be determined uniquely. So we get O(a*b) solution.
+
+**Problem C**
+
+The easiest solution is to process all the days from 1 to n, and check for each day, that it is covered by exactly one segment [*a**i*, *b**i*]. If you find a day which is covered by less or more than one segment, output this day.
+
+**Problem D**
+
+Let us call ships that were produced initially ''the ships of the first generation''. When a ship of the first generation reaches a planet, and new ships are build there, we call them ''ships of the second generation'', and so on.
+
+Let us prove that the first collision is between two ships of the second generation, moving towars each other. Indeed, ships of the first generation move in distict dirrections (no three points lie on the same line), so they cannot collide. If a ship of the first generation collides with a ship of the second generation, the lines of their moving form a triangle OAC, where O is the first planet, A is a planet where the ship of the second generation has been produced, and C is a point of the collision. But it's clear that OA + AC > OC, and ships are moving with the same speed, so such collision cannot happen.
+
+Speaking about ships of the third generation, they cannot be produced at all! Suppose that a ship from the first planet has reached the planet A, and then a ship from planet A has reached the planet B. But by virtue of the triangle inequality, a ship from the first planet has reached the planet B earlier, ships were produced at B, one of them was sent to A and collide with the ship, moving from A to B.
+
+For similar reasons two ships cannot collide, if one of them is moving from A to B, and another is moving from C to D. Ships moving from A to C and from C to A will collide earlier.
+
+Thus, the solution is to compute for each pair of planets A, B a perimeter of the triangle OAB, and find the minimal one.
+
+**Problem E**
+
+There are multiple ways to split the string. One of them is to split it into parts of lengths n / k and n / k + 1, if n is not divisible by k. Here n is the length of the given string. If lengths of such parts are not less than a and not greater than b, the answer is found. Otherwise there is no solution.
+
+**Problem H**
+
+The answer may be rather large, because it grows exponentially with growth of n, but it fits int64. Indeed, there are 10 ways to choose the first digit, than 1 or 2 ways to choose the second one, 1 or 2 ways for the third one, and so on. So the number of ways doens't exceed 10· 2*n* - 1.
+
+The problem can be solved by dynamic programming. Let *d**ij* be a number of ways to get first i digits of a correct number with the i-th digit equal to j. From such part of a number we can obtain a part of size i + 1 with (i+1)-th digit equal to (*j* + *a**i* + 1) / 2 or (*j* + *a**i* + 1 + 1) / 2, where *a**i* is the i-th digit of Masha's number. So if we have *d**ij* for all *j*, we can obtain *d**i* + 1, *j*.
+
+Do not forget to subtract 1, if Masha can obtain her own number. It will happen in case when each two successive digits in the given number differs at most by 1.
+
+**Problem J**
+
+First, if the tiling is possible, it is unique. Consider the most upper-left position (x, y) that is not cut out. If it is black, the tiling is impossible. If it is white, look at the next position (x, y + 1). If it is cut out, the only possible way to put a trimino is to put it vertically. Otherwise we must put a trimino horisontally, because if we put it vertically, we wouldn't be able to cover the next black position (x, y + 1). These considerations give us an algorithm for the solution.
+
+Four symbols a, b, c, d are always enough to represent the tiling, because a trimino can have common sides with no more than 3 triminoes located to the left or above it. So even if all the 3 triminoes are marked by 3 different symbols, the next one may be marked by the 4-th one.
diff --git a/editorials/46.md b/editorials/46.md
@@ -0,0 +1,19 @@
+Source: https://codeforces.com/blog/entry/916
+
+**Task B**. T-shirts from sponsor.
+
+Enumerate sizes of t-shirts by integers from 0 to 4. For each size we store the number of t-shirts of this size left. To process each participant, we need to determine the number of his preferable size. Then we iterate over all possible sizes and choose the most suitable one (with the nearest number) among the sizes with non-zero number of t-shirts left.
+
+**Task D**. Parking.
+
+Lets keep a set of cars which are currently parked. In this problem it is not essential how to keep this set. For each car, store its length and position. To process a request of type 2, we need to find the car which should leave the parking and remove it from the set. To do this, we should enumerate the cars and get the car number by the number of request. Now consider a request of type 1. As the drives tries to park his car as close to the beginning of the parking slot as possible, we can reduce the set of reasonable positions for parking: include into this set the beginning of the parking and all positions that are exactly *b* meters after the front of some car. For every position in this set we should determine if it is possible to park car in it. Then we choose the closest to the beginning position among admissible ones.
+
+**Task E**. Comb.
+
+Denote the input matrix by *a*. Compute the partial sums in each row first: . All these sums can be easily computed in *O*(*nm*). Then solve the task using dynamic programming. By *d**i*, *j* denote the maximum sum of numbers that we can take from first *i* rows, taking exactly *j* numbers in row *i* and not violating the "comb" condition. Starting values are obvious *d*1, *j* = *s*1, *j*. Transitions for *i* > 1 looks like this:
+
+1) If *i* is even, 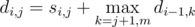.
+
+2) If *i* is odd, 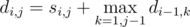.
+
+Straightforward computing of values *d**i*, *j* by these formulas has complexity *O*(*nm*2), which is not suitable. Use the following fact: if we compute values *d**i*, *j* in order of decreasing *j* in case of even *i* and in order of increasing *j* in case of odd *i*, the maximum values of *d**i* - 1, *k* from the previous row can be computed in *O*(1), using value for previous *j*, i.e. without making a cycle for computation. This solution has complexity *O*(*nm*) and passes all tests.
diff --git a/editorials/47.md b/editorials/47.md
@@ -0,0 +1,54 @@
+Source: https://codeforces.com/blog/entry/931
+
+1) Because of small constraints, just iterate *n* from 1 to *T**n* and check 
+
+```
+for (int n = 1; n <= Tn; n++)
+{
+ if (n * (n + 1) / 2 == Tn)
+ {
+ cout << "YES\n";
+ return;
+ }
+}
+cout << "NO\n";
+```
+
+
+ 2) Let's consider a graph, where the letters *A*, *B*, *C* are the vertexes and if *x* < *y*, then the edge *y* - > *x* exists. After that let's perform [topological sort](https://en.wikipedia.org/wiki/Topological_sorting). If a cycle was found during this operation, put "Impossible" and exit. Otherwise put the answer.
+
+Another approach is acceptable because of small constaints (by [Connector](https://codeforces.com/profile/Connector) in russian comments).
+Just iterate over all of 3! permutaioins of the letters and check if they are sorted. If no such permutation, put "Impossible"
+
+ 3) Let's iterate over all of 6! = 720 permutations. For every permutation let's try to put the first 3 words horizontally, the others - vertically:
+
+1. hor[0], ver[0] - left-up
+2. hor[2], ver[2] - right-down
+3. hor[1]: (len(ver[0]) - 1, 0)
+4. ver[1]: (0, len(hor[0]) - 1)
+
+Now let's define N = len(ver[1]), M = len(hor[1]).
+A Conditions for the solution existence
+
+1. len(hor[0]) + len(hor[2]) == M + 1 // edges of "eight"
+2. len(ver[0]) + len(ver[2]) == N + 1 // edges of "eight"
+3. len(hor[0]) >= 3 && len(hor[2]) >= 3 && len(ver[0]) >= 3 && len(ver[2]) >= 3 // "eight" is nondegenerate
+4. The letters at start/end of appropriate strings are match
+5. The letters on the intersection of hor[1], ver[1] are match
+
+Now we have the right field of the size N x M, and update the answer
+Note In C++ if you use vector<vector<char> > or vector<string> as the field type, then you can simply use operator "<" for updating.
+
+4) Let's consider not the most efficient, but AC algorithm, with the complexity *O*(*mC**n*5*log*(*C**n*5)).
+Let's consider the 1 answer of the system: <number, v>. The amount of the variants of the password is *C**n**v* - not very large number in constaints of the problem, you can simply generate this variants. Declare this set of variants as current. Now, for the every answer let's generate a set of possible passwords, and let's declare the intersection of this set and current set as current. After *m* iterations we'll have some set. Then we'll erase elements from this set, which were in the answers of the system, and the answer of the problem will be the size of this set.
+
+
+5) Let's consider an algorightm with complexity *O*((*n* + *m*)*log*(*n* + *m*)).
+Exclude from considiration every wall can't be achieved by canon: *x* > *v*2 / *g*
+Because of α < =π / 4:
+
+1. Function *X**max*(α) is monotonous
+2. Function *Y*(α, *x*), when x is fixed, is monotonous
+
+Such observation allows to assign to each wall a section of the attack angle [α1, α2]. If this canon shoots with angle within this section, it hits the wall. These angles can be obtained by solving equation (it will be biquadratic), but because of monotonous we can use binary search.
+Sort walls by *x*. Now the initial problem has reduced to the problem: for every shoot it is need to obtain minimal index of the wall, when shoot angle is between attack angles for this wall. This problem can be solved by Segment Tree for Minimum with possibility to update on an interval. At first, fill tree with KInf. Next, for every wall let's perform update(α1, α2, index). Then let's iterate over requests. If getMin(α) == KInf, then missle do not hit any wall and hit the land, otherwise it hit the wall with index getMin(α).
diff --git a/editorials/50.md b/editorials/50.md
@@ -0,0 +1,41 @@
+Source: https://codeforces.com/blog/entry/1006
+
+***Problem A***: Answer is floor(N*M*0.5). Since there is N*M cells on the board and each domino covers exactly two of them we cannot place more for sure. Now let's show how to place exactly this number of dominoes. If N is even, then place M rows of N/2 dominoes and cover the whole board. Else N is odd, so cover N-1 row of the board as shown above and put floor(M/2) dominoes to the last row. In the worst case (N and M are odd) one cell remains uncovered.
+
+***Problem B***: Of course you were expected to code solution which is not quadratic in time complexity. Iterate over the string and count how many times each char is used. Let Ki be the number of occurrences of char with ASCII-code i in the string S. Then answer is sum(Ki2). While coding the solution the following common mistakes were made:
+
+1. Code quadratic solution (double loop over the string)
+2. Forget to use int64. Whether in answer or in Ki squaring.
+3. Wrong int64 output.
+
+All these problems were easily hacked by max test with 100000 equal chars. This turned the hacking process into the game "who hacks the next B solution faster" because newbies often made all these mistakes. This problem was severed by the fact that GCC-compiler turned out to be MinGW-compiler, so output like printf("%lld", ...) did not work on it. Another strange problem hackers faced was quiet test truncation by length about 30000 when copy/pasting it into the test editor. Of course the overflow in solution disappears after it.
+
+***Problem C***: You were asked to make all the cows strictly inside the interior of the route. Initially I planned to put "non-strict" there, but later I abandoned this idea because the answer for single point was really weird then=) The difference in solution is quite small. The answer for "strict" problem is always more than for "non-strict" by exactly 4. Some coders preferred to add four neighboring points for each point like a cross to switch to solving non-strict problem.
+
+The non-strict problem is solved in the following way. Notice that the required route can always be searched as an octagon, perhaps with some zero sides. Take four pairs of parallel lines and "press" it to the points. In other words, we find axis-aligned bounding box for the set of points. Then find axis-aligned bounding box of the point set on the picture which is rotated by 45 degrees. Now intersect these two boxes (as filled figures). We get an octagon in the common case, which is the required one. To implement the solution, we have to calculate minimums and maximums of X, Y, X+Y, X-Y through all the points, then use non-trivial formulas to get the answer.
+
+A lot of contestants solved the problem in other way. It is easy to see that to move by vector (X, Y) shepherd needs to make max(|X|, |Y|) turns. We can make the shepherd walk along the vertices of convex hull. We need to run a standard Graham scan and then iterate through all the points on the hull and sum max(|X'-X|, |Y'-Y|) for all pairs of neighboring vertices in it. This solution is also correct.
+
+There was an idea to make limit on coordinates equal to 109, but we decided that there was no need to ask for int64 again. Perhaps it'd have been better if there'd been int64 in this problem instead of problem B.
+
+***Problem D***: The problem statement looks intricate and aggressive. That's because the problem legend originates from civil defense classes in the university. Civil defense is such a discipline which for example teaches how to behave before and after nuclear attack...
+
+First of all we should notice that the bigger the warhead, the better (I mean the probability to succeed is higher). This seems quite reasonable. Function P(D, R) increases as R increases with fixed D. Obviously the probability to hit at least K objects increases in this case too. Hence we can find the answer by binary search. We have to be able to find the probability to accomplish the mission with fixed and known radius R to perform binary search.
+
+Now we have to solve the problem: there are N objects, each of them is destroyed with given probability (pi). Find the probability to destroy at least K of them. The problem is solved by dynamic programming which is similar to calculating binomial coefficients using Pascal's triangle. Let R[i, j] be the probability to hit exactly j objects among the first i of all the given ones. If we find all the R values for 0<=j<=i<=N, then the answer is calculated as sum_{j=k..N} R[N, j]. The base of DP is: R[0, 0] = 1. Induction (calculating the new values) is given by the formula R[i, j] = R[i-1, j-1] * pi + R[i-1, j] * (1-pi). Keep in mind that for j<0 or j>i all the elements of R are zeroes.
+
+It was shown experimentally that many coders (me included) try to solve the problem by taking into account only the closest K targets. I.e. they think that the probability to succeed is simply p1 * p2 *... * pK. This is wrong: for example, if two buildings with equal distance are given, then the probability to hit at least one of them is 1-(1-p)2 instead of p. But I decided to please these coders and composed the pretests only of the cases on which this solution passes=) So this particular incorrect solution was passing all the pretests intentionally.
+
+***Problem E***: Let D = b2-c be quarter of discriminant. The equation roots are -b-sqrt(D) и -b+sqrt(D). Thus there are two types of roots: irrational ones like x +- sqrt(y) and integer ones. We count the number of different roots separately for these types.
+
+Irrational roots are in form x+sqrt(y) (y is not square of integer). If two numbers in this form are equal, then their x и y values are also equal. It can be checked on the piece of paper. The main idea is to use irrationality of sqrt(y). Thus if two irrational roots are equal, then the equations are the same. Hence all the irrational roots of all the given equations are different. Let's iterate b=1..N. For each of b values we have to find the number of equations with positive discriminant which are not squares on integers. I.e. number of c=1...M with D = b2-c is not square of integer. We can calculate set of all possible values of D as a segment [L; R] (L >= 0). Then take its size (R-L+1) and subtract number of squares in it. It is exactly the the number of equations with irrational roots for a fixed b. Multiply it by 2 (two roots per equation) and add it to the answer.
+
+Now let's handle integer roots. For a fixed b we've calculated the segment [L;R] of all D values. Then sqrt(D) takes integer values in segment [l; r] = [ceil(sqrt(L)); floor(sqrt(R))]. We put this segment into the formula for equation roots and understand that all the integer roots of equations with fixed b compose segments [-b-r;-b-l] и [-b+l;-b+r]. However the integer roots may substantially be equal for different equations. That's why we have to mark in a global data structure that all the roots in these two segments are "found". After we iterate through all b=1..N, we have to find number of integers marked at least once in this data structure.
+
+This data structure is implemented on array. All the integer roots of equations lie in bounds from -10000000 to 0. Allocate an array Q which is a bit larger in size. To mark segment [s; t] we increment Q[s] by one and decrement Q[t+1] by one. At the end of the solution iterate through the whole array Q from left to right and calculate prefix sums to array S. I.e. S[i] = Q[-10000010] + Q[-10000009] + ... + Q[i-1] + Q[i]. Then S[i] represents number of times we've marked number i. Now iterate through S array and count number of nonzero elements. It is the number of different integer roots.
+
+The solution requires O(N) time since we have to iterate through all b values. It is likely that purely combinatoric (O(1)) formula for answer exists=)
+
+***Conclusion***. I think that there were two problems in the contest (except the system's epic fail of course). The first: there was no technically hard problem. Because of this high-rated coders had solved all the problems by the end of first hour and had to torture themselves by hacking others in heavily instable contest system during the remaining hour. I think that problem E in any round should be really tough to code. The second problem is huge number of hacks for problem B. I should have set the limit on string length to 40000. There is one more interesting question: why are divisions merged together? It would be wiser if any room were first division only or second division only. Then first division coders would concentrate on hacking solution for difficult problems instead of catching simple newbies' mistakes.
+
+Reminder: you can see the tests for all problems in contest system.
diff --git a/editorials/51.md b/editorials/51.md
@@ -0,0 +1,68 @@
+Source: https://codeforces.com/blog/entry/1038
+
+Еще вопрос: кто-нибудь знает, как поставить ссылку на профиль пользователя в посте?
+
+A. Задача Читериуса
+
+В этой задаче теоретически могли быть следующие проблемы: считывание, сравнивание, "я не прочитал, что *n<=1000*" и "электричка опоздала на 10 минут к началу раунда". У меня была последняя :)
+Считывать можно было либо построчно, либо по токенам. Всё языки это умеют.
+Сравнивать два квадрата можно опять же как угодно. Я делал так: считал две строчки, соеденил в одну и поменял 3й и 4й местами. Получилась "ленточка". Две "ленточки" можно сравнить двумя циклами: первый перебирает сдвиг, второй проверяет, что всё совпало.
+Далее оставалось лишь посчитать количество стопок. Это можно было делать так: перебираем все непомеченные квадратики, добавляем один к ответу и помечаем все квадратики, которые равны текущему.
+
+
+
+B. Анализ таблиц bHTML
+
+Задача тоже не ахти какая сложнае, если знать, как строятся парсеры в общем виде.
+Для начала требовалось прочитать все строчки и склеить их в одну.
+После чего поступаем так: заводим указатель на текущий рассматриваемый символ. Изначально он равен нулю. Затем делаем вспомогательную процедуру "прочитать строку". Она пытается посимвольно прочитать что-нибудь, начиная с текущего символа, и, если удалось - возвращает *True* и перемещает указатель вправо, если нет - возвращает *False*, и указатель не трогает.
+После этого можно написать рекурсивные процедуры ReadCell, ReadRow и ReadTable - каждая из них возвращает количество ячеек в текущей таблице.
+*ReadCell* работает так: прочитать *<td>*, если дальше не удалось прочитать *</td>*, добавить к ответу *ReadTable()* и прочитать *</td>*. Вернуть 1.
+*ReadRow*: считали *<tr>*, пока не удаётся прочитать *</tr>*, делаем ReadCell. Вернуть сумму по всем *ReadCell*.
+*ReadTable*: считали *<table>*, пока не удаётся прочитать *</table>*, делаем *ReadRow*. Вернуть сумму по всем *ReadRow*.
+В конце надо посортировать количества ячеек во всех таблицах и вывести.
+
+Также можно было делать так: завести функцию *getTag*, которая возвращает какой из 6 тегов был, а далее разобрать три случая:
+"table" => *stack.push_back(0)*
+"td" => *stack.top++*
+"/table" => *ans.push_back( stack.top() ), stack.pop_back()*
+
+C. Три базовых станции
+
+Для начала упростим себе задачу: посортируем дома и удалим одинаковые.
+Теперь давайте в цикле переберём самый правый дом, который покрывает первая станция.
+Этот дом однозначно определяет её минимальную мощность. Далее хочется быстро найти границу для второй станции. Что мы хотим минимизировать? Максимум из мощности второй и третьей станций (т.к. первая у нас уже фиксированна). При движении границы слева направо мощность второй растёт, а третьей - убывает. Соответственно, максимум из этих двух величин до какого-то времени невозрастает, а затем - неубывает. Хотим найти момент этого перехода - в нем и будет искомый минимум. Это можно сделать при помощи указателя, т.к. этот момент всегда движется только направо.
+Т.о. получаем решение за линейное время.
+
+
+D. Геометрическая задача
+
+Первое, что требовалось вспомнить - бываю еще и нули.
+Давайте для начала научимся понимать, является ли последовательность геометрической прогрессией. У каждой прогресси либо есть знаменатель *b* (возможно, 0), либо он может быть любым (*c=0*). Для каждых двух соседних элементов опять же, либо есть однозначные знаменатель, либо нет. Собирав эту информацию со всех элементов и проверив на непротиворечивость, мы убедимся что последовательнось - прогрессия.
+
+Побежим по последовательности слева направо. Заведём две переменные - знаменатель последовательности (*b*) и флаг, определили ли мы его уже (*exb*). Вначале *exb=false*.
+Далее мы обрабатываем элемент (*a1*) и предыдущий (*a0*). Мы должны проверить, что они **не конфликтуют** с уже известной информацией и что они вообще могут встретиться рядом хоть в какой-то последовательности. Если это так, то нам надо пересчитать знаменатель (если *a0* != 0), иначе сразу возвращаем *false*.
+Для проверки на конфликты у меня была функция equal. Она работает следующим образом: если *a0 = 0*, то надо проверить, что *a1 = 0* и вернуть *true*, иначе выбросить исключение. Иначе, если знаменатель еще не определён, то вернуть *true*. В противном случае проверить, что отношение элементов и знаменатель совпадают.
+Если в конце оказалось, что конфликтов и исключений не было, то да, такая геометрическая прогрессия есть.
+
+Теперь у нас есть функция проверки, является ли последовательность прогрессией. Мы уже можем написать квадратичное решение. Для получения OK нам требуется чуть-чуть изменить квадрат и сделать precalc.
+Как работает тупой квадрат? Выкидываем по очереди элементы и проверяем, что прогрессия есть. Теперь давайте заметим, что массив без одного элемента - это какой-то его префикс плюс суффикс.
+Что значит, это это объединение есть прогрессия? Что, во-первых, каждый из них является прогрессией, и, во-вторых, что их можно "склеить". Т.е. что пара (*an*, *b1*) не конфликтует ни с первой прогрессией, ни со второй.
+Теперь у нас есть цикл, внутри которого идёт куча вызовов вида *check(0, 0)*, *check(0, 1)*, *check(0, 2)* и т.д. Их можно объединить в один и с запоминанием результатов на каждом шаге. Это даёт линейное решение со всеми разобранными случаями.
+
+
+E. Пентагон (спасибо, @Sereja)
+
+Пускай массив *Q* означает наличие ребра между двумя вершинами, а *st* - степень вершины.
+
+Для начала для каждой пары посчитаем количество вершин которые "лежат между ними", иными словами, достижимы от обоих из них. Запишем эти данные в массив *A* (это можно сделать за кубическое время).
+После того, как мы знаем эти данные, переберем 3 вершины из цикла, две из которых будут лежать "рядом" в цикле. Назовём их *i*, *j* и *l* (*Q[i,j]=1*). Тогда возьмем две переменные, которые будут отвечать за количество вершин "между" *i* и *l* , *j* и *l*. Это будут значения *A[i, l]* и *A[j,l]*, но при этом, в случае *Q[j, l]* = 1 от первого нужно отнять 1, для второго - аналогично. Это делается для того, чтобы никакая вершина не входила в цикл два раза. К ответу добавим произведение этих значений. Есть еще один отдельный случай: когда *Q[i, l]=1* и *Q[j, l]=1*, то от ответа нужно отнять *st[l]-2*? Чтобы понять это, нужно на листке бумажки расписать, как будут происходить добавления новых циклов, и через какие вершины мы их пропустим.
+Полученный ответ делим на 5 для удаления повторов (каждый цикл мы считаем из каждой его вершины), это и будет финальный ответ.
+
+В комментариях есть [обобщённое решение](https://codeforces.com/blog/entry/1038#comment-17512) на случай более длинных циклов.
+
+
+
+F. Гусеница
+
+[Ссылка](https://codeforces.com/blog/entry/1030#comment-17431)
diff --git a/editorials/53.md b/editorials/53.md
@@ -0,0 +1,56 @@
+Source: https://codeforces.com/blog/entry/1065
+
+Let's go.
+
+
+A. Autocomplete
+
+
+
+In this problem you should read the statement and solve in any way. One of the most simple solutions is read string and last visited pages, sort (even bubble source - 1003 isn't a lot, 3rd power because we need 100 operations to compare two strings), and rundown pages. When we find good string, we should write it and exit.
+If there are no such one, write source string. 'Goodness' of string is checking with one *if* (to check lengths and avoid *RTE*) and *for*.
+
+
+
+C. Froggy (Little Frog)
+
+IMHO it's the second difficulty problem. If you cannot see solution just after you saw the statement, you can write brute-force solution (rundown all permutation and check), run it for *n=10* and see beautiful answer.
+Answer is *1 n 2 (n-1) 3 (n-2) 4 (n-3) ...* Let's define two pointers - *l* and *r*.Inthe beginning, the first one will point to 1, and the second one - to n. On odd positions write down *l* (and increase it), on even - *r* (and decrease it). Do it while *l <= r*.
+Proof is rather easy: every jump is shorter than the previous one.
+
+
+D. Physical education
+
+
+
+This problem is also very easy. The first thing we should learn is moving element from position *x* to position *y (y < x)*. Let's move *x* to position *x - 1* with one oblivious swap. Then to position *x -2*. And so on.
+Now we want to make *a1=b1*. Find in *b* element, that equals *a1* and move it to the first position. Similarly we can make *a2=b2*. So, we have *n* steps and at every step we do *n - 1* swaps at the most. *n<=300*, so *n(n-1)<=89700<106*.
+
+
+B. Blog photo
+
+
+
+Due to [bug in GCC](https://codeforces.com/blog/entry/1059) I've lost 25 minutes solving this problem. In the end I've used MSVC++.
+But it was digression, now let's think.
+The first thing we need to do is fix one side (which are power of two). Because there are two sides and copy-paste is great place for bugs it'll be better to make one more *for* from 1 to 2 and on the 2nd step swap *w* and *h*. It decreases amount of code.
+Now we know that *h=2x*. We need to find such *w*, that *0.8 <= h/w <= 1.25.* Solve inequalities for *w*: *h/1.25 <= w <= h/0.8.* Because *w* is integer, it can take any value from *ceil(h/1.25)* to *floor(h/0.8)* inclusive. We need to maximize square and *h* is fixed, so our target is maximize *w*. We need to let *w=floor(h/0.8)* and check that it fit borders. If so - relax the answer.
+It's *O(log2 h)* solution.
+Possible bugs are:
+
+* You calculate square in 32-bit type or like this: *int w = ..., h = ...; long long s = w * h;* In this case compiler calculate *w * h* **in 32-bit type first**, and then convert it to *long long*. Solution is *long long s = (long long)w * h*
+* *floor(0.9999999999)=0.* The *floor* function does not correspond with inaccuracy of floating point types. It can be solved either with adding something *eps* to number before calling *floor*, or with additional check that difference between *floor*'s result and source value is not greater than *1 - eps*.
+* p.s. The *floor* function is up to **8-9 times** slower that conversion to *int*.
+
+
+
+E. Dead ends
+
+
+
+The first thing you should notice - - *n <= 10*. It means, that we have exponential solution and we can rundown some subsets.
+
+Solution is dynamic programming *d[m][subm]* - number of ways to make connected tree from subgraph *m* (it's a bit mask) with dead ends *subm* (it's also a bit mask). Answer is sum of *d[2n-1][x]*, where *|x|=k* (size of *x* as a subset is *k*).
+Recalculating isn't really hard. For empty subset and subset of two vertexes (either 0 or 1) answer is oblivious. Also you should know that there is no tree with exactly one dead end (it's easy to prove). Now for greater subsets: rundown *i* from *subm* - one of dead ends. Cut it off from tree along some edge to *b* (*b* shouldn't be a dead end, otherwise we got unconnected graph). Now we have tree with lower count of vertexes and either decreased 1 number of dead ends or with changed *i* to *b* (if *b* had exactly two neighbors). Answer for this tree we know already. In the end of summarizing we should divide answer by *k* - each tree has been taken as many times, as it has dead ends (*k*).
+
+p.s. I'll be glad if you tell me my mistakes in English.
diff --git a/editorials/54.md b/editorials/54.md
@@ -0,0 +1,15 @@
+Source: https://codeforces.com/blog/entry/1085
+
+
+
+The most important step on the way to solve this problem - is to understand that it's enough to consider only such rotations of the polygon, that one of its sides lies on the side of the room.
+
+Let's try to understand this fact. Suppose that the fact is wrong, and there exists such a position of vacuum cleaner, that neither of its sides lies on the side of the room. Denote as *i* and *j* the numbers of vertices that lie on the room sides. It's easy to understand that the polygon form between vertices *i* and *j* doesn't make any sense itself: for each rotation we can see that from the area of triangle *OP*[*i*]*P*[*j*] some constant area is subtracted, while the concrete value of this constant depends on the polygon form.
+
+That's why we see that the polygon form doesn't influence on anything (if we have fixed numbers *i* and *j*), and we have just to minimize the area of right-angled triangle *OP*[*i*]*P*[*j*]. But, taking into account that its hypotenuse is a constant, it's easy to see that the minimum is reached in borderline cases: i.e. when one of the polygon sides lies on the room side.
+
+So, we've proved the fact. Then we have to invent fast enough solution. We have already obtained an *O*(*n*2) solution: iterate over all sides of the polygon (i.e. iterating over all possible *i*), mentally push it to one side of the room, then find the threshold point *j*, then calculate answer for given *i* and *j*. Let's learn how to do these both things in *O*(1).
+
+In order to do the first thing (finding *j*) we can use a method of moving pointer: if we iterate over *i* in the same order as in the input file, then we can just maintain the right value of *j* (i.e. when we move from *i* to *i* + 1 we have to increase *j* several times, while it is getting further and further).
+
+In order to do the second thing (the area calculation) we have to do some precalculation. For example, we can find the mass center *Q* of the vacuum cleaner, and pre-calculate all partial sums *S*[*i*] - sums of all triangles *QP*[*j* - 1]*P*[*j*] for all *j* ≤ *i*. After this precalculation we can get the answer for every *i* and *j* in *O*(1) as a combination of difference of two values from *S*[] and two triangles' areas: *QP*[*i*]*P*[*j*] and *OP*[*i*]*P*[*j*].
diff --git a/editorials/56.md b/editorials/56.md
@@ -0,0 +1,63 @@
+Source: https://codeforces.com/blog/entry/1147
+
+**Задача А. Бар**
+
+Ответом на задачу является количество посетителей, которые удовлетворяют одному из предложенных ограничений:
+
+> *1) Указан возраст посетителя и он меньше 18 лет*
+>
+> *2) Указан напиток посетителя и он является алкогольным*
+
+Далее остается аккуратная реализация.
+
+**Задача B. Испорченная перестановка**
+
+Задача имеет множество решений. В разборе будет расказанно решение с асимптотикой O(N), где N - количество элементов последовательности.
+
+Найдем такое наименьшее i, такое что Ai не равно i (элементы нумеруются с единицы). Если такого i не существует, то все числа стоят на своих местах и, соответственно, ответом являются два нуля. Иначе, предполагаем, что ответом являются числа i и Ai (мы можем быть точно уверены, что i < Ai). Переворачиваем подпоследовательность элементов с i-ого по Ai-ый и проверяем всю полученную последовательность на то, везде ли Ai равно i. Если да, то ответом является пара (i, Ai), иначе ответ - два нуля.
+
+**Задача C. Почта в корпорации**
+
+Для решения задачи вполне подходит решение за O(N2L), где N - количество людей в иерархии, а L - средняя длина имени сотрудника. То есть сравнение строк можно выполнять без использования хэш-функции.
+
+Первая часть решения - аккуратная реализация примитивного парсинга строки. Наиболее простой способ - рекурсивная функция, которая читает сначала имя сотрудника, а потом и всех его подчиненных до тех пор, пока не достигнет точки. Далее потребуется хранить в памяти дерево из N вершин. Хранение дерева можно организовать как с помощью динамической памяти, так и простой матрицей смежности. Далее можно просто для каждой вершины запустить обход в глубину из нее и посмотреть скольким вершинам в этом поддереве сопоставлено такое же имя. Стоит обратить внимание на то, что сама вершина, из которой изначально запускается обход в глубину, не должна быть посчитана в ответ.
+
+Такое решение можно улучшить до сложности O(NlogN), используя хэширование и более сложные структуры данных (например map). При данных ограничениях это было бы пустой тратой времени. Даже грубой оценки N < 500 достаточно, чтобы решение уложилось в time limit.
+
+**Задача D. Получаем строку**
+
+Наиболее простым решением этой задачи является решение с использованием динамического программирования. Обозначим первую строку за A, а вторую за B. Длина первой строки равна N, а второй - M. Тогда решение имеет асимптотику O(NM).
+
+Обозначим за S(i, j) - подстроку строки S с i-ого по j-ый символ.
+
+Введем функцию F(x, y) - сколько минимум действий надо выполнить, чтобы из подстроки A(x, N - 1) получить подстроку B(y, M - 1) (индексы символов нумеруются с нуля). Тогда значание F(x, y) это минимум из:
+
+> *F(x + 1, y + 1), при x < N, y < M и A[x] = B[x]*
+>
+> *F(x + 1, y + 1) + 1, при x < N, y < M*
+>
+> *F(x + 1, y), при x < N*
+>
+> *F(x, y + 1), при y < M*
+
+Очевидно, что F(N, M) равно нулю.
+
+Если при обработке очередного перехода не только обновлять значение функции, но и запоминать тип перехода, то по окончании подсчета функции F(0, 0) можно будет восстановить набор необходимых операций для превращения строки A в строку B. Ну а само значение F(0, 0) и будет искомым ответом.
+
+**Задача E. Принцип домино**
+
+Задача вполне может иметь множество решений, но в данном разборе будет рассказано одно из наиболее тривиальных.
+
+Для начала отсортируем все доминошки по координате x слева направо, запомнив изначальную нумерацию. Эта нумерация потребуется только для вывода ответа в правильном порядке. Далее нужно сформулировать несколько тривиальных утверждений:
+
+> *1) Если толкнуть какую-либо доминошку вправо, то среди упавших доминошек все (кроме самой доминошки) будут находиться справа от той, что толкнули.*
+>
+> *2) Если какая-либо доминошка упала, то упали и все доминошки, которые находятся левее этой, но не левее той, что изначально толкнули.*
+>
+> *3) Для каждой доминошки можно определить номер наиболее правой доминошки такой, что она упадет, если толкнуть данную.*
+
+Обозначим за F(i) номер наиболее правой доминошки, которая упадет, если толкнуть i-ую доминошку. Сама по себе i-ая доминошка может не упасть на F(i)-ую, но из-за "принципа домино" F(i)-ая все же упадет. Если доминошка при падении вообще не задевает никакую другую доминошку, то F(i) = i. Очевидно, что такое равенство выполняется для самой правой доминошки. Для остальных доминошек можно найти значение F(i) с помощью уже найденных F(j), где j > i.
+
+Для каждой доминошки с номером i можно найти такую доминошку с номером j, что при падении i-ая повалит j-ую (непосредственно), и такое j максимально. То есть найти самую правую из доминошек, которую повалит непосредственно i-ая. Далее F(i) = max(F(k)), где k принимает значения на интервале [i + 1, j].
+
+Реализация решения с асимптотикой O(N2) точно не влезет в ограничения по времени. Поэтому необходимо написать решение как минимум за O(NlogN), для чего достаточно воспользоваться структурой данных типа дерева интервалов. Короче говоря, решить задачу Range Maximum Query.
diff --git a/editorials/57.md b/editorials/57.md
@@ -0,0 +1,43 @@
+Source: https://codeforces.com/blog/entry/1171
+
+###
+
+### Problem А.
+
+Since the restrictions were not so big you can offer many different solutions. For example, you can construct a graph with N * 4 vertices and use bfs. But there was a faster solution with complexity O(1): enumerate the integer points lying on the square, for example, as is shown below:
+
+
+
+Then finding the number of a point by its coordinates isn’t difficult. For example if a point has coordinate y == n -> then its position is n + x (if the numeration, is as shown, i.e. starts with zero). It turns out that we have transformed the square into a line with a small complication: cells N * 4 - 1 and 0 are adjacent, so we have not a line but a circle, where for the base points from 0 to 4 * N-1 the distance between the adjacent two points is 1. It is easy to take the difference of indices of the points and find the distance when moving clockwise and counterclockwise: (a-b +4 * n)% (4 * n) and (b - a + 4 * n)% (4 * n), the shortest distance will be the answer.
+
+### Problem B
+
+Under the restrictions on the number of requests, you cannot iteratively add staircase. But the problem is simplified by the fact that the number of cells in which it was necessary to know the number of stones was no more than 100. That’s why you can check for each "interesting" cell all the queries and calculate how much each of them adds stones, so the complexity is: O (K * M), which fits within the given 2 seconds well. A faster solution with complexity O(N + M + K) is as follows: we will keep in mind two variables: a – how many items should be added now to the cell, v - how much should change a next step. So problem is to update the value of a and v so that a equaled to the number of stones in the cell after all the operations, and v – to how much a increases during the transition to the next cell. Then the problem will be reduced to that you need to properly update a and v, which is not very difficult to do, for example if there is a request (x, y, z) – then in the cell x you need to add x to a and add 1 to v, since with each next cell the number of stones for some staircase will increase by 1. Similarly, after the cell y is passed you need to subtract 1 from v and pick up from “a” the current number of stones subquery. If you save all such pairs of queries in a single array and it's possible to calculate everything in one cycle.
+
+### Problem C
+
+First, let's count how many there are arrays in which each successive element starting from the second one is no less than the previous one. To do this quickly, let’s take a piece of squared with height of one square and the length of N*2 - 1 square, then select N-1 squares and put crosses in them - let it encode some array, let the number of blank cells from the beginning of the array before the first cross be equal to the number of ones in the array, the number of blank cells from the first cross to the second – to the number of 2 in the array, and so on. It is easy to see that the number of empty cells will be equal to N * 2-1 - (N-1) = N. It turns out that each paper encodes an array which suits us, and moreover all the possible arrays can be encoded using such paper. There is exactly C (N * 2-1, N) different pieces of paper (the binomial coefficient of N * 2-1 to N). This number can be calculated by formula with factorials, the only difficulty is division. Since the module was prime - it was possible to calculate the inverse number in the field for the module and replace division by multiplication. So we get the number of non-decreasing sequences, respectively have the same number of non-increasing, we just need to take away those who were represented in both array sets, but they are just arrays with a similar number like {1,1,1,...,1} or {4,4,...,4,4} just subtract n.
+
+###
+
+### Problem D
+
+Let's see, if there is no occupied cells, then it is not difficult to calculate the answer - the answer is a sum of Manhattan distances, taking into account the fact that the Manhattan distance can be divided: first we can calculate the distance of one coordinate and then of another one and then just to sum up, so the answer is not difficult to find. What do we have when there are occupied cells? If the cell from which we seek the distance does not lie on the same horizontal or vertical with occupied cells – then it absolutely does not affect the difficulty of accessing the rest of the cells:
+
+
+
+This happens due to the fact that in each cell from the previous distance front (the distance to the set of cells with maximum distance from the start cell, the fronts form a diamond as you can see in the picture or from the Manhattan distance formula) there are two ways how to get to the cell, we take into account the rule that no two cells can be adjacent (either diagonally or vertically or horizontally), it turns out that such a cell does not interfere with us. But a close look at the picture brings to mind the obvious: it is the cell which is located on the same vertical / horizontal that has only one neighbor from the previous front, let’s see what happens in such case:
+
+
+
+All the cells after occupied one starts "to lag" at 2 in distance, but more importantly, that changed the front! Now (with the upper side of the front) are 2 cells for which the transition from the previous front is unique, and as a consequence there are two cells meeting of which will produce a new segment of a late cells, and the angle of the front will change again. Since we are only interested in one side of its expansion (on the other hand there can not be occupied cells by the condition) so we can assume that it was expand from the start cell:
+
+
+
+It turns out that you can count how many cells will be "delayed", especially considering that the lag always equals to two. For each direction, you can choose each occupied cell and check in the left and right directions for adjacent cells series, and add delay for interval of free cell before occupied cell (in the current direction). It is possible to calculate such delays with complexity: square of the number of occupied cells (it is not greater than min(N, M)). The rest is details. You need to compute all Manhattan distances, taking into account the existence of occupied cells. To do this, first calculate the sum of distances for an empty field, then for each occupied cell calculate the distance to all the others - subtract it twice, as the extra distance is subtracted for the first time when we got out of this cell and for the second time when takes away from all other cells to the given one. But in this case we will take away twice the distance between two occupied cells - so we’ll have to add them (the complexity is also a square). A total complexity of solution is O (K ^ 2) where K is the number of occupied cells.
+
+###
+
+### Problem E
+
+### The task turned out to be very difficult as it was planned. First remove all the deleted cells - let's see how changes the number of accessible cells with the increase of the new moves. First, the changes do not appear stable, but at some point we see a figure which won’t to change the form anymore and will only expand, it is obvious that the figure is two-dimensional, therefore the growth of its “area” is a quadratic function, in fact, a simple check shows that with each new turn the number of cells increases by the number of new cells opened with previous turn + 28, so after a certain point, you can simply take the sum of an arithmetic progression. The case with the deleted cells is similar. In general, there are several possible options - either occupied cells block further penetration of the horse or not, in the first case bfs is simply enough to find solutions, in the second one the story is the same: over time, when the figure "becomes balanced", the number of new opened cells satisfies the same rule "prev +28" . Moreover, because of restrictions of the coordinates of the deleted cells (-10 <= x, y <= 10) this happens fairly quickly. So, use usual bfs to balance figures, and after this use the sum of the arithmetic progression.
diff --git a/editorials/58.md b/editorials/58.md
@@ -0,0 +1,30 @@
+Source: https://codeforces.com/blog/entry/1771
+
+**Problem A. Chat room**
+
+Solution is greedy algorithm. The first thing we do is find in our string the first letter 'h'. Then we find letter 'e' which is righter that found 'h'. If we find the whole word 'hello' in such way, obliviously, answer is YES.
+Now let's prove that if answer exists, we find it. Let see on position of the 'h' in right answer. If we move it to the first 'h' in our string, nothing changes. But now we can say that our greedy algorithm correctly Now let's do such with the second letter, and so on.
+We have greedy algorithm with work time O(n), where n - length of the input.
+
+
+
+**Problem B. Coins**
+
+This problem also have greedy solution: we run down all number from 2 and greater and while denomination of the last added to answer coin is divisible by current number, we divide and increase answer.
+You can prove correctness, if you take a look at prime factorizations of coins' denominations. In each next denomination each prime have less or equal power than the current one (it's equivalent to '*a* divide *b*'). Obliviously, if summary degree of primes decreases at least two (for example, we had number*a* = *x*· *y*· *z* (where *y*, *z* > 1, and the current number is *b* = *x*), then we can add one more coin with demonitaion *a* > *c* = *x*· *y* > *b*. So, in the optimal answer sum of degrees decreasing at exactly one. Our greedy algorithm do exactly what it need.
+
+
+**Problem C. Trees.**
+
+The first thing we notice - beautiful sequence is can be determined with any member. The next thing - at least one tree will remain the same height. Prove: let's fix height of the first tree, and correct heights of all other ones. Obliviously, they all remain positive.
+Solution with work time *O*(*n*2): we run down which tree we will fix, determine required height of the first tree and then relax answer.
+This solution can be optimized to linear solution: if we don't touch some tree, we know the first element of sequence. Let's count for each possible element amount of trees, which have required height. It can be done with linear loop and the 'increment' operation on array. After that we just find value of the first element, for which amount of 'good' trees is maximal and output *n* - *x*, where *x* is this amount.
+
+**Problem D. Calendar**
+
+We know, that all lines of calendar should have equal length, so we can find this length. It's just , where *suml* - summary length of all strings. Now let take a look at string, which will be the first one in our calendar. Obliviously, it's profitably to take string with maximal *s* + *d* (where *s* is our string and *d* - is character from input). Such string is unique otherwise we have two equal strings in input (as *d* is not contained in any string); Of cause, you should remember that if you fix the first string in a line, you fix length of the second one - it's required to have at least one such. Great, now we know the first string in our calendar. Now let's determine the second one. We know it's length, so we need just to take minimal string with such length.
+We know one line, let's do similary with the second line and so on.
+
+**Problem E. Expression**
+
+Under construction. The main idea is 3D dynamic with O(102) transition.
diff --git a/editorials/60.md b/editorials/60.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/1317
+
+**Problem A.** Solution - *O*(*n*2).
+
+We take phrase and parse it. Mark all cells, that obviously didn't match - *O*(*n*). In the end we go through the array and count all unmarked cells.
+
+If 0 - we print "-1", else - amount of unmarked cells.
+
+**Problem B.** Solution - *O*(*k* × *n* × *m*).
+
+We start BFS from given point. Go from cell to all 6 directions. The answer - number of visited cells.
+
+**Problem C**. Solution - *O*(27 × *n*2).
+
+We can see, that in connected component - if we know 1 number - then we know all others in component, because in each pare we know minimal and maximal
+
+power of each primes. Because number of different primes in one number " < = 1000000" is less, than 7, we can look over all possibilities of 1 number in connected compoment - and for each number, that we get, we check, that it suits.
+
+How to check? We can notice, that if we know *a*, (*a*, *b*), [*a*, *b*], then , start DFS and check.
+
+**Problem D.** Solution - *O*(max numebr).
+
+We can notice, that each beautiful triplet has form - (*x*2 - *y*2, 2*xy*, *x*2 + *y*2). Now we can gen all such triples. For each triple, we watch - if we have more than 1 number in given set - we union them.
+
+How to gen all the triples?
+
+*x* > *y*.
+
+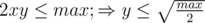. This means, that 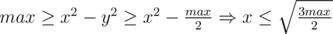.
+
+Now for gen all this triples we an take -  и . The number of iterations - .
+
+what means - "union"?
+
+We take a data structure named DSU. If two number belong to one beautiful triple - they are connected with edge, in our situation - we can union corresponding to them unions.
+
+**Problem E**. Solution - *O*(*n* + *log*(*xy*)).
+
+We can see, that after one minute the sum changes - it multiply on 3, and substract first and last elements of sequence. Because of that we can count of sum with help of power of matrix.
+
+What happens after sorting.
+
+First number stay on his place. On the last place - *F**x**a**n* + *F**x* - 1*a**n* - 1. Where *n* - number of elements, ans *F**x* - *x* Fibonacci number - with *F*- 1 = 0 and *F*0 = 1.
+
+This means - that we can count the last number with matrix too.
+
+After that we use the first idea.
+
+If you have questions - ask them.
diff --git a/editorials/62.md b/editorials/62.md
@@ -0,0 +1,59 @@
+Source: https://codeforces.com/blog/entry/1363
+
+Problem A. A Student's Dream.
+
+There was a lot of troubles because of incorrect statement. Now I hope statement is ok. Let's solve it. =)
+
+If boy will goes to the left he will take her left hand with his right one and boy's left hand and girl's right hand will be unused. Situation is looks like the same if we swap them vice versa. So, we need to check two situations and choose the best one.
+
+There is a simple way to check comfortableness, let's assume that boy has *B* fingers on active hand and girl has *G* fingers on active hand, so:
+
+* If *B* < *G* they will be happy only when *B* = *G* - 1, you may see a pattern *GBGBGBG*...*GBGBG*. In this pattern you can add no girl's finger for save the condition in statement
+* If *B* > *G* the worst but correct situation for them is a pattern *BBGBBGBB*...*BBGBB*. As you may see this way must be satisfy 2*G* + 2 > = *B* condition
+* Simple situation is *B* = *G*, obviously answer is "yes"
+
+Problem B. Tyndex.Brome.
+
+Let's define *p* as total length of all potential addresses *c*. In this problem obvious solution has O(*p*· *k*) difficulty and it is getting a TLE verdict. Let's speed up it by next way: we will save all position of letters 'a', 'b', ..., 'z' in address entered by user *s* separately in increasing order. After this step we can find closest position of letter *c**i* in *s* for logarithmic time by binary search. This solution has O(*p* · *logk*) difficulty that gives "accepted".
+
+Look carefully for length of potential address (it can be more than 105). Answer can be too big and asks you for using integer 64-bit type.
+
+Problem C. Inquisition.
+
+All triangles are located strickly inside of square. It makes problem more simplify, because you don't need to check situations of touching sides.
+
+Let's save all segments of every triangle and cross them in pairs. There are many points at every segment - the results of crossing. Look at the every subsegment which do not contain any points of crossing inside. There are two situations: this subsegment completely lie on the side of some triangle or this subsegment completely lie inside of some triangle.
+
+We may check what is situation by this way: let's take a point at the middle of subsegment. If this point is strickly inside of some triangle then all subsegment is located inside and vice versa. We should calculate only subsegments located on the side of triangles and print their total length.
+
+If you are using integer numbers you should be careful for some operations like vector multiplication because it may leave 32-bit type.
+
+If you are using real numbers you should change you types for as large as possible for good precision (long long in c++, extended in pascal).
+
+Problem D. Wormhouse.
+
+In this problem you asks to find lexicographically next euler cycle or say that there is no way. Let's solve this problem backwards.
+
+We should repeat way of Arnie. Now it needs to rollback every his step and add edges for empty graph (graph without edges). Let's assume we had rollback edge from some vertix *x* to vertix *y*. We need to check is there some vertix *z* that is connected to *x* by an edge and value of *z* is more than *y*? Besides edge (*x*; *z*) shouldn't be a bridge because our component needs to be connected.
+
+No solution answer if it's impossible to find such *z* at any step.
+
+But if edge (*x*; *z*) satisfied to conditions upper is exists let's change it to move and after this step our problem is to find lexicographically smallest euler way. It is possible to find only in unbreaked component of graph so every next step must going along non-brigde edges in vertix with as low number as possible. Of course, we must destroy unachievable vertices and do not destroy initial vertix.
+
+We can check is edge a bridge for O(*E*) time by depth first search. Total difficulty of algorithm represented above is O(*N*· *E*2).
+
+Problem E. World Evil.
+
+*Author of this problem is Vasily Vadimov, NNSU. He wrote her own tutorial for you.*
+
+In this problem you were to find the maximal flow in network with a cyllinder structure. The dynamic solution with complexity *O*(*mn*2*n*) was considered.It's well known that the maximal flow is equal to value of the minimal cut. Also all the sources must belong to one part of the cut and all the drains --- to the other part. Then we look over all the vertices from the left to the right, from the top to the bottom and append to the one or the other part of the cut, recalculating the answer during the process. The trivial solution has complexity *O*(2*mn*) and doesn't fit the time limit.
+
+But we can notice the number add to the answer after appending a new vertice to some part of the cut depends only on what parts of the cut the vertices in the current and the previous columns belong to. So we can calculate such a value using dynamic programming: what is the minimal cut can be obtained by adding *i* columns and the mask of belongings of vertices of the *i*th column to the parts of the cut is *mask*. Then we have 2*n* conversions because there are 2*n* different states of the *i* - 1th column. So we have the *O*(*mn*22*n*) solution.
+
+But this solution also can be improved. We calculate the minimal cut, if *i* - 1 columns are added completely and *j* vertices from the *i*th column are added, and mask of belongings of vertices that have no neighbours on the right is *mask*. Then we append *j*-th vertice to one of the parts, recalculate the value of the cut and do the conversion. So we have *mn*2*n* conditions and *O*(1) conversions from the every condition and the solution's complexity is *O*(*mn*2*n*).
+
+Also congratulations to the participants rng_58 and Ra16bit who solved this problem during the contest!
+
+*Thanks to boys from NNSU (Vladislav Epifanov, Alexey Shmelev) who helps us with alternating solutions and etc.*
+
+*Sorry for poor english*
diff --git a/editorials/63.md b/editorials/63.md
@@ -0,0 +1,13 @@
+Source: https://codeforces.com/blog/entry/1391
+
+These are my solutions and little explanation
+
+[Problem A](http://blog.vudduu.com/2011/02/codeforces-beta-round-59-solution.html)
+
+[Problem B](http://blog.vudduu.com/2011/02/codeforces-beta-round-59-solution_28.html)
+
+[Problem C](http://blog.vudduu.com/2011/02/codeforces-beta-round-59-solution_3345.html)
+
+[Problem D](http://blog.vudduu.com/2011/02/codeforces-beta-round-59-solution_7459.html)
+
+[Problem E](http://blog.vudduu.com/2011/02/codeforces-beta-round-59-solution_8729.html)
diff --git a/editorials/65.md b/editorials/65.md
@@ -0,0 +1,95 @@
+Source: https://codeforces.com/blog/entry/1431
+
+**Problem A**
+
+Fist, consider the case when all the numbers are non-zero. You can take a*c*e grams of sand, turn them into b*c*e grams of lead, and them turn into b*d*e grams of gold, and them turn into b*d*f grams of sand. If b*d*f > a*c*e, you can infinitely increase the amount of sand and consequently the amount of gold. Otherwise, if b*d*f <= a*c*e, it is impossible to get infinitely large amount of gold. The same is true when the fraction (a*c*e)/(b*d*f) has zero numerator only or zero denuminator only. Otherwise there is 0/0, and you have to check cases specially.
+
+I explain, why I make this problem to be problem A.
+
+1. Solution of the problem requires very little knowledge of programming (only "if"), so it was feasible for all participants.
+
+2. Tricky cases really exist, but I hoped that "stronger competitors will ... help newcomers to catch all bugs by their hacks". And so it happened.
+
+Maybe I was wrong: this problem is too complex for A.
+
+A large number of hacks for this problem is a quite foreseen circumstance. I haven't include the special class of tests into the pretests intendently, to make hacking more interesting. In fairness I should note that Artem Rakhov was against this idea. Beause of this task the problem surfaced that Gassa writes about [here](https://codeforces.com/comments/1432#comment-26176) in Russian: pretests cover some incomplete set of cases and it is not clear in advance what the event "solution passed pretests" means. I think it should be discussed, and strong principles of pretests development should be stated.
+
+**Problem B**
+
+The problem has greedy solution. Change a digit in the first date to make it as small as possible. At each of the next steps try all one-digit exchanges in the current date and choose one that makes the date not less than the previous one and as small as possible at the same time. If the last year won't exceed 2011 - the answer is found. Otherwise there is no solution.
+
+How to prove that? Consider any correct answer. Clearly, if the first date in it is different from the smallest possible number that can be obtained from the first of given years, your can put the smallest number instead of it. The second date can be exchanged by the smallest possible number not exceeding the first number, etc.Ar a result you obtain a greedy solution that is built by the algorithm described above. If the greedy solution doesn't exist, solution doesn't esist too.
+
+The problem also has a dynamic solution.
+
+**Problem C**
+
+Check for each segment in the polyline if Harry can catch the snitch in it. Note that since *v**p* ≥ *v**s*, if Harry can catch the snitch at some moment of time, he can catch it at any later moment. He can just follow snitch along its trajectory. So use binary search in each segment.
+
+About problems with EPS that participants got. The problems may be caused by
+
+1) some EPS in the condition: while (leftTime + EPS < rightTime) <do binary search>. The task was to output with a fixed accurancy not only the time, but also the point coordinates. If the difference between the time and the right one is less than EPS, the difference between coordinates may be significantly larger. In such cases you should compare not arguments of a function, but values of the function with EPS. Or the way that I usually follow and that once was not liked by the teacher of numerical methods - to implement some fixed number of iterations of the binary search (say, 60).
+
+2) EPS in comparison of time moments inside the binary search like this:
+
+if (currentTime + addTime > distance / potterSpeed - EPS)
+
+rightTime = currentTime;
+
+else
+
+leftTime = currentTime;
+
+Here it is better to remove EPS at all. Or to put EPS significantly smaller than the required accurancy for printing the point.
+
+(Code fragments are from Egor's solution.)
+
+Thus, there was no crime with severe limitations. Probably for such problems extreme accurancy tests should be in pretests? It is about principles of pretests making again.
+
+**UPD.** The problem has an analytical solution too. Consider the i-th segment. Let (*x**i*, *y**i*, *z**i*) and (*x**i* + 1, *y**i* + 1, *z**i* + 1) be its ends, and let *t**i* be the time required for the snitch to reach the beginning of the segment. Then at the moment t the snitch will be at the point (x, y, z), *x* = *x**i* + (*x**i* + 1 - *x**i*)(*t* - *t**i*) / *T**i*, *y* = *y**i* + (*y**i* + 1 - *y**i*)(*t* - *t**i*) / *T**i*, *z* = *z**i* + (*z**i* + 1 - *z**i*)(*t* - *t**i*) / *T**i*, *T**i* is a time necessary for snitch to overcome the segment. To catch the snitch at the point (x, y, z), Harry have to overcome the distance that squared is equal to (*x* - *P**x*)2 + (*y* - *P**y*)2 + (*z* - *P**z*)2 for the time t. It is possible if (*x* - *P**x*)2 + (*y* - *P**y*)2 + (*z* - *P**z*)2 ≤ (*tv**p*)2. To find the minimal proper moment t, solve the corresponding quadratic equation.
+
+**Problem D**
+
+Let *S**i* be a set of all possible assignments of the first *i* students to the houses, that is a set of tuples (*a*1, *a*2, *a*3, *a*4), where *a*1 is a number of students sent to Gryffindor, *a*2 - to Ravenclaw, etc. It's intuitively clear that these sets will not be large. So you can get *S**i* - 1 from *S**i* in a trivial way, and get finally *S**n*, and determine the answer from it.
+
+**What is a rigorous proof of the algorithm? Let us have a set***S* = {(*a**i*1, *a**i*2, *a**i*3, *a**i*4)}*i* = 1, 2, ..., *k*. Represent its elements as *a**i**j* = *b**j* + *x**i**j*, *x**i**j* ≥ 0, where *b**j* are maximal possible, i.e. there is i for each j such that *x**i**j* = 0. Let the tuple (*b*1, *b*2, *b*3, *b*4) be called the base part of S, and the set {(*x**i*1, *x**i*2, *x**i*3, *x**i*4)}*i* = 1, 2, ..., *k* be called the variant part of S.****
+
+Initially for *S*0 both base and variant parts are zeroes. Let us see how base and variant parts change when a current student is added. If a house is fixed for the student, only the base part changes. It increases by 1 at the position corresponding to the house. In particular, it follows that a set with every base part can be obtained (since the string given in the input can contain every combination of symbols G, H, R, S). If the current symbol in the string is '?', it can influence both base and variant parts.
+
+For example, for the string '????' we have:
+
+*S*0 = {(0 + 0, 0 + 0, 0 + 0, 0 + 0)},
+
+*S*1 = {(0 + 1, 0 + 0, 0 + 0, 0 + 0), (0 + 0, 0 + 1, 0 + 0, 0 + 0), (0 + 0, 0 + 0, 0 + 1, 0 + 0), (0 + 0, 0 + 0, 0 + 0, 0 + 1)},
+
+*S*2 = {(0 + 1, 0 + 1, 0 + 0, 0 + 0), (0 + 1, 0 + 0, 0 + 1, 0 + 0), (0 + 1, 0 + 0, 0 + 0, 0 + 1), (0 + 0, 0 + 1, 0 + 1, 0 + 0), (0 + 0, 0 + 1, 0 + 0, 0 + 1), (0 + 0, 0 + 0, 0 + 1, 0 + 1)},
+
+*S*3 = {(0 + 1, 0 + 1, 0 + 1, 0 + 0), (0 + 1, 0 + 1, 0 + 0, 0 + 1), (0 + 1, 0 + 0, 0 + 1, 0 + 1), (0 + 0, 0 + 1, 0 + 1, 0 + 1)},
+
+*S*4 = {(1 + 0, 1 + 0, 1 + 0, 1 + 0)}.
+
+Let us investigate the question of what species a variant part may have. It can be analyzed independently from a base one, taking into account that a base part can be any. Consider a directed graph with vertices corresponding to variant parts and with edges determined by the existence of**at least one base part that let go from one variant part to another. We are interested only in vertices reachable from {(0, 0, 0, 0)}.**
+
+Proposition. For all the vertices reachable from zero the following properties hold
+
+(1) *x**i**j* ≤ 2,
+
+(2) *k* ≤ 13.
+
+Let us prove that all the vertices not having the properties (1) and (2) are unreachable from zero. Consider a variant part with the property (1). To get all edges going from it you have to try all possible base parts. Note that base parts, that consist of the numbers 0, 1, 2, 3 and contain at lest one 0, are enough. Indeed, base part influence which elements are minimal, and 1 will be added to them. A base part can be always normed to contain at least one 0. If a base part contains numbers greater than 3, then the corresponding positions will never be minimal (since 4+0 > 0+2) and they can be changed equivalently by 3 (3+0 > 0+2).
+
+Unfortunately, my attempts to deal with cases by hand were unsuccessful, so I wrote [the program](http://pastebin.com/p3sFKKya) that traverse the described graph. Starting from 0, it builds edges trying only "small" base parts described in the previous paragraph. As a result, the program obtains all the reachable variant parts (there is a little more than 1000 of them) and check (1) and (2) for them. In addition, the program helps to construct a test with***k* = 13.**
+
+**The problem was supposed to be a problem on intuition. Participants have another solution passed. Their solution generate all permutations and distribute students greedily with respect to each permutation.******This solution was a complete surprise for me. Unfortunately, it is wrong. Test 66 against it was added. Of course, submissions accepted during the round won't be rejudged. If such a solution be expected, most likely I wouldn't give such a task. In terms of intuition this solution is not better and not worse than mine. I hope you will not judge me strictly: it is a beautiful problem, and it was interesting to see how it would be solved.****
+
+**Problem E**
+
+Consider a graph with floors as vertices and staircases as edges. It is clear that Harry can visit the whole connected component in which he is currently located.
+
+Every edge can be used to reach a new vertex for not more than two times. If a connected component contains n vertices and m edges, only n - 1 edges are used to reach a new vertex during its traversal. The remaining m - n + 1 edges are not used to reach a new vertex in their initial placement. So they will be used to reach a new vertex not more than once.
+
+So using edges of only one connected component you can reach no more than n - m + 1 new vertices. Totally there are not more than 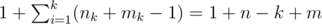 reachable vertices. If m < k - 1, it is impossible to visit all the vertices.
+
+We show that otherwise (m >= k - 1), if the degree of the vertex 0 is different from zero, it is possible to visit all the vertices. In other words, there is such a traversal that every edge can be moved. Use depth-first search for the current component. If a current edge goes to an already visited vertex, move it to a new component and traverse it recursively. If a current edge goes to a new vertex, after you visit this vertex and go back, you also can move this edge to a new component. As a result each edge can be moved and used again, if you reach all the components. If a component contains at least one edge, you can go from it to the next one. First visit components with edges, and you will visit them all and by the inequality (m >= k - 1) there are enough edges to visit all the isolated vertices.
+
+If the degree of the vertex 1 is zero, you can not start a traversal before you move some edge to it. After that you can go by this edge and remove it with the vertex 1 from the graph, becase you can not use this edge once more. If the chose edge is a bridge, you get k connected components and m - 1 egdes. If it is not a bridge, you get k - 1 components and m - 1 edges. In the first case the inequality m >= k - 1 turns m >= k. In the second case - m >= k - 1. So if not all the edges are bridges, you should not take a bridge. If they all are bridges, you should disconnect an edge from a vertex of degree >= 2 not to came back to the initial situation with the zero degree of the first vertex. If there is no such vertex, it is easy to check that there is no solution.
diff --git a/editorials/66.md b/editorials/66.md
@@ -0,0 +1,90 @@
+Source: https://codeforces.com/blog/entry/1452
+
+Here you can find the editorial for the past round. You can ask questions in the comments below. Special thank you goes to [sdya](//codeforces.com/profile/sdya "Colonel sdya") who prepared editorials for problems D and E, which I used here.
+
+### Problem A
+
+In this problem you should answer to 4 questions:
+
+1) Can we use type byte to store N?
+
+2) Can we use type short to store N?
+
+3) Can we use type int to store N?
+
+4) Can we use type long to store N?
+
+We should check these conditions in the given order. If all these conditions are wrong, the answer is BigInteger.
+
+The simplest way to check these conditions is to store numbers as strings and write a function to compare such strings. In Java you can use type BigInteger.
+
+### Problem B
+
+Try to check all possibilities for creation artificial rain and calculate how many sections contain water. The maximal answer from all these possibilities is the answer for the problem. To calculate the answer for the given position we should check how many sections are to the left and to the right of the given section receive water. The complexity of this algorithm is O(N^2).
+
+### Problem C
+
+Will be published later.
+
+### Problem D
+
+Consider N distinct prime numbers: p1, p2, …, pn.
+
+Let A=p1*p2*…*pn. Then, easy to see, that the numbers A/p1, A/p2, …, A/pn can be considered as the answer.
+
+The special case is when N=2. In this case there is no answer. We can see that this solution needs long arithmetic. If we choose first n prime numbers as p1, p2, …, pn then the maximal number in the answer for all N<=50 contains less than 100 digits.
+
+
+
+Of course, there are other solutions. For example, if N=3 numbers 15, 10, 6 are the answer, and for N>3 numbers 15, 10, 6, 6*2, 6*3, …, 6*(N-2) are the answer.
+
+### Problem E
+
+First of all we divide our problem into 2 parts: consider stations from which we can start if we are moving in the clockwise direction and stations from which we can start if we are moving in the counterclockwise direction.
+
+Obviously, if we know the solution of one of these problems, we know the solution of another problem.
+
+So, we may assume that stations are located in the counterclockwise order and we are moving in the counterclockwise direction.
+
+Consider the following differences:
+
+D1=a1-b1,
+
+D2=(a1+a2)-(b1+b2),
+
+D3=(a1+a2+a3)-(b1+b2+b3),
+
+…
+
+Dn=(a1+a2+…+an)-(b1+b2+…+bn);
+
+Obviously if one of Di’s is less than a zero, then we cannot drive one round along the road. Let D = min(Di) – we will use it later.
+
+Obviously, if D<0 then the first station cannot be the start station.
+
+Now, we can check with complexity O(n) whether the first station can be used as the starting point. Next, we want to show how we can check this for the second station with complexity O(1).
+ To show this, consider:
+
+E1=D1-(a1-b1),
+
+E2=D2-(a1-b1),
+
+…
+
+En=Dn-(a1-b1).
+
+Next, substitute Di in these equalities. We get the following:
+
+E1=(a1-b1)-(a1-b1)=0=(a2+a3+…+an+a1)-(b2+b3+…+bn+b1) – (a1+…+an=b1+…+bn=X)
+
+E2=(a1+a2)-(b1+b2)-(a1-b1)=a2-b2
+
+E3=(a1+a2+a3)-(b1+b2+b3)-(a1-b1)=(a2+a3)-(b2+b3)
+
+…
+
+En=(a1+a2+…+an)-(b1+b2+…+bn)-(a1-b1)=(a2+…+an)-(b2+…+bn)
+
+But it’s easy to see that number E1 has the same meaning for the second station as number D1 for the first one. So, we just have to check min(Ei)>=0. But Ei=Di-(a1-b1), so we have to check min(Di-(a1-b1))>=0. Now, we can see that if min(Di)=Dk, then min(Di-(a1-b1))=Dk-(a1-b1). So, if we know Dk, that we can check whether the second station can be the starting point with complexity O(1). Similarly, we can check this for the third, the fourth, …, the nth stations.
+
+Now we should check the same things but assuming that the car is moving in the clockwise direction.
diff --git a/editorials/68.md b/editorials/68.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/1542
+
+**A**
+
+Итак, в этой задаче можно было просто выполнить то, что было написано в условии – перебрать все числа от **A** до **B**, для каждого из них перебрать все перестановки модулей и проверить, что не менее чем для 7 перестановок **f(****x)=****x**.
+
+А еще можно было заметить следующее. Пусть **p=min(p1,p2,p3,p4).** Тогда если **x<p**, то, очевидно, при взятии любого модуля **x** не изменится, ведь он меньше любого модуля. Очевидно также, что в противному случае он изменится, потому что будет взят по определенному модулю, меньше или равному **х**. Таким образом, вне зависимости от перестановки модулей, для числа либо выполняется равенство **f(x)=x**, либо не выполняется. Некоторые участники просто проверили для определенной перестановки модулей, подходит ли каждое число из промежутка, и вывели количество чисел, для которых равенство выполняется. Однако достаточно было даже просто посчитать количество чисел в пересечении интервалов **[0;p-1]** и **[****a;****b]**.
+
+
+
+**B**
+
+Пусть у нас после всех перераспределений энергии во всех накопителях установился уровень энергии, равный **Х.** Тогда очевидно, что все накопители, в которых было больше **Х** изначально, должны передавать энергию накопителям, в которых изначально было меньше **Х**. Таким образом, каждая частица энергии будет передана лишь один раз. Пусть изначально у всех накопителей, у которых было больше **Х** энергии, в сумме было **Up**, а всего их было **A**, а у остальных сумма – **Dn**, и их **B=N-A**. Тогда **(Up-A*X)*****(100-K)/100.0= X*B-Dn** – то, что нужно заполнить, составляет **100-К** процентов от того, что надо убрать. Ясно, что одна из сторон этого равенства будет возрастать, а вторая – падать, при изменении **Х**. Следовательно, можно реализовать двоичный поиск по величине **Х**, подсчитать левую и правую часть этого уравнения, и изменять границы в зависимости от того, какая часть больше.
+
+На самом деле можно перебирать **Х**, равный только величине начальной энергии в какой-то точке, это можно сделать в целых числах, а затем на фиксированном промежутке между двумя значениями найти ответ аналитически. Любопытные могут вывести формулы самостоятельно.
+
+**C**
+
+ Авторы предполагали следующее решение задачи: последовательно перебираем количество топлива, которое течет по каждой трубе. В тот момент, когда значения топлива во всех трубах, идущих от или к какой-то вершине, уже определены, (если это не начальная и не конечная вершина) проверяем, что сумма топлива, которое втекло в узел, равна сумме топлива, которое из него вытекла. Также надо было проверять, что сумма топлива, текущего из начальной вершины, не больше уже найденного лучшего ответа. Решение работает в пределах 30мс на всех тестах.
+
+ Хотелось бы услышать, какое решение писали некоторые участники. Напоминает динамику по профилю?
+
+ UPD: Оценка сложности. Ребер из первой вершины 5. Перебор всех возможных значений потока в этих ребрах - 65 Из каждой следующей на 1 ребро меньше, но надо учесть, что значение потока по последнему ребру определяется однозначно. Стало быть сложность 65 * 63 * 62 * 61 * 60 * 6 = 612 = 2176782336. Последний множитель - это проверка на то, что сумма входящих равна сумме выходящих. Это число велико, но участники сами могли убедиться, что при отсечении, что мы не рассматривает поток больший уже найденного, решение работает очень быстро.
+
+**E**
+
+Disclaimer: Я буду часто употреблять фразу «треугольник», подразумевая «точки, соотвествующие данному треугольнику».
+
+Во-1, очевидно, что если два треугольника полностью совпадают, то имеет смысл их наложить.
+
+Теперь предположим, что у нас нету полностью совпадающих треугольников.
+
+Посмотрим на лучшее возможное расположение треугольников на плоскости, такое, что оно состоит ровно из оптимального числа точек.
+
+Рассмотрим граф из 4 вершин, соответствующих треугольникам. Между парой вершин столько ребер, сколько общих точек у двух соответствующих треугольников.
+
+Ясно, что этот граф связен. ( Пусть это не так. Тогда у нас есть два множества треугольников, не имеющие общих точек. Сдвинем одно множество так, чтобы у него была общая точка со вторым множеством. Ответ уменьшился. Противоречие. )
+
+Посмотрим на графы в этом цикле.
+
+Что значит, что есть цикл длины 2? Значит, у 2 треугольников две общие точки.
+
+Что значит, что есть цикл длины 3? Значит, есть тройка точек, таких, что любые две принадлежат какому-то из трёх треугольников.
+
+Что значит, что есть цикл длины 4 и нету циклов длины 2 и 3? Это значит, что есть 4 точки, такие, что любые две соседних принадлежат какому-то треугольнику. Этот случай можно рассмотреть отдельно – проверить, что можно выбрать по стороне от каждого из треугольников так, чтобы они образовывали 4угольник. Пускай мы его рассмотрели.
+
+Итак, как мы можем перебрать все разумные расположения точек? Будем перебирать все порядки добавления треугольников. Пусть у нас уже добавлены некоторые точки. Может произойти одно из трех действий:
+
+1). Мы просто добавляем наш очередной треугольник так, чтобы он имел общую точку со всеми предыдущими. К примеру, одна точка в (0,0), еще одна в (х,0), еще одна со строго положительной ординатой.
+
+2). Мы нашли пару точек, расстояние между которыми равно стороне текущего треугольника. Тогда у нас есть не более 4 вариантов, как приставить его, чтобы его сторона совпала с отрезком, соединяющим две выбранные точки. Добавили, пошли дальше.
+
+3). Мы нашли пару точек A B, таких, что можно найти такую точку С, что расстояния АВ и АС равны сторонам двух еще не добавленных треугольников соответственно. Добавляем эти два треугольника. Это соответствует либо циклу длины 3, либо 4 либо какому-то пути.
+
+Проверяем что число точек в данный момент не превышает оптимального, переходим к следующему ( в случаях 1-2) или через 1 (в случае 3) треугольнику. И все)
+
+Деталь реализации: чтобы найти точку, находящуюся на двух заданных расстояниях от двух заданных точек, достаточно уметь пересекать окружности.
diff --git a/editorials/69.md b/editorials/69.md
@@ -0,0 +1,66 @@
+Source: https://codeforces.com/blog/entry/1571
+
+Problem A.
+
+In this task all you had to do was to make sure that the sum of all Σxi is 0, the sum of all Σyi is 0 and that the sum of all Σzi - 0 .
+ We have not written that condition evidently in order that participants will have a chance to break a solution.
+
+
+
+Problem B.
+
+In this problem, in fact, you should find a winner at every section. For each section, you must do a full search of all competitors to find a competitor with a minimum section time, which ran that section. Asymptotic of the solution is O(nm).
+
+
+
+Problem C.
+
+In this task, you had to update the collection of artifacts, which belong to Kostya’s friends, after each purchase . You had to set a matrix c[i][j] - number of the j-th basic artifact that is required in order to collect the i-th component artifact. Further, one can make a matrix of composite artifacts, where a[i][j] is number of the j-th basic artifact of the i-th friend and a similar matrix b of composite artifacts, and check whether i-th friend has any a composite artifact of O (MN) after each i-th friend’s purchase. Check whether one component of the artifact assembles for O (N): while checking whether the i-th friend is able to collect the j-th artifact you have to check, if there is such u, that c[j [u]> a[i][u], if so, the j-th artefact will not be collected, if not, then you have to increase the b[i][j] and update the values in a[i]).
+
+So.the asymptotics of the processing of all purchases will be O (NQM). Then, we need to make a list of artifacts for each person, keeping their quantity(a total of O (KN + KM), and sort it (a total of O (QlogQ)).
+
+
+
+Problem D.
+
+This game is over, because except for a finite number (2) of reflections about the line y = x,the coordinates are changed to non-negative integer (and at least one coordinate is changed to a positive number).
+
+Algorithm for solving this problem is DFS / BFS (states) where the state is a pair of coordinates, and two logical variables, which denote if the 1 (2) player had reflected a point about the line y = x.
+
+Total number of states is obtained by S <= 4D^2 (pairs of coordinates) * 4 (Boolean variables).
+
+Processing of one state takes O (N) actions (do not forget to try to reflect the point about the line y = x, if the player had not made it earlier in the game). Thereby, we have the overall asymptotic O (ND^2), which works on C + + in less than 200ms.
+
+
+
+
+
+Problem E
+
+To solve this problem you have to do a "move" subsegment and know :
+
+ 1. The set B of numbers, meeting once, with the function of extracting the maximum for O (logN)
+
+2.The set of numbers appearing on this subsegments with keeping the number of times,that this number is found on this subsegments, with function of verifying how many times the number in this subsegments for O (logN).
+
+
+
+While moving a segment from (a[i] .. a[i + k - 1]) for 1 item left (a[I + 1] .. a[I + k]) you have to:
+
+1) Check whether a[i] with a[I + k]. If yes, then there is no need to modify the set, otherwise proceed to item 2 and 3.
+
+2) Check how many times we have a[i] in the set A: if 2, then add a[i] to B, if 1, then remove it from A and B. Do not forget to reduce the corresponding number of occurrences of a[i] in the current segment 1.
+
+3) Check, how many times we have a[I + k] in the set A: if 0, then add a[i] in the B and A, if 1, then remove it from B. Do not forget to increase the corresponding number of occurrences of a[i] the current interval to 1.
+
+
+
+After that, if the set is not empty, we should take peak from it.
+
+
+
+So the asymptotics of this process will be O(NlogN).
+
+
+
+As such data structures set / map(for those who use C + +) and the Cartesian tree are suitable.
diff --git a/editorials/70.md b/editorials/70.md
@@ -0,0 +1,57 @@
+Source: https://codeforces.com/blog/entry/1598
+
+**Problem A.**
+
+Let's define a half-filled square of size *k* as an empty square of size *k* after adding a cookie of the biggest posible size.
+
+Notice, that if we add a cookie of the biggest possible size into the half-filled square of size 2*n* × 2*n*, it will be divided into three half-filled squares of size 2*n* - 1 × 2*n* - 1 and one filled square. After performing the same actions with the three half-filled squares we will get nine half-filled squares of size 2*n* - 2 × 2*n* - 2 and so on. It's easy to get the formula *f*(*n*) = 3 * *f*(*n* - 1), *f*(0) = *f*(1) = 1. 3*n* - 1 (for *n* > 0) and 1 (for *n* = 0).
+
+**Problem** **B.**
+
+It's obviously, that sentences should be added into the SMS greedily. Really, if we put the sentence into the new message, when it's possible to add into previous, the number of messages may be increased. The only thing you should pay attention is correct processing whitespaces between the sentences.
+
+**Problem** **C.**
+
+Will be added soon.
+
+Let's learn how to solve more easy problem: it's need to count a number of lucky tickets with 1 ≤ *a* ≤ *x* and 1 ≤ *b* ≤ *y*. Rewrite sentence *a* * *b* = *rev*(*a*) * *rev*(*b*) as *a* / *rev*(*a*) = *rev*(*b*) / *b*. Brute all *a* and count a number of irreducible fractions *a* / *rev*(*a*) using, for example, map from STL. Now for every *b* you should count the number of fractions *a* / *rev*(*a*) equal to *rev*(*b*) / *b* and add to answer.
+
+Come back to our problem.
+
+If the number of lucky tickets with 1 ≤ *a* ≤ *max**x* and 1 ≤ *b* ≤ *max**y* less than *w*, it should be printed - 1. If the solution exist, let's use the method of two pointers.
+
+We need to keep up the quantity of lucky tickets with 1 ≤ *a* ≤ *x* and 1 ≤ *b* ≤ *y* for some state (*x*, *y*) an change it to (x,y+1), (x+1,y), (x,y-1), (x-1,y). That's why we create two structures of type map (named m1 and m2). Let's learn how to change state from (x,y) to (x,y+1), (x+1,y), (x,y-1), (x-1,y). If we want to increase (decrase) the value of *x*, we should add (subtract) m2[x/rev(x)] to (from) the number of lucky tickets and increase (decrease) m1[x/rev(x)] by one. In the case of changing *y* you should do the similar actions.
+
+Let's set the state (*x*, *y*), where *x* = *max**x*, *y* = 1 and count the quantity of lucky tickets for it. We will be increase *y*, while the number of lucky tickets is less than *w*. Obviously, that it will be the least *y* for *x*, such as it will be enough lucky tickets in the range. Relax the answer. You had to decrease *x* by one and do the same actions while *x* is greater than one.
+
+The anser have the least value of *x* * *y* because we relaxed it with the optimal state for every *x*.
+
+So, the *x* was equael to every value between 1 and *max**x* not more than once. The similar is correct for *y* because it was only increasing. The time need for change the value in map is O(log(map_size)), that's why the algorithm lave an asymptotic form as *O*(*max**x* * *log*(*max**y*) + *max**y* * *log*(*max**x*)).
+
+**Problem** **D.**
+
+Notice, that any point from the triangle based on first three points will be into the area bounded with the convex hull in the future. Let choose one of these points ad set it as the origin. All points of convex hull will keep in structure like map in C++, where the key is the angle of vector from the origin to a point. No two points from the hull will have the same angle.
+
+How to answer the second-type queries? For the point from the query (*A*) let's find the closest point clockwise (*B*) and the closest point anticlockwise (*C*). If the vectors *AB* and *AC* make up a clockwise rotation, then point A doesn't lay into the convex or on it's bounds.
+
+How to answer the first-type queries? If the point from the query (*C*) lays into the convex hull, then do nothing else let's find two closest points clockwise relative to point *C* (the closest will be named *A*, tho other will be named *B*). If rotation from the vector *AB* to the vector *AC* is a counterclockwise rotation then processing points laying clockwise relative to point *C* in ended, else you have to delete point *A* from the structure and repeat the same actions. The similar actions you should apply to points anticlockwise relative to point *C*.
+
+All points will be added and deleted in the structure not more than once. These operations need *O*(*log*(*h*)) time, where *h* is a number of point in convex hull. Total asymptotic form is *O*(*q* * *log*(*h*)).
+
+**Problem** **E.**
+
+Notice next facts. If we have the fixed state of some regional centers then for every city will be assigned the nearest regional center. The regional center of some city will be assigned for all cities between this city and it's regional center. It means that tree should be divided into some subtrees. Also define *d*[0] = 0.
+
+Let's solve the problem using "crossed" Dynamic Programming.
+
+First function of DP. D1(T, g, x, s) will be responsible for forming the subtree with the regional center g. T is somme subtree of tree from the input defined with edge *uv*. regional center g must be situated in T. Let's consider that *g* is assigned to *v*. The aim will be considered in choosing edges which will bound our subtree. Picture:
+
+
+
+Green and red edges connect cities which g was assigned. Purple edge bounds the set of such cities. Notice, that vertexes laying on the red pass cannot be bounding, because g is assigned to v.
+
+Let *xs* edge be bounding, then for subtree *T*' (vertexes of it's subtree are into the circle) call the secnod funtion of DP *D*2(*T*').
+
+The second function of DP will brute every point of subtree *T*' as a regional center and call D1.
+
+D1 have *O*(*n*3) states, because the number of subtrees *T* is *O*(*n*), number of options to choose g is the same and pair (x;s) makes up an edge, number of edges is 2*n-2. The second function of DP has *O*(*v*) states and transition need *O*(*v*) iterations. Thats why solution need *O*(*n*3) memory and have asymptotic form *O*(*n*3).
diff --git a/editorials/71.md b/editorials/71.md
@@ -0,0 +1,58 @@
+Source: https://codeforces.com/blog/entry/1624
+
+**A.** In this problem you can just do what is written in the statement. Let read all words. For each of them compute its length *L*, its the first and the last letter. If *L* > 10, output word without any changes, otherwise output the first letter, next *L* - 2 and finally the last letter.
+
+**B.** At first, compute . It equals ⌊ *mnk* / 100⌋, where ⌊ *x*⌋ is rounding down. Next we fill first ⌊ *z* / *k*⌋ squares with a saturation *k*. (⌊ *z* / *k*⌋ + 1)-th square (if it exists) we fill in a saturation *z* - ⌊ *z* / *k*⌋ *k*. All other squares we leave with a saturation 0.
+
+**C.** Define an *good* polygon as a regular polygon which has a knight in a good mood in every of its vertex. Side of polygon we will measure in arcs which is obtained by dividing border of round table with knights.
+
+Freeze the length of the side. Let this length equals *k*. Observe that the regular polygon with such length of side exists only if *k* divides *n*. We have exactly *k* of such polygons. Every of them has exactly *n* / *k* vertices. Check every of the polygons for goodness by review all of its vertices.
+
+If sum of vertices with knight in a good mood equals to *n* / *k*, this polygon is good. Checking of all polygons with some frozen length of side works in an *O*(*n*).
+
+Now observe that *n* has  of divisors. Really, all divisors (may be except only one) we can divide into pairs (for *i* corresponds *n* / *i*, for *i* = *n* / *i* there is no pair). One of divisors in every pair less than . It means thah number of pairs no more than  and number of divisors no more than .
+
+It gives solution - iterate over all divisors of *n* and for every of them check existence of good polygon with length side equals this divisor. Solution has an  time.
+
+In reality for big *n* is has  divisors. So solution actually has *O*(*n*4 / 3)-complexity. For all numbers less than 105 maximal number of divisors is 128.
+
+UPD. There was found an  solution by some participants. This solution uses following idea. If we have a good polygon with *xy* vertices, we also have a good polygon with *x* vertices. So we can check only prime divisors of *n* (except 2 - here we must check 4).
+
+**D.** This problem can be divided into some subproblems.
+ Author's solution means following ones:
+
+1. Check validness of square 3 × 3. Square is valid if all cards in it has equal suit or different rank. You may not check equal suit because equal suits imply different ranks.
+
+2. Find 2 valid noninetsect squares 3 × 3 or return thah there are no ones. You can check all pairs of squares for inetsection. If some pair has no intersections check them with solution of subproblem 1.
+
+3. Build set of cards which can be replaced with jokers. Generate full deck without jokers and drop from it all cards which in rectangle *n* × *m* are present.
+
+4. Find number of jokers and its positions in rectangle.
+
+5. Main subproblem. At first, solve subproblems 3 and 4. Now replace jokers in rectangle with cards from deck from subproblem 3 by all possible ways. For every replace solve subproblem 2. Arter all of variants of replacement just output answer.
+
+There are *O*(*n*2*m*2) solution with small constant.
+
+**E.** At first, you can use some search engine for find periodic table in some printable form. Next use copy-paste (one or several times) and format it by deleting all excess. It is mechanical work for no more than 5 minutes. Also some parser may be written. Note than author's solution does not mean write 100 symbols by hand from a picture. Next build some functions which transform symbols into numbers and vice versa.
+
+So, we have some set of numbers. We need summarize some from them and get some another set of numbers. We will use dymanic programming over subsets.
+
+Compute the first dp dp1[mask]->sum. For each subset calculate sum of numbers of all atoms in this subset. It can be done in *O*(2*n**n*).
+
+Now compute the second dp dp2[mask]->length. The "length" is a length of some prefix of result sequence of atoms which can be obtained by subset mask. If length -1, it means that it is impossible to get any prefix from this subset.
+
+The second dp we can calculate in *O*(3*n*). Iterate over all masks and if dp2[mask]!=-1, iterate all its subsets of remained atoms (invert mask and get all its submasks). If some subset has sum of numbers which equals number of (dp2[маска]+1)-th atom from result set, recalculate dp2[mask XOR submask]=dp2[mask]+1.
+
+At end, if dp2[2*n* - 1]=k, there are solution.
+
+There are *O*(3*n* + 2*n**n*) solution.
+
+In this problem some brutforce solutions are passed because it is difficult to pick up some counterexample.
+
+UPD. [SkorKNURE](../../../profile/SkorKNURE "Майор SkorKNURE") found a solution in *O*(2*n**n*). This solution is some modification of the author's solution.
+
+Instead of dp2 calculate dp dp2'[mask]->(i,j), where i is a length of prefix which mask covers and j is part of number of (i+1)-th atom which mask covers.
+
+Iterate over all masks. For each mask iterate over all its 0-bits (they are atoms which cover nothing from the finish set). We try to cover with this 0-bit a remainder of number of the (i+1)-th atom from the finish set. Let atomic number of an atom for current 0-bit is p and this atom is q-th in the start set. If we cover with this atom only part of the remainder of number of the (i+1)-th atom, dp2'[mask XOR (1<<q)]=(i,j+p). If we cover with this atom the remainder fully (and exactly this remainder, no more!), dp2'[mask XOR (1<<q)]=(i+1,0).
+
+Now dp1 is useless. If at end dp2'[2*n* - 1]=(k,0), solution exists (it is easy to restore it), otherwise there is no solution.
diff --git a/editorials/73.md b/editorials/73.md
@@ -0,0 +1,47 @@
+Source: https://codeforces.com/blog/entry/1700
+
+**Problem A.**
+
+Let’s call the monster dimension sizes as *x1, x2, x3*.
+
+1. *O(min(k, x1 + x2 + x3))* solution
+
+We can make at most *(x1 – 1) + (x2 – 1) + (x3 – 1)* cuttings, so we may assume that *k <= x1 + x2 + x3 – 3*. For each of the three dimensions we will store an integer *ai* – number of cuttings performed through the corresponding dimension. Let’s perform the following actions *k* times: consider all numbers *ai* which we may increase (*ai < xi - 1*) , call these dimensions “uncompleted”. Select the minimum number *aj* among all uncompleted *ai* and perform a cut through the corresponding dimension (*aj* will be increased by 1 as the result). Now let’s consider the resulting set after *k* actions: *{a1, a2, a3}*. Using the described algorithm we grant that the maximum element of this set is as little as possible and the minimum element is as big as possible. Because the sum *a1 + a2 + a3 = k* is fixed, we get the maximum product *(a1 + 1) * (a2 + 1) * (a3 + 1)* which is the answer for the problem.
+
+2. *O(1)* solution
+
+Instead of simulation all the *k* actions we may quickly determine values of numbers *ai* after using the algorithm described above.
+
+Let *x* – the smallest value among *(xi– 1)*. When *x * 3 >= k* on each of the algorithm iterations all three dimensions will be uncompleted. It means that during the first *(k / 3) * 3* steps each of numbers *ai* will be increased by *(k / 3)*. Then 0, 1 or 2 numbers *ai* will be increased by 1 subject to value of *k % 3*. So, we have found values *ai*.
+
+Otherwise (*x * 3 < k*) during the first *x * 3* steps each of *ai* will be increased by *x*. After that we will have at most two uncompleted dimensions which can be processed a similar way (we should choose the minimum value *x* among the remaining uncompleted dimensions).
+
+
+
+**Problem B.**
+
+We may assume that we have exactly *n* awarded places but some of them give 0 points.
+
+Let’s sort places by amount of points (*bi*) and racers by amount of currently gained points (*ai*). First let’s find the best place Vasya can reach. In the best case he will get *b0* points (where *b0* is the greatest number among *bi*). So, let the total Vasya’s point is *v*. Now we should to distribute other prize points to racers so that the number of racers better than Vasya will be minimal. For doing that we are to give maximum number of prizes so that corresponding racers will have less than *v* points. Note that if we can give *k* prizes keeping this property, than we can give *k* “cheapest” prizes too. The following statement is also true: if we can get a prize with *t* points to racer *i* and to racer *j* , *ai > aj*, then it is better to give this prize to racer *i*. Formally: if there exists a way to give *k* prizes where this prize will get racer *j*, than there exists a way to give *k* prizes where this prize will get racer *i*. It can be proven the following way. Consider a way to give *k* prizes where racer *j* got prize with *t* points, racer *i* – *s* points or didn’t get prize at all. In the first case we can swap prizes for racers *i* and *j*: *ai > aj* and *ai + s < v* (since racer *i* have got the prize), so *aj + s < v*, and *ai + t < v* i.e. this change is acceptable. In the second case we can just give the prize *t* to racer *i* instead of racer *j*. In the both cases we get a way to give *k* prizes where racer *i* receive prize *t*.
+
+Now including this statement we may give prizes to racers using the following greedy algorithm. Let’s begin to give prizes starting from the cheapest one and check the racers starting from the best one (of course excluding Vasya and the best prize). For each prize *i* we will go through the racers until applicable racer (*j*) found: *bi + aj < v*. If no such racers remain we are unable to give more prizes without violating the rule (racers should have less than *v* points). In this case we should stop the algorithm and the answer is *n – k* where *k* is the number of prizes we have given. If we have found such racer *j* we can give him prize *bi* and go to the next prize. Complexity of this step is *O(n)*.
+
+Similarly we can find the worst place for Vasya. For doing that we should give him the cheapest prize (note it may have positive points though). After that we should distribute the prizes iterating over prizes from the largest to cheapest and check racers from the worst to the best one trying to make sum of racer’s points more than *v*.
+
+Total complexity of the described algorithm is *O(n * log(n))* because we have to sort prizes and racers.
+
+
+
+**Problem C.**
+
+It is easy to see that if we put some symbol *c* at position *p* of the string *s* it will not affect symbols at positions (*p+2*) and greater. So we have a standard DP problem. State of the dynamic is described by three parameters: *p* – the number of already processed symbols (or the index of currently processed symbol of the string), *c* – the previous symbol, *t* – the number of allowed symbol changes. To calculate the answer for a state we should choose the best value among all symbols for current position (when *t > 0*) or just go to the index (*p + 1*) with current symbol *s[p]*. Thus we get the followings formulas:
+
+*d[n][*][*] = 0*
+
+*d[p][c][t] = d[p + 1][s[p]][t] + bonus[c][s[p]]*when*t = 0*
+
+*d[p][c][t] = max(d[p + 1][c’][t – (c’ <> s[p])] + bonus[c][c’])*
+
+where *n* is the length of string *s*.
+
+Computation complexity of the algorithm is *O(n * k * h^2)*, where *h* is the alphabet size (*h = 26* for current problem).
diff --git a/editorials/74.md b/editorials/74.md
@@ -0,0 +1,7 @@
+Source: https://codeforces.com/blog/entry/1735
+
+For problem C, I did a little explanation
+
+[Problem A](http://blog.vudduu.com/2011/04/codeforces-beta-round-68-problem.html) Room Leader (Sort, C++)
+
+[Problem C](http://blog.vudduu.com/2011/04/codeforces-beta-round-68-problem-c.html) Chessboard Billar (DFS, C++)
diff --git a/editorials/75.md b/editorials/75.md
@@ -0,0 +1,100 @@
+Source: https://codeforces.com/blog/entry/1715
+
+**Problem A:**
+In this problem you need to do what is written in the statement. You can do it in the following 3 steps:
+1- Calculate C.
+2- Remove all zeros from A, B and C.
+3- Check if the new values form a correct equation.
+
+[C++ solution for problem A.](http://pastebin.com/1cc1xKNW)
+
+
+**Problem B:**
+This problem is a direct simulation to the rules written in the problem statement.
+You need to iterate over all actions and parse each one to know the type of the action, and the 2 names X and Y, and if your name is X or Y then update your priority factor with this person with the action corresponding value. And take care about some special names like "post", "wall", "commented" and "on".
+Then sort all names according to the sorting criteria mentioned in the statement.
+Just make sure to print all names which are mentioned in the input (excluding yourself), even if the priority factor with you is 0.
+
+[C++ solution for problem B.](http://pastebin.com/cGHAv8qs)
+
+
+**Problem C:**
+In this problem you will need to generate all common divisors between a and b before answering any query.
+The first step in this problem is to factorize a and b, you can use the trial division technique which runs in O(sqrt(N)), you can check getFactors function in my solutions.
+Then using a recursive function you can generate all divisors for a and b from their prime factors, you can check getDivisors function in my solutions.
+Then intersect the 2 sets of divisors for both to get all common divisors, you can do this in O(N+M) where N and M are the lengths of the 2 sets, and also you can do a trivial O(N*M) intersection algorithm, because the maximum number of divisors is not too big (it's 1344).
+Now for each query you need to find the largest common divisor which lies in the given range, you can do this by sorting all common divisors and do binary search for the largest one which lies in the given range. Also you can do this using linear search, because the total number of queries is not too big.
+
+Also there is much shorter solution for this problem. Here is a hint for it, the GCD between a and b should be dividable by all common divisors of a and b.
+
+[C++ solution for problem C (with binary search).](http://pastebin.com/zcEGkKhw)
+[C++ solution for problem C (without binary search).](http://pastebin.com/Uw4rG7Ar)
+[Java solution for problem C (with binary search).](http://pastebin.com/Nd54H6em)
+
+
+**Problem D:**
+This problem is my favorite one in this problem set. Maybe it will be easier to solve this problem if you know how to solve the standard one.
+But because we can't construct the big array, so we can't apply the standard solution for this problem.
+Let's see first how to solve the standard problem, the following code solves it for a given array arr with length len:
+
+int mx = -(1 << 30);
+int sum = 0;
+for (int j = 0; j < len; j++) {
+ mx = max(mx, arr[i]); // we need this for the case where all elements in the array are negatives
+ sum += arr[i];
+ if (sum < 0)
+ sum = 0;
+ else
+ mx = max(mx, sum);
+}
+
+Now let's solve the big array problem, the first step is to calculate 4 values for each small array:
+1- The total sum of it, let's call it tot.
+2- The maximum sum of 0 or more consecutive elements starting from the first element in the array, let's call it lft.
+3- The maximum sum of 0 or more consecutive elements ending at the last element in the array, let's call it rght.
+4- The maximum sum of 1 or more consecutive elements, let's call it gen.
+
+The final result will be 1 of 2 cases:
+1- The consecutive elements with the maximum sum will start and end inside the same small array.
+2- The consecutive elements with the maximum sum will start and end inside different small arrays.
+
+For the first case, we can simply pick the maximum gen for all small arrays which exist in the big array.
+For the second case, we can apply something similar to the standard solution, we will keep a variable called sum, and it's initialized to 0, this will be the maximum sum of 0 or more consecutive elements ending at the last element in the previous small array. Now for each small array, if the maximum possible sum will end in this small array, so it will be sum+lft and maximize over this value (make sure this will be for 1 or more elements). And we need to update sum to be the maximum of the following 3 values:
+1- sum+tot (we will include all elements of this small array to the old sum).
+2- rght (we will take the maximum sum ending at the last element in the current small array).
+3- 0 (we will not take any elements in sum).
+
+The running time for this solution will be just for reading the input, in my solutions I have no iterations except for reading the input.
+
+You can check my solutions for more clarification.
+
+[C++ solution for problem D.](http://pastebin.com/bsxvF4aC)
+[Java solution for problem D.](http://pastebin.com/k1hzX5XD)
+
+
+**Problem E:**
+The main idea for this problem is not hard, but maybe the hard part is implementing it.
+First we need to know if the straight line segment between the source and destination points intersect with the island or not. So we will intersect this line segment with all the polygon sides. If there are 2 segments intersect in more than 1 point we will consider as they don't intersect, because it's mentioned in the problem statement that you can move on the island's edge and it will be considered in the sea.
+Now we have a set of all distinct intersection points of the polygon and the straight line segment between the source and destination points. Because the polygon is convex, this set will contain at most 2 points. We have 3 different cases now:
+1- This set contains less than 2 points.
+2- This set contains 2 points and they are on the same polygon side.
+3- This set contains 2 points and they are not on the same polygon side.
+
+In the first 2 cases the result will be simply the length of the straight line segment.
+In the 3rd case you can do the following:
+1- Move from the source point to the nearest point of the 2 intersection points.
+2- You have 3 options here:
+ a- Move inside the island to the other intersection point.
+ b- Move in clockwise direction on the island's edge to the other intersection point.
+ c- Move in anti-clockwise direction on the island's edge to the other intersection point.
+ First option will be considered moving inside the island, and the other 2 options will be considered moving in the sea.
+ You should pick the minimum one.
+3- Move from the 2nd intersection point to the destination point.
+
+Another solution:
+You can construct a graph where the nodes are the source point, the destination point, the intersection points and the polygon corner points. Then add an edge between any 2 points which you can move between them with the corresponding cost. Then run any shortest path algorithm, Floyd Warshall for example.
+
+You can check my solutions for more clarification.
+
+[C++ solution for problem E.](http://pastebin.com/7jgsu40r)
+[C++ solution for problem E (with Floyd Warshall).](http://pastebin.com/cZVCifwt)
diff --git a/editorials/76.md b/editorials/76.md
@@ -0,0 +1,120 @@
+Source: https://codeforces.com/blog/entry/1712
+
+The editorial is now completed.
+
+**Problem A: Gift (Roman Iedemskyi)**
+
+Suppose that the pair (*A*, *B*) is an optimal solution, where *A* is the number of gold coins in a gift and *B* is a number of silver coins. It is easy to see that there exist two (probably equal) indexes *i* and *j* such that *g**i* = *A* and *s**j* = *B*. It is true, because in the other case we could decrease either *A* or *B* without changing connectivity of the graph.
+
+Let *R*(*A*, *B*) be the graph in which for all *i* the following statement holds: 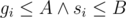.
+
+Let *T*(*A*) be the weighted graph in which for all edges *g**i* ≤ *A*. For each edge *i* we will assign a weight equal to *s**i*. Let's find a spanning tree of this graph, which has the property that its maximal edge is minimal possible. It can be shown that for the fixed *A* the minimal value of *B* for which graph *R*(*A*, *B*) is still connected is equal to the weight of the maximal edge in this spanning tree.
+
+*Claim*. Minimal spanning tree of a graph has the property that its maximal edge is minimal possible among all spanning trees.
+
+*Proof*. Let *L* be the minimal spanning tree of a graph. Suppose there exists a spanning tree *P* in which all edges have smaller weight than the weight of the maximal edge of *L*. We can then remove the maximal edge from *L* and add some edge from *P* to it which will connect the graph back. After that *L* will have strictly smaller weight, which is impossible because it is a minimal spanning tree.
+
+Let's sort all edges of the graph in ascending order of *g**i*. Then the edges of graph *T*(*A*) for the fixed *i* will be all edges with indexes *j* ≤ *i*.
+
+Suppose that for some value of *i* we have already found minimal spanning tree in every connected component of the graph *T*(*g**i*). Let's add an edge with index *i* + 1 into it. If it connects two different components, then after this operation they will be merged into one big component and it is obviously that the spanning tree we have in it is the minimal spanning tree. If *i* + 1-th edge connects two vertices from the same connected component, then it will create exactly one cycle in the graph. We can find the maximal edge in this cycle and remove it from the graph. It can be proven that the remaining tree will be the minimal spanning tree of this connected component.
+
+We can perform the search of the maximal edge in a cycle as well as the insertion and removal of the edges in O(N). The total complexity is *O*(*NM* + *MlogM*).
+
+**Problem B: Mice (Roman Rizvanov)**
+
+It is easy to see that the number of closest pieces of cheese for each mouse is not greater than 2.
+
+Let's find the closest pieces of cheese for each mouse to the left and to the right from it. From two directions we will choose the one which gives us shorter way to cheese or both of them if their lengths are equal. If on the chosen way between the mouse and the cheese stands another mouse, then we should exclude this way from consideration, because another mouse will get to the cheese faster. Now all the directions lead to cheese and for each piece of cheese there is at most one mouse which can potentially eat it from each direction.
+
+We will process mice from left to right. If the current mouse can move left and the cheese to the left of it is not chosen by any other mouse or it is chosen by a mouse with the same distance to it, then the current mouse can move to the left and eat this piece of cheese without interfering with other mice. This choice will not affect any choices of the next mice, because only one mouse can go to this piece of cheese from the right (see previous paragraph). Thus, this choice can not decrease the answer. In all other cases the current mouse can not increase the answer by moving left, so it should move to the right if it has such opportunity.
+
+The complexity is *O*(*N* + *M*).
+
+This problem can be also solved using dynamic programming.
+
+**Problem C: Mutation (Iaroslav Tverdokhlib)**
+
+In the editorial we will replace terms "risk", "genome" and "gene" with "cost", "string" and "character", respectively. Let *S* be the starting string.
+
+Let *M* be the bitmask of chars which will be removed. Let's iterate over all possible values of *M*. For the fixed *M* we need to find a cost of the string, which remained after removal of *M* and if this cost doesn't exceed *T* we will increase the answer by 1. Naive implementation of this idea has the complexity *O*(2*K**N*).
+
+We can not get rid of iterating over all *M*, so we will try to optimize a part of the algorithm which finds a cost of the remaining string.
+
+Let's take two indexes *l* and *r* from the beginning string *l* < *r*. Let *M*' be the bitmask of all characters which are located strictly between them. It is obviously that if  or  then *l* and *r* can not be neighbours in the remaining string. Hence for the fixed *l* there are not more than *K* possible candidates for *r*, which means that there are *O*(*NK*) pairs of such potential neighbours. We will call such pairs "good".
+
+We want to find out what form should have the set *M* that after its removal indexes *l* and *r* became adjacent. It is easy to see that the following two conditions should be true:
+
+1. 
+
+2. 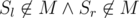
+
+Let's iterate over all good pairs of *l* and *r* and for each of them we will find the set *M*'. For each triple (*a*, *b*, *P*) we will store the sum of costs of neighborhood of all pairs *l* and *r* for which *S**l* = *a*, *S**r* = *b*, *M*' = *P*. After that for the fixed *M* we will iterate over all pairs of characters (*a*, *b*) and its subsets *P* and add all their costs together. Also we need to add the cost of removal of *M* and the resulting sum will be the cost of the string which will left after removal of *M*. The complexity of such solution is *O*(3*K* * *K*2 + *NK*).
+
+We will optimize the previous solution by decreasing a factor near 3*K*. Let's look at the following (incorrect) algorithm:
+
+We will iterate over all good pairs *l* and *r* and for each of them we will find *M*'. Let's create an array *v* in which for each mask *P* we will store the sum of costs of neighborhood of all pairs *l* and *r* for which *M*' = *P*. For the fixed *M* we will find a sum of all values from *v* for all submasks of *M*, then add the cost of removal of *M* to it and the resulting sum will be the cost of the remaining string.
+
+This algorithm is incorrect, because some costs of neighborhood are added to the total cost, but in fact the respective *l* or *r* are removed. Let's use inclusion-exclusion principle and make the following at the phase of filling array *v*:
+
+*v*[*M*'] + = *cost*
+
+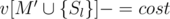
+
+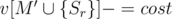
+
+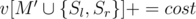
+
+With such filling of *v* the algorithm described above is correct and the total complexity becomes *O*(3*K* + *NK*).
+
+This is still not enough for the full solution, but we are almost there. We only need to find a fast way of finding the sum of the values of *v* for all submasks of all masks *M*. We will use the following iterative algorithm for this purpose:
+
+Before the first iteration we have an array *v* in which the starting values are stored. After iteration with number *i* in *v*[*mask*] we will store the sum of all the values from the original array *v* for all submasks of *mask* for which the first *K* - *i* bits are equal to the respective bits of *mask*. On iteration with number *i* for all masks in which the *i*-th bit is equal to 1 (bits are numbered from 1) we will perform the following: *v*[*mask*] + = *v*[*mask*\{*i*}]. It is easy to see that after the *K*-th iteration of this algorithm we will have the values we were looking for in array *v*.
+
+The complexity is *O*(2*K**K* + *NK*).
+
+**Problem D: Plus and XOR (Daniel Neiter)**
+
+Let's take a look at some bit in X, which is equal to 1. If the respective bit in Y is equal to 0, then we can swap these two bits, thus reducing X and increasing Y without changing their sum and xor. We can conclude that if some bit in X is equal to 1 then the respective bit in Y is also equal to 1. Thus, *Y* = *X* + *B*. Taking into account that *X* + *Y* = *X* + *X* + *B* = *A*, we can obtain the following formulas for finding *X* and *Y*:
+
+*X* = (*A* - *B*) / 2
+
+*Y* = *X* + *B*
+
+One should also notice that if *A* < *B* or *A* and *B* have different parity, then the answer doesn't exist and we should output -1. If *X* *and* (*A* - *X*) ≠ *X* then the answer is also -1.
+
+**Problem E: Points (Daniel Neiter)**
+
+Let's regroup summands and split the sum of squares of distances we are looking for into two sums:
+
+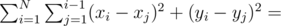
+
+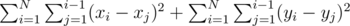
+
+Now we need to rewrite each of these sums in the following way (it will be shown for the first sum):
+
+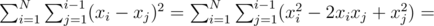
+
+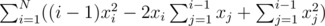
+
+This formula allows us to find an answer in one pass through the array. The complexity is O(N).
+
+**Problem F: Tourist (Ilya Porublyov)**
+
+We can get to the event *j* from the event *i* if the following statements are true:
+
+* *t**i* ≤ *t**j*
+* |*x**i* - *x**j*| ≤ |*t**i* - *t**j*|· *V*
+
+We can represent all the events as points on a plane with coordinates (*x**i*, *t**i*). Now we can reformulate the two statements written above in the following way:
+
+From the event *i* we can get to the event *j* if the point (*x**j*, *t**j*) lise inside an angle pointed to the top with its vertex in (*x**i*, *t**i*) and its sides form an angle *arctg*(*V*) with vertical axis. Let's make coordinate transformation according to which the point with coordinates (*x**i*, *t**i*) will transform into the point (*p**i*, *q**i*), where
+
+*p**i* = - *x**i* + *t**i* * *V*
+
+*q**i* = *x**i* + *t**i* * *V*
+
+Now we can get to the event *j* from the event *i* if *p**i* ≤ *p**j* и *q**i* ≤ *q**j*. Let's sort all points in ascending order of *p*. If several points have the same *p* we will sort them by *q*. The second subproblem of our problem can be solved by finding a longest increasing subsequence by *q* in this array. It can be done in *O*(*NlogN*).
+
+To solve the first subproblem we can add dummy event with coordinate 0 and time 0 (if it is not present in our set of events yet) and force tourist's start from it.
+
+The total complexity if *O*(*NlogN*).
diff --git a/editorials/77.md b/editorials/77.md
@@ -0,0 +1,39 @@
+Source: https://codeforces.com/blog/entry/1769
+
+My solution for this task.
+
+We need discriminant to be above zero, so we have:
+
+p - 4q >= 0
+
+p >= 4q
+
+What is probability? It's relation of needed events to all. In this case needed events are all pairs (p,q) where p >= 4q
+
+All events are all possible pairs (p,q)
+
+How we can count them?
+
+All possible pairs is Cartasian product. We can draw it like rectangle.
+
+Its area - number of all possible pairs.
+
+Also we need to find area of polygon, where p >= 4q.
+
+For this let's draw line y=4x and needed set of points is above this line.
+
+Our answer is relation between this area and area of whole rectangle.
+
+I think finding areas isn't problem.
+
+There is one case that I draw on second image, when 4b < a
+
+There are 2 cases - when a=0 and b=0
+
+When a=0 we have only left part of image, so answer is 0.5
+
+When b=0 we have vertical line, so answer is 1.0
+
+Sorry for some mistakes in English.
+
+
diff --git a/editorials/78.md b/editorials/78.md
@@ -0,0 +1,49 @@
+Source: https://codeforces.com/blog/entry/1812
+
+**A.** You should count a number of vowels for every of three phrases. Next, you should compare this numbers with numbers 5, 7 and 5. If all is matched, answer is YES, otherwise answer is NO.
+
+Author of problem is [Ripatti](../../../profile/Ripatti "Майор Ripatti").
+
+
+**B.** At first, you can [*n* / 7] times output string "ROYGBIV" ([] is a rounding down). After than you can output "", "G", "GB", "YGB", "YGBI", "OYGBI" or "OYGBIV" according to remainder of division *n* by 7. A resulting string will satisfy problem's requirements.
+
+You can also build answer in other way.
+
+Author of problem is [Ripatti](../../../profile/Ripatti "Майор Ripatti").
+
+
+**C.** If *n* is even, Marsel wins - he just symmetrically repeats moves of Timur.
+
+Now consider a case of odd *n*. If Timur cannot move - he is losing automatically. If he can do a move, he always can split one log into few parts that this parts cannot be splitted again. It can be done if we have find minimal *t* that *k* ≤ *t* < *m* and *t*|*m*. Next we split log into parts with length *t*. Thereafter Timur symmetrically repeats moves of Marsel and wins.
+
+For checking that Timur could move or not, you can iterate over all divisors of *m*. If there is exists some divisor *t* that *k* ≤ *t* < *m*, Timar can do a move. Chech of all divisors can be done in  time.
+
+Author of problem is [Lepetrandr](../../../profile/Lepetrandr "Майор Lepetrandr").
+
+
+**D.** It should be solved like a classical problem "count the number of square cells 1x1 lying inside the circle". Firstly, lets find the highest hexagon that lies inside the circle. Then we move to the right and up from this hexagon, and then go down until we find hexagon lying inside the circle. Repeat this process until you reach the rightmost part of the circle.
+
+Thus we can count number of hexagons in each column, answer is sum of this numbers. Total number of operations is *O*(*n*).
+
+Few words about implementation. Coordinates of every considered point looks like . That's why distance between this points and (0,0) should be calculated using integers only. For example, criteria "point  lies inside circle of radius *R*" looks like *x*2 + 3*y*2 ≤ 4*R*2.
+
+Also you can solve this problem in . For every column of hexagons you can find number of hexagons inside circle by using binary search.
+
+Author of problem is [Ripatti](../../../profile/Ripatti "Майор Ripatti").
+
+
+**E.** Firstly, let's calculate the following value:
+dp[t][x0][y0][x][y] == true iff scientist from block (x0,y0) can reach block (x,y) in time t, considering toxic coolant.
+
+Secondly, let's consider a graph consisting of 4 parts:
+1 - source (one vertex)
+2 - first fraction (nxn vertices)
+3 - second fraction (nxn vertices)
+4 - sink (one vertex)
+Each vertex of each fraction is for one block. Build edge from source to each vertex of the first fraction with capability as number of scientists in corresponding block. Build edge from each vertex of the second fraction to sink with capability as number of rescue capsules in corresponding block. Build edge from vertex (x0,y0) of the first fraction to vertex (x,y) of the second fraction iff dp[T][x0][y0][x][y]==true for at least one T. Capability of this edges is infinity.
+
+As one can see, value of maxflow in this graph is answer for the problem.
+
+Complexity of this solution is *O*(*tn*4 + *kn*6), where *k* is maximum possible number of scientists in each block(in this problem *k* = 9).
+
+Author of problem is [Ripatti](../../../profile/Ripatti "Майор Ripatti").
