
757.md (40750B)
1 Source: https://codeforces.com/blog/entry/49743 2 3 ## [757A — Gotta Catch Em' All!](//www.codeforces.com/contest/757/problem/A) 4 5 **Author:** [Baba](/profile/Baba "Candidate Master Baba") 6 **Testers:** [virus_1010](/profile/virus_1010 "Specialist virus_1010") [born2rule](/profile/born2rule "Specialist born2rule") 7 8 **Expected complexity**:  9 **Main idea**: Maintain counts of required characters. 10 11 Since we are allowed to permute the string in any order to find the maximum occurences of the string "Bulbasaur", we simply keep the count of the letters 'B', 'u', 'l', 'b', 'a', 's', 'r'. Now the string "Bulbasaur" contains 1 'B', 2'u', 1 'l', 2'a', 1 's', 1'r' and 1 'b', thus the answer to the problem is Min(count('B'), count('b'), count('s'), count('r'), count('l'), count('a')/2, count('u')/2). You can maintain the counts using an array. 12 13 **Corner Cases:** 14 1. Neglecting 'B' and while calculating the answer considering count('b')/2. 15 2. Considering a letter more than once ( 'a' and 'u' ). 16 17 **Tester's code:** 18 19 ``` 20 #include <bits/stdc++.h> 21 using namespace std; 22 23 int main() 24 { 25 map<char, int> m; 26 string s; 27 cin>>s; 28 for(auto x : s) 29 m[x]++; 30 31 int ans = m['B']; 32 ans = min(ans, m['u']/2); 33 ans = min(ans, m['a']/2); 34 ans = min(ans, m['b']); 35 ans = min(ans, m['s']); 36 ans = min(ans, m['r']); 37 ans = min(ans, m['l']); 38 cout << ans << endl; 39 return 0; 40 } 41 ``` 42 43 ## [757B — Bash's Big Day](//www.codeforces.com/contest/757/problem/B) 44 45 **Author**: [architrai](/profile/architrai "Expert architrai") 46 **Testers**: [mprocks](/profile/mprocks "Expert mprocks"), [deepanshugarg](/profile/deepanshugarg "Expert deepanshugarg") 47 48 **Expected complexity**:  49 **Main idea**: Square-root factorization and keeping count of prime factors. 50 51 The problem can be simplified to finding a group of Pokemons such that their strengths have a common factor other that 1. We can do this by marking just the prime factors, and the answer will be the maximum count of a prime factor occurring some number of times. The prime numbers of each number can be found out using pre-computed sieve or square-root factorization. 52 53 Corner Cases : Since a Pokemon cannot fight with itself (as mentioned in the note), the minimum answer is 1. Thus, even in cases where every subset of the input has gcd equal to 1, the answer will be 1. 54 55 **Tester's code:** 56 57 ``` 58 #include<bits/stdc++.h> 59 using namespace std; 60 int N; 61 unordered_map<int, int> factors; 62 int main() 63 { 64 ios_base::sync_with_stdio(false); 65 cin >> N; 66 67 while(N--) 68 { 69 int strength; 70 cin >> strength; 71 72 int root = sqrt(strength); 73 for(int i = 2; i <= root; i++) 74 { 75 if(strength%i == 0) 76 factors[i]++; 77 78 while(strength%i == 79 0) strength 80 /= i; 81 } 82 83 if(strength > 1) factors[strength]++; 84 } 85 86 int ans = 1; 87 for(auto it = factors.begin(); it != factors.end(); it++) 88 { 89 ans = max(ans, (*it).second); 90 } 91 92 cout << ans << endl; 93 94 return 0; 95 } 96 ``` 97 98 ## [757C — Felicity is Coming!](//www.codeforces.com/contest/757/problem/C) 99 100 **Author:** [shivamkakkar](/profile/shivamkakkar "Candidate Master shivamkakkar") 101 **Testers:** [codelegend](/profile/codelegend "Candidate Master codelegend") 102 103 **Expected complexity**:  104 **Main idea**: Divide pokemon types into equivalence classes based on their counts in each list. 105 106 Consider a valid evolution plan *f*. Let *c*[*p*, *g*] be the number of times Pokemon *p* appears in gym *g*. If *f*(*p*) = *q* then . 107 108 Now consider a group of Pokemon *P* such that all of them occur equal number of times in each gym (i.e. for each ). Any permutation of this group would be a valid bijection. 109 110 Say we have groups *s*1, *s*2, *s*3, ..., then the answer would be |*s*1|! |*s*2|! |*s*3|! ... *mod* 109 + 7. 111 112 For implementing groups, we can use *vector* < *vector* < *int* > > and for *i*-th pokemon, add the index of the gym to *i*-th vector. 113 114 Now we need to find which of these vectors are equal. If we have the sorted *vector* < *vector* < *int* > > , we can find equal elements by iterating over it and comparing adjacent elements. 115 116 Consider the merge step of merge sort. For a comparison between 2 vectors *v*1 and *v*2, we cover at least *min*(*v*1.*size*(), *v*2.*size*()) elements. Hence  work is done at each level. There are  levels. 117 118 Bonus : Try proving the time complexity for quicksort as well. 119 120 **Authors's code:** 121 122 ``` 123 #include<bits/stdc++.h> 124 125 using namespace std; 126 127 typedef long long LL; 128 129 #define PB push_back 130 #define ALL(X) X.begin(), X.end() 131 132 #define fast_io ios_base::sync_with_stdio(false);cin.tie(NULL) 133 134 const int N = 1e6; 135 const LL MOD = 1e9 + 7; 136 LL fact[N+1]; 137 int main() 138 { 139 fast_io; 140 fact[0] = fact[1] = 1; 141 for(LL i=2;i<=N;i++) 142 fact[i] = (fact[i-1]*i)%MOD; 143 int n,m; 144 cin >> n >> m; 145 vector< vector<int> > x(m); 146 for(int i=0;i<n;i++) { 147 int s; 148 cin >> s; 149 for(int j=0;j<s;j++) { 150 int t; 151 cin >> t; 152 x[t-1].PB(i); 153 } 154 } 155 for(int i=0;i<m;i++) 156 sort(ALL(x[i])); 157 sort(ALL(x)); 158 LL ans = 1; 159 LL sm = 1; 160 for(int i=1;i<m;i++) { 161 if(x[i]==x[i-1]) 162 sm++; 163 else 164 ans = (ans*fact[sm])%MOD, sm = 1; 165 } 166 ans = (ans*fact[sm])%MOD; 167 cout << ans << endl; 168 return 0; 169 } 170 ``` 171 172 ## [757D — Felicity's Big Secret Revealed](//www.codeforces.com/contest/757/problem/D) 173 174 **Author:** [saatwik27](/profile/saatwik27 "Expert saatwik27") 175 **Testers:** [imamit](/profile/imamit "Candidate Master imamit"),[abhinavaggarwal](/profile/abhinavaggarwal "Expert abhinavaggarwal"),[Chipe1](/profile/Chipe1 "Candidate Master Chipe1") 176 177 **Expected complexity**:  178 **Main idea**: DP with Bitmask. 179 180 This problem can be solved using Dynamic Programming with bitmask. 181 182 The important thing to note here is that the set of distinct numbers formed will be a maximum of 20 numbers, i.e. from 1 to 20, else it won't fit 75 bits(1*(1 bits) + 2*(2 bits) + 4*(3 bits) + 8*(4 bits) + 5*(5 bits) = 74 bits). So, we can use a bitmask to denote a set of numbers that are included in a set of cuts. 183 184 Let's see a Top-Down approach to solve it : 185 186 Lets define the function *f*(*i*, *mask*) as : *f*(*i*, *mask*) denotes the number of sets of valid cuts that can be obtained from the state *i*, *mask*. The state formation is defined below. 187 188 Let *M* be the maximum number among the numbers in *mask*. *mask* denotes a set of numbers that have been generated using some number of cuts, all of them before *b**i*. Out of these cuts, the last cut has been placed just before *b**i*. Now, first we check if the set of cuts obtained from *mask* is valid or not(in order for a mask to be valid, mask == 2*X* - 1 where *X* denotes number of set bits in the mask) and increment the answer accordingly if the mask is valid. And then we also have the option of adding another cut. We can add the next cut just before *b**x* provided the number formed by "*b**i* *b**i* + 1...*b**x* - 1" <= 20. Set the corresponding bit for this number formed to 1 in the *mask* to obtain *newMask* and recursively find *f*(*x*, *newMask*). 189 190 **Author's code:** 191 192 ``` 193 // Saatwik Singh Nagpal 194 195 #include <bits/stdc++.h> 196 using namespace std; 197 198 #define TRACE 199 #ifdef TRACE 200 #define TR(...) __f(#__VA_ARGS__, __VA_ARGS__) 201 template <typename Arg1> 202 void __f(const char* name, Arg1&& arg1){ 203 cerr << name << " : " << arg1 << std::endl; 204 } 205 template <typename Arg1, typename... Args> 206 void __f(const char* names, Arg1&& arg1, Args&&... args){ 207 const char* comma = strchr(names + 1, ',');cerr.write(names, comma - names) << " : " << arg1<<" | ";__f(comma+1, args...); 208 } 209 #else 210 #define TR(...) 211 #endif 212 213 typedef long long LL; 214 typedef vector < int > VI; 215 typedef pair < int,int > II; 216 typedef vector < II > VII; 217 218 #define MOD 1000000007 219 #define EPS 1e-12 220 #define N 200100 221 #define PB push_back 222 #define MP make_pair 223 #define F first 224 #define S second 225 #define ALL(v) v.begin(),v.end() 226 #define SZ(a) (int)a.size() 227 #define FILL(a,b) memset(a,b,sizeof(a)) 228 #define SI(n) scanf("%d",&n) 229 #define SLL(n) scanf("%lld",&n) 230 #define PLLN(n) printf("%lld\n",n) 231 #define PIN(n) printf("%d\n",n) 232 #define REP(i,j,n) for(LL i=j;i<n;i++) 233 #define PER(i,j,n) for(LL i=n-1;i>=j;i--) 234 #define endl '\n' 235 #define fast_io ios_base::sync_with_stdio(false);cin.tie(NULL) 236 237 #define FILEIO(name) \ 238 freopen(name".in", "r", stdin); \ 239 freopen(name".out", "w", stdout); 240 241 inline int mult(int a , int b) { LL x = a; x *= LL(b); if(x >= MOD) x %= MOD; return x; } 242 inline int add(int a , int b) { return a + b >= MOD ? a + b - MOD : a + b; } 243 inline int sub(int a , int b) { return a - b < 0 ? MOD - b + a : a - b; } 244 LL powmod(LL a,LL b) { if(b==0)return 1; LL x=powmod(a,b/2); LL y=(x*x)%MOD; if(b%2) return (a*y)%MOD; return y%MOD; } 245 246 int dp[1<<20][77]; 247 int b[77] , n; 248 int go(int mask , int i) { 249 int cnt = __builtin_popcount(mask); 250 if(i == n) { 251 if(cnt != 0 && (1<<cnt)-1 == mask) 252 return 1; 253 return 0; 254 } 255 if(dp[mask][i] != -1) return dp[mask][i]; 256 257 int ret = 0; 258 if(b[i] == 0) 259 ret = go(mask , i+1); 260 else { 261 int num = 0; 262 int j = i; 263 while(1) { 264 num *= 2; 265 num += b[j]; 266 if(num > 20) break; 267 //if(!(mask & (1<<(num-1)))) 268 ret = add(ret , go(mask | (1<<(num-1)) , j+1)); 269 j ++; 270 if(j == n) break; 271 } 272 if(cnt != 0 && mask == (1<<cnt)-1) 273 ret ++; 274 } 275 return dp[mask][i] = ret; 276 } 277 278 int main() { 279 FILL(dp,-1); 280 cin >> n; 281 string s; cin >> s; 282 REP(i,0,n) 283 b[i] = s[i] - '0'; 284 int ans = 0; 285 REP(i,0,n) 286 ans = add(ans , go(0,i)); 287 PIN(ans); 288 return 0; 289 } 290 ``` 291 292 ## [757E — Bash Plays with Functions](//codeforces.com/contest/757/problem/E) 293 294 **Author**: [satyam.pandey](/profile/satyam.pandey "Expert satyam.pandey") 295 **Testers**: [Superty](/profile/Superty "Candidate Master Superty"),[vmrajas](/profile/vmrajas "Candidate Master vmrajas") 296 297 **Expected complexity**:  298 **Main idea**: Multiplicative Functions. 299 300 We can easily see that *f*0 = 2(*number* *of* *distinct* *prime* *factors* *of* *n*). We can also see that it is a **multiplicative function**. 301 302 We can also simplify the definition of *f**r* + 1 as: 303 304  305 306 Since *f*0 is a multiplicative function, *f**r* + 1 is also a multiplicative function. (by property of multiplicative functions) 307 308 For each query, factorize *n*. 309 310 Now, since *f**r* is a multiplicative function, if *n* can be written as: 311 312 *n* = *p*1*e*1*p*2*e*2 ... *p**q**e**q* 313 314 Then *f**r*(*n*) can be computed as: 315 316 *f**r*(*n*) = *f**r*(*p*1*e*1) * *f**r*(*p*2*e*2) * ... * *f**r*(*p**q**e**q*) 317 318 Now observe that the value of *f**r*(*p**n*) is independent of *p*, as *f*0(*p**n*) = 2. It is dependent only on *n*. So we calculate *f**r*(2*x*) for all r and x using a simple *R* * 20 DP as follows: 319 320  321 322 And now we can quickly compute *f**r*(*n*) for each query as: 323 324 *f**r*(*n*) = *dp*[*r*][*e*1] * *dp*[*r*][*e*2] * ... * *dp*[*r*][*e**q*] 325 326 **Author's code:** 327 328 ``` 329 //Kyokai no Kanata // 330 //Written by Satyam Pandey// 331 #include<bits/stdc++.h> 332 333 using namespace std; 334 335 typedef pair<int,int> II; 336 typedef vector<II> VII; 337 typedef vector<int> VI; 338 typedef vector< VI > VVI; 339 typedef long long int LL; 340 341 #define PB push_back 342 #define MP make_pair 343 #define F first 344 #define S second 345 #define SZ(a) (int)(a.size()) 346 #define ALL(a) a.begin(),a.end() 347 #define SET(a,b) memset(a,b,sizeof(a)) 348 349 #define si(n) scanf("%d",&n) 350 #define dout(n) printf("%d\n",n) 351 #define sll(n) scanf("%lld",&n) 352 #define lldout(n) printf("%lld\n",n) 353 #define fast_io ios_base::sync_with_stdio(false);cin.tie(NULL) 354 #define TRACE 355 356 #ifdef TRACE 357 #define trace(...) __f(#__VA_ARGS__, __VA_ARGS__) 358 template <typename Arg1> 359 void __f(const char* name, Arg1&& arg1){ 360 cerr<<name<<" : "<<arg1<<endl; 361 } 362 template <typename Arg1, typename... Args> 363 void __f(const char* names,Arg1&& arg1,Args&&... args){ 364 const char* comma=strchr(names+1,','); 365 cerr.write(names,comma-names)<<" : "<<arg1<<" | ";__f(comma+1,args...); 366 } 367 #else 368 #define trace(...) 369 #endif 370 float inf=std::numeric_limits<double>::infinity(); 371 LL INF=std::numeric_limits<LL>::max(); 372 //FILE *fin = freopen("in","r",stdin); 373 //FILE *fout = freopen("out","w",stdout); 374 const int R=int(1e6)+5,P=25,N=R,mod = int(1e9)+7; 375 int F[R][P],LP[N]; 376 inline void seive(){ 377 LP[1]=1; 378 for(int i=2;i<N;i++){ 379 if(!LP[i]) 380 for(int j=i;j<N;j+=i) 381 LP[j]=i; 382 } 383 } 384 inline void precalc() 385 { 386 for(int i=0;i<R;i++) F[i][0] = 1; 387 for(int i=1;i<P;i++) F[0][i] = 2; 388 for(int i=1;i<R;i++) 389 for(int j=1;j<P;j++) 390 F[i][j] = (F[i][j-1] + F[i-1][j])%mod; 391 } 392 inline LL solve(int r,int n) 393 { 394 LL ans=1; 395 while(n!=1) 396 { 397 int cnt=0,p=LP[n]; 398 while(n%p==0) n/=p,cnt++; 399 ans=(ans*F[r][cnt])%mod; 400 } 401 return ans; 402 } 403 int main() 404 { 405 seive();precalc(); 406 int q;si(q); 407 int r,n; 408 while(q--) 409 { 410 si(r);si(n); 411 lldout(solve(r,n)); 412 } 413 return 0; 414 } 415 ``` 416 417 ## [757F — Team Rocket Rises Again](//www.codeforces.com/contest/757/problem/F) 418 419 **Author**: [Baba](/profile/Baba "Candidate Master Baba") 420 **Testers**: [shubhamvijay](/profile/shubhamvijay "Expert shubhamvijay"), [tanmayc25](/profile/tanmayc25 "Expert tanmayc25"), [vmrajas](/profile/vmrajas "Candidate Master vmrajas") 421 422 **Expected complexity**:  423 **Main idea**: Building Dominator tree on shortest path DAG. 424 425 First of all, we run Dijkstra's shortest path algorithm from *s* as the source vertex and construct the shortest path DAG of the given graph. Note that in the shortest path DAG, the length of any path from *s* to any other node *x* is equal to the length of the shortest path from *s* to *x* in the given graph. 426 427 Now, let us analyze what the function *f*(*s*, *x*) means. It will be equal to the number of nodes *u* such that every path from *s* to *u* passes through node *x* in the shortest path DAG, such that on removing node *x* from the DAG, there will be no path from *s* to *u*. 428 429 In other words, we want to find the number of nodes *u* that are dominated by node *x* considering *s* as the sources vertex in the shortest path DAG. This can be calculated by building dominator tree of the shortest path DAG considering *s* as the source vertex. 430 A node *u* is said to dominate a node *w* wrt source vertex *s* if all the paths from *s* to *w* in the graph must pass through node *u*. 431 You can read more about dominator tree [here](https://tanujkhattar.wordpress.com/2016/01/11/dominator-tree-of-a-directed-graph/). 432 433 Once the dominator tree is formed, the answer for any node *x* is equal to the number of nodes in the subtree of *x* in the tree formed. 434 435 **Author's code:** 436 437 ``` 438 //Tanuj Khattar 439 #include<bits/stdc++.h> 440 441 using namespace std; 442 443 typedef pair<int,int> II; 444 typedef vector< II > VII; 445 typedef vector<int> VI; 446 typedef vector< VI > VVI; 447 typedef long long int LL; 448 449 #define PB push_back 450 #define MP make_pair 451 #define F first 452 #define S second 453 #define SZ(a) (int)(a.size()) 454 #define ALL(a) a.begin(),a.end() 455 #define SET(a,b) memset(a,b,sizeof(a)) 456 457 #define si(n) scanf("%d",&n) 458 #define dout(n) printf("%d\n",n) 459 #define sll(n) scanf("%lld",&n) 460 #define lldout(n) printf("%lld\n",n) 461 #define fast_io ios_base::sync_with_stdio(false);cin.tie(NULL) 462 463 #define TRACE 464 465 #ifdef TRACE 466 #define trace(...) __f(#__VA_ARGS__, __VA_ARGS__) 467 template <typename Arg1> 468 void __f(const char* name, Arg1&& arg1){ 469 cerr << name << " : " << arg1 << std::endl; 470 } 471 template <typename Arg1, typename... Args> 472 void __f(const char* names, Arg1&& arg1, Args&&... args){ 473 const char* comma = strchr(names + 1, ',');cerr.write(names, comma - names) << " : " << arg1<<" | ";__f(comma+1, args...); 474 } 475 #else 476 #define trace(...) 477 #endif 478 479 //FILE *fin = freopen("in","r",stdin); 480 //FILE *fout = freopen("out","w",stdout); 481 const int N = int(1e5)+10; 482 const int M = int(2e5)+10; 483 const LL INF = LL(1e16); 484 namespace Dominator{ 485 VI g[N],tree[N],rg[N],bucket[N]; 486 int sdom[N],par[N],dom[N],dsu[N],label[N]; 487 int arr[N],rev[N],T;//1-Based directed graph input 488 int Find(int u,int x=0){ 489 if(u==dsu[u])return x?-1:u; 490 int v = Find(dsu[u],x+1); 491 if(v<0)return u; 492 if(sdom[label[dsu[u]]]<sdom[label[u]]) 493 label[u] = label[dsu[u]]; 494 dsu[u] = v; 495 return x?v:label[u]; 496 } 497 void Union(int u,int v){ //Add an edge u-->v 498 dsu[v]=u; //yup,its correct :) 499 } 500 void dfs0(int u){ 501 T++;arr[u]=T;rev[T]=u; 502 label[T]=T;sdom[T]=T;dsu[T]=T; 503 for(int i=0;i<SZ(g[u]);i++){ 504 int w = g[u][i]; 505 if(!arr[w])dfs0(w),par[arr[w]]=arr[u]; 506 rg[arr[w]].PB(arr[u]); 507 } 508 } 509 void dfs1(int u,int p,int sub[]){ 510 sub[u]=1; 511 for(auto w:tree[u]) 512 if(w!=p) 513 dfs1(w,u,sub),sub[u]+=sub[w]; 514 } 515 void reset(int n){ 516 for(int i=1;i<=n;i++){ 517 g[i].clear();rg[i].clear();tree[i].clear();arr[i]=0; 518 } 519 T=0; 520 } 521 void addEdge(int u,int v){ 522 g[u].PB(v); 523 } 524 //Build Dominator tree(in main) 525 void get(int n,int root,int sub[]){ 526 dfs0(root);n=T; 527 for(int i=n;i>=1;i--){ 528 for(int j=0;j<SZ(rg[i]);j++) 529 sdom[i] = min(sdom[i],sdom[Find(rg[i][j])]); 530 if(i>1)bucket[sdom[i]].PB(i); 531 for(int j=0;j<SZ(bucket[i]);j++){ 532 int w = bucket[i][j],v = Find(w); 533 if(sdom[v]==sdom[w])dom[w]=sdom[w]; 534 else dom[w] = v; 535 }if(i>1)Union(par[i],i); 536 } 537 for(int i=2;i<=n;i++){ 538 if(dom[i]!=sdom[i])dom[i]=dom[dom[i]]; 539 tree[rev[i]].PB(rev[dom[i]]); 540 tree[rev[dom[i]]].PB(rev[i]); 541 } 542 dfs1(rev[1],rev[1],sub); 543 }//done :) 544 } 545 int n,m,s,vis[N],sub[N]; 546 VII g[N];VI P[N]; 547 LL d[N]; 548 int dijkstra(int root){ 549 for(int i=1;i<=n;i++)d[i]=INF,P[i].clear(); 550 Dominator::reset(n);d[root]=0;SET(vis,0); 551 set<pair<LL,int>> S;S.insert({d[root],root}); 552 while(!S.empty()){ 553 int u = S.begin()->S; 554 S.erase(S.begin()); 555 if(vis[u])continue; 556 vis[u]=1; 557 for(auto w:g[u]) 558 if(d[u] + w.S < d[w.F]){ 559 d[w.F] = d[u] + w.S; 560 P[w.F].clear();P[w.F].PB(u); 561 S.insert({d[w.F],w.F}); 562 } 563 else if(d[u]+w.S==d[w.F]) 564 P[w.F].PB(u); 565 } 566 for(int i=1;i<=n;i++) 567 for(auto j : P[i]) 568 Dominator::addEdge(j,i); 569 Dominator::get(n,root,sub); 570 int mx = 0; 571 for(int i=1;i<=n;i++) 572 if(i!=root) 573 mx = max(mx,sub[i]); 574 return mx; 575 } 576 int main() 577 { 578 si(n);si(m);si(s); 579 for(int i=1;i<=m;i++){ 580 int u,v,w; 581 si(u);si(v);si(w); 582 g[u].PB({v,w}); 583 g[v].PB({u,w}); 584 } 585 dout(dijkstra(s)); 586 return 0; 587 } 588 ``` 589 590 Another approach for forming dominator tree is by observing that the shortest path directed graph formed is a DAG i.e. acyclic. So suppose we process the nodes of the shortest path dag in topological order and have a dominator tree of all nodes from which we can reach *x* already formed. Now, for the node *x*, we look at all the parents *p* of *x* in the DAG, and compute their LCA in the dominator tree built till now. We can now attach the node *x* as a child of the LCA in the tree. 591 For more details on this approach you can look at [EvenImage](/profile/EvenImage "Legendary Grandmaster EvenImage")'s solution [here](//codeforces.com/contest/757/submission/23761400). 592 593 ## [757G — Can Bash Save the Day?](//www.codeforces.com/contest/757/problem/G) 594 595 **Author**: [Baba](/profile/Baba "Candidate Master Baba") 596 **Testers**: [Toshad](/profile/Toshad "Candidate Master Toshad"), [abhinavaggarwal](/profile/abhinavaggarwal "Expert abhinavaggarwal") 597 598 **Expected complexity**:  599 **Main idea**: Making the Centroid Tree Persistent. 600 601 ### Simpler Problem 602 603 First let's try to solve a much simpler problem given as follows. 604 605 **Question:** Given a weighted tree, initially all the nodes of the given tree are inactive. We need to support the following operations fast : 606 *Query* *v* : Report the sum of distances of all active nodes from node *v* in the given tree. 607 *Activate* *v* : Mark node *v* to be an active node. 608 609 **Solution:** The above problem can be easily solved by a fairly standard technique called Centroid Decomposition. You can read more about [here](https://tanujkhattar.wordpress.com/2016/01/10/centroid-decomposition-of-a-tree/) 610 611 ### Solution Idea 612 613 * Each query of the form (*L* *R* *v*) can be divided into two queries of form (1 *R* *v*) - (1 *L* - 1 *v*). Hence it is sufficient if we can support the following query: (*i* *v*) : Report the answer to query (1 *i* *v*) 614 * To answer a single query of the form (*i* *v*) we can think of it as what is the sum of distance of all active nodes from node *v*, if we consider the first *i* nodes to be active. 615 * Hence initially if we can preprocess the tree such that we activate nodes from 1 to *n* and after each update, store a copy of the centroid tree, then for each query (*i* *v*) we can lookup the centroid tree corresponding to *i*, which would have the first *i* nodes activated, and query for node *v* in  time by looking at it’s ancestors. 616 * To store a copy of the centroid tree for each *i*, we need to make it persistent. 617 618 ### Persistent Centroid Tree : Key Ideas 619 620 * Important thing to note is that single update in the centroid tree affects only the ancestors of the node in the tree. 621 * Since height of the centroid tree is , each update affects only  other nodes in the centroid tree. 622 * The idea is very similar to that of a persistent segment tree **BUT** unlike segtree, here each node of the centroid tree can have arbitrarily many children and hence simply creating a new copy of the affected nodes would not work because linking them to the children of old copy would take 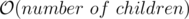 for each affected node and this number could be as large as *N*, hence it could take  time in total ! 623 624 ### Binarizing the Input Tree 625 626 * To overcome the issue, we convert the given tree *T* into an equivalent binary tree *T*' by adding extra dummy nodes such that degree of each node in the transformed tree *T*' is < = 3, and the number of dummy nodes added is bounded by . 627 * The dummy nodes are added such that the structure of the tree is preserved and weights of the edges added are set to 0. 628 * To do this, consider a node *x* with degree *d* > 3 and let *c*1, *c*2...*c**d* be it's adjacent nodes. Add a new node *y* and change the edges as follows : 629 + Delete the edges (*x* - *c*3), (*x* - *c*4) ... (*x* - *c**d*) and add the edge (*x* - *y*) such that degree of node *x* reduces to 3 from *d*. 630 + Add edges (*y* - *c*3), (*y* - *c*4) ... (*y* - *c**d*) such that degree of node *y* is *d* - 1. Recursively call the procedure on node *y*. 631 * Since degree of node *y* is *d* - 1 instead of original degree *d* of node *x*, it can be proved that we need to add at most  new nodes before degree of each node in the tree is < = 3. 632 633 ### Conclusion 634 635 Hence we perform centroid decomposition of this transformed tree *T*'. The centroid tree formed would have the following properties. 636 637 * The height of the centroid tree is  638 * Each node in the centroid tree has ≤ 3 children. 639 640 Now we can easily make this tree persistent by path-copying approach. 641 To handle the updates, 642 643 * **Way-1 :** Observe that swapping *A*[*i*] and *A*[*i* + 1] would affect only the *i*'*th* persistent centroid tree, which can be rebuilt from the tree of *i* - 1 by a single update query. In this approach, for each update we add  new nodes. See author's code below for more details. 644 * **Way-2 :** First we go down to the lca of *A*[*x*] and *A*[*x* + 1] in the *x*'th persistent tree, updating the values as we go. Now, let *c**l* be the child of lca which is an ancestor of *A*[*x*], and let *c**r* be the child which is an ancestor of *A*[*x* + 1]. Now, we replace *c**r* of *x*'th persistent tree with *c**r* of (*x* + 1)'th persistent tree. Similarly, we replace *c**l* of *x* + 1'th persistent tree with *c**l* of *x*'th persistent tree. So now *A*[*x* + 1] is active in *x*'th persistent tree and both *A*[*x*] and *A*[*x* + 1] are active in (*x* + 1)'th persistent tree.To deactivate *A*[*x*] in *x*'th persistent tree we replace *c**l* of *x*'th persistent tree with *c**l* of (*x* - 1)'th persistent tree. Hence in this approach we do not need to create new  nodes for each update. See testers's code below for more details. 645 646 **Author's code:** 647 648 ``` 649 //Tanuj Khattar 650 #include<bits/stdc++.h> 651 652 using namespace std; 653 654 typedef pair<int,int> II; 655 typedef vector< II > VII; 656 typedef vector<int> VI; 657 typedef vector< VI > VVI; 658 typedef long long int LL; 659 660 #define PB push_back 661 #define MP make_pair 662 #define F first 663 #define S second 664 #define SZ(a) (int)(a.size()) 665 #define ALL(a) a.begin(),a.end() 666 #define SET(a,b) memset(a,b,sizeof(a)) 667 668 #define si(n) scanf("%d",&n) 669 #define dout(n) printf("%d\n",n) 670 #define sll(n) scanf("%lld",&n) 671 #define lldout(n) printf("%lld\n",n) 672 #define fast_io ios_base::sync_with_stdio(false);cin.tie(NULL) 673 674 #define TRACE 675 676 #ifdef TRACE 677 #define trace(...) __f(#__VA_ARGS__, __VA_ARGS__) 678 template <typename Arg1> 679 void __f(const char* name, Arg1&& arg1){ 680 cerr << name << " : " << arg1 << std::endl; 681 } 682 template <typename Arg1, typename... Args> 683 void __f(const char* names, Arg1&& arg1, Args&&... args){ 684 const char* comma = strchr(names + 1, ',');cerr.write(names, comma - names) << " : " << arg1<<" | ";__f(comma+1, args...); 685 } 686 #else 687 #define trace(...) 688 #endif 689 690 //FILE *fin = freopen("in","r",stdin); 691 //FILE *fout = freopen("out","w",stdout); 692 const int MAXN = int(2e5)+10; 693 const int MAXQ = int(2e5)+10; 694 const int N = 2*MAXN; 695 const int M = 2*N; 696 int A[N]; //the permutation given 697 int last[N],prv[M],nxt[M],to[M],deg[N],W[M],root[N]; 698 namespace tree{ 699 int sz,edge,vis[N]; 700 void addEdge(int u,int v,int w = 0){ 701 prv[edge] = last[u];W[edge] = w; 702 if(last[u]!=-1)nxt[last[u]] = edge; 703 last[u] = edge; 704 to[edge] = v; 705 edge++; 706 } 707 void addEdge1(int u,int v,int e){ 708 prv[e] = last[u];nxt[e] = -1; 709 if(last[u]!=-1)nxt[last[u]] = e; 710 last[u] = e; 711 to[e] = v; 712 } 713 void deleteEdge(int u,int e){ 714 if(nxt[e]!=-1)prv[nxt[e]] = prv[e]; 715 if(prv[e]!=-1)nxt[prv[e]] = nxt[e]; 716 if(last[u] == e) last[u] = prv[e]; 717 } 718 void changeEdge(int u,int v,vector<int> edges){ 719 //assert(SZ(edges) == 3);assert(deg[u] > 3); 720 sort(ALL(edges));reverse(ALL(edges)); 721 for(auto e : edges) 722 deleteEdge(u,e); 723 last[v] = last[u]; 724 last[u] = -1; 725 for(auto e : edges) 726 addEdge1(u,to[e],e); 727 } 728 void pre(){ 729 SET(last,-1);SET(nxt,-1); 730 SET(prv,-1);SET(to,-1); 731 } 732 //binarize the give tree.should be called from a leaf node. 733 void binarize(int u,int p,int edge){ 734 vis[u]=1; 735 if(deg[u] > 3){ 736 addEdge(u,++sz); 737 deg[sz] = deg[u] - 1; 738 set<int> temp;temp.insert(edge^1); 739 int e = last[u]; 740 while(SZ(temp) < 3){ 741 temp.insert(e); 742 e = prv[e]; 743 } 744 changeEdge(u,sz,vector<int>(temp.begin(),temp.end())); 745 deg[u] = 3; 746 addEdge(sz,u); 747 } 748 for(int e = last[u];e >= 0; e = prv[e]){ 749 if(!vis[to[e]]) 750 binarize(to[e],u,e); 751 else to[e] = p; 752 } 753 } 754 } 755 namespace Centroid{ 756 const int LOGN = 19; 757 const int MAXC = N + (MAXN + MAXQ)*LOGN; 758 int sub[N],nn,done[M],C[MAXC][3],L[N],R[N],idx[N],len[N],T,cnt[MAXC],lvl,IDX[MAXC]; 759 LL sum[MAXC],cntbn[MAXC],dist[LOGN][N]; 760 void dfs1(int u,int p){ 761 sub[u]=1;nn++; 762 for(int e = last[u];e >= 0; e = prv[e]){ 763 int w = to[e]; 764 if(w!=p && !done[e]) 765 dfs1(w,u),sub[u]+=sub[w]; 766 } 767 } 768 int dfs2(int u,int p){ 769 for(int e = last[u];e >= 0; e = prv[e]){ 770 if(done[e])continue;int w = to[e]; 771 if(w!=p && sub[w]>nn/2) 772 return dfs2(w,u); 773 }return u; 774 } 775 void dfs(int u,int p){ 776 for(int e = last[u];e >= 0; e = prv[e]){ 777 if(done[e] || to[e]==p)continue; 778 dist[lvl][to[e]] = dist[lvl][u] + W[e]; 779 dfs(to[e],u); 780 } 781 } 782 int decompose(int root,int p,int l = 0){ 783 nn=0;dfs1(root,root); 784 root=dfs2(root,root); 785 lvl = l;dfs(root,root); 786 idx[root] = ++T; 787 int id = idx[root];IDX[T] = T; 788 L[id] = T; 789 for(int e = last[root];e >= 0;e = prv[e]){ 790 if(done[e])continue; 791 assert(!done[e^1]); 792 done[e]=done[e^1]=1; 793 int c = decompose(to[e],root,l+1); 794 assert(len[id] < 3); 795 C[id][len[id]++] = idx[c]; 796 } 797 R[id] = T; 798 return root; 799 } 800 int update(int x,int id,int lvl=0){ 801 int ID = ++T; 802 cnt[ID] = cnt[id] + 1; 803 sum[ID] = sum[id] + dist[lvl][x]; 804 IDX[ID] = IDX[id]; 805 for(int i=0;i<len[IDX[id]];i++) 806 if(L[IDX[C[id][i]]] <= idx[x] && idx[x] <= R[IDX[C[id][i]]]){ 807 C[ID][i] = update(x,C[id][i],lvl+1); 808 cntbn[C[ID][i]] = cntbn[C[id][i]] + dist[lvl][x]; 809 } 810 else C[ID][i] = C[id][i]; 811 return ID; 812 } 813 LL query(int x,int id,int lvl=0){ 814 LL ret = sum[id]; 815 for(int i=0;i<len[IDX[id]];i++) 816 if(L[IDX[C[id][i]]] <= idx[x] && idx[x] <= R[IDX[C[id][i]]]) 817 ret += query(x,C[id][i],lvl+1) - cntbn[C[id][i]] + (cnt[id] - cnt[C[id][i]])*dist[lvl][x]; 818 return ret; 819 } 820 } 821 void binarize(int n){ 822 int root = -1; 823 for(int i=1;i<=n;i++) 824 if(deg[i] == 1) 825 root = i; 826 tree::binarize(root,root,-1); 827 } 828 int main() 829 { 830 tree::pre(); 831 int n,q; 832 si(n);si(q); 833 tree::sz = n; 834 for(int i=1;i<=n;i++)si(A[i]); 835 for(int i=1;i<n;i++){ 836 int u,v,w; 837 si(u);si(v);si(w); 838 tree::addEdge(u,v,w); 839 tree::addEdge(v,u,w); 840 deg[u]++;deg[v]++; 841 } 842 //binarize the given tree 843 binarize(n); 844 //build the centroid tree. 845 Centroid::decompose(1,-1); 846 root[0] = 1; 847 //make it persistent and handle the queries. 848 for(int i=1;i<=n;i++) 849 root[i] = Centroid::update(A[i],root[i-1]); 850 const int MOD = (1 << 30); 851 LL ans = 0; 852 while(q--){ 853 int t;si(t); 854 if(t==1){ 855 int l,r,v; 856 si(l);si(r);si(v); 857 l = l ^ ans; 858 r = r ^ ans; 859 v = v ^ ans; 860 ans = Centroid::query(v,root[r])-Centroid::query(v,root[l-1]); 861 lldout(ans); 862 ans = ans % MOD; 863 } 864 else{ 865 int x;si(x);x = x ^ ans; 866 root[x] = Centroid::update(A[x+1],root[x-1]); 867 swap(A[x],A[x+1]); 868 } 869 } 870 return 0; 871 } 872 ``` 873 874 **Testers's code:** 875 876 ``` 877 //Toshad Salwekar 878 #include<bits/stdc++.h> 879 #define f(i,a,n) for(int i=a;i<n;i++) 880 #define S second 881 #define F first 882 #define Sc(n) scanf("%lld",&n) 883 #define scc(a,b,c) scanf("%lld %lld %lld",&a,&b,&c) 884 #define sp(a) scanf("%lld %lld",&a.first,&a.second) 885 #define pb push_back 886 #define mp make_pair 887 #define lb lower_bound 888 #define ub upper_bound 889 #define all(a) a.begin(),a.end() 890 #define sc(n) scanf("%d",&n) 891 #define It iterator 892 #define SET(a,b) memset(a,b,sizeof(a)) 893 #define DRT() int t; cin>>t; while(t--) 894 // inbuilt functions 895 // __gcd, __builtin_ffs, (returns least significant 1-bit, __builtin_ffsll(1)=1) 896 // __builtin_clz, (returns number of leading zeroes in 897 // __builtin_popcount, 898 using namespace std; 899 typedef long long LL; 900 typedef pair<int,LL> PII; 901 typedef vector<int> vi; 902 #define tr(container, it) for(__typeof(container.begin()) it = container.begin(); it != container.end(); it++) 903 #define trv(s,it) for(auto it:s) 904 #define TRACE 905 906 #ifdef TRACE 907 #define trace(...) __f(#__VA_ARGS__, __VA_ARGS__) 908 template <typename Arg1> 909 void __f(const char* name, Arg1&& arg1){ 910 cerr << name << " : " << arg1 << std::endl; 911 } 912 template <typename Arg1, typename... Args> 913 void __f(const char* names, Arg1&& arg1, Args&&... args){ 914 const char* comma = strchr(names + 1, ',');cerr.write(names, comma - names) << " : " << arg1<<" | ";__f(comma+1, args...); 915 } 916 #else 917 #define trace(...) 918 #endif 919 #define N 400005 920 #define LOGN 20 921 const int MAX = N*LOGN; 922 const int MOD = (1<<30); 923 int cn[N],nn,par[N],arr[N],centroid,C,tot,anc[N]; 924 LL dis[LOGN][N]; 925 vector<PII> tree[N]; 926 bool mark[N]; stack<int> st; 927 struct node 928 { int id,cn,len; LL sum,psum; 929 node* child[4]; 930 }*pers[N]; 931 node BUFF[MAX]; 932 int buf_len; 933 int dfs1(int i,int p) 934 { int r=1,mx=0,t; 935 for(auto it:tree[i]) 936 if(it.F!=p && !mark[it.F]) 937 r+=dfs1(it.F,i); 938 cn[i]=r; 939 return r; 940 } 941 int dfs2(int i,int p,int num) 942 { for(auto it:tree[i]) 943 if(cn[it.F]>num/2 && !mark[it.F] && it.F!=p) 944 return dfs2(it.F,i,num); 945 return i; 946 } 947 void dfs(int i,int p,LL d) 948 { for(auto it:tree[i]) 949 if(it.F!=p && !mark[it.F]) 950 dfs(it.F,i,d+it.S); 951 dis[C][i]=d; 952 } 953 void dec(int root, node* p,int c) 954 { dfs1(root,root); 955 int cen=dfs2(root,root,cn[root]); //cen is centroid of current subtree 956 C=c; 957 dfs(cen,cen,0LL); 958 mark[cen]=1; 959 node* tmp= BUFF + buf_len++; 960 tmp->id=cen; 961 tmp->cn=0; tmp->len=0; 962 tmp->sum=0; 963 if(p!=NULL) 964 { p->child[p->len++]=tmp; 965 par[cen]=p->id; 966 } 967 else 968 { pers[0]=tmp; //This means cen is the centroid 969 centroid=cen; 970 } 971 for(auto it:tree[cen]) 972 if(!mark[it.F]) 973 dec(it.F,tmp,c+1); 974 } 975 node* persist(node* root, int i,int l) 976 { 977 node* tmp= BUFF + buf_len++; 978 tmp->id=root->id; 979 tmp->sum=root->sum + dis[l][i]; 980 if(l) 981 tmp->psum=root->psum + dis[l-1][i]; 982 tmp->cn=root->cn + 1; 983 tmp->len=0; 984 f(j,0,root->len) 985 if(!st.empty() && (root->child[j])->id==st.top()) 986 { st.pop(); 987 tmp->child[tmp->len++]=persist(root->child[j],i,l+1); 988 } 989 else 990 tmp->child[tmp->len++]=root->child[j]; 991 return tmp; 992 } 993 LL query(node* root, int i,int l) 994 { LL ans=0; 995 ans+=(root->cn)*dis[l][i]+root->sum; // Add all nodes in range which are in subtree(in centroid tree) of current node 996 f(j,0,root->len) 997 if(!st.empty() && root->child[j]->id==st.top()) 998 { st.pop(); 999 ans-=(root->child[j]->psum)+(root->child[j]->cn)*dis[l][i]; //Subtract all nodes which will be considered in the child(i.e., they are 1000 ans+=query(root->child[j],i,l+1); // in same subtree as the query node). 1001 } 1002 return ans; 1003 } 1004 void binarise(unordered_map<int,LL> &add,int i,PII p,bool fl) 1005 { unordered_map<int,LL> tmp; 1006 mark[i]=1; 1007 if(fl) // fl=1 for those nodes which were not in original tree 1008 { add.erase(p.F); 1009 tree[i].pb(p); 1010 tree[i].pb(*(add.begin())); 1011 add.erase(add.begin()); 1012 if(add.size()>1) // Need to create more nodes 1013 { tree[i].pb(mp(tot++,0LL)); 1014 binarise(add,tot-1,mp(i,0LL),1); 1015 } 1016 else 1017 { tree[i].pb(*(add.begin())); 1018 binarise(tmp,tree[i][2].F,mp(i,tree[i][2].S),0); 1019 } 1020 binarise(tmp,tree[i][1].F,mp(i,tree[i][1].S),0); 1021 } 1022 else if(tree[i].size()>3) 1023 { int t=0;bool fl=0; 1024 if(tree[i][t].F==p.F) 1025 t++; 1026 f(j,t,tree[i].size()) 1027 if(mark[tree[i][j].F] && tree[i].size()==4) // This means that tree[i][j].F is the parent in original tree 1028 fl=1; 1029 if(fl) // Only has 1030 { f(j,0,tree[i].size()) 1031 if(tree[i][j]!=p && !mark[tree[i][j].F]) 1032 binarise(tmp,tree[i][j].F,mp(i,tree[i][j].S),0); 1033 else if(mark[tree[i][j].F]) 1034 tree[i][j]=p; 1035 return; 1036 } 1037 if(mark[tree[i][t].F]) 1038 t++; 1039 binarise(tmp,tree[i][t].F,mp(i,tree[i][t].S),0); //t represents the child which will stay the child of this node. 1040 f(j,0,tree[i].size()) 1041 if(j==t); 1042 else if(!mark[tree[i][j].F] && tree[i][j].F!=p.F) 1043 tmp.insert(tree[i][j]); 1044 else if(mark[tree[i][j].F]) //Replace original parent with new parent 1045 tree[i][j]=p; 1046 PII tm=tree[i][t]; 1047 tree[i].clear(); 1048 if(i!=1) // 1 is root. For all others, add parent. 1049 tree[i].pb(p); 1050 tree[i].pb(tm); 1051 tree[i].pb(mp(tot++,0LL)); // Add new extra node 1052 binarise(tmp,tot-1,mp(i,0LL),1); 1053 } 1054 else 1055 f(j,0,tree[i].size()) 1056 if(tree[i][j]!=p && !mark[tree[i][j].F]) 1057 binarise(tmp,tree[i][j].F,mp(i,tree[i][j].S),0); 1058 else if(mark[tree[i][j].F]) //Replace original with new parent 1059 tree[i][j]=p; 1060 } 1061 1062 int main() 1063 { 1064 int n,q; LL a,b,c; 1065 cin>>n>>q; 1066 tot=n+1; 1067 f(i,1,n+1) 1068 sc(arr[i]); 1069 f(i,1,n) 1070 { scc(a,b,c); 1071 tree[a].pb(mp(b,c)); 1072 tree[b].pb(mp(a,c)); 1073 } 1074 unordered_map<int,LL> stmp; 1075 binarise(stmp,1,mp(0,0LL),0); 1076 SET(mark,0); 1077 dec(1,NULL,0); 1078 f(i,1,n+1) 1079 { 1080 int p=arr[i]; 1081 while(p!=centroid) //push all nodes to be added in a stack 1082 { st.push(p); 1083 p=par[p]; 1084 } 1085 pers[i]=persist(pers[i-1],arr[i],0); 1086 } 1087 LL an = 0; 1088 f(i,1,q+1) 1089 { Sc(a); 1090 Sc(b); 1091 if(a==1) 1092 { Sc(c); Sc(a); 1093 b = b ^ an; c = c ^ an; a = a ^ an; 1094 int p=a; 1095 an=0; 1096 while(p!=centroid) //push all nodes to be queried in a stack 1097 { st.push(p); 1098 p=par[p]; 1099 } 1100 an-=query(pers[b-1],a,0); 1101 p=a; 1102 while(p!=centroid) //push all nodes to be queried in a stack 1103 { st.push(p); 1104 p=par[p]; 1105 } 1106 an+=query(pers[c],a,0); 1107 printf("%lld\n",an); 1108 an %= MOD; 1109 } 1110 else 1111 { b = b ^ an; 1112 int p=arr[b],lca=centroid,h=centroid; 1113 while(p!=centroid) 1114 { anc[p]=i; //mark all ancestors of arr[b] 1115 p=par[p]; 1116 } 1117 p=arr[b+1]; 1118 while(p!=centroid) 1119 { if(anc[p]==i) 1120 { lca=p; break; } 1121 h=p; // h is the highest ancestor of arr[b+1] which is not an ancestor of arr[b] 1122 p=par[p]; 1123 } 1124 node *rt1=pers[b], *rt2=pers[b+1], *rt=pers[b-1]; 1125 int l=0,k=-1; 1126 while(rt->id!=lca) //traverse down to lca in all 3 centroid trees. 1127 { rt1->sum -= dis[l][arr[b]] - dis[l][arr[b+1]]; 1128 if(l) 1129 rt1->psum -= dis[l-1][arr[b]] - dis[l-1][arr[b+1]]; 1130 l++; 1131 f(j,0,rt1->len) 1132 if(anc[rt1->child[j]->id]==i) 1133 { rt1=rt1->child[j]; 1134 break; 1135 } 1136 f(j,0,rt2->len) 1137 if(anc[rt2->child[j]->id]==i) 1138 { rt2=rt2->child[j]; 1139 break; 1140 } 1141 f(j,0,rt->len) 1142 if(anc[rt->child[j]->id]==i) 1143 { rt=rt->child[j]; 1144 break; 1145 } 1146 } 1147 rt1->sum-=dis[l][arr[b]]-dis[l][arr[b+1]]; //update lca too 1148 if(l) 1149 rt1->psum-=dis[l-1][arr[b]]-dis[l-1][arr[b+1]]; 1150 1151 /* This is the swapping part. 1152 * b1child represents the child containing arr[b], 1153 * b2child represents the child containing arr[b+1] and 1154 * bchild represents the child containing arr[b] in persistent centroid tree of first b-1 elements 1155 * The difference between b1child and bchild is that in b1child the ans due to arr[b] is considered, but it is not so in bchild. 1156 * Now we replace b1child with bchild and add b2child in pers[b], so that in pers[b], arr[b+1] is now active and not arr[b]. 1157 * */ 1158 node *b1child=NULL,*b2child=NULL,*bchild=NULL; 1159 f(j,0,rt->len) //find bchild It may not exist if arr[b] = lca 1160 if(anc[rt->child[j]->id]==i) 1161 bchild=rt->child[j]; 1162 f(j,0,rt1->len) 1163 if(anc[rt1->child[j]->id]==i) //find b1child. It may not exist if arr[b] = lca 1164 { b1child=rt1->child[j]; k=j; } 1165 int vv=0; 1166 if(b1child!=NULL) // vv is used to handle the case where b1child = NULL 1167 vv=b1child->id; 1168 f(j,0,rt2->len) 1169 if(rt2->child[j]->id==h) //find b2child. It may not exist if arr[b+1] = lca 1170 b2child=rt2->child[j]; 1171 else if(rt2->child[j]->id==vv) 1172 rt2->child[j]=b1child; 1173 if(k>=0) //Again, check if b1child exists. 1174 rt1->child[k]=bchild; 1175 f(j,0,rt1->len) 1176 if(rt1->child[j]->id==h) 1177 rt1->child[j]=b2child; 1178 swap(arr[b],arr[b+1]); 1179 } 1180 1181 } 1182 } 1183 ``` 1184 1185 Hope you enjoyed the problemset! Any feedback is appreciated! :)