
601.md (24387B)
1 Source: https://codeforces.com/blog/entry/21755 2 3 ### Hints: 4 5 [div2A](#div2A): Try conversions between bases. 6 7 [div2B](#div2B): Solve a simpler version of the problem where *A**i* + 1 ≠ *A**i* for all *i*. 8 9 [div1A](#div1A): What are the shortest paths of the vehicles? what's the shorter of those paths? 10 11 [div1B](#div1B): Forget about the ceiling function. Draw points (*i*, *A*[*i*]) and lines between them — what's the Lipschitz constant geometrically? 12 13 [div1C](#div1C): Some dynamic programming. Definitely not for the exp. score of one person — look at fixed scores instead. 14 15 [div1D](#div1D): Compute *dif*(*v*) in *O*(*N*) (without hashing) and then solve the problem in *O*(*N*2). You need some smart merges. 16 17 [div1E](#div1E): Can you solve the problem without events of type 1 or 2? Also, how about solving it offline — as queries on subsets. 18 19  20 21 ### Div. 2 A: Two Bases 22 23 --- 24 25 It's easy to compare two numbers if the same base belong to both. And our numbers can be converted to a common base — just use the formulas 26 27 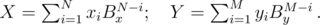 28 29 A straightforward implementation takes *O*(*N* + *M*) time and memory. Watch out, you need 64-bit integers! And don't use `pow` — iterating 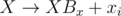 is better. 30 31  32 33 ### Div. 2 B: Approximating a Constant Range 34 35 --- 36 37 Let's process the numbers from left to right and recompute the longest range ending at the currently processed number. 38 39 One option would be remembering the last position of each integer using STL `map<>`/`set<>` data structures, looking at the first occurrences of *A**i* plus/minus 1 or 2 to the left of the current *A**i* and deciding on the almost constant range ending at *A**i* based on the second closest of those numbers. 40 41 However, there's a simpler and more efficient option — notice that if we look at non-zero differences in any almost constant range, then they must alternate: .., + 1, - 1, + 1, - 1, ... If there were two successive differences of + 1-s or - 1-s (possibly separated by some differences of 0), then we'd have numbers *a* - 1, *a*, *a*, ..., *a*, *a* + 1, so a range that contains them isn't almost constant. 42 43 Let's remember the latest non-zero difference (whether it was +1 or -1 and where it happened); it's easy to update this info when encountering a new non-zero difference. 44 45 When doing that update, we should also check whether the new non-zero difference is the same as the latest one (if *A**i* - *A**i* - 1 = *A**j* + 1 - *A**j*). If it is, then we know that any almost constant range that contains *A**i* can't contain *A**j*. Therefore, we can keep the current leftmost endpoint *l* of a constant range and update it to *j* + 1 in any such situation; the length of the longest almost constant range ending at *A**i* will be *i* - *l* + 1. 46 47 This only needs a constant number of operations per each *A**i*, so the time complexity is *O*(*N*). Memory: *O*(*N*), but it can be implemented in *O*(1). 48 49 Bonus: the maximum difference permitted in an almost constant range is an arbitrary *D*. 50 51  52 53 ### Div. 2 C / Div. 1 A: The Two Routes 54 55 --- 56 57 The condition that the train and bus can't meet at one vertex except the final one is just trolling. If there's a railway , then the train can take it and wait in town *N*. If there's no such railway, then there's a road , the bus can take it and wait in *N* instead. There's nothing forbidding this :D. 58 59 The route of one vehicle is clear. How about the other one? Well, it can move as it wants, so the answer is the length of its shortest path from 1 to *N*... or - 1 if no such path exists. It can be found by BFS in time *O*(*N* + *M*) = *O*(*N*2). 60 61 In order to avoid casework, we can just compute the answer as the maximum of the train's and the bus's shortest distance from 1 to *N*. That way, we compute 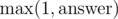; since the answer is ≥ 1, it works well. 62 63 In summary, time and memory complexity: *O*(*N*2). 64 65 Bonus: Assume that there are *M*1 roads and *M*2 railways given on the input, all of them pairwise distinct. 66 67 Bonus 2: Additionally, assume that the edges are weighted. The speed of both vehicles is still the same — traversing an edge of length *l* takes *l* hours. 68 69  70 71 ### Div. 2 D / Div. 1 B: Lipshitz Sequence 72 73 --- 74 75 Let 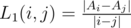 for *i* ≠ *j*. 76 77 Key observation: it's sufficient to consider *j* = *i* + 1 when calculating the Lipschitz constant. It can be seen if you draw points (*i*, *A**i*) and lines between them on paper — the steepest lines must be between adjacent pairs of points. 78 79 In order to prove it properly, we'll consider three numbers *A**i*, *A**j*, *A**k* (*i* < *j* < *k*) and show that one of the numbers *L*1(*i*, *j*), *L*1(*j*, *k*) is ≥ *L*1(*i*, *k*). W.l.o.g., we may assume *A**i* ≤ *A**k*. There are 3 cases depending on the position of *A**j* relative to *A**i*, *A**k*: 80 81 * *A**j* > *A**i*, *A**k* — we can see that *L*1(*i*, *j*) > *L*1(*i*, *k*), since |*A**j* - *A**i*| = *A**j* - *A**i* > *A**k* - *A**i* = |*A**k* - *A**i*| and *j* - *i* < *k* - *i*; we just need to divide those inequalities 82 * *A**j* < *A**i*, *A**k* — this is similar to the previous case, we can prove that *L*1(*j*, *k*) > *L*1(*i*, *k*) in the same way 83 * *A**i* ≤ *A**j* ≤ *A**k* — this case requires more work: 84 85 + we'll denote *d*1*y* = *A**j* - *A**i*, *d*2*y* = *A**k* - *A**j*, *d*1*x* = *j* - *i*, *d*2*x* = *k* - *j* 86 + then, *L*1(*i*, *j*) = *d*1*y* / *d*1*x*, *L*1(*j*, *k*) = *d*2*y* / *d*2*x*, *L*1(*i*, *k*) = (*d*1*y* + *d*2*y*) / (*d*1*x* + *d*2*x*) 87 + let's prove it by contradiction: assume that *L*1(*i*, *j*), *L*1(*j*, *k*) < *L*1(*i*, *k*) 88 + *d*1*y* + *d*2*y* = *L*1(*i*, *j*)*d*1*x* + *L*1(*j*, *k*)*d*2*x* < *L*1(*i*, *k*)*d*1*x* + *L*1(*i*, *k*)*d*2*x* = *L*1(*i*, *k*)(*d*1*x* + *d*2*x*) = *d*1*y* + *d*2*y*, which is a contradiction 89 90 We've just proved that to any *L*1 computed for two elements *A*[*i*], *A*[*k*] with *k* > *i* + 1, we can replace one of *i*, *j* by a point *j* between them without decreasing *L*1; a sufficient amount of such operations will give us *k* = *i* + 1. Therefore, the max. *L*1 can be found by only considering differences between adjacent points. 91 92 This is actually a huge simplification — the Lipschitz constant of an array is the maximum abs. difference of adjacent elements! If we replace the array *A*[1..*n*] by an array *D*[1..*n* - 1] of differences, *D*[*i*] = *A*[*i* + 1] - *A*[*i*], then the Lipschitz constant of a subarray *A*[*l*, *r*] is the max. element in the subarray *D*[*l*..*r* - 1]. Finding subarray maxima actually sounds quite standard, doesn't it? 93 94 No segment trees, of course — there are still too many subarrays to consider. 95 96 So, what do we do next? There are queries to answer, but not too many of them, so we can process each of them in *O*(*N*) time. One approach that works is assigning a max. difference *D*[*i*] to each subarray — since there can be multiple max. *D*[*i*], let's take the leftmost one. 97 98 We can invert it to determine the subarrays for which a given *D*[*i*] is maximum: if *D*[*a**i*] is the closest difference to the left of *D*[*i*] that's ≥ *D*[*i*] or *a**i* = 0 if there's none, and *D*[*b**i*] is the closest difference to the right that's > *D*[*i*] or *b**i* = *n* - 1 if there's none (note the strict/non-strict inequality signs — we don't care about differences equal to *D*[*i*] to its right, but there can't be any to its left, or it wouldn't be the leftmost max.), then those are all subarrays *D*[*j*..*k*] such that *a**i* < *j* ≤ *i* ≤ *k* < *b**i*. 99 100 If we don't have the whole array *D*[1..*n* - 1], but only some subarray *D*[*l*..*r*], then we can simply replace *a**i* by  and *b**i* by . The number of those subarrays is *P**i* = (*i* - *a**i*)(*b**i* - *i*), since we can choose *j* and *k* independently. 101 102 All we have to do to answer a query is check all differences, take *a**i*, *b**i* (as the max/min with some precomputed values) and compute *P**i*; the answer to the query is . We only need to precompute all *a**i*, *b**i* for the whole array *D*[1..*n* - 1] now; that's a standard problem, solvable using stacks in *O*(*N*) time or using maps + Fenwick trees in  time. 103 104 The total time complexity is *O*(*NQ*), memory *O*(*N*). 105 106 Bonus: *Q* ≤ 105. 107 108  109 110 ### Div. 1 C: Kleofáš and the n-thlon 111 112 --- 113 114 As it usually happens with computing expected values, the solution is dynamic programming. There are 2 things we could try to compute: probabilities of individual overall ranks of Kleofáš or just some expected values. In this case, the latter option works. 115 116 * "one bit is 8 bytes?" 117 * "no, the other way around" 118 * "so 8 bytes is 1 bit?" 119 120 After some attempts, one finds out that there's no reasonable way to make a DP for an expected rank or score of one person (or multiple people). What does work, and will be the basis of our solution, is the exact opposite: we can compute the expected number of people with a given score. The most obvious DP for it would compute *E*(*i*, *s*) — the exp. number of people other than Kleofáš with score *s* after the first *i* competitions. 121 122 Initially, *E*(0, 0) = *m* - 1 and *E*(0, *s* > 0) = 0. How can we get someone with score *s* in competition *i*? That person can have any score *k* from 1 to *m* except *x**i* (since Kleofáš has that one) with the same probability . The expected values are sums with probabilities *P*(*i*, *s*, *j*) that there are *j* people with score *s*: 123 124  125 126 Considering that the probability that one of them will get score *k* is , we know that with probability , we had *j* people with score *s* before the competition and one of them had score *s* + *k* after that competition — adding 1 to *E*(*i* + 1, *s* + *k*). By summation over *j*, we'll find the exp. number of people who had overall score *s* and scored *k* more: 127 128  129 130 Lol, it turns out to be so simple. 131 132 We can find the probability *E*(*i* + 1, *t*) afterwards: since getting overall score *t* after *i* + 1 competitions means getting score *k* in the currently processed competition and overall score *s* = *t* - *k* before, and both distinct *k* and expectations for people with distinct *s* are totally independent of each other, then we just need to sum up the exp. numbers of people with those scores (which we just computed) over the allowed *k*: 133 134  135 136 The formulas for our DP are now complete and we can use them to compute *E*(*n*, *s*) for all 1 ≤ *s* ≤ *mn*. Since *E*(*n*, *s*) people with *s* greater than the overall score *s**k* of Kleofáš add *E*(*n*, *s*) to the overall rank of Kleofáš and people with *s* ≤ *s**k* add nothing, we can find the answer as 137 138  139 140 This takes *O*(*m*2*n*2) time, since there are *O*(*mn*) scores, *O*(*mn*2) states of the DP and directly computing each of them takes *O*(*m*) time. Too slow. 141 142 We can do better, of course. Let's forget about dividing by *m* - 1 for a while; then, *E*(*i* + 1, *t*) is a sum of *E*(*i*, *s*) for one or two ranges of scores — or for one range minus one value. If you can solve div1C, then you should immediately know what to do: compute prefix sums of *E*(*i*, *s*) over *s* and find *E*(*i* + 1, *t*) for each *t* using them. 143 144 And now, computing one state takes *O*(1) time and the problem is solved in *O*(*mn*2) time (and memory). 145 146 Bonus: Really, how fast can you solve this problem? 147 148  149 150 ### Div. 1 D: Acyclic Organic Compounds 151 152 --- 153 154 The name is really almost unrelated — it's just what a tree with arbitrary letters typically is in chemistry. 155 156 If you solved problem TREEPATH from the recent Codechef November Challenge, this problem should be easier for you — it uses the same technique, after all. 157 158 Let's figure out how to compute  for just one fixed *v*. One more or less obvious way is computing hashes of our strings in a DFS and then counting the number of distinct hashes (which is why there are anti-hash tests :D). However, there's another, deterministic and faster way. 159 160 #### Compressing the subtree *T**v* into a trie. 161 162 Recall that a trie is a rooted tree with a letter in each vertex (or possibly nothing in the root), where each vertex encodes a unique string read along the path from the root to it; it has at most σ sons, where σ = 26 is the size of the alphabet, and each son contains a different letter. Adding a son is done trivially in *O*(σ) (each vertex contains an array of 26 links to — possibly non-existent — sons) and moving down to a son with the character *c* is then possible in *O*(1). 163 164 Compressing a subtree can be done in a DFS. Let's build a trie *H**v* (because *T**v* is already used), initially consisting only of one vertex — the root containing the letter *s**v*. In the DFS, we'll remember the current vertex *R* of the tree *T* and the current vertex *cur* of the trie. We'll start the DFS at *v* with *cur* being the root of *H**v*; all we need to do is look at each son *S* of *R* in DFS, create the son *cur**s* of *cur* corresponding to the character *s**S* (if it didn't exist yet) and run *DFS*(*S*, *cur**s*). This DFS does nothing but construct *H**v* that encodes all strings read down from *v* in *T**v*. And since each vertex of *H**v* encodes a distinct string,  is the number of vertices of *H**v*. 165 166 This runs in *O*(|*T**v*|σ) time, since it can create a trie with |*T**v*| vertices in the worst case. Overall, it'd be *O*(*N*2σ) if *T* looks sufficiently like a path. 167 168 #### The HLD trick 169 170 Well, what can we do to improve it? This trick is really the same — **find the son *w* of *v* that has the maximum |*T**w*|, add *s**v* to *H**w* and make it *H**v*; then, DFS through the rest of *T**v* and complete the trie *H**v* as in the slow solution.** The trick resembles HLD a lot, since we're basically remembering tries on HLD-paths. 171 172 If *v* is a leaf, of course, we can just create *H**v* that consists of one vertex. 173 174 How do we "add" *v* to a trie *H**w* of its son *w*? Well, *v* should be the root of the trie afterwards and the original *H**w*'s root should become its son, so we're rerooting *H**w*. We'll just create a new vertex in *H**w* with *s**v* in it, make it the root of *H**w* and make the previous root of *H**w* its son. And if we number the tries somehow, then we can just set the number of *H**v* to be the number of *H**w*. 175 176 It remains true that *dif*(*v*) is |*H**v*| — the number of vertices in the trie *H**v*, which allows us to compute those values directly. After computing *dif*(*v*) for each *v*, we can just compute both statistics directly in *O*(*N*). 177 178 Since each vertex of *T* corresponds to vertices in at most  tries (for each heavy edge that's on the path from it to the root), we aren't creating tries with a total of *O*(*N*2) vertices, but . The time complexity is therefore . However, the same is true for the memory, so you can't waste it too much! 179 180 Bonus: you have an additional tiebreaker condition for vertices with identical . Count the number of distinct strings which occurred exactly *k* times for each *k* in an array *P**r*[]; take the vertex/vertices with lexicograhically maximum *P**r*[] (as many strings as possible which occur only once, etc). 181 182 Bonus 2: Can you get rid of the logarithm in the time complexity? 183 184  185 186 Comic strip name: [Indy](http://www.vgcats.com/super/?strip_id=56). Go read the whole thing, it's not very long, but pretty good. 187 188 ### Div. 1 E: A Museum Robbery 189 190 --- 191 192 In this problem, we are supposed to solve the 0-1 knapsack problem for a set of items which changes over time. We'll solve it offline — each query (event of type 3) is asked about a subset of all *N* exhibits appearing on the input. 193 194 #### Introduction 195 196 If we just had 1 query and nothing else, it's just standard knapsack DP. We'll add the exhibits one by one and update *s*(*m*) (initially, *s*(*m*) = 0 for all *m*). When processing an exhibit with (*v*, *w*), in order to get loot with mass *m*, we can either take that exhibit and get value at least *s*(*m* - *w*) + *v*, or not take it and get *s*(*m*); therefore, we need to replace *s*(*m*) by ; the right way to do it is in decreasing order of *m*. 197 198 In fact, it's possible to merge 2 knapsacks with any number of items in *O*(*k*2), but that's not what we want here. 199 200 Note that we can add exhibits this way. Thus, if there were no queries of type 2, we would be able to solve whole problem in *O*(*Nk*) time by just remembering the current *s*(*m*) and updating it when adding an exhibit. Even if all queries were of type 2 (with larger *n*), we'd be able to solve it in *O*(*nk*) time in a similar way after sorting the exhibits in the order of their removal and processing queries/removals in reverse chronological order. 201 202 #### The key 203 204 Let's have *q* queries numbered 1 through *Q* in the order in which they're asked; query *q* is asked on some subset *S**q* of exhibits. 205 206 MAGIC TRICK: Compute the values *s*(*m*) only for subsets  — the intersections of pairs of queries 2*q*, 2*q* + 1 (intersection of the first and the second query, of the third and fourth etc.), **recursively**. Then, recompute *s*(*m*) for all individual queries in *O*((*N* + *Q*)*k*) time by adding elements which are missing in the intersection, using the standard knapsack method. 207 208 What?! How does this work?! Shouldn't it be more like *O*(*N*2) time? Well, no — just look at one exhibit and the queries where it appears. It'll be a contiguous range of them — since it's displayed until it's removed (or the events end). This element will only be missing in the intersection, but present in one query (so it'll be one of the elements added using knapsack DP), if query 2*q* + 1 is the one where it appears first or query 2*q* the one where it appears last. That makes at most two addittions of each element and *O*(*N*) over all of them; adding each of them takes *O*(*k*) time, which gives *O*(*Nk*). 209 210 The second part of the complexity, *O*(*Qk*) time, is spent by copying the values of *s*(*m*) first from the intersection of queries 2*q* and 2*q* + 1 to those individual queries. 211 212 If we're left with just one query, we can solve it in *O*(*Nk*) as the usual 0-1 knapsack. 213 214 Since we're halving the number of queries when recursing deeper, we can only recurse to depth  and the time complexity is . 215 216 #### A different point of view (Baklazan's) 217 218 We can also look at this as building a perfect binary tree with sets *S*1, ..., *S**Q* in leaves and the intersection of sets of children in every other vertex. 219 220  221 222 For each vertex *v* of this tree, we're solving the knapsack — computing *s*(*m*) — for the set *D**v* of displayed exhibits in it. We will solve the knapsack for the root directly and then proceed to the leaves. In each vertex *v*, we will take *s*(*m*), the set *D**p* of its parent *p* and find *s*(*m*) for *v* by adding exhibits which are in *D**v*, but not in *D**p*. 223 224 We know that the set *D**p* is of the form  for some *a*, *b* and *D**v* is either of the form  or  for  (depending on whether it's the left or the right son). In the first case, only elements removed between the *m*-th and *b*-th query have to be added and in the second case, it's only elements added between the *a*-th and *m* + 1-th query. Since each element will only be added/removed once and the ranges of queries on the same level of the tree are disjoint, we will do *O*((*N* + *Q*)*k*) work on each level and the overall time complexity is . 225 226 #### Finding the intersections and exhibits not in the intersections 227 228 Of course, bruteforcing them in *O*(*NQ*) isn't such a bad idea, but it'd probably TLE — and we can do better. We've just described how we can pick those exhibits based on the queries between which they were added/removed. Therefore, we can find — for each exhibit — the interval of queries for which it was displayed and remember for each two consecutive queries the elements added and removed between them; finding the exhibits added/removed in some range is then just a matter of iterating over them. Since we're actually adding all of them, this won't worsen the time complexity. 229 230 In order to efficiently determine the exhibits in some set , we can remember for each exhibit the interval of time when it was displayed. The exhibit is in the set  if and only if it was displayed before the *a*-th query and remained displayed at least until the *b*-th query. 231 232 To conclude, the time complexity is  and since we don't need to remember all levels of the perfect binary tree, but just the one we're computing and the one above it, the memory complexity is *O*(*qk*).